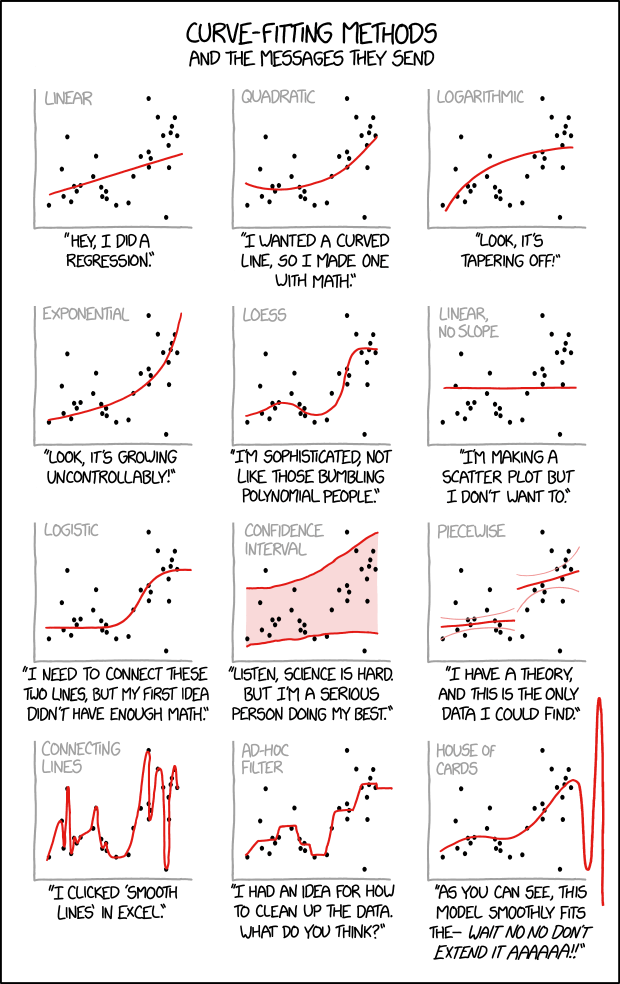
Data that Persuades
Brandon John Williams
November 17, 2026
Considering alternative policies is a challenging task
Decision-makers need to know:
- Where are we now (status quo)?
- What is the objective function?
- What is the response to a small change in policy dosage?
- Is the response increasing? Decreasing? Monotonic?
- Is the response linear? Or more complicated?
Motivation
Ideally, data and models give us insight into the shape of the policy response function
Policy choices are not made by disinterested technocratic experts
Communicating with evidence to guide people to optimal policy choices is important
Bureaucrats, politicians, special interest groups all aim to persuade through data
Motivation
People readily misinterpret data:
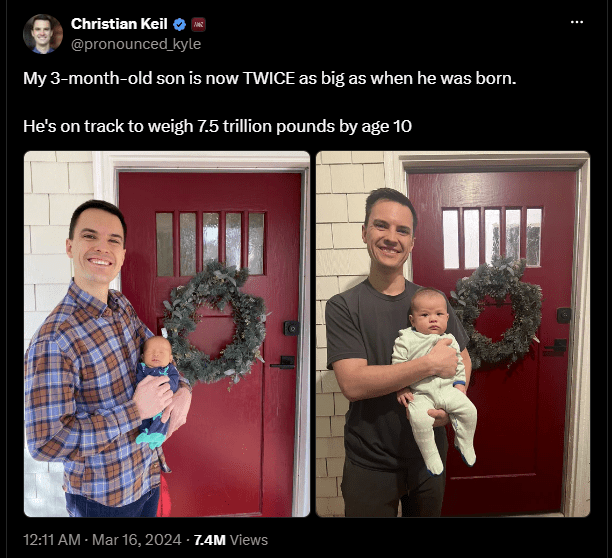
- Inferring large, generalizable trends from small, local changes:
- "It is colder than this time last year, so average temperatures are not increasing"
- "This month's job report shows a complete turnaround"
- Using extreme cases/endpoints to imply monotonicity:
- "Revenue falls to zero at 100% taxation, so cutting rates raises revenue"
- "A $100 minimum wage would kill jobs, so any increase would cost us jobs."
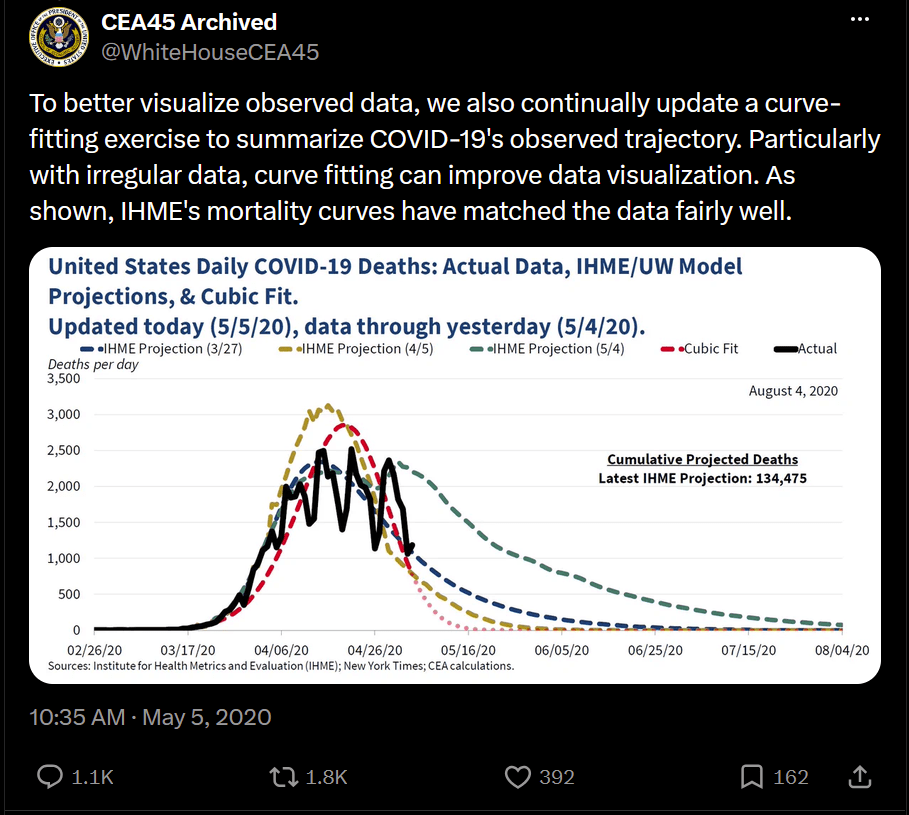
- Failure to anticipate threshold changes:
- "We've increased our fishing every year with no large drop in the population, so we can increase again this year"
Motivation
Motivation
Bad Decision-making
Misunderstanding Data
Bad Models
Bad Decision-making
Misinterpreting Data
Bad Models
Bad Evidence
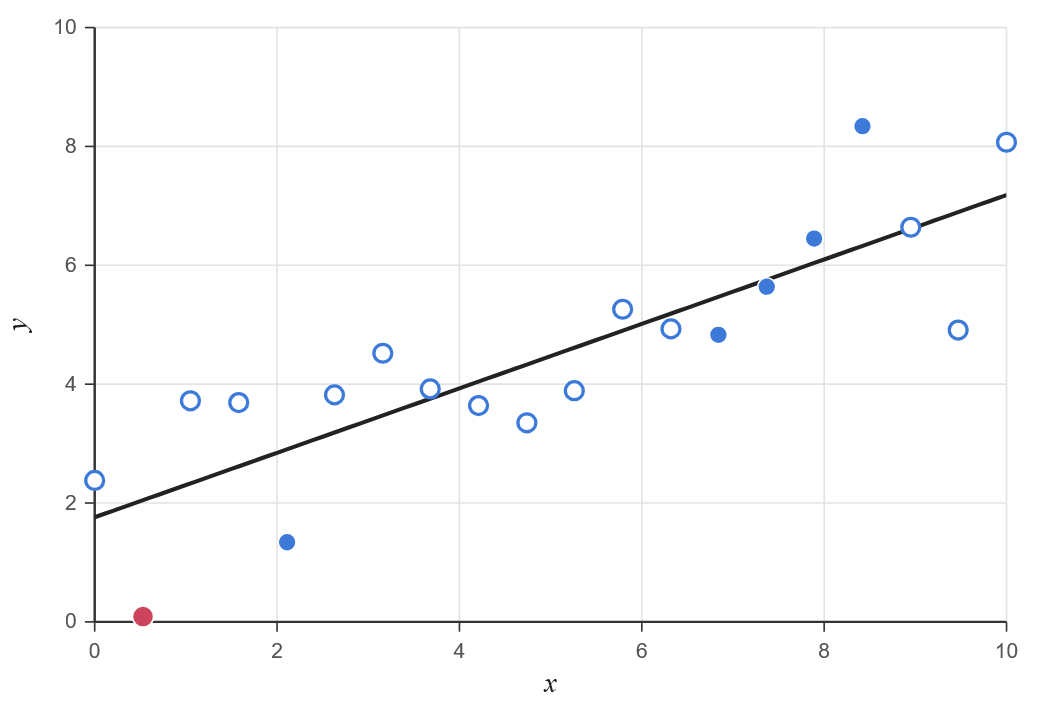
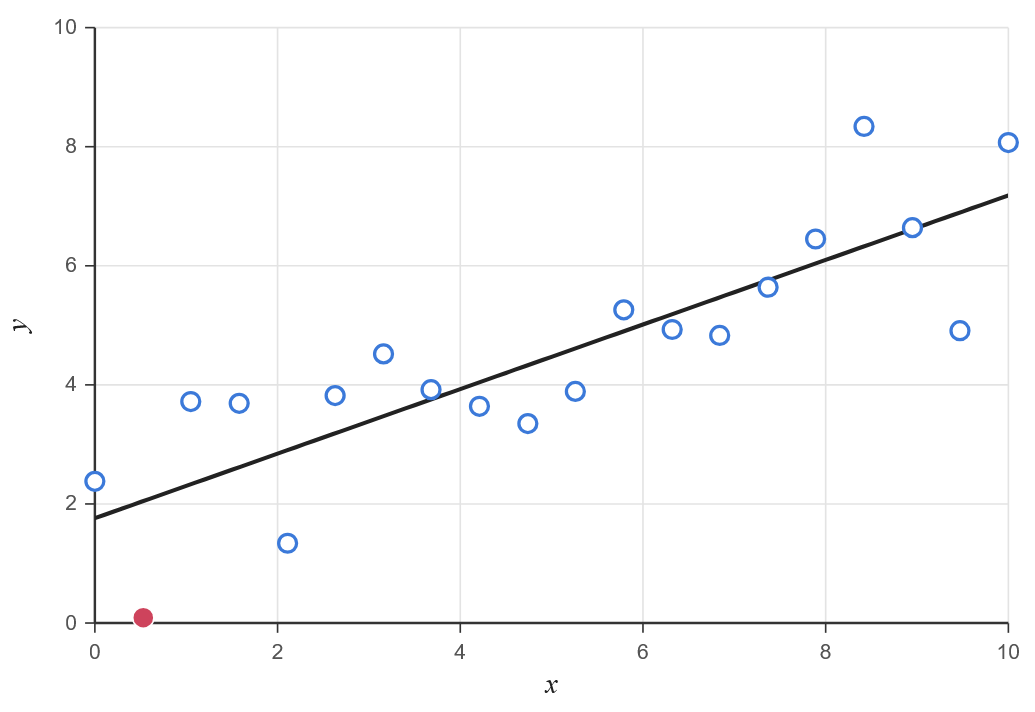
What is the relationship between x and y?
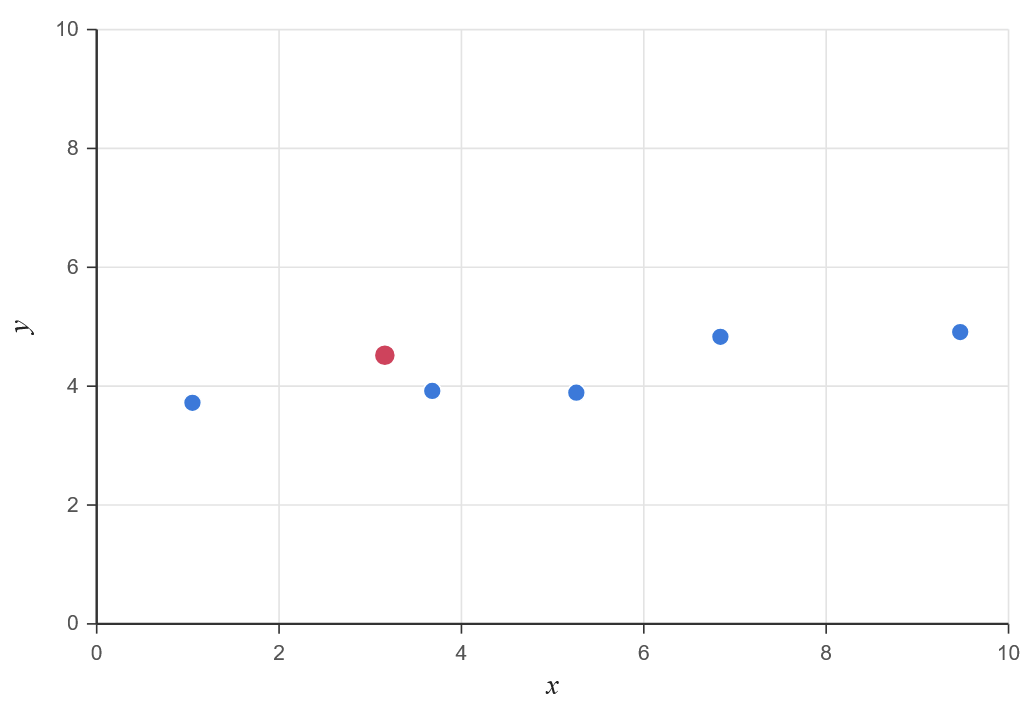
What is the relationship between x and y?
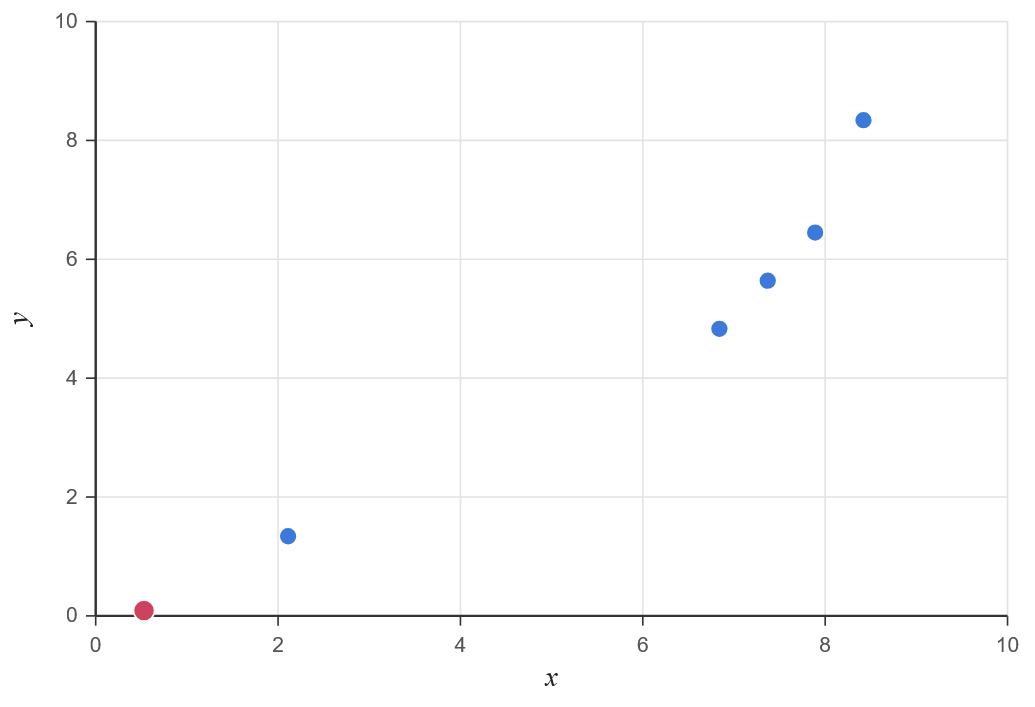
What is the relationship between x and y?
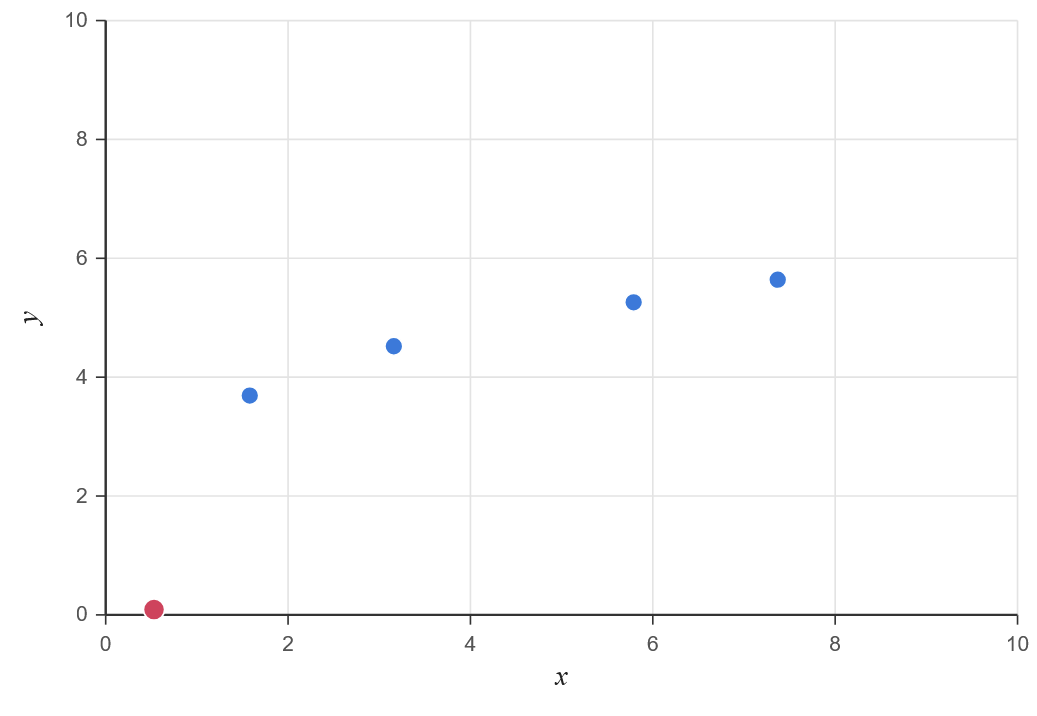
What is the relationship between x and y?
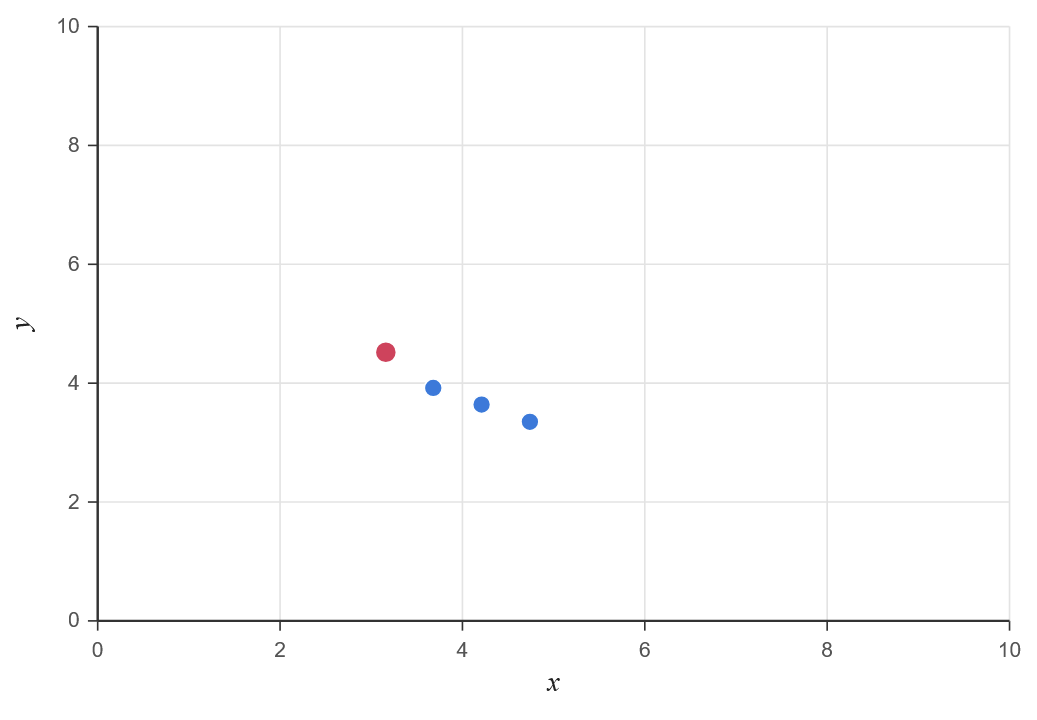
What is the relationship between x and y?
Bad Decision-making
Misinterpreting Data
Bad Models
Biased Transmission
Bad Evidence
Research Question
What data signals are most persuasive?
- What models do decision-makers construct on available data?
- What models do persuaders induce on DMs?
What is the relationship between persuasive data and persuasive rhetoric?
Conceptual Framework
An expert party (government, politician, think tank, special interest group) wants to persuade decision-makers (voters, shareholders) towards a policy dosage - role of benevolent social planner?
They can communicate through verifiable data (no scope for lying)
The present state (status quo) is common knowledge, but otherwise the expert party has the necessary information - what do we mean by necessary information
The experts want to induce a model in DMs through selected signals - what is the proper language of "signals"
DMs know that some experts may have a bias that leads to misaligned payoffs
Why an experiment?
Policy preferences are multidimensional where people have varied priors of different strength
- Experiment: induce a transparent objective function optimal solution
Pinning down what elements of communication are persuasive is challenging because of heterogeneous preferences, beliefs about trustworthiness of information sources, non-instrumental utility of beliefs, etc.
- Experiment: shut down other channels and focus on mental models as a channel in which people understand the world
Theory and Setup
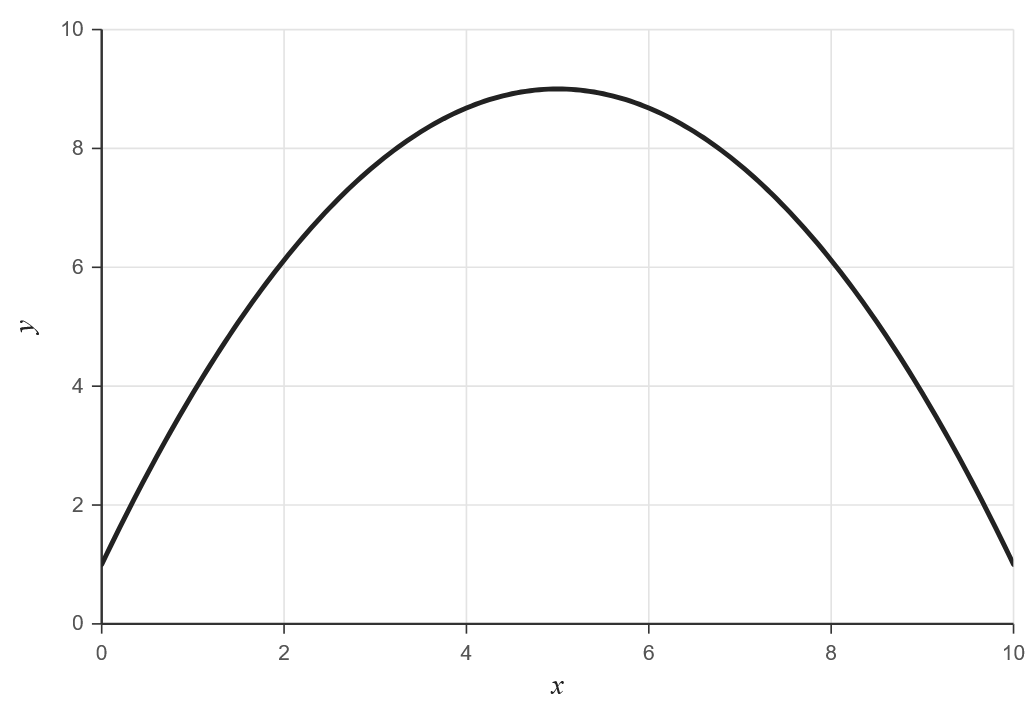
The policy space is a two-dimensional plane: \(x\) is the policy dosage and \(y\) is the policy response
The true relationship between \(x\) and \(y\) is a polynomial of unknown degree
\[f_{d,\beta}(x) = \sum_{k=0}^{d} \beta_k x^k,\]
\[\qquad d \in \mathcal{K} \equiv \{0, 1, \dots, 10\}, \qquad \beta = (\beta_0, \dots, \beta_d) \in \mathbb{R}^{d+1}.\]
Data Generating Process
DGP
The receiver's prior has two layers: a prior over structure (how complex the relationship is) and a prior over the coefficients given the structure:
\[d \sim \pi(d), \qquad \beta \mid d \sim \mathcal{N}\left(\mu_d, \Sigma_d\right)\]
The receiver can see the status quo \( (x_s, y_s) \), which gives both a single point of information and the choice of "don't change policy"
The receiver has an action space \( \mathcal{X} = [\underline{x}, \bar{x}] \)
What assumptions do we need to make about the prior?
The Receiver
The Receiver
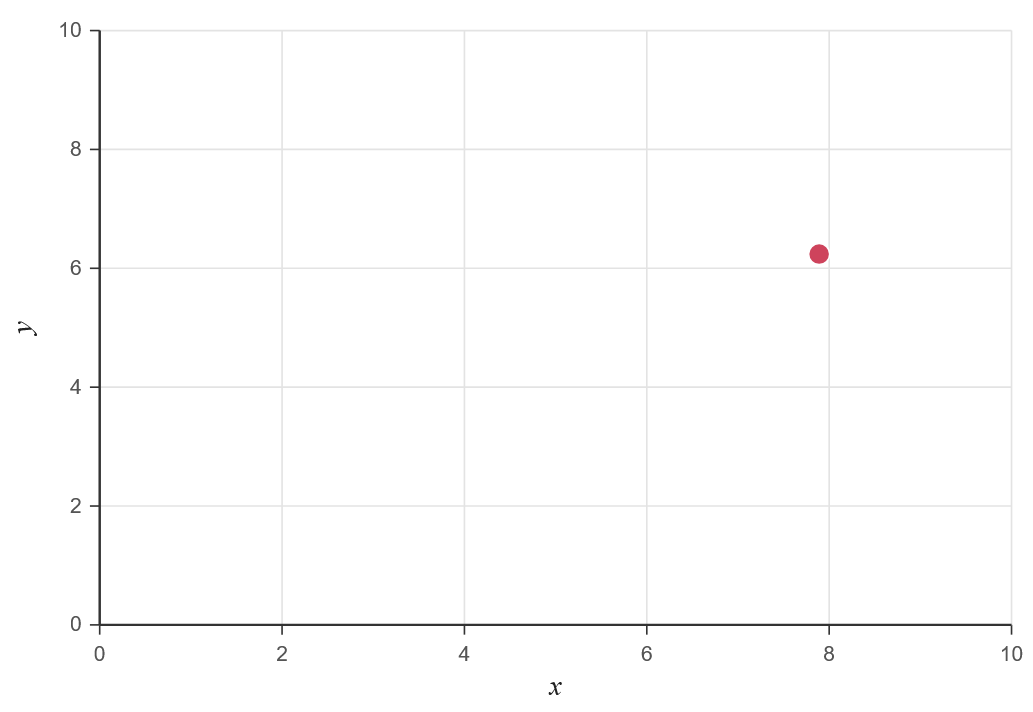
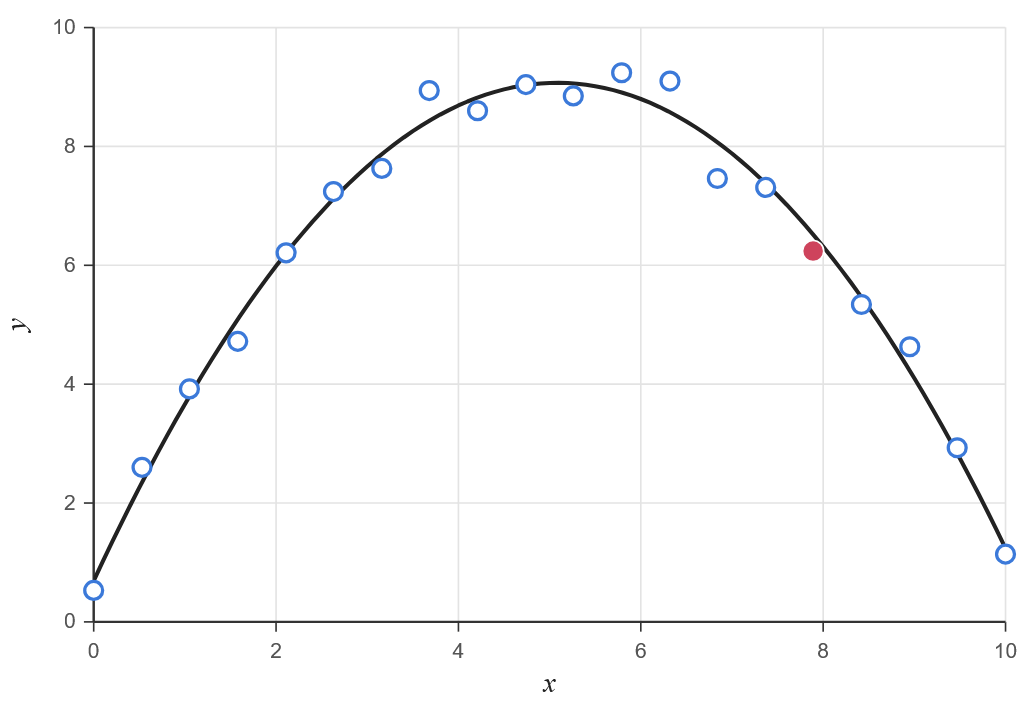
Conditional on \((d, \beta)\), the dataset \(\mathcal{D} = \{(x_i, y_i)\}_{i=1}^{N}\) is generated by
\[y_i = f_{d,\beta}(x_i) + \varepsilon_i, \qquad x_i \overset{iid}{\sim} G, \qquad \varepsilon_i \overset{iid}{\sim} \mathcal{N}(0, \sigma^2), \qquad i = 1, \dots, N,\]
with \(\varepsilon_i\) independent of \(x_i\). The status quo is a single publicly observed point,
\[y_s = f_{d,\beta}(x_s) + \varepsilon_s, \qquad x_s \in \mathcal{X} = [\underline{x}, \bar{x}].\]
The action that maximizes the true outcome is
\[x^*= \operatorname*{arg\,max}_{x \in \mathcal{X}} f_{d,\beta}(x).\]
This slide felt out of place
Realized Data
DGP
Independently of \((d, \beta)\), the sender's type is drawn as
\[\theta \in \{A, B\}, \qquad \Pr(\theta = B) = q \in [0, 1)\]
where \(A\) denotes an aligned sender and \(B\) a misaligned sender.
A misaligned sender has an optimal payoff different from the optimal of the real DGP
Sender Alignment
Sender Alignment
Sender Alignment
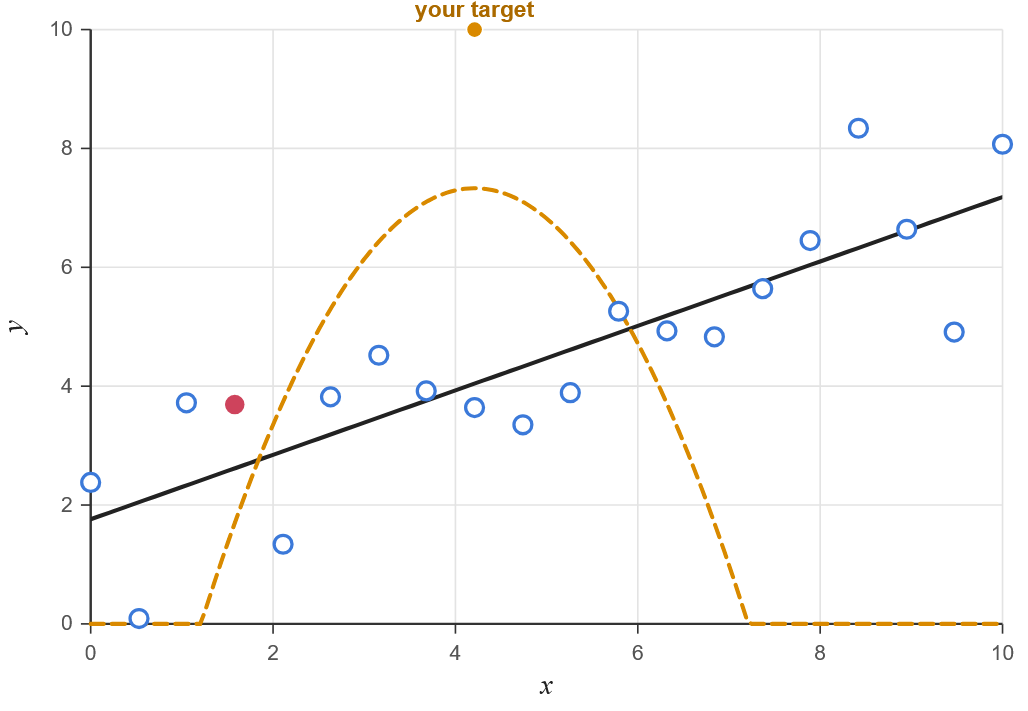
The sender communicates by disclosing a subset of the data, \(m \subseteq \mathcal{D}\).
Messages are verifiable: the sender can choose which points to disclose but cannot alter or fabricate them.
Disclosing \(|m|\) costs the sender \(c(|m|)\), where \(c : \{0, 1, \dots, N\} \to \mathbb{R}_{+}\) satisfies
\[c(0) = 0, \qquad c(n+1) - c(n) > 0, \qquad c(n+1) - c(n) \ge c(n) - c(n-1).\]
That is, cost is strictly increasing and convex in the number of points disclosed, with convexity defined by non-decreasing marginal cost since \(|m|\) is an integer.
The Message
The sender's message is constrained in 2 ways:
- A hard cap where the total cost of sending that many messages exceeds the largest possible payoff (including the optimal action)
- A soft cap where the marginal cost of an additional message exceeds the possible marginal improvement in the choice
Need to be more precise here
Let \(a(m) \in \mathcal{X}\) denote the receiver's chosen action after observing \(m\). The sender's payoff is
\[u_\theta(m) = v_\theta\left(a(m)\right) - c(|m|). \]
The sender chooses
\[m \in \operatorname*{arg\,max}_{m' \subseteq \mathcal{D}} \; u_\theta(m'). \]
The Message
The Message
The Message
The Message
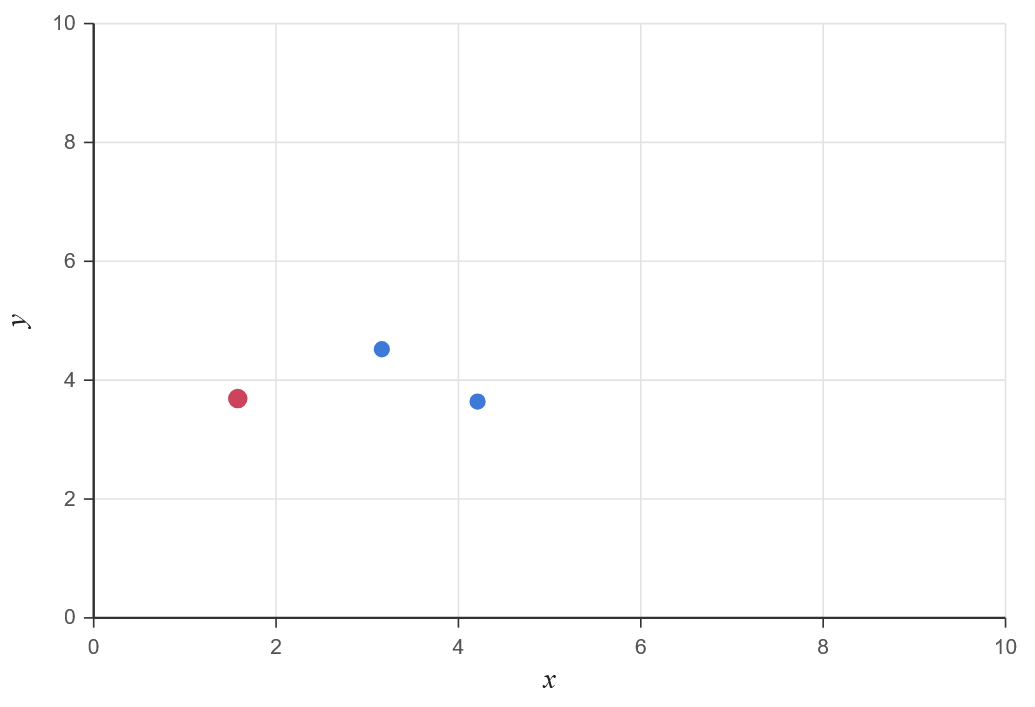
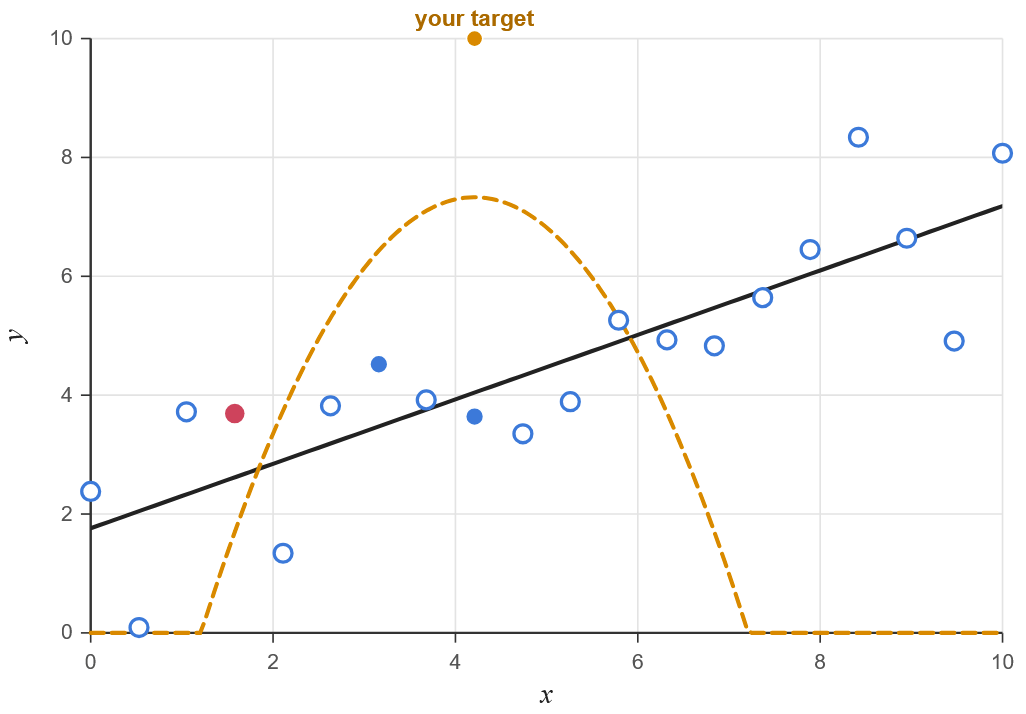
The receiver's payoff is determined by the true function underlying the DGP and the action:
\[u_R(a; d, \beta) = f_{d,\beta}(a). \]
Choosing \(a = x_s\) corresponds to remaining at the status quo, with payoff \(f_{d,\beta}(x_s)\). In every state, the receiver's most preferred action is the true optimum \(x^*\).
Since the receiver does not observe \((d, \beta)\), it evaluates actions by expected payoff under the posterior, \(\mathbb{E}_{\mu(\cdot \mid m)}\left[ f_{d,\beta}(a) \right]\).
Payoffs
The aligned sender's gross payoff from the receiver's action is
\[v_A(a; d, \beta) = f_{d,\beta}(a)- c(|m|). \]
and the aligned sender's most preferred action is also \(x^*\).
Payoffs
The misaligned sender's payoff depends on the action, the message length, and its bliss point, not on the state,
\[v_B(a; x_B) = \gamma_B - (a - x_B)^2- c(|m|),\]
Need gamma here considering it is in theory?
The misaligned sender wants the receiver at \(x_B\) regardless of the true curve, so its interests coincide with the receiver's only in states where \(x^* = x_B\), and the conflict grows with \(|x^* - x_B|\).
The bliss point is the misaligned sender's private information.
Payoffs
The Message
A strategy for a type-\(\theta\) sender is a distribution over messages for each bliss point and state, \(\rho_\theta(m \mid x_B, d, \beta, \mathcal{D})\), supported on subsets \(m \subseteq \mathcal{D}\).
After observing \(m\), the receiver holds a posterior \(\mu(d, \beta, \theta, x_B \mid m)\). This posterior defines the receiver's working model of the curve,
\[\bar{f}_m(x) = \mathbb{E}_{\mu(\cdot \mid m)}\left[ f_{d,\beta}(x) \right] = \sum_{d \in \mathcal{K}} \mu(d \mid m)\; \mathbb{E}_{\mu}\left[ f_{d,\beta}(x) \mid m, d \right], \]
and the receiver's action is the peak of that model, \(a(m) \in \operatorname*{arg\,max}_{x \in \mathcal{X}} \bar{f}_m(x)\).
Strategies
The sender influences the receiver's through the model the message induces.
It can shift beliefs about structure, \(\mu(d \mid m)\), such as whether the curve is monotone or has an interior peak, and beliefs about coefficients within a structure, which locate the peak.
The receiver can consider not only the points sent, but also what is not sent.
Strategies
Skipping some notation...
The receiver's posterior belief is a mixture of sophisticated and naive response:
\[\mu^{\omega}(\cdot \mid m) = \omega\, \mu^{N}(\cdot \mid m) + (1 - \omega)\, \mu^{S}(\cdot \mid m), \qquad \omega \in [0, 1], \]
where \(\omega\) indexes the receiver's degree of selection neglect.
Pin down and explain omega better
That is, the receiver's induced model is the corresponding mixture of models,
\[\bar{f}^{\omega}_m = \omega\, \bar{f}^{N}_m + (1 - \omega)\, \bar{f}^{S}_m\]
Equilibrium
Given the receiver's model:
\[\bar{f}^{\omega}_m = \omega\, \bar{f}^{N}_m + (1 - \omega)\, \bar{f}^{S}_m,\]
there are some special cases:
- If \( \omega =0\) the receiver fully accounts for the selective disclosure and it becomes Perfect Bayesian Equilibrium.
- If \( \omega =1\) the receiver is fully credulous and their model can be fully imposed on them by the sender directly.
Model is solved?
Equilibrium
Experiment and Predictions
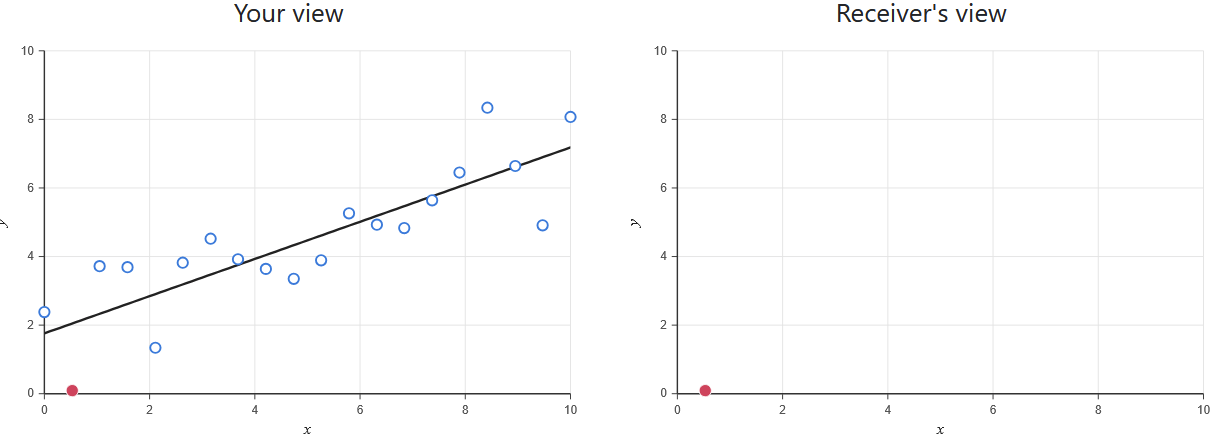
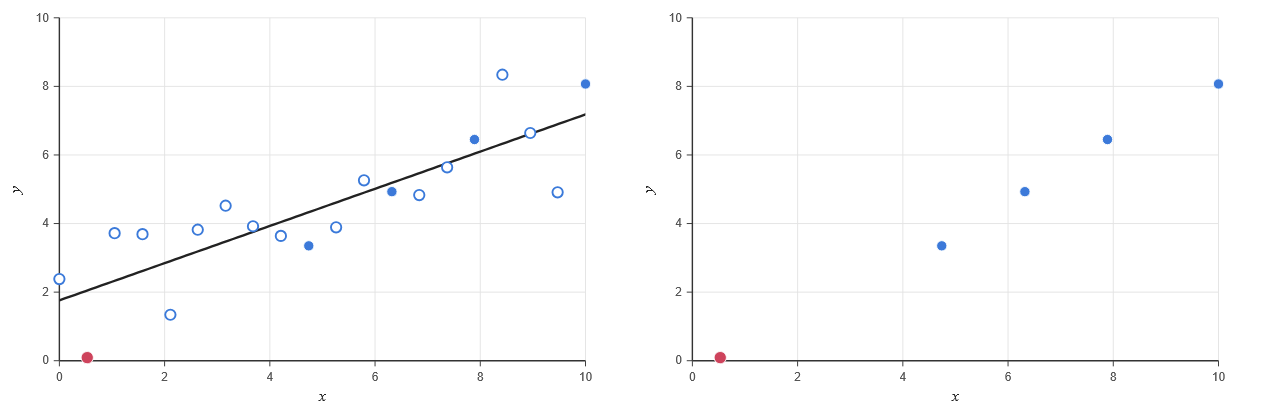
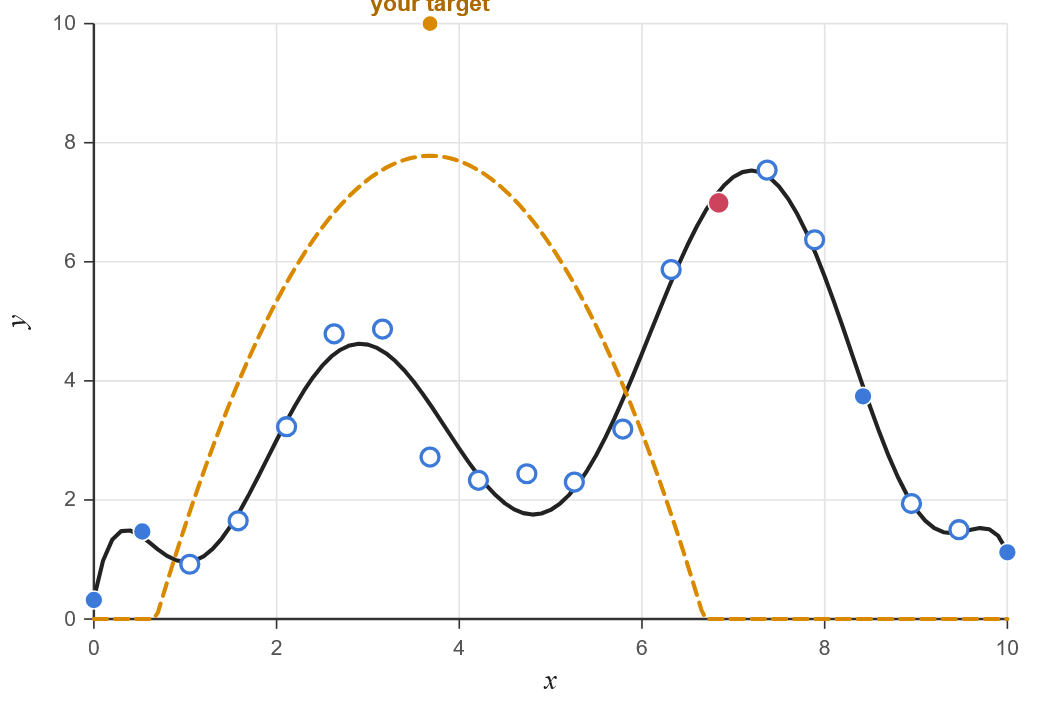
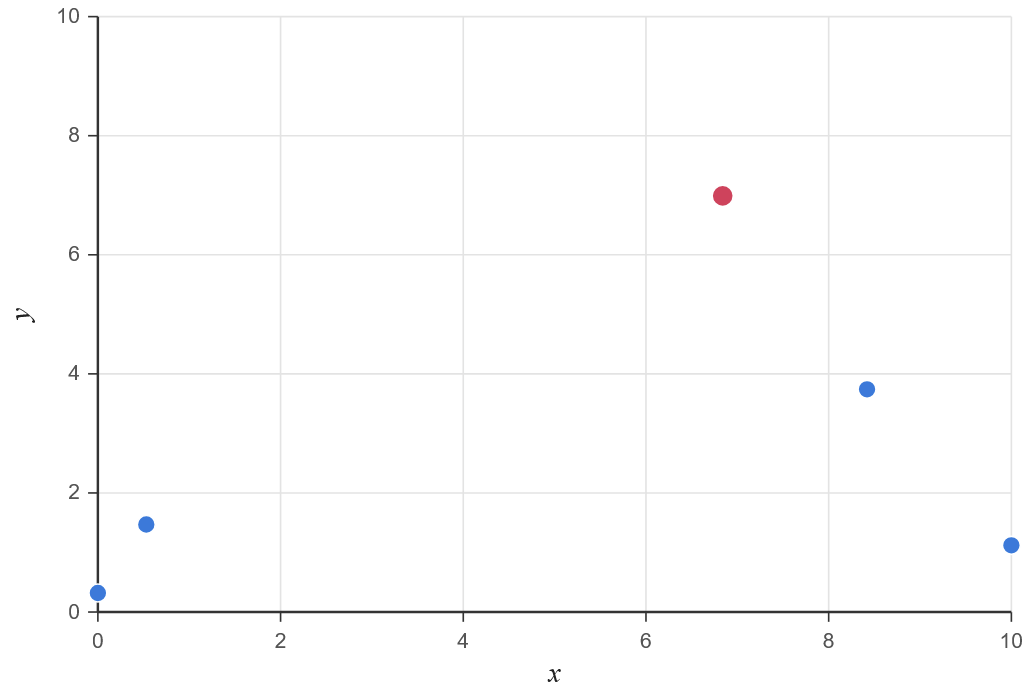
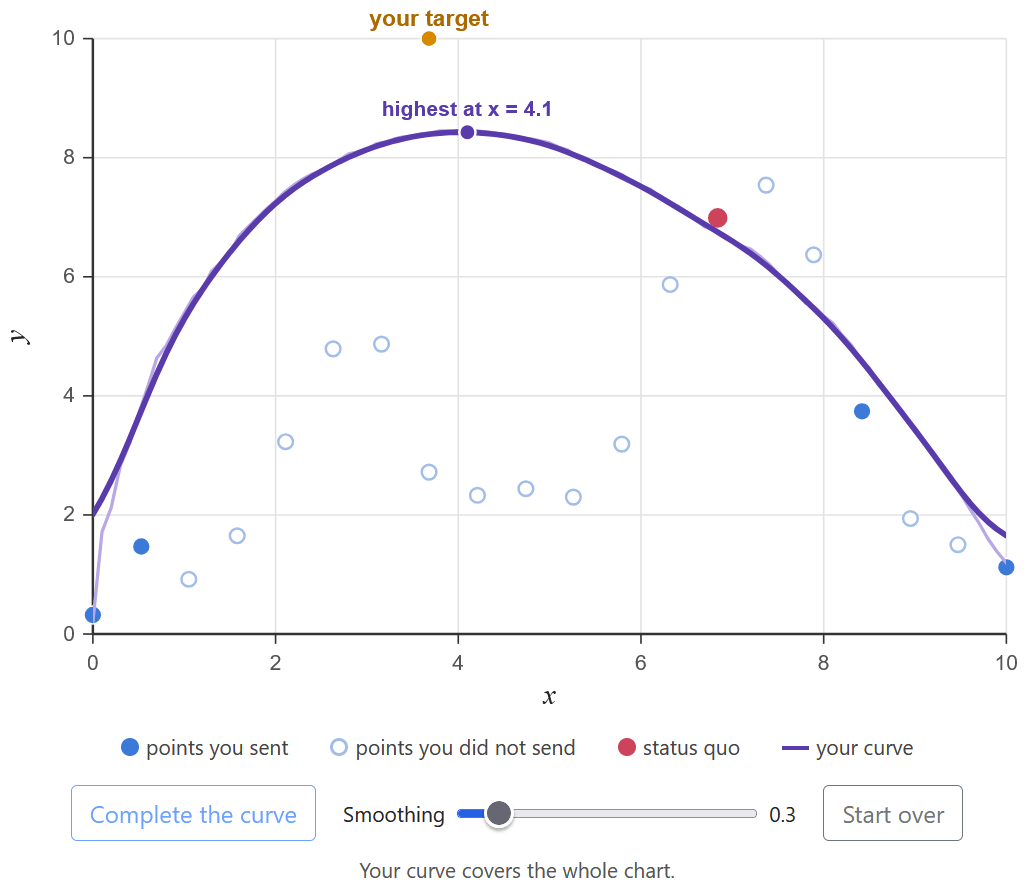
Senders have to communicate to receivers the optimal policy choice using data
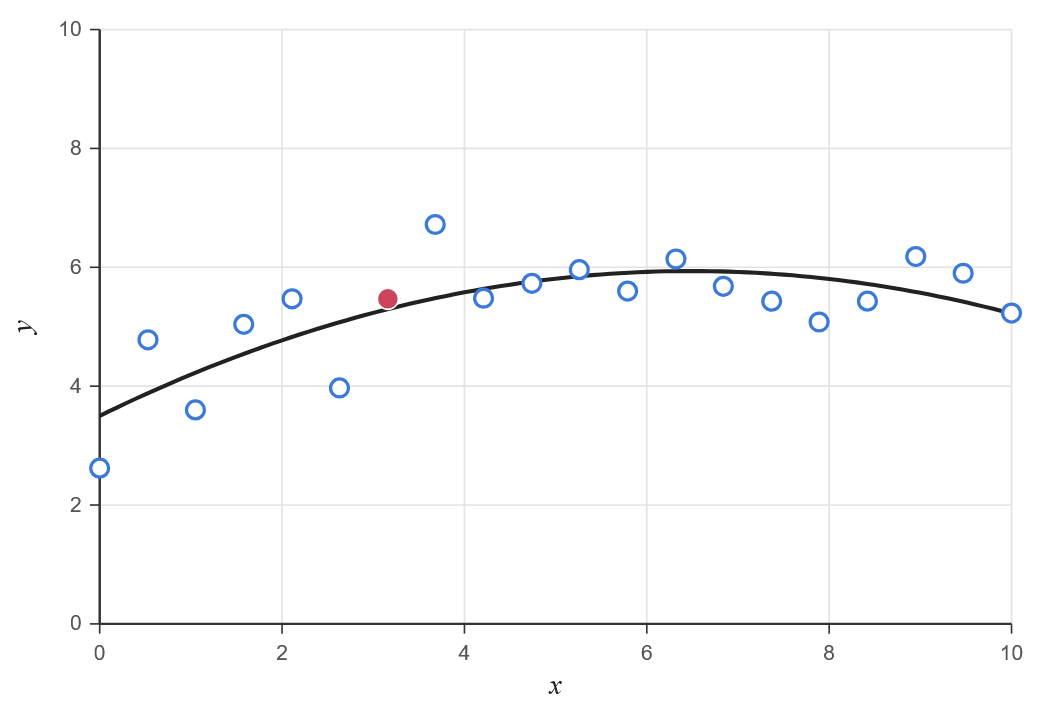
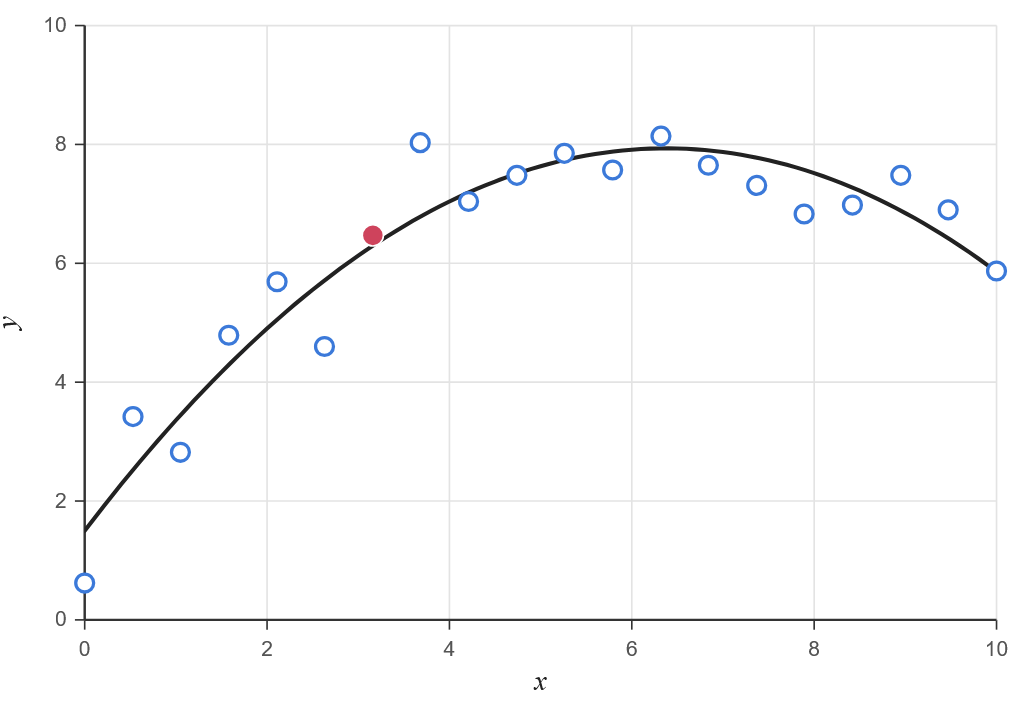
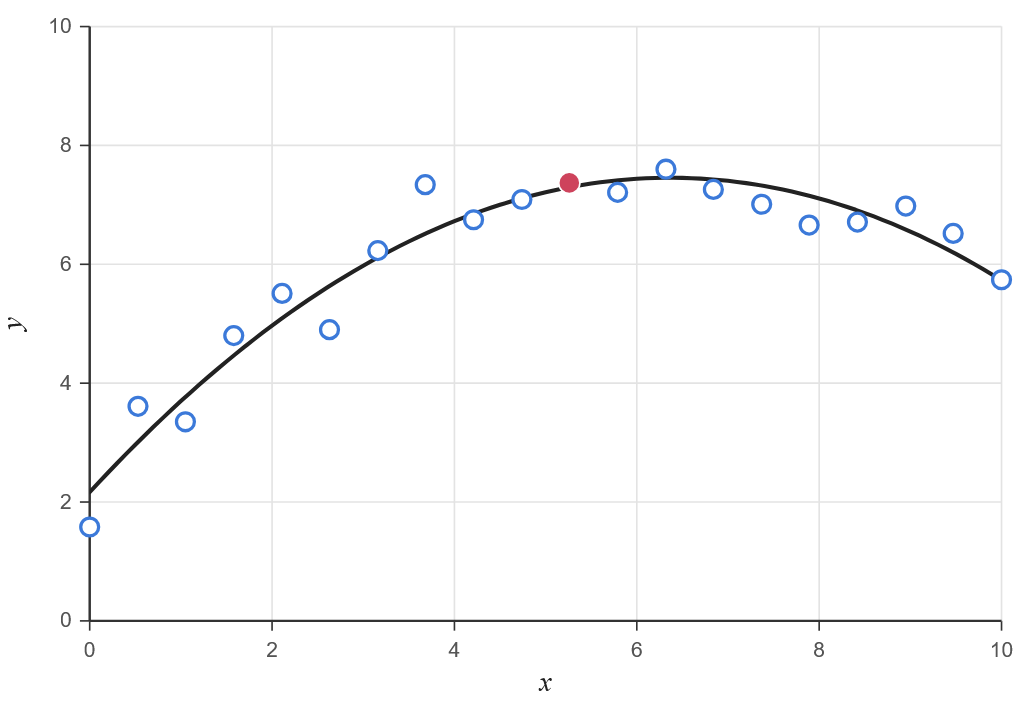
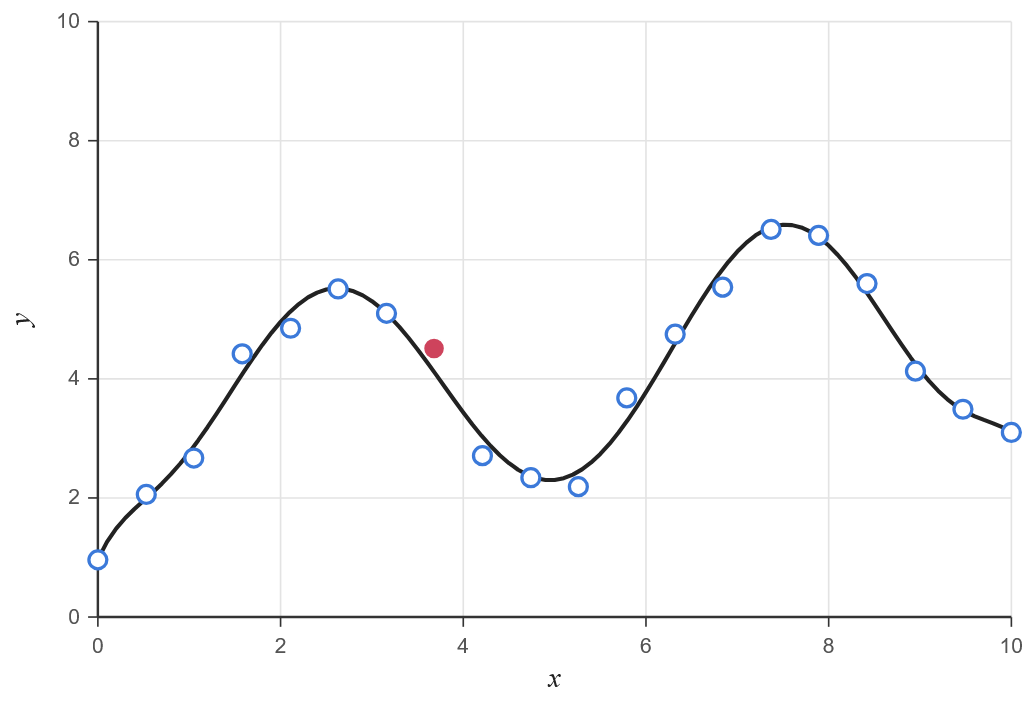
The signals are displayed as points in the plot
Easiest (but not trivial) case: guaranteed aligned senders
Experiment
Experiment
Experiment
Experiment
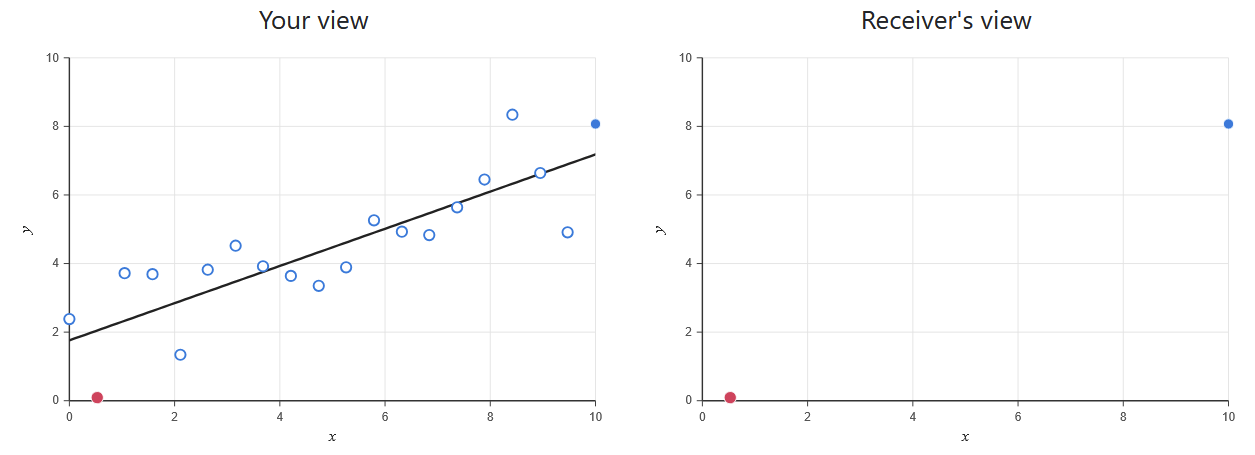
Prediction 1: for non-corner solutions, three signals is sufficient for an optimal choice. For corner solutions, one signal is sufficient.
Prediction 1a: senders will send more signals than is sufficient, even when they do not need to signal credibility
Experiment
Set the probability of a misaligned sender >0 and receivers should adopt a sophisticated approach
Introducing misaligned senders "poisons the well"
Prediction 2: average \(|m|\) increases when misaligned senders are introduced, and \(|m_A|\geq |m_B|\)
Experiment
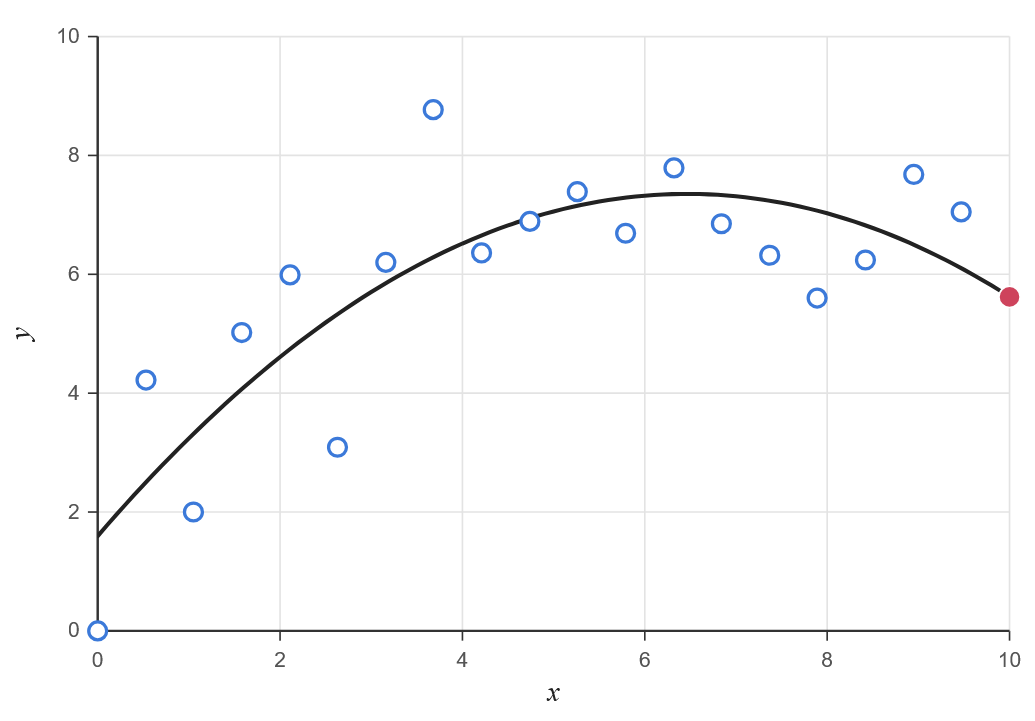
Two factors which increase the scope for misleading data transmission: total variation of \(y\) and noise \(\sigma \).
Prediction 3: Receivers will make worse decisions when total variation of \(y\) and noise \(\sigma \) increase:
\[ TV(y) \Rightarrow \uparrow |a-x^*| \]
\[ \uparrow \sigma \Rightarrow \uparrow |a-x^*| \]
Experiment
Experiment
Experiment
What can we learn about senders?
What models do senders hope to induce in receivers?
What can we learn about senders?
What can we learn about senders?
What can we learn about senders?
What can we learn about senders?
What models do senders hope to induce in receivers?
Remove other-regarding: can senders identify an optimal strategy when playing against an algorithm?
What can we learn about receivers?
Do receivers have a baseline preference for model type/simplicity?
- Elicit their bias-variance tradeoff (Frechette, Vespa, Yuksel, 2026) from random data
What model do they suspect for the data?
Measure the \(\omega \)-level for each receiver: to what degree are the sophisticated about possible distortions by biased senders?
Remove other-regarding: do they make the same choice when choosing over equivalent lottery?
How to map this to natural language rhetoric?
Current prototype: senders can construct paragraph of information using pre-written verifiable statements about the data
- Point descriptions
- Local changes
- Summary statistics (by region)
Alternative: local LLM that checks free text for accuracy
Thank You!