Retrieval-Augmented Generation (RAG)
Retrieval
Learning Outcome
4
Choose the right k value and diagnose retrieval issues.
3
Recognize re-ranking, hybrid search, and metadata filtering.
2
Identify the retrieval process from query to top-k results.
1
Understand retrieval and its role in RAG.
Vector Indexing organizes embeddings for fast search.
Common methods include ANN and graph-based indexing.
Indexing avoids comparing with every stored vector.
Embeddings are now stored and organized efficiently.
Next, Retrieval finds relevant information for a user query.
Recall
Imagine asking a skilled librarian a specific question.
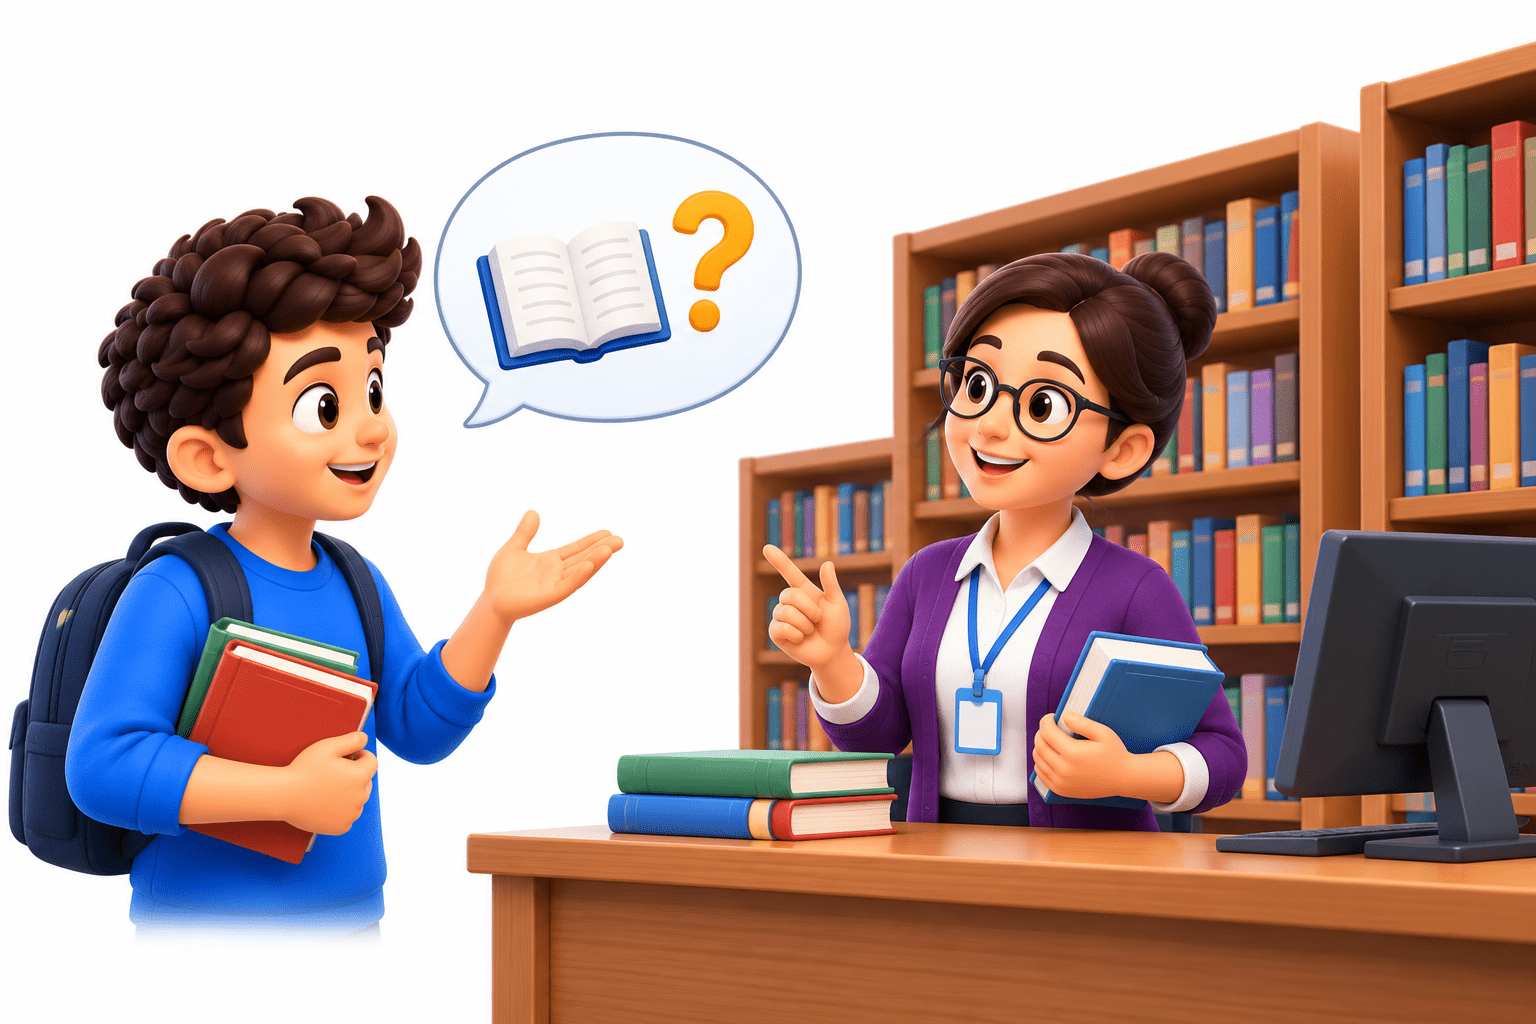
A poor librarian finds something with matching words.
A skilled librarian understands your actual question.
They compare multiple relevant sources.
They give you the most useful pages, not an entire shelf.
Similarly, Retrieval finds the most relevant chunks for a user’s query.
Skilled Librarian → Right Pages | Retrieval → Right Chunks
Previously, we imagined a poor librarian handing over a loosely related book versus a skilled librarian handing over exactly the right pages.
If a system simply matched a query against document chunks based only on a few shared words, would it reliably find the chunks that are actually most relevant in meaning?
Not always — matching on shared words alone can miss genuinely relevant information that uses different wording, or surface chunks that share words but aren't actually useful.
The librarian was just an easy example to help us understand the idea. Now let's break down what Retrieval really is.
What is Retrieval?
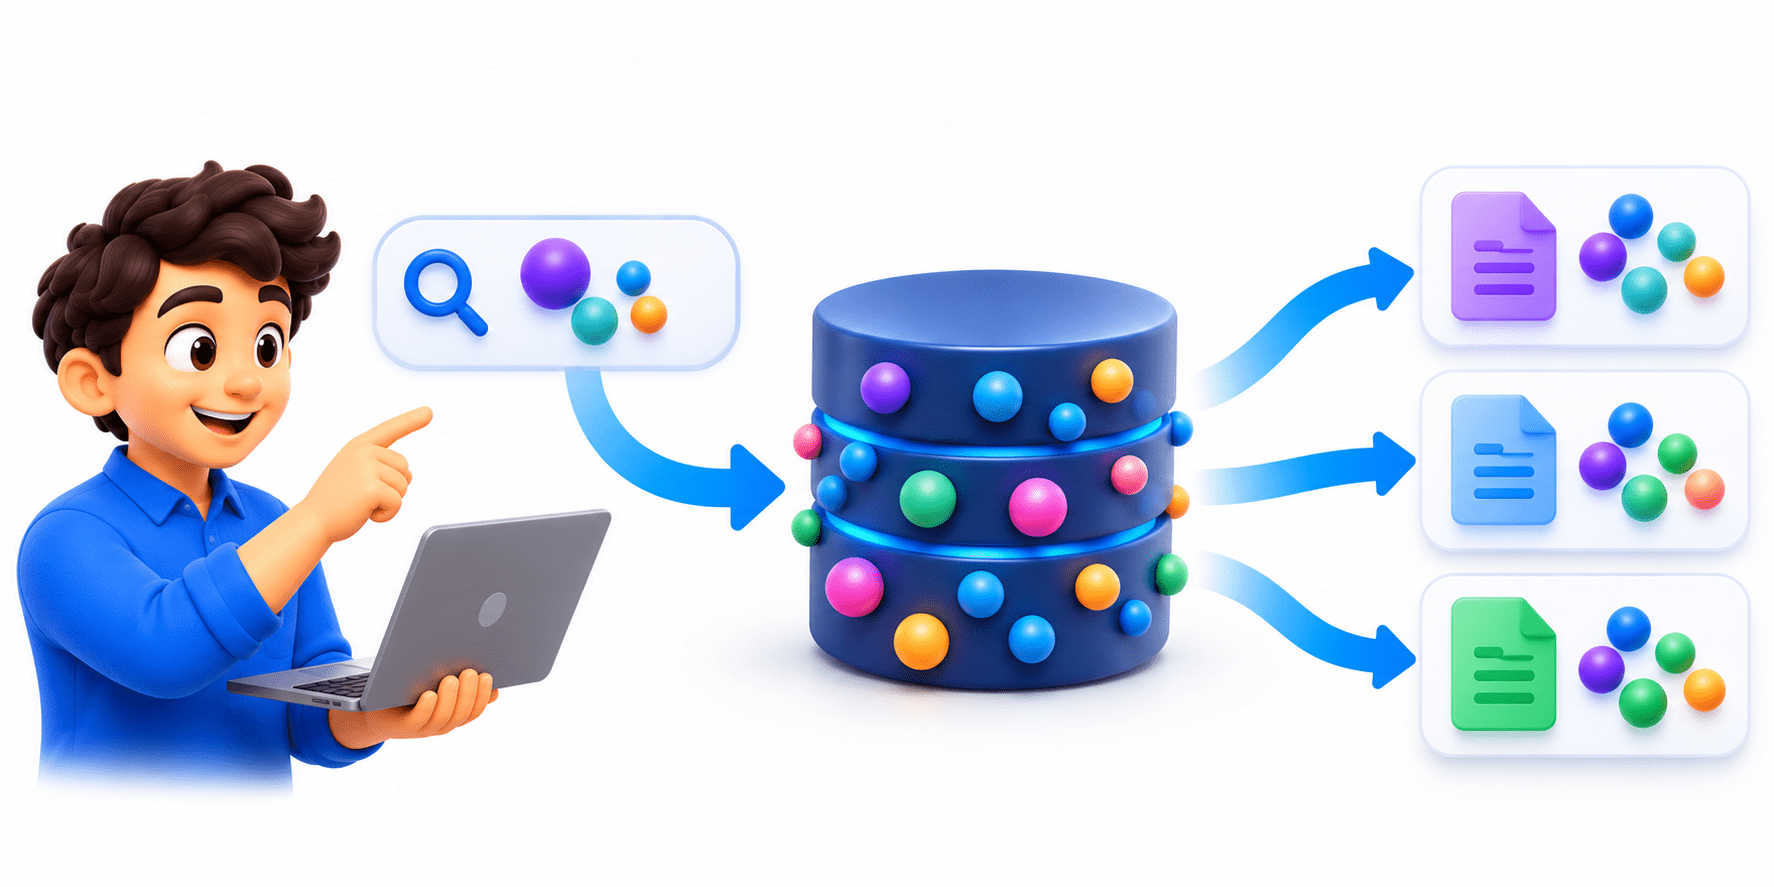
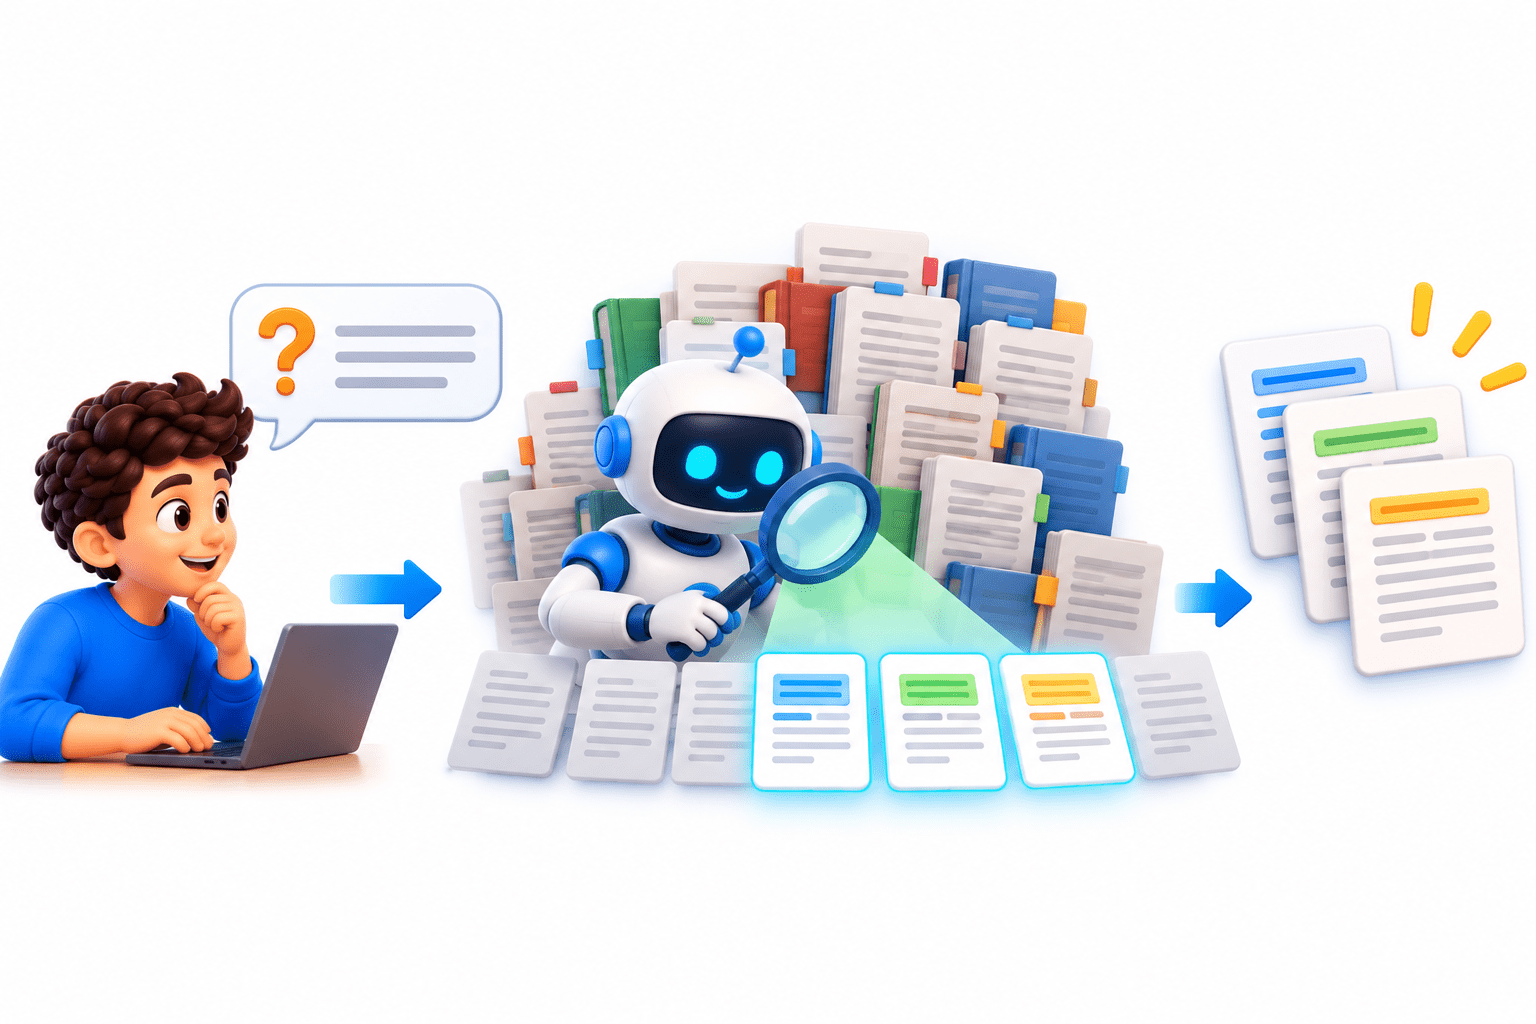
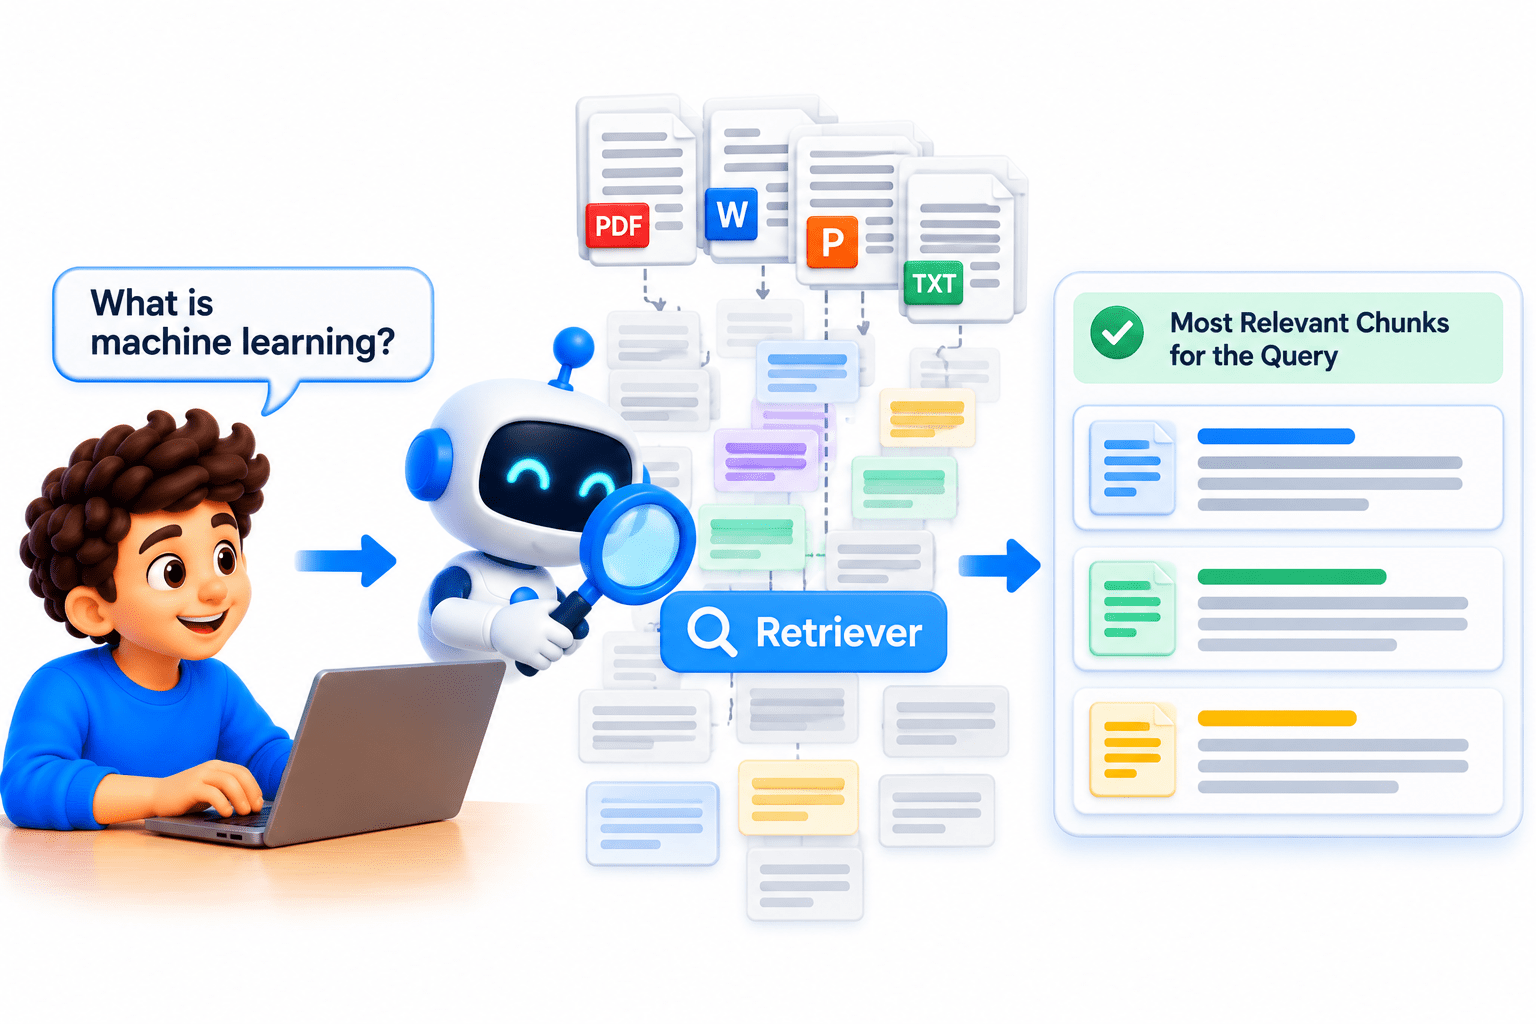
Retrieval finds the most relevant information for a user’s query.
The user query is converted into an embedding.
The embedding is searched against the vector index.
The most similar and relevant chunks are retrieved.
These chunks are combined with the query and sent to the LLM for response generation.
The Retrieval Process, Step by Step
Query Embedding
Convert the user’s query into an embedding using the same embedding model.
Similarity Search
Compare the query embedding with indexed chunk embeddings.
query_embedding = model.encode(user_query)Top-k Selection
Return only the top-k most relevant chunks.
Pass Results Forward
Send retrieved chunks to the augmentation step for response generation.
results = collection.query(query_embeddings=[query_embedding], n_results=5)Why Simple Similarity Search Isn't Always Enough
Hybrid Search
- Re-evaluates retrieved chunks for better relevance
- Re-orders them to place the most useful chunks first
Re-ranking
- Combines vector similarity + keyword search.
- Helps find important exact terms, such as product codes or legal terms.
Metadata filtering
- Uses structured information to narrow the search
- Filters by department, date range, or document type.
- Helps retrieve more relevant chunks efficiently.
Getting the Value of k Right
Too Few Chunks
May miss relevant information, causing incomplete answers.
Too Many Chunks
Adds irrelevant information, increasing cost and reducing response quality.
Choose a balanced k value for relevant and focused retrieval.
Retrieval at a Glance
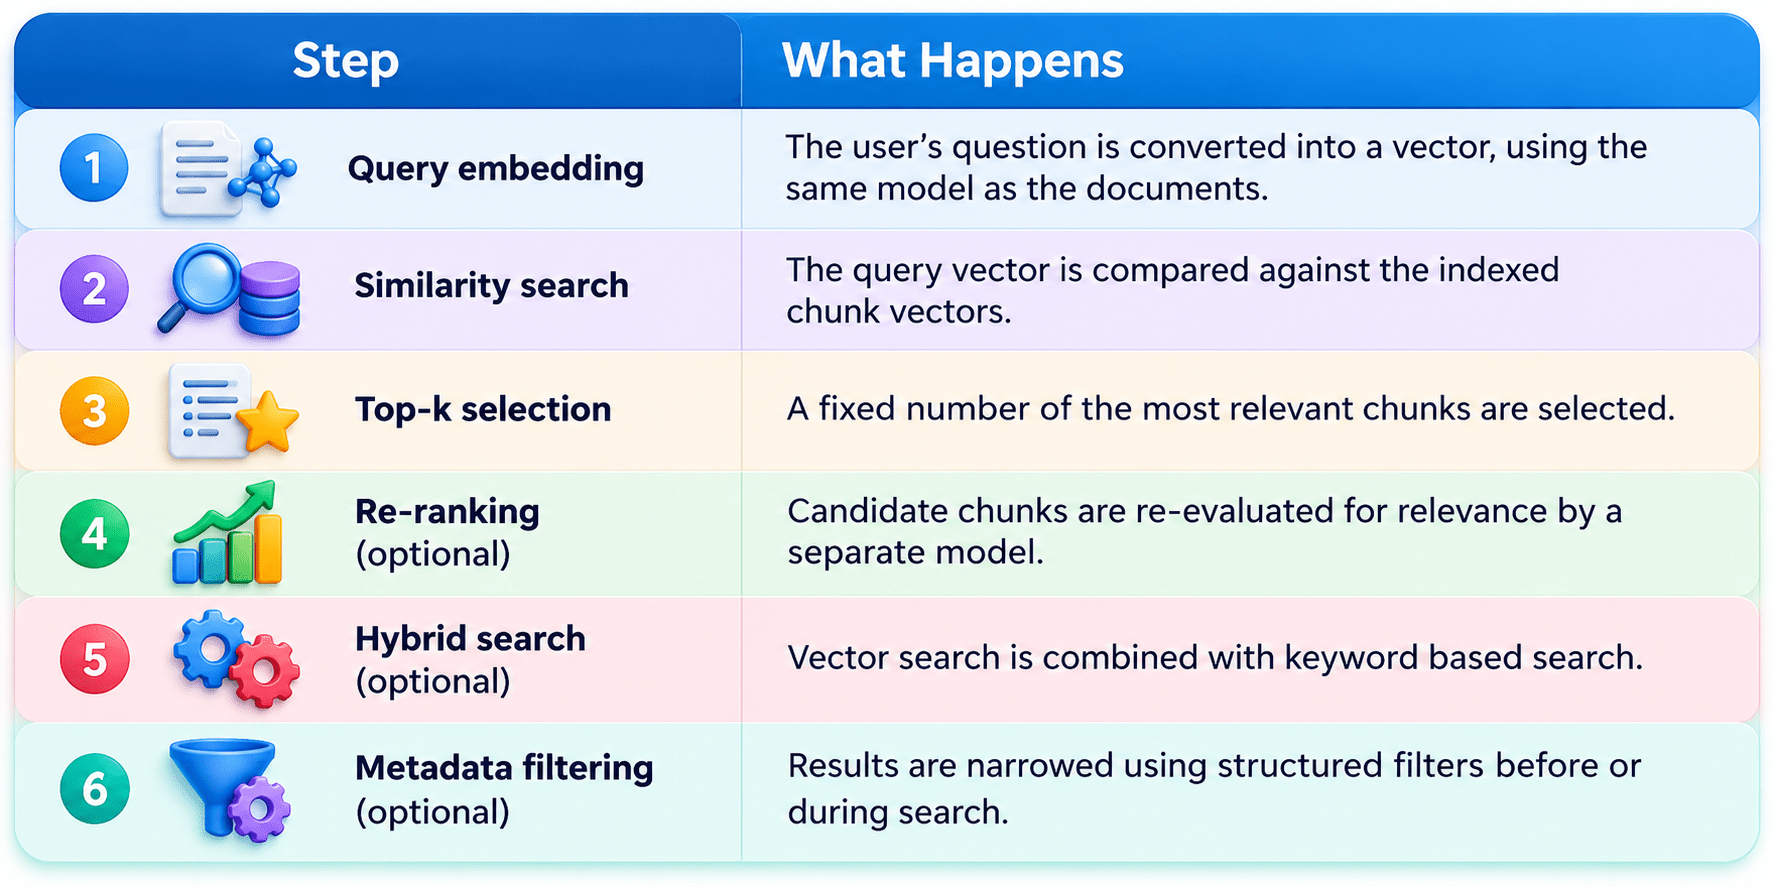
Retrieval at a Glance
Identify the problem
Find which retrieval step is causing it.
Missing relevant chunks
Increase k, use Hybrid Search, or Re-ranking.
Too many irrelevant chunks
Reduce k or improve similarity search.
Apply the right refinement based on the retrieval problem.
Retrieval quality depends on the query, k value, and retrieval refinements.
Applications of Retrieval
02
03
04
01
Customer Support
Find the right policy or troubleshooting guide.
Legal Research
Retrieve relevant clauses or case precedents.
Healthcare
Find relevant clinical guidelines or patient information.
Enterprise Search
Surface the right internal documents or reports.
An Easy Way to Remember
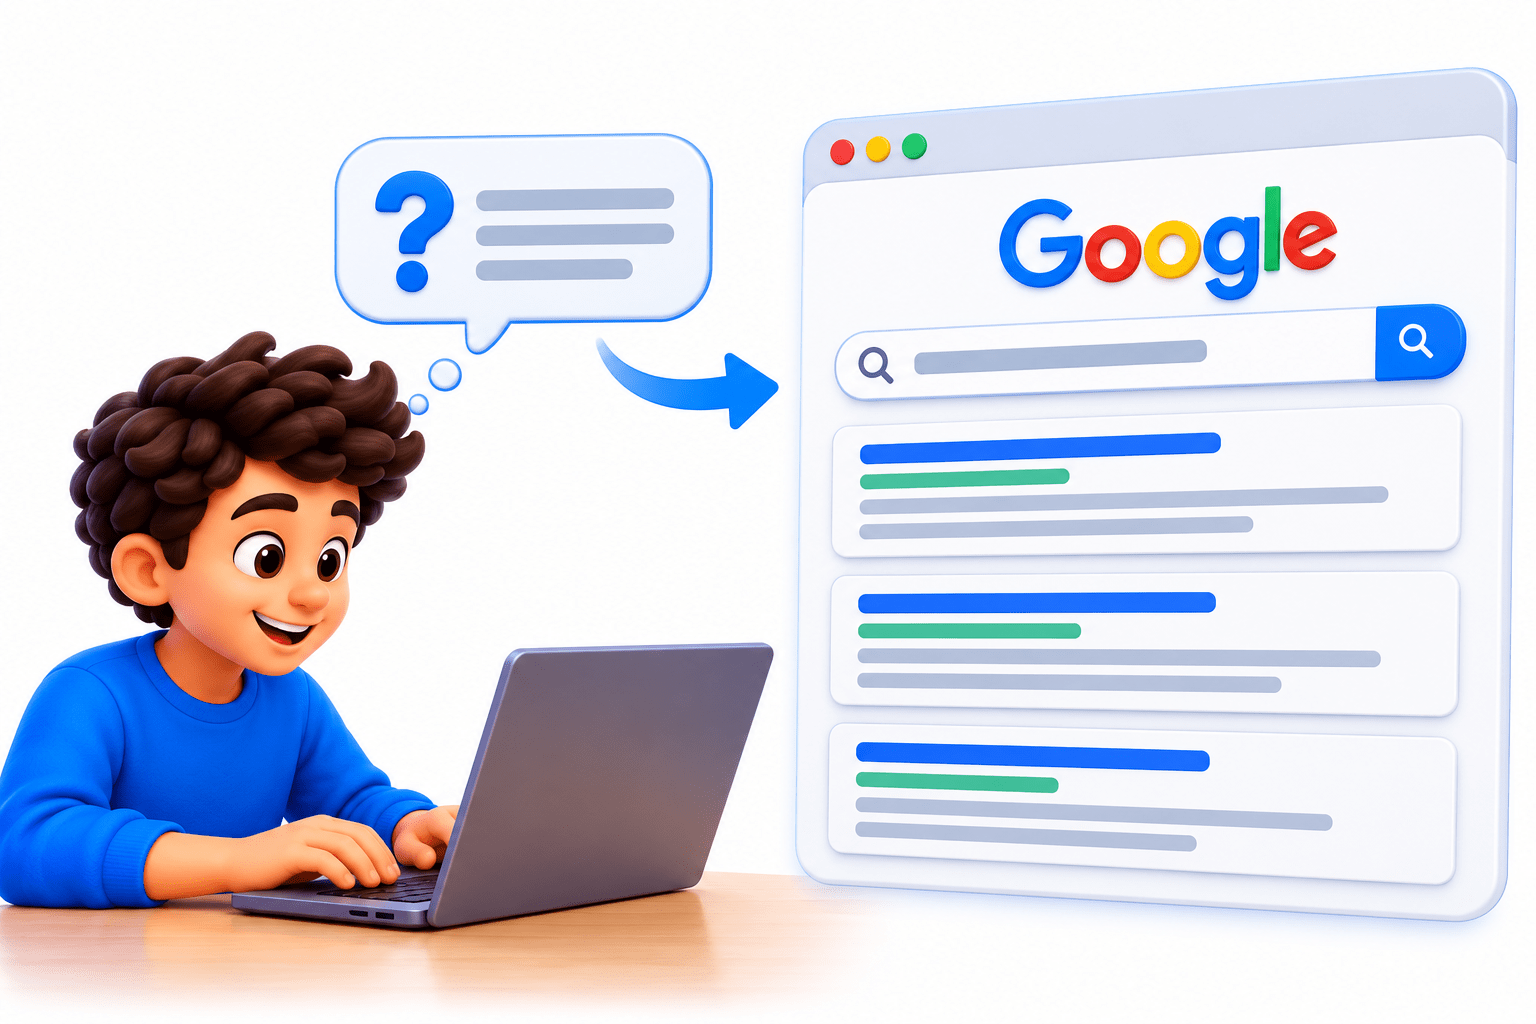
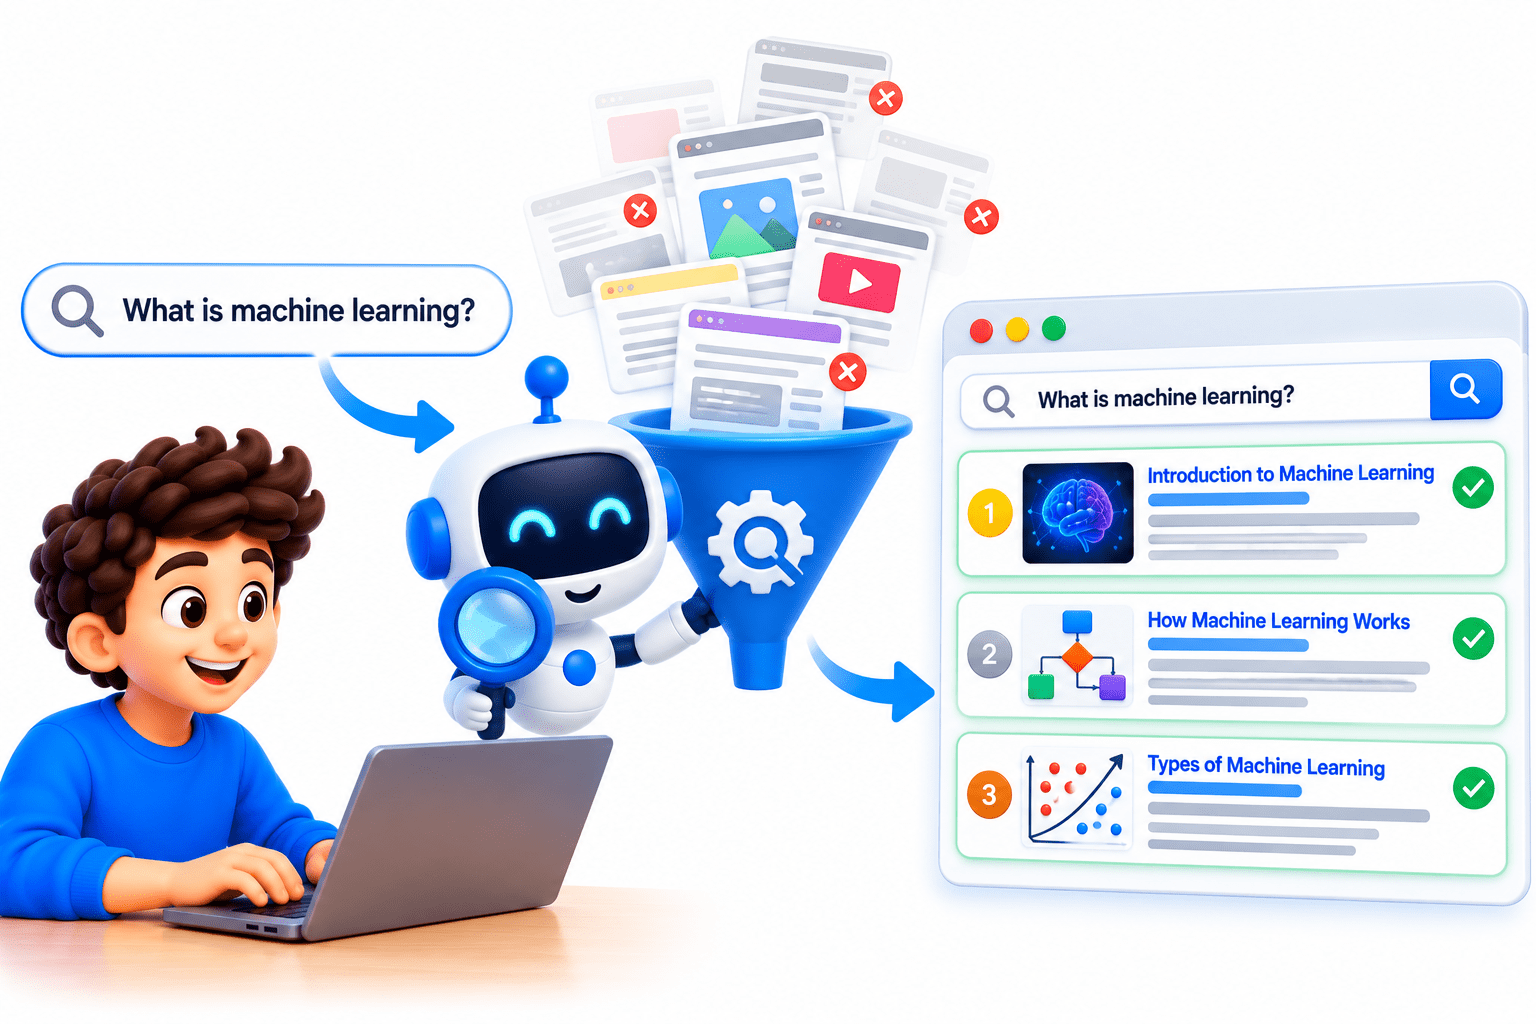
Imagine asking a search engine a question.
A weak search engine gives loosely related pages.
A good search engine understands your query.
It ranks results by relevance.
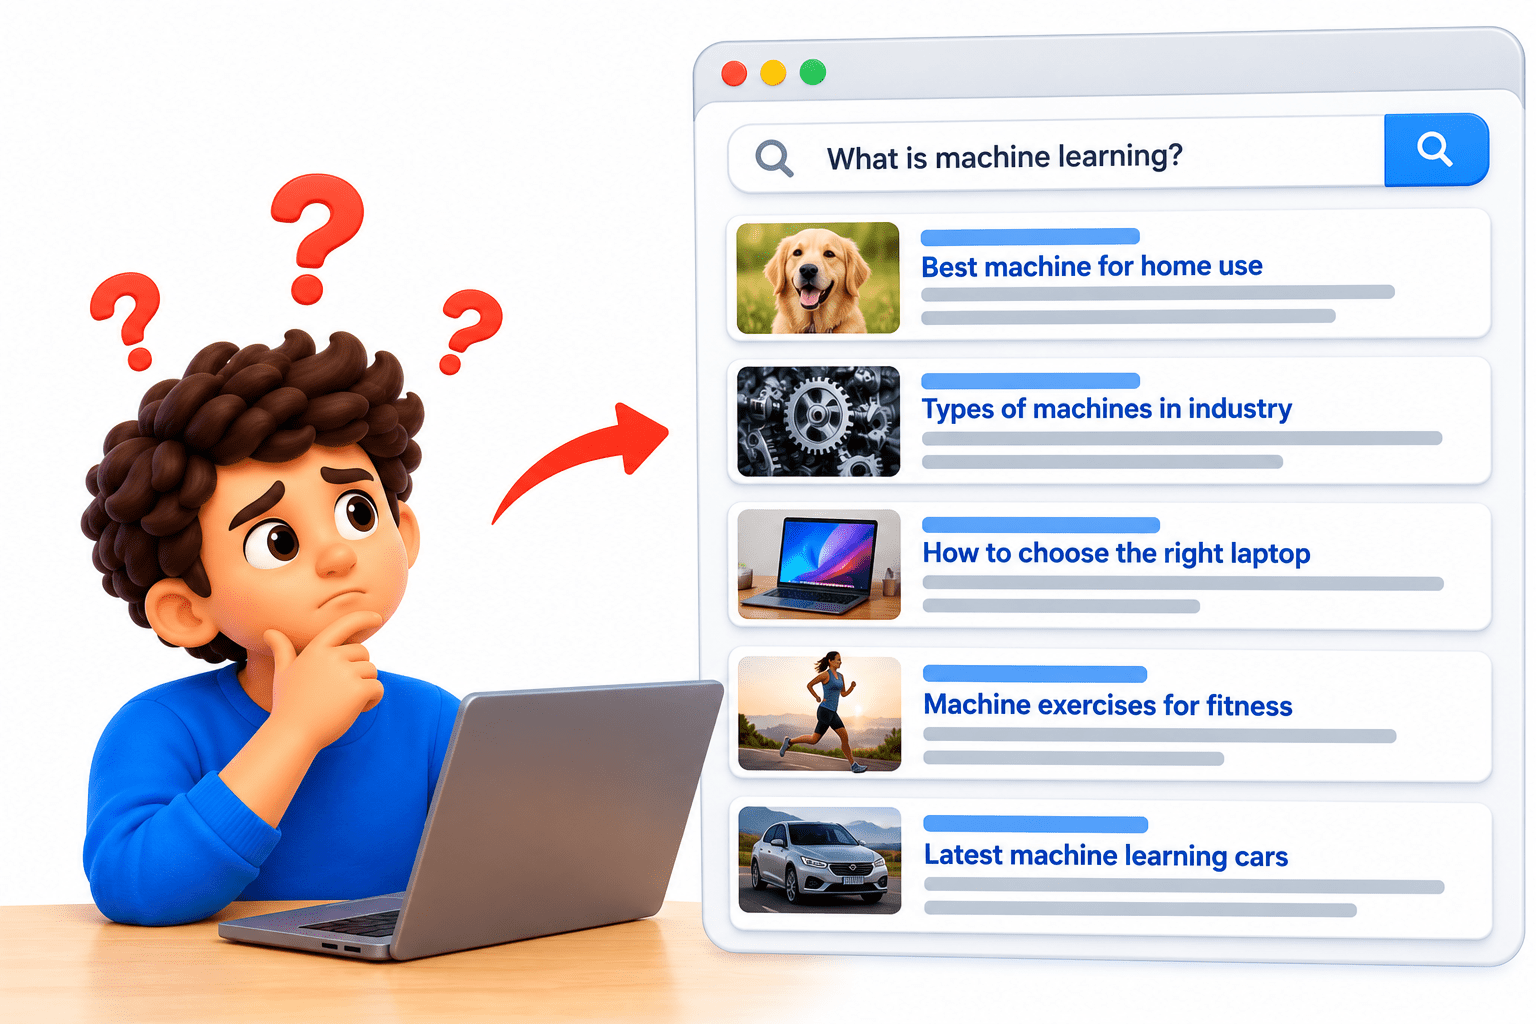
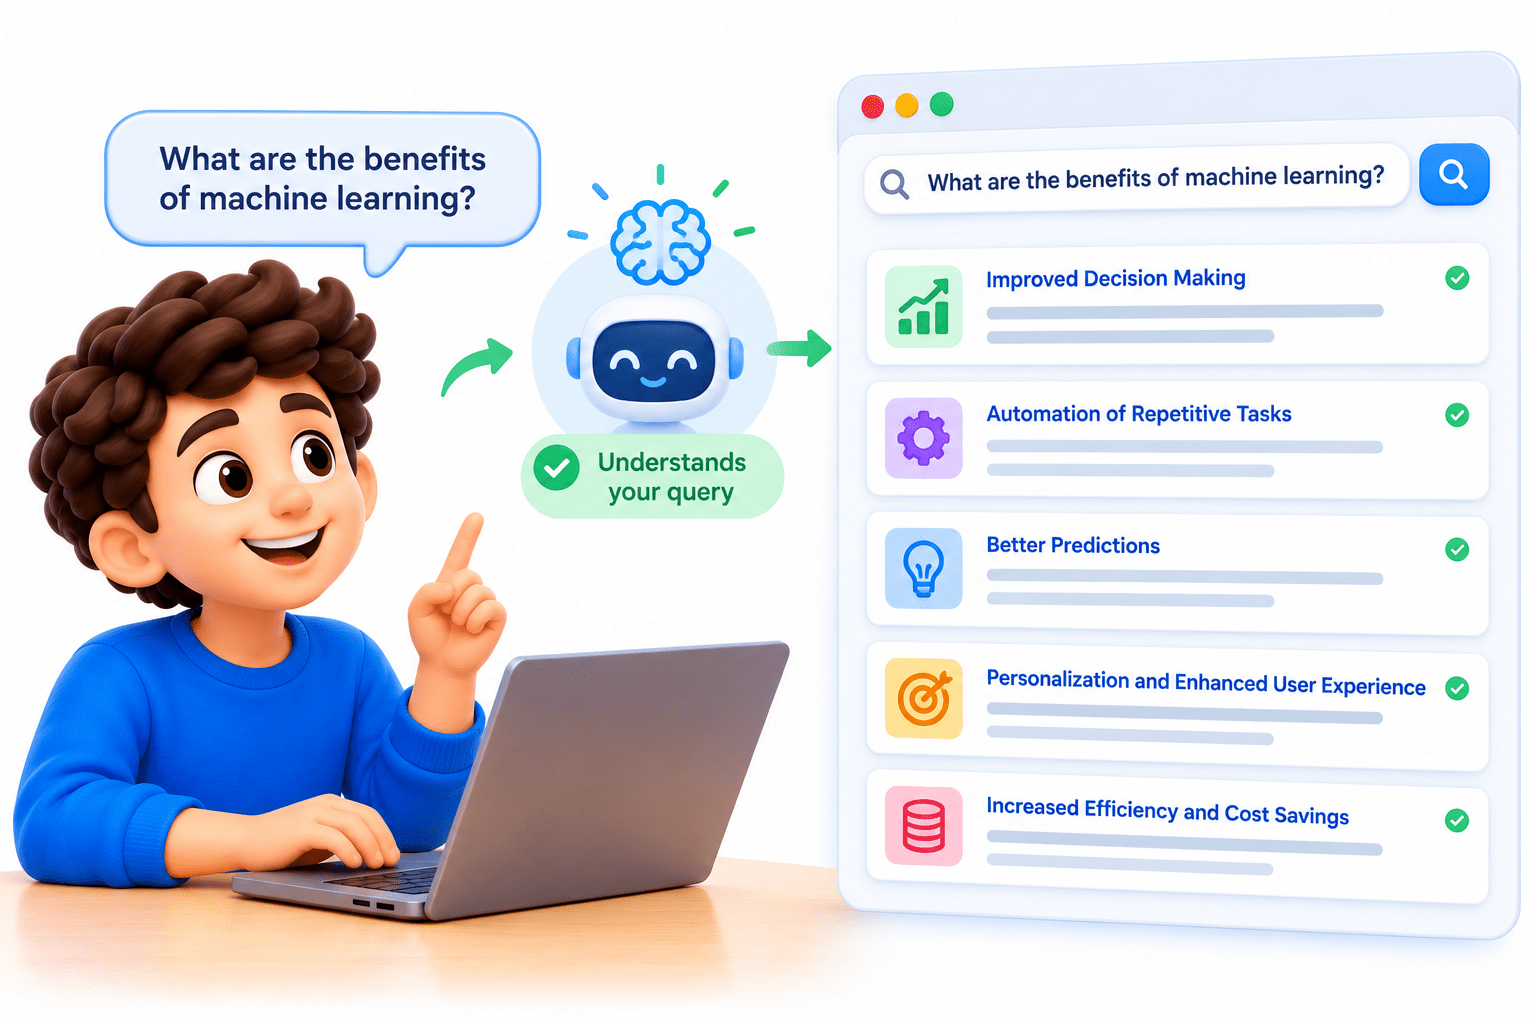
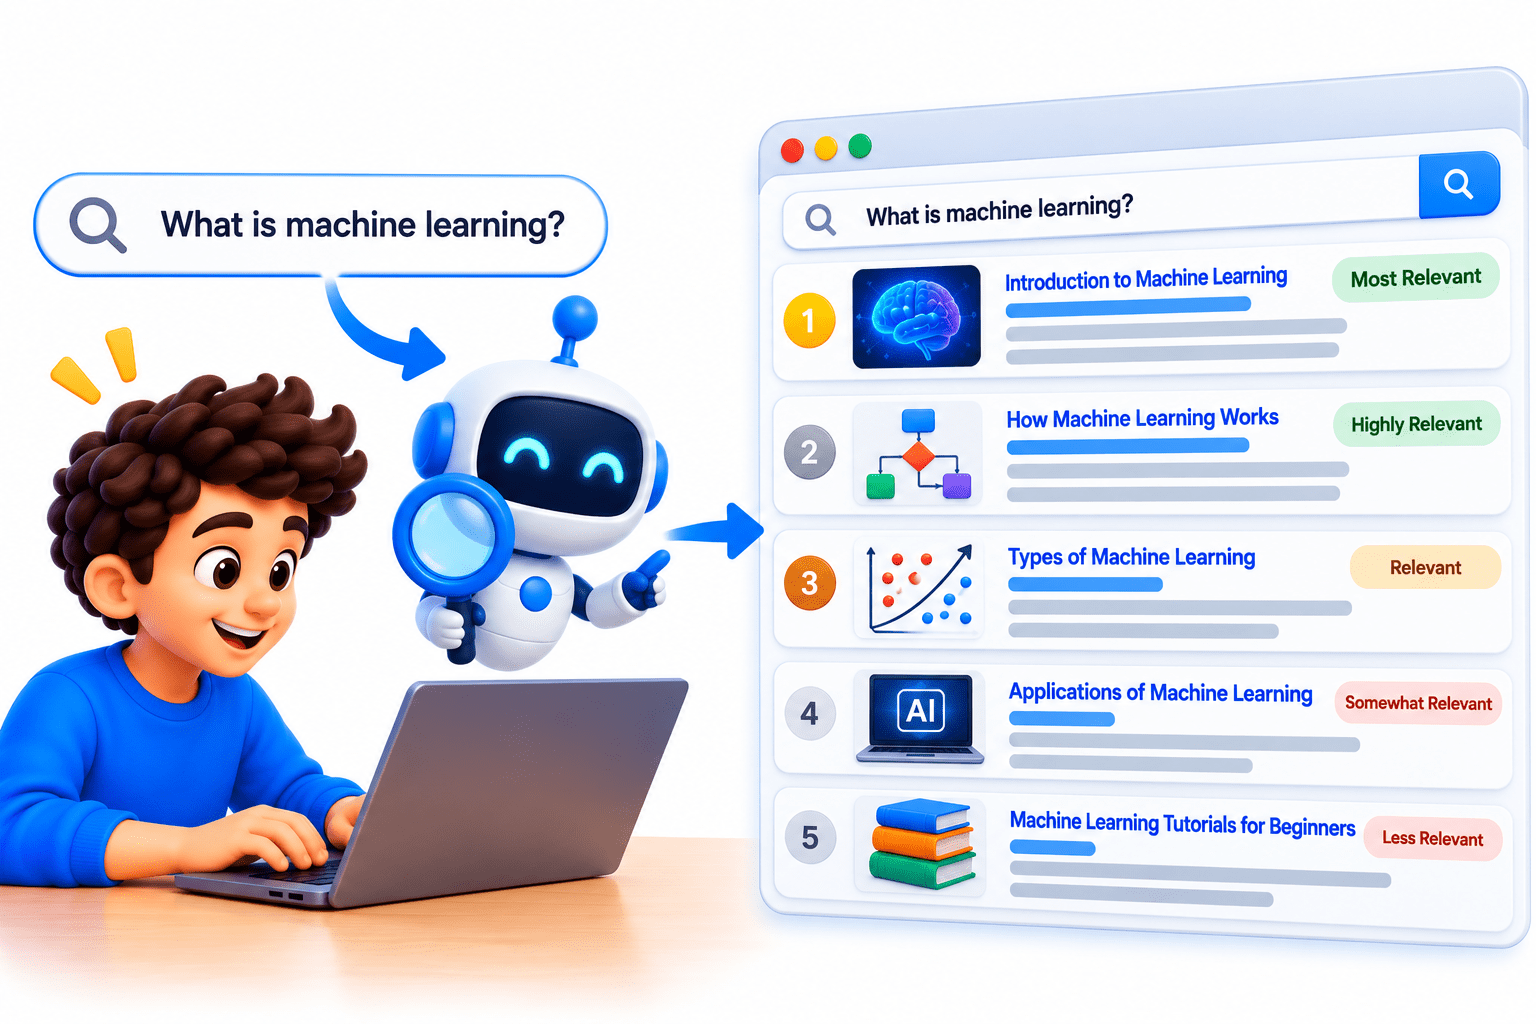
It returns only the most useful pages.
Similarly, Retrieval finds the most relevant chunks for the query.
Good Search Engine → Right Pages | Retrieval → Right Chunks
An Easy Way to Remember
Support Chatbot
Retrieves the exact help article.
Research Database Finds papers with related terminology.
Note-Taking App Resurfaces the most relevant note.
Company Wiki
Finds the most relevant internal page.
Summary
5
Right k balances quality and relevance.
4
Hybrid & Metadata Search improve accuracy.
3
Re-ranking improves relevance.
2
Flow: Embed → Search → Top-k → Results.
1
Retrieval finds relevant chunks.
Quiz
Which technique combines semantic similarity with keyword-based search?
A. Re-ranking
B. Metadata Filtering
C. Hybrid Search
D. Top-k Selection
Which technique combines semantic similarity with keyword-based search?
A. Re-ranking
B. Metadata Filtering
C. Hybrid Search
D. Top-k Selection
Quiz-Answer