Retrieval-Augmented Generation (RAG)
Vector Indexing
Learning Outcome
4
Choose the right indexing approach for different use cases
3
Recognize common vector indexing approaches.
2
Identify vector similarity methods.
1
Understand vector indexing and its importance.
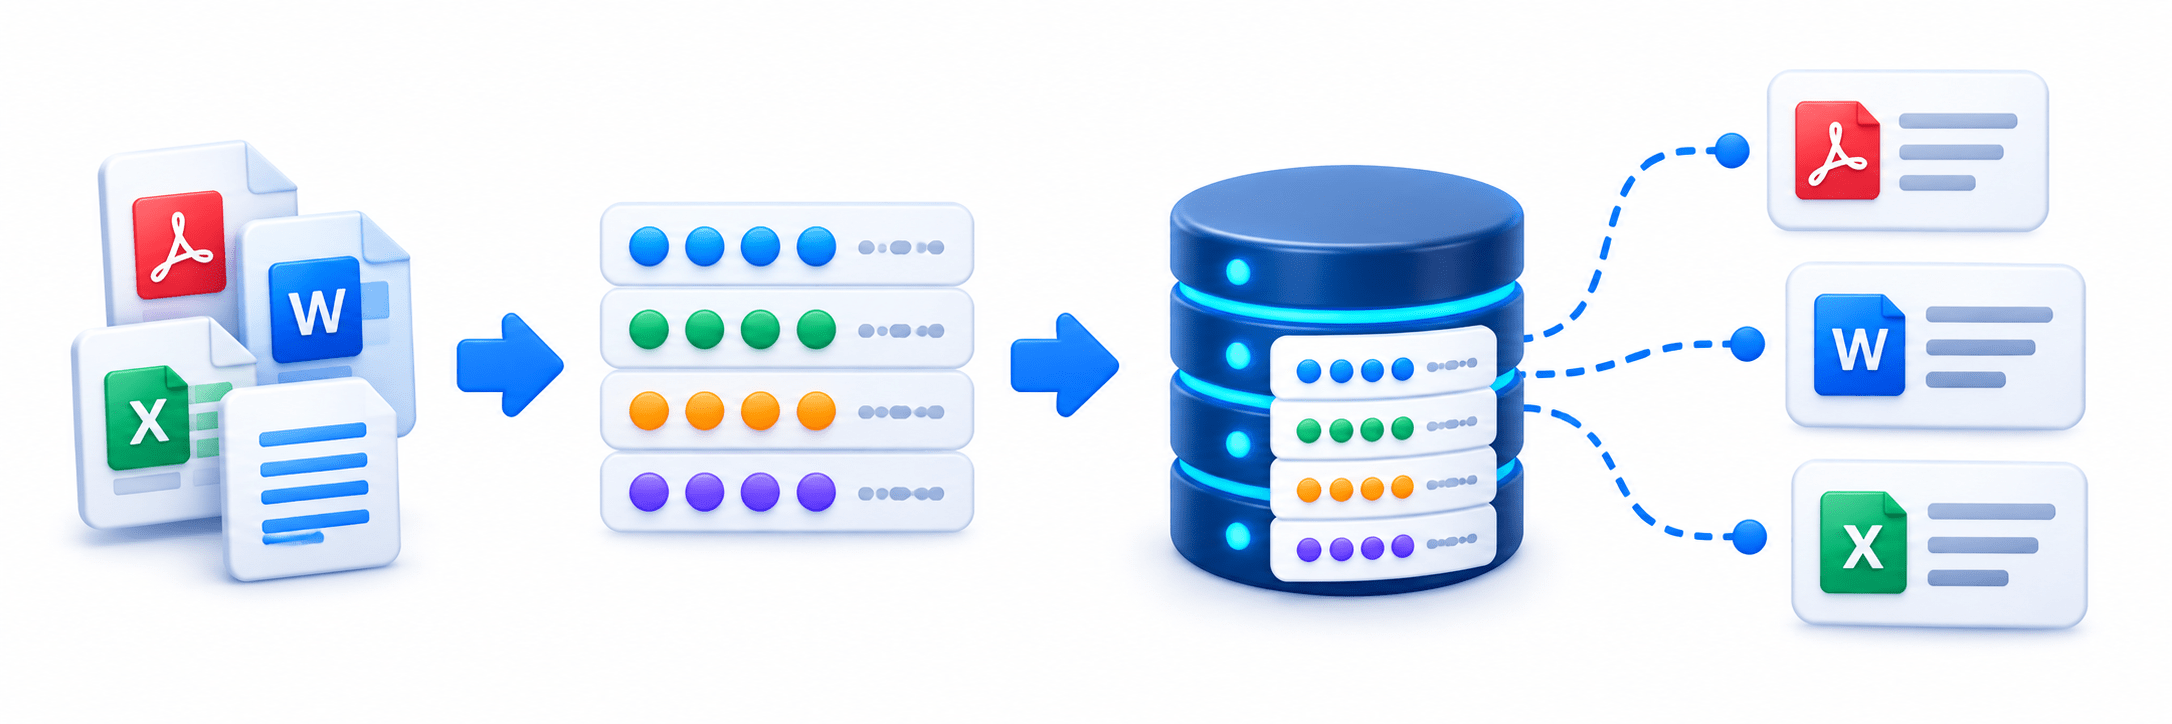
Documents are first loaded and cleaned.
Large documents are divided into smaller chunks.
Each chunk is converted into an embedding.
Millions of embeddings make searching difficult and slow.
Vector Indexing enables fast and relevant retrieval.
Recall
Imagine a huge library with millions of books.
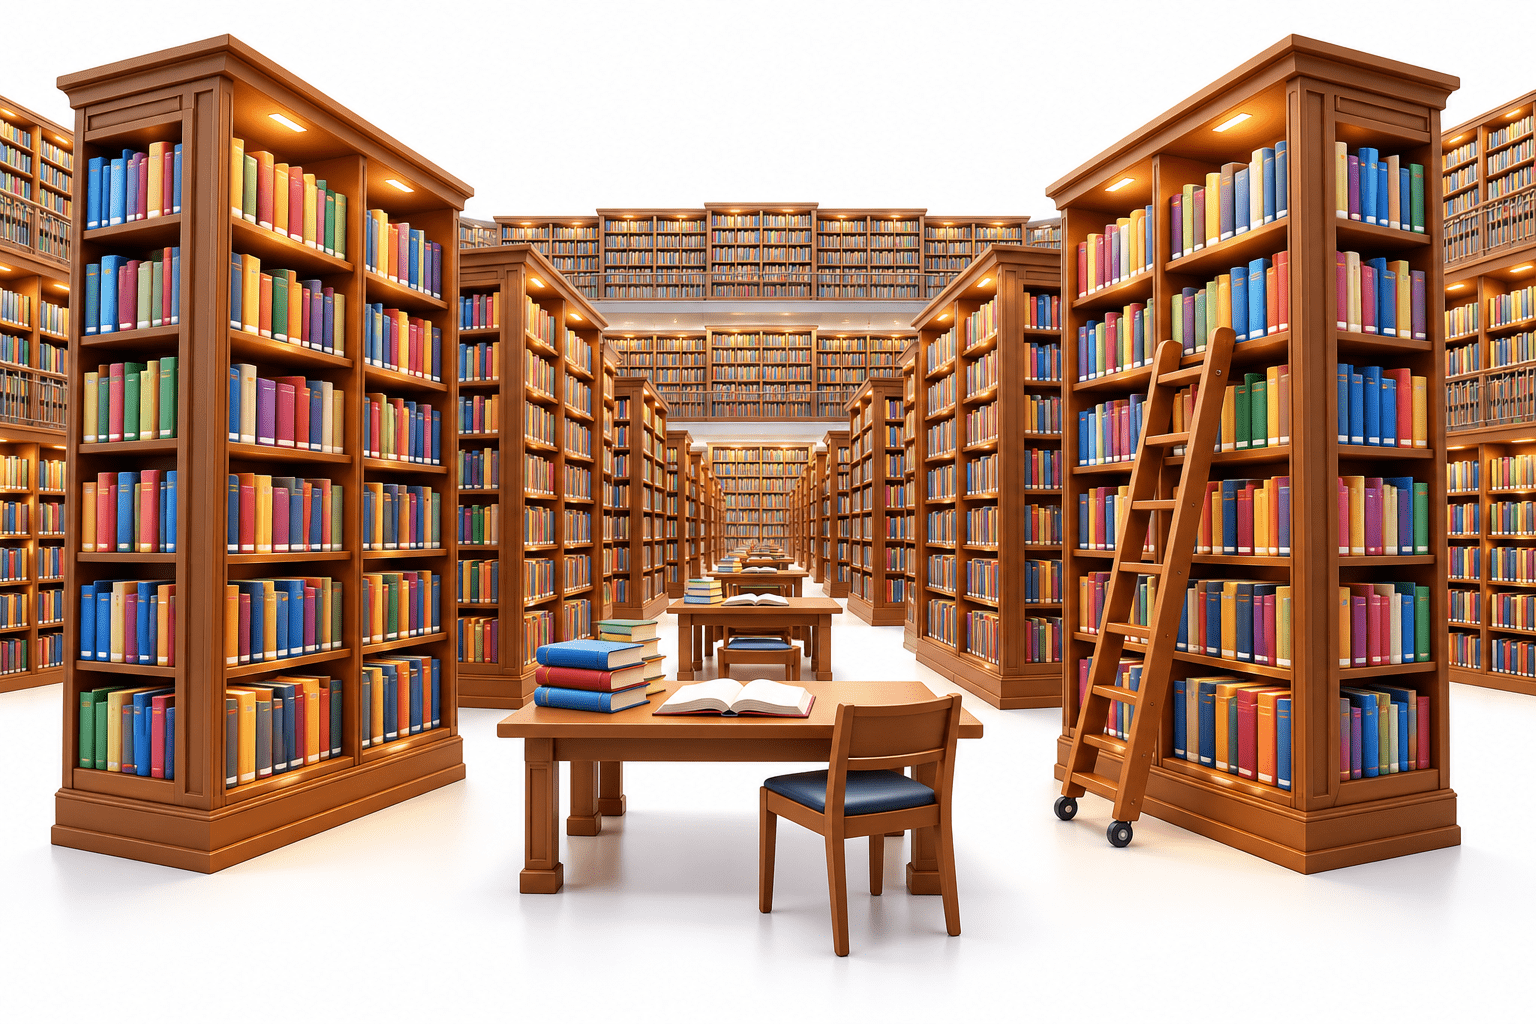
Without a catalogue, you must check every book to find the right one.
A library catalogue organizes books for faster searching.
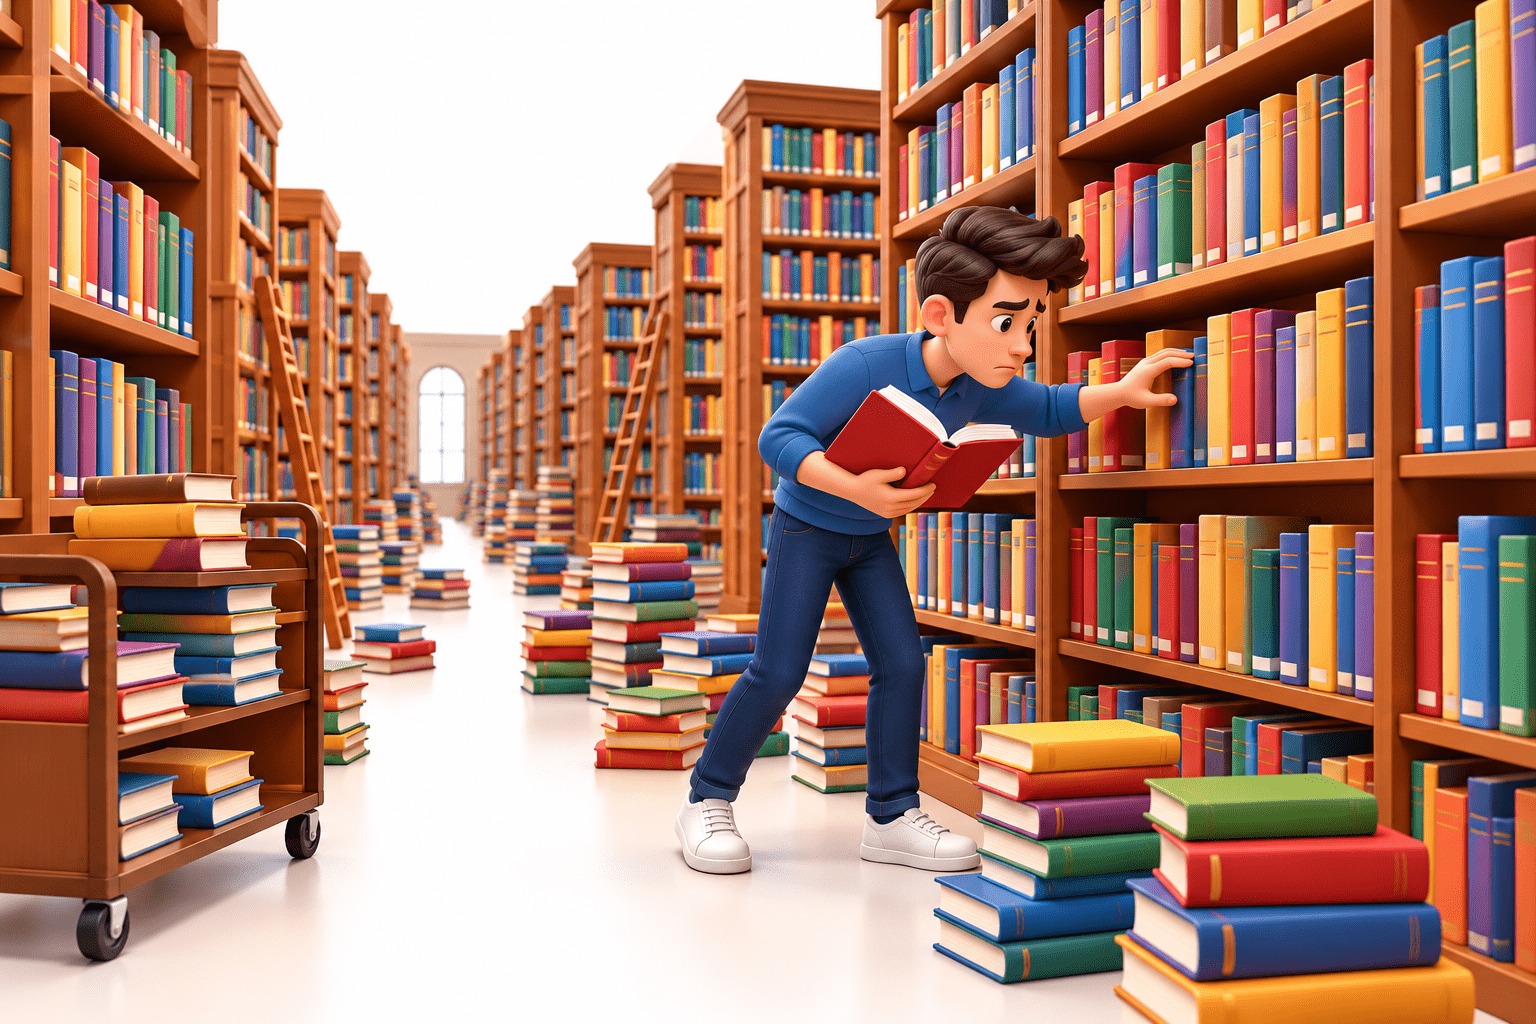
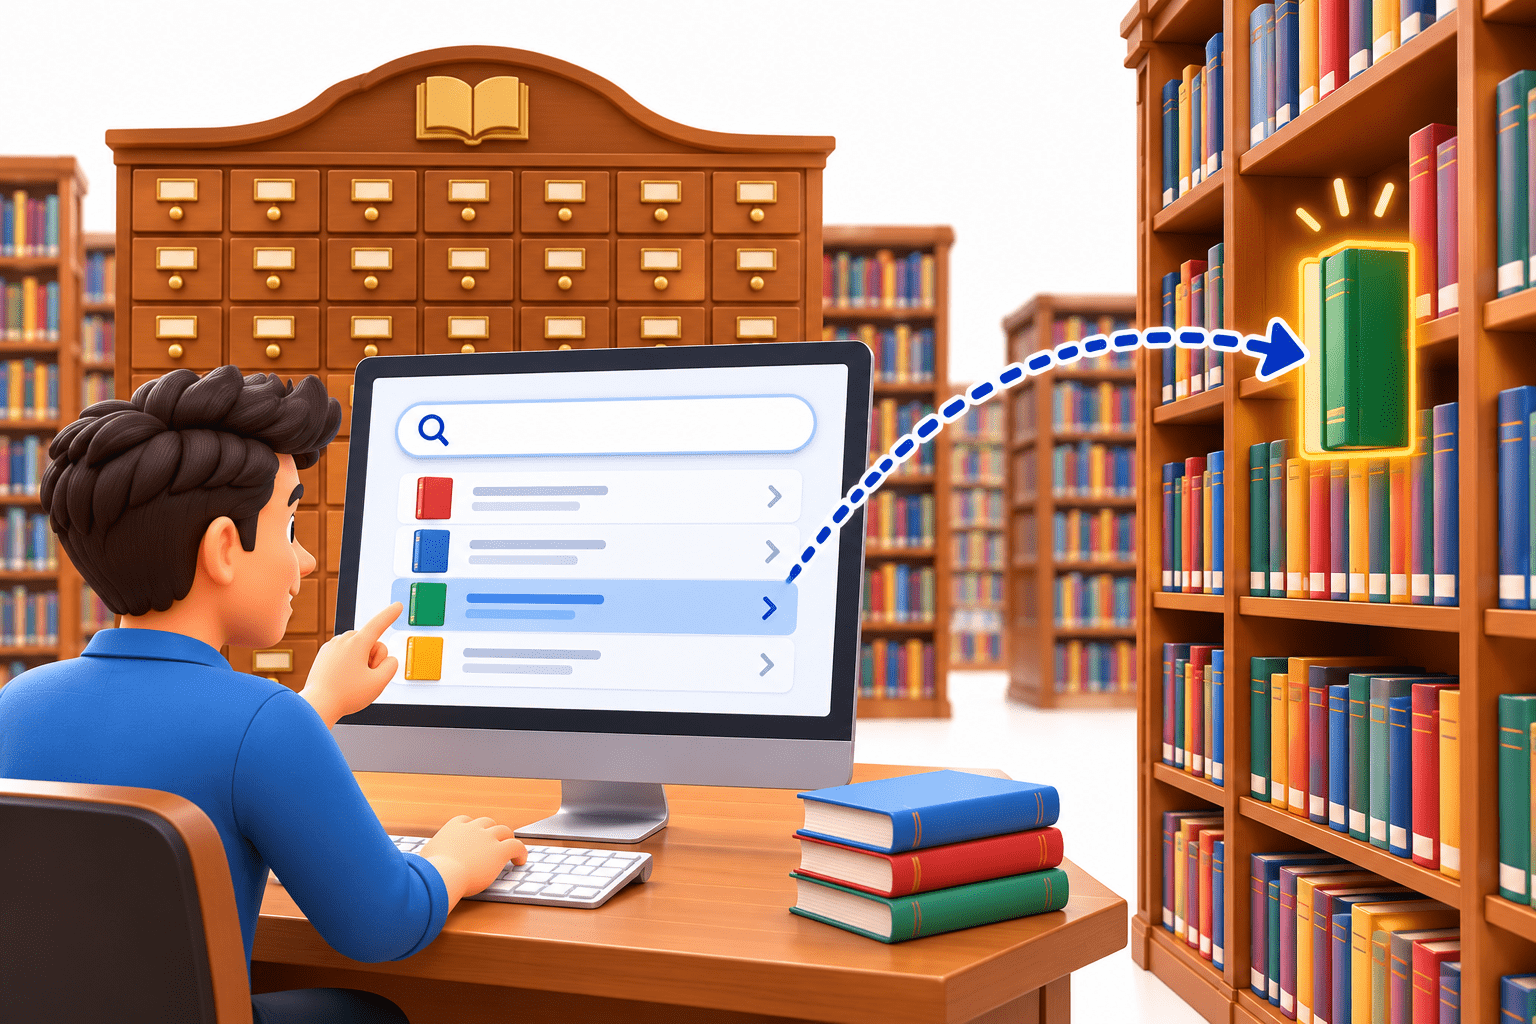
Similarly, Vector Indexing organizes millions of embeddings.
It helps find the most similar vectors quickly without checking every vector.
Library Catalogue → Organizes Books | Vector Indexing → Organizes Embeddings
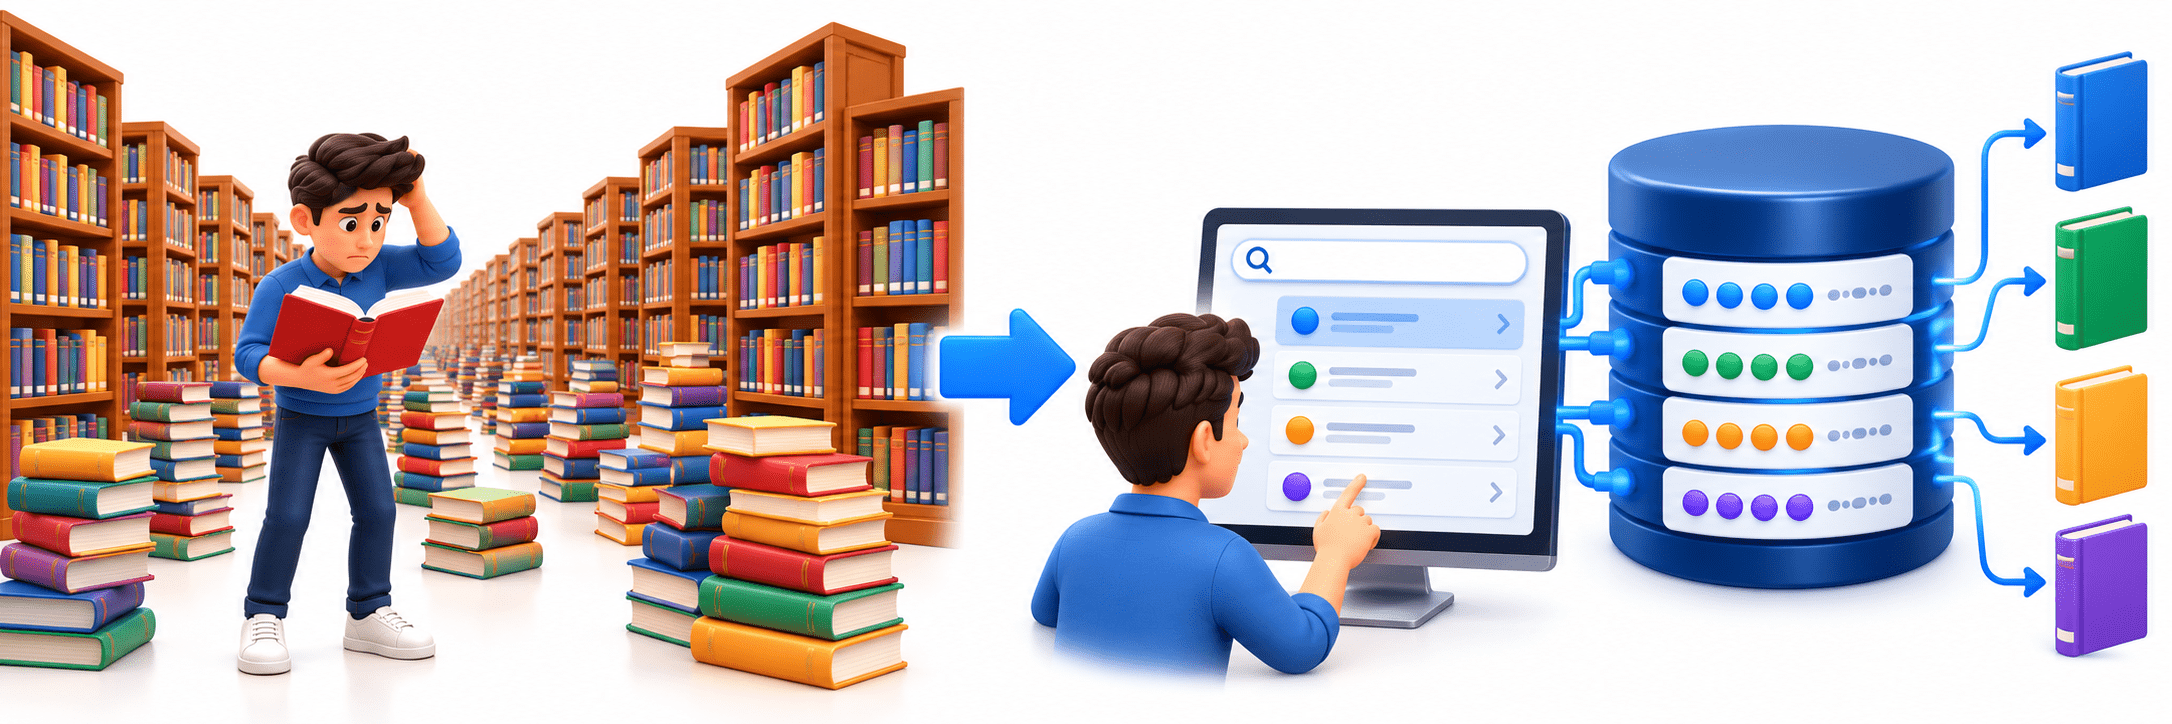
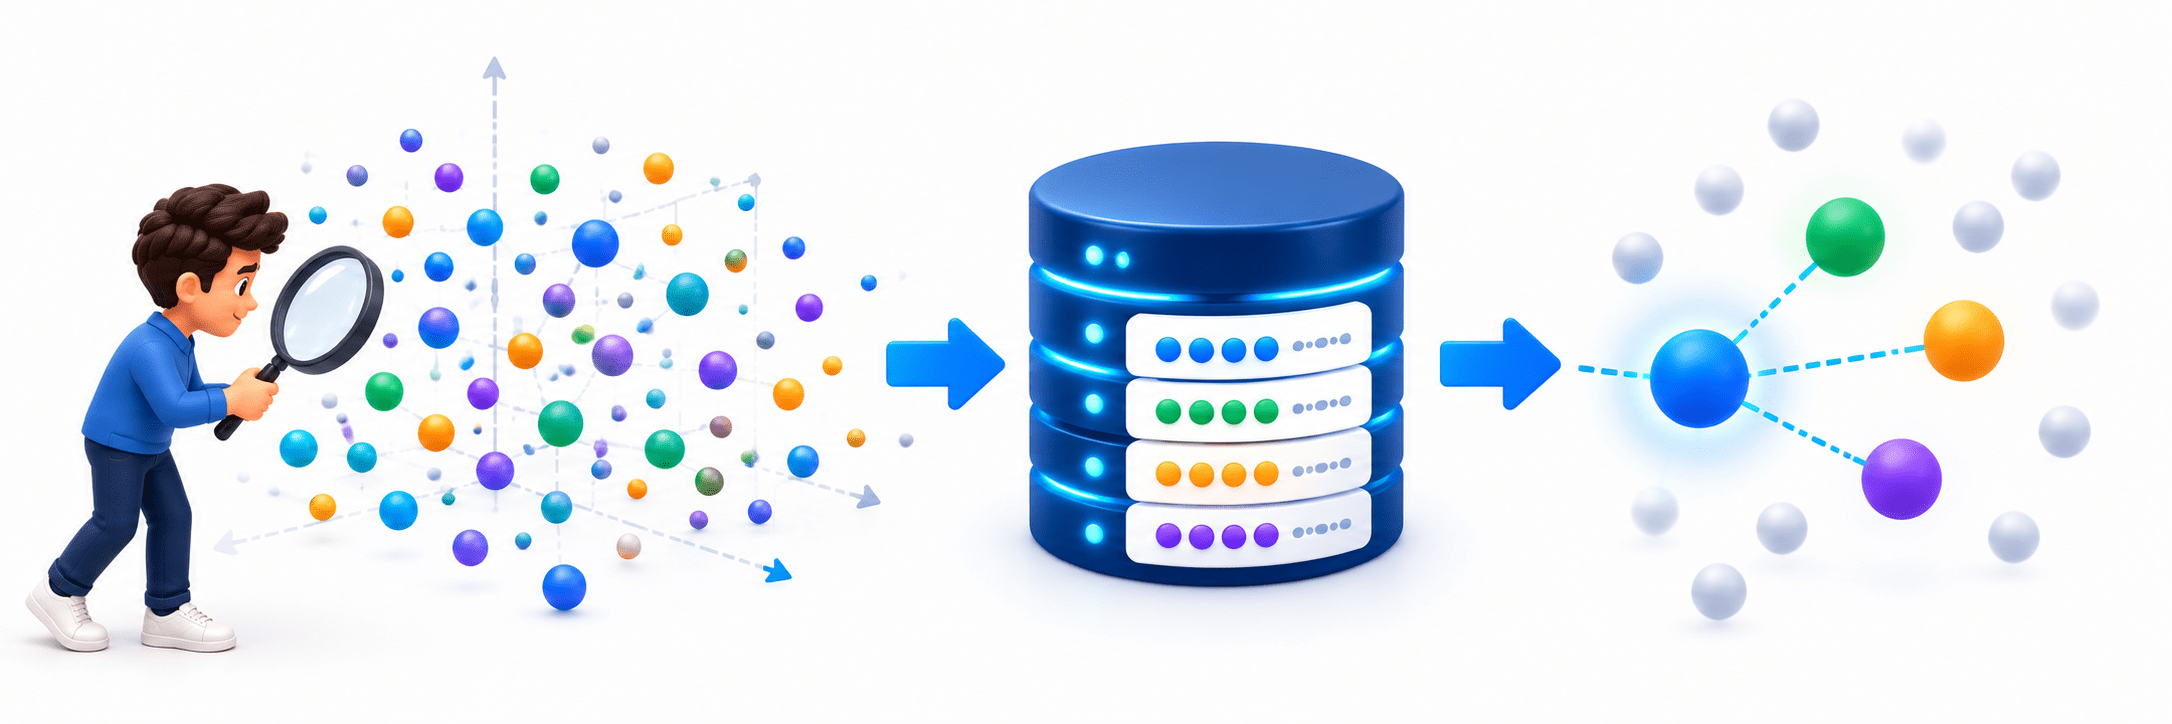
Previously, we imagined a library with millions of books and no catalogue, forcing someone to check every single book one at a time.
If a RAG system stored a million document embeddings and compared a new query against every single one of them individually, would that be fast enough for a real-time application?
No — comparing a query against every single stored vector one by one would be far too slow at that scale, just like searching a library with no catalogue.
The library was just an easy example to help us understand the idea. Now let's break down what Vector Indexing really is.
What is Vector Indexing?
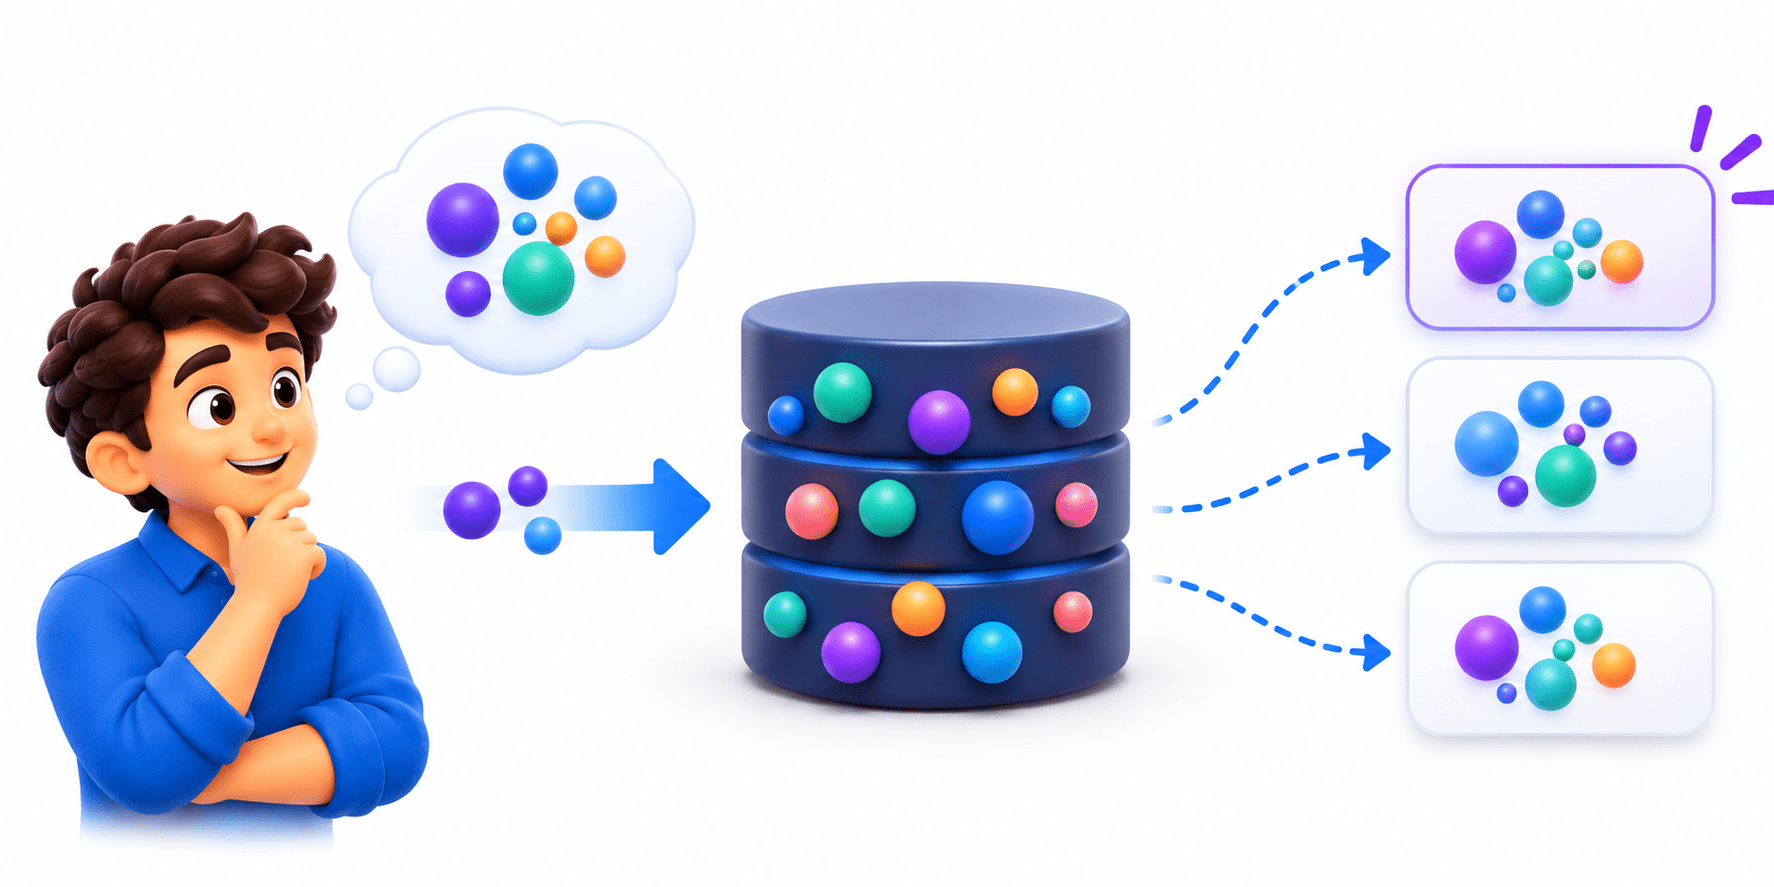
Vector Indexing organizes embeddings for fast similarity search.
It quickly finds vectors most similar to a query vector.
01
02
Without indexing, brute-force search checks every stored vector.
03
Brute-force search becomes too slow for millions of vectors.
04
How Similarity is Measured
Cosine Similarity
Measures the angle/direction between vectors.
Commonly used for text embeddings to compare semantic meaning.
Euclidean Distance
Measures the straight-line distance between vectors.
Smaller distance = greater similarity.
Code
cosine_similarity(vec_a, vec_b)Vector indexing makes these similarity searches fast at scale.
Code
np.linalg.norm(vec_a - vec_b)
Common Vector Indexing Approaches
01
02
03
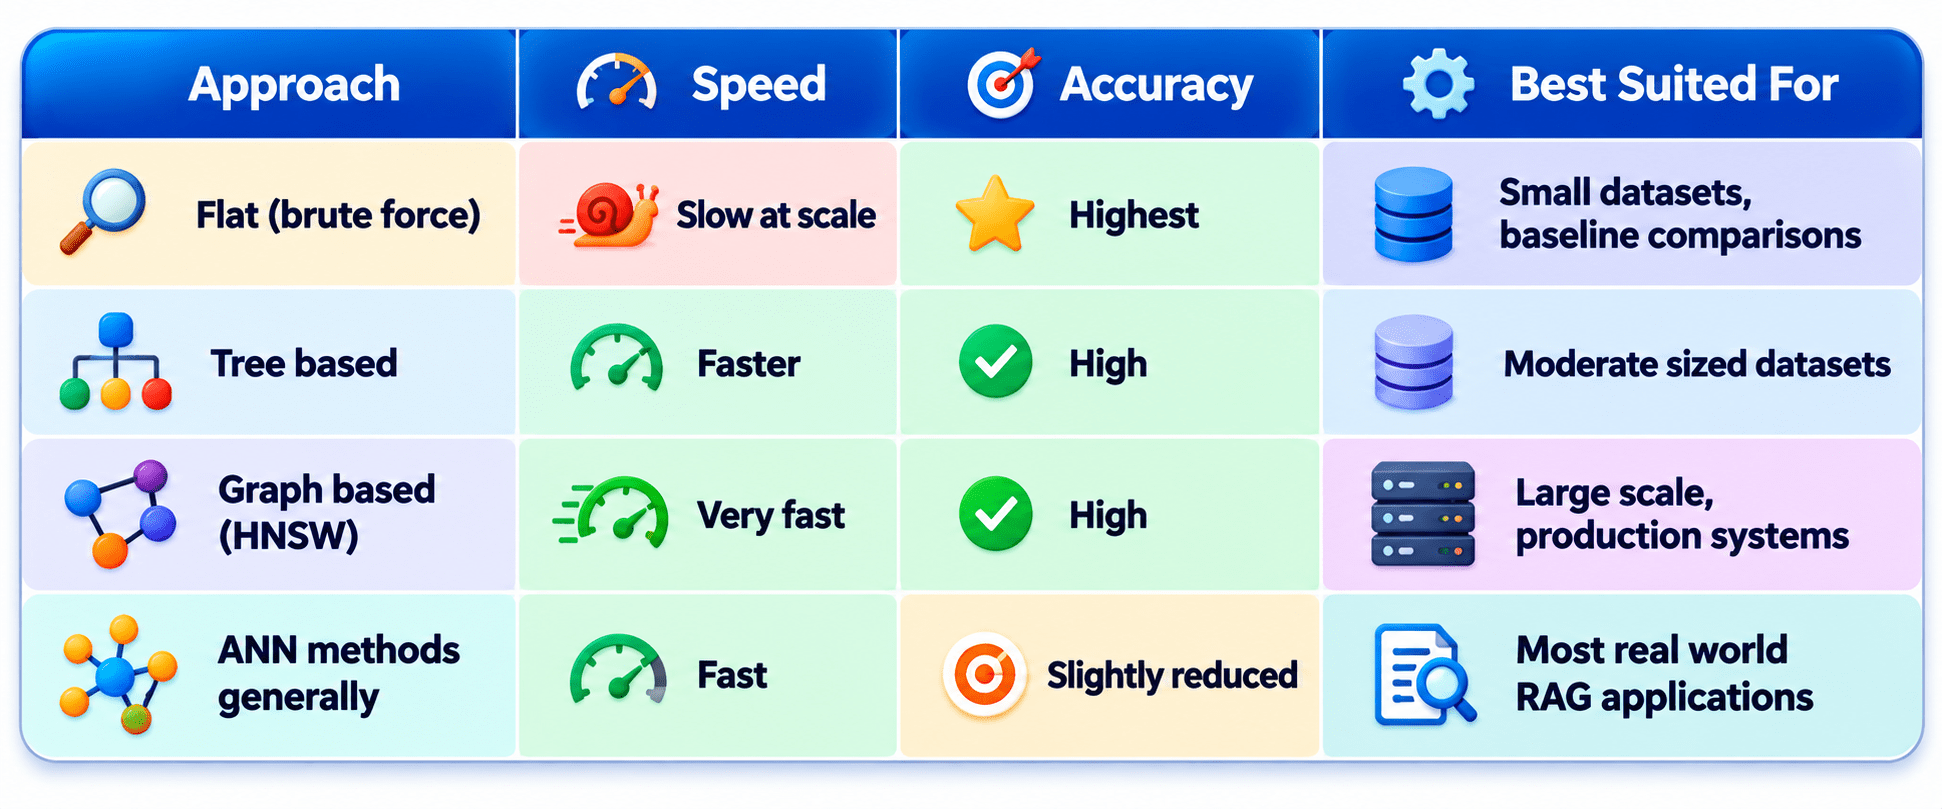
Flat (brute force) indexing
Compares the query with every stored vector
Provides high accuracy but becomes slow at scale.
Best for small datasets or baseline testing.
04
faiss.IndexFlatL2(dimension)
01
02
03
Approximate Nearest Neighbour (ANN)
Searches without checking every vector.
Trades a little accuracy for much faster speed.
Commonly used in production RAG systems.
04
faiss.IndexIVFFlat(quantizer, dimension, nlist)
01
02
03
Tree-Based Indexing
Organizes vectors in a tree-like structure.
Narrows the search to the most relevant branches.
Avoids searching the entire dataset.
Graph-Based Indexing (HNSW)
01
02
03
Organizes vectors in a navigable graph.
Search hops between vectors toward closer matches.
Provides a strong balance of speed and accuracy.
04
Widely used in modern vector databases.
The Trade-Off: Speed vs Accuracy
Every method balances search speed and retrieval accuracy.
Flat indexing is highly accurate but too slow at massive scale.
ANN methods are much faster with only a small accuracy trade-of
For millions of vectors and real-time chatbots, graph-based ANN such as HNSW is a strong choice.
A tiny loss in accuracy is often worth the major speed improvement.
Vector Indexing at a Glance
Applications of Vector Indexing
Recommendation Systems
Find similar products, songs, or content.
Image & Video Search
Search large visual databases using embeddings.
Duplicate & Fraud Detection
Identify similar records or transactions quickly.
Enterprise Search & RAG
Retrieve relevant information from large knowledge bases in real time.
An Easy Way to Remember
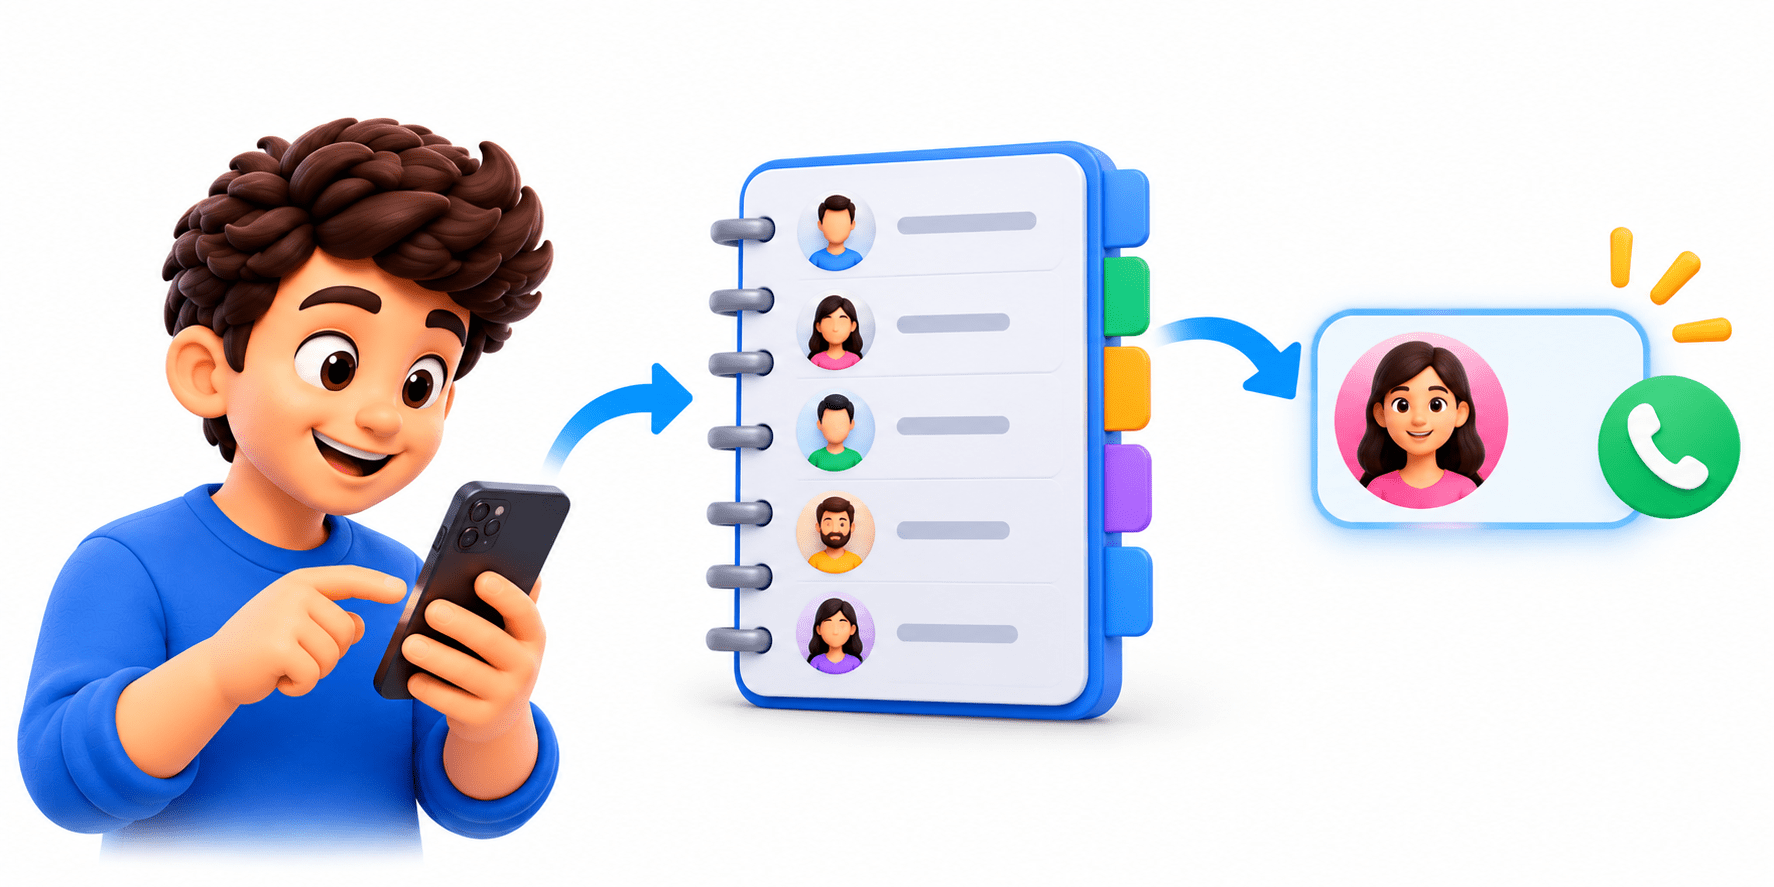
Imagine searching for “Mom” by scrolling through every contact.
This would be slow and inefficient.
An indexed contact list lets you jump quickly to the right name.
Similarly, Vector Indexing helps jump quickly to the closest matching vectors.
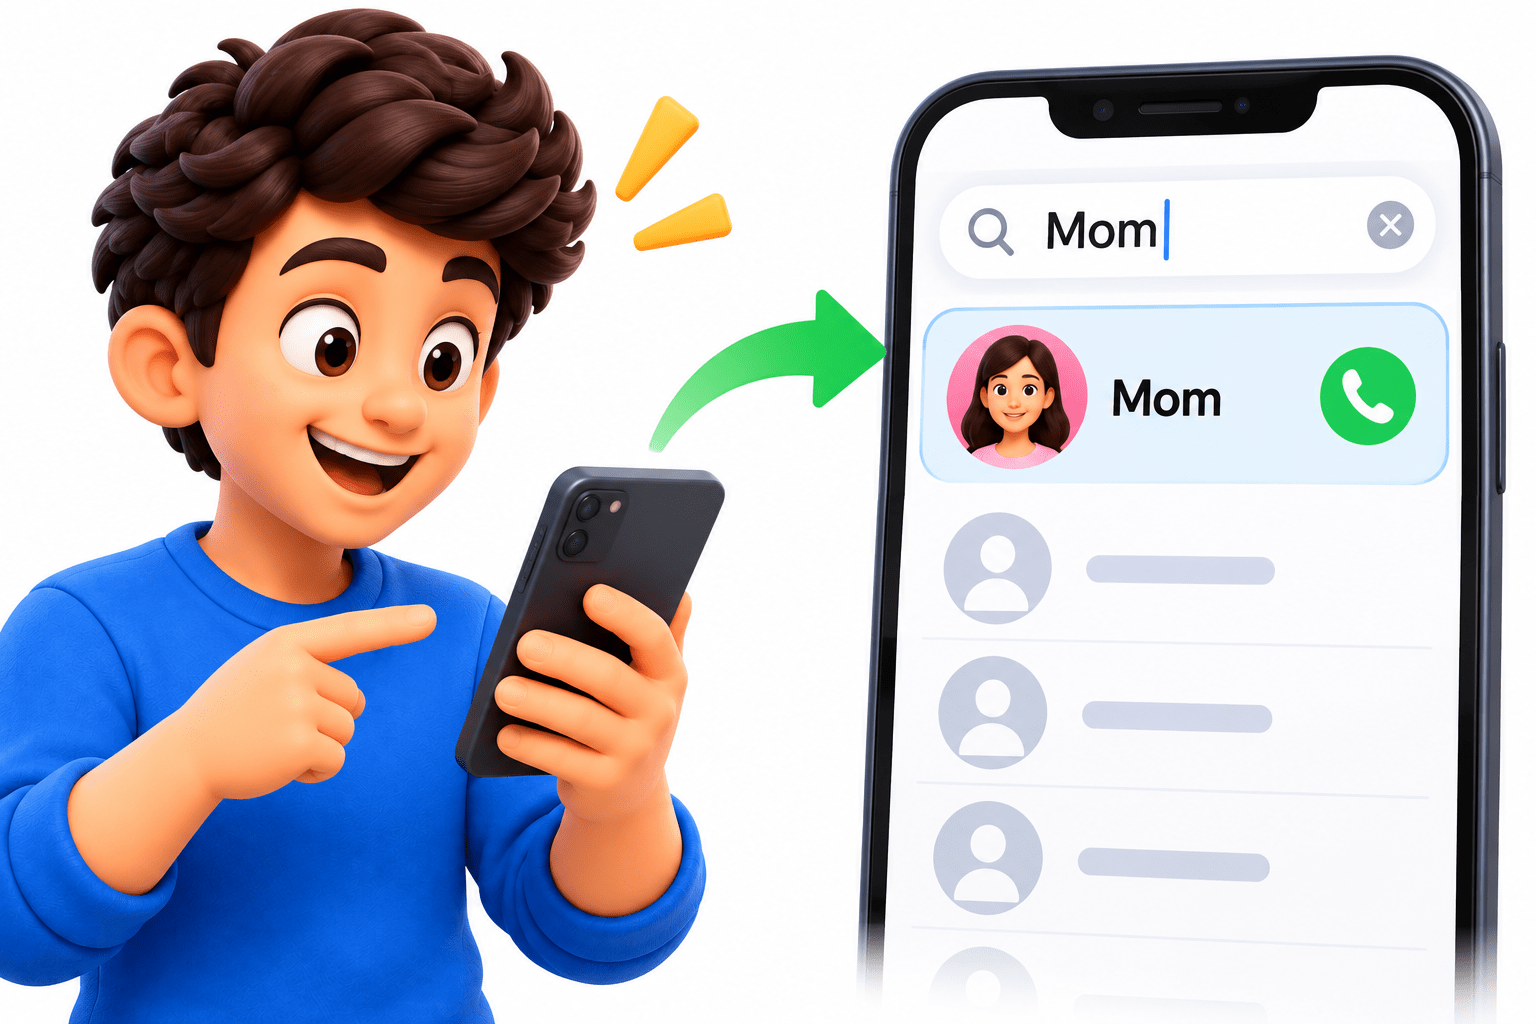
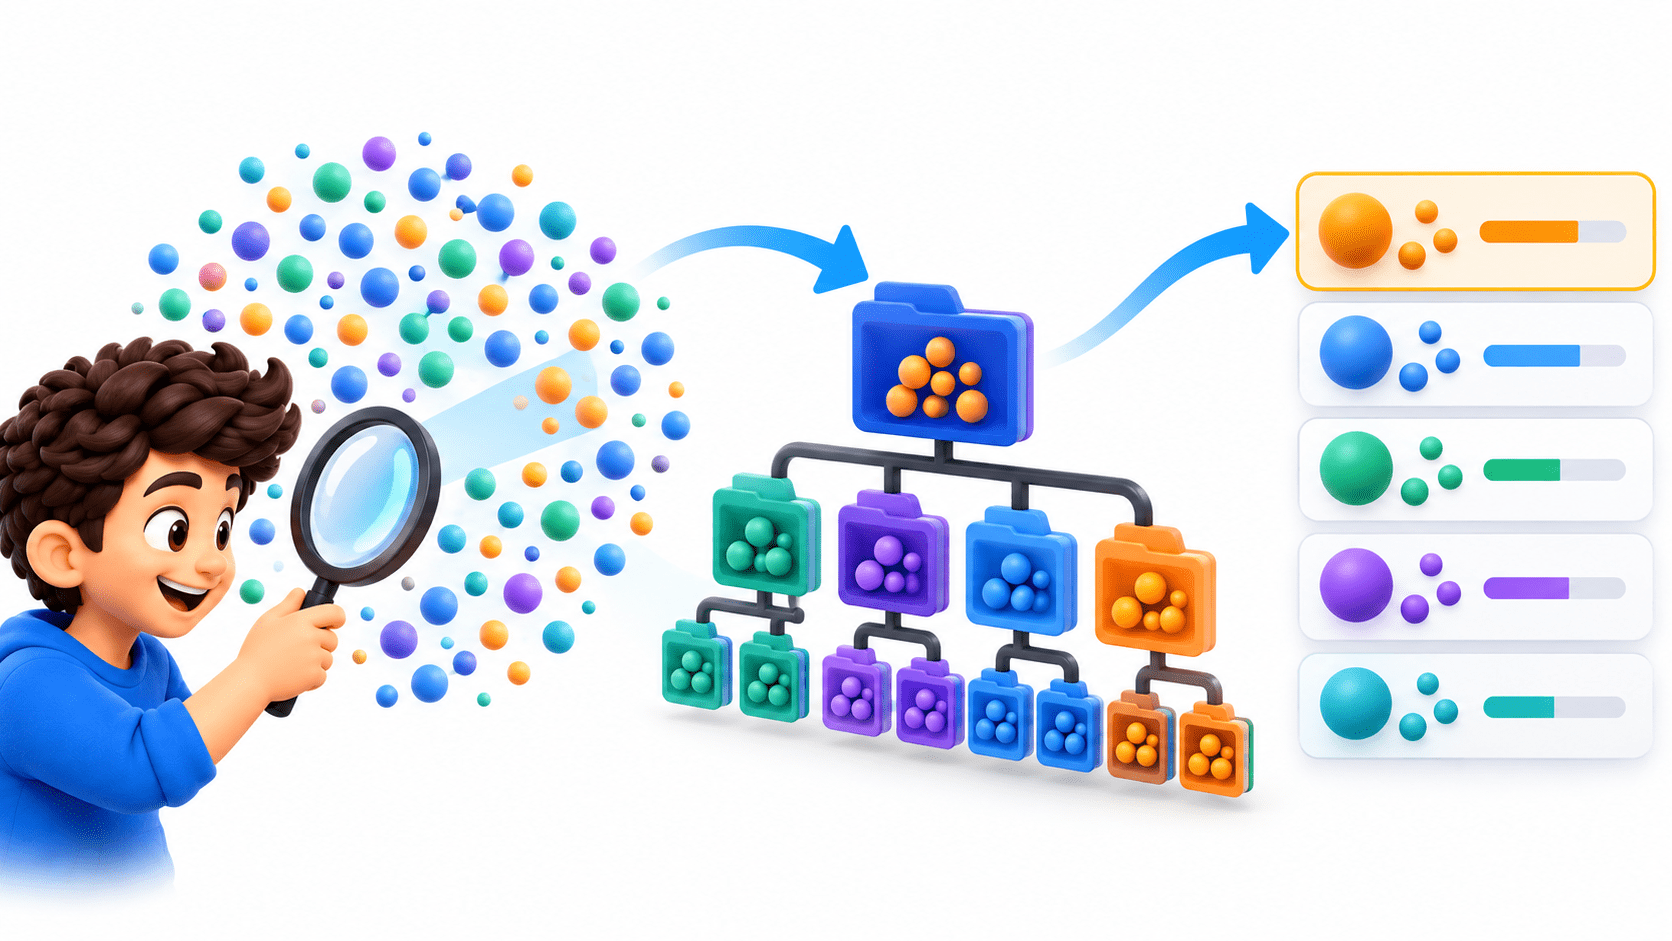
Contact Index → Finds Names Fast
Vector Index → Finds Similar Embeddings Fast.
Daily Life Applications
Music Apps → Find similar songs instantly.
Reverse Image Search → Finds visually similar images.
Shopping Apps → Suggest related products quickly.
Spam Filters → Detect emails similar to known spam.
Summary
5
RAG systems use ANN for fast retrieval.
4
ANN provides faster search with a small accuracy trade-off.
3
Methods: Flat, Tree-Based & HNSW.
2
Cosine Similarity and Euclidean Distance measure vector similarity.
1
Vector Indexing enables fast similarity search.
Quiz
Which indexing approach is best for searching millions of vectors in real time? Pasted text
A. Flat Indexing
B. ANN-based Indexing (HNSW)
C. No Indexing
D. Manual Search
Which indexing approach is best for searching millions of vectors in real time? Pasted text
A. Flat Indexing
B. ANN-based Indexing (HNSW)
C. No Indexing
D. Manual Search
Quiz-Answer