Strategies: Heat Equation
Parallel Algorithms
David Mayerich
Scalable Tissue Imaging and Modeling (STIM) Laboratory
Department of Electrical and Computer Engineering
Cullen College of Engineering
University of Houston
David Mayerich
STIM Laboratory, University of Houston

2D Heat Equation
-
Constants: thermal conductivity \(k\), density \(\rho\), and heat capacity \(c\)
-
\(T\) is the temperature measured at point \((x,y)\) at time \(t\)
-
Laplace operator (Laplacian):
David Mayerich
STIM Laboratory, University of Houston
change in temperature over time
material properties
heat flow along both directions
Discretization
-
Track the discrete temperature on a grid:
David Mayerich
STIM Laboratory, University of Houston
-
Each discrete spatial location \((x_i,y_j)\) stores the temperature at time \(t_n\)
-
Spacing between grid points is consistent (but doesn't have to be):
\(\Delta_x = x_{i+1}-x_i \quad\quad \Delta_y = y_{j+1}-y_j\) -
We update this grid to calculate the temperature at each time step:
\(\Delta_t = t_{n+1}-t_n\)-
Step values are specified by the user
-
Related to actual spatial locations and time points, for example:
\(x_i = x_0 + i\cdot \Delta_x\)
-
Finite Difference Calculus
-
Start from a first-order Taylor series:
David Mayerich
STIM Laboratory, University of Houston
-
Given two known points \(c=x_i\) and \(x=x_{i+1}=x_i + x_\Delta\):
-
Solve for \(f'(x)\):
-
Note that the order in the error term is reduced:
Finite Difference Calculus
-
Finite difference methods are used to approximate a partial derivative from samples of a function:
David Mayerich
STIM Laboratory, University of Houston
-
Given these approximations for the spatial partial derivatives, we want to compute \(T\) at \(t_{n+1}\) based on the diffusion equation:
-
Approximating the second derivative:
Explicit Method
-
Given the temperature \(T^n_{i,j}\) at \(t_n\), we approximate the future temperature \(T^{n+1}_{i,j}\) at \(t_{n+1}\) using the forward finite difference:
David Mayerich
STIM Laboratory, University of Houston
-
Using the same finite difference methods, we can approximate the two spatial derivatives:
by solving for \(T^{n+1}\):
which depends on the partial differential equation we already know:
-
Assuming \(h=\Delta_x = \Delta_y\) and collecting terms, we have:
Algorithm: Explicit Euler Method
Euler's Method: solves a PDE using a first-order (Taylor Series) approximation
Given the value of \(T^n_{i,j}=T(x_i, y_j, t_n)\)
Approximate the PDE at every point:
David Mayerich
STIM Laboratory, University of Houston
-
Update every point to the next time step:
Simulation Error
-
Finite difference methods are based on Taylor series:
\(f(x)=f(c)+f'(c)(x-c)+O(\Delta_x)\)-
where \(c=x_i\) and \(x=x_{i+1}\):
\(f(x_{i+1})=f(x)+f'(x_i)\Delta_x + O(\Delta_x)\) -
solve for the derivative:
\(f'(x_i)=\frac{f(x_{i+1}) - f(x)}{\Delta_x} + O(\Delta_x)\)
-
-
Second derivative error:
David Mayerich
STIM Laboratory, University of Houston
-
Error term depends on sample spacing: \(E = O(\Delta_x^2)\)
-
Smaller samples provide better accuracy but increase compute time
-
Stability is based on the Courant-Friedrichs-Lewy (CFL) condition:
Approximation
Error and Stability
-
Select \(\Delta_x\), \(\Delta_y\), and \(\Delta_t\) to optimize accuracy and minimize compute time
Implementation 1: Follow the Math
David Mayerich
STIM Laboratory, University of Houston
void heat(float* A, float alpha, float h, float dt, int S, float epsilon) {
}
Implementation 1: Follow the Math
David Mayerich
STIM Laboratory, University of Houston
void heat(float* A, float alpha, float h, float dt, int S, float epsilon) {
  float* B = new float[S * S];		// create a new array to store the output
  float c = alpha / (h * h); 		// pre-compute the spatial diffusion term
  while(true) { 					// loop indefinitely
  }
}
Implementation 1: Follow the Math
David Mayerich
STIM Laboratory, University of Houston
void heat(float* A, float alpha, float h, float dt, int S, float epsilon) {
  float* B = new float[S * S];		// create a new array to store the output
  float c = alpha / (h * h); 		// pre-compute the spatial diffusion term
  while(true) { 					// loop indefinitely
    float diff = 0.0f; 				// track how much the simulation result has changed
    // iterate through each pixel (why y then x?), note boundaries
	for(int j=1; j<S; j++) {
	  for(int i=1; i<S; i++) {

      }
    }

  }
}
Implementation 1: Follow the Math
David Mayerich
STIM Laboratory, University of Houston
void heat(float* A, float alpha, float h, float dt, int S, float epsilon) {
  float* B = new float[S * S];		// create a new array to store the output
  float c = alpha / (h * h); 		// pre-compute the spatial diffusion term
  while(true) { 					// loop indefinitely
    float diff = 0.0f; 				// track how much the simulation result has changed
    // iterate through each pixel (why y then x?), note boundaries
	for(int j=1; j<S; j++) {
	  for(int i=1; i<S; i++) {
        // calculate the partial derivative with respect to time (main calculation)
        dT_dt = c * (A[j*S+i+1] + A[j*S+i-1] + A[(j+1)*S+i] + A[(j-1)*S+i] – 4*A[j*S+i];
	    B[j*S+i] = A[j*S+i] + dt * dT_dt; 			// use explicit integration
		diff += fabs(B[j*S+i] - A[j*S+i]); 			// sum the absolute change
      }
    }

  }
}
Implementation 1: Follow the Math
David Mayerich
STIM Laboratory, University of Houston
void heat(float* A, float alpha, float h, float dt, int S, float epsilon) {
  float* B = new float[S * S];			// create a new array to store the output
  float c = alpha / (h * h); 			// pre-compute the spatial diffusion term
  while(true) { 						// loop indefinitely
    float diff = 0.0f; 					// track how much the simulation result has changed
    // iterate through each pixel (why y then x?), note boundaries
	for(int j=1; j<S; j++) {
	  for(int i=1; i<S; i++) {
        // calculate the partial derivative with respect to time (main calculation)
        dT_dt = c * (A[j*S+i+1] + A[j*S+i-1] + A[(j+1)*S+i] + A[(j-1)*S+i] – 4*A[j*S+i];
	    B[j*S+i] = A[j*S+i] + dt * dT_dt; 				// use explicit integration
		diff += fabs(B[j*S+i] - A[j*S+i]); 				// sum the absolute change
      }
    }
    // swap pointers
    float* tmp = A;  A = B;  B = tmp;
    // delete the temporary array and return
    if(diff / (S*S) < epsilon) { delete B; return; }
  }
}
2X memory!
Implementation 2: Single-Process
David Mayerich
STIM Laboratory, University of Houston
Implementation 2: Single-Process
David Mayerich
STIM Laboratory, University of Houston
void heat(float* A, float alpha, float h, float dt, int S, float epsilon) {
  float* B = new float[S * S];			// create a new array to store the output
  float c = alpha / (h * h); 			// pre-compute the spatial diffusion term
  while(true) { 						// loop indefinitely
    float diff = 0.0f; 					// track how much the simulation result has changed
    // iterate through each pixel (why y then x?), note boundaries
	for(int j=1; j<S; j++) {
	  for(int i=1; i<S; i++) {
        // calculate the partial derivative with respect to time (main calculation)
        dT_dt = c * (A[j*S+i+1] + A[j*S+i-1] + A[(j+1)*S+i] + A[(j-1)*S+i] – 4*A[j*S+i];
	    B[j*S+i] = A[j*S+i] + dt * dT_dt; 				// use explicit integration
		diff += fabs(B[j*S+i] - A[j*S+i]); 				// sum the absolute change
      }
    }
    // swap pointers
    float* tmp = A;  A = B;  B = tmp;
    // delete the temporary array and return
    if(diff / (S*S) < epsilon) { delete B; return; }
  }
}
Implementation 2: Single-Process
David Mayerich
STIM Laboratory, University of Houston
void heat(float* A, float alpha, float h, float dt, int S, float epsilon) {
  float c = alpha / (h * h); 			// pre-compute the spatial diffusion term
  while(true) { 						// loop indefinitely
    float diff = 0.0f; 					// track how much the simulation result has changed
    // iterate through each pixel (why y then x?), note boundaries
	for(int j=1; j<S; j++) {
	  for(int i=1; i<S; i++) {
        // calculate the partial derivative with respect to time (main calculation)
        float prev = A[j*S+i];
        dT_dt = c * (A[j*S+i+1] + A[j*S+i-1] + A[(j+1)*S+i] + A[(j-1)*S+i] – 4*prev;
	    B[j*S+i] = A[j*S+i] + dt * dT_dt; 				// use explicit integration
		diff += fabs(B[j*S+i] - prev); 					// sum the absolute change
      }
    }
    // delete the temporary array and return
    if(diff / (S*S) < epsilon) { delete B; return; }
  }
}
dep
dep
Dependencies & Conflicting Requirements
Implementation 1 (write to a temp array)
-
Each grid point is independent within one time step
-
Requires 2X memory
-
Requires a larger cache (or more misses)
-
Memory and cache size are the first sacrifices in parallel processors
David Mayerich
STIM Laboratory, University of Houston
Implementation 2 (single array)
-
No additional memory
-
Better cache coherence
-
Both cases have a dependency in the terminating condition
// ....
    diff += fabs(B[j*S+i] - prev)
  }
}
if(diff / (S*S) < epsilon) return;
Implementation 3: Alternating Grid
David Mayerich
STIM Laboratory, University of Houston
Implementation 3: Parallelization
How can we evaluate \(\frac{\partial T}{\partial t}\) in parallel?
Red vs. Blue - will this work?
No, red and blue are dependent on each other
Calculate all red, then all blue, etc.
Interleaving
David Mayerich
STIM Laboratory, University of Houston
P2
P2
P2
P1
P1
P1
Implementation 3: Parallelization
-
How can we evaluate \(\frac{\partial T}{\partial t}\) in parallel?
-
Red vs. Blue - will this work?
-
No, red and blue are dependent on each other
-
Calculate all red, then all blue, etc.
-
-
Interleaving
-
Blocking
-
Less communication required
-
Distributed systems (send blocks to different computers)
-
-
Depends on architecture and problem (computation vs. memory access)
David Mayerich
STIM Laboratory, University of Houston
P2
P1
Implementation 3: Parallel Red/Blue
David Mayerich
STIM Laboratory, University of Houston
void heat_r(float* A, float alpha, float h, float dt, int S, float eps, int t_min, int t_max) {
  float c = alpha / (h * h); 			// pre-compute the spatial diffusion term
  while(true) { 						// loop indefinitely
    diff = 0.0f; 					// track how much the simulation result has changed
    // iterate through each pixel (why y then x?), note boundaries
	for(int j=t_min; j<t_max; j++) { 	// iterate through lines associated with this thread
	  for(int i=1; i<S; i++) {
        // calculate the partial derivative with respect to time (main calculation)
        float prev = A[j*S+i];
        dT_dt = c * (A[j*S+i+1] + A[j*S+i-1] + A[(j+1)*S+i] + A[(j-1)*S+i] – 4*prev;
	    B[j*S+i] = A[j*S+i] + dt * dT_dt; 				// use explicit integration
		diff += fabs(B[j*S+i] - prev); 					// sum the absolute change
      }
    }
    // delete the temporary array and return
    if(diff / (S*S) < eps) { delete B; return; }
  }
}
race
race
Implementation 3: Parallel Red/Blue
David Mayerich
STIM Laboratory, University of Houston
void heat_r(float* A, float alpha, float h, float dt, int S, float epsilon, int t_min, int t_max) {
  float c = alpha / (h * h); 			// pre-compute the spatial diffusion term
  while(true) { 						// loop indefinitely
    float diff = 0.0f; 					// track how much the simulation result has changed
    // iterate through each pixel (why y then x?), note boundaries
	for(int j=t_min; j<t_max; j++) { 	// iterate through lines associated with this thread
	  for(int i=1; i<S; i++) {
        // calculate the partial derivative with respect to time (main calculation)
        float prev = A[j*S+i];
        dT_dt = c * (A[j*S+i+1] + A[j*S+i-1] + A[(j+1)*S+i] + A[(j-1)*S+i] – 4*prev;
	    B[j*S+i] = A[j*S+i] + dt * dT_dt; 				// use explicit integration
		atomicAdd(diff, fabs(B[j*S+i] - prev); 			// sum the absolute change
      }
    }
    // delete the temporary array and return
    if(diff / (S*S) < epsilon) { delete B; return; }
  }
}
lock
Implementation 3: Parallel Red/Blue
David Mayerich
STIM Laboratory, University of Houston
void heat_r(float* A, float alpha, float h, float dt, int S, float epsilon, int t_min, int t_max) {
  float c = alpha / (h * h); 			// pre-compute the spatial diffusion term
  while(true) { 						// loop indefinitely
    float thread_diff = 0.0f; 					// track how much the simulation result has changed
    // iterate through each pixel (why y then x?), note boundaries
	for(int j=t_min; j<t_max; j++) { 	// iterate through lines associated with this thread
	  for(int i=1; i<S; i++) {
        // calculate the partial derivative with respect to time (main calculation)
        float prev = A[j*S+i];
        dT_dt = c * (A[j*S+i+1] + A[j*S+i-1] + A[(j+1)*S+i] + A[(j-1)*S+i] – 4*prev;
	    B[j*S+i] = A[j*S+i] + dt * dT_dt; 				// use explicit integration
        thread_diff += fabs(B[j*S+i] - prev; 			// sum the absolute change
      }
    }
    atomicAdd(diff, thread_diff);
    // delete the temporary array and return
    if(diff / (S*S) < epsilon) { delete B; return; }
  }
}
lock
Limitations
David Mayerich
STIM Laboratory, University of Houston
-
Synchronization limits parallelism
time
occupancy
time
occupancy
-
Summing per-thread (
thread_diff) with atomic operations (atomicAdd):
time
occupancy
sequential (\(P=1\))
parallel
adding within threads
What happens when the number of processors/threads approaches the number of grid points (\(P\rightarrow S^2\))?
t0
t1
tP
Divide Grid Between
Processors
synchronize
t0
t1
tP
synchronize
t0
t1
tP
diff
thread_diff
diff
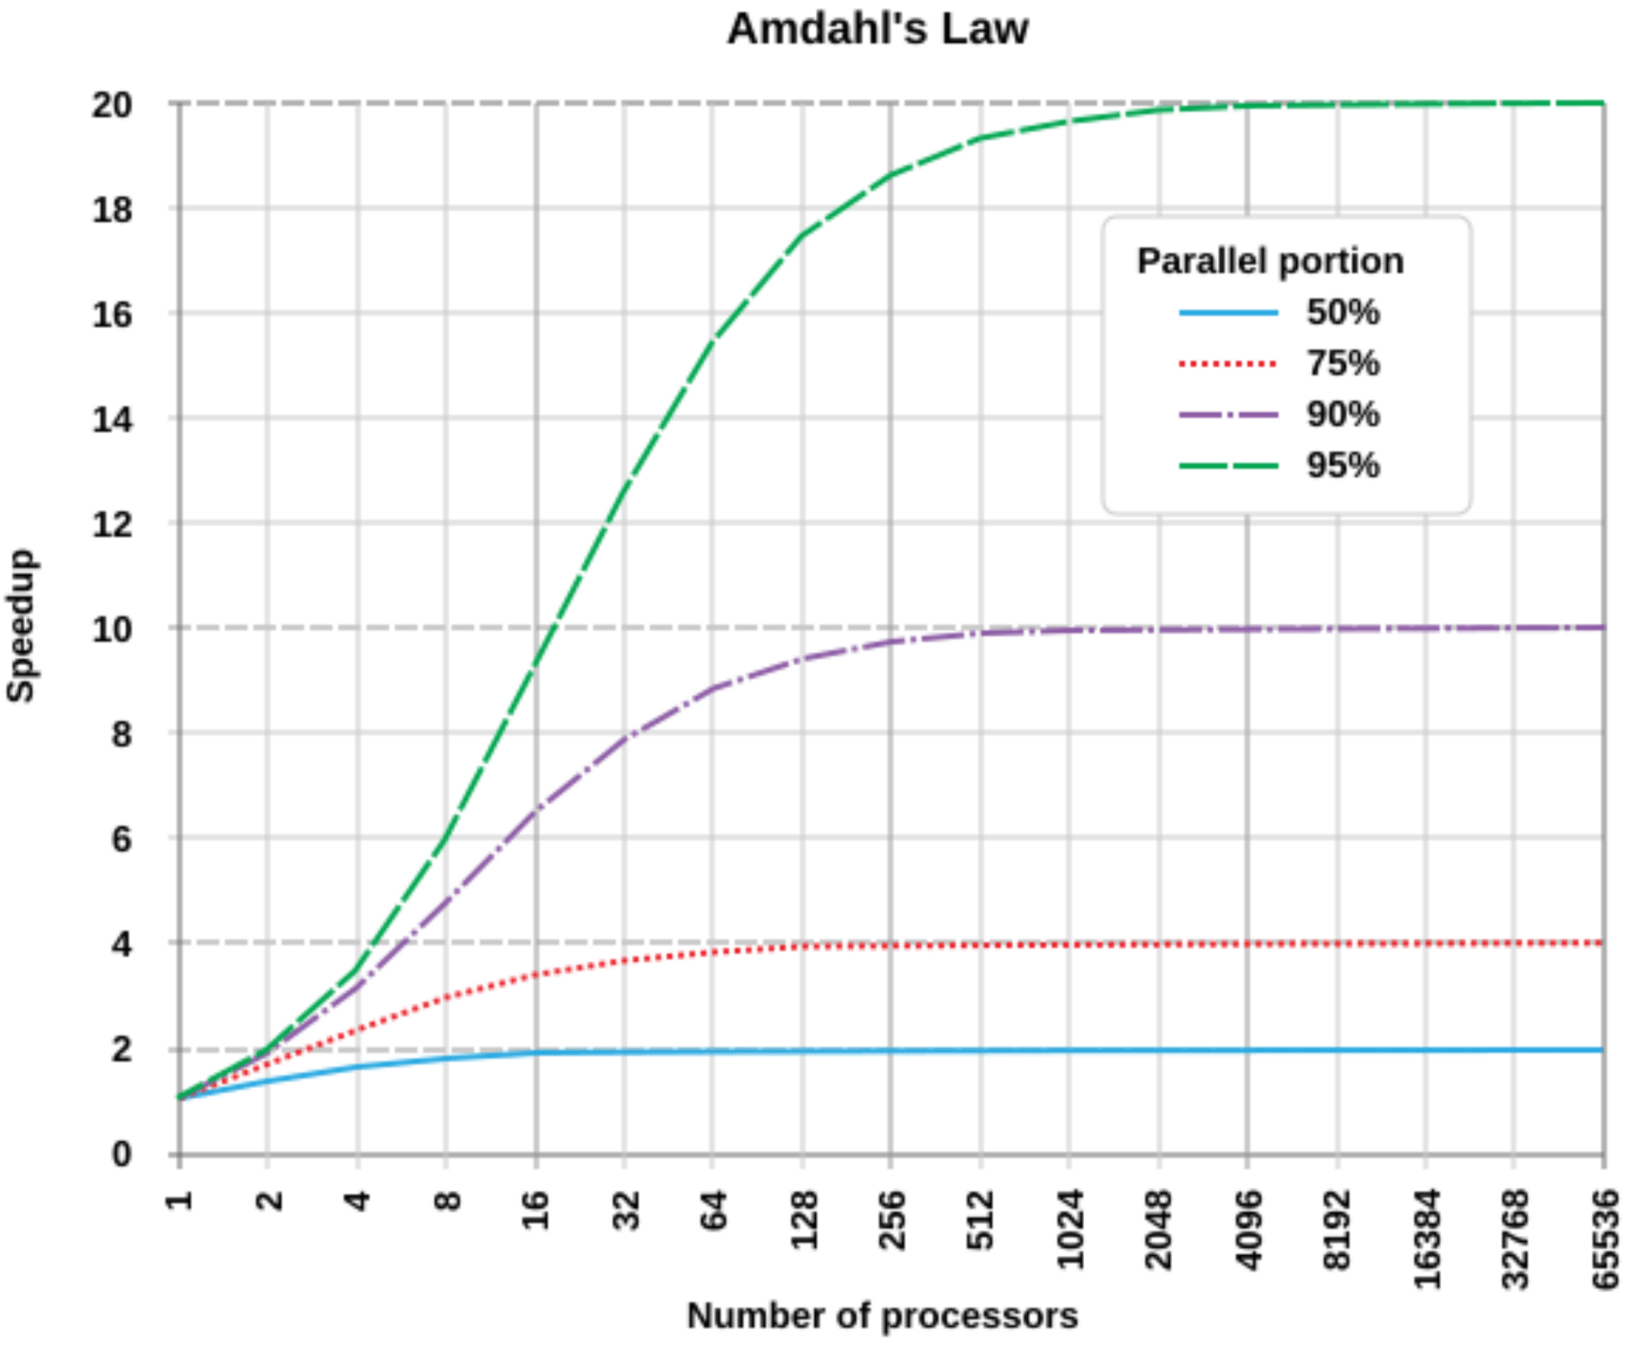
Amdahl's Law
-
Your ability to parallelize a program is limited by the serial parts:
-
\(S\) is the speedup
-
\(p\) is the parallel portion of the program
-
\(n\) is the number of processors
-
-
What is your expected speedup with 64 processors if 99.9% of your program can be parallelized?
David Mayerich
STIM Laboratory, University of Houston
Gustafson's Law
-
Alternative approach gives more optimistic results:
\(S=1-p+pn\)-
\(S\) is the speedup
-
\(p\) is the parallel portion of the code
-
\(n\) is the number of processors
-
-
What is your expected speedup with 64 processors if 99.9% of your program can be parallelized?
\(0.001 + 0.999 \times 64 \approx 64X\)
David Mayerich
STIM Laboratory, University of Houston
-
Why different answers (60X vs. 64X)?
-
Ahmdal's law represents a fixed problem size
-
Gustafson's law assumes the parallel part will grow to fully occupy the available processors
How would this apply to our heat equation example?