Lecture 17: Visuomotor Policies (via Behavior Cloning)
This is a live streamed presentation. You will automatically follow the presenter and see the slide they're currently on.
This is a live streamed presentation. You will automatically follow the presenter and see the slide they're currently on.
a prelude to RL and Control
MIT 6.4210/2:
Robotic Manipulation
Fall 2022, Lecture 17
Follow live at https://slides.com/d/KfJ018c/live
(or later at https://slides.com/russtedrake/fall22-lec17)
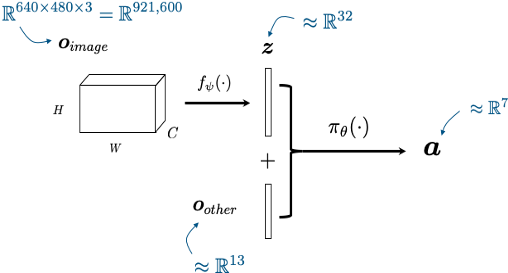
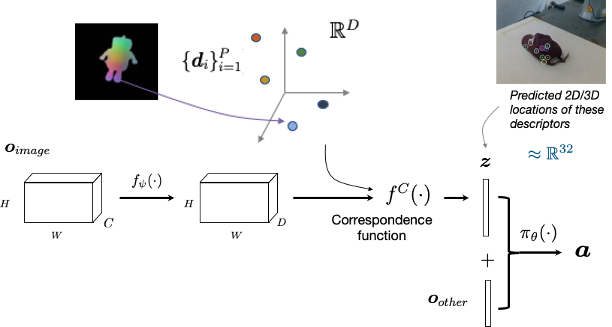
policy needs to know
state of the robot x state of the environment
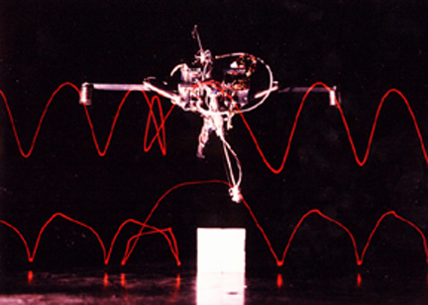
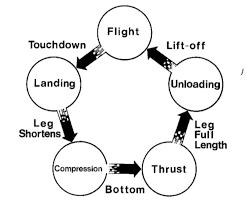
http://www.ai.mit.edu/projects/leglab/robots/robots.html
2017
Levine*, Finn*, Darrel, Abbeel, JMLR 2016
from hand-coded policies in sim
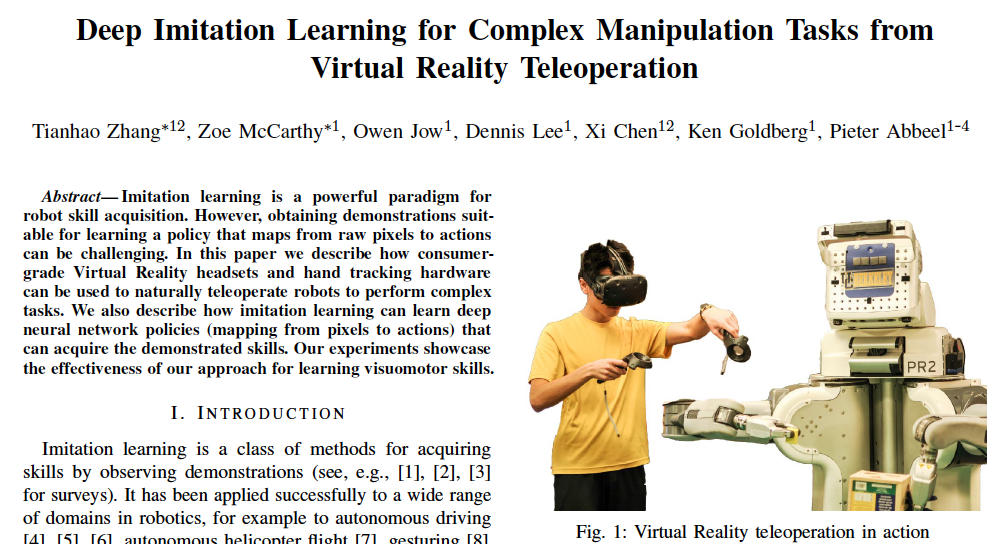
and teleop on the real robot
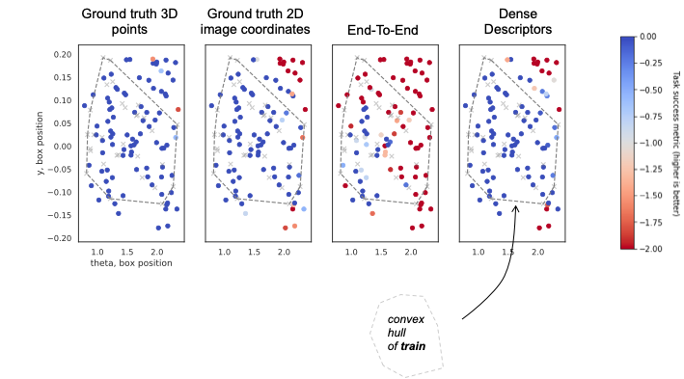
Standard "behavior-cloning" objective + data augmentation
"push box"
"flip box"
Policy is a small LSTM network (~100 LSTMs)
"And then … BC methods started to get good. Really good. So good that our best manipulation system today mostly uses BC, with a sprinkle of Q learning on top to perform high-level action selection. Today, less than 20% of our research investments is on RL, and the research runway for BC-based methods feels more robust."
Andy Zeng's MIT CSL Seminar, April 4, 2022
Andy's slides.com presentation