Field-level inference of primordial
non-Gaussianity from DESI:
Validation on simulations
Hugo SIMON,
PhD student supervised by
Arnaud DE MATTIA and François LANUSSE
2026/01/15
Cosmological inference
\(\Omega := \{ \Omega_m, \Omega_\Lambda, H_0, \sigma_8, f_\mathrm{NL},...\}\)
inference
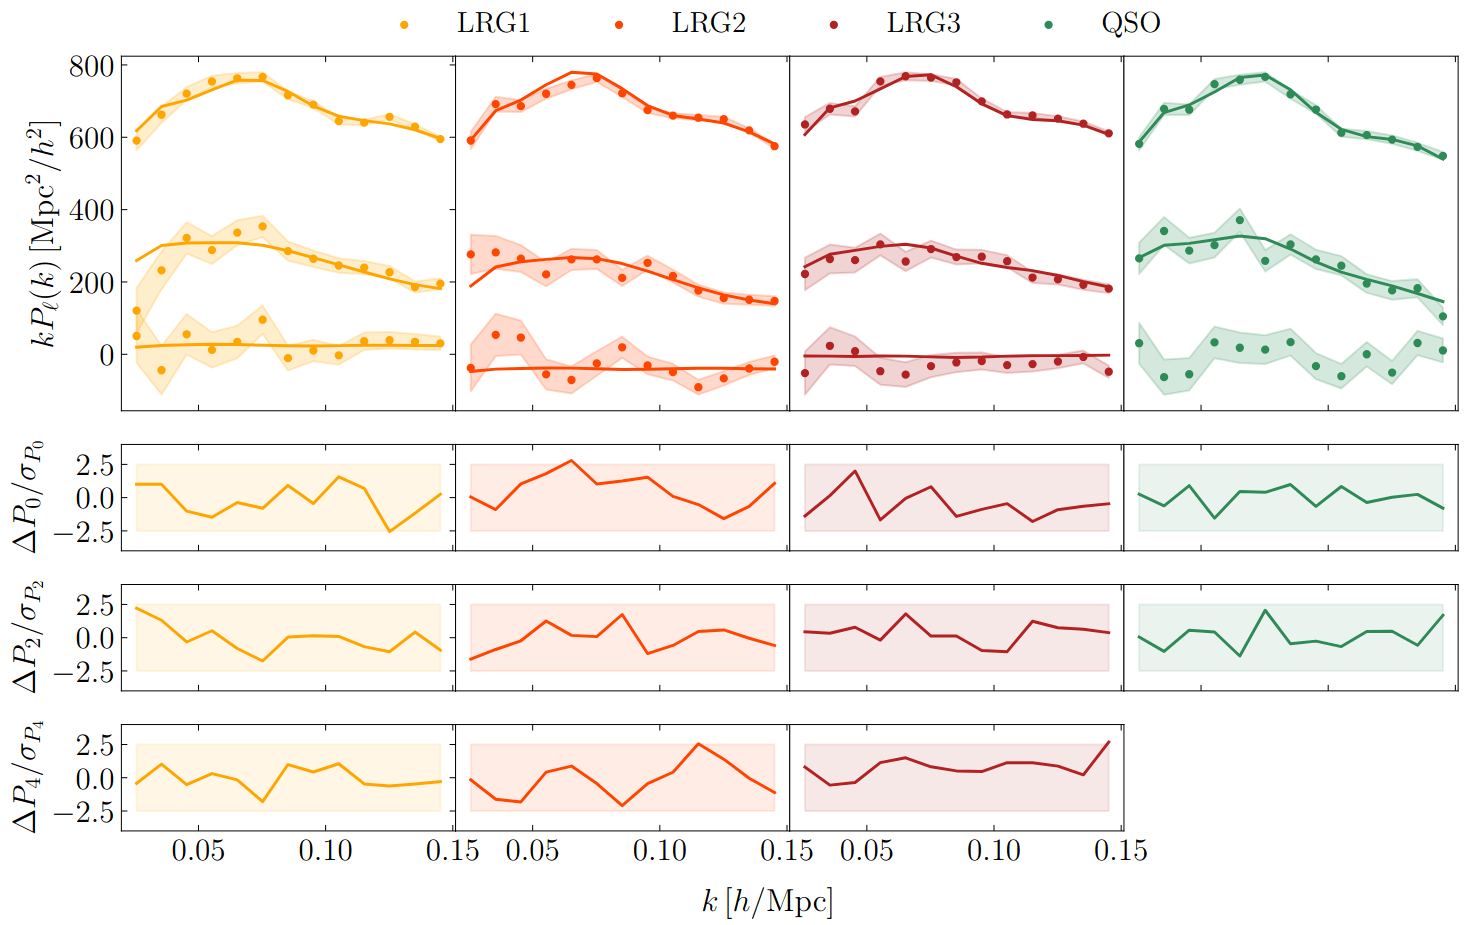
\(P\)
\(\Omega\)
\(\delta_L\)
\(\delta_g\)
Cosmological inference
\(\Omega := \{ \Omega_m, \Omega_\Lambda, H_0, \sigma_8, f_\mathrm{NL},...\}\)
\(\Omega\)
\(\delta_L\)
\(\delta_g\)
inference
-
Sample initial conditions
-
LSS formation: 2LPT or N-body PM
(BullFrog or FastPM) lightcone - EFT-based galaxy bias
- Redshift-Space Distortions
- Observational noise and systematics
Field-Level Modeling and Inference
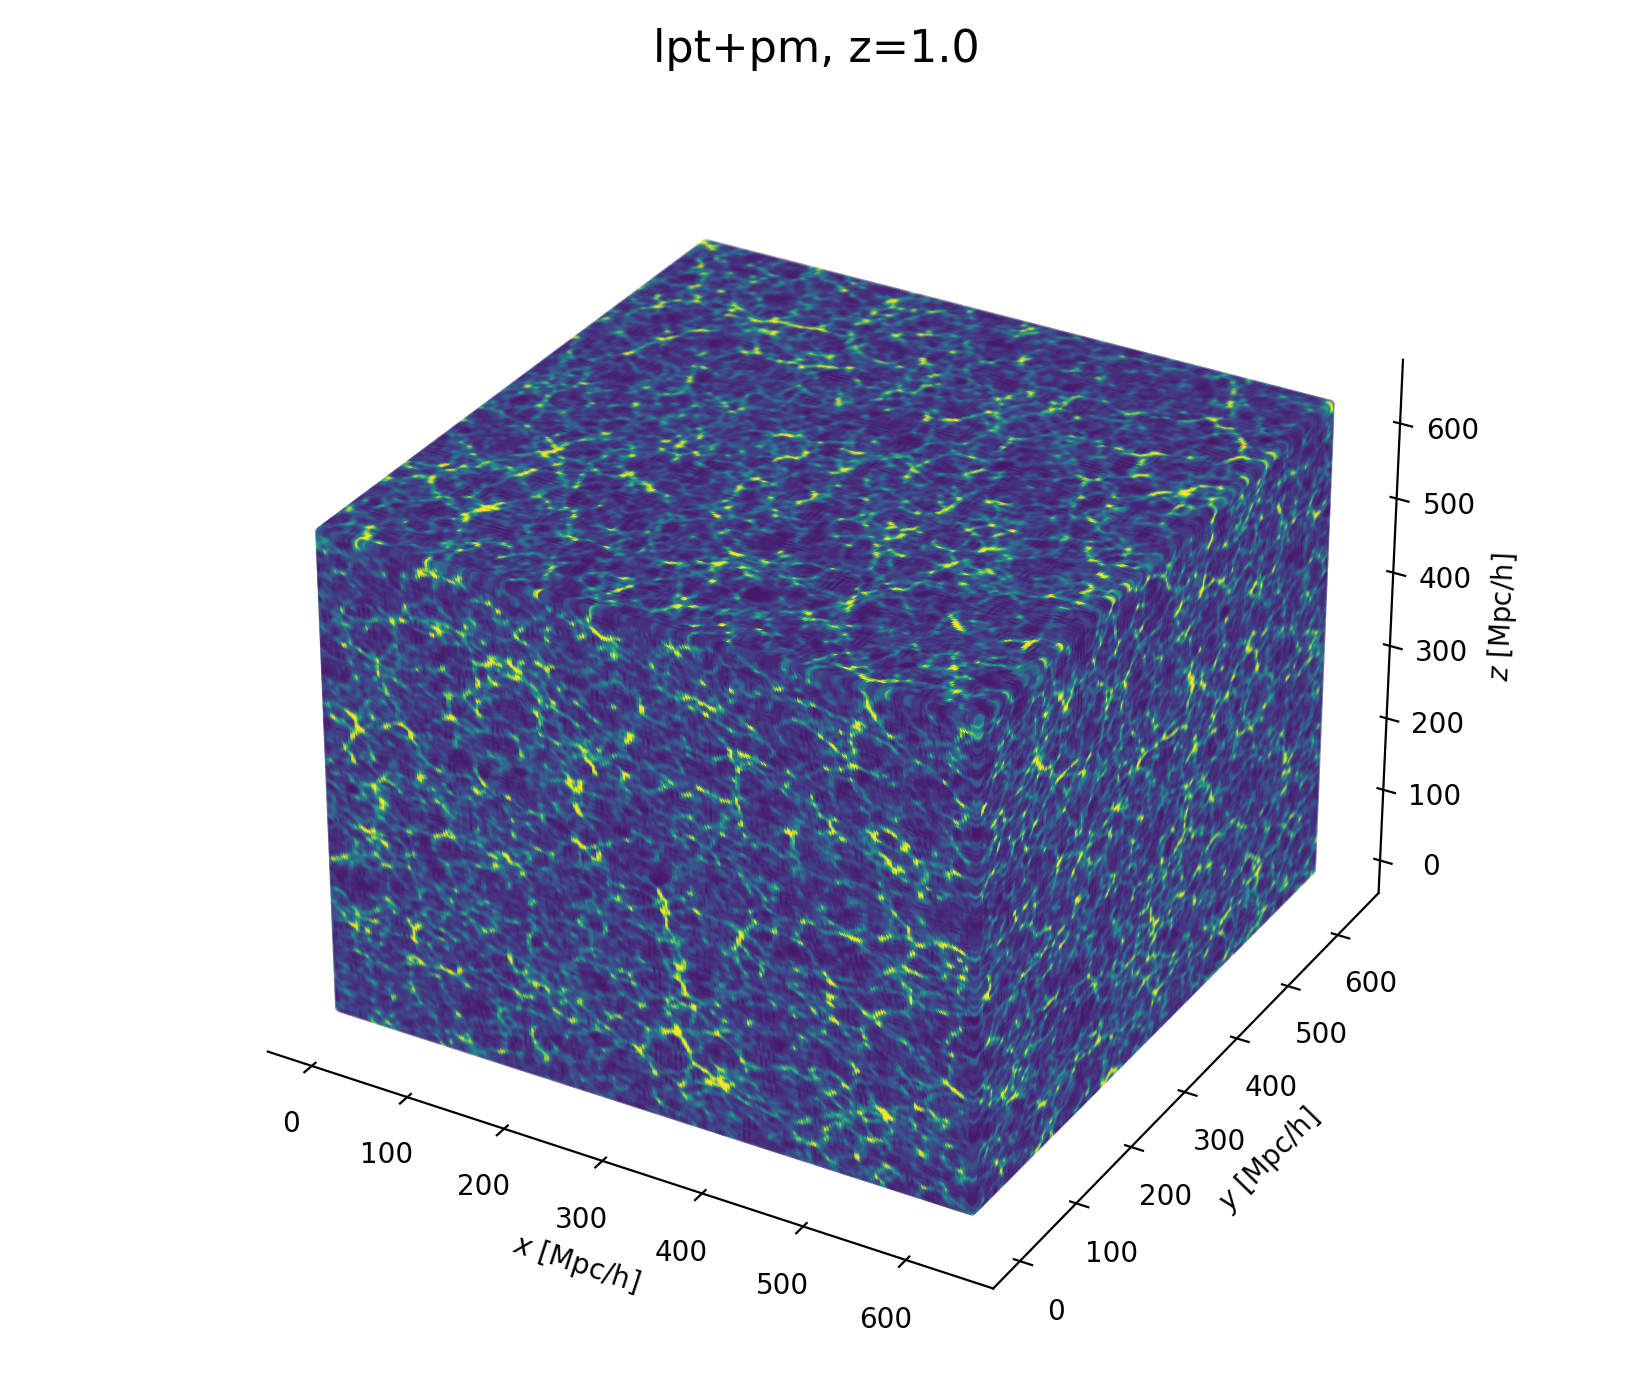
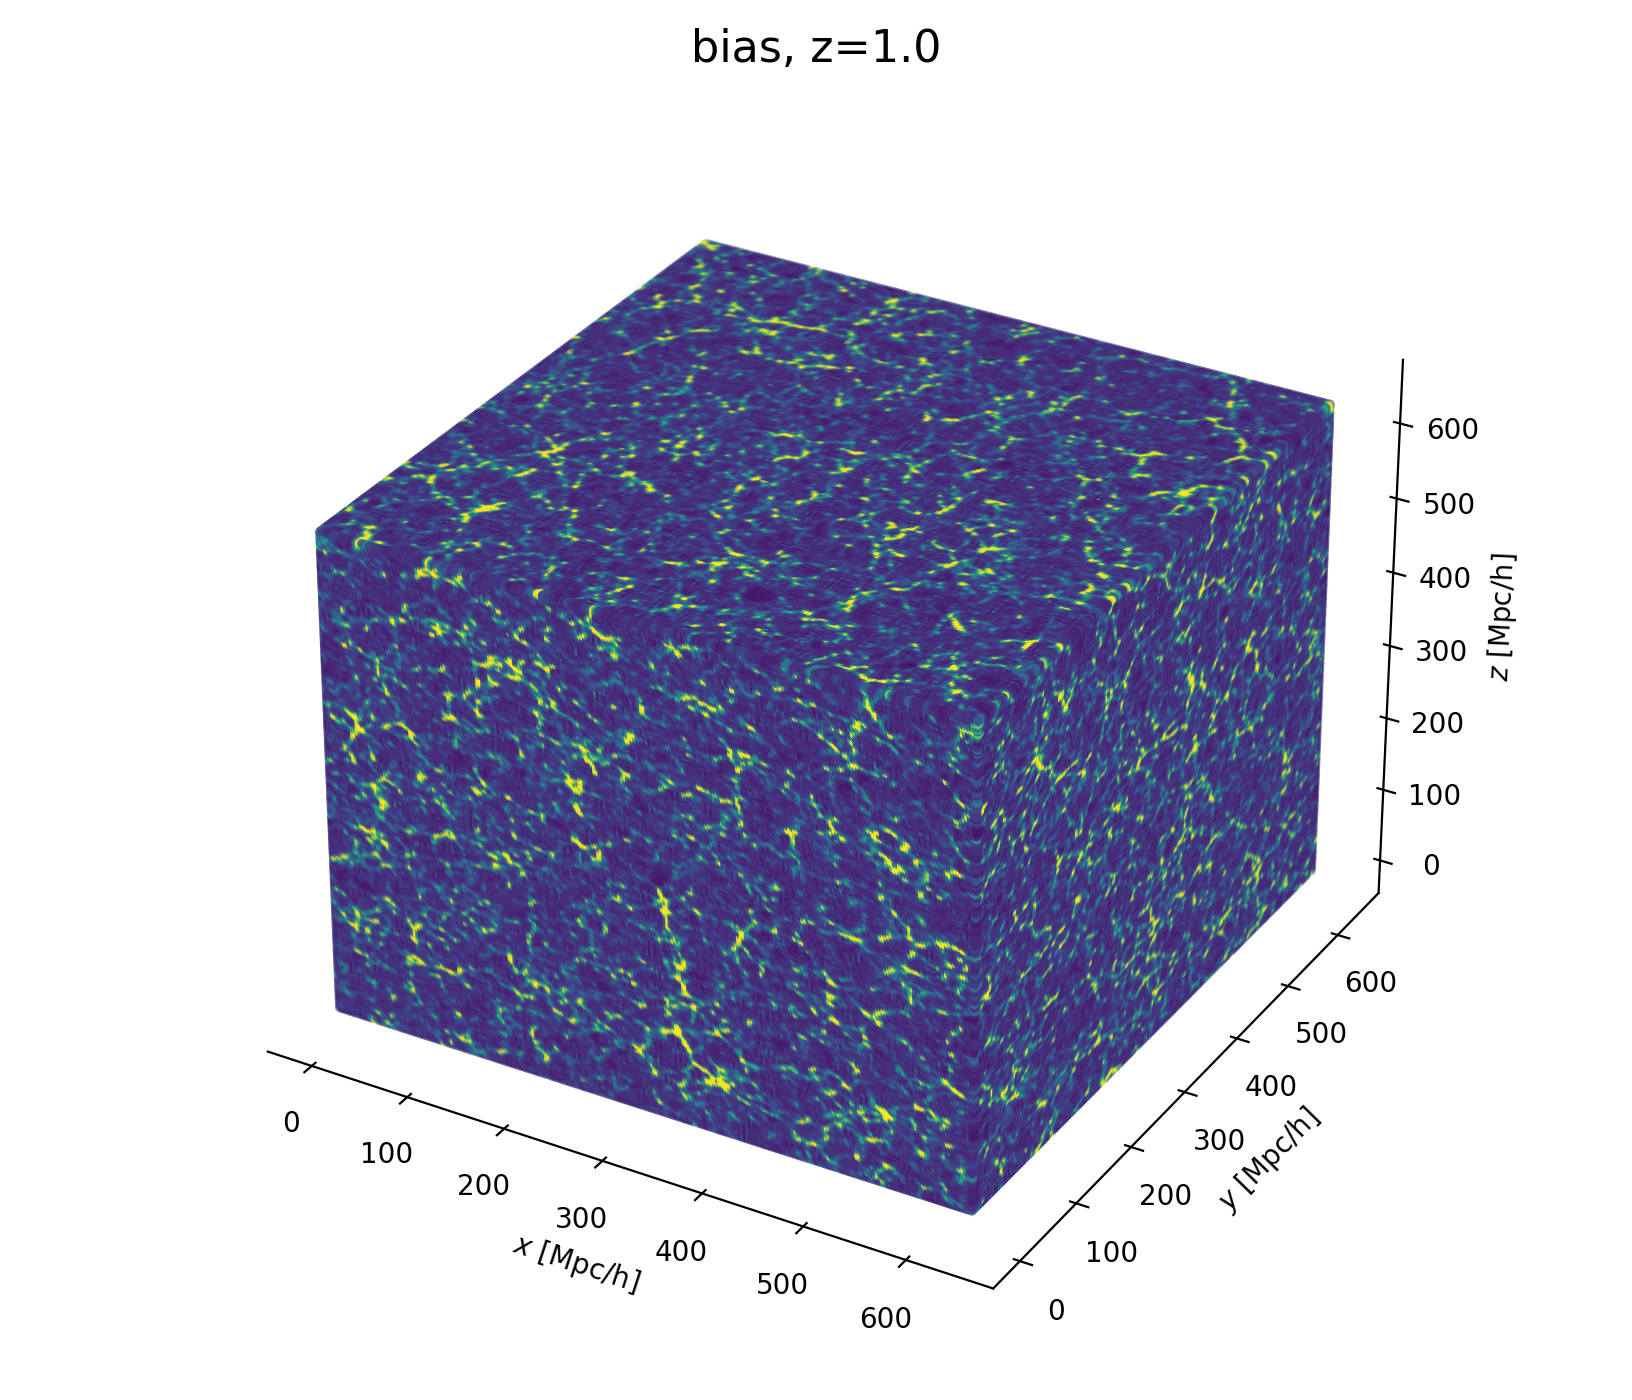
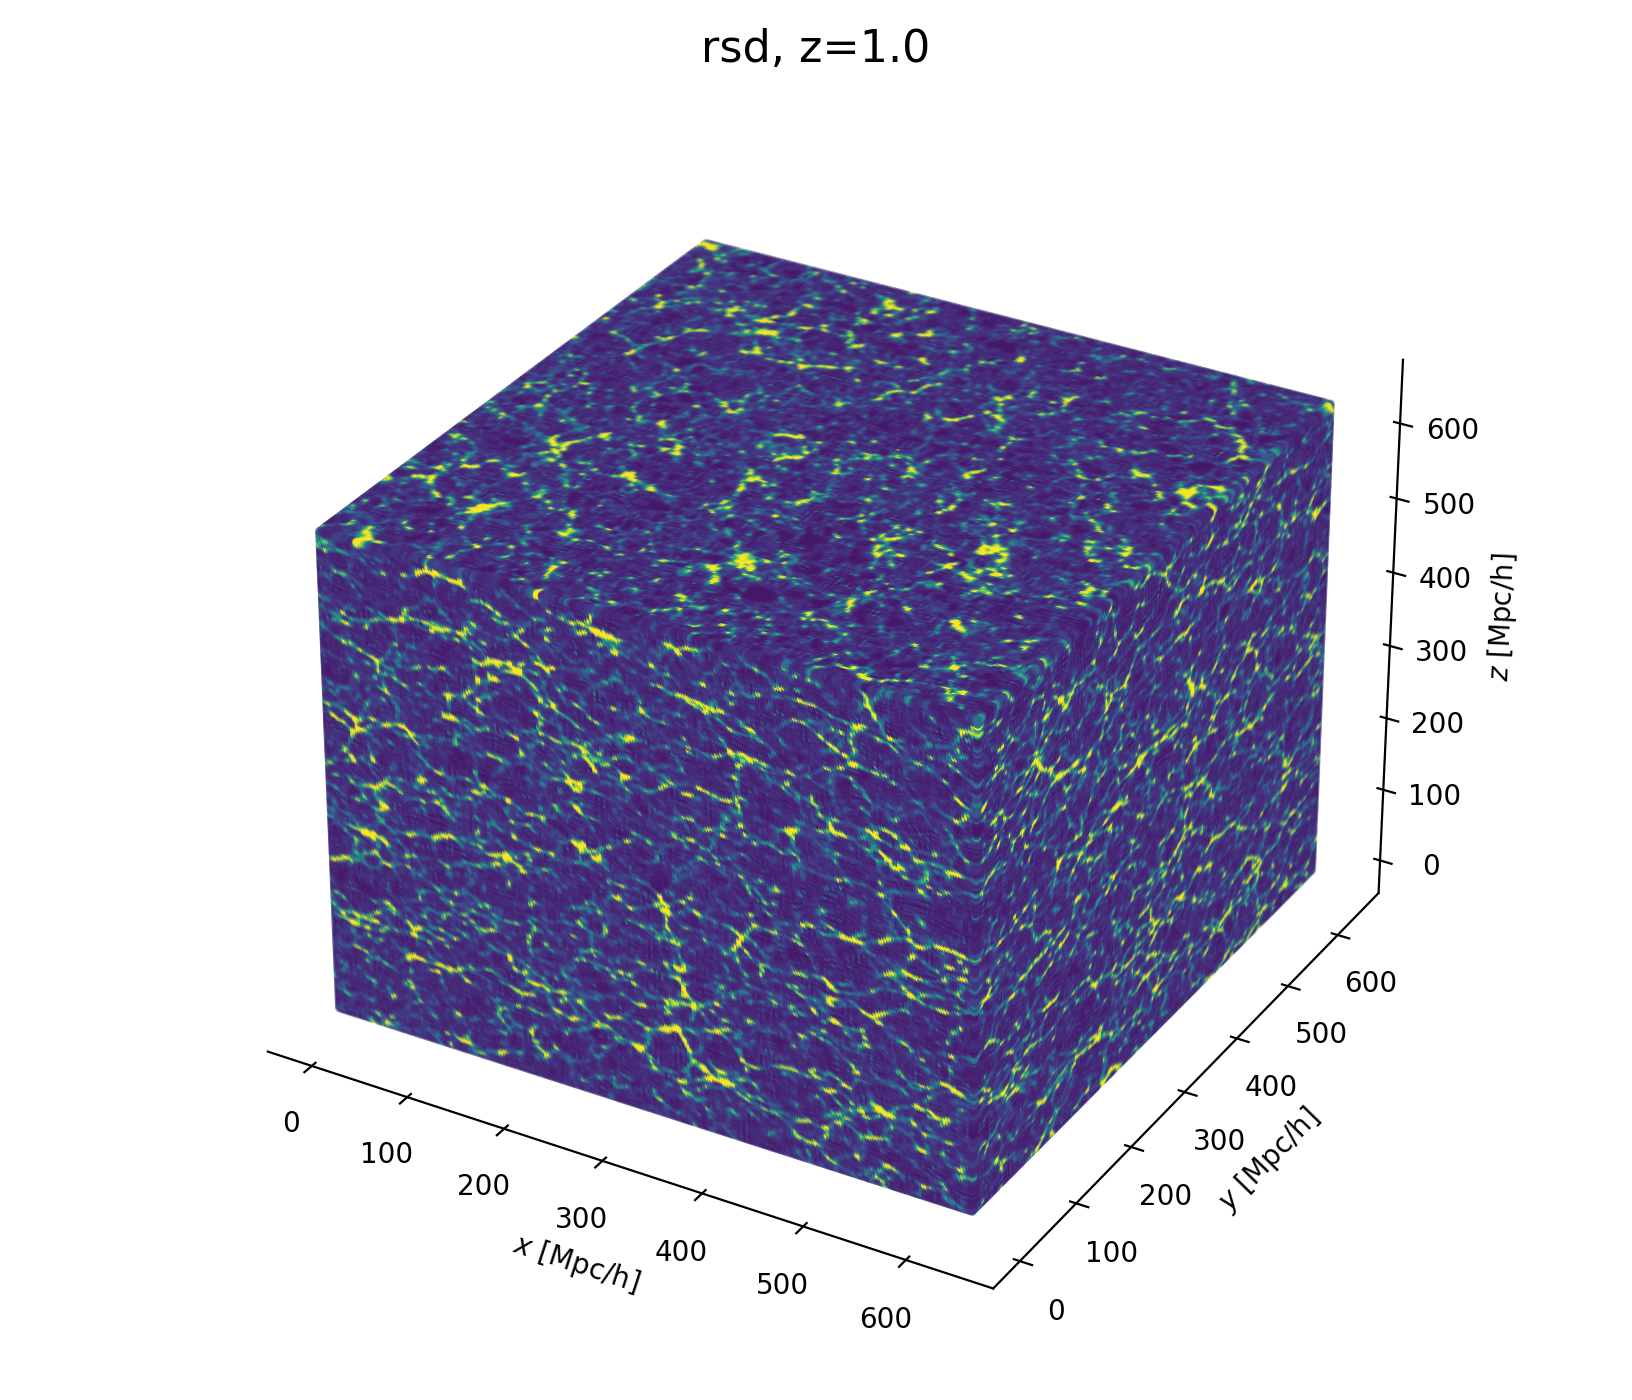
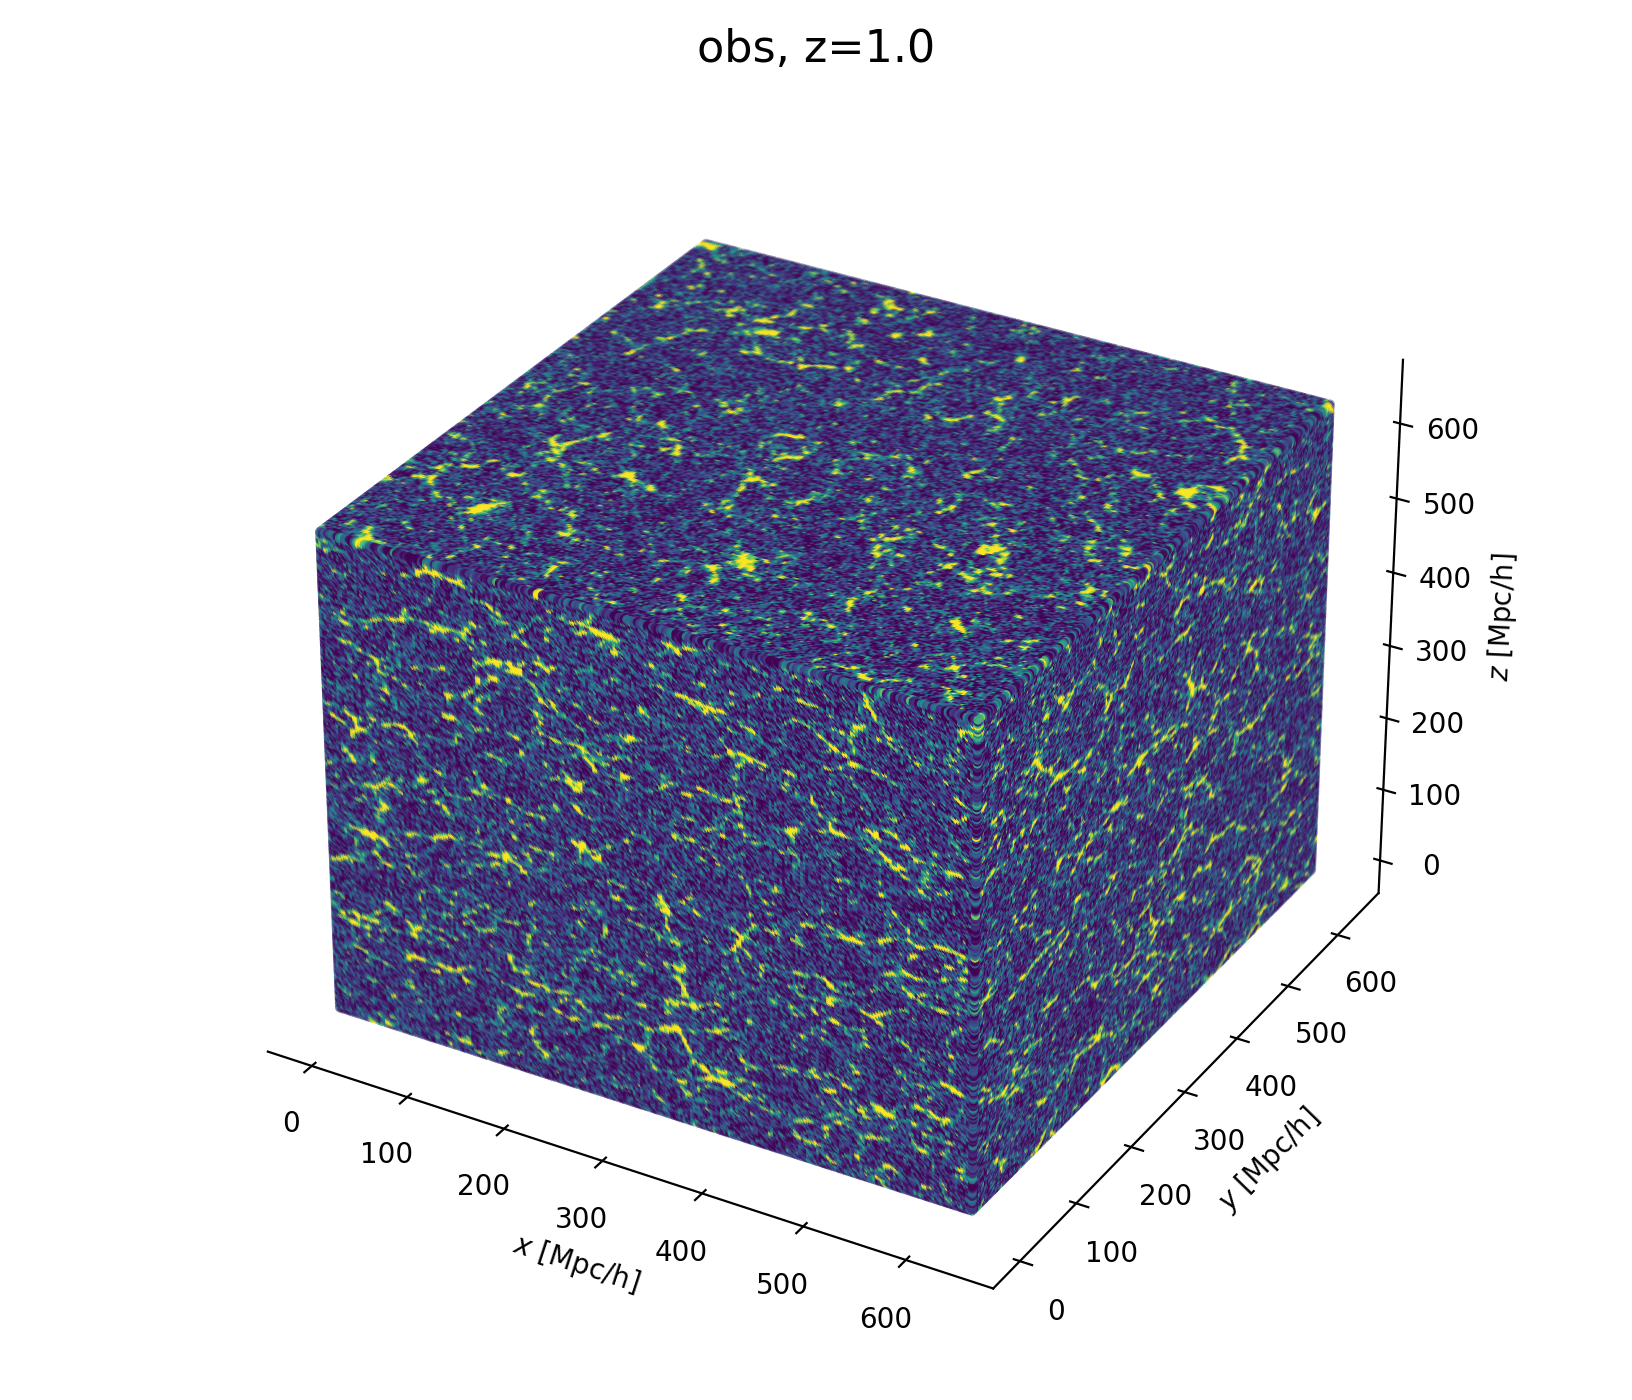
Fast and differentiable model with
+ field-level preconditioning = \(128^3\) PM inference in 4h on a single GPU node
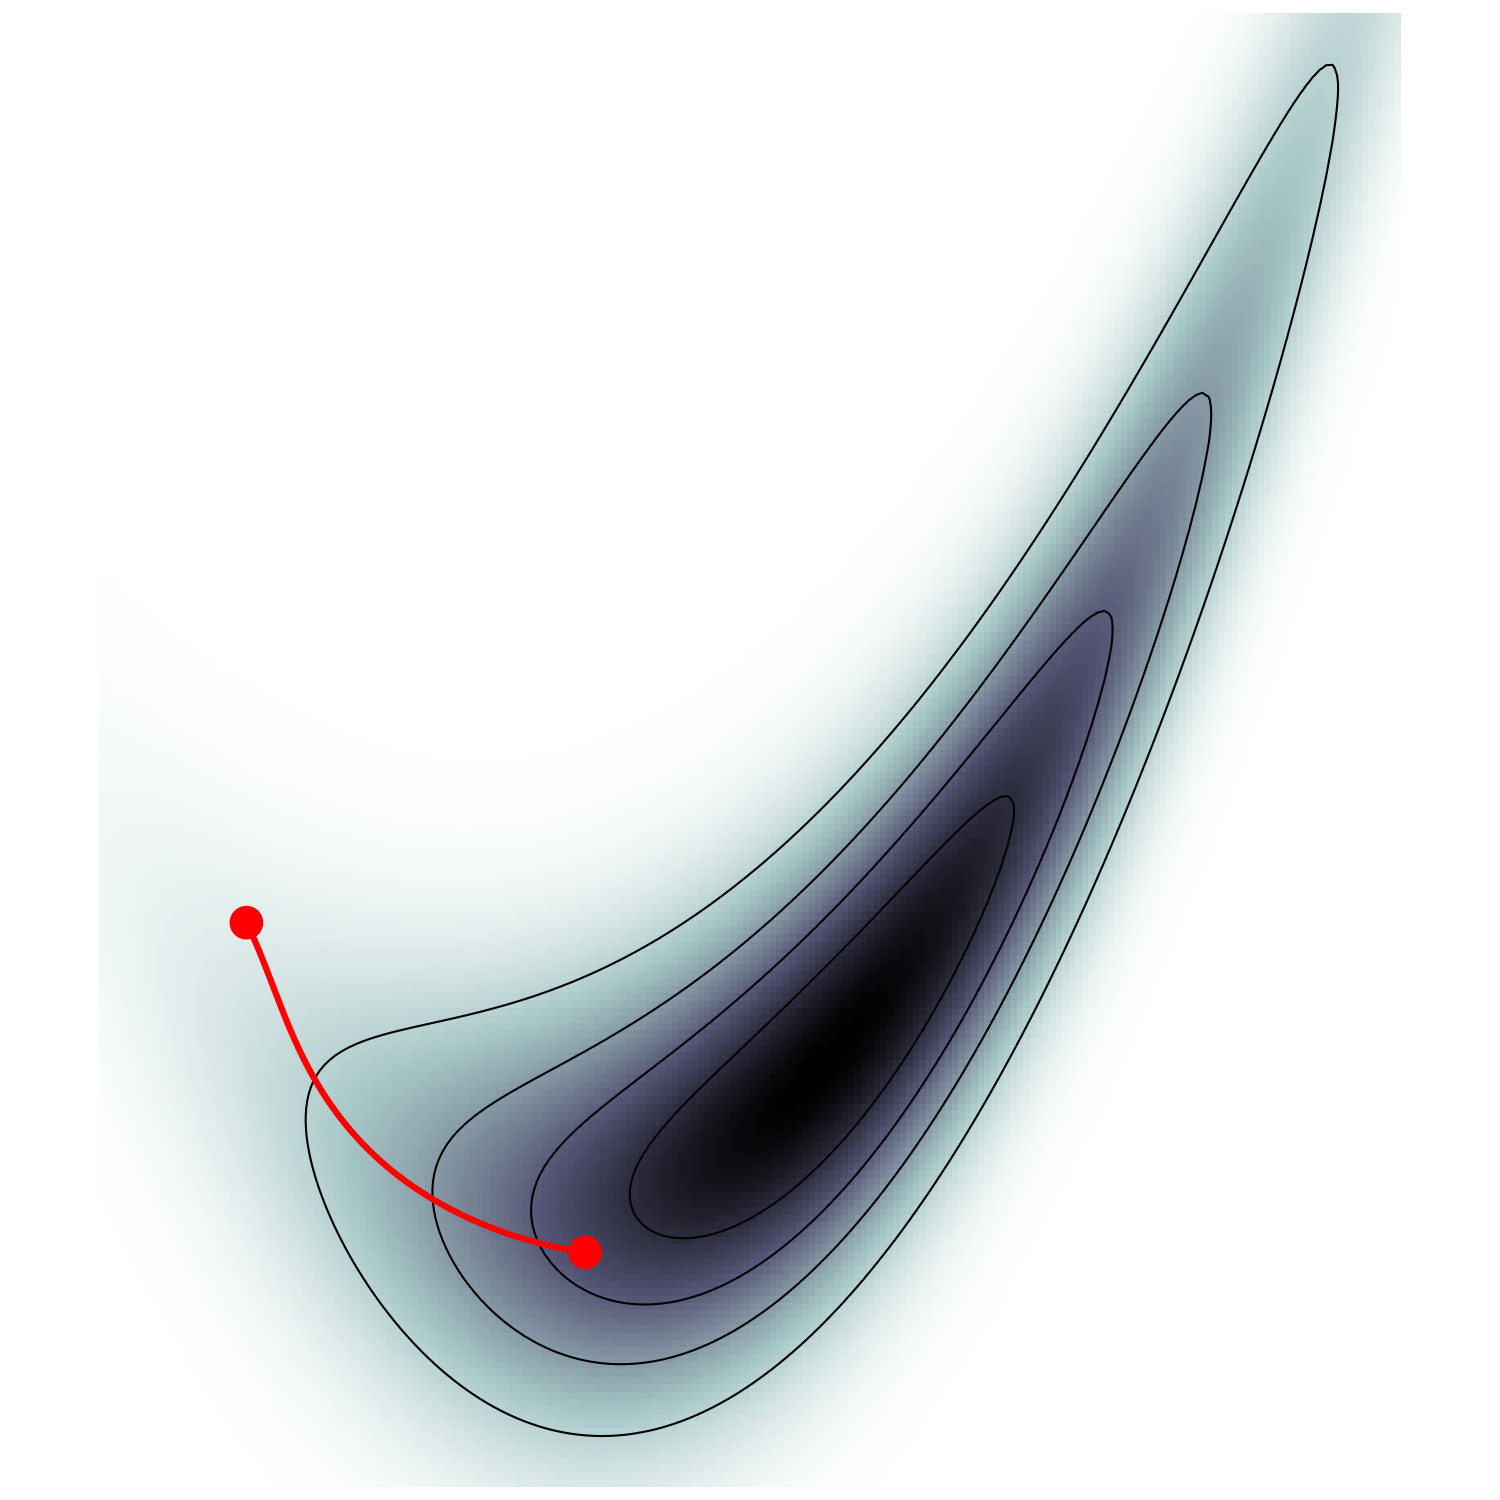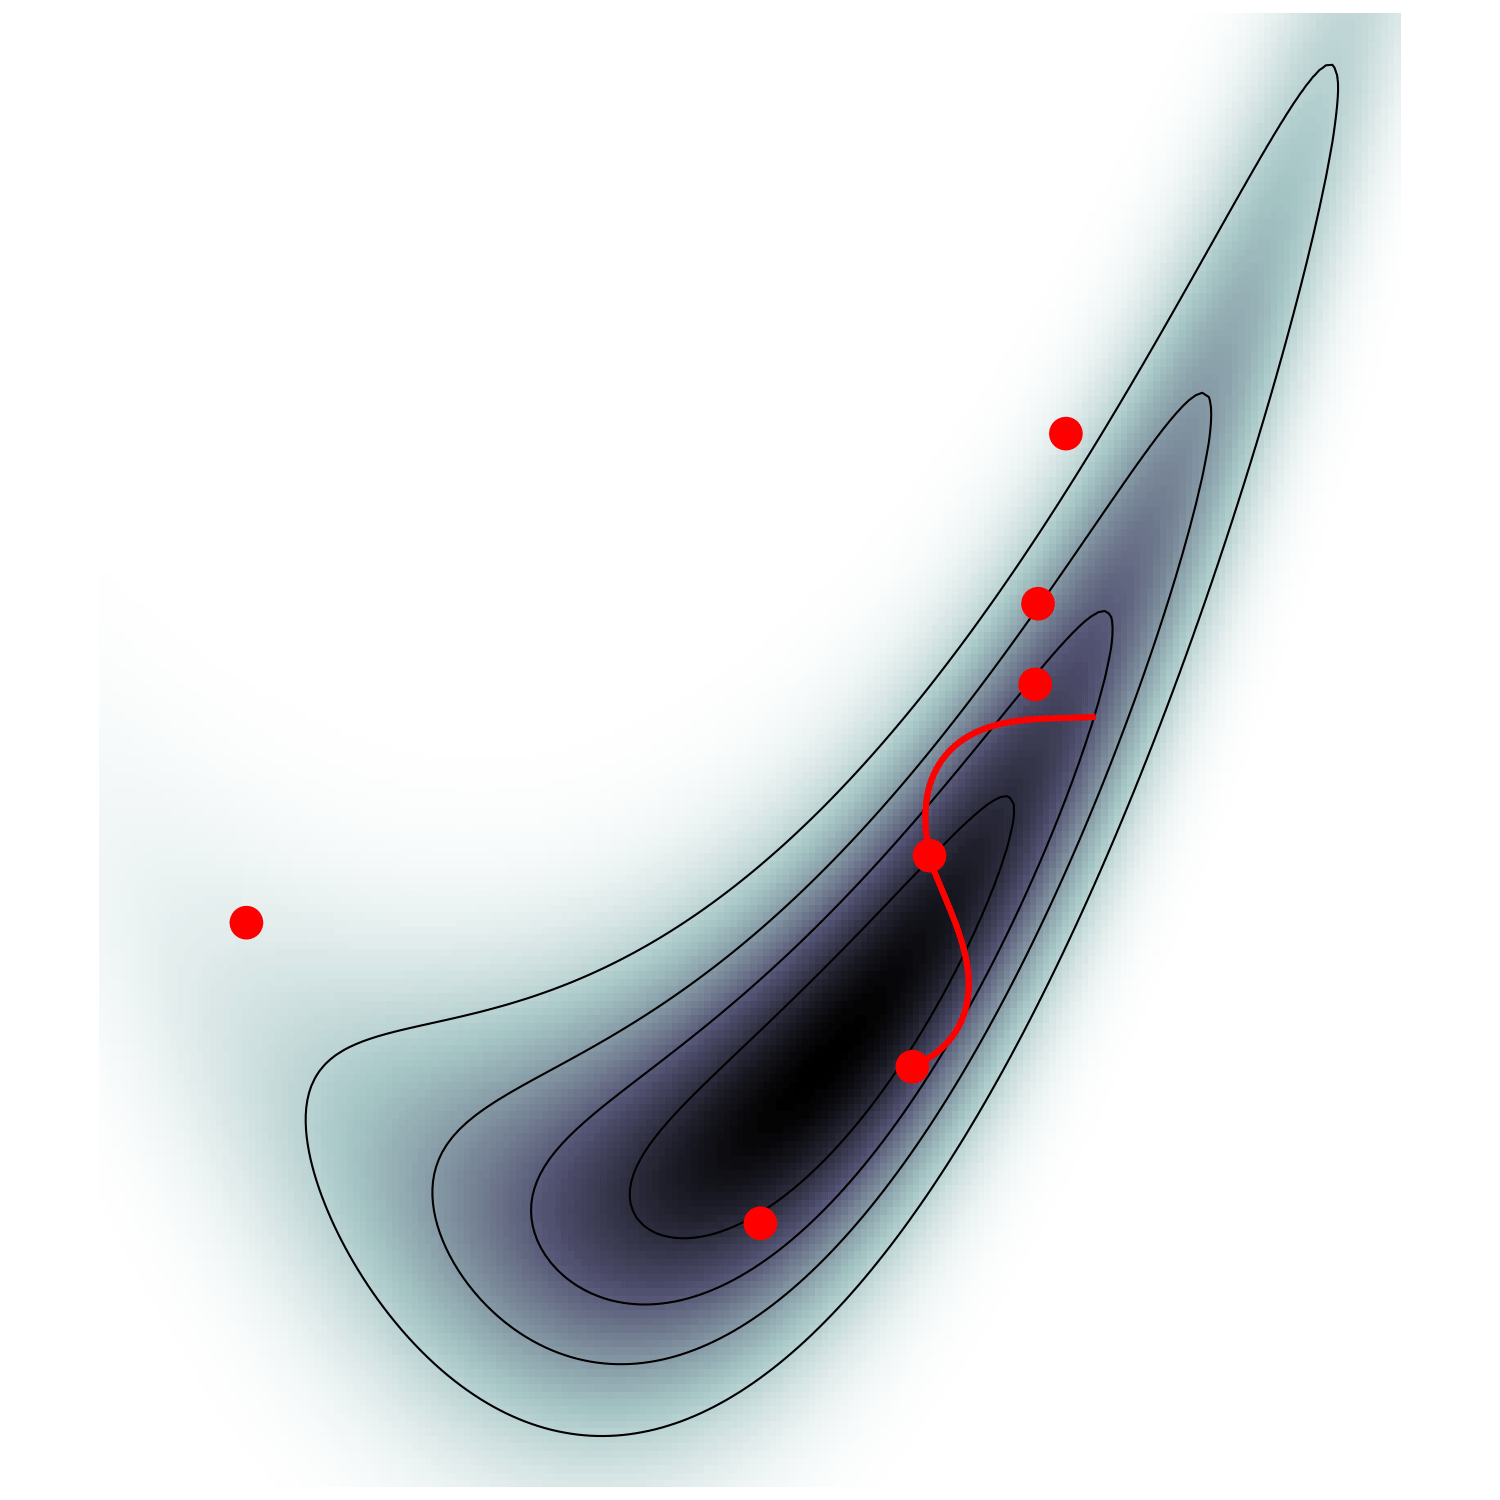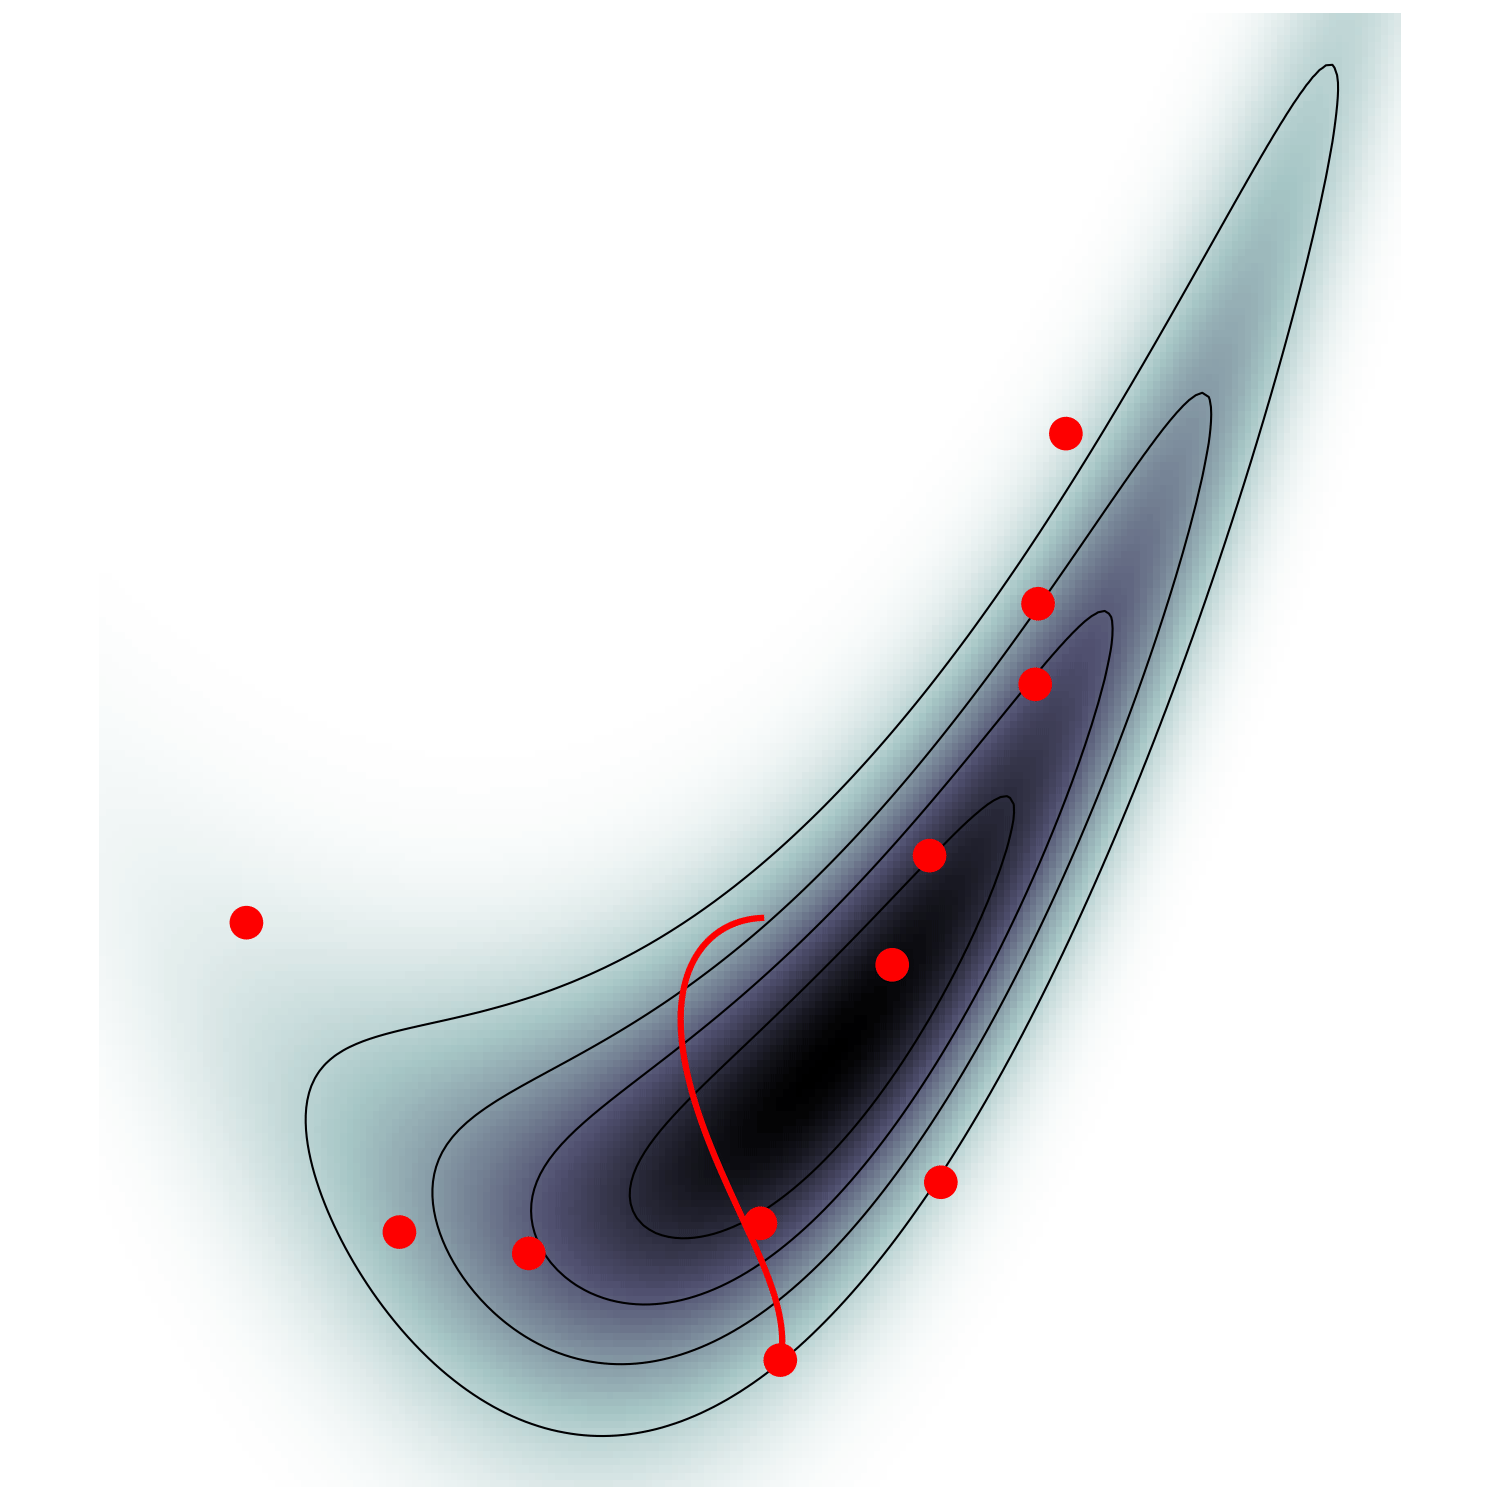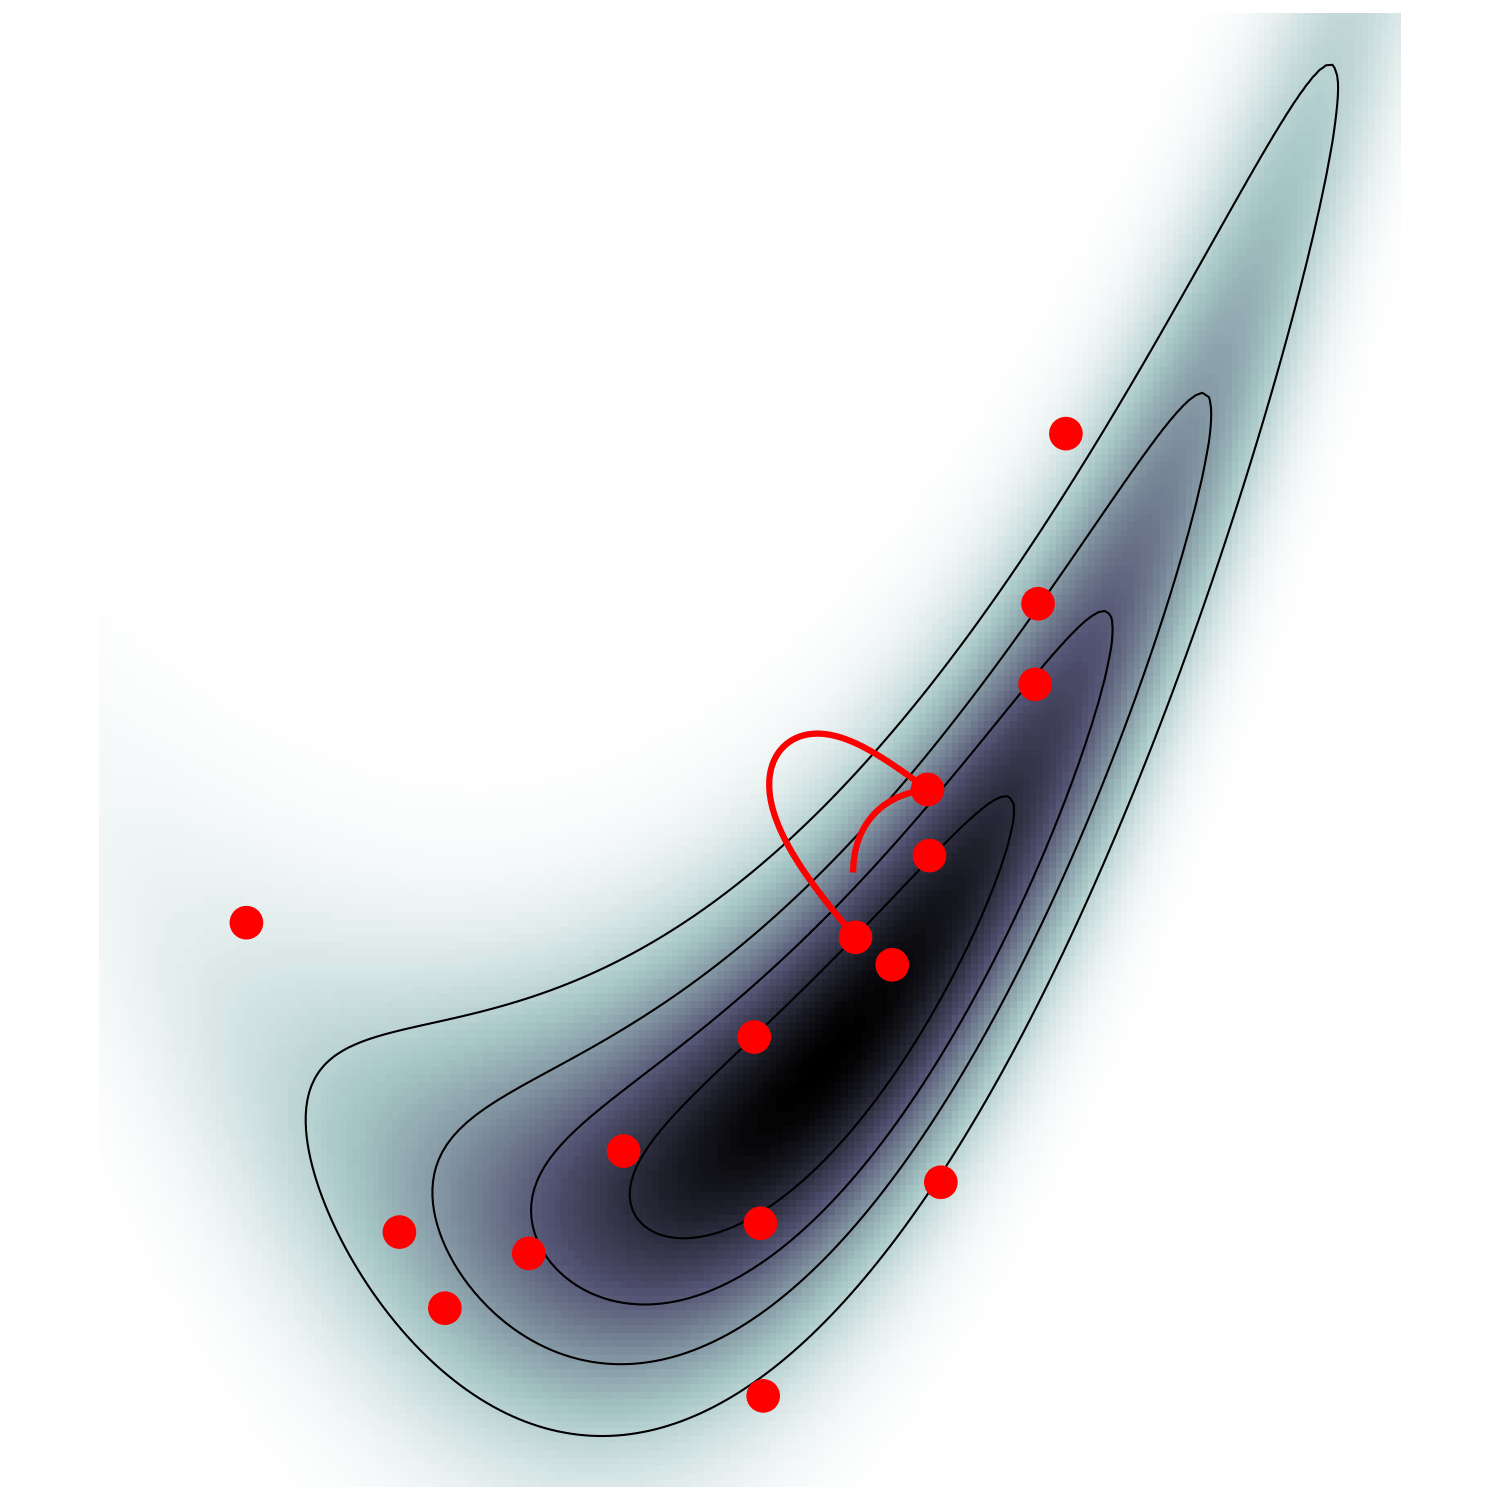
MicroCanonical sampling
+
-
Sample initial conditions
-
LSS formation: 2LPT or N-body PM
(BullFrog or FastPM) lightcone - EFT-based galaxy bias
- Redshift-Space Distortions
- Observational noise and systematics
Fast and differentiable model with
+ field-level preconditioning = \(128^3\) PM inference in 4h on a single GPU node
MicroCanonical sampling
+
Field-Level Modeling and Inference
Primordial Non-Gaussianity from galaxies
Local-type PNG is mostly constrained by the induced scale-dependent bias
\(\phi_{\mathrm{NL}}=\phi+{\color{purple}f_{\mathrm{NL}}}\phi^{2}\)
\(\delta_g(\boldsymbol k)\simeq\left(b_{1}+ b_\phi {\color{purple}f_\mathrm{NL}}k^{-2} \right) \delta_L(\boldsymbol k)\)
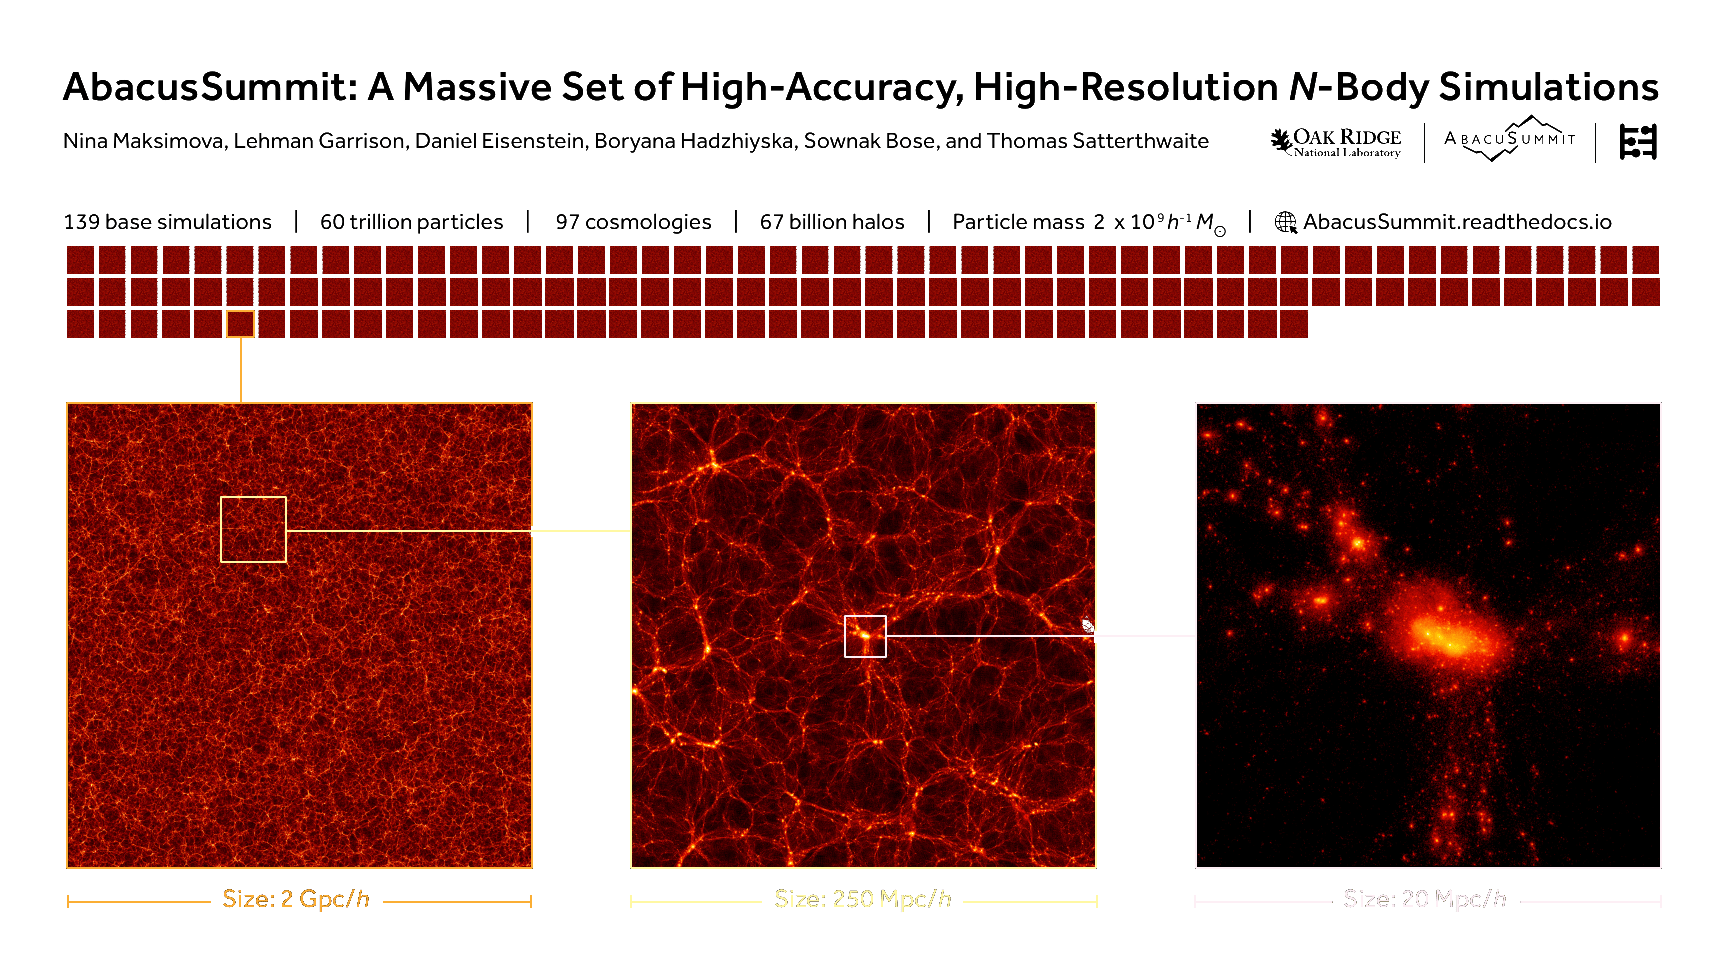
Ideal first demonstration for FLI
- Most of signal from easier large scales
- Result very sensitive to systematics, more directly implemented at field-level
- Bonus: fully explicit/explainable, no black box modeling
- Validate on DESI reference simulations: HOD-populated N-body AbacusSummit
Field-Level modeling of PNG
-
Sample initial conditions and add PNG
$$\phi_{\mathrm{NL}}=\phi+{\color{purple}f_{\mathrm{NL}}}\phi^{2}$$ - Compute Lagrangian bias of particles at \(\boldsymbol q^\mathrm{in}\) $$\mathcal O_{\rm L}=1+{\color{purple}b_{1}}\,\delta_{\rm L}+{\color{purple}b_{2}}\delta_{\rm L}^{2}+{\color{purple}b_{s^2}}s^{2}+ {\color{purple}b_{\nabla^2}} \nabla^2 \delta _{\rm L}\\\!\!\!\!\!\!\! + {\color{purple}f_{\rm NL} b_\phi}\phi + {\color{purple} f_{\rm NL} b_{\phi\delta}} \phi \delta_{\rm L}$$
-
Displace particles to \(\boldsymbol q^\mathrm{fin}\)
\(\boldsymbol q^\mathrm{fin} = \boldsymbol q^\mathrm{2LPT} + H^{-1}\dot {\boldsymbol q}^\mathrm{2LPT}_\parallel + {\color{purple}b_{\nabla_\parallel}} \nabla_\parallel \delta_\mathrm{L}(\boldsymbol q^\mathrm{in})\) -
Paint particles on grid with kernel \(K\) and weight \(\mathcal O_{\rm L}\)
$$(1+\delta_g)(\boldsymbol x) = \int K(\boldsymbol x - \boldsymbol q^\mathrm{fin}) \mathcal O_L(\boldsymbol q^\mathrm{in})\, \mathrm d \boldsymbol q^\mathrm{in}$$ -
Noise via galaxy stochasticity
$$n_g \sim \mathcal N({\color{purple} \bar n_g} (1+\delta_g),\, {\color{purple}\bar n_g \sigma_0}(1+{\color{purple}\sigma_\delta}\delta_g))$$
3 PNG parameters, 2 options:
- infer the 3 as independent
- assume "universality" relations
$$\begin{align*}b_\phi &=2\delta_c({\color{purple} b_1}+1-p)\\b_{\phi \delta} &=2 (\delta_c {\color{purple} b_2}+ {\color{purple} b_1})\end{align*}$$(Lagrangian form)
Fast and differentiable model with
- Sample initial conditions and add PNG
$$\phi_{\mathrm{NL}}=\phi+{\color{purple}f_{\mathrm{NL}}}\phi^{2}$$ - Compute Lagrangian bias of particles at \(\boldsymbol q^\mathrm{in}\) $$\mathcal O_{\rm L}=1+{\color{purple}b_{1}}\delta_{\rm L}+{\color{purple}b_{2}}\delta_{\rm L}^{2}+{\color{purple}b_{s^2}}s^{2}+ {\color{purple}b_{\nabla^2}} \nabla^2 \delta _{\rm L}\\\!\!\!\!\!\!\! + {\color{purple}f_{\rm NL} b_\phi}\phi + {\color{purple} f_{\rm NL} b_{\phi\delta}} \phi \delta_{\rm L}$$
- Displace particles to \(\boldsymbol q^\mathrm{fin}\)
\(\boldsymbol q^\mathrm{fin} = \boldsymbol q^\mathrm{2LPT} + H^{-1}\dot {\boldsymbol q}^\mathrm{2LPT}_\parallel + {\color{purple}b_{\nabla_\parallel}} \nabla_\parallel \delta_\mathrm{L}(\boldsymbol q^\mathrm{in})\) - Paint particles on grid with kernel \(K\) and weight \(\mathcal O_{\rm L}\)
$$(1+\delta_g)(\boldsymbol x) = \int K(\boldsymbol x - \boldsymbol q^\mathrm{fin}) \mathcal O_L(\boldsymbol q^\mathrm{in})\, \mathrm d \boldsymbol q^\mathrm{in}$$ - Noise via galaxy stochasticity
$$n_g \sim \mathcal N({\color{purple} \bar n_g} (1+\delta_g),\, {\color{purple}\bar n_g \sigma_0}(1+{\color{purple}\sigma_\delta}\delta_g))$$
Fast and differentiable model with
In practice, discreteness reduction: oversampling, deconvolution, interlacing, kernel choice (NUFFT-like)

\(k_\mathrm{evolve}\)
(LPT, bias)
\(k_\mathrm{paint}\)
\(k_\mathrm{final}\)
\(k_\mathrm{init}\)
Field-Level modeling of PNG
Field-Level modeling of PNG
\(k_\mathrm{evolve}\)
(LPT, bias)
\(k_\mathrm{paint}\)
\(k_\mathrm{final}\)
\(k_\mathrm{init}\)
\(k_\mathrm{evolve}\)
(LPT, bias)
\(k_\mathrm{paint}\)
\(k_\mathrm{final}\)
\(k_\mathrm{init}\)
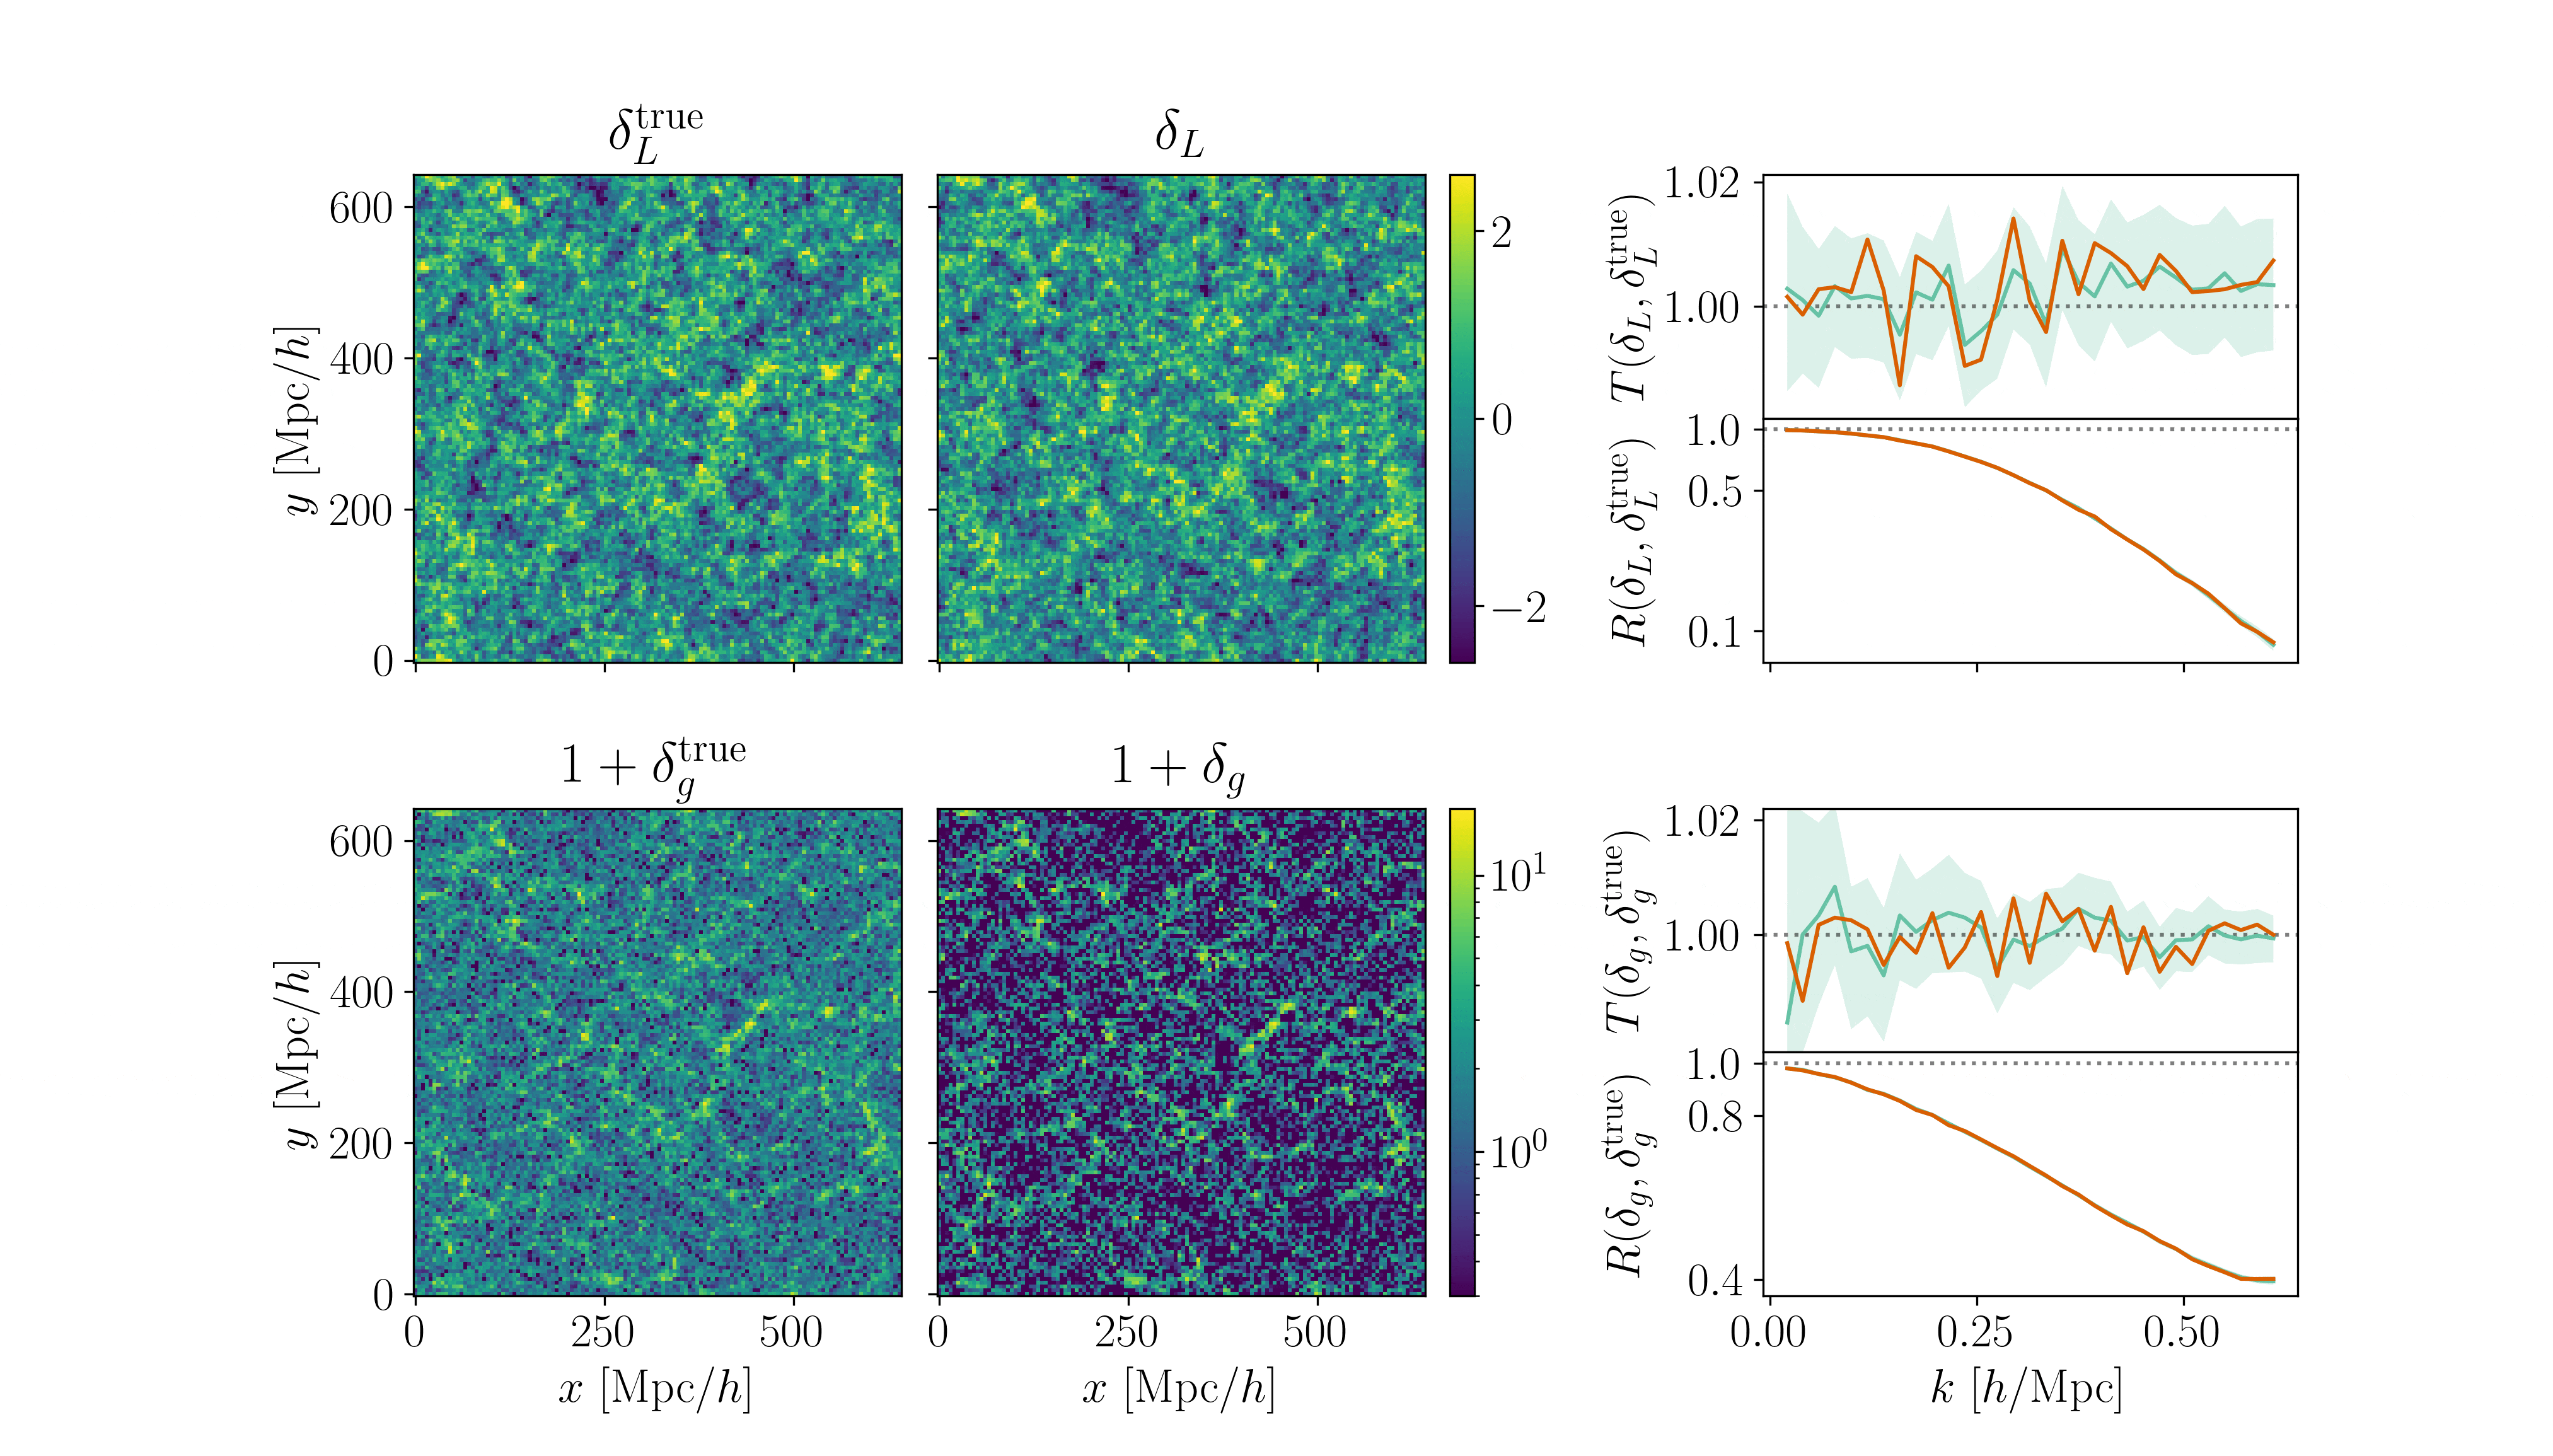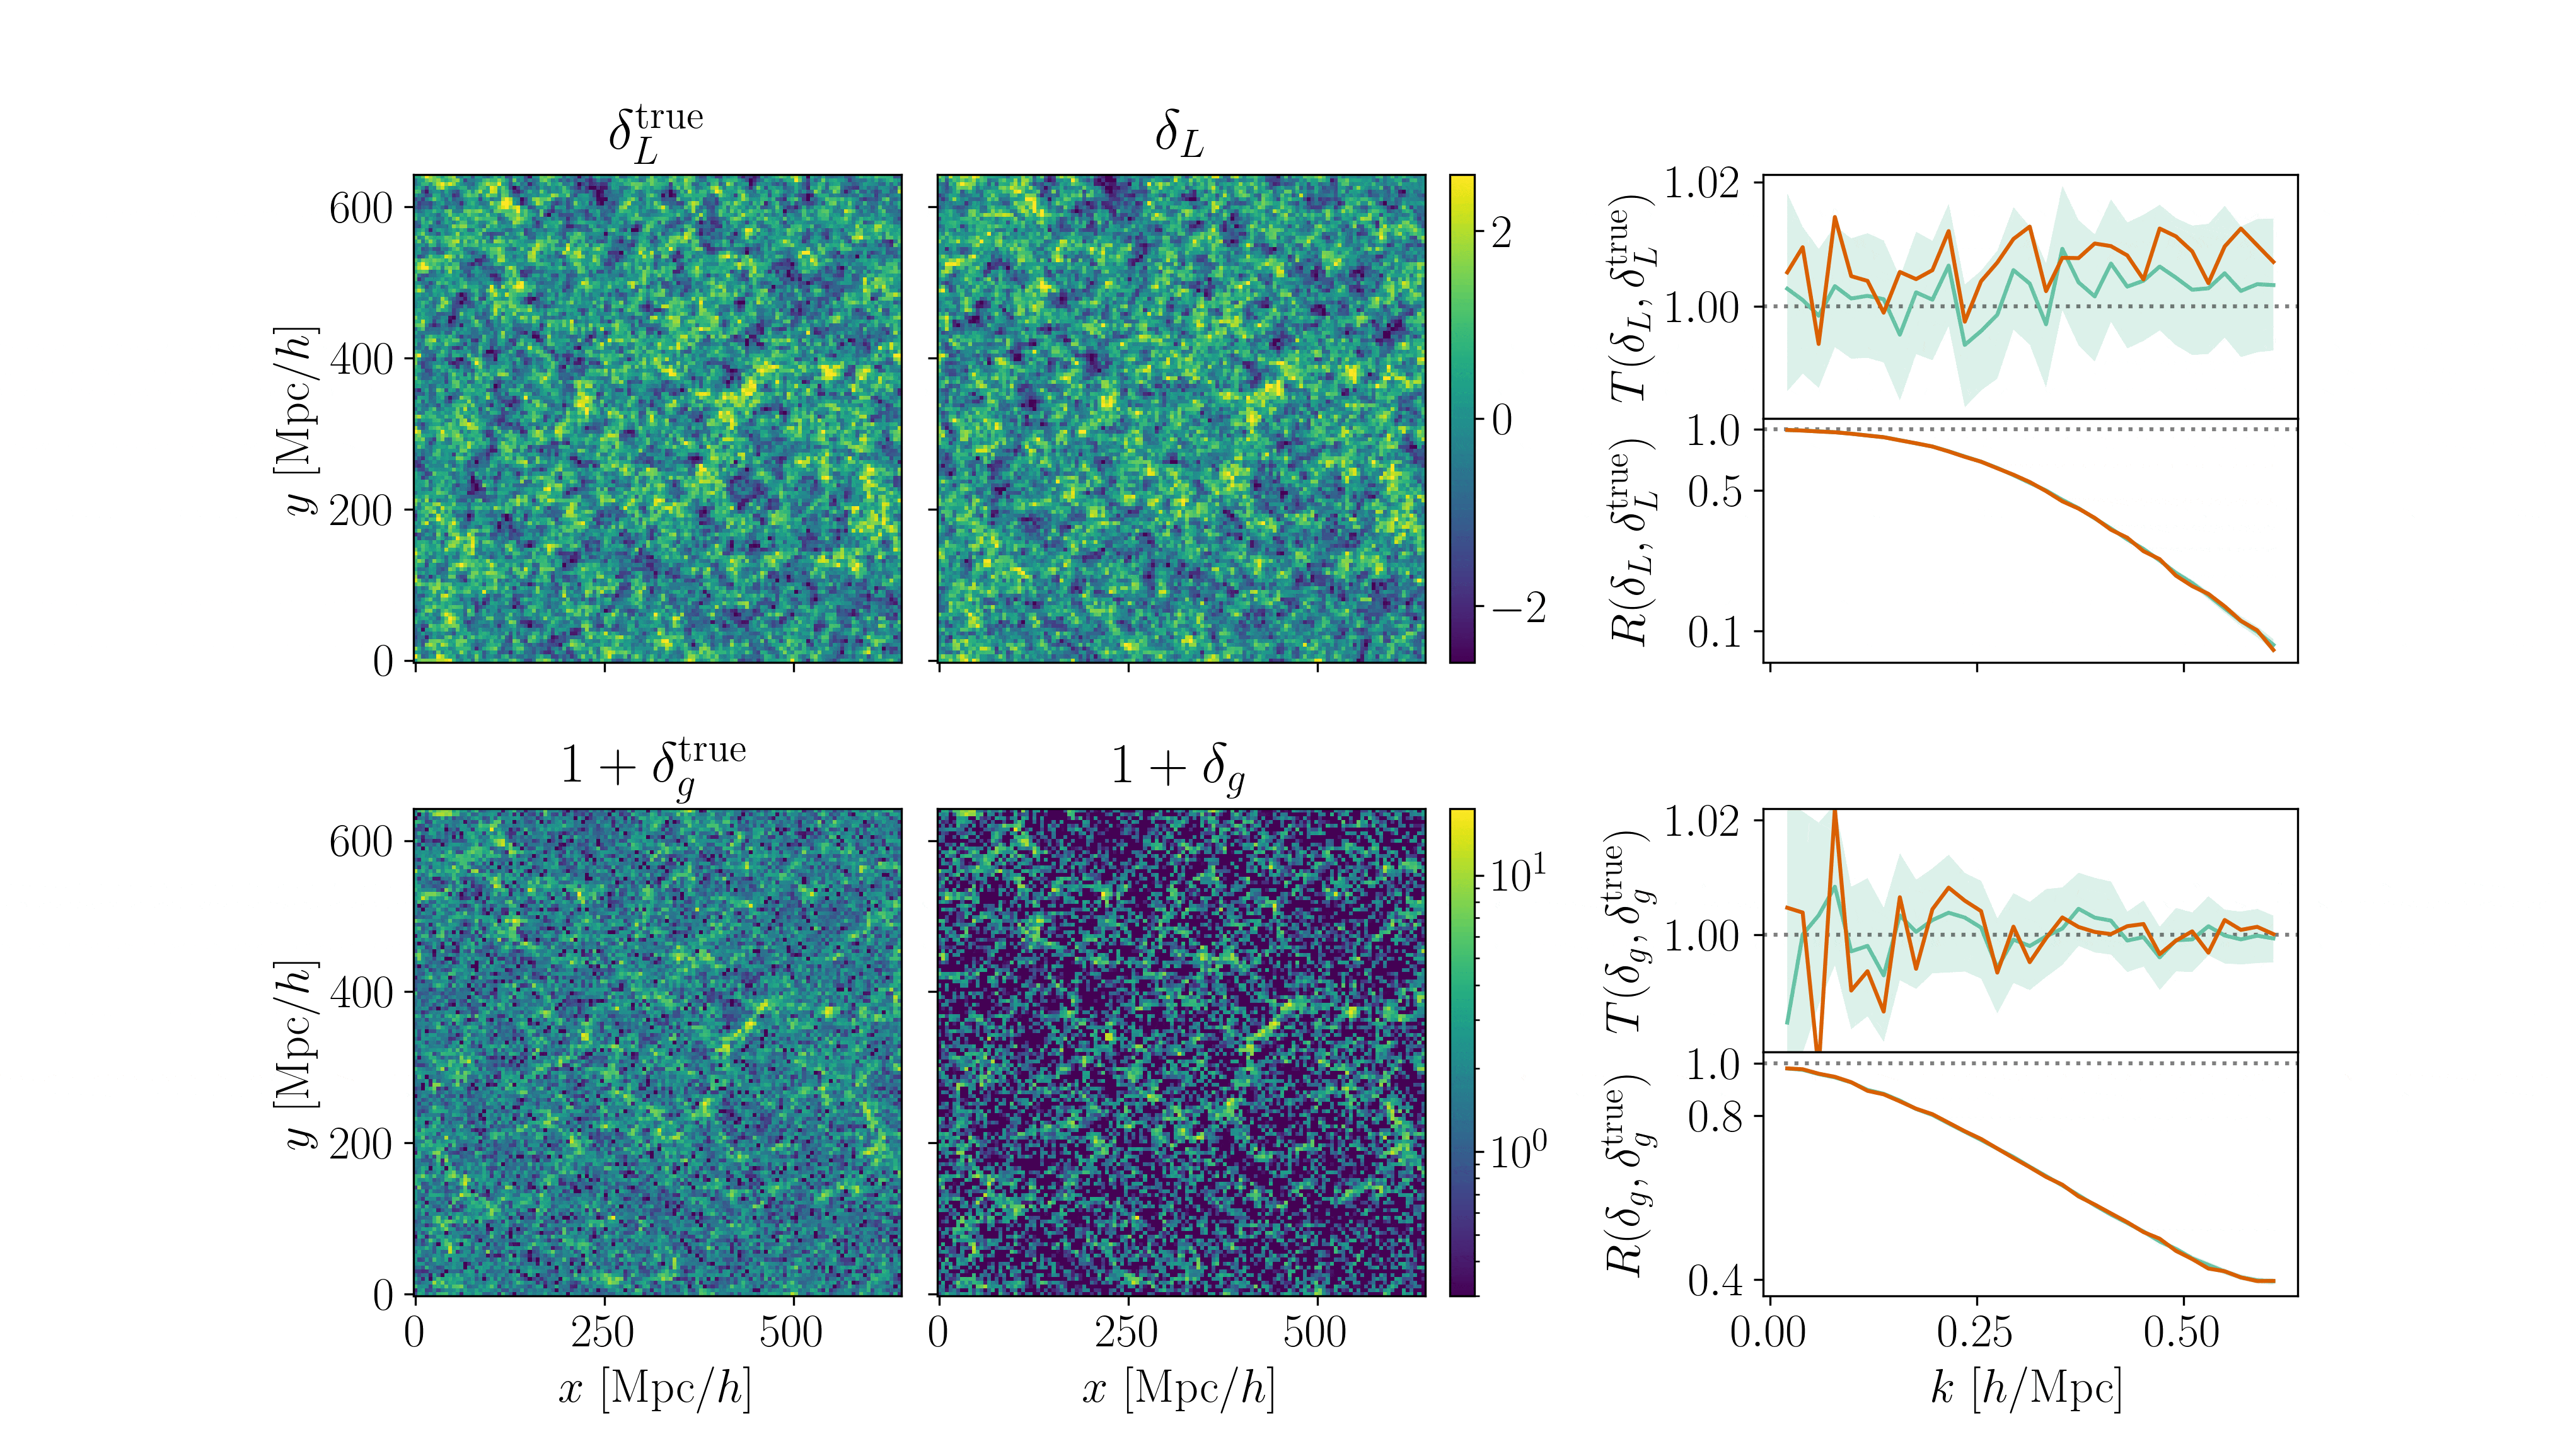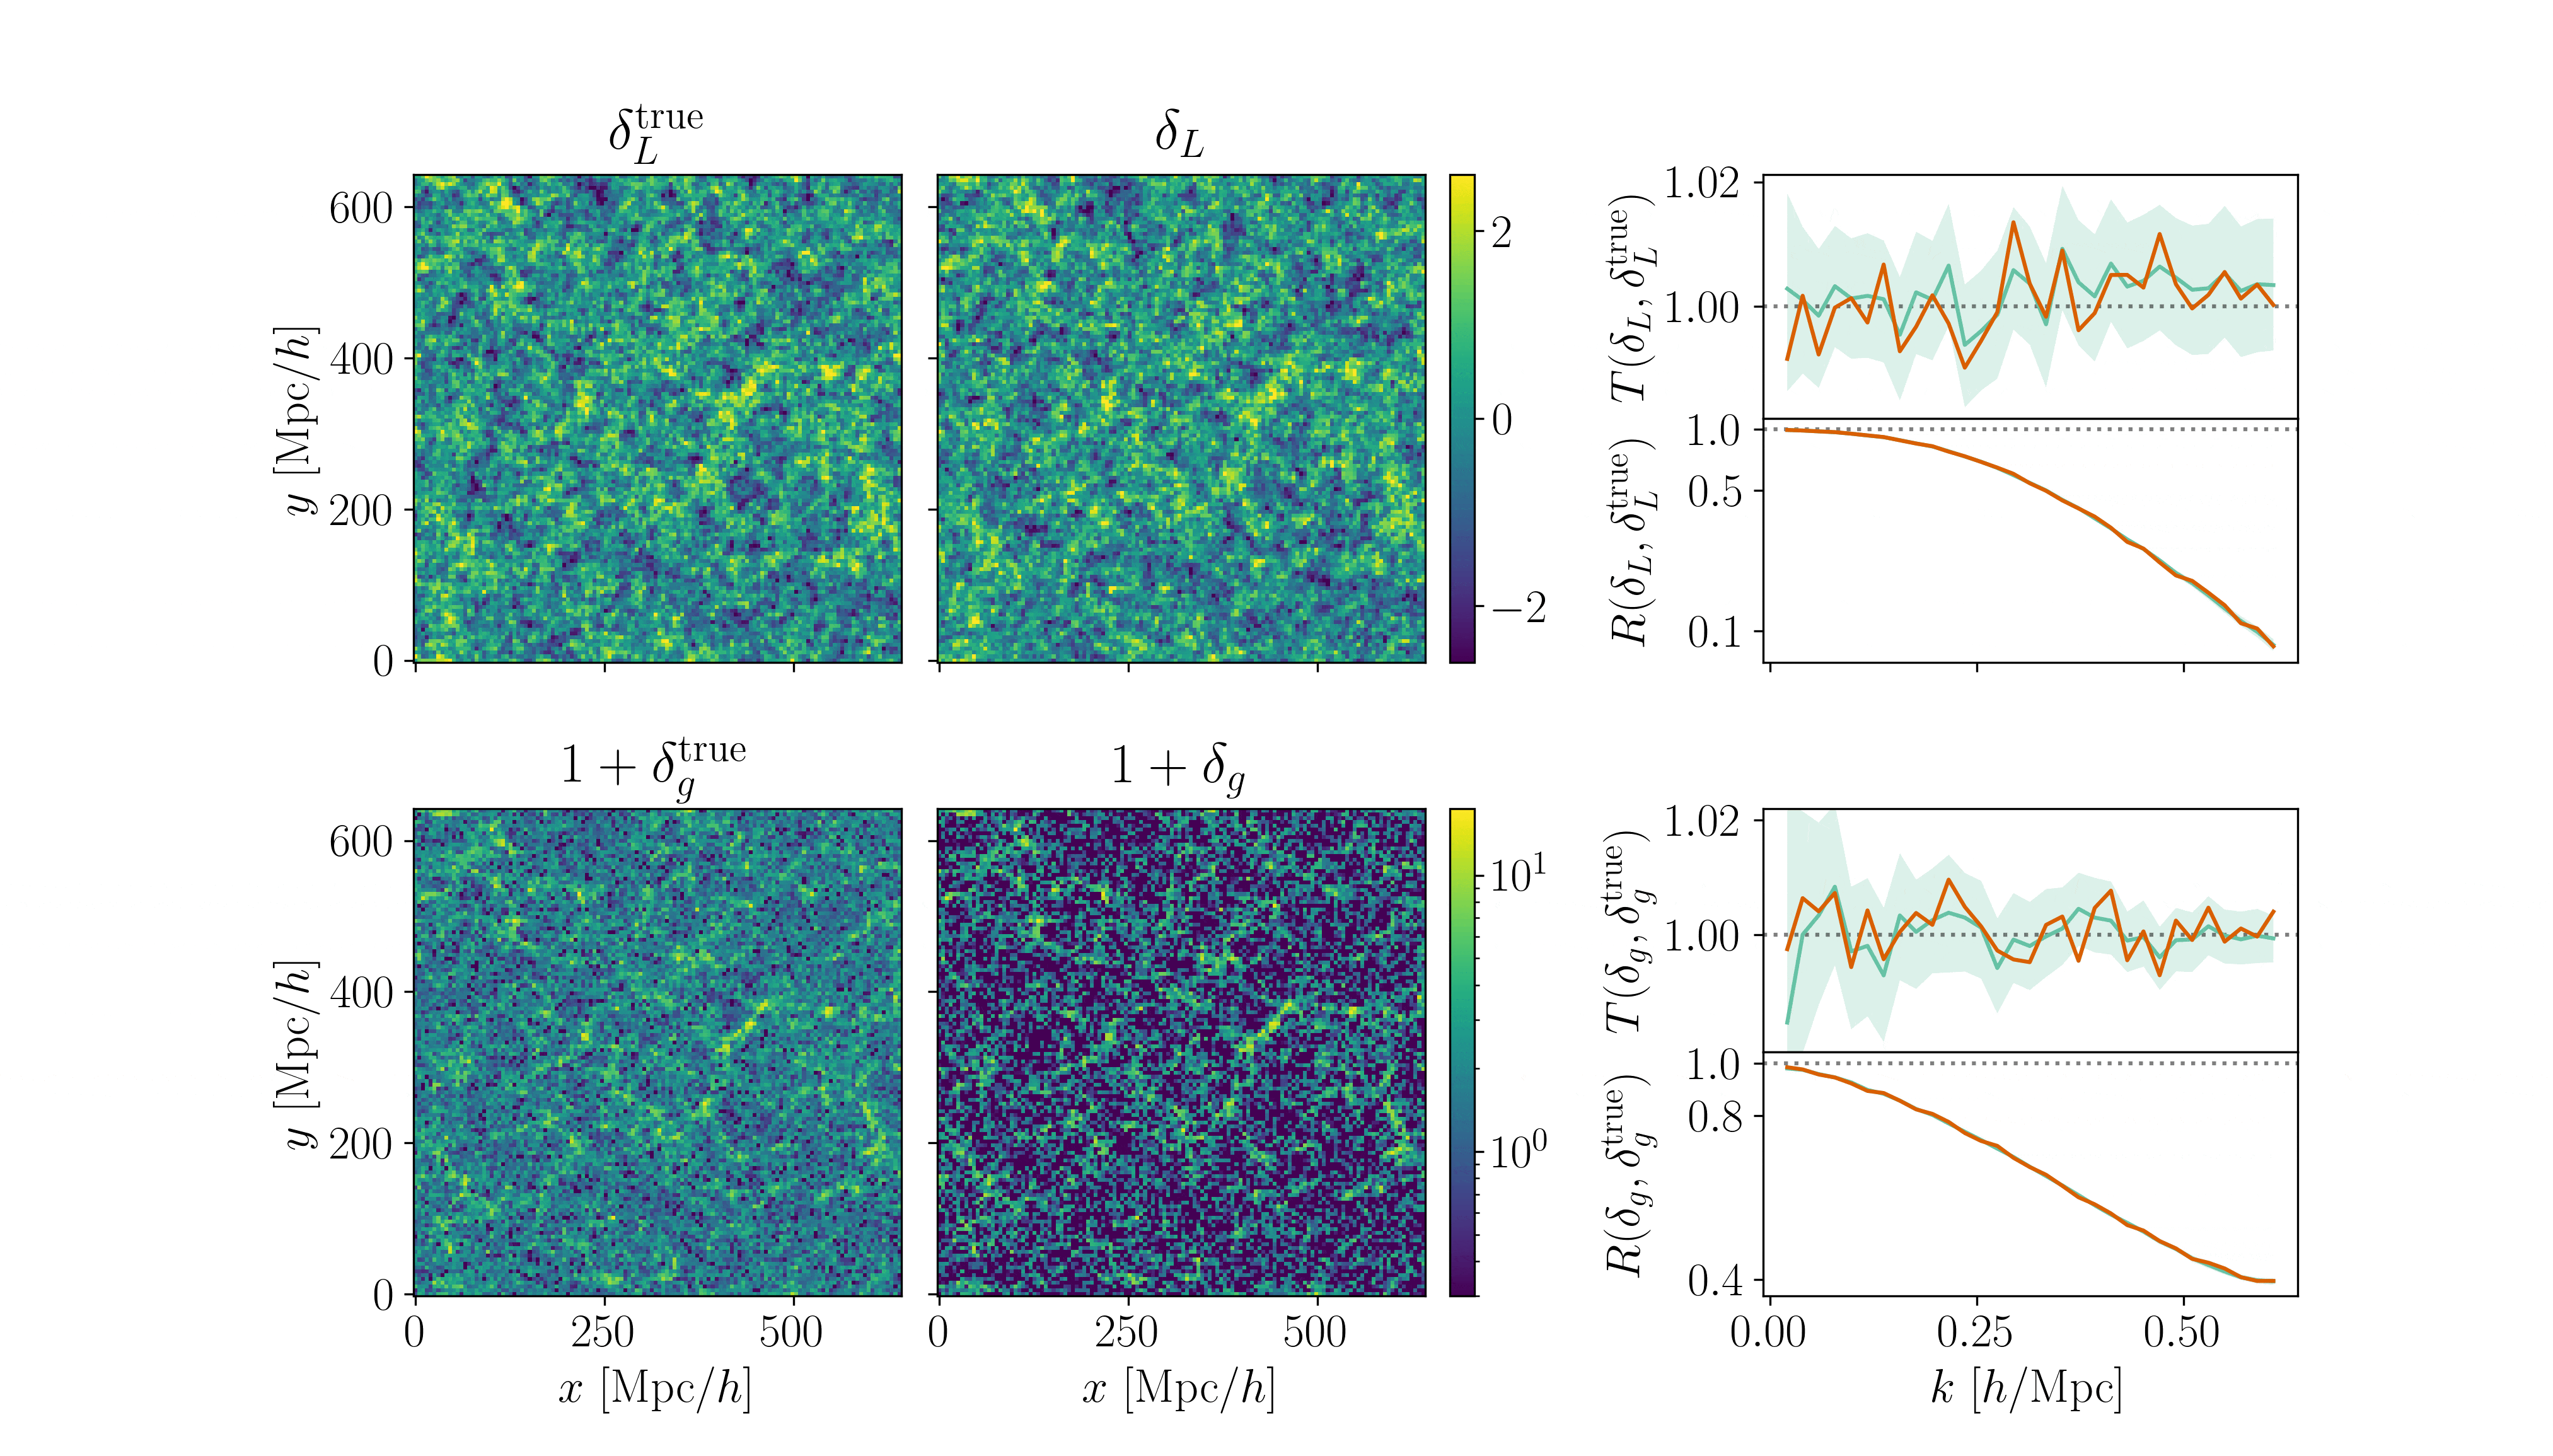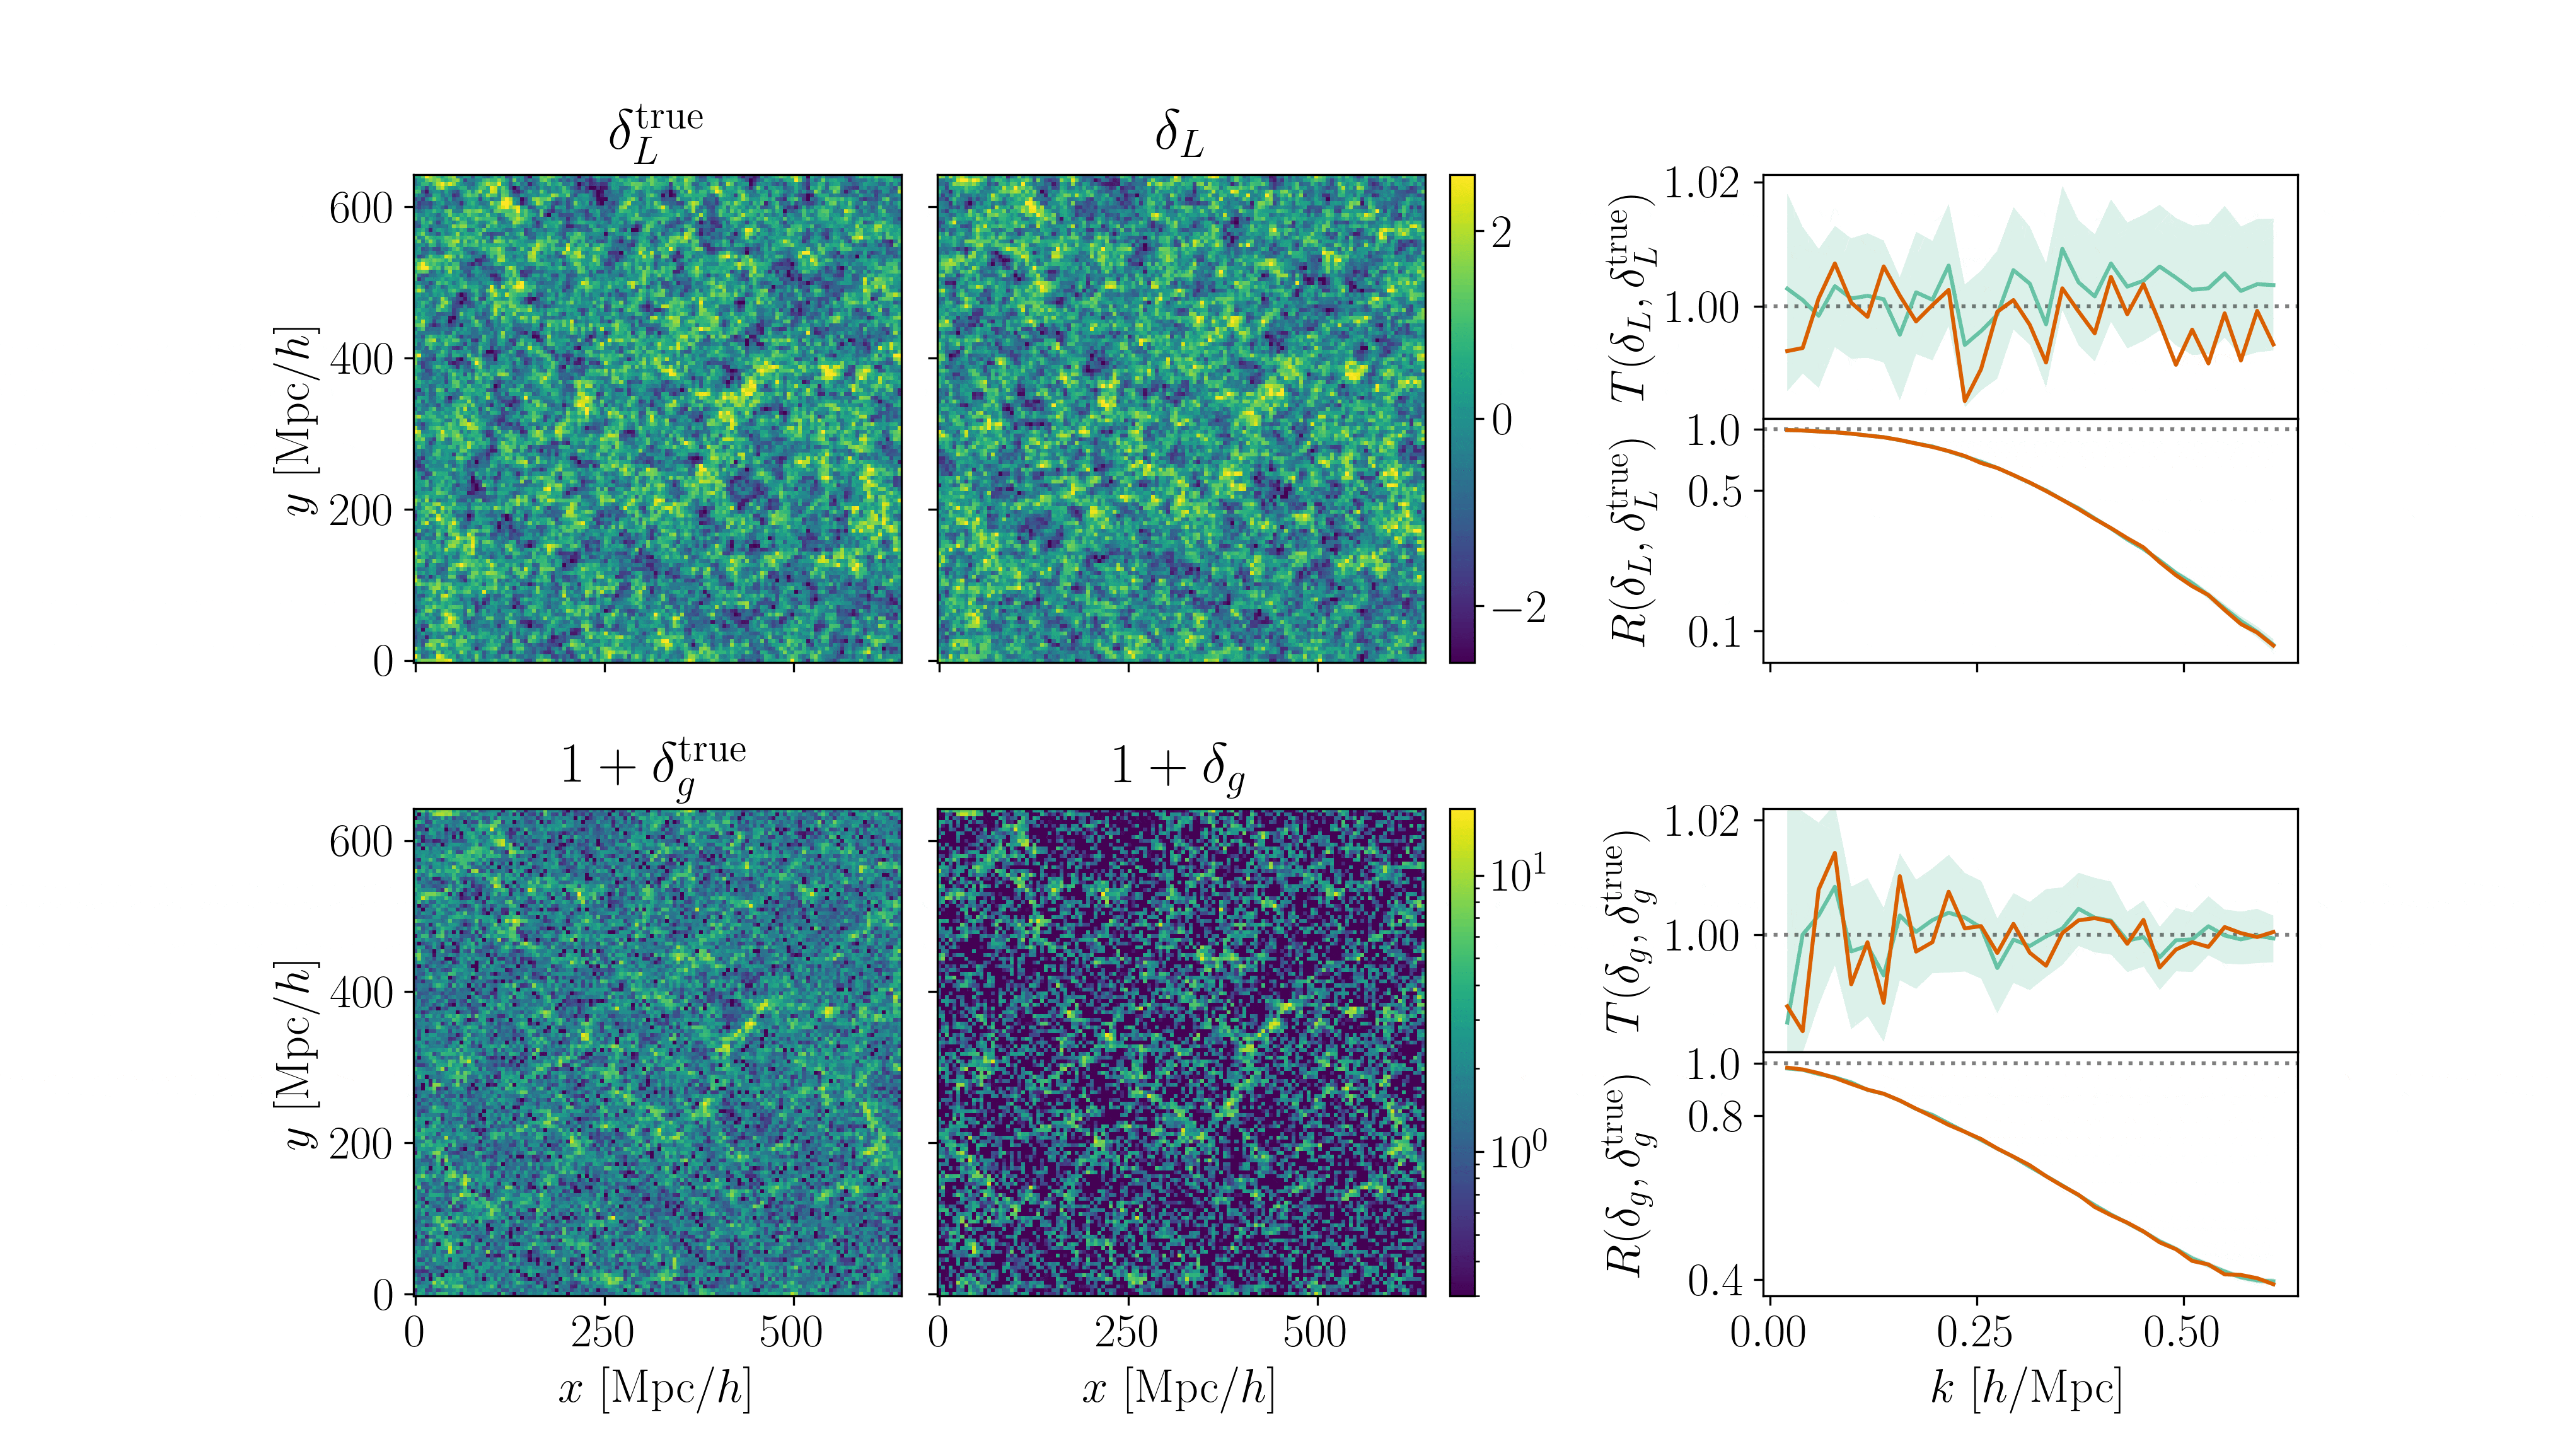
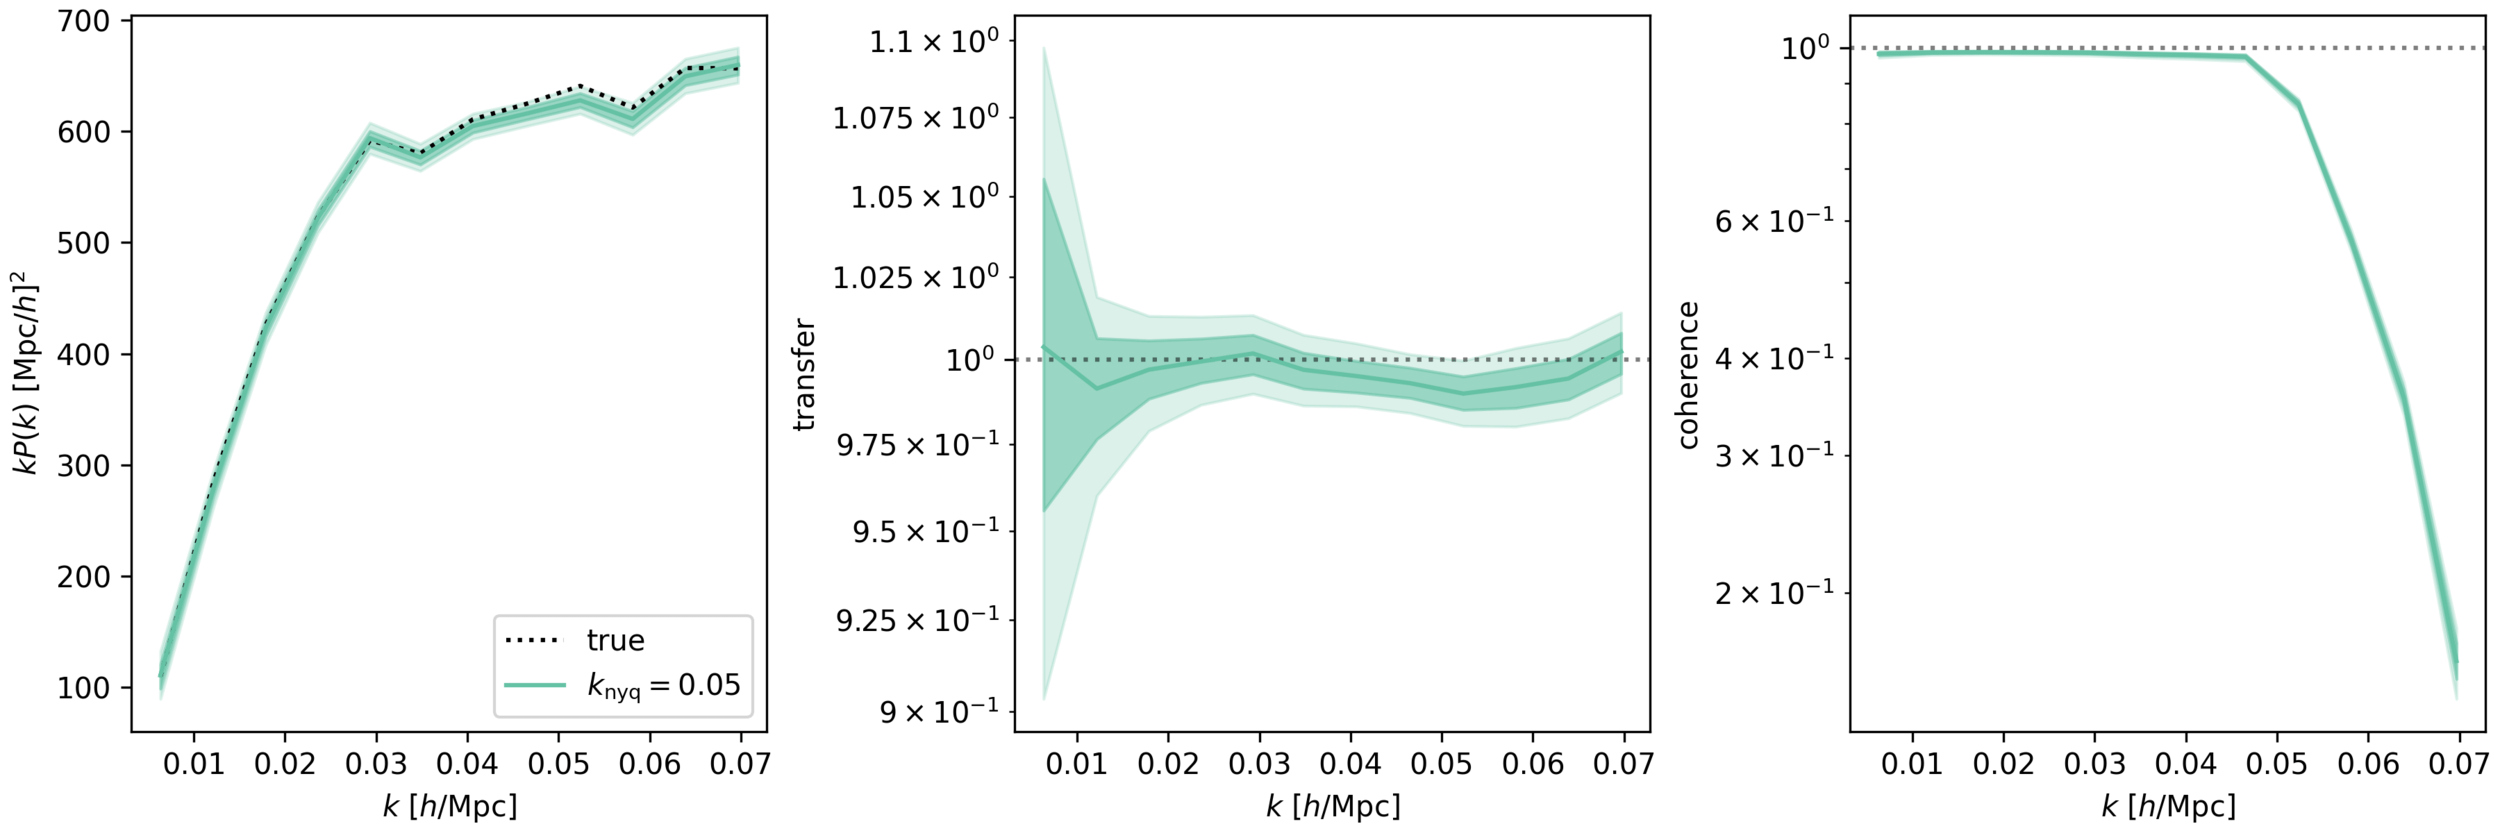
Fitting AbacusSummit+HOD
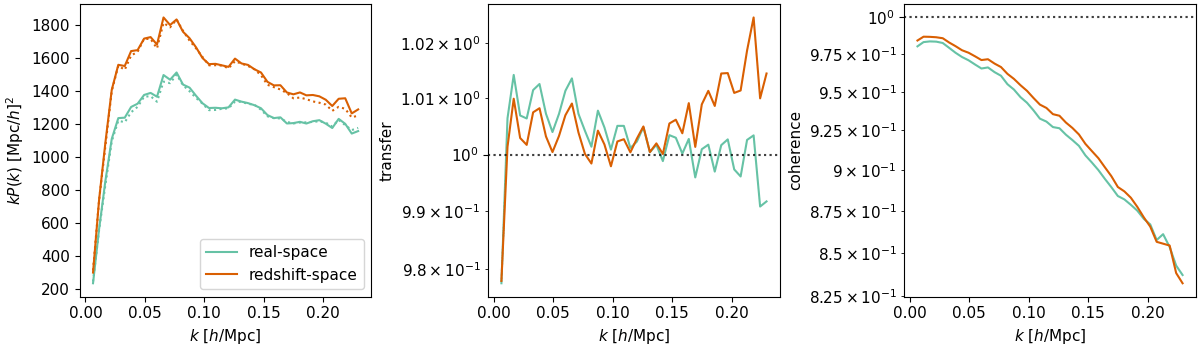
- CDM: fix initial conditions. Match within \(0.5\%\) at field-level for \(k_\mathrm{nyq} < 0.1 h/\mathrm{Mpc} \)
- Tracer (LRG, \(z=0.8\)): fix initial conditions and optimize on EFT parameters
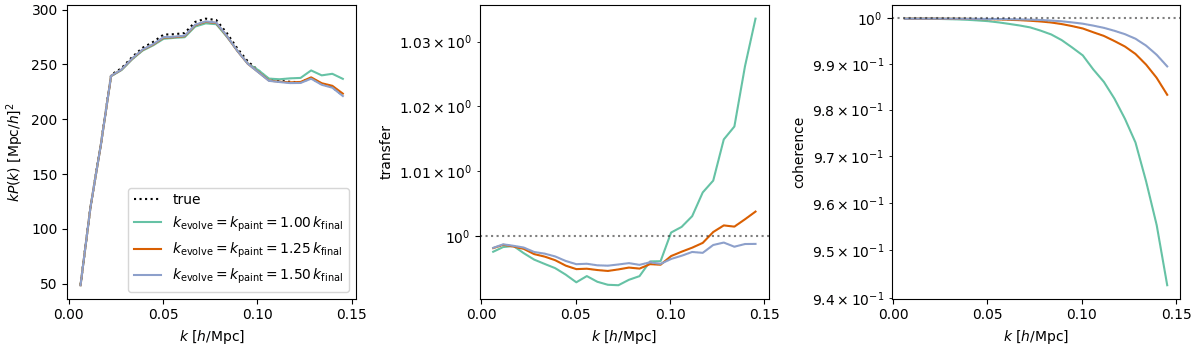
$$\sqrt{P_{\delta} / P_{\delta^\mathrm{true}}}$$ = amplitude info
$$P_{\delta,\delta^\mathrm{true}} / \sqrt{P_{\delta}P_{\delta^\mathrm{true}}}$$ = phase info
Galaxy stochasticity characterization
EFT says \({\color{purple}\sigma_0}(1+{\color{purple}\sigma_\delta}\delta_g^\mathrm{det})\)
Poisson \(\simeq \sigma_0=\sigma_\delta=1\), but fit shows sub-Poisson
For positivity, we take:
\({\color{purple}\sigma_0}\ln(1+e^{1+{\color{purple}\sigma_\delta}\delta_g^\mathrm{det}})\)
Quite Gaussian for \(k_\mathrm{nyq} \leq 0.15 h/ \mathrm{Mpc}\)👍
So \(\delta_g \sim \mathcal N(\delta_g^\mathrm{det},\, {\color{purple}❓})\)
EFT says \({\color{purple}\sigma_0}(1+{\color{purple}\sigma_{2}}k^2 + {\color{purple}\sigma_{\mu,2}}(\mu k)^2)\)
Negligible for currently probed scales.
If not, can be implemented in real domain with sparse matrices.
Galaxy stochasticity = \(\delta_g^\mathrm{true} -\delta_g^\mathrm{det}\), and we take \(\delta_g^\mathrm{det}\) to be EFT best fit.
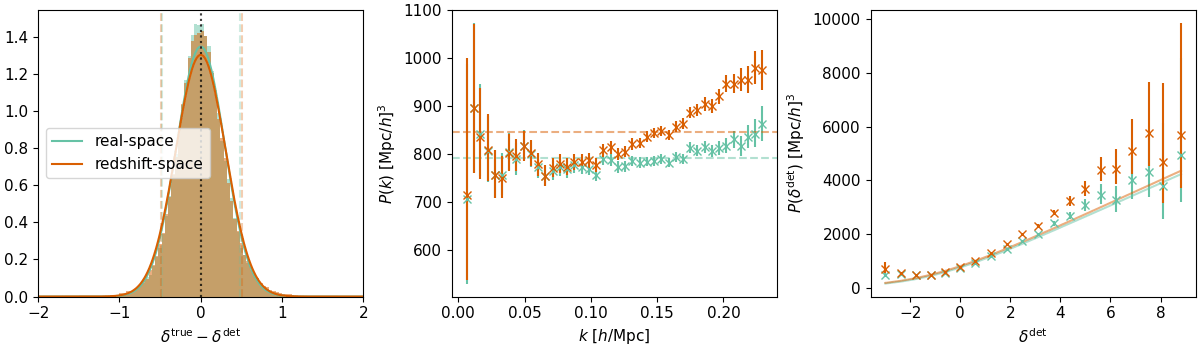
\(\sigma^2(\delta^\mathrm{det})\)
Preliminary FLI results on PNG
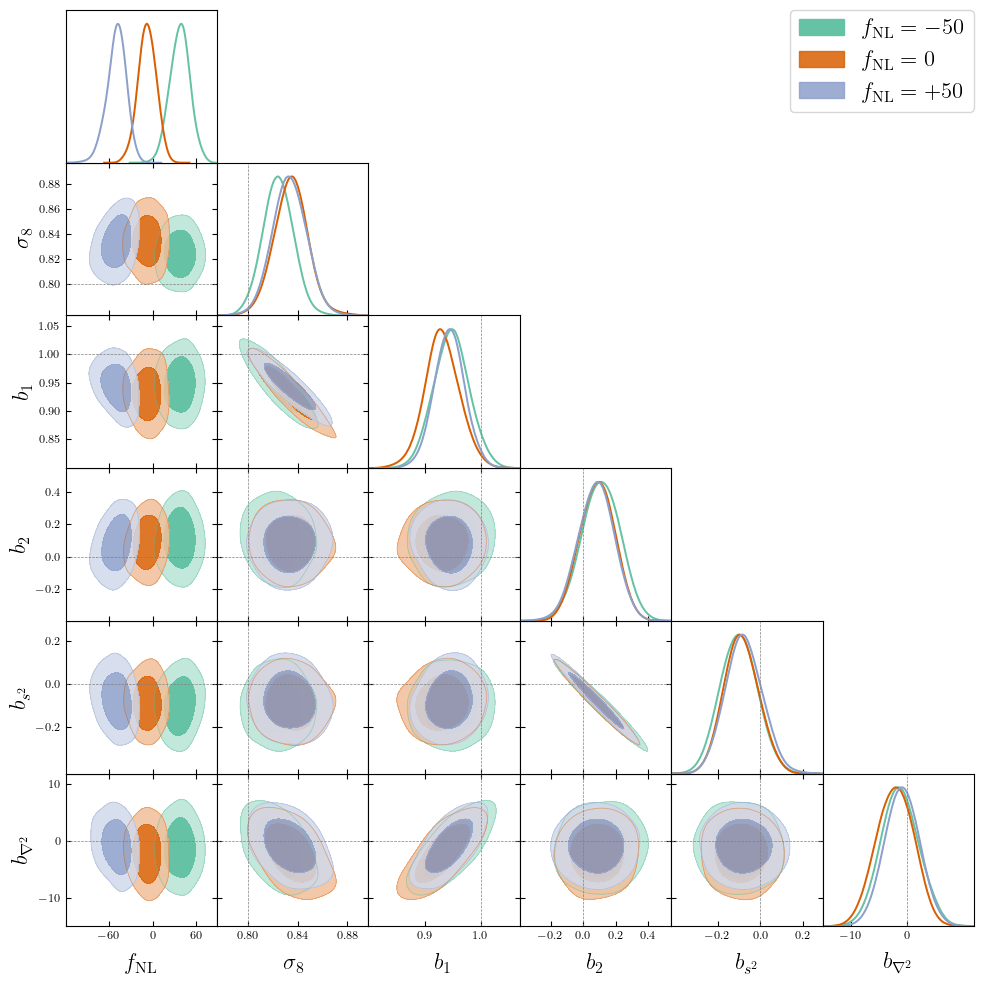
On AbacusSummit + HOD mock (\(f_\mathrm{NL}= 0\))
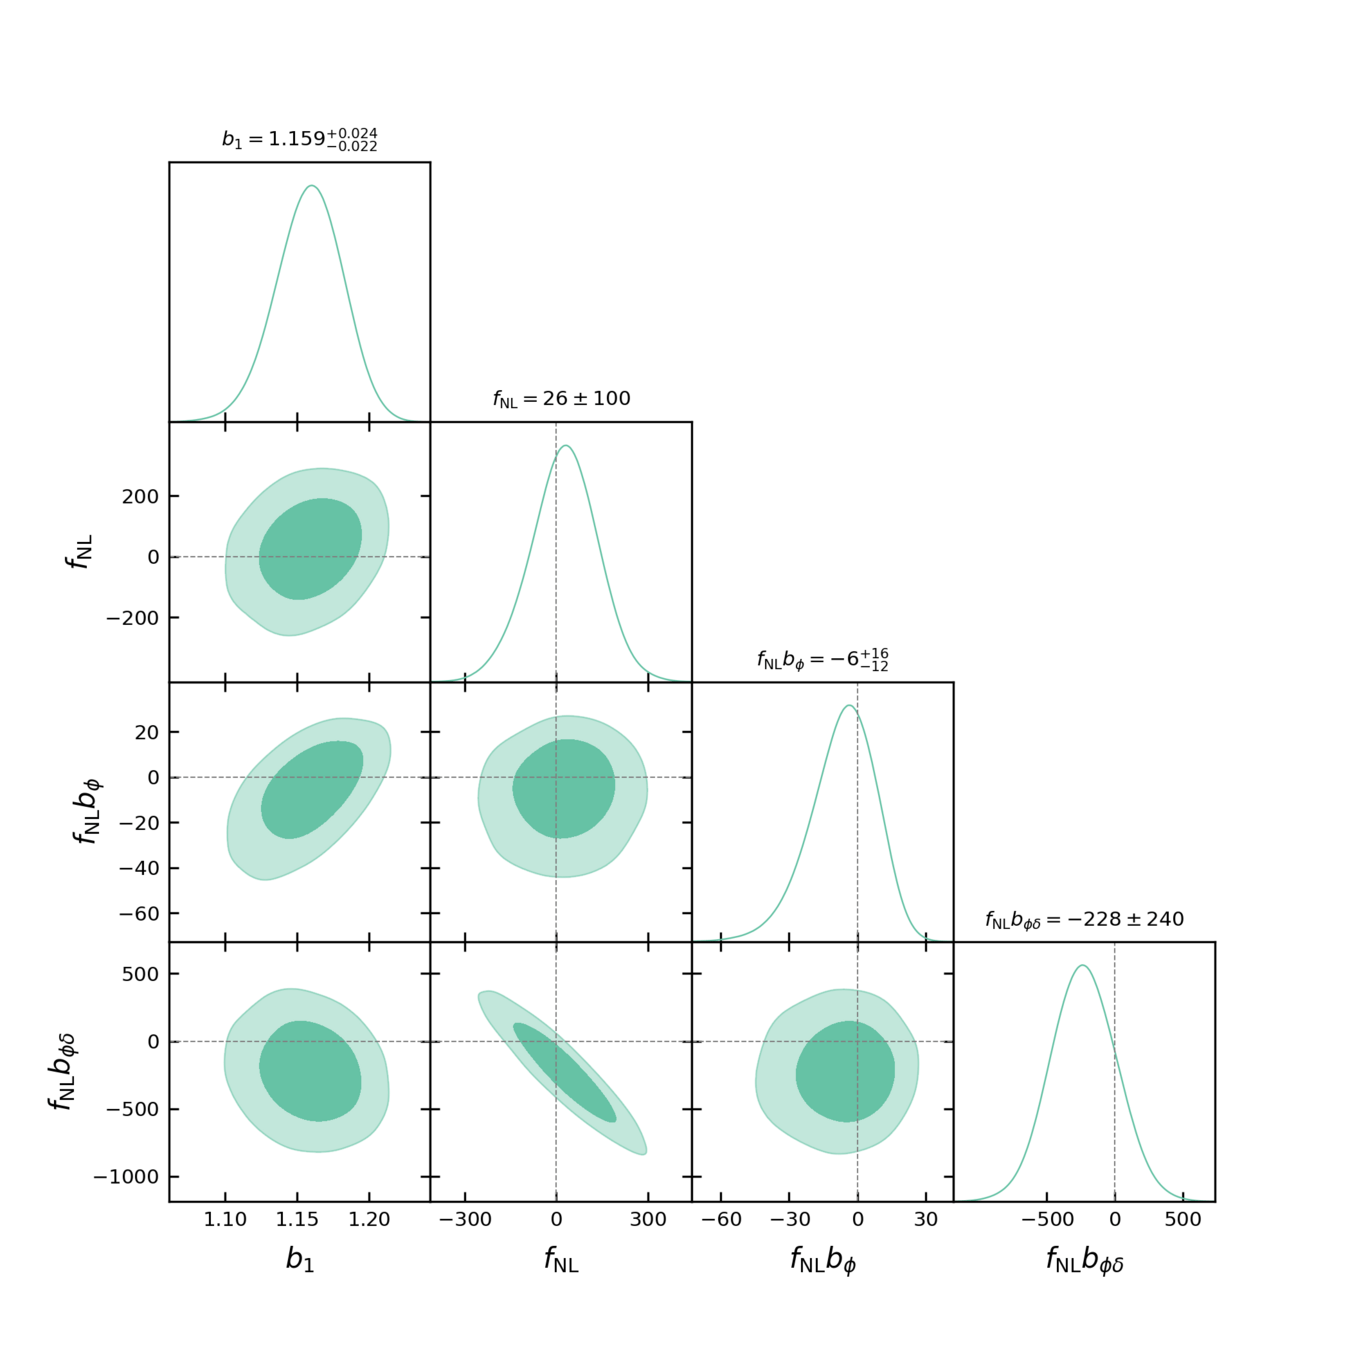
For \(k_\mathrm{nyq} = 0.05\ h/\mathrm{Mpc}\), inference compatible with \(f_\mathrm{NL}= 0\).
TBD: posterior calibration tests
\((2\ \mathrm{Gpc}/h)^3,\, \mathrm{LRG}\, z=0.8\)
PRELIMINARYProbing inflation with FLI
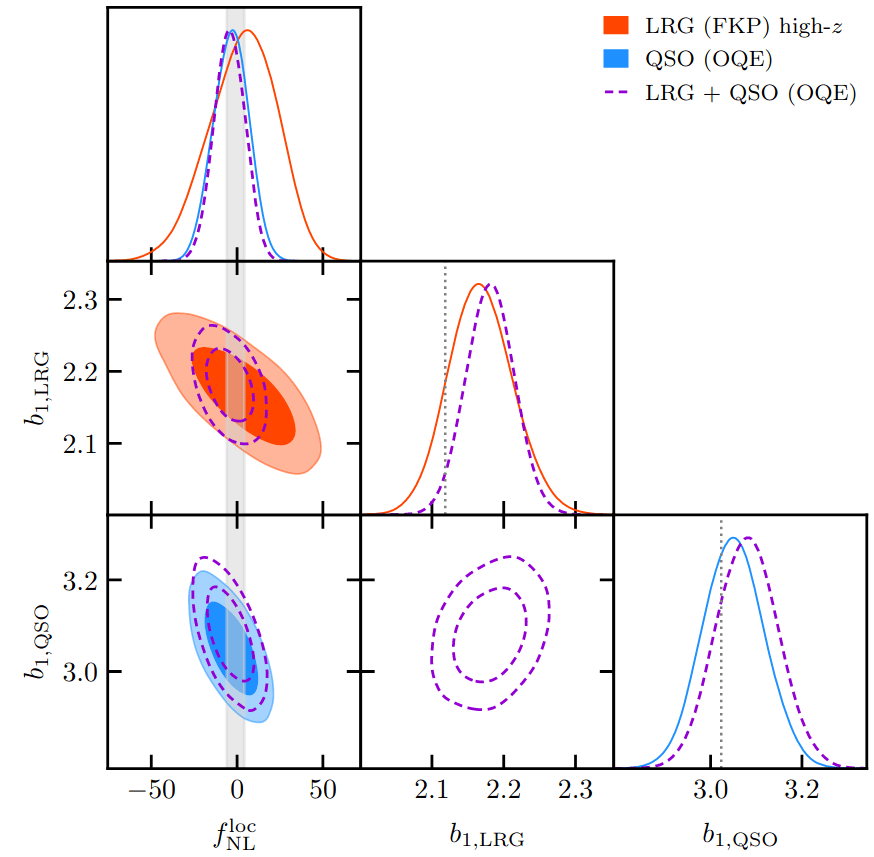
NOW: validation on AbacusSummit (DESI reference sims) and FastPM + HOD mocks
\((2.76\ \mathrm{Gpc}/h)^3,\,k_\mathrm{nyq} = 0.073 h/ \mathrm{Mpc},\\ \mathrm{QSO}\, z=1,\, \operatorname{dim}(\delta_L) = 96^3\)
PNG, ideal first demonstration of FLI:
- Most of signal from easier large scales
- Result very sensitive to systematics, more directly implemented at field-level
- Bonus: fully explicit/explainable
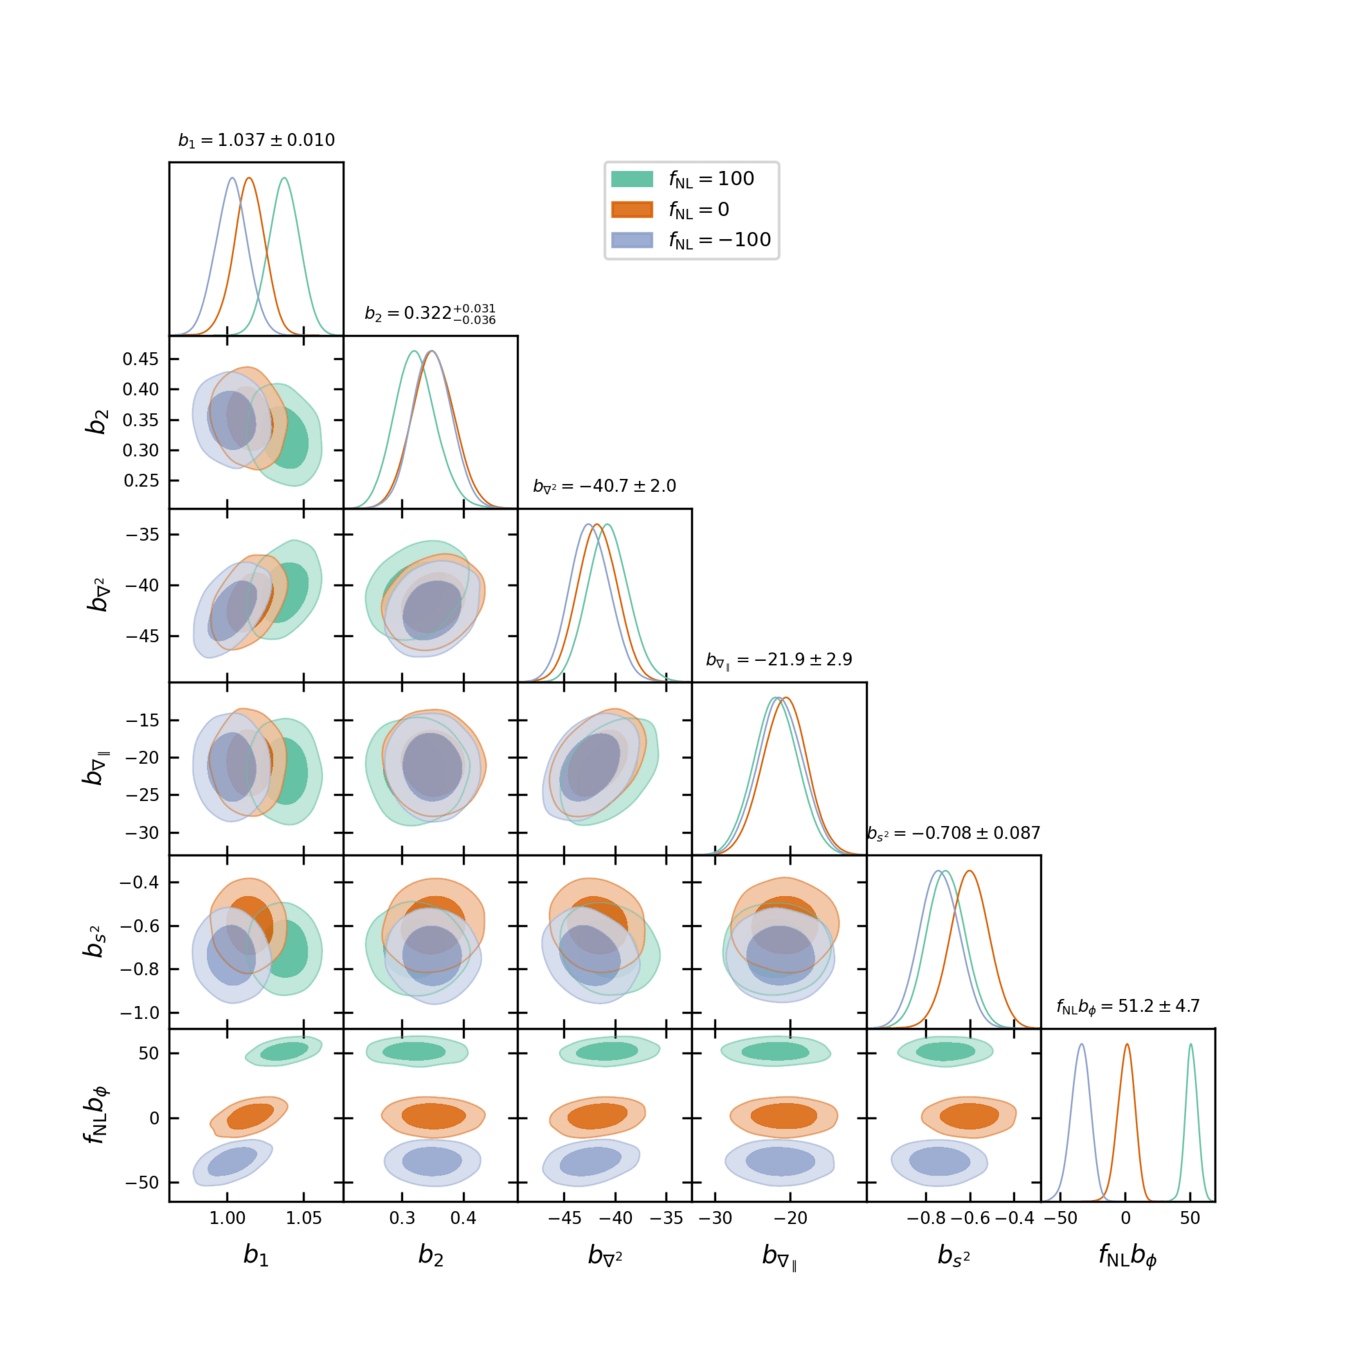
PRELIMINARYNext steps:
- Validation of survey realism on contaminated mocks
- Application to DESI LRGs and QSOs
In prep: Simon+2025
Preliminary FLI results on PNG
On \(f_\mathrm{NL}\neq 0\) FastPM + HOD mocks (courtesy of Edmond)
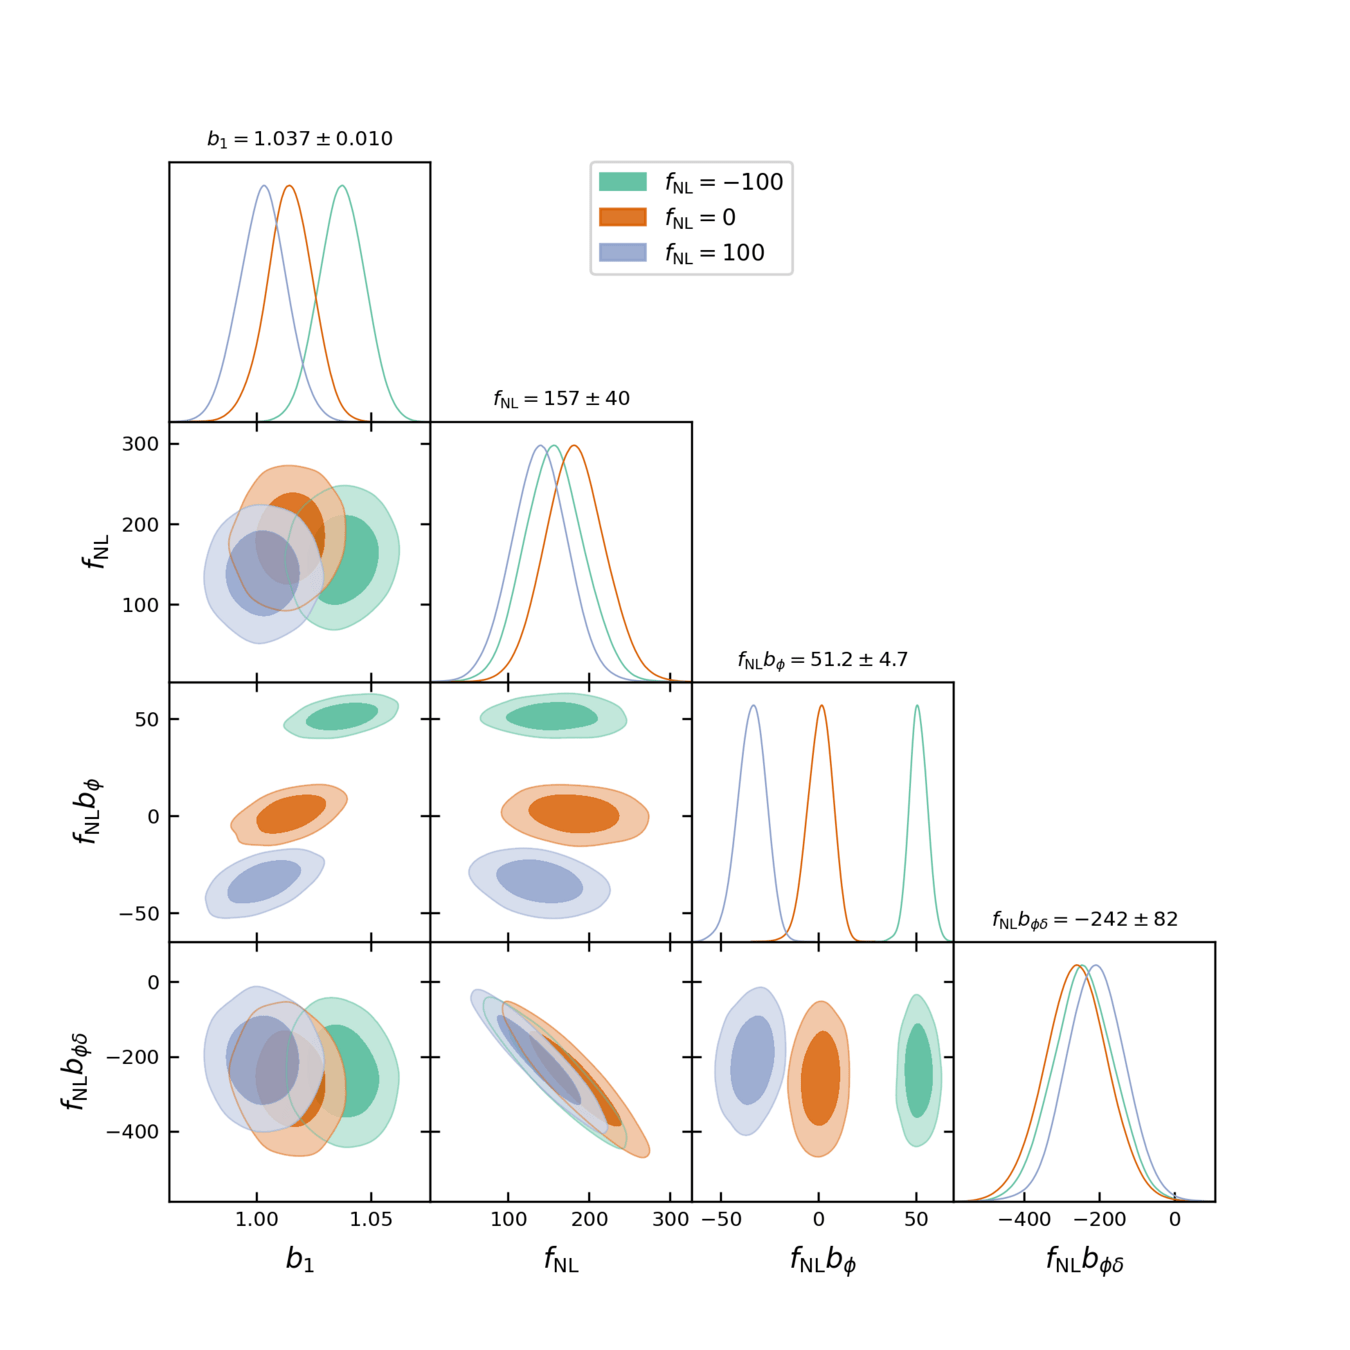
PRELIMINARY\((2.76\ \mathrm{Gpc}/h)^3,\,k_\mathrm{nyq} = 0.073 h/ \mathrm{Mpc},\\ \mathrm{QSO}\, z=1,\, \operatorname{dim}(\delta_L) = 96^3\)
PRELIMINARY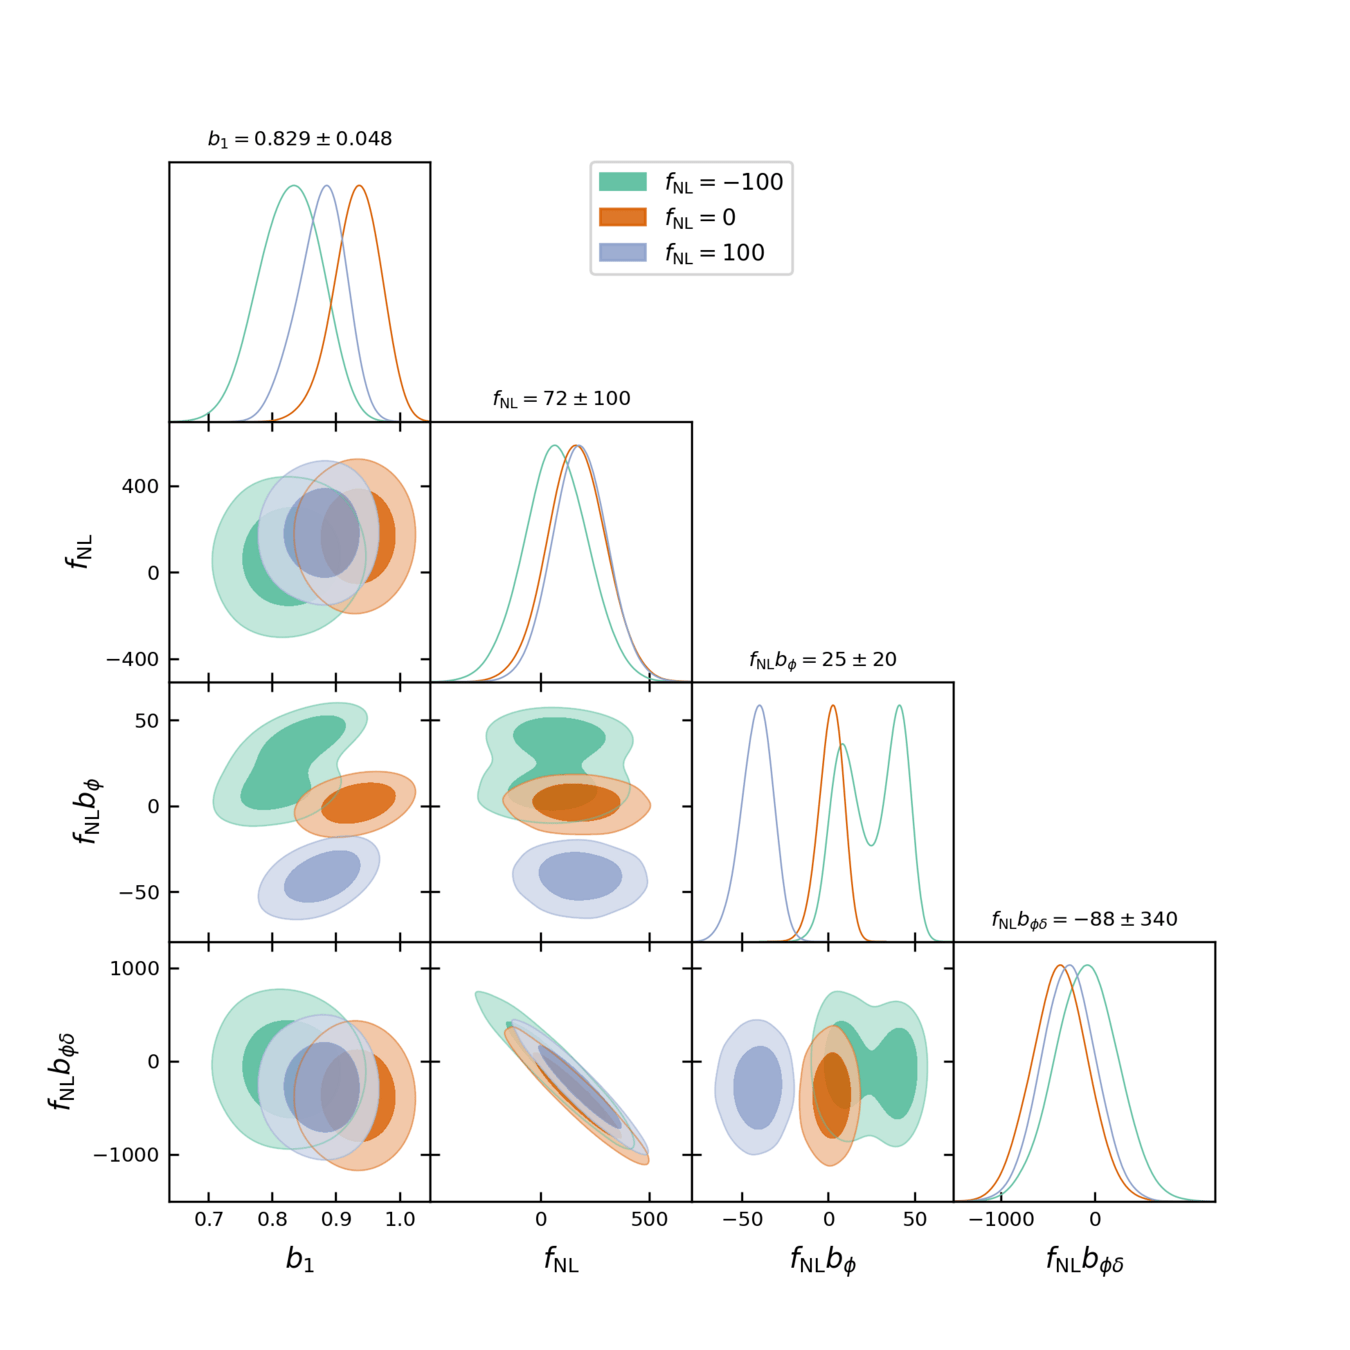
\((2.76\ \mathrm{Gpc}/h)^3,\,k_\mathrm{nyq} = 0.036 h/ \mathrm{Mpc},\\\, \mathrm{QSO}\, z=1,\,\operatorname{dim}(\delta_L) = 48^3\)
Next steps:
- confirm the calibration at relevant scales on PNG-Unitsims
- light-cone, survey selection, imaging...
Field-level implementation is
more direct than for P+B analyses
- Lightcone
- Survey selection
- Imaging (linear modeling for LRG and QSO,
more complex for ELG) - Radial Integral Constraint
Toward more survey realism
Less relevant for PNG:
- Fiber assignment (incomplet.+competition+collisions)
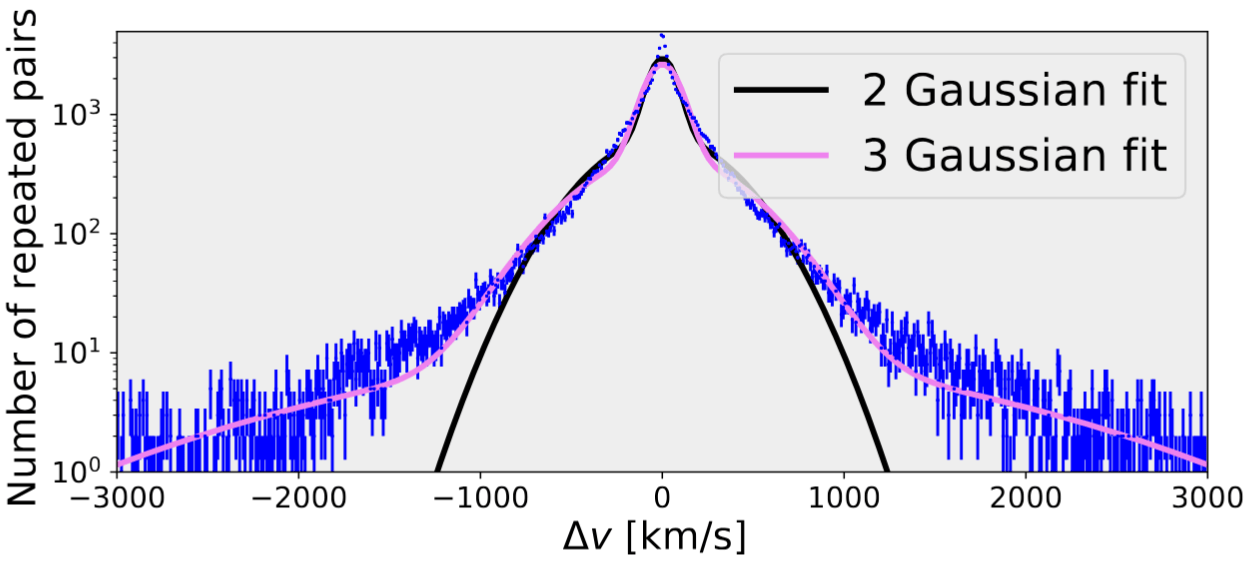
- Redshift uncertainty
\(\Delta z\) due to broad QSO bands
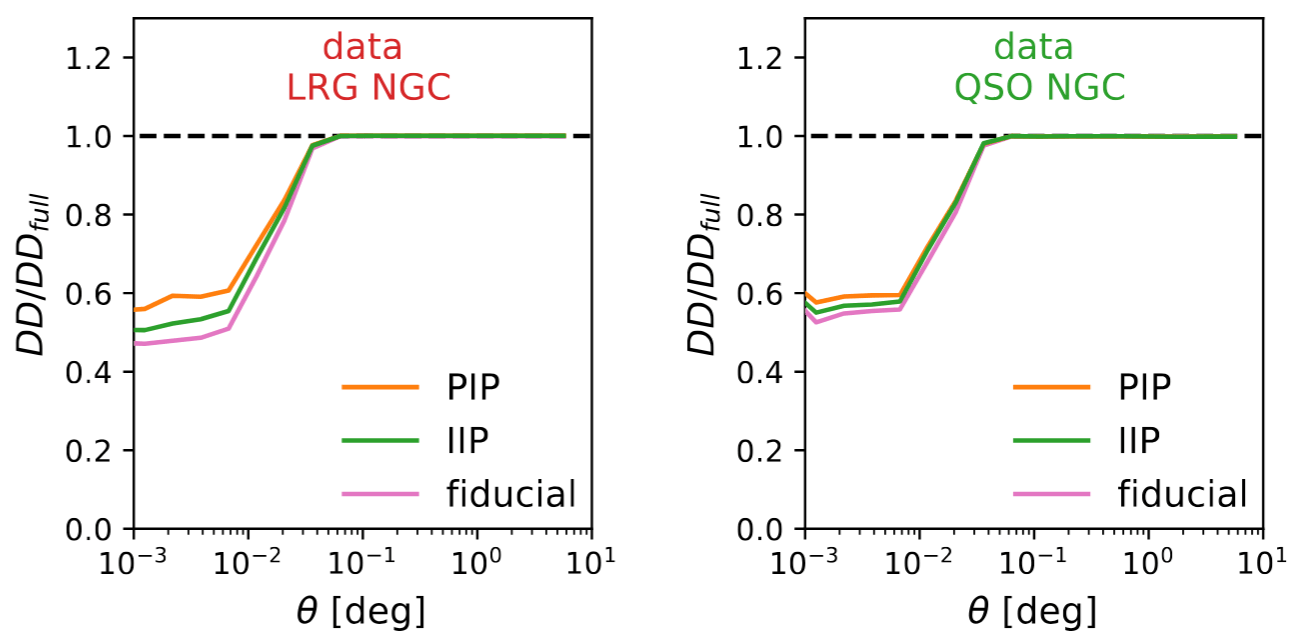
FA damping at small angles
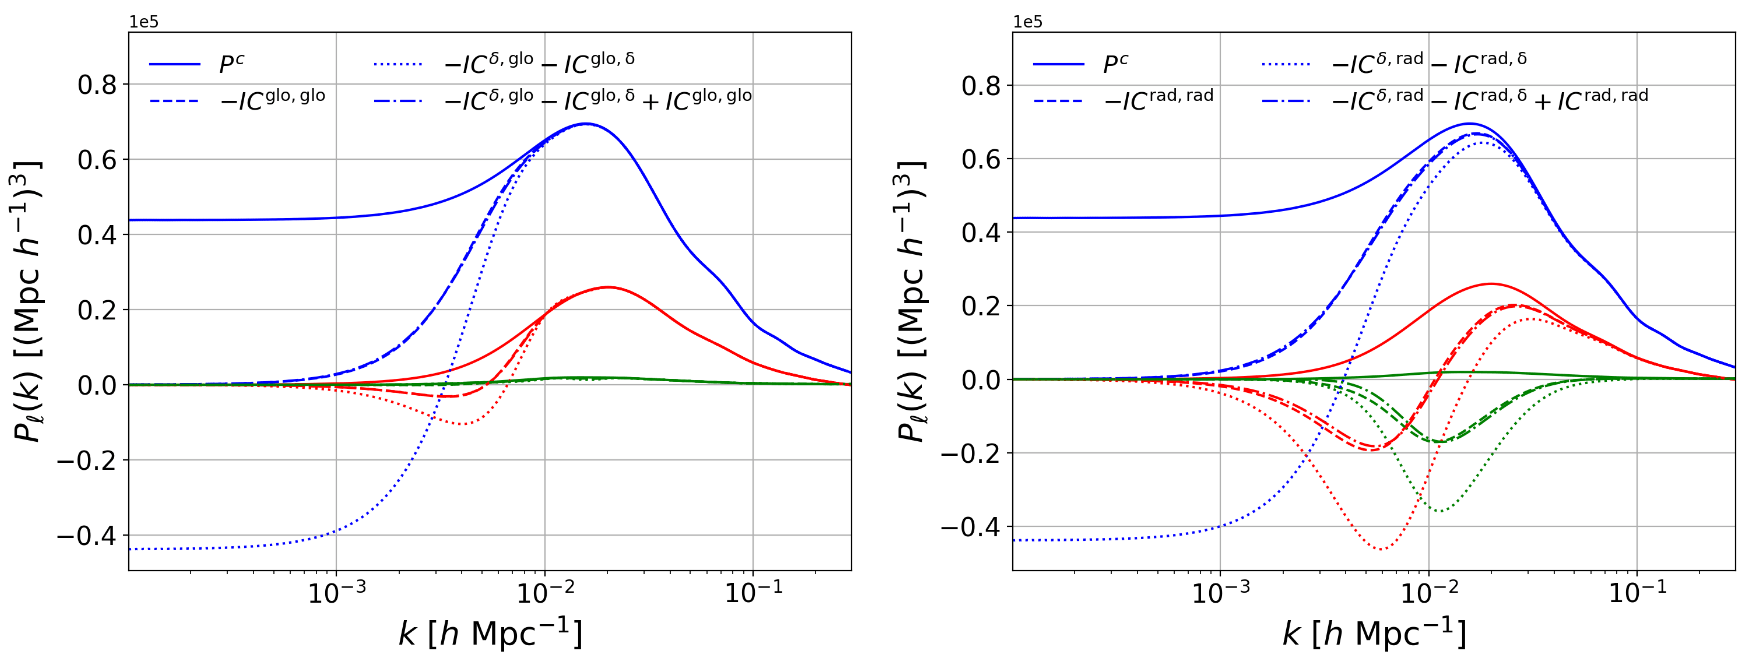
RIC damping on large scales
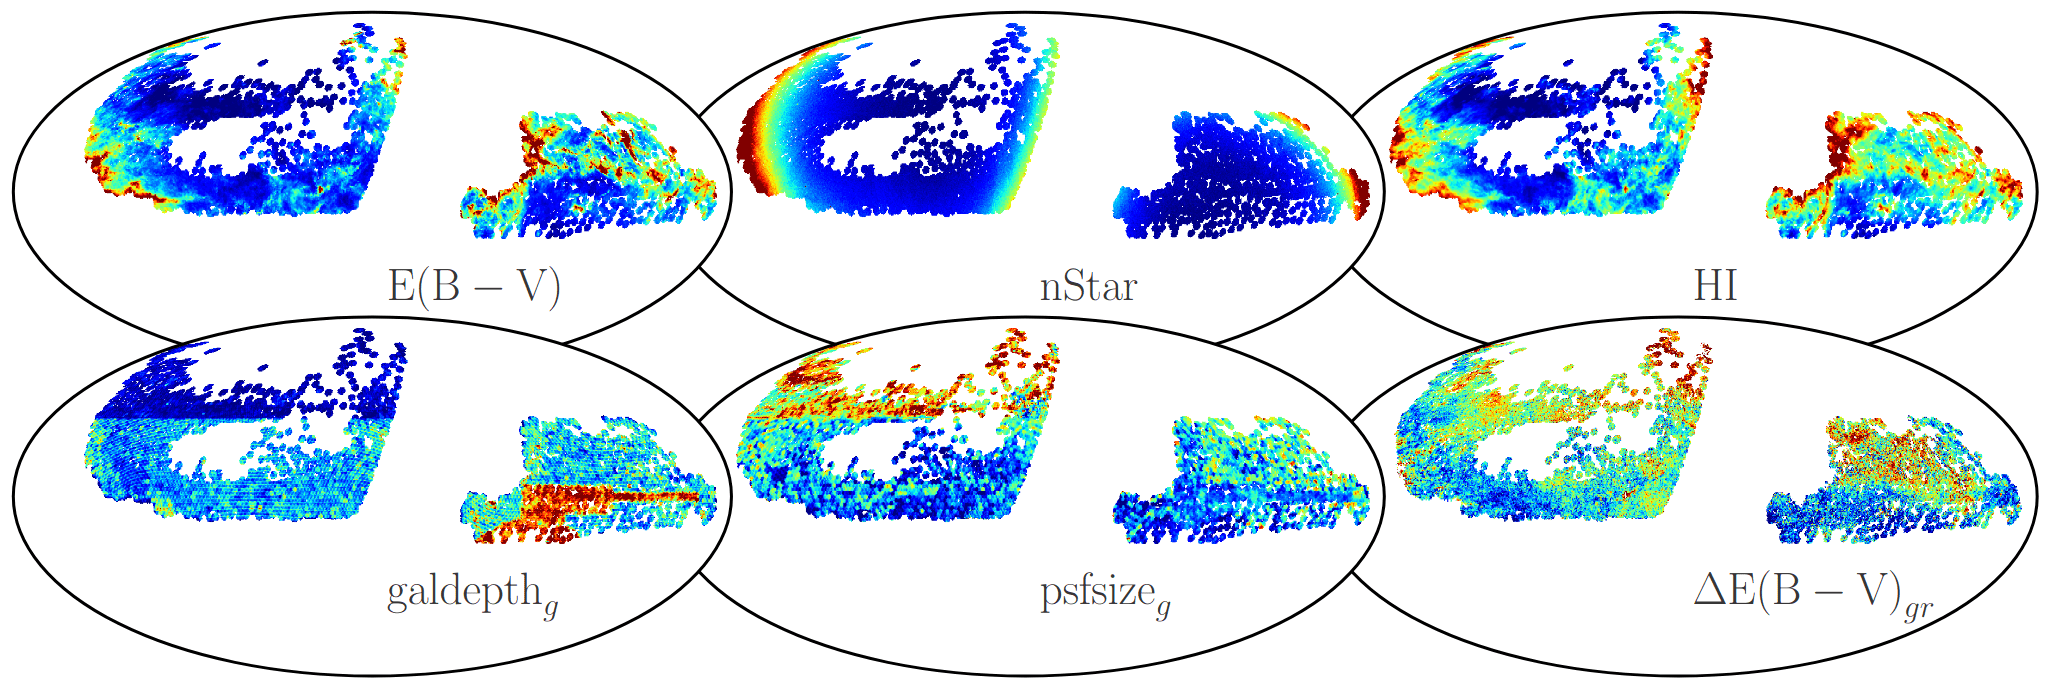
Imaging templates
Field-level implementation is
more direct than for P+B analyses
- Lightcone
- Survey selection
- Imaging (linear modeling for LRG and QSO,
more complex for ELG) - Radial Integral Constraint
Toward more survey realism
Less relevant for PNG:
- Fiber assignment (incomplet.+competition+collisions)
- Redshift uncertainty
\(\Delta z\) due to broad QSO bands
FA damping at small angles
RIC damping on large scales
Imaging templates
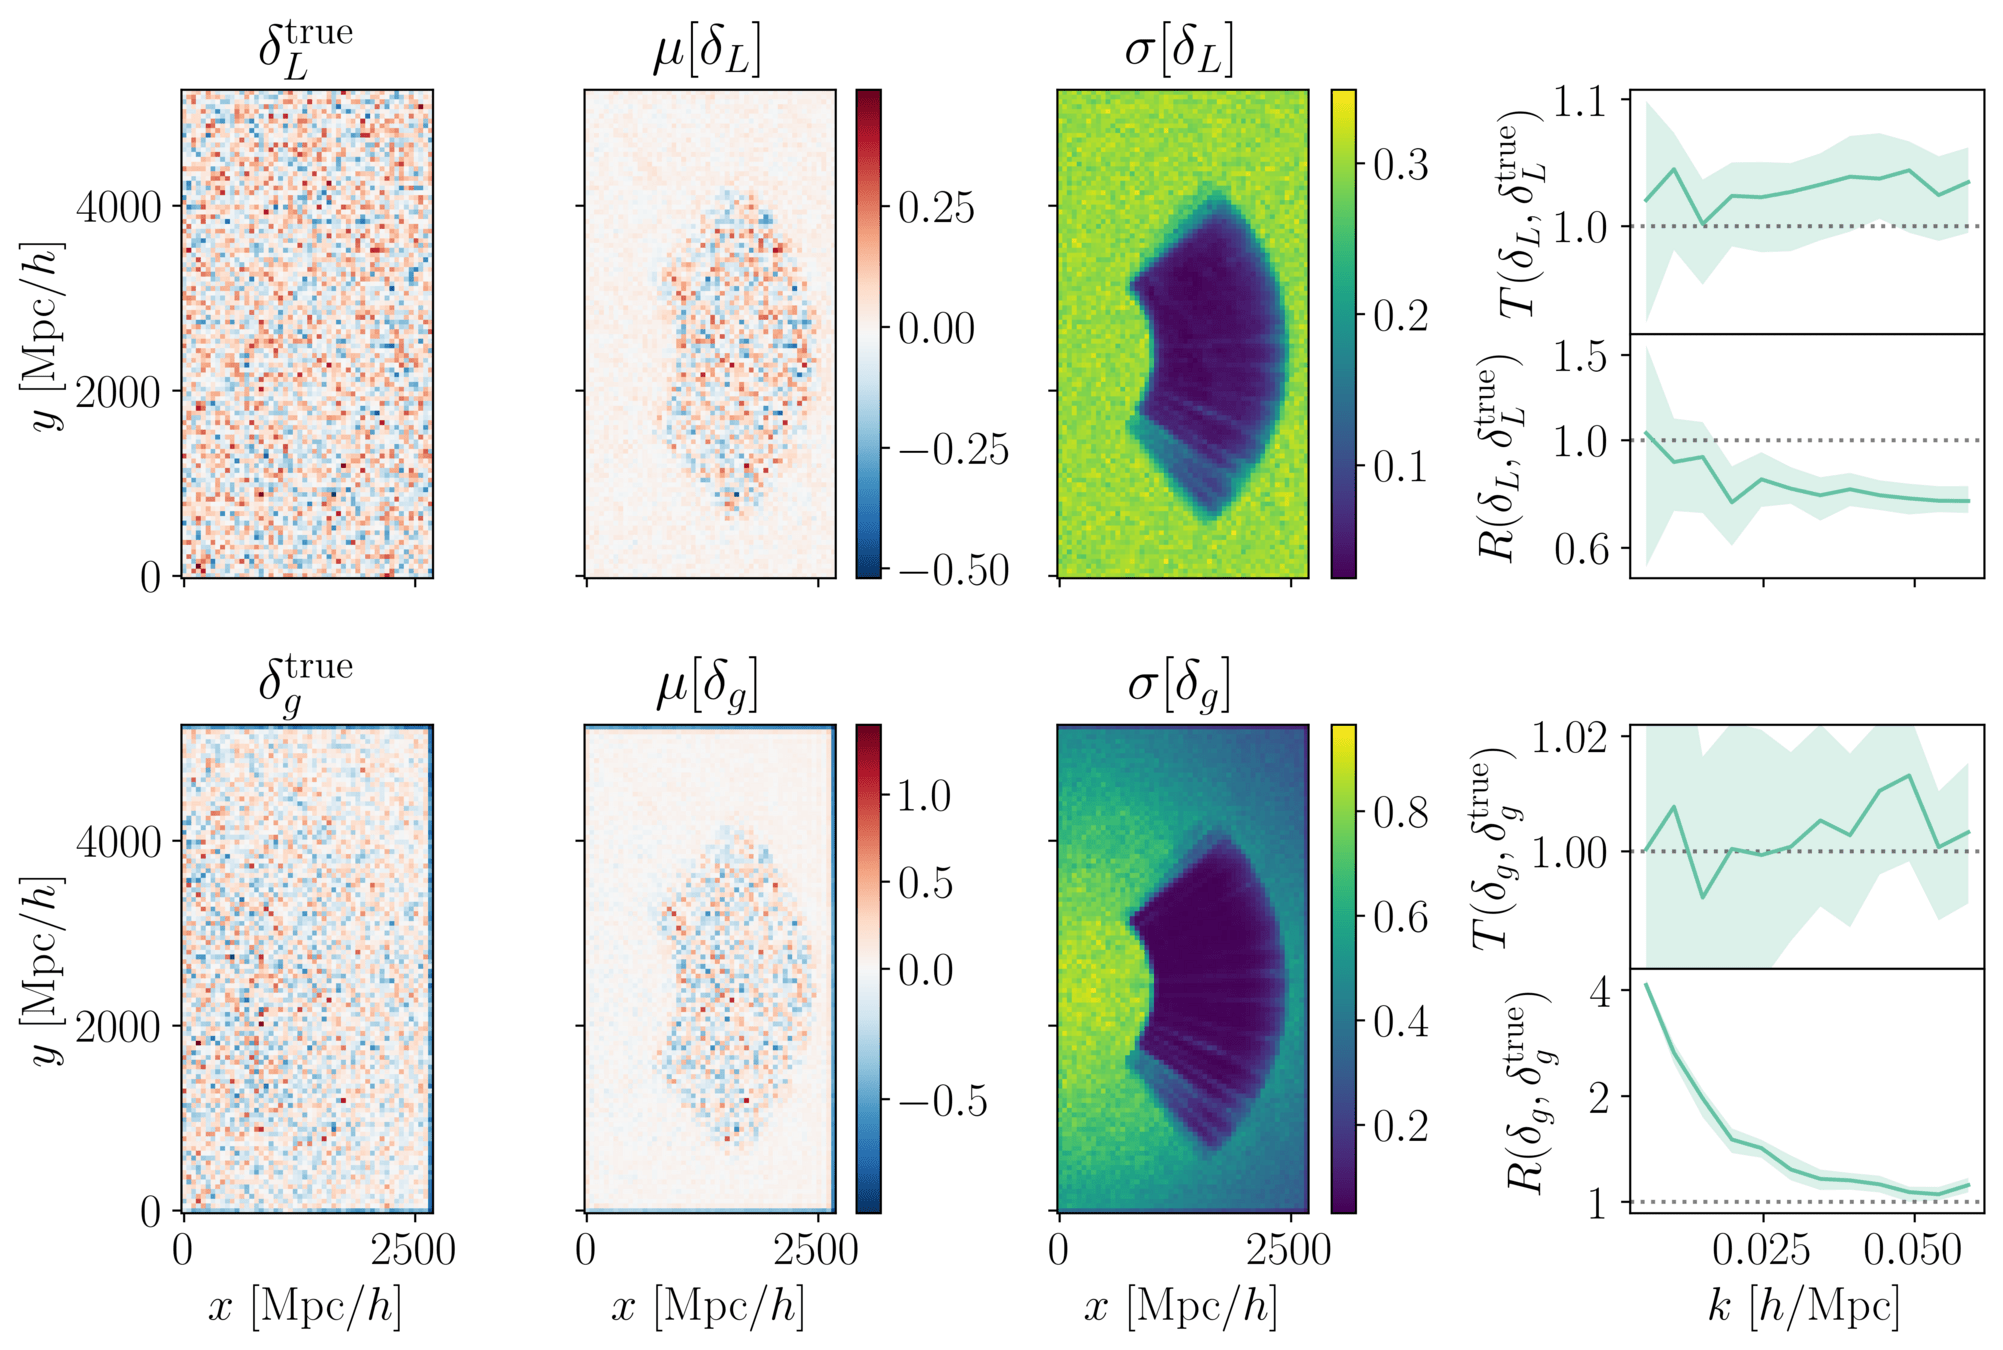
PRELIMINARY\(k_\mathrm{max} \approx 0.04\ h/\mathrm{Mpc}\)
FLI on LRG SGC footprint with lightcone, survey selection, and RIC
Perspectives for FLI with DESI
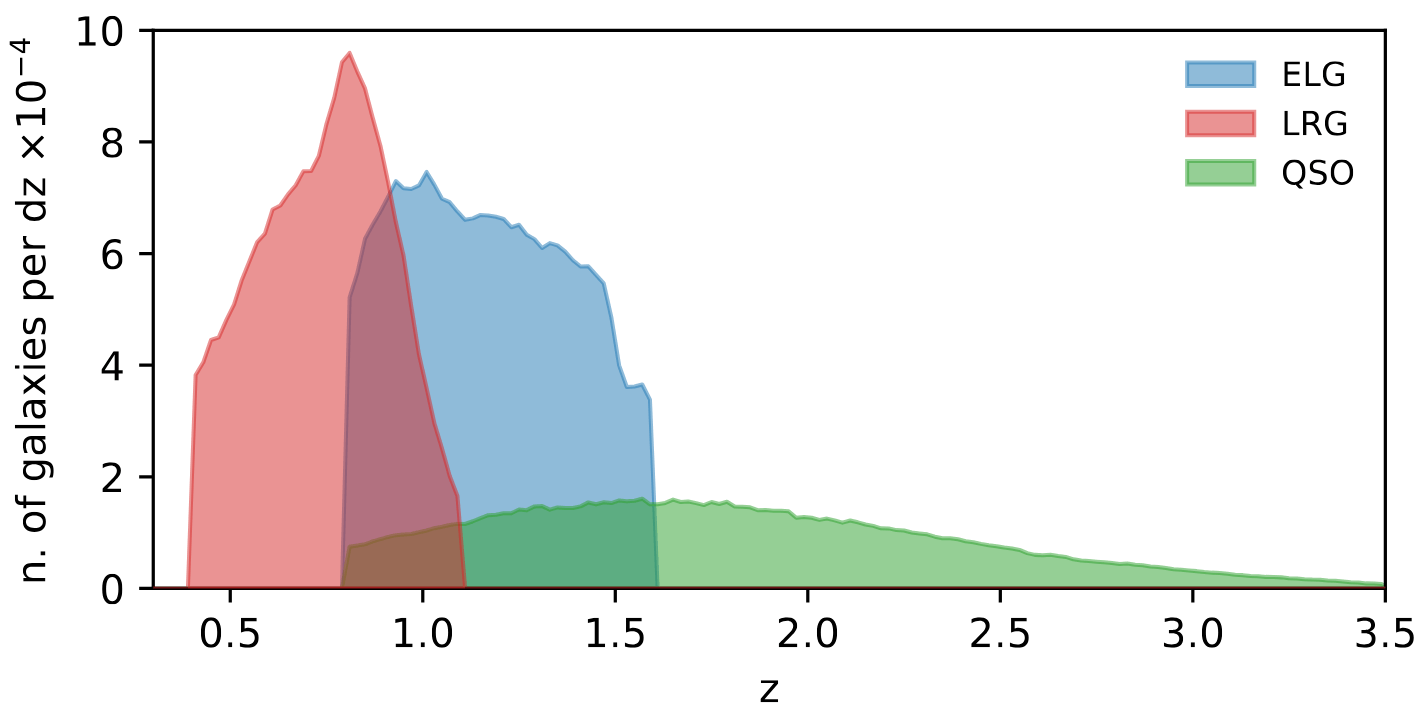
-
To probe smaller scales, revise EFT likelihood, peculiar velocities, ELGs, FA, and \(\Delta z\)
- Make use of the overlap between DESI tracers for cosmic variance cancellation
- Extend EFT modeling to Ly\(\alpha\)-forests to probe LSS at higher redshift
- Approximate sampling methods for fast iterations
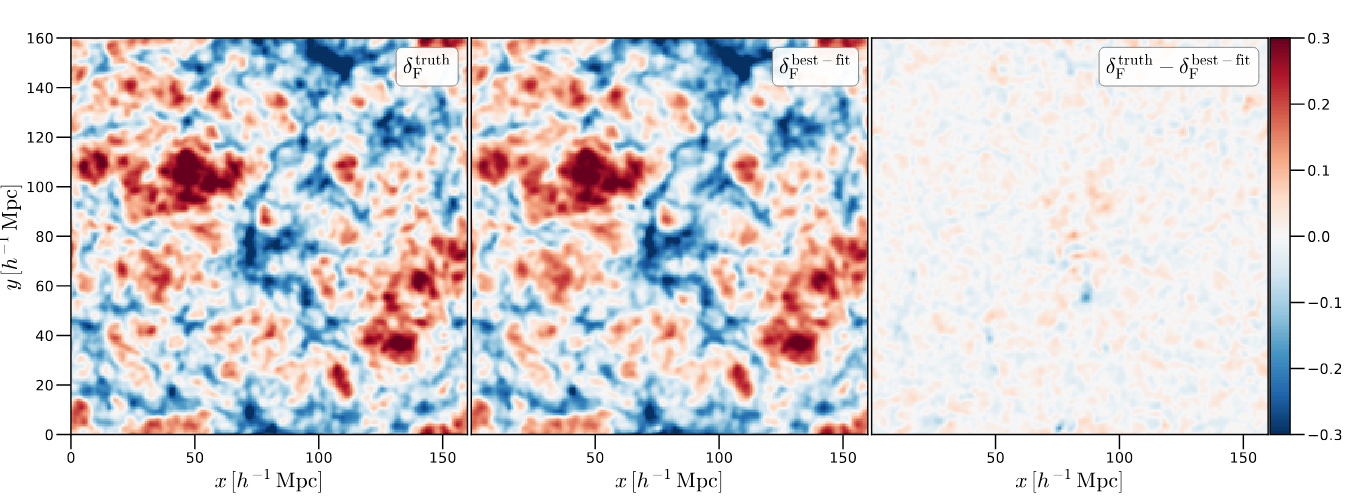
\(k_\perp\) might be enough, espec. for DR2
FoG+broad QSO bands
\((k\mu)^2\) might not be enough
Perspectives for FLI with DESI
-
Approximate sampling methods for fast iterations
$$\log p(x,\theta) \approx \log p(x,\theta,\hat z) + \tfrac{d}{2}\log(2\pi) +\tfrac12\log |H_z(x,\theta,\hat z)|$$
Laplace Approx with Hutchinson trace and Chebyshev polynomials for stochastic estimation of the log determinant. Then plug in MCLMC?
- Boltzmann sampling with diffusion model?
Field-level modeling of PNG
$$\begin{align*}w_g&=1+{\color{purple}b_{1}}\,\delta_{\rm L}+{\color{purple}b_{2}}\delta_{\rm L}^{2}+{\color{purple}b_{s^2}}s^{2}+ {\color{purple}b_{\nabla^2}} \nabla^2 \delta _{\rm L}\\&\quad\quad\! + {\color{purple}b_\phi f_{\rm NL}} \phi + {\color{purple} b_{\phi\delta} f_{\rm NL}} \phi \delta_{\rm L}\\\Delta \boldsymbol q_\parallel &= H^{-1} \dot{\boldsymbol q}_\parallel + {\color{purple}b_{\nabla_\parallel}} \nabla_\parallel \delta_\mathrm{L}\end{align*}$$
\(\phi_{\mathrm{NL}}=\phi+{\color{purple}f_{\mathrm{NL}}}\phi^{2}\)
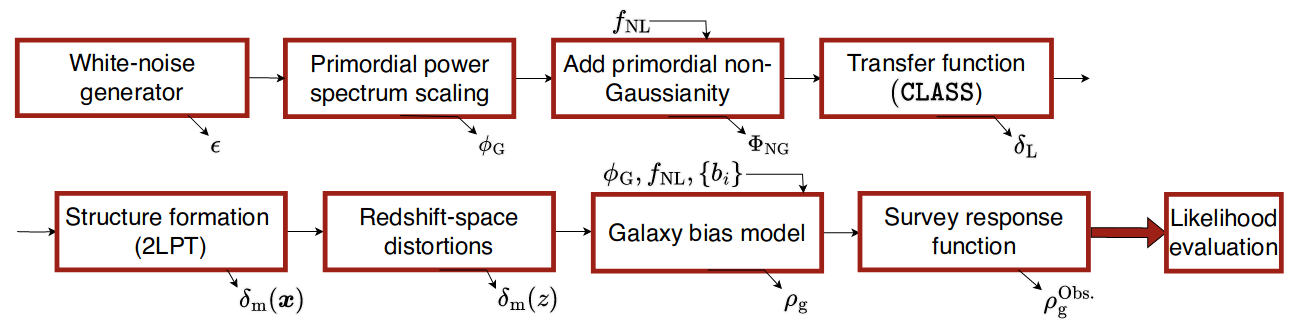
\(\boldsymbol q_\mathrm{LPT} \simeq \boldsymbol q_\mathrm{in} + \Psi_\mathrm{LPT}(\boldsymbol q_\mathrm{in}, z(\boldsymbol q_\mathrm{in}))\)
one-shot 2LPT light-cone
\(n_g^\mathrm{obs}(\boldsymbol q) \approx (1+\delta_g(\boldsymbol q))\, {\color{purple}\bar n_g(\,r)}\, {\color{blue}W(\boldsymbol q)}\, (1+{\color{purple}\beta_i} {\color{green}T^i(\theta)})\)
RIC relax + selection + imag. templates
\(\delta_g \sim \mathcal N(\delta_g^\mathrm{det}, \sigma^2)\) with
\(\sigma(k) = {\color{purple}\sigma_0}(1+{\color{purple}\sigma_2} k^2 + {\color{purple}\sigma_{\mu2}}(k\mu)^2)\)
EFT-based modeling, many scale cuts alleviating discretization effects (see Stadler+2024)
A word on integral constraints
Radial Integral Constraint
\(\delta_g \propto n_g - \braket{n_g}\approx n_g - \bar n_g(r)\)
i.e. impose \(\bar \delta_g(r) = 0\)
Global Integral Constraint
\(\delta_g \propto n_g - \braket{n_g} \approx n_g - \bar n_g\)
i.e. impose \(\bar \delta_g = 0\)
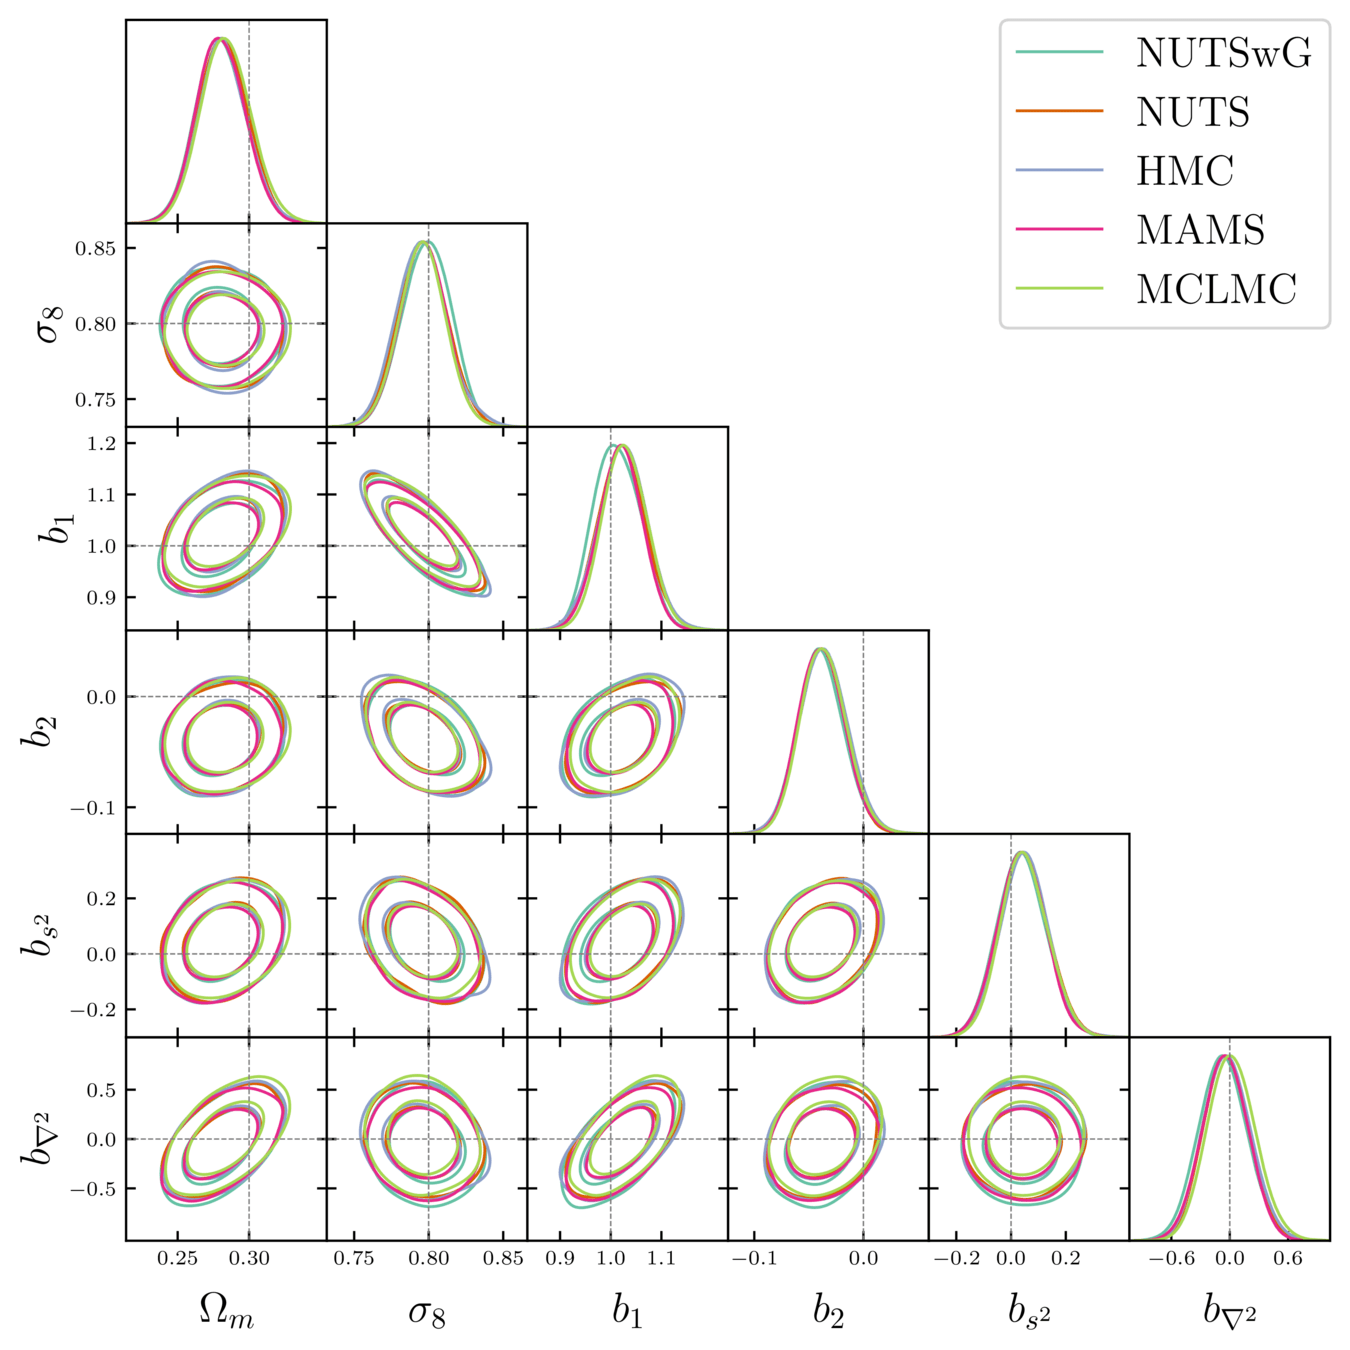
- Different samplers and strategies used for field-level (e.g. Lavaux+2018, Bayer+2023). Additional comparisons required.
- We provide a consistent benchmark for field-level from galaxy surveys. Build upon \(\texttt{NumPyro}\) and \(\texttt{BlackJAX}\).
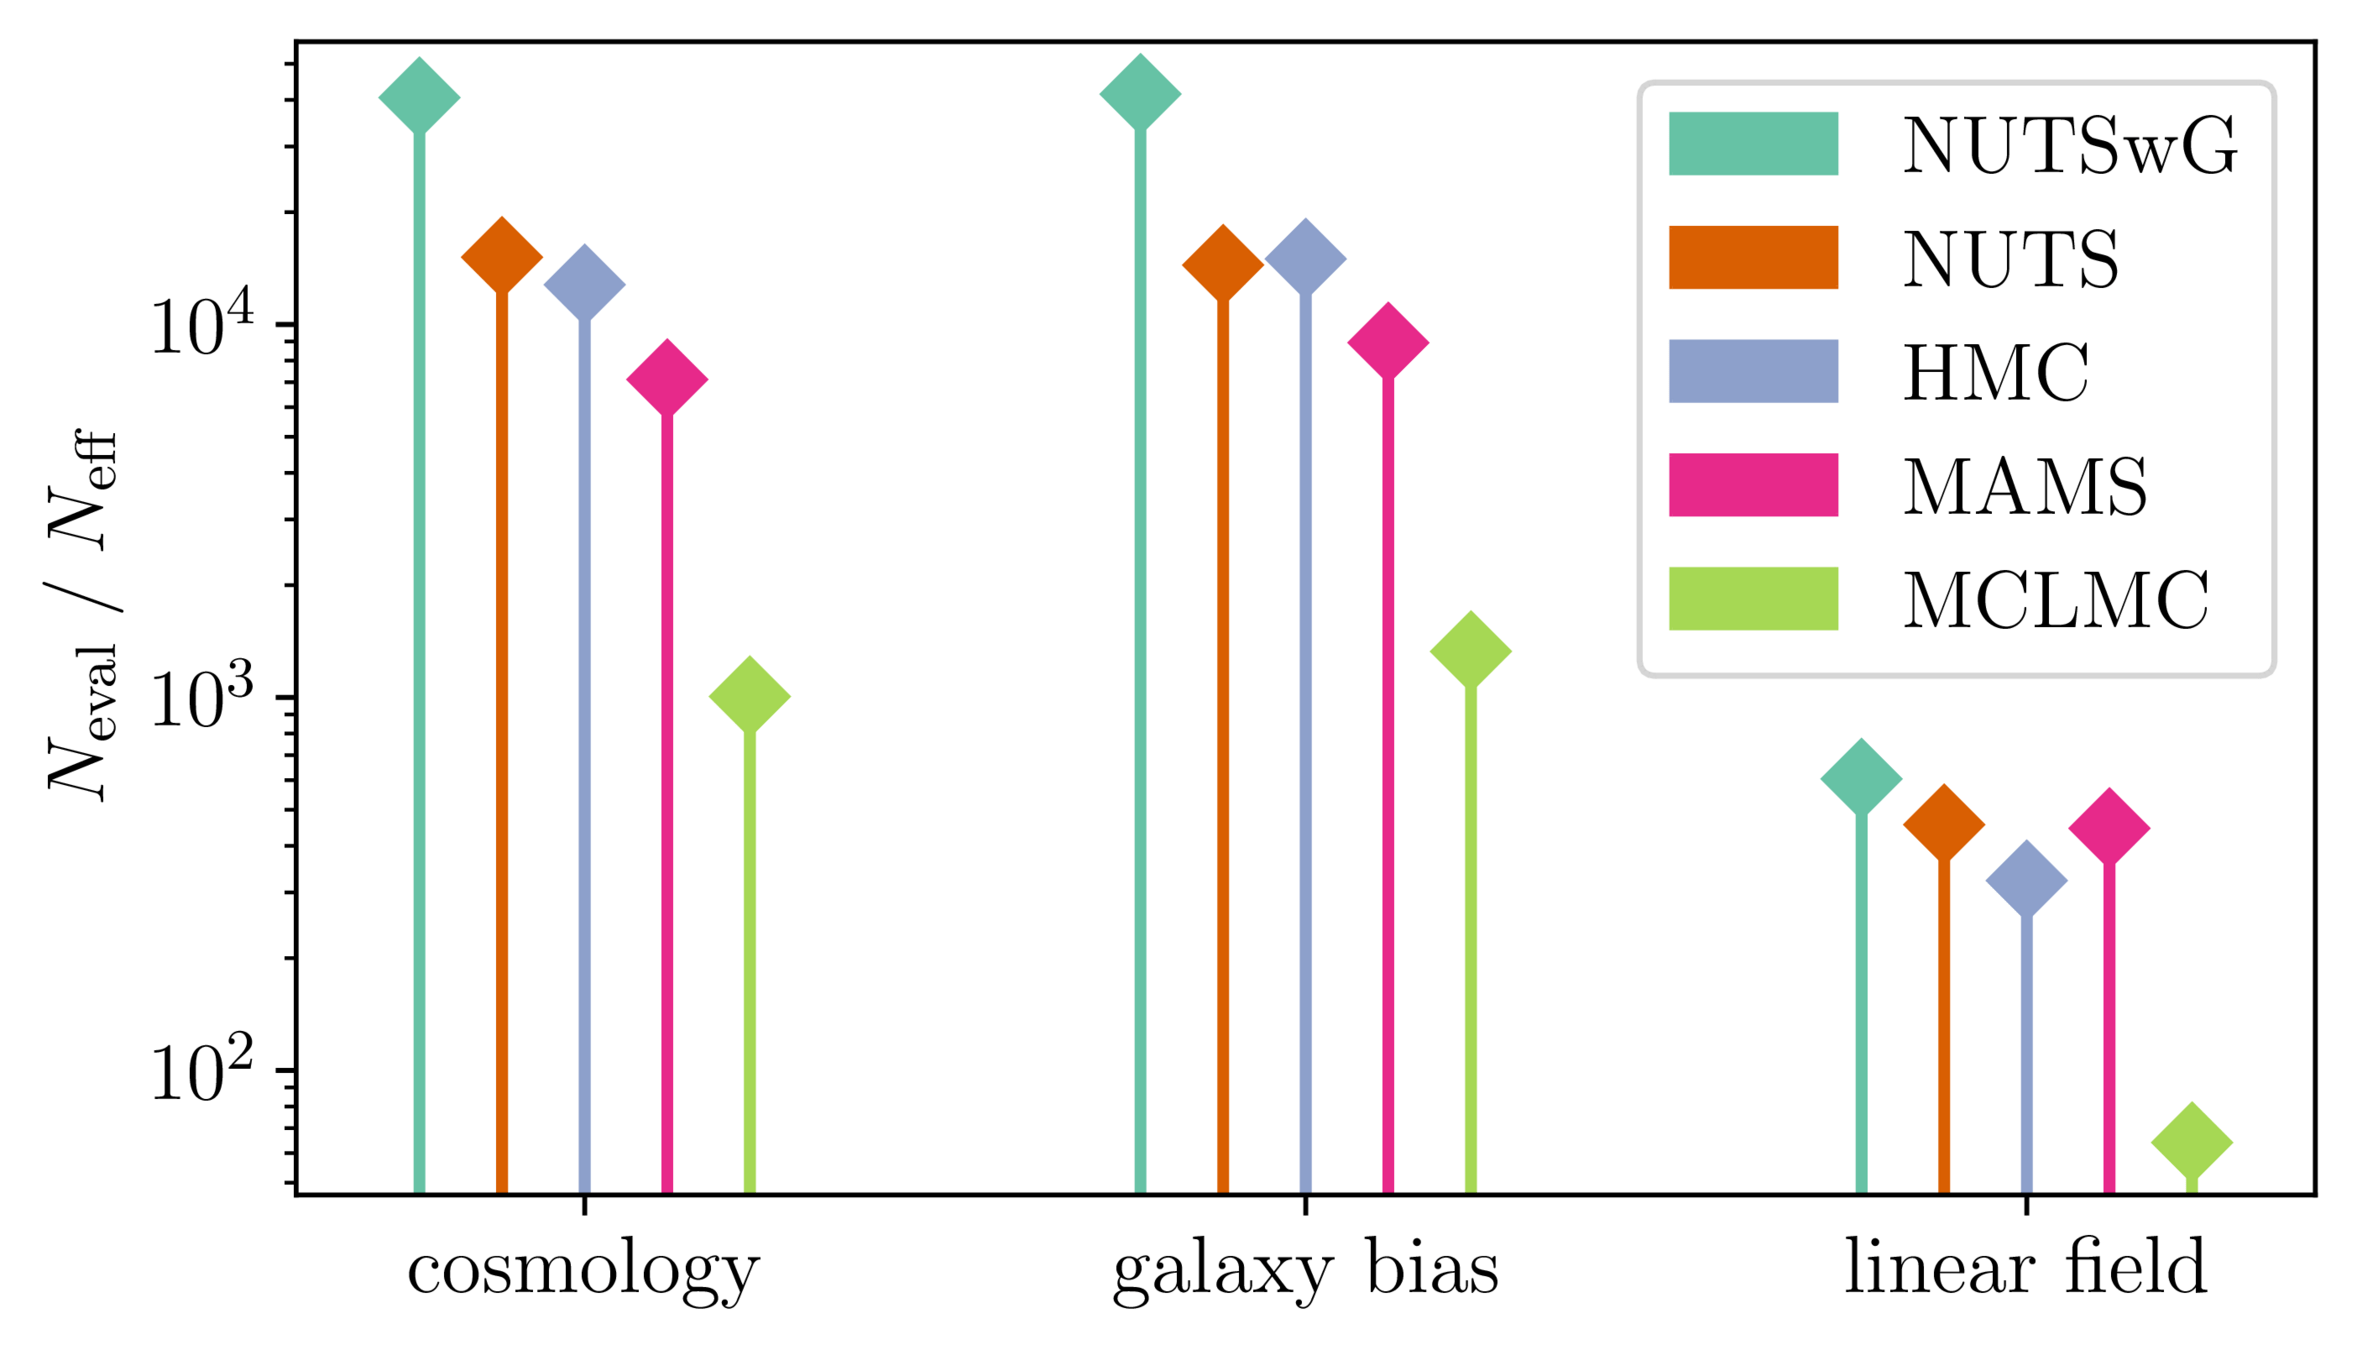
Samplers comparison
= NUTS within Gibbs
= auto-tuned HMC
= adjusted MCHMC
= unadjusted Langevin MCHMC
10 times less evaluations required
Unadjusted microcanonical sampler outperforms any adjusted sampler
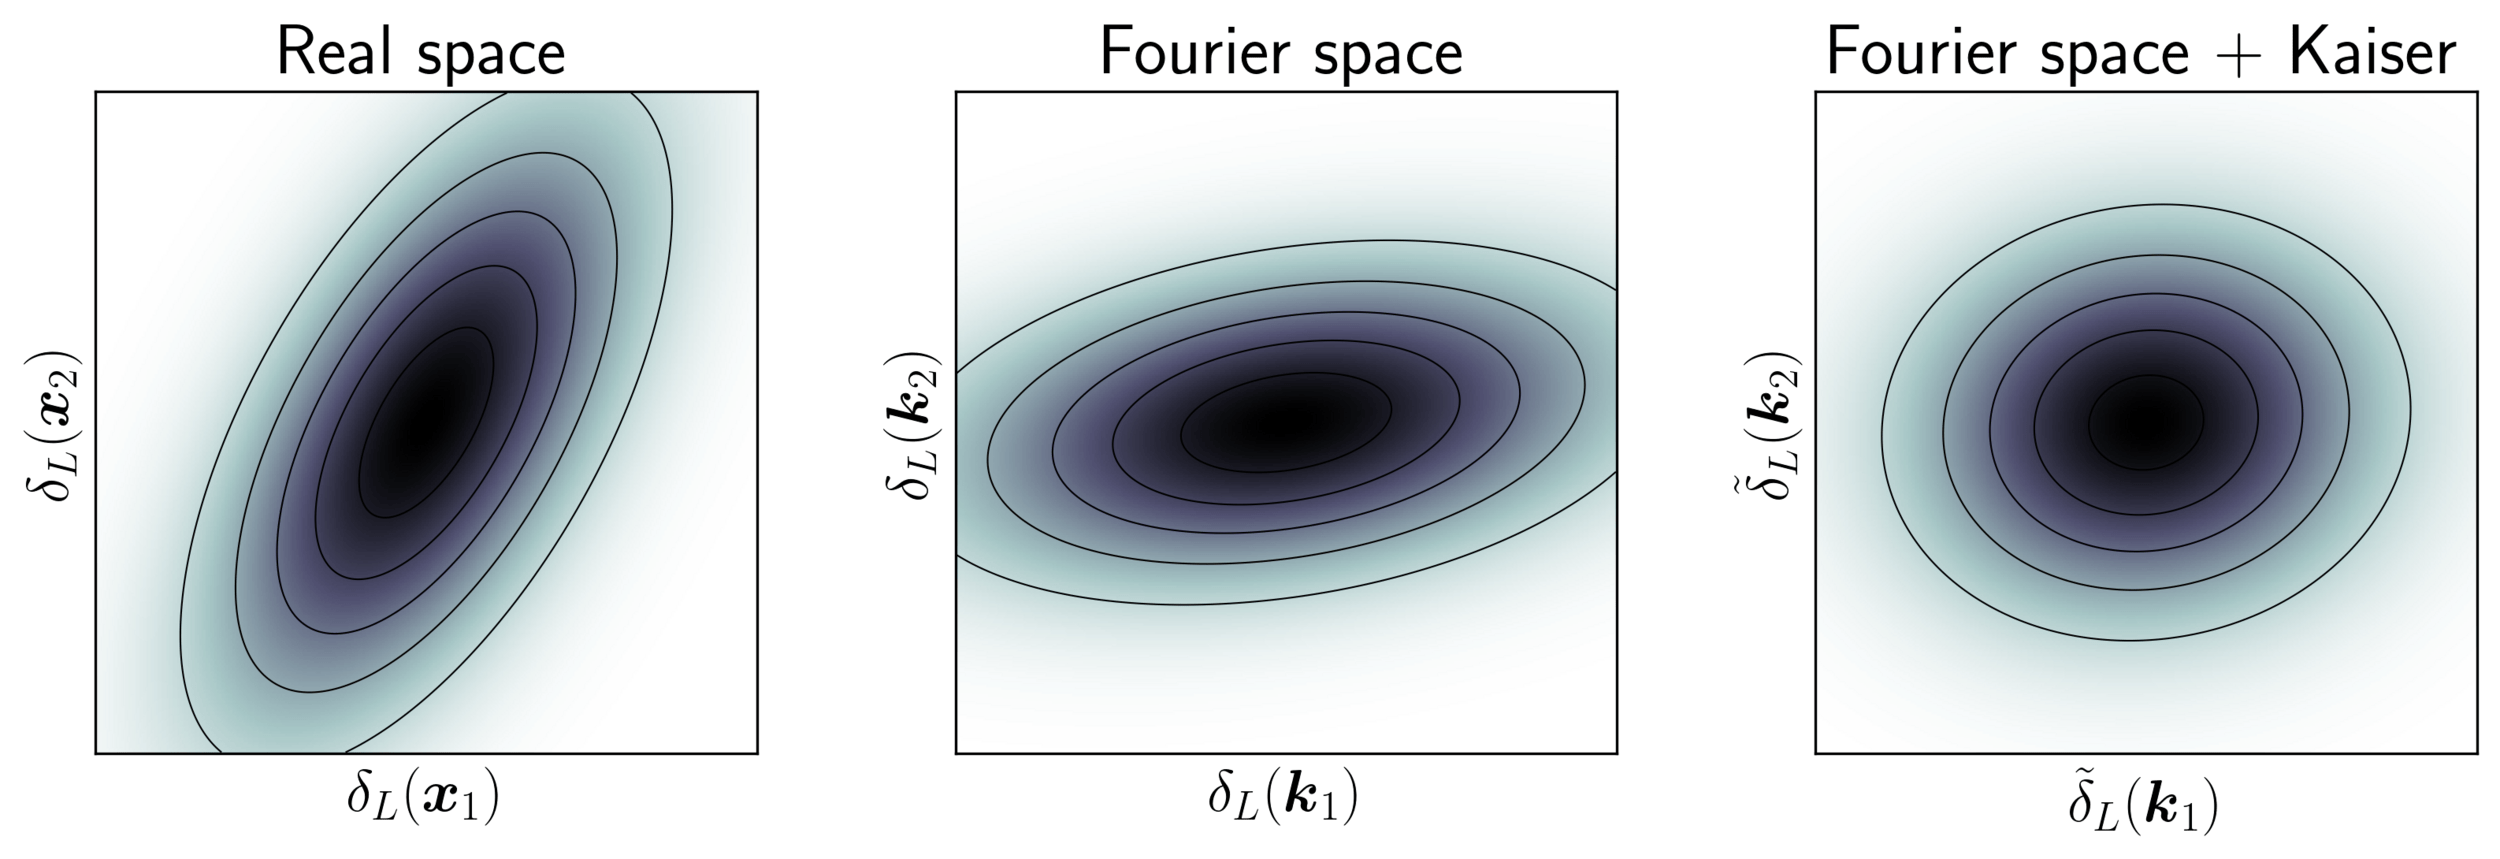
Model preconditioning
- Sampling is easier when target density is isotropic Gaussian
- The model is reparametrized assuming a tractable Kaiser model:
linear growth + linear Eulerian bias + flat sky RSD + Gaussian noise
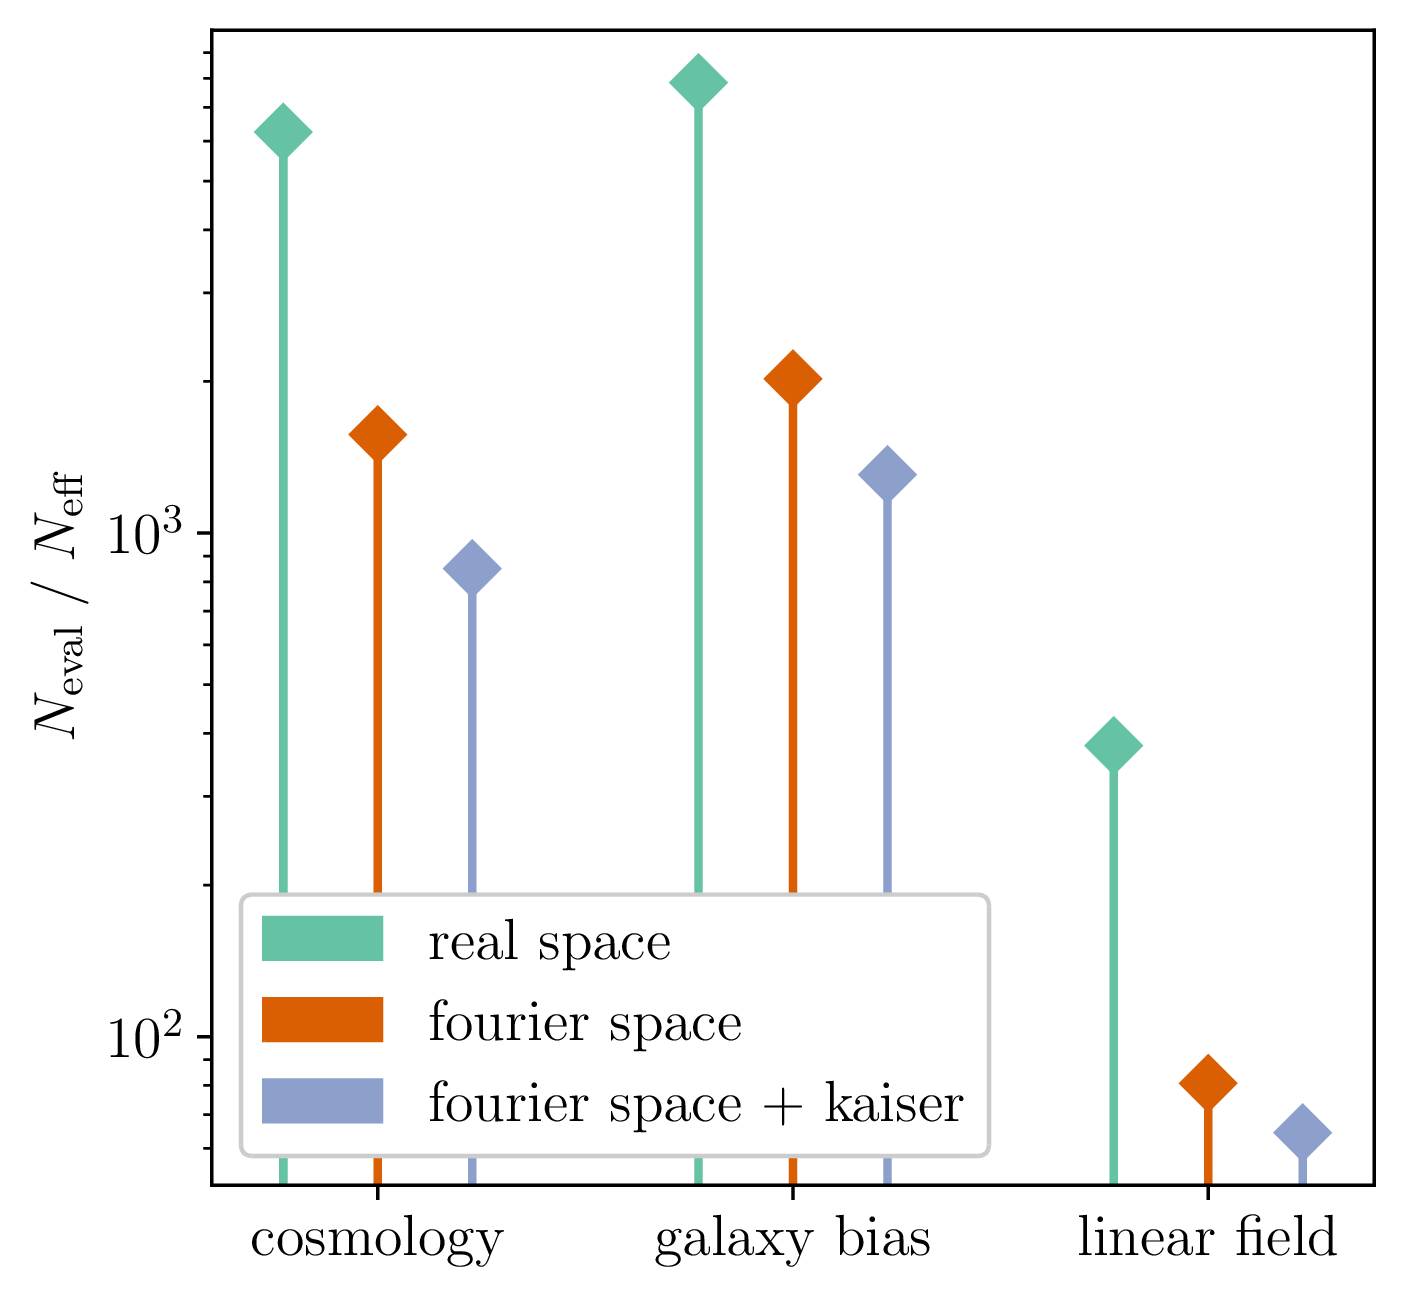
10 times less evaluations required
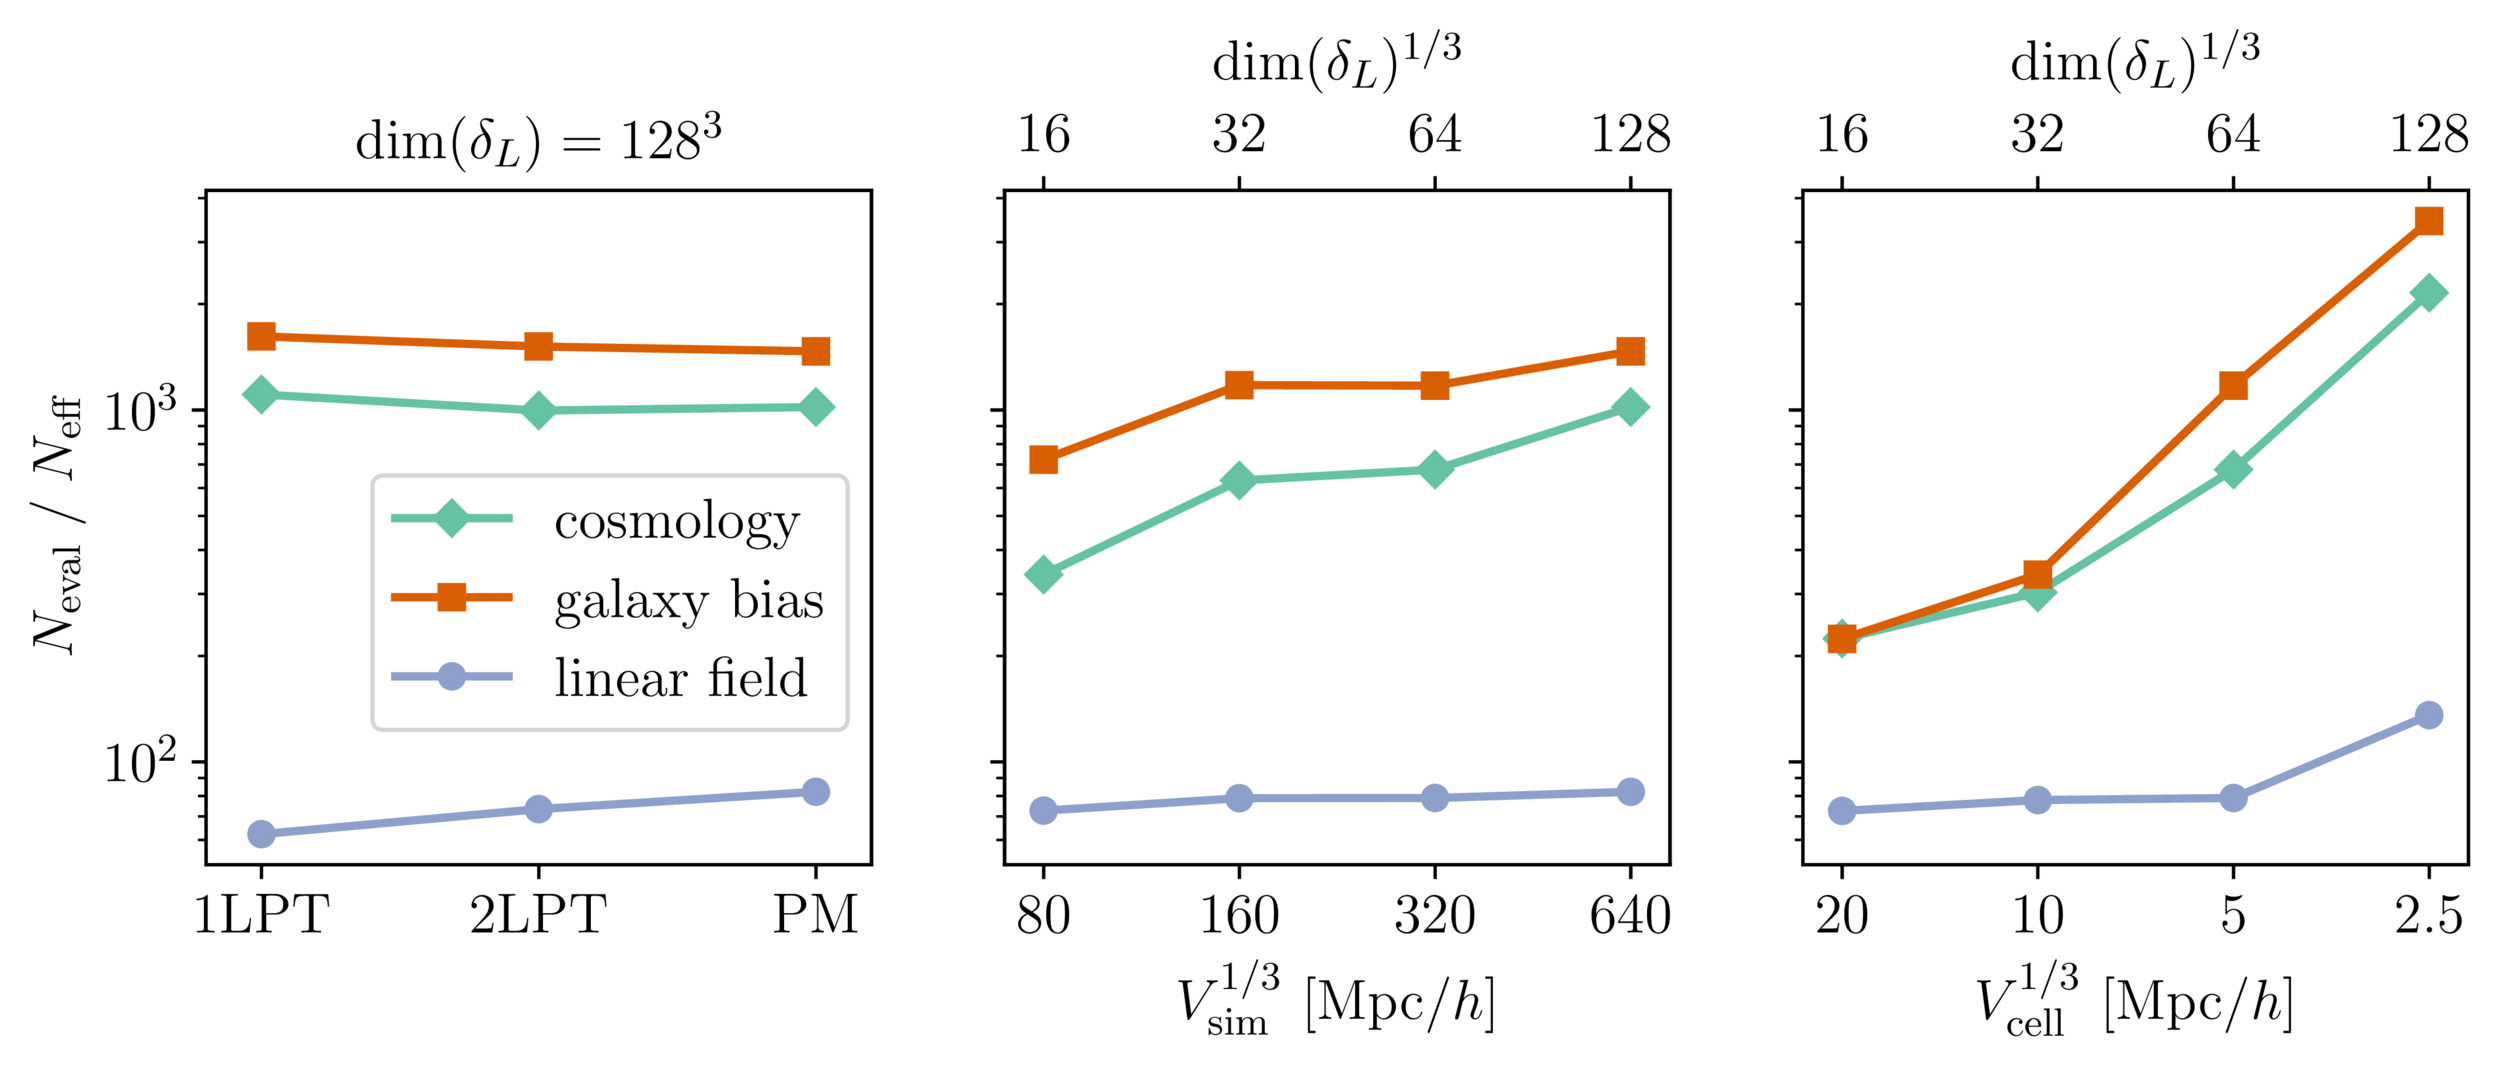
Benchmark results
- Promising for future inferences, going multi-GPU using JaxDecomp
- Code readily available at github.com/hsimonfroy/benchmark-field-level
Mildly dependent with respect to formation model and volume
Probing smaller scales could be harder
MCLMC sampler + field-level preconditioning assuming a linear Kaiser model:
4h on a 8GPU-node for \(128^3\) PM inference
Handling bias in unadjusted MCLMC
- Microcanonical dynamics \(\implies\) energy should not vary
- Numerical integration yields quantifiable errors that can be linked to bias
- Stepsize can be tuned to ensure controlled bias, see Robnik+2024
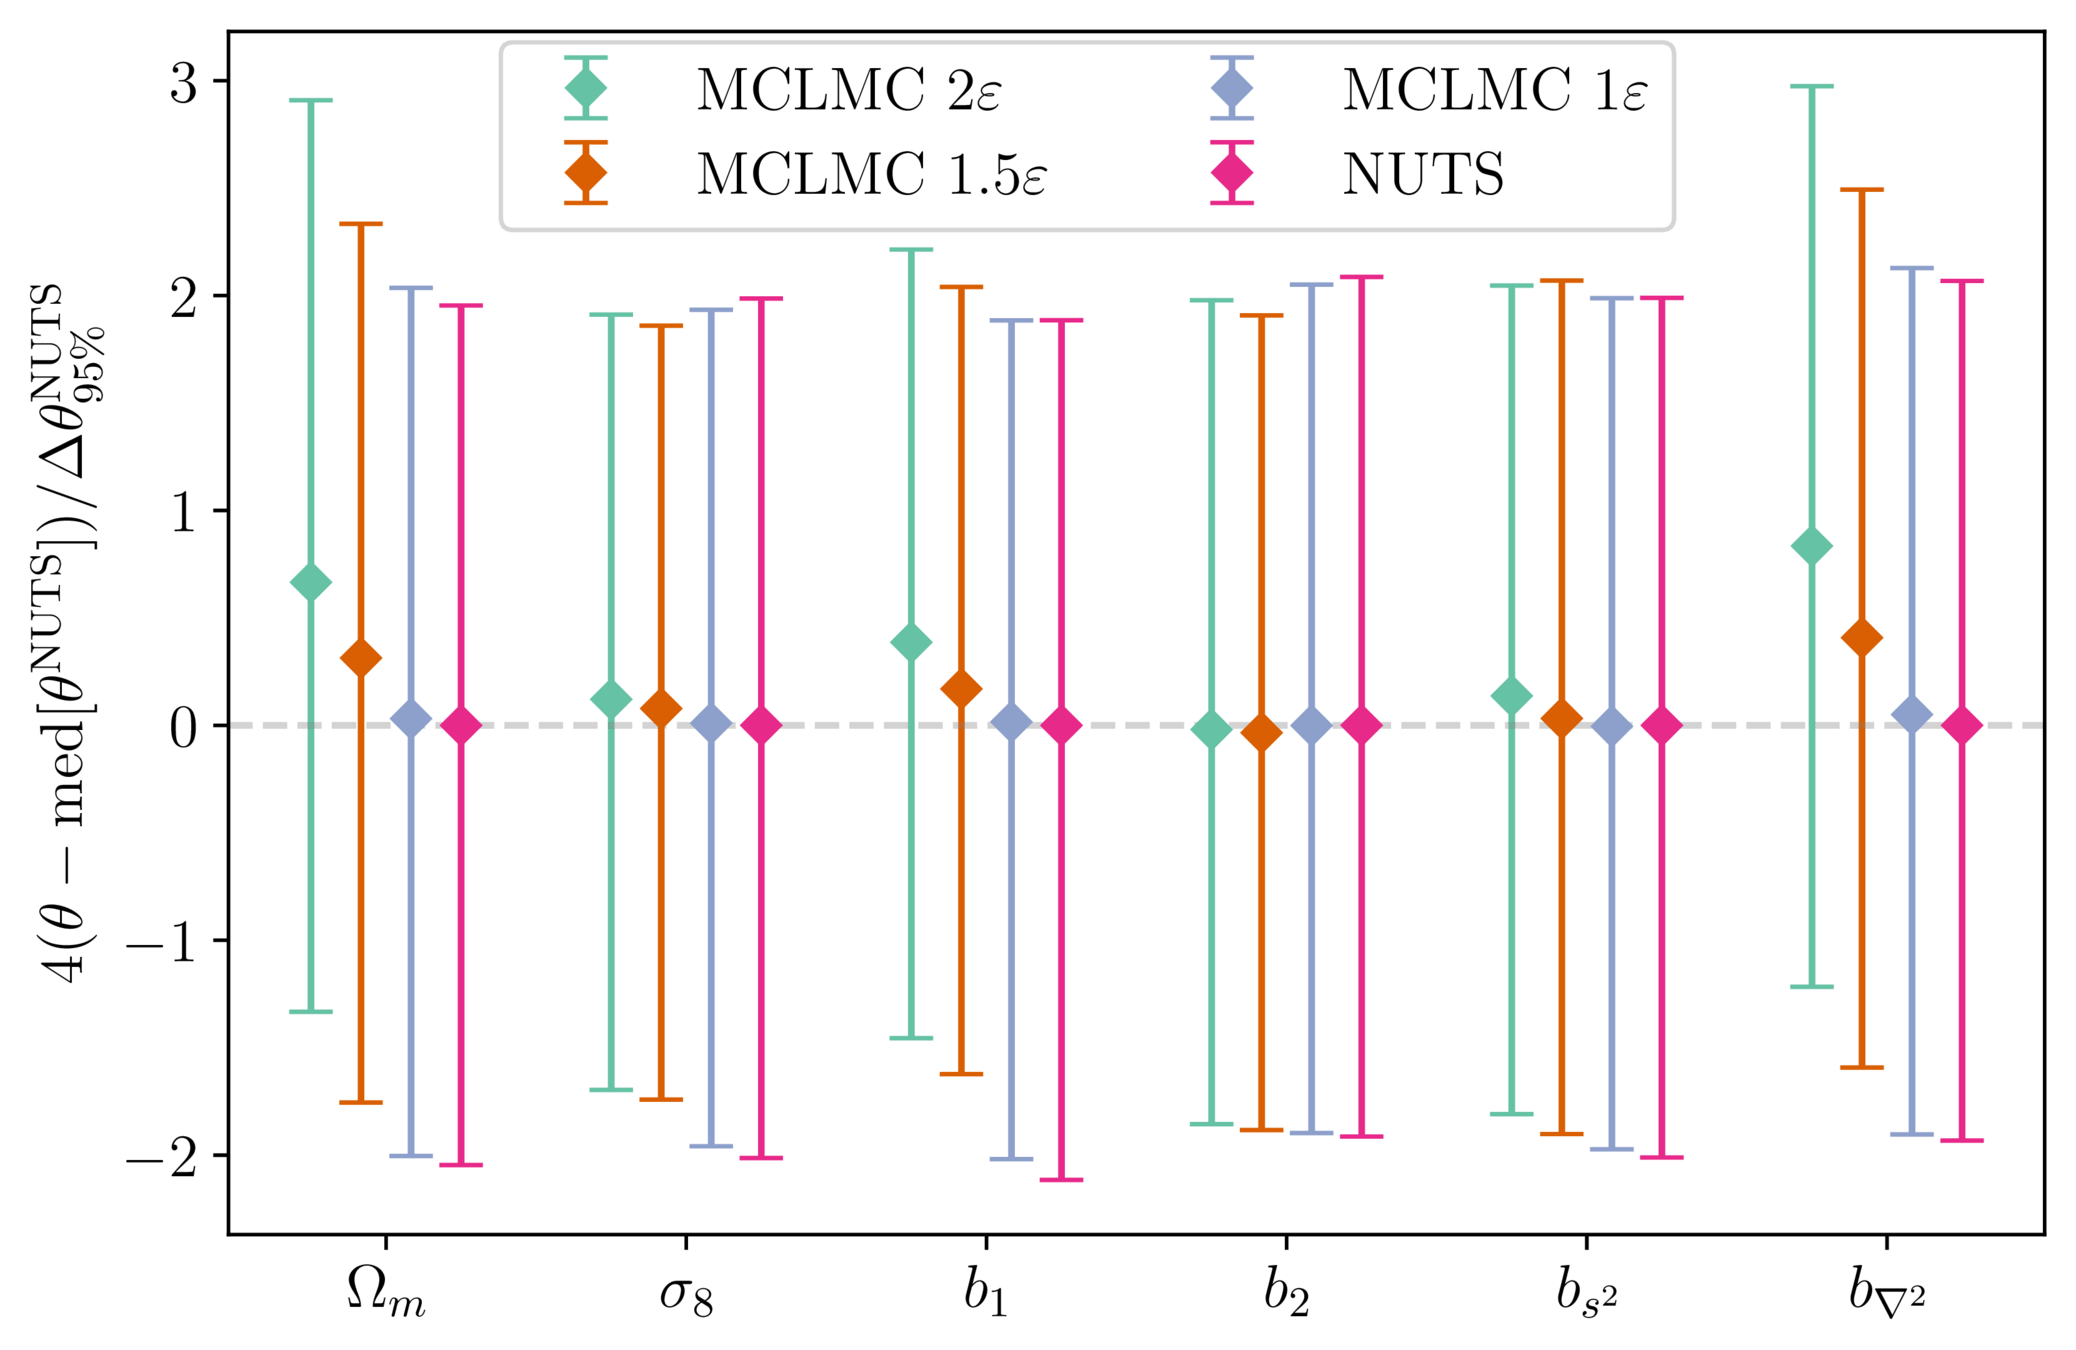
reducing stepsize rapidly brings bias under Monte Carlo error