In Search of News Past
The Challenges and Opportunities of Interdisciplinarity at the Impresso Project
Martin Grandjean
ULB 28.09.2026
The Impresso project
"Media Monitoring of the Past"
Introduction
The Impresso Project
Impresso 1
2017-2020
Impresso 2
2023-2027
Developing new approaches and interfaces for the exploration and critical analysis of historical media archives.
Swiss and Luxembourg newspapers
Cutting-edge platform
New collections from across Europe
Radio broadcasts
Datalab
Impresso 2
Funded by:
Hosted by:
Team
Principal investigators
An interdisciplinary team spanning history, web development, linguistics, and digital humanities
Partners
A network of partner institutions that provide digitized newspaper and radio collections
Data & Design
Making this much data available to the general public
Challenge 1
Challenge 1
The data
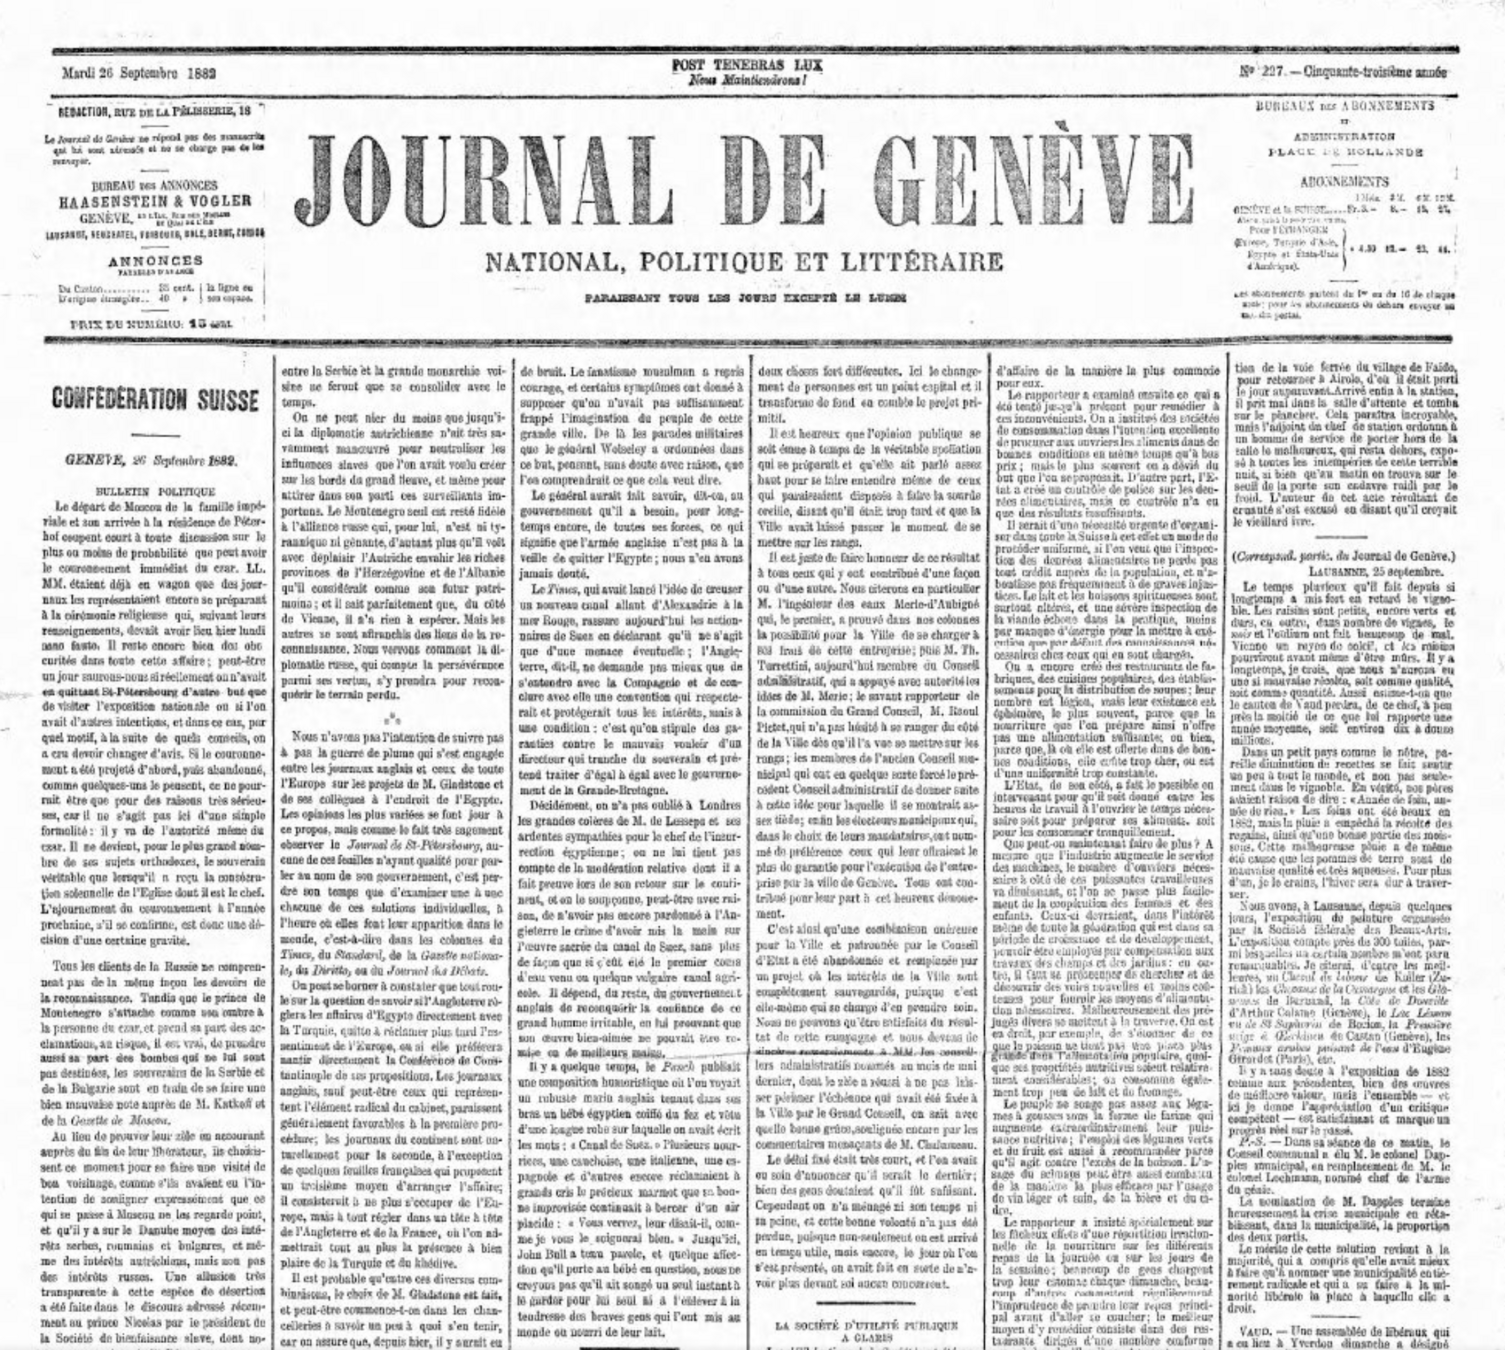
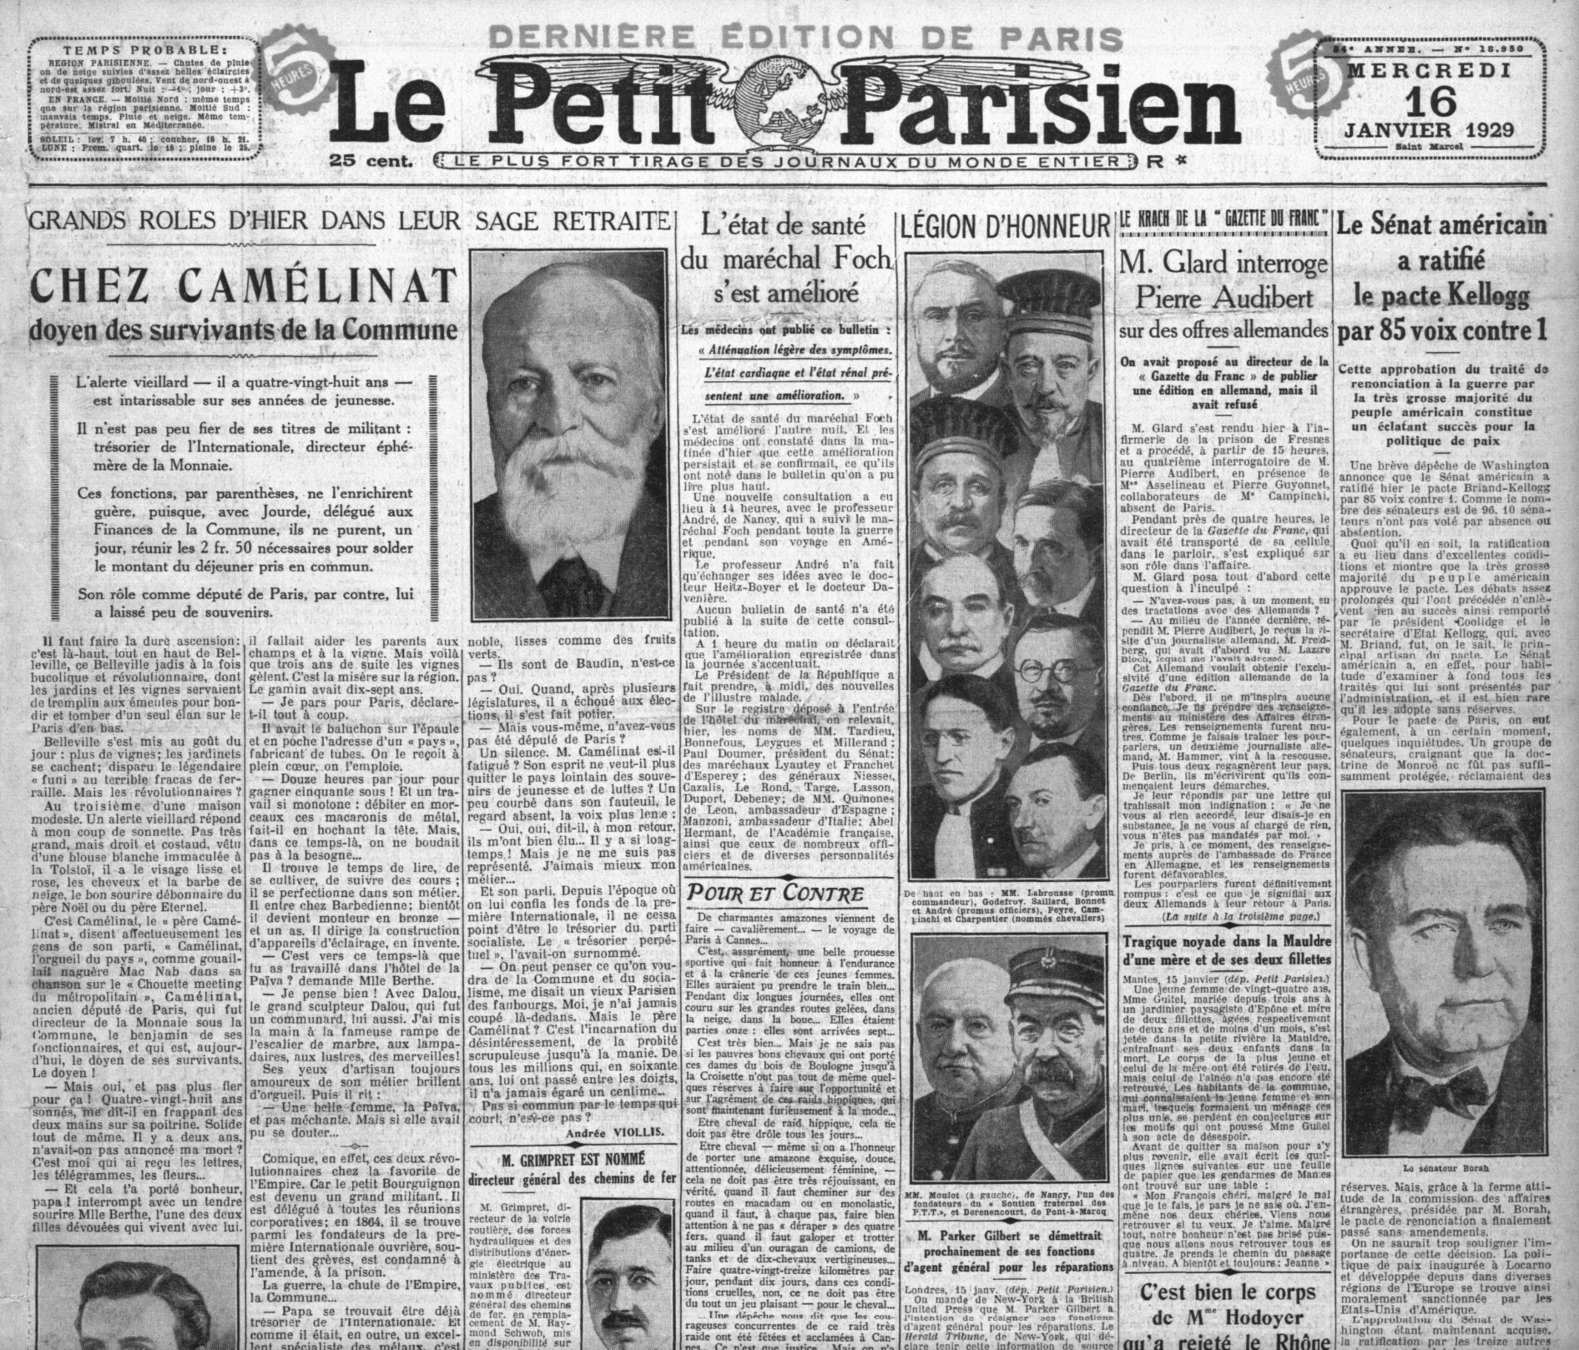
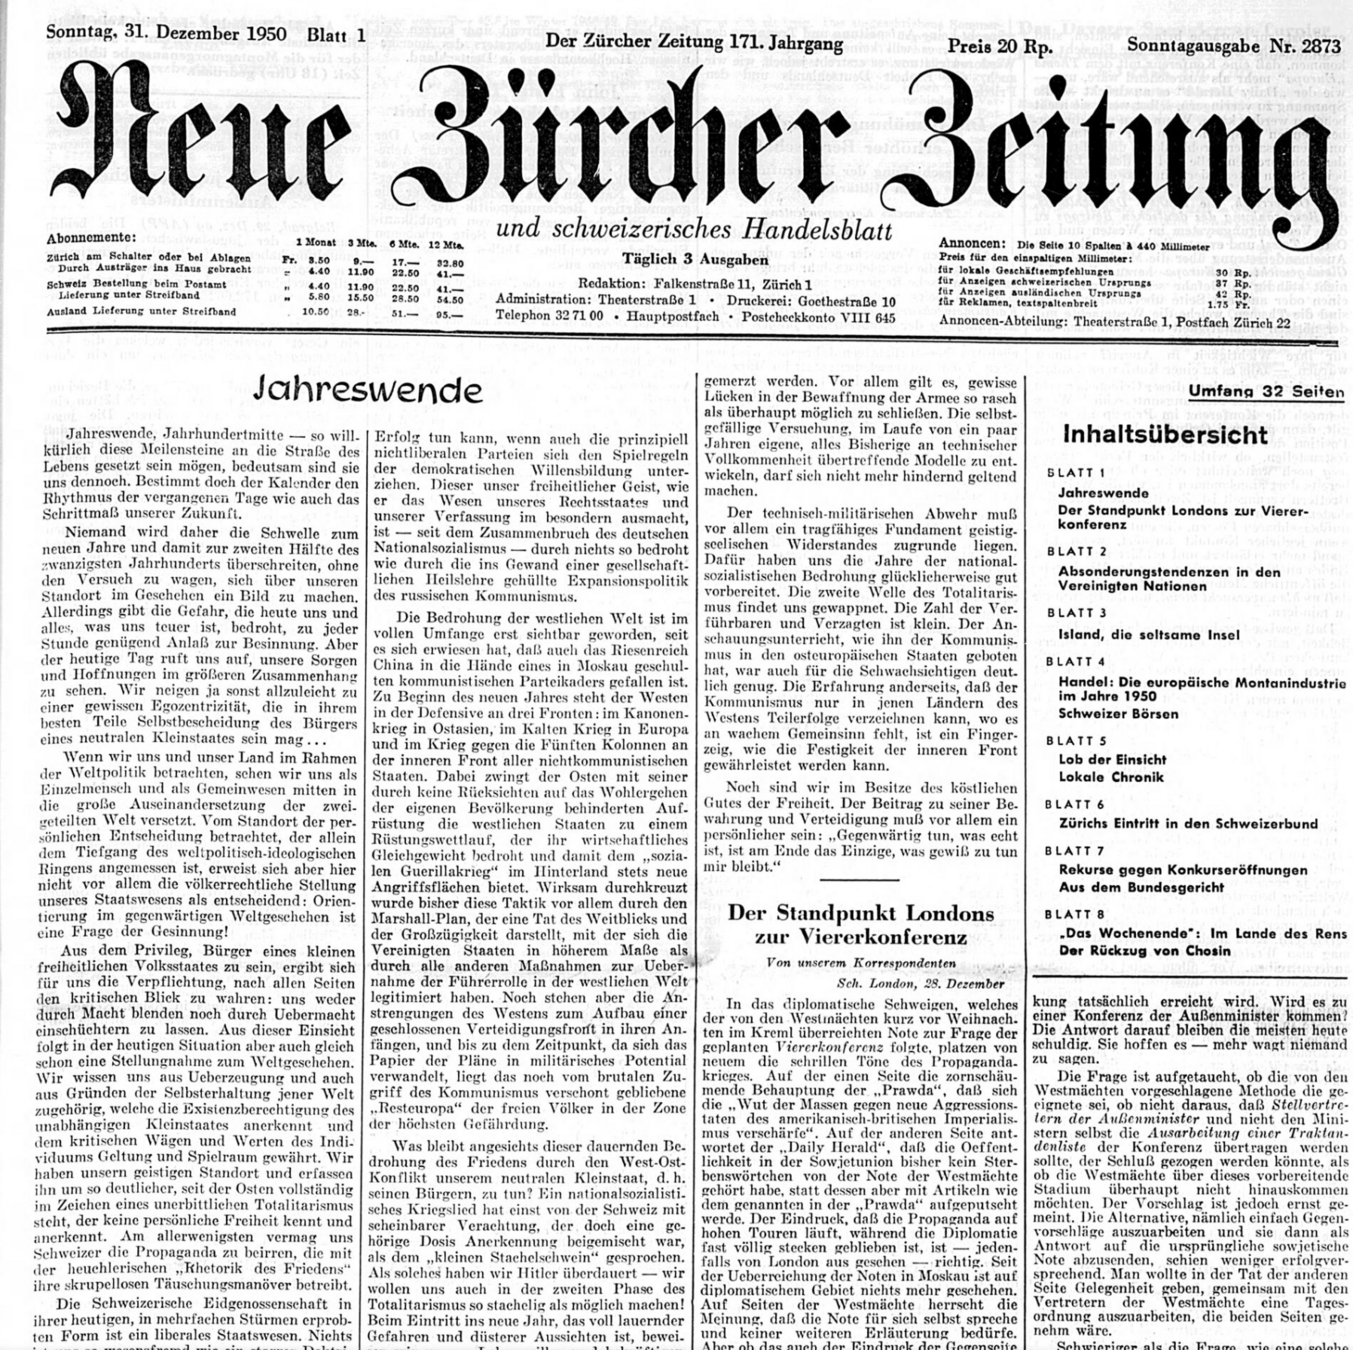
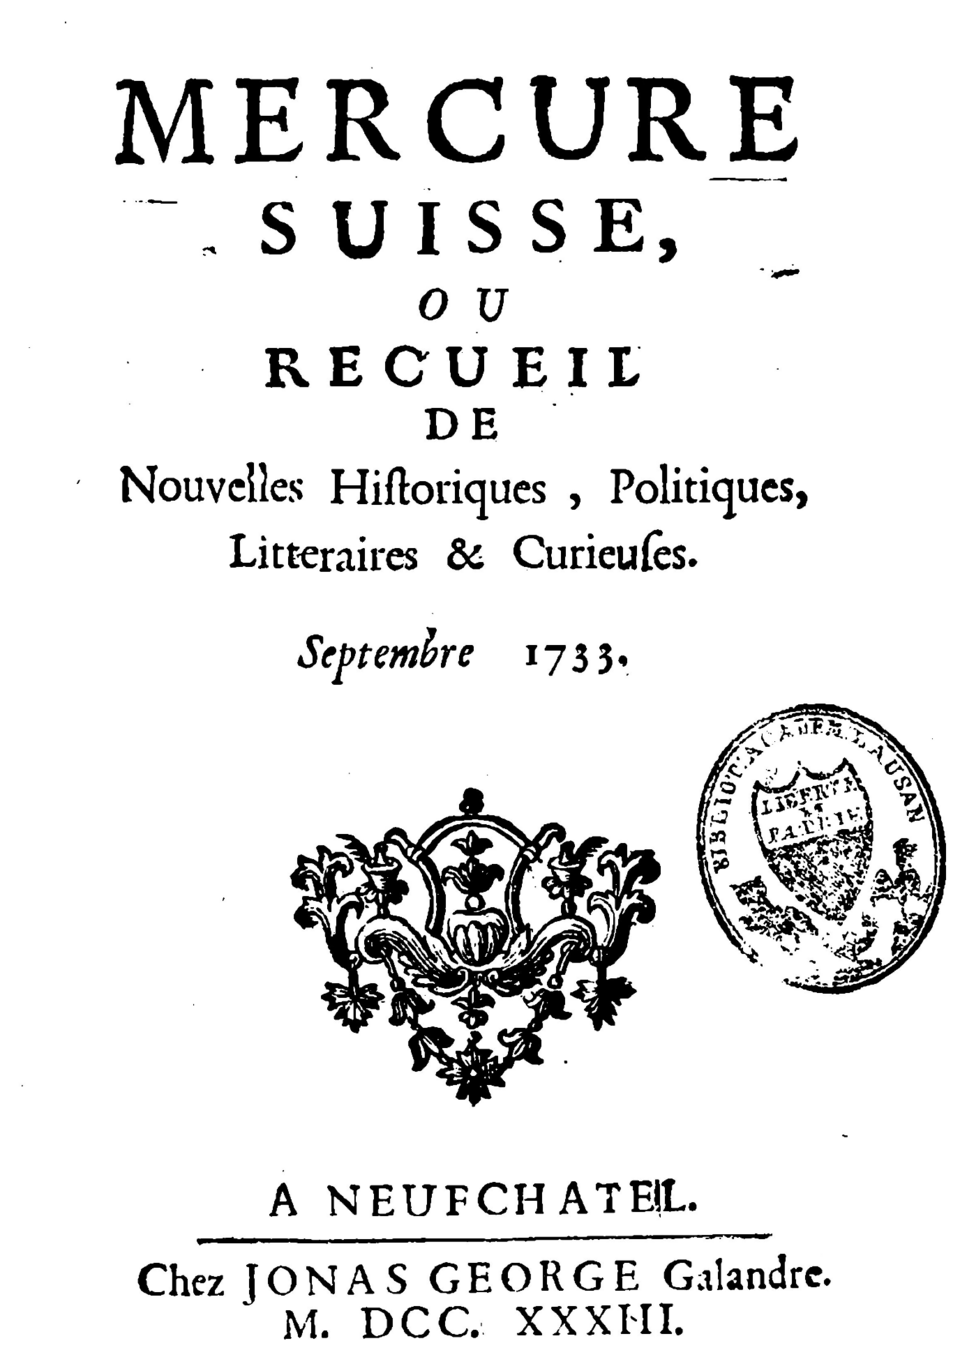
The collections are massive, but also very diverse:
- wide time spans
- different countries and languages
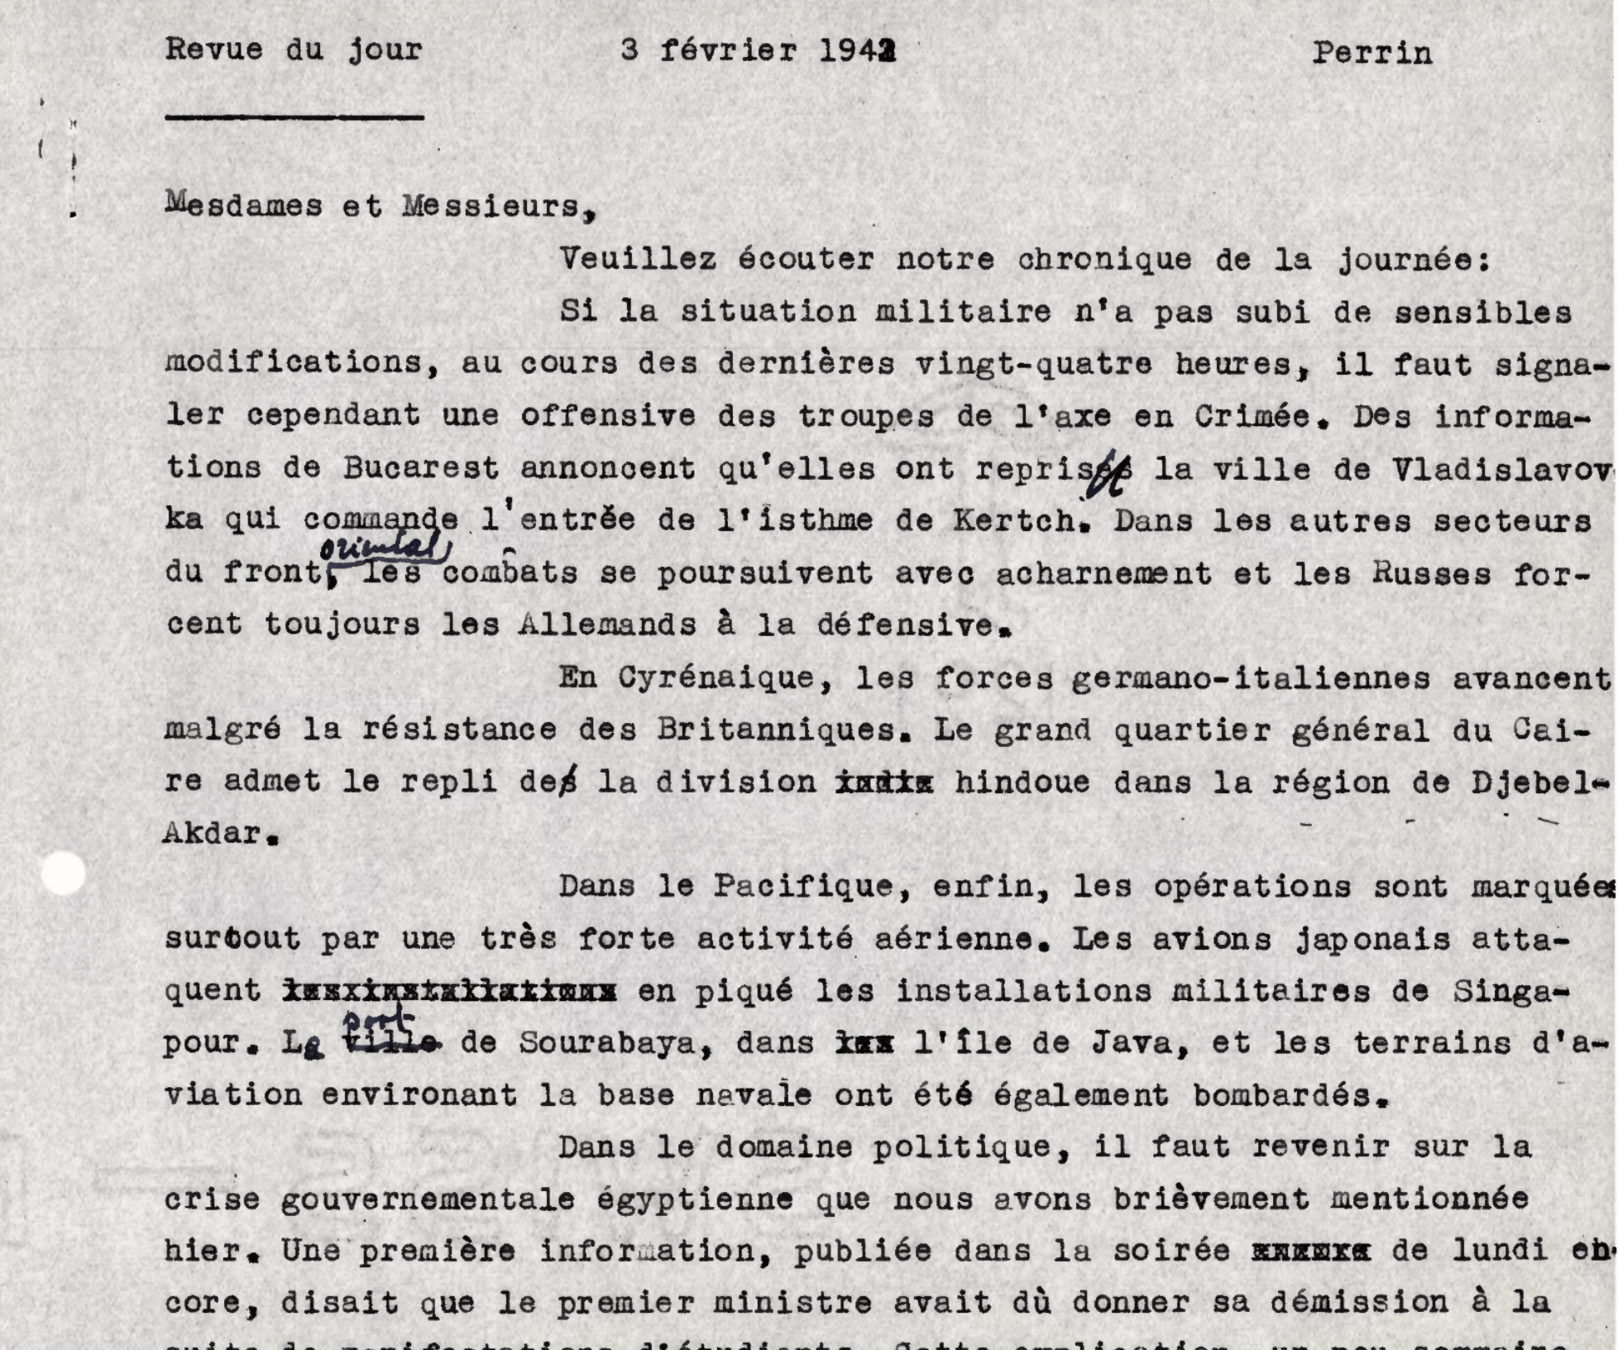
- different types of sources (newspapers, radio, typescripts)
- varying OCR quality
Press from 1732 to 2018
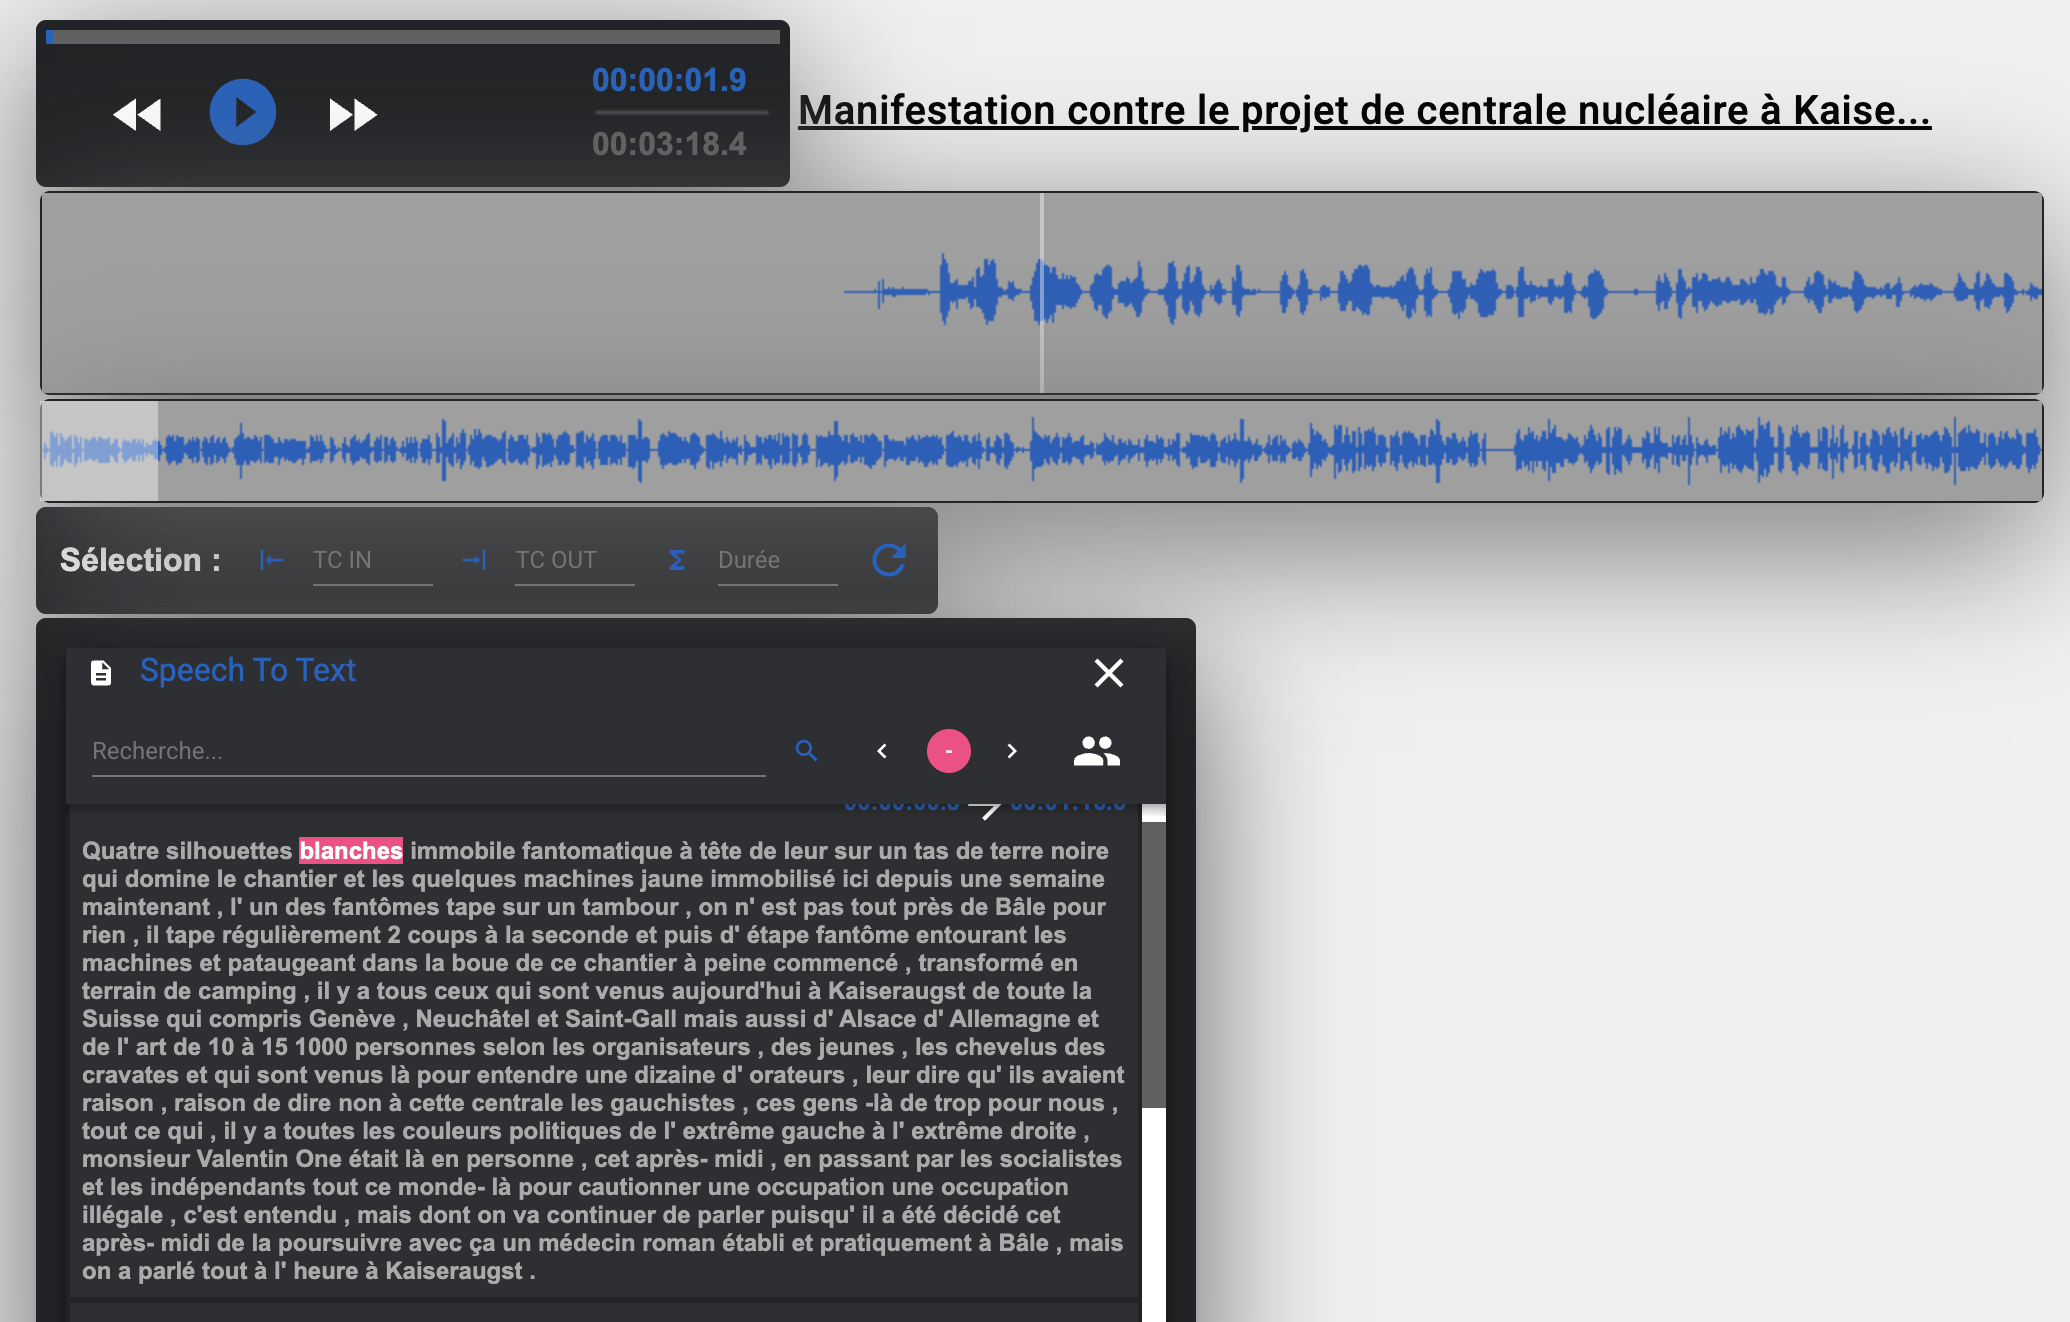
Radio programs in audio format with speech-to-text
Transcripts of radio news broadcasts
Challenge 1
The data
The collections come from different institutions:
- different jurisdictions, requirements, and policies
- different shared data, metadata, formats, and transcriptions
- different copyright regimes, approaches to managing the public domain, and gray areas
Consequences:
- Signing of multiple data-sharing agreements
- Identification of target audiences and differentiated access rights
- Identification of different types of access (view text excerpts, view facsimiles, export metadata or full text)
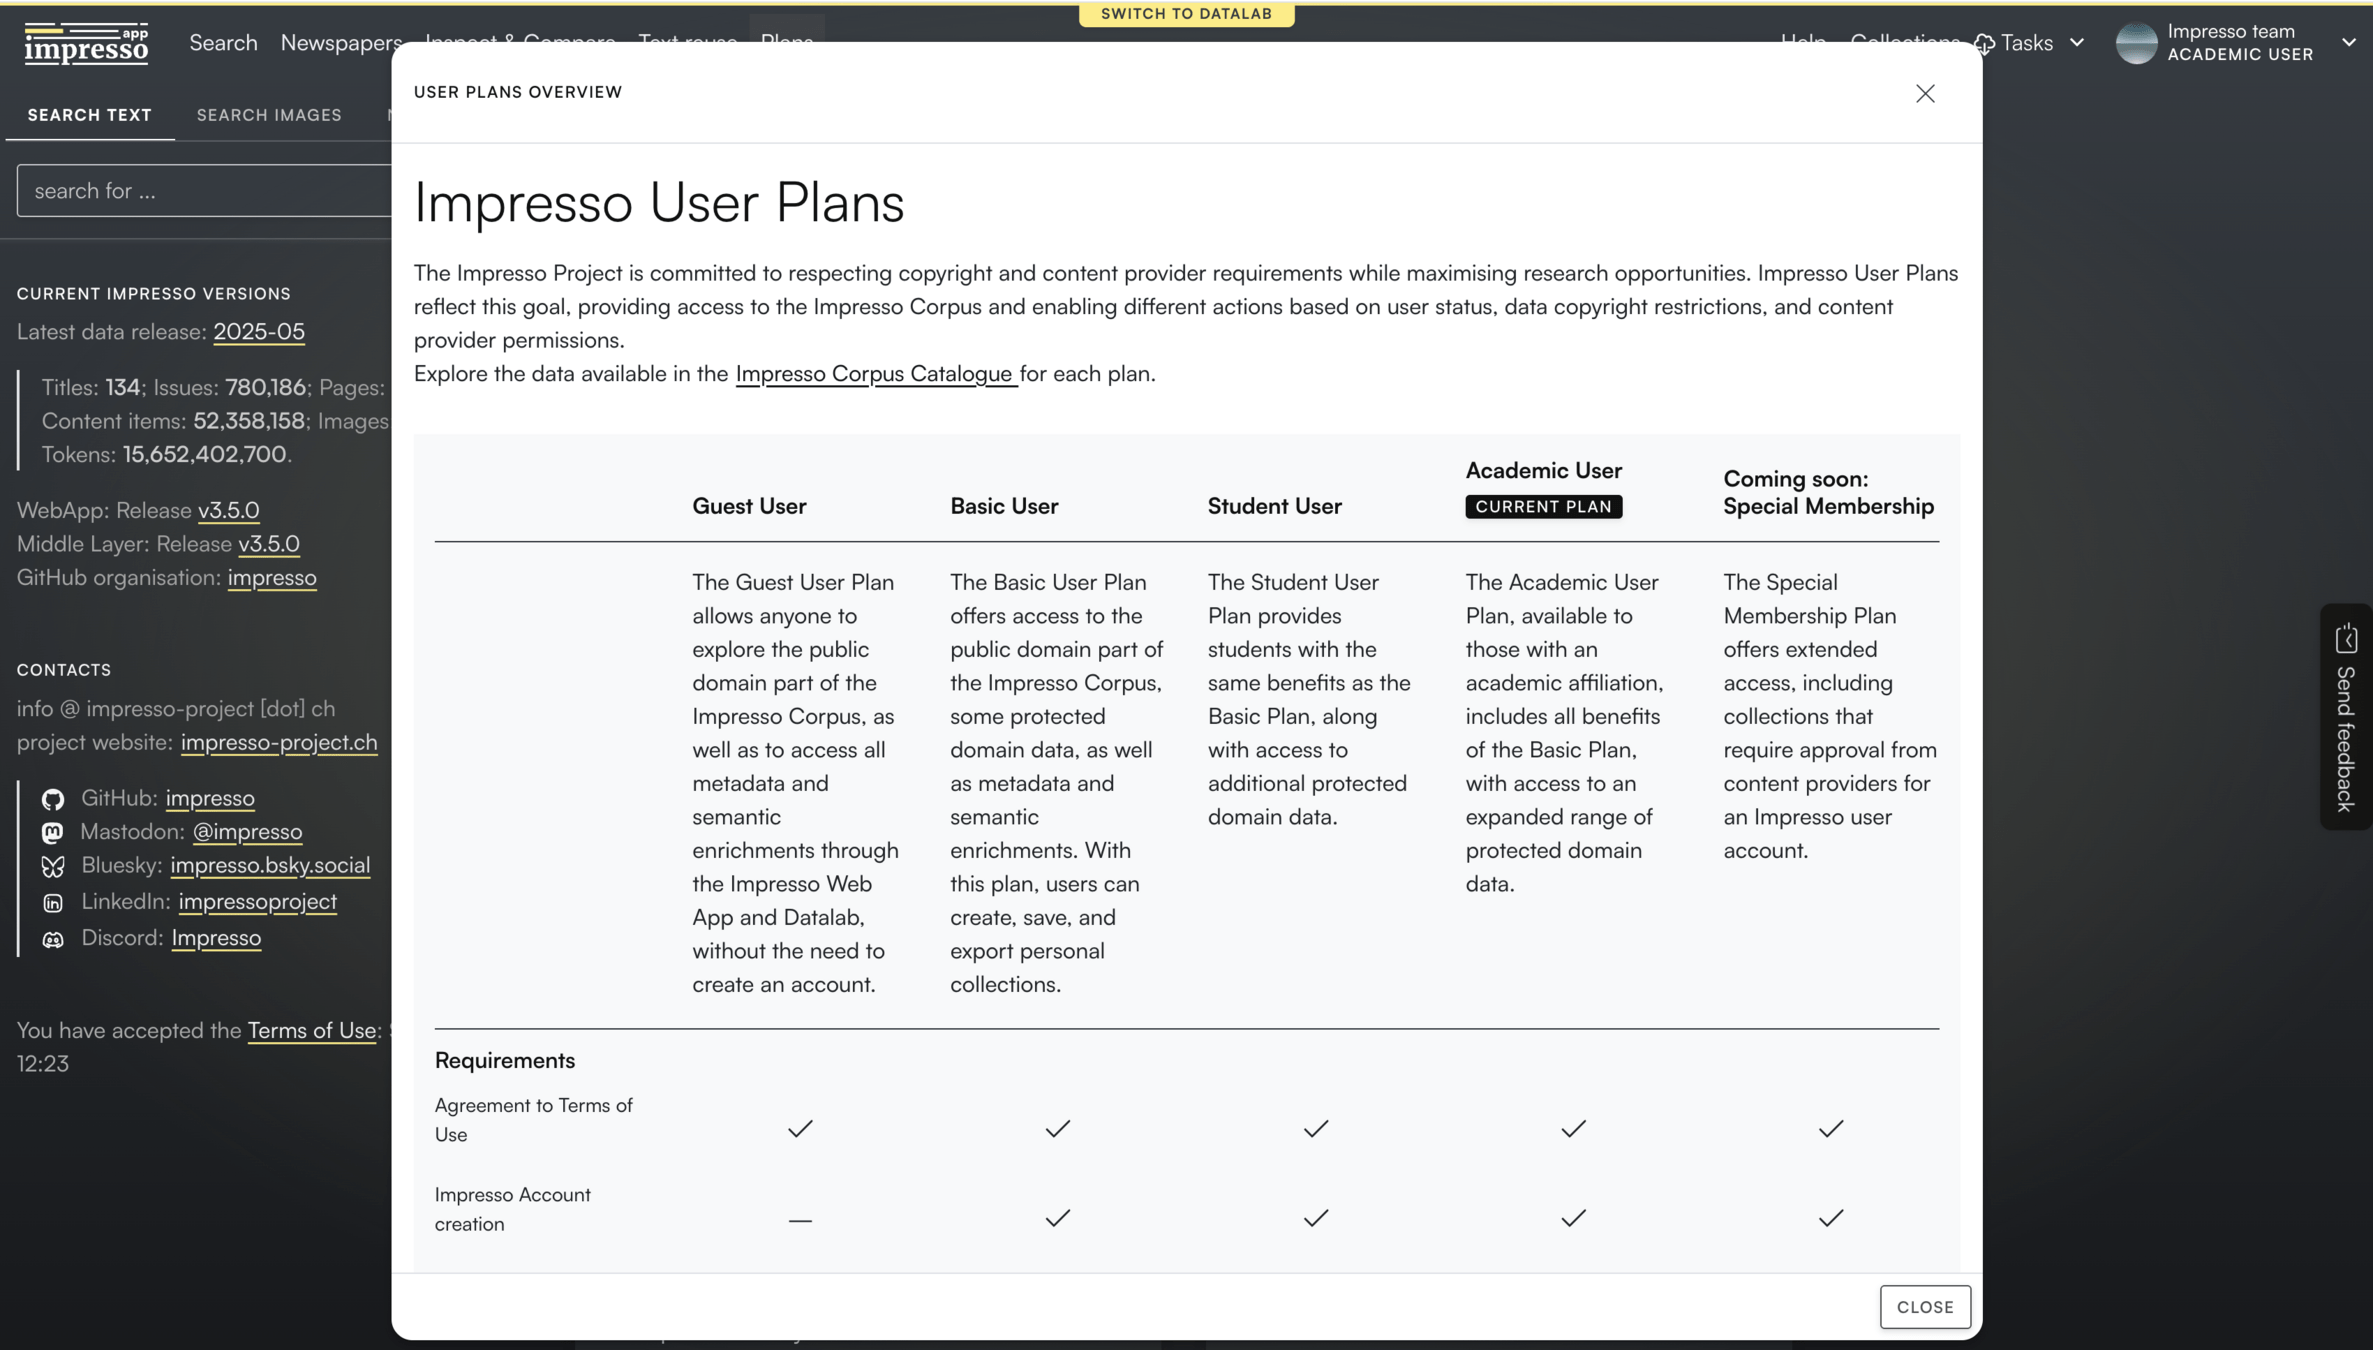
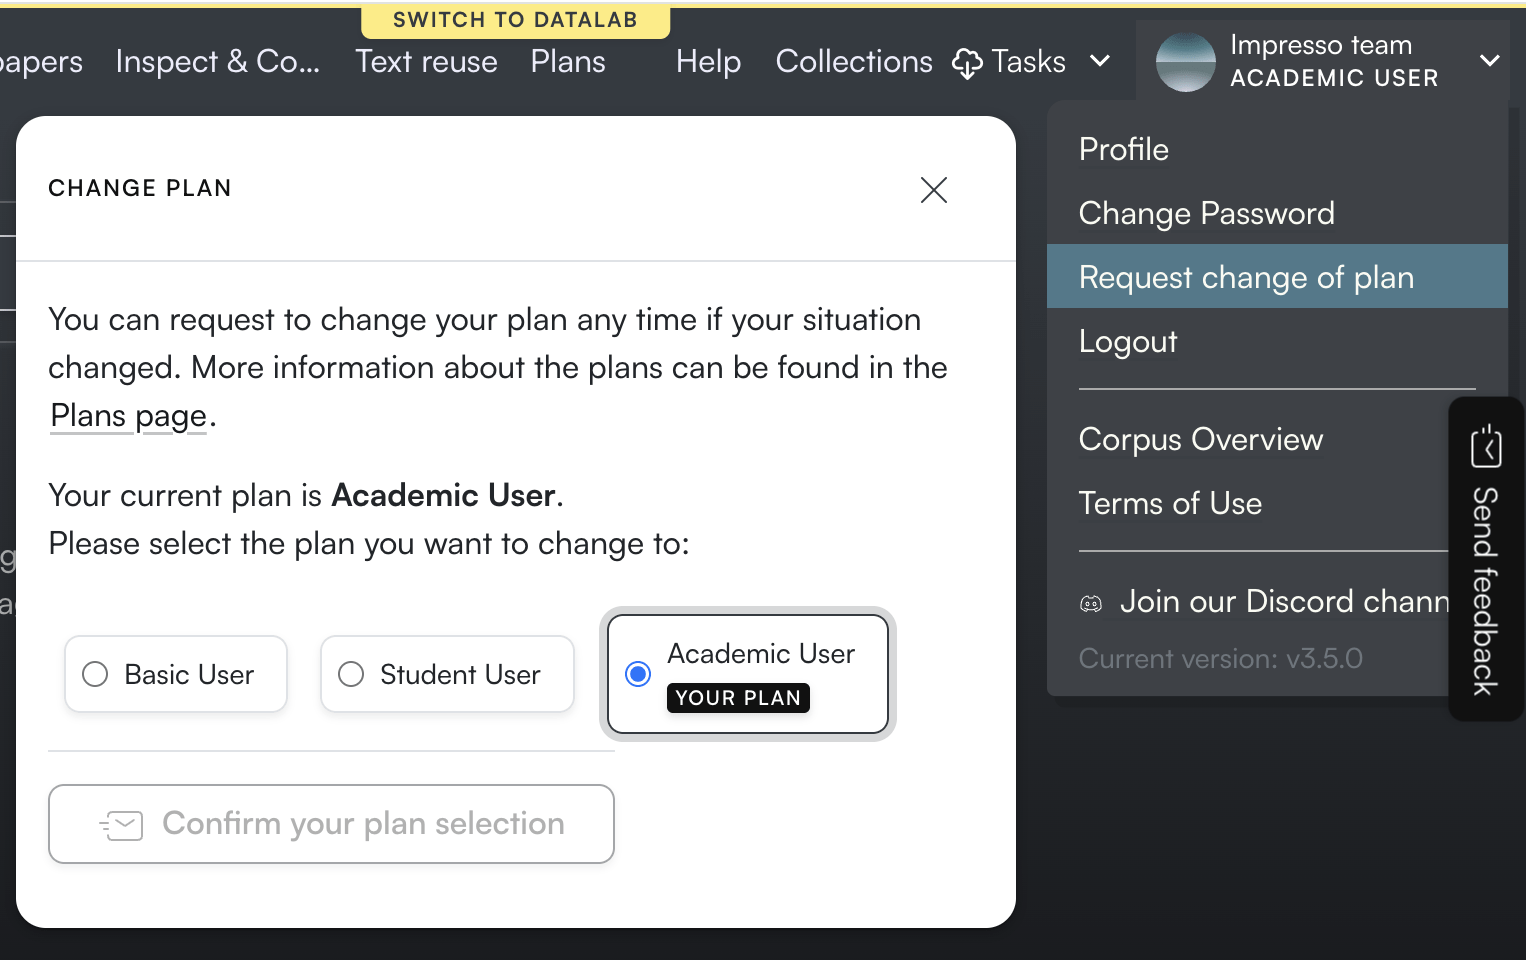
Impresso user plans
Challenge 1
The design
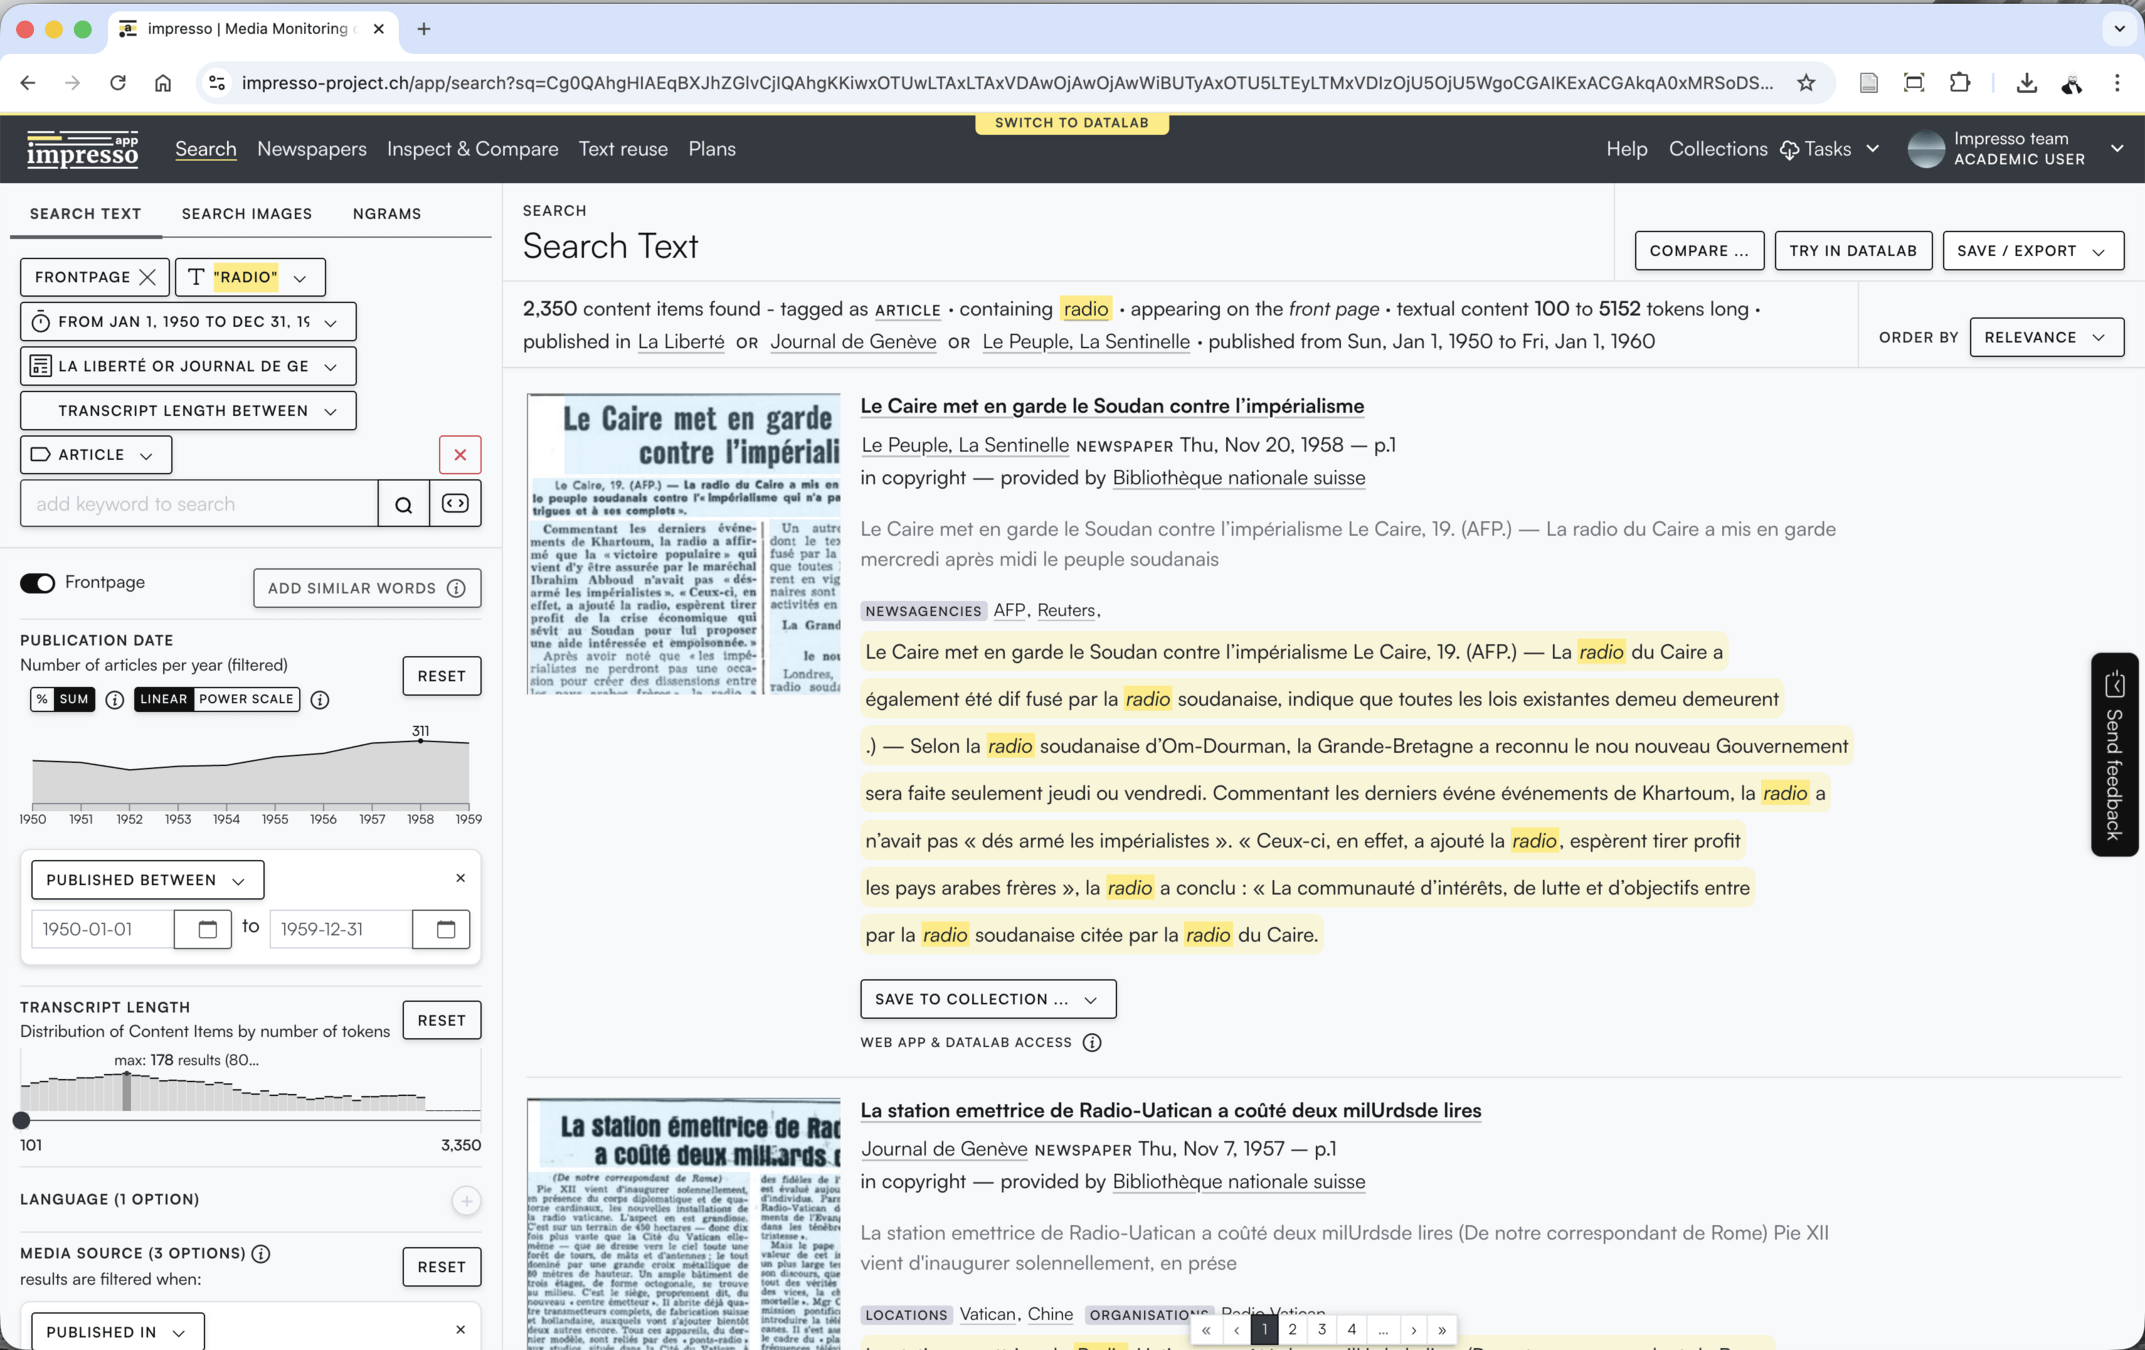
As many features as possible, but with the smoothest possible user experience
Creating an app that provides access to tens of millions of newspaper articles and radio broadcasts is one thing.
Making sure it’s usable by both the general public and advanced researchers is another.
Impresso web app
Challenge 1
The design
Multiple filters
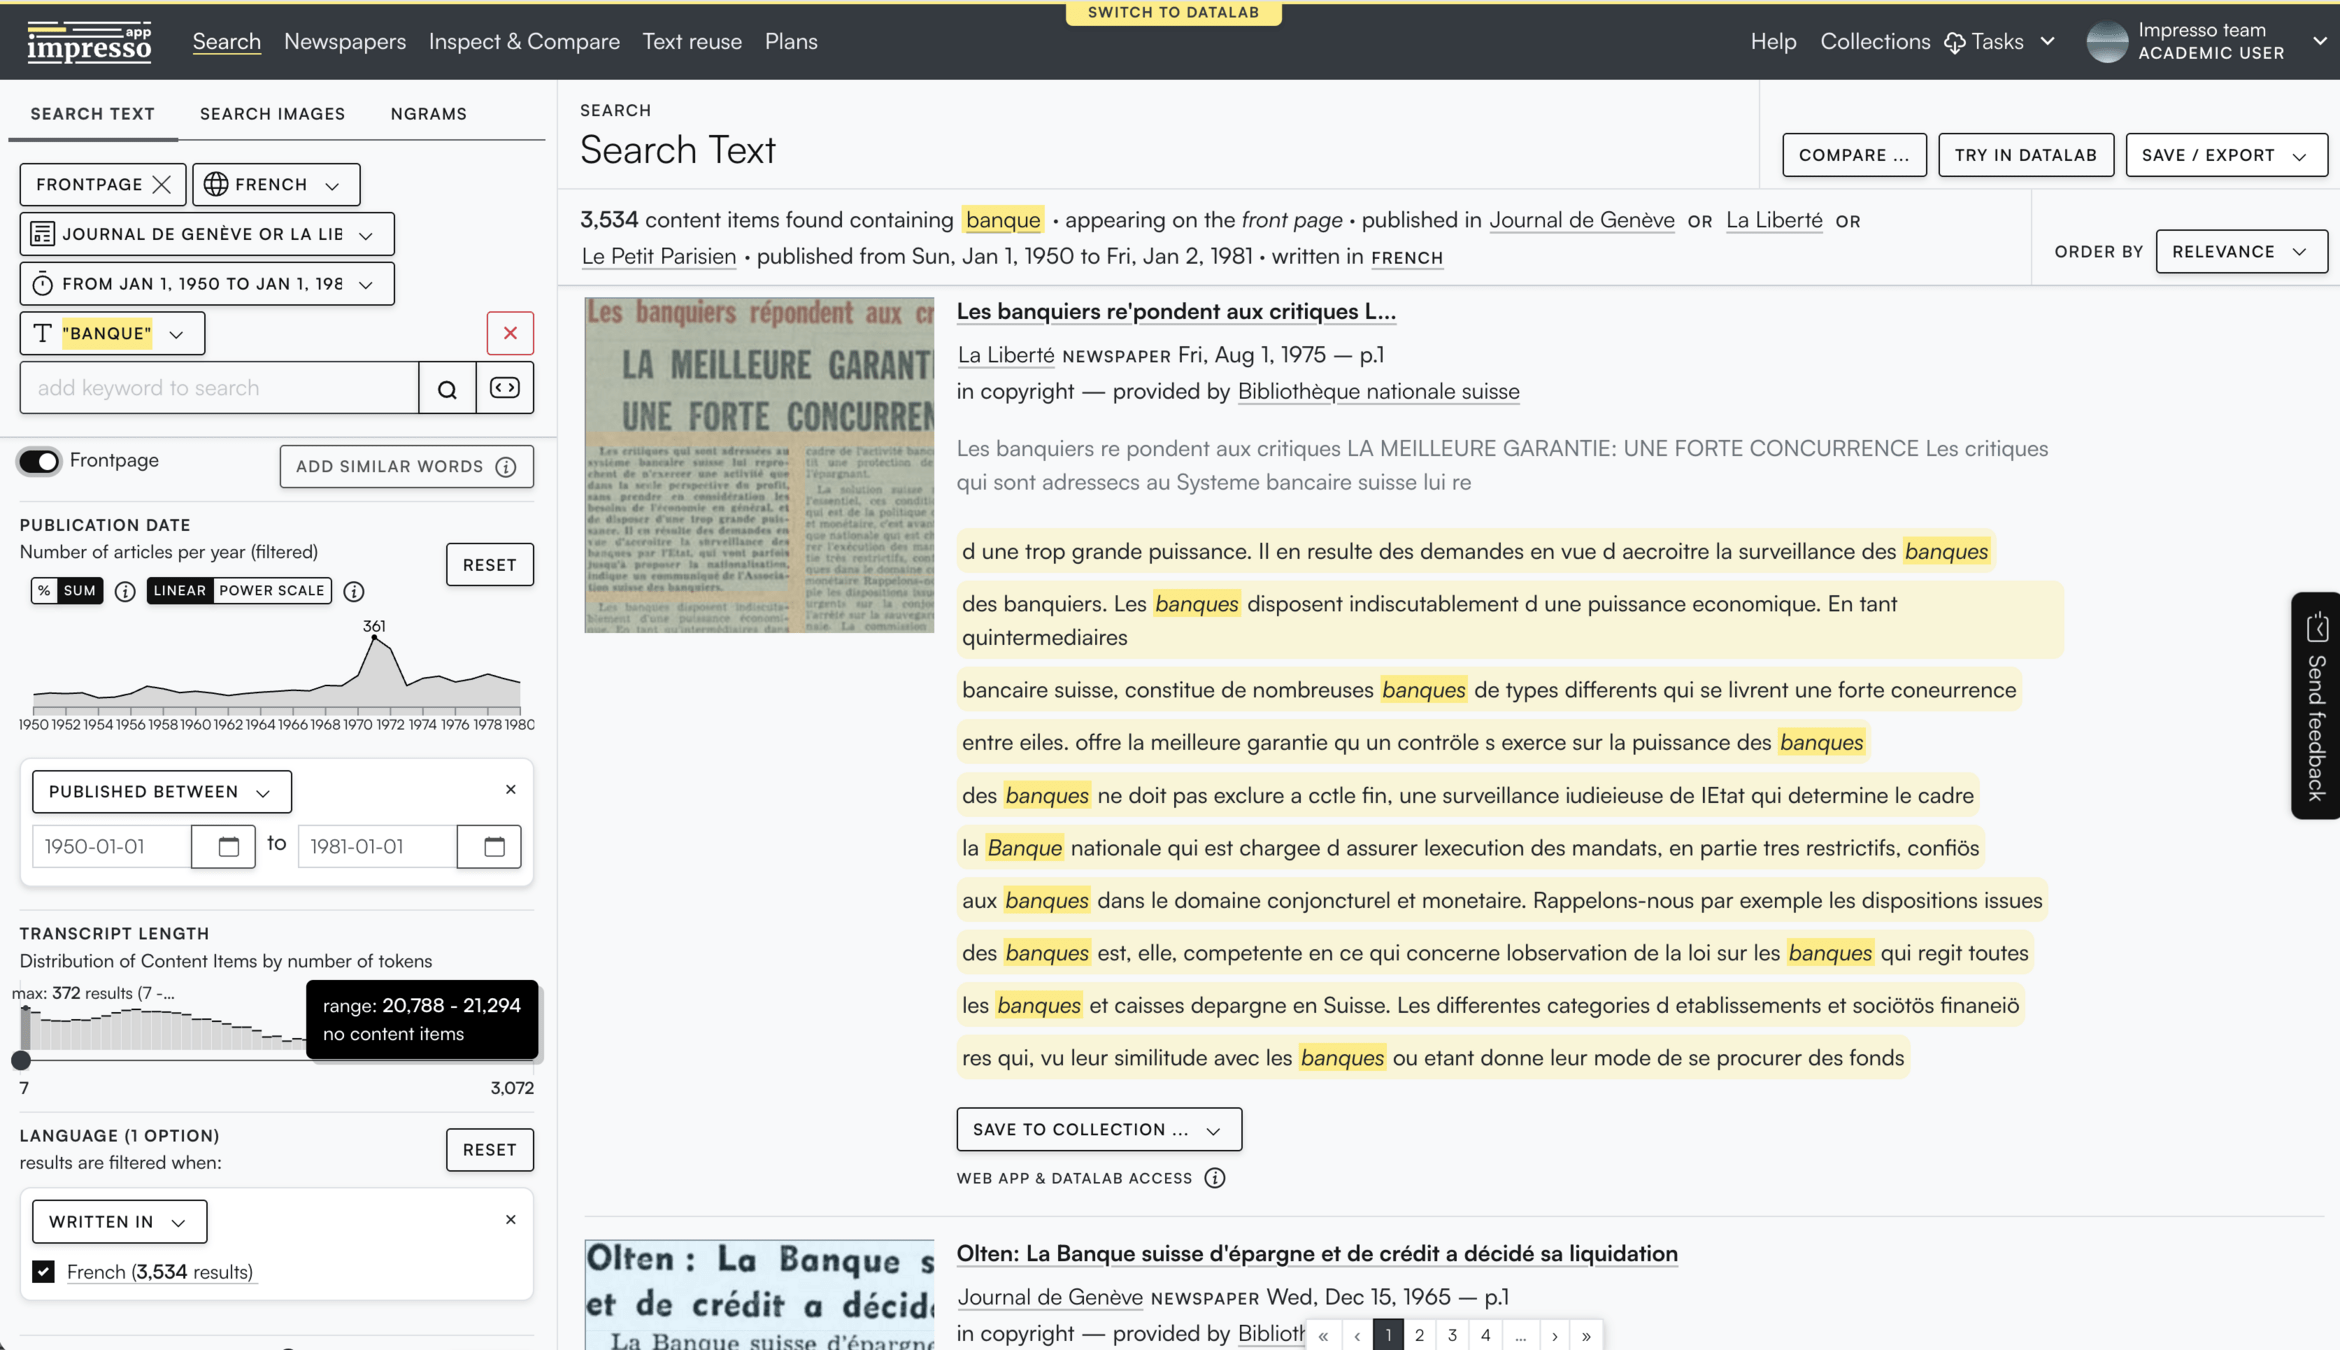
date range
language
keywords
source
length
article type
and many more...
Challenge 1
The design
Advanced features
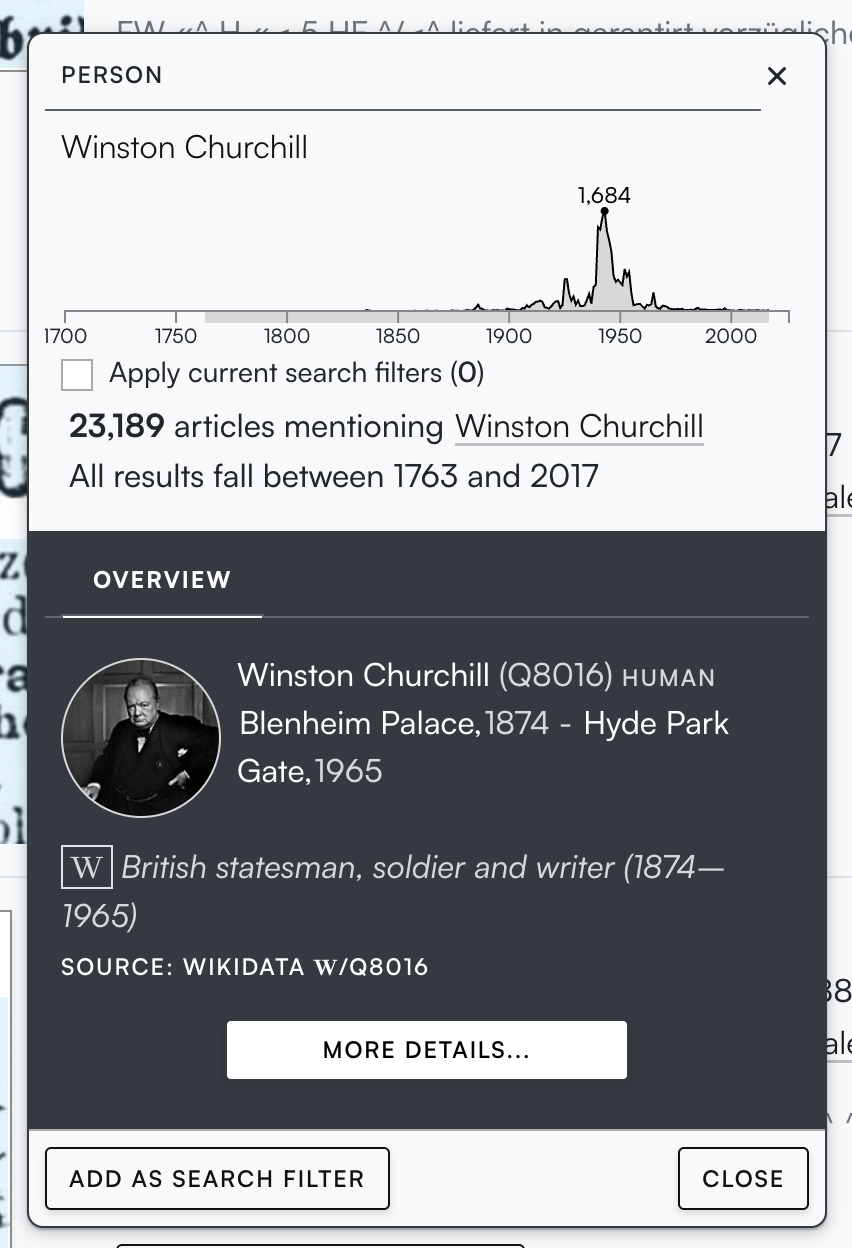
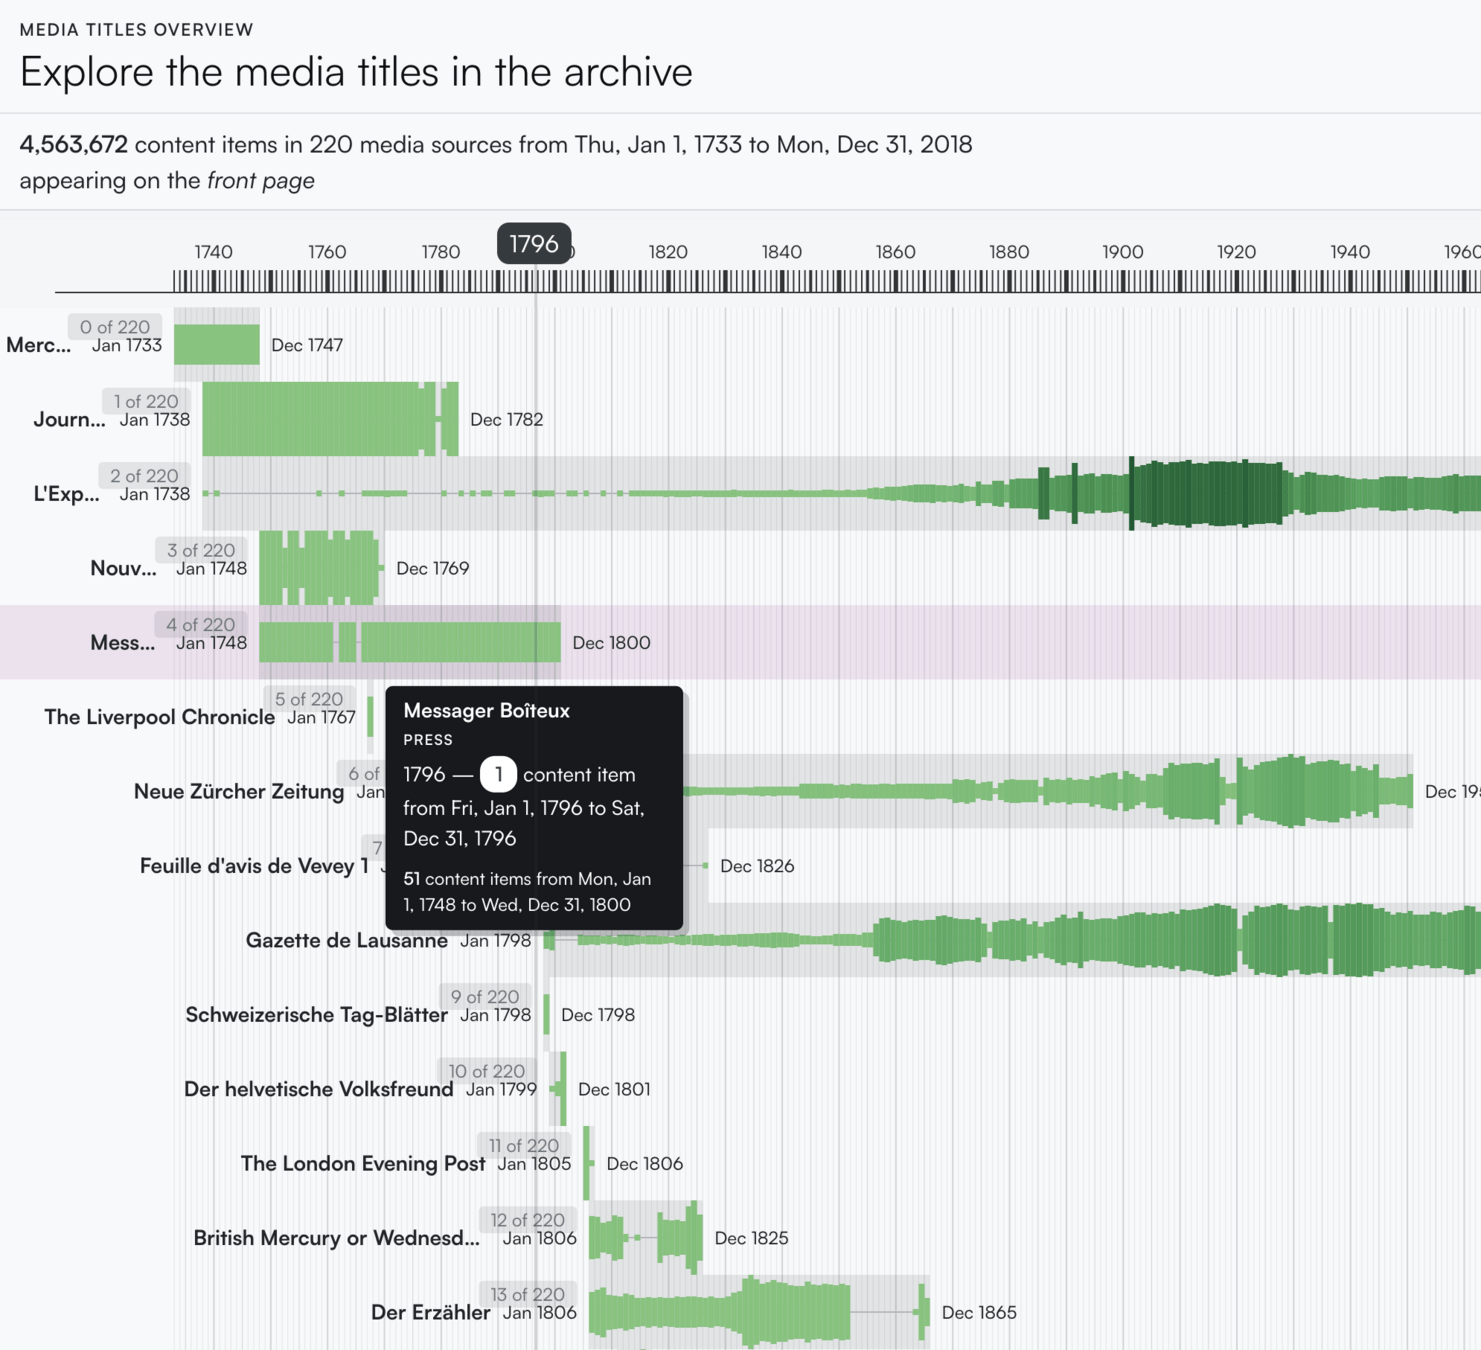
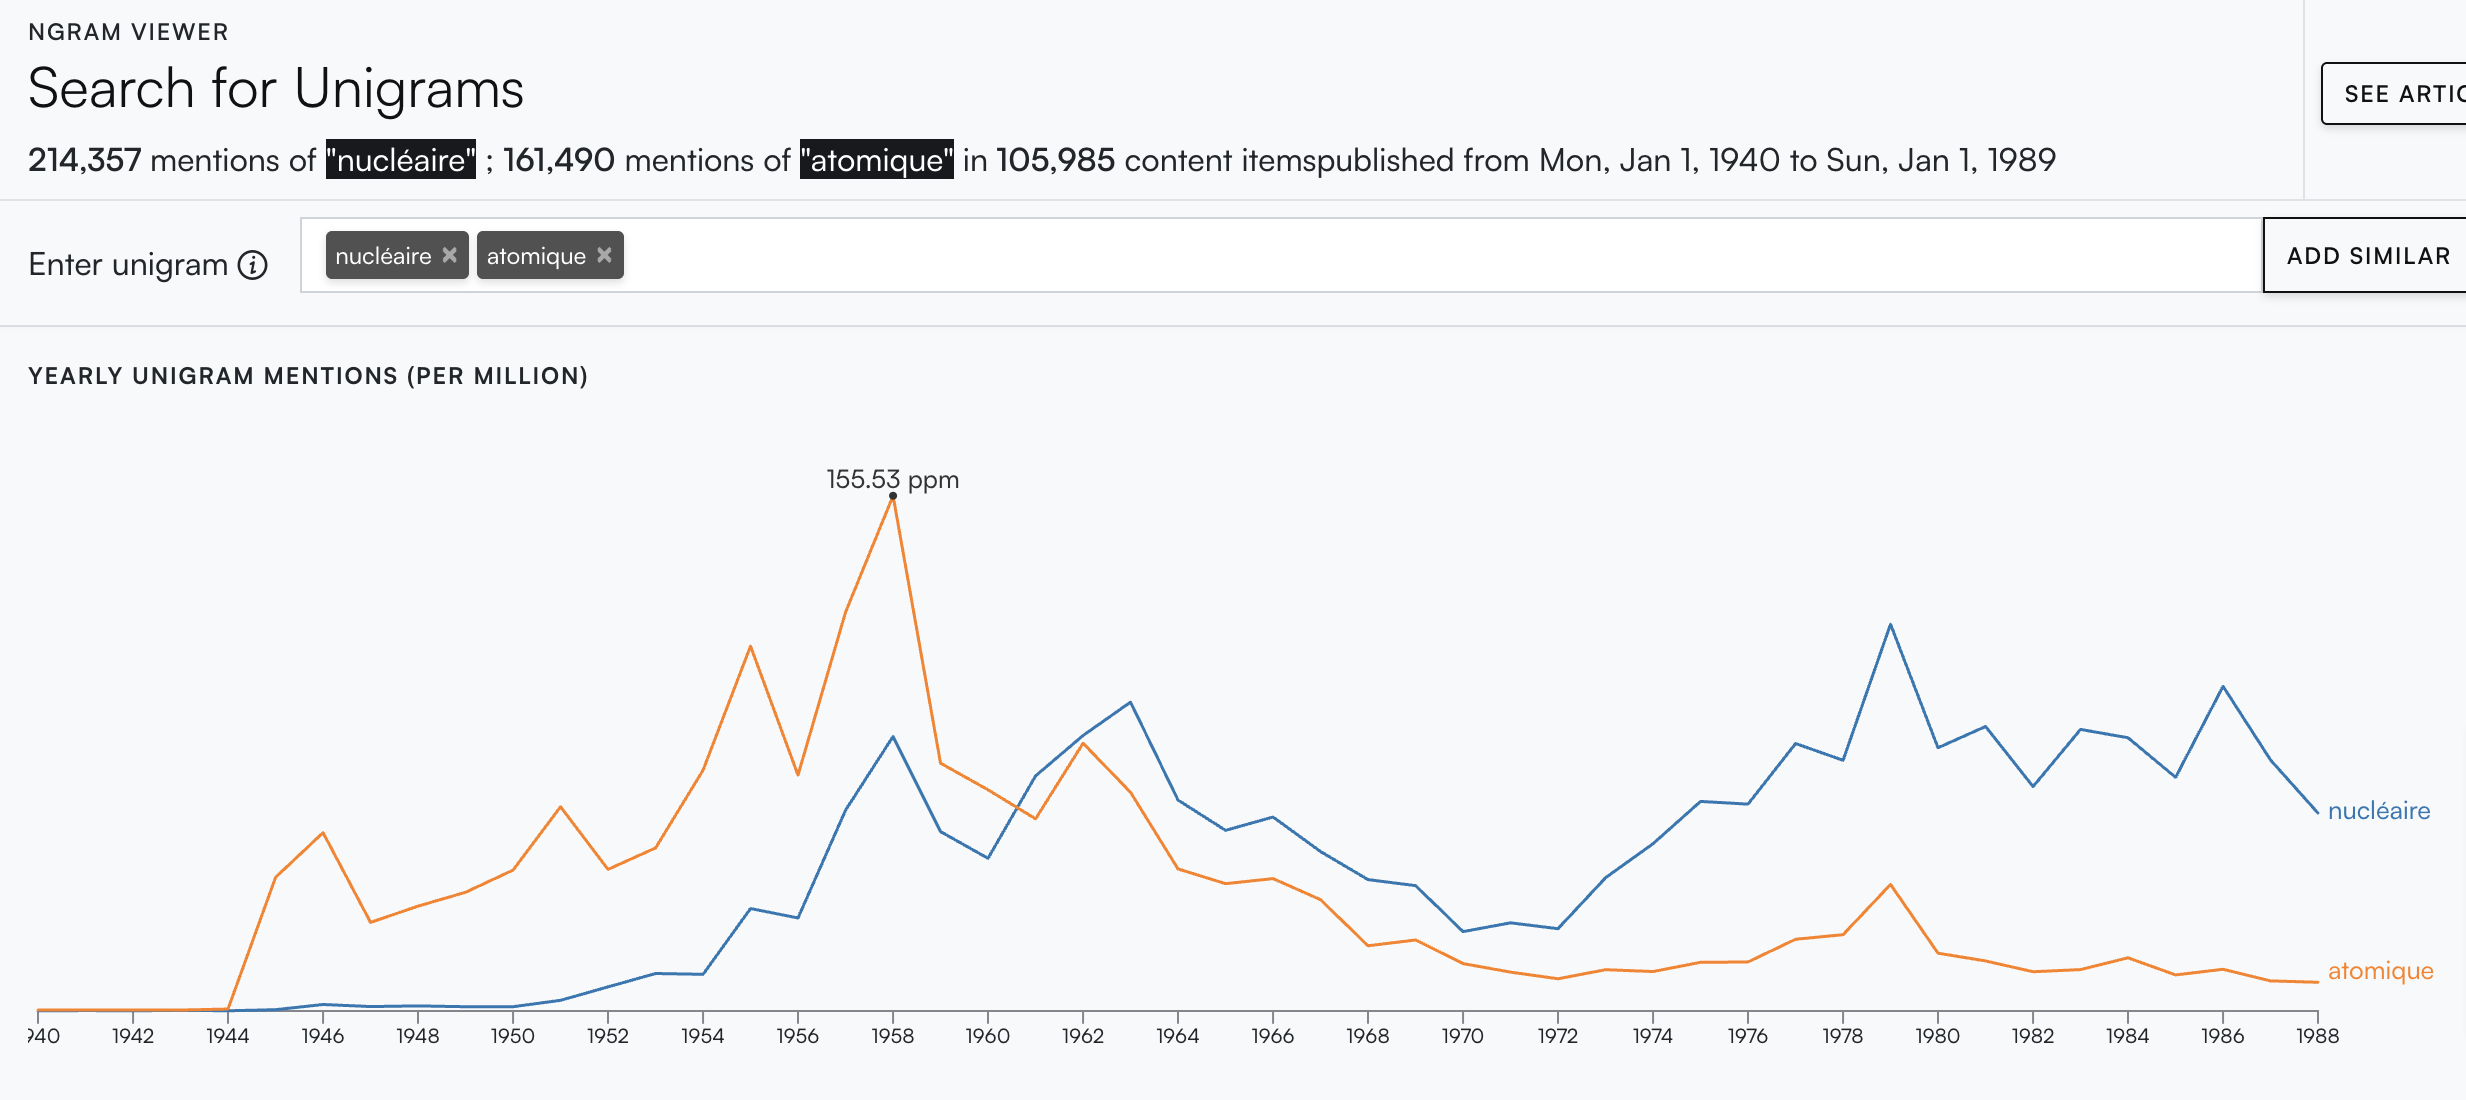
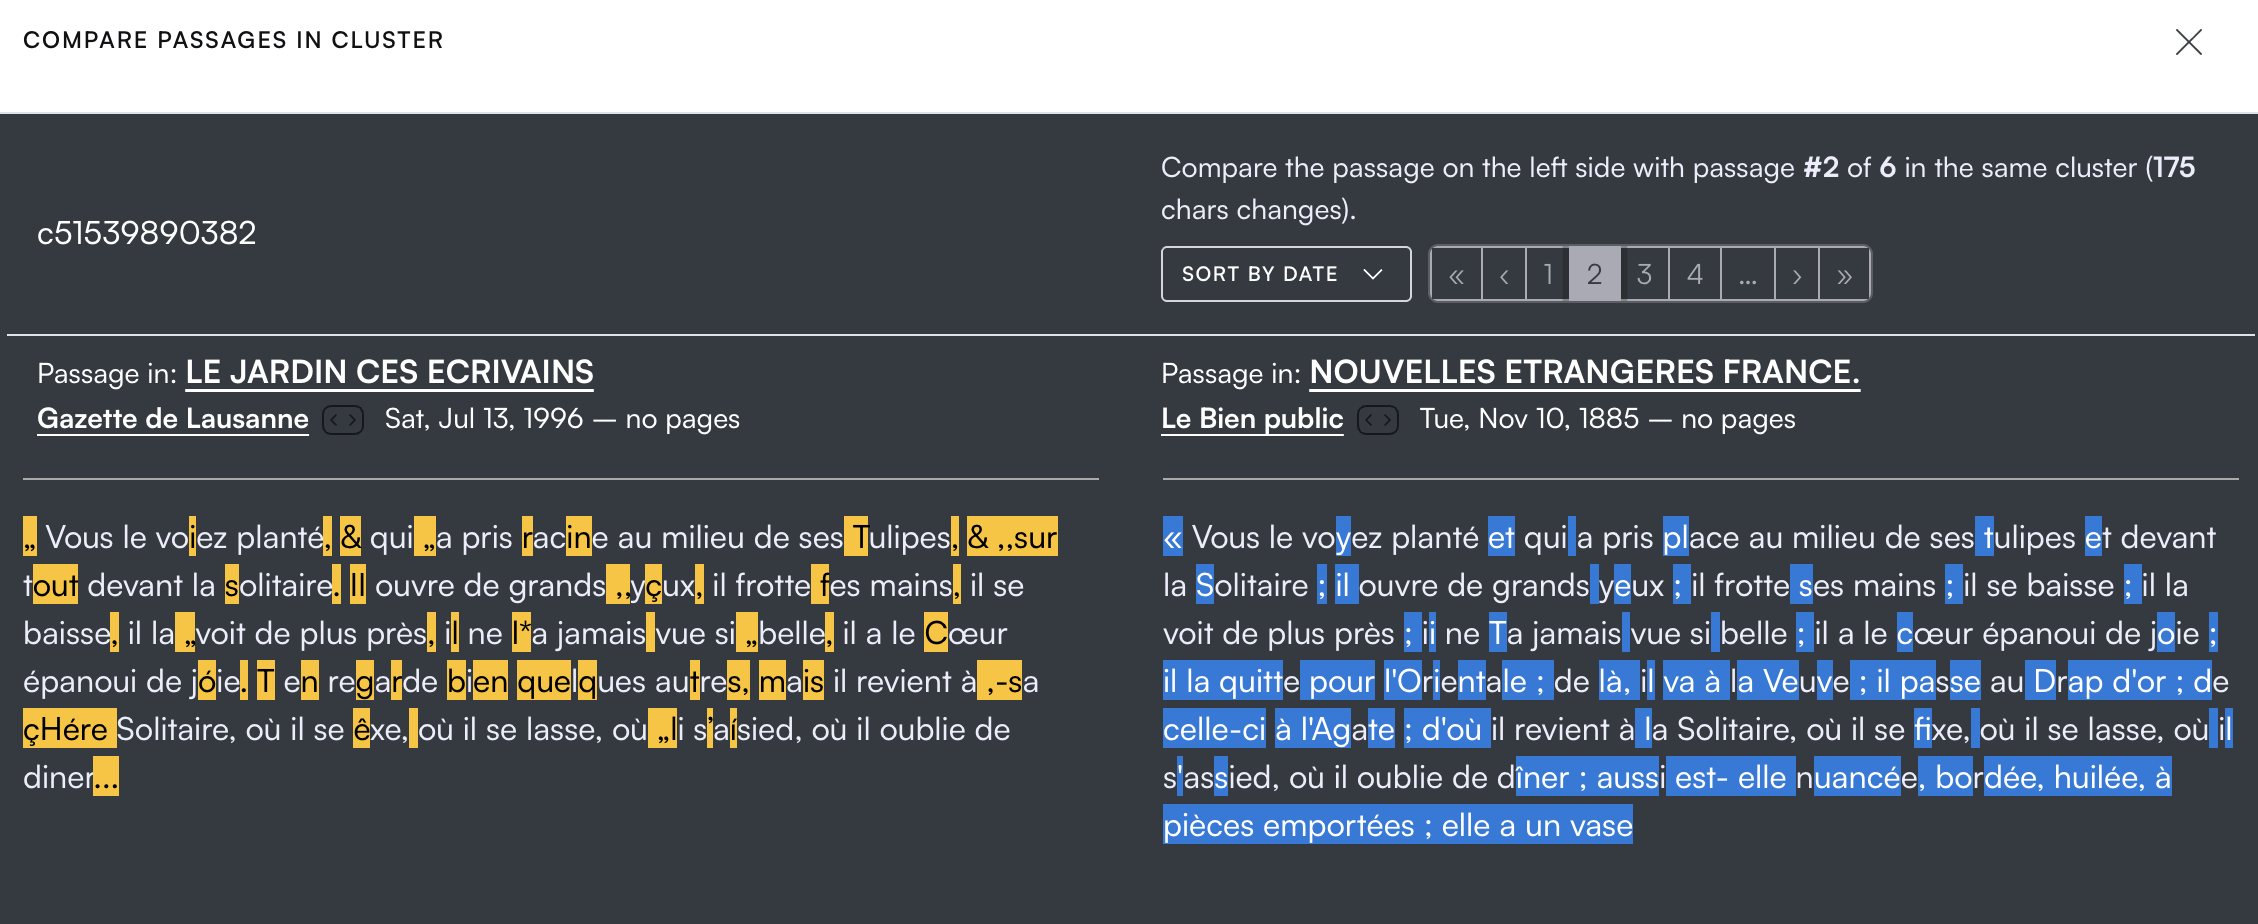
Named entities profiles
Corpus overview
Ngrams
Text reuse
Challenge 1
The design
Browse newspapers and radio broadcasts at the same time
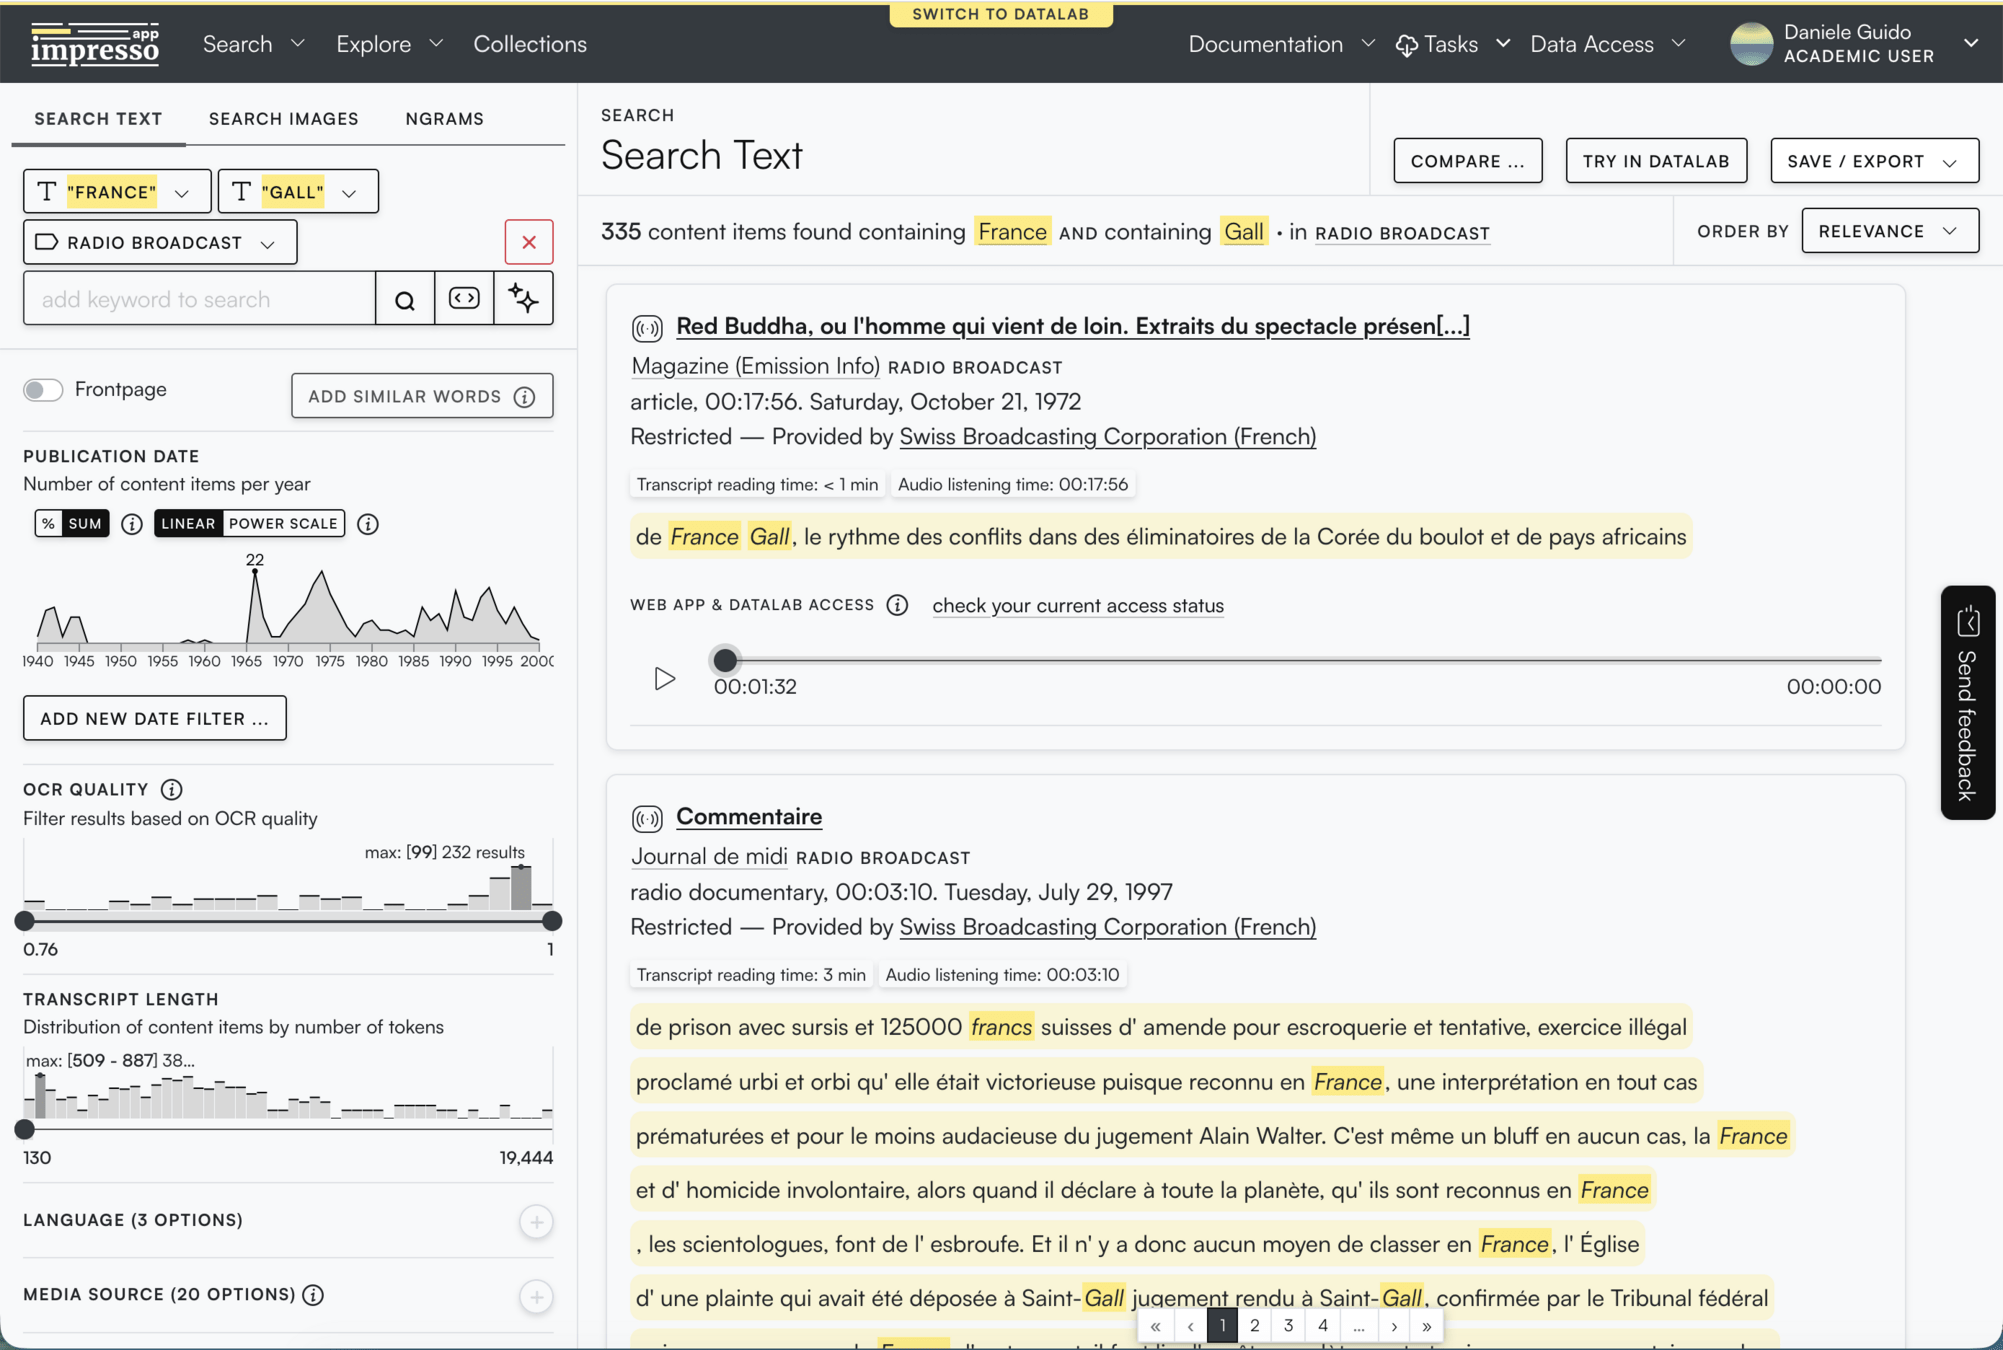
Example of future integration of audio files into the Impresso app
Perspectives
Impresso app
Currently under development
Making data analysis accessible to everyone
A “datalab” to provide access to collections and more advanced tools
Challenge 2
Using these collections independently
The Impresso datalab
The Impresso datalab, a suite of analysis tools that leverage the API and enriched data from the press and radio
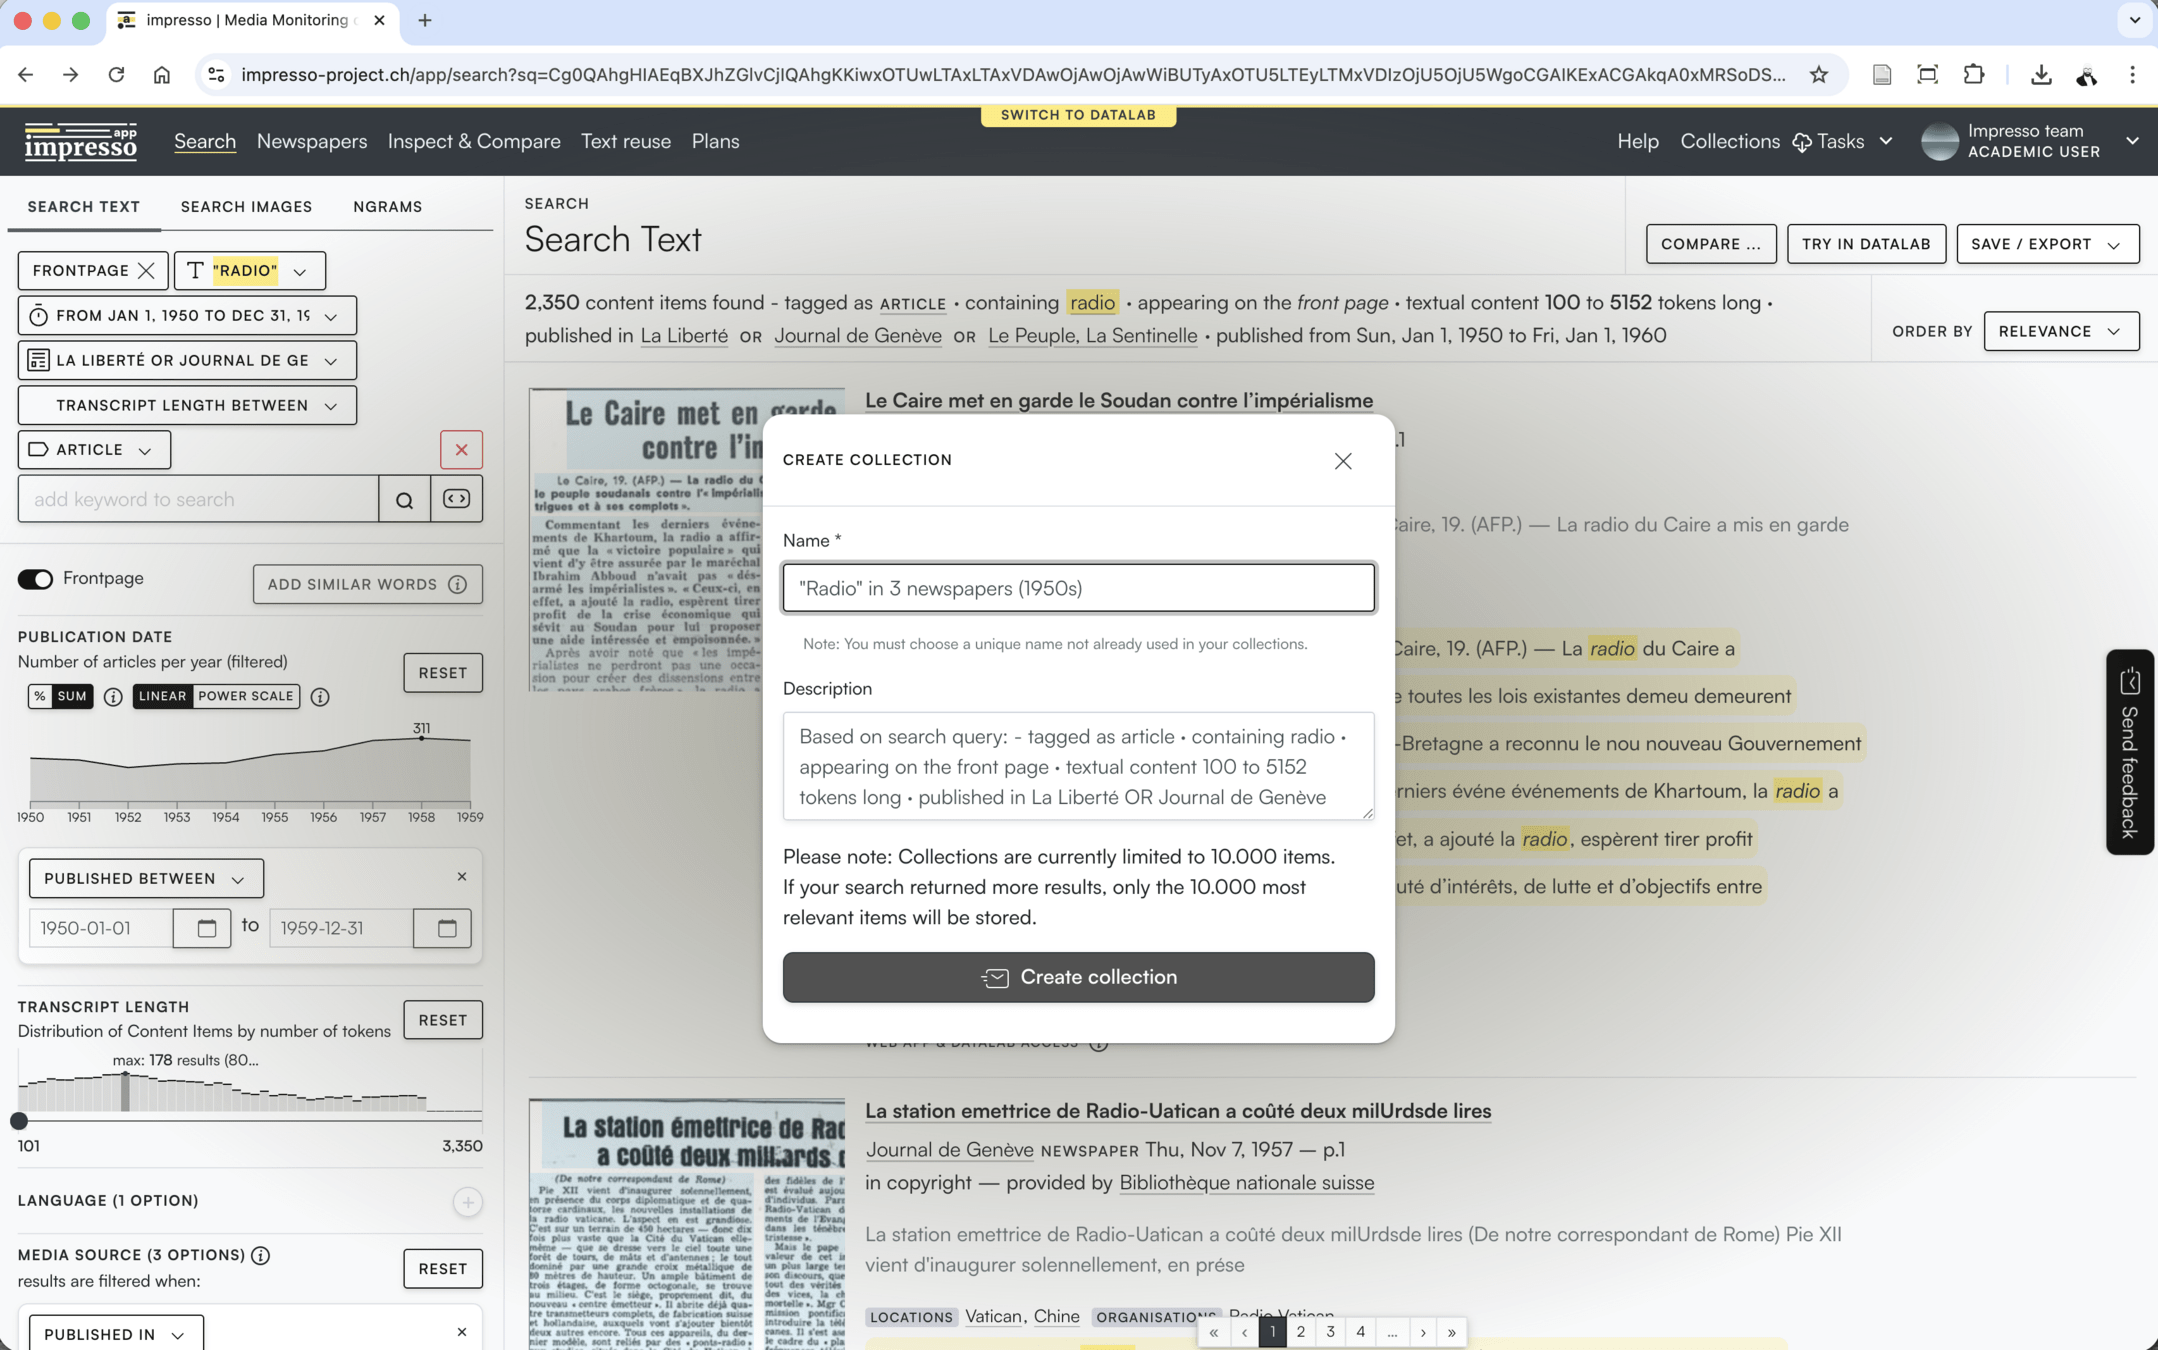
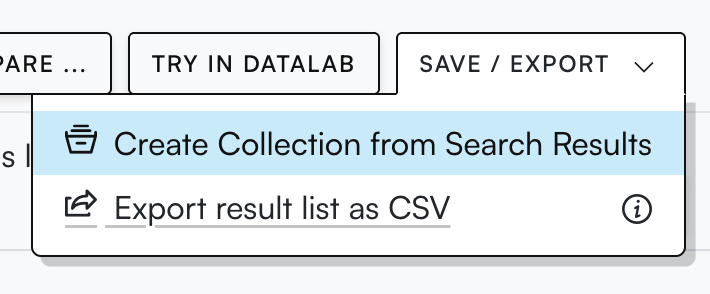
To preserve a corpus, it can be saved as a collection.
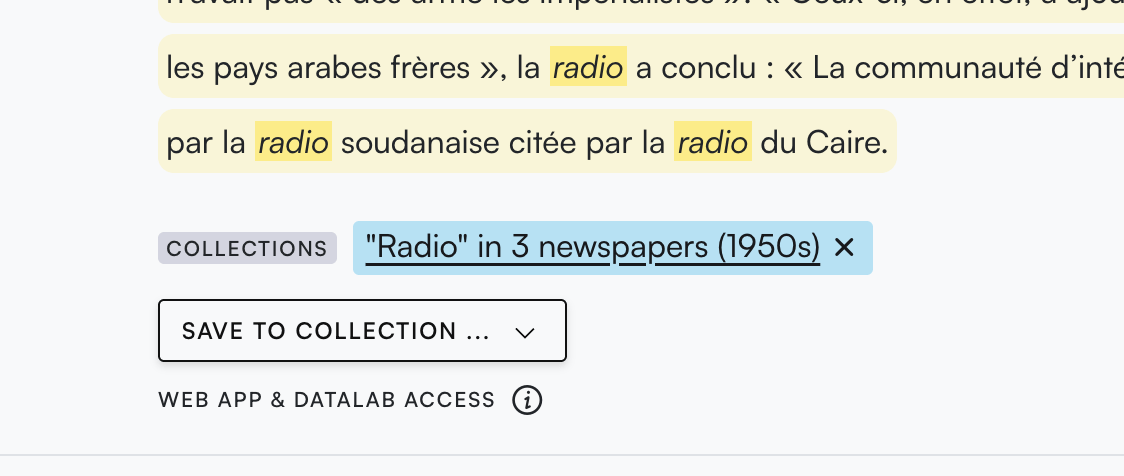
All articles are now tagged so they stand out in search results.
Creating personal collections
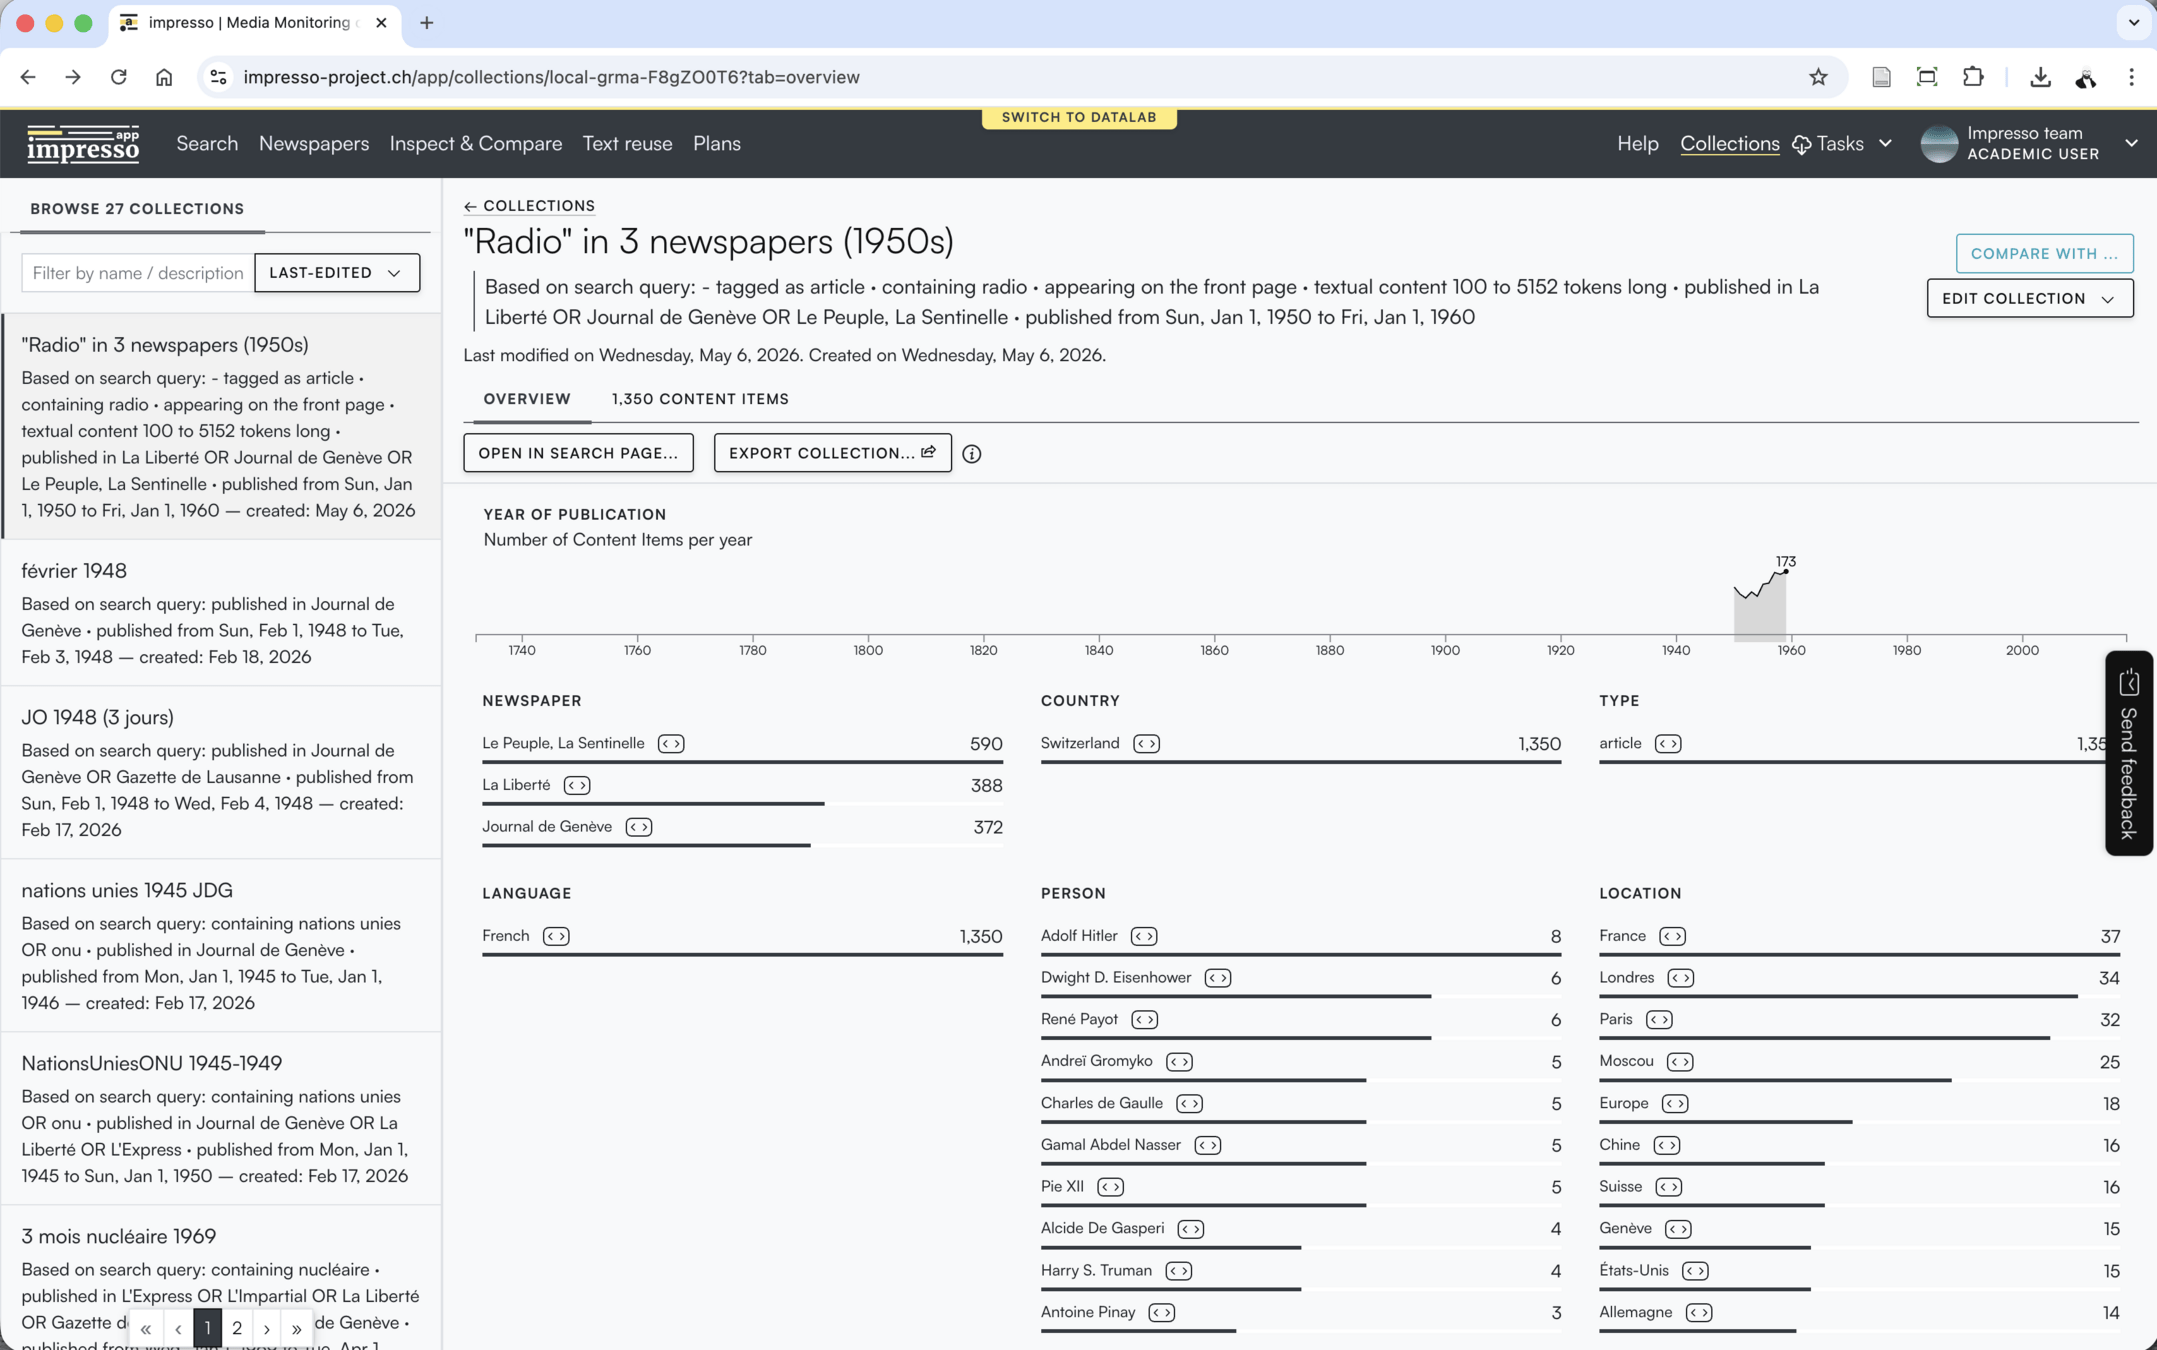
Each collection has its own page, complete with some descriptive statistics.
Creating personal collections
A collection can be exported as a CSV file.
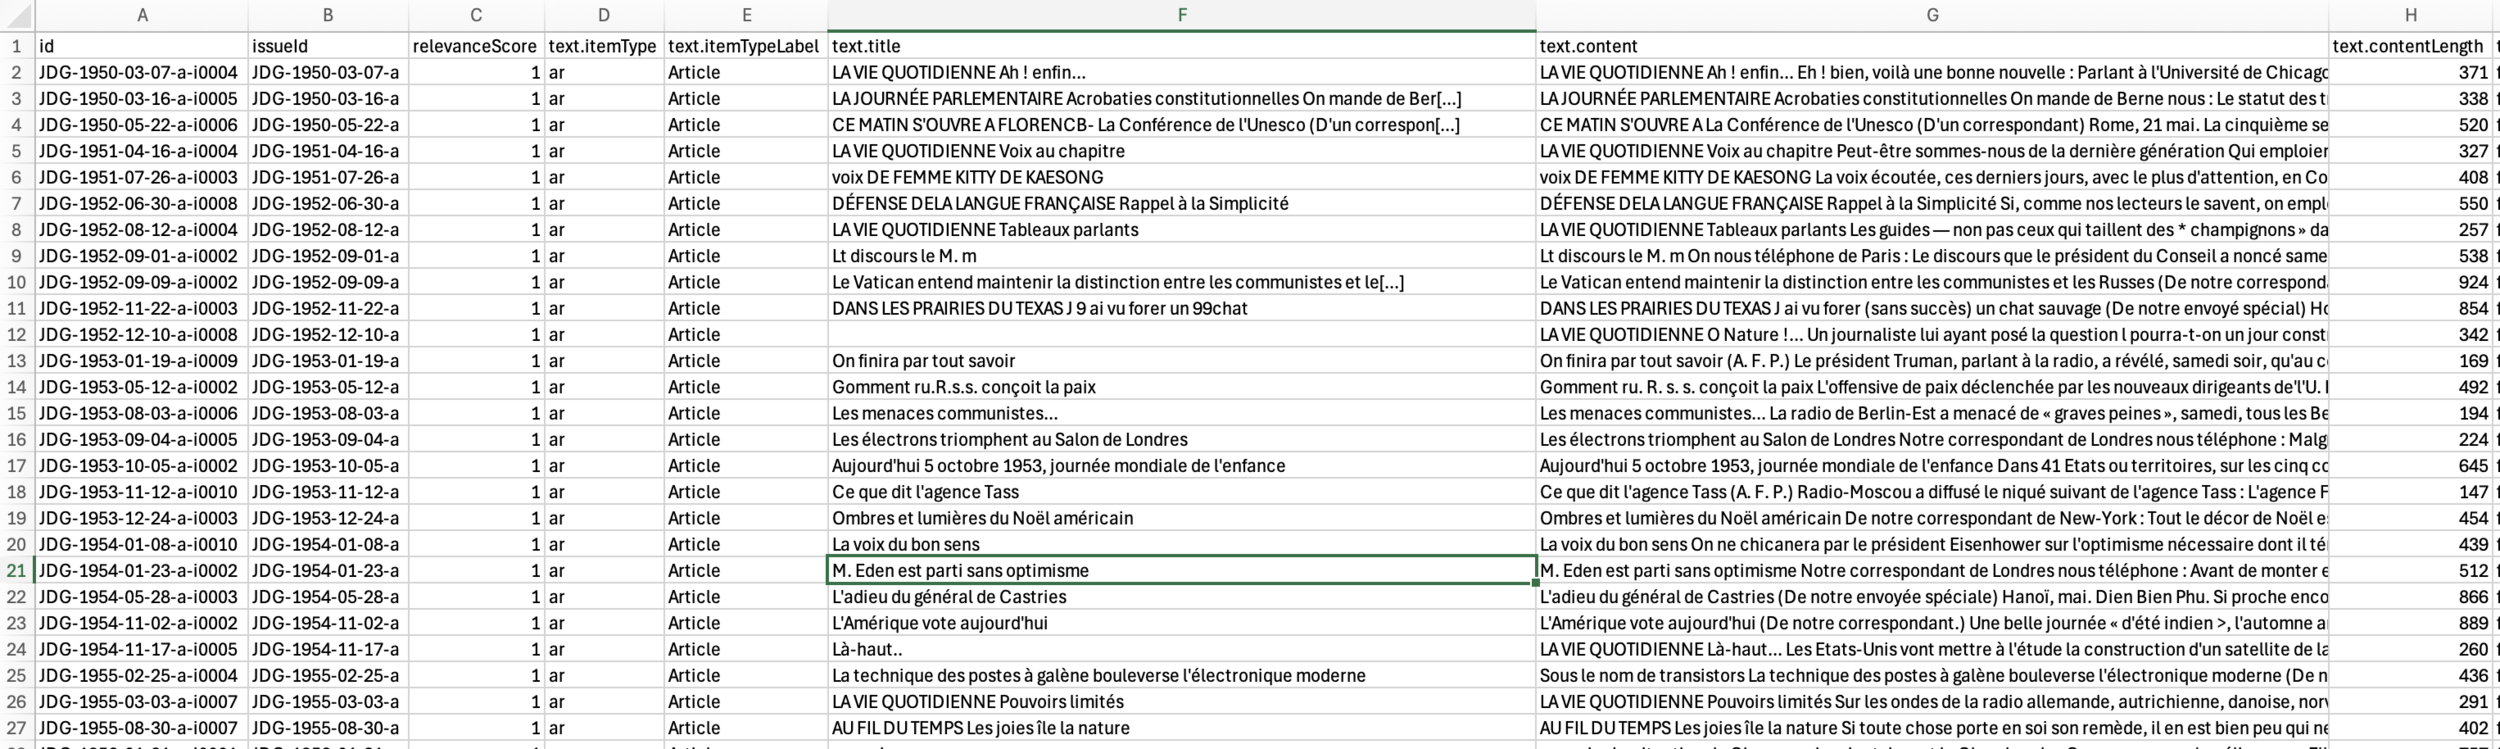
Once exported, the CSV file can be downloaded and opened in a spreadsheet program.
It includes all the data that your plan grants you access to.
Creating personal collections
The Impresso datalab
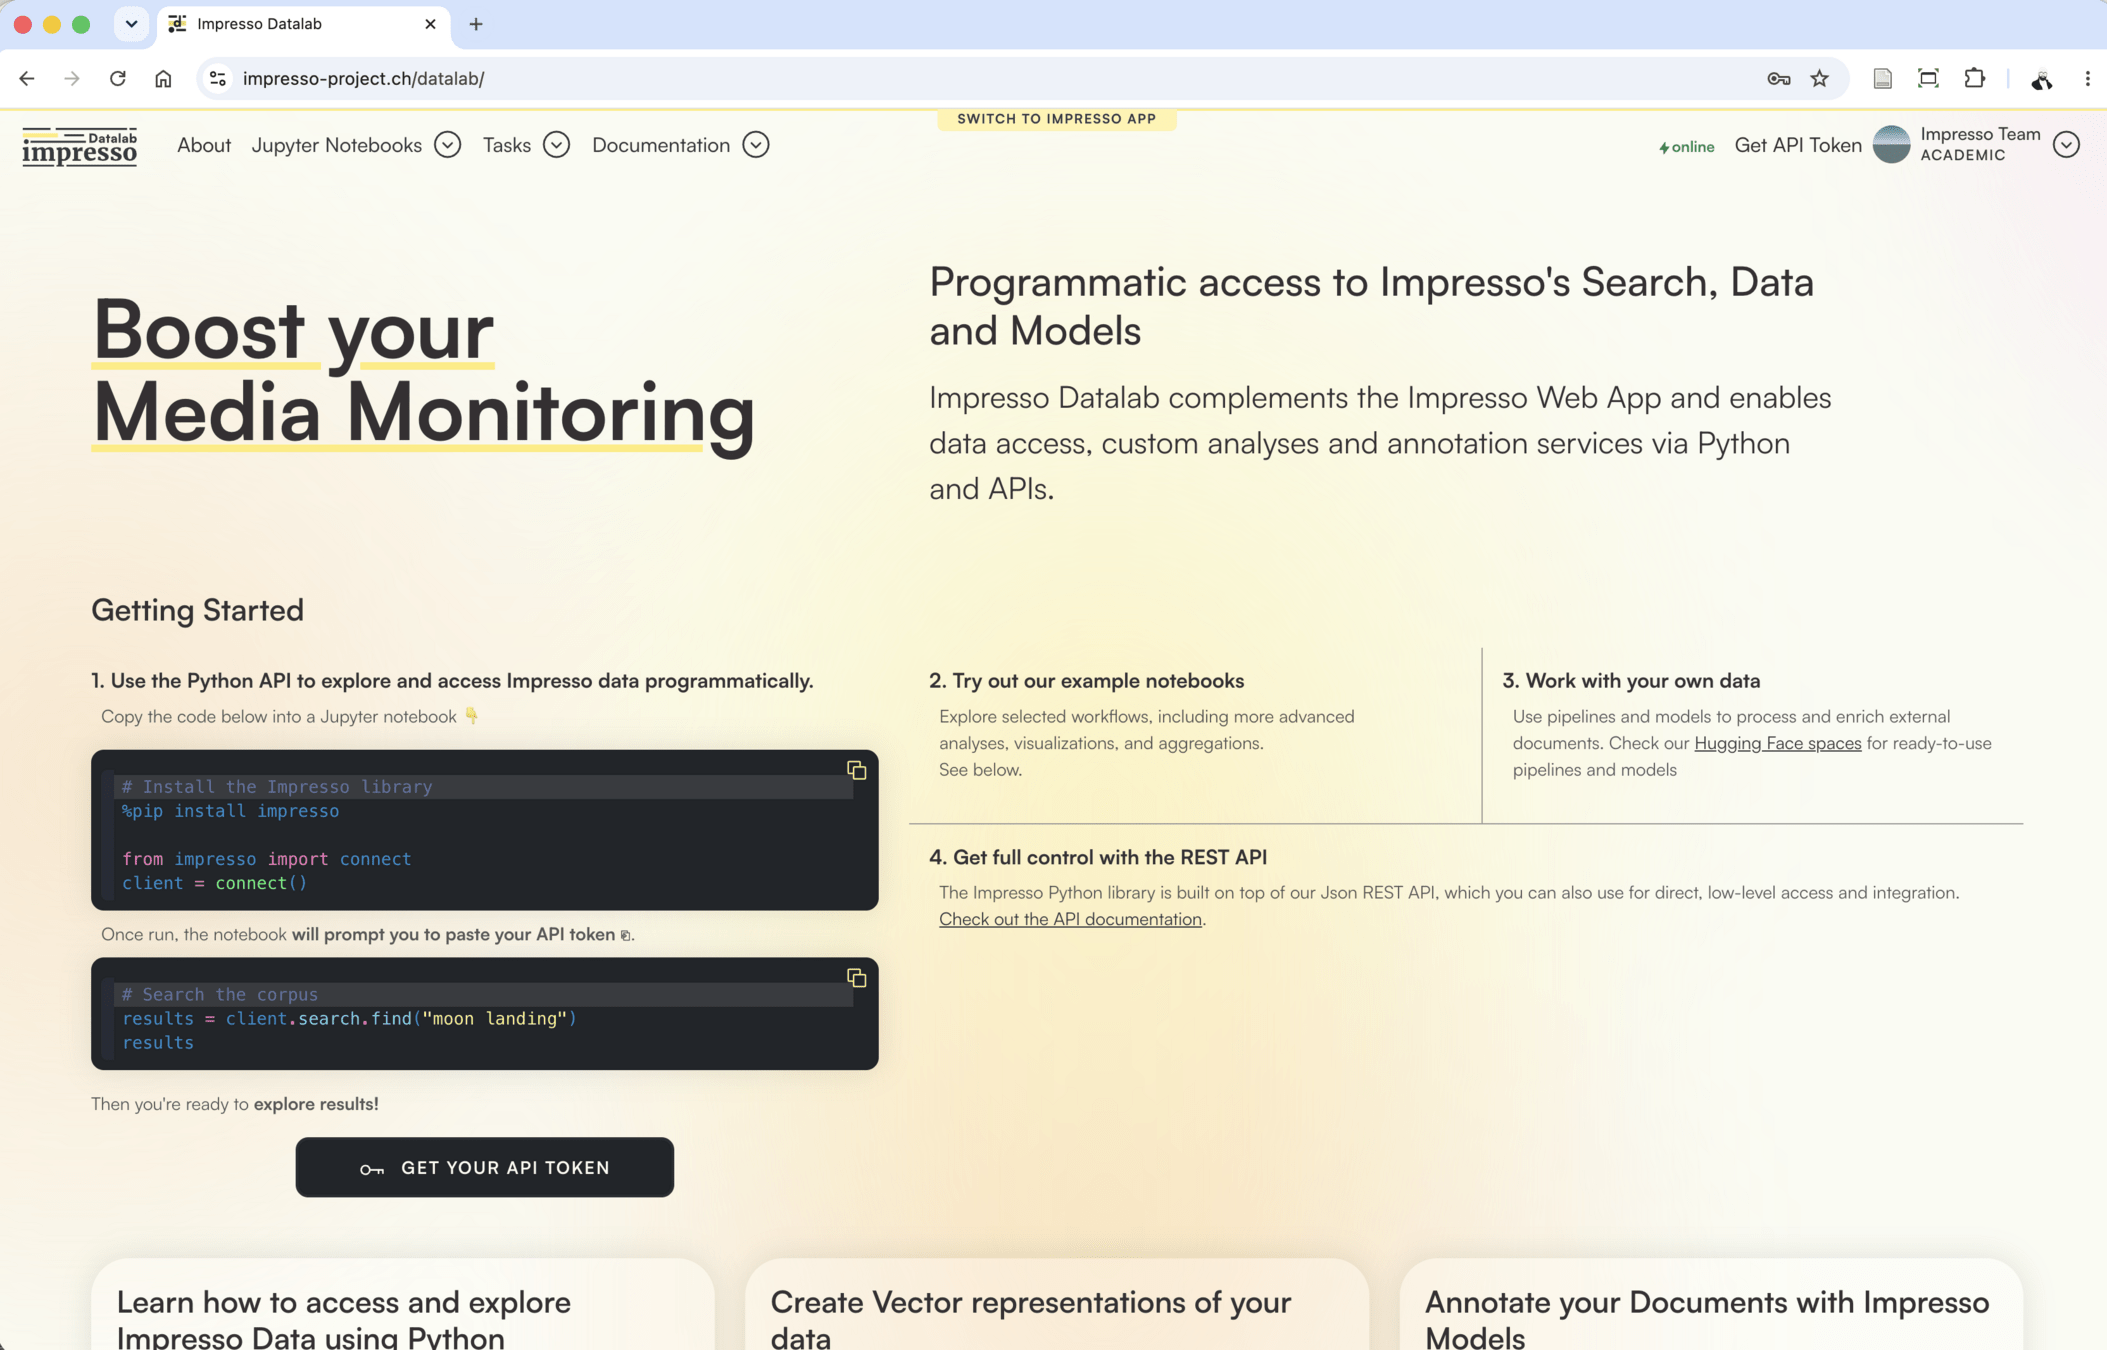
The Datalab contains instructions for programmatically accessing the Impresso API. But for the general public, it’s the notebooks that are of particular interest.
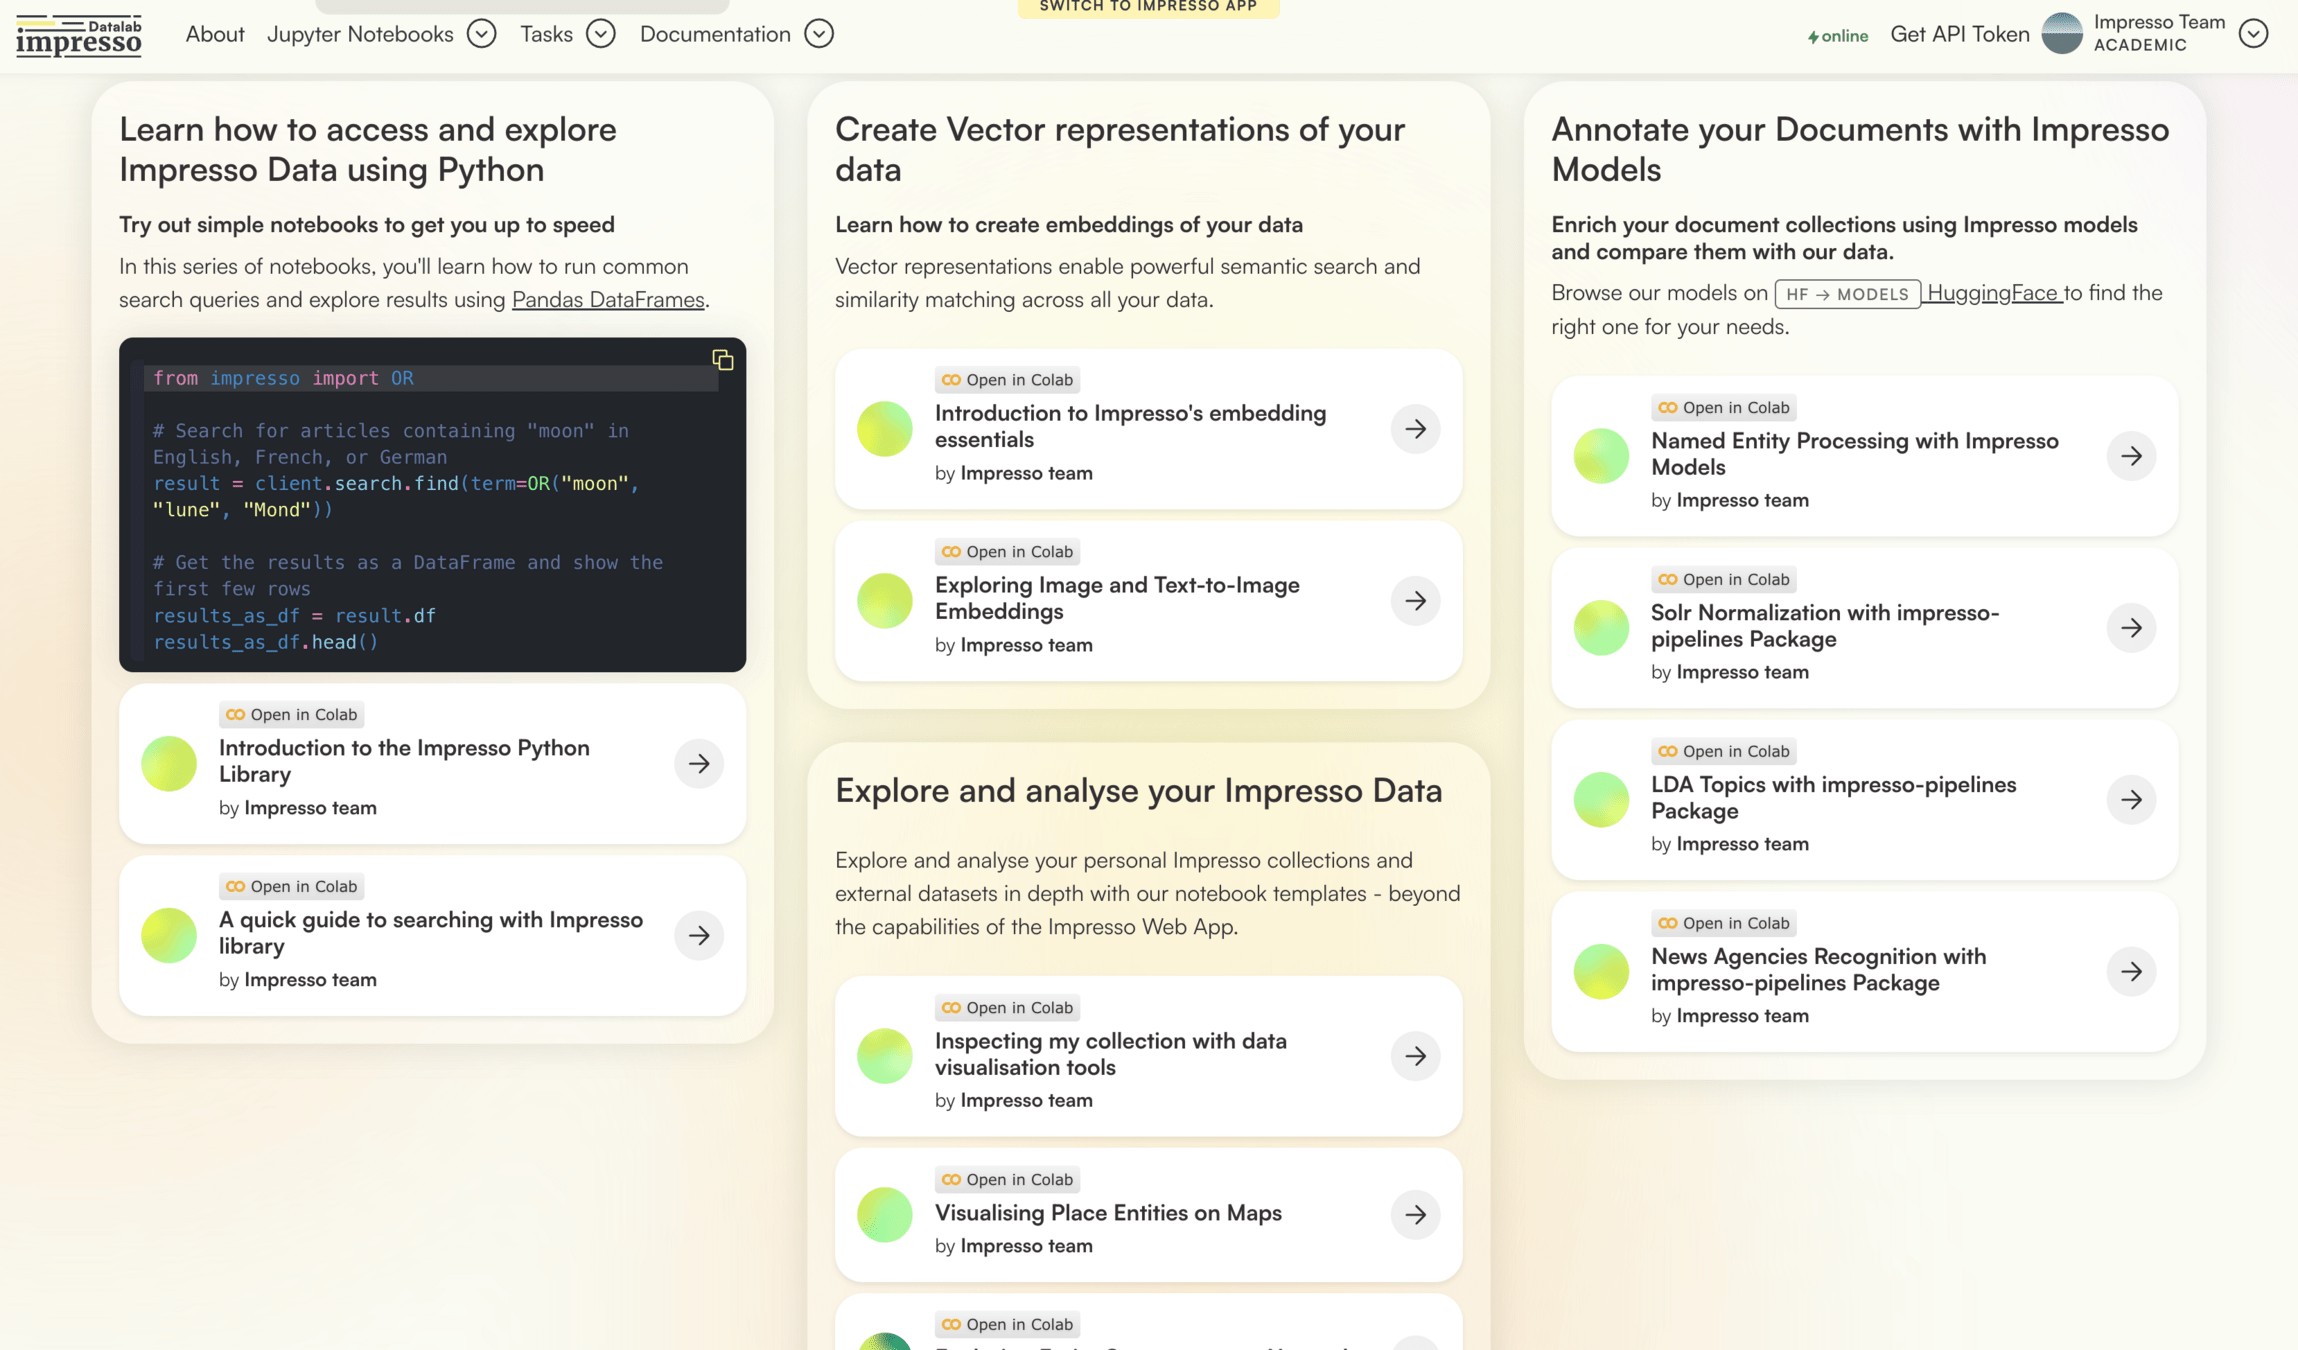
We have also developed additional notebooks that are currently pending. We also invite colleagues outside the project to develop their own notebooks, which we could add here.
Descriptive statistics for a collection
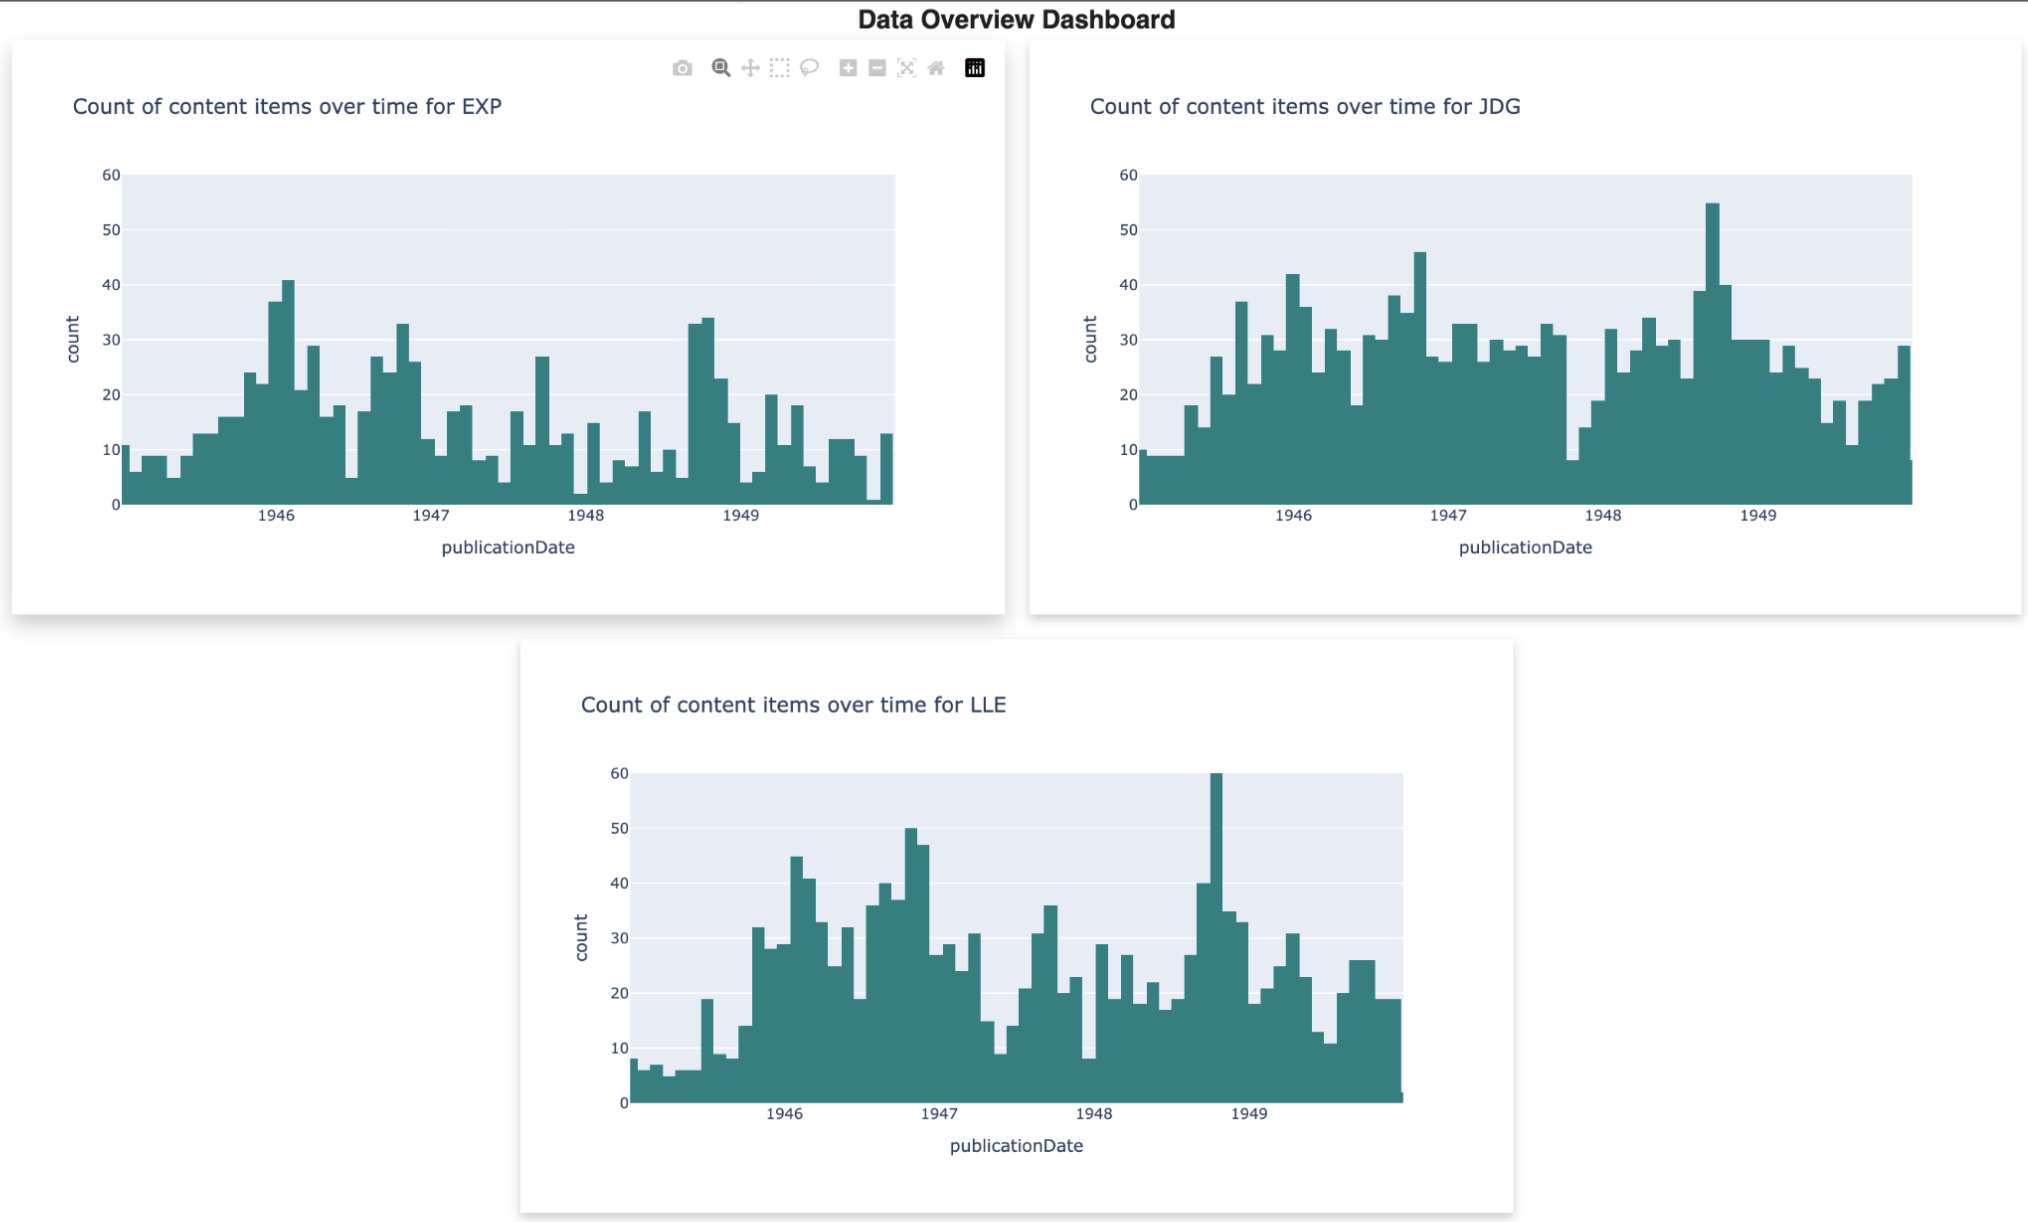
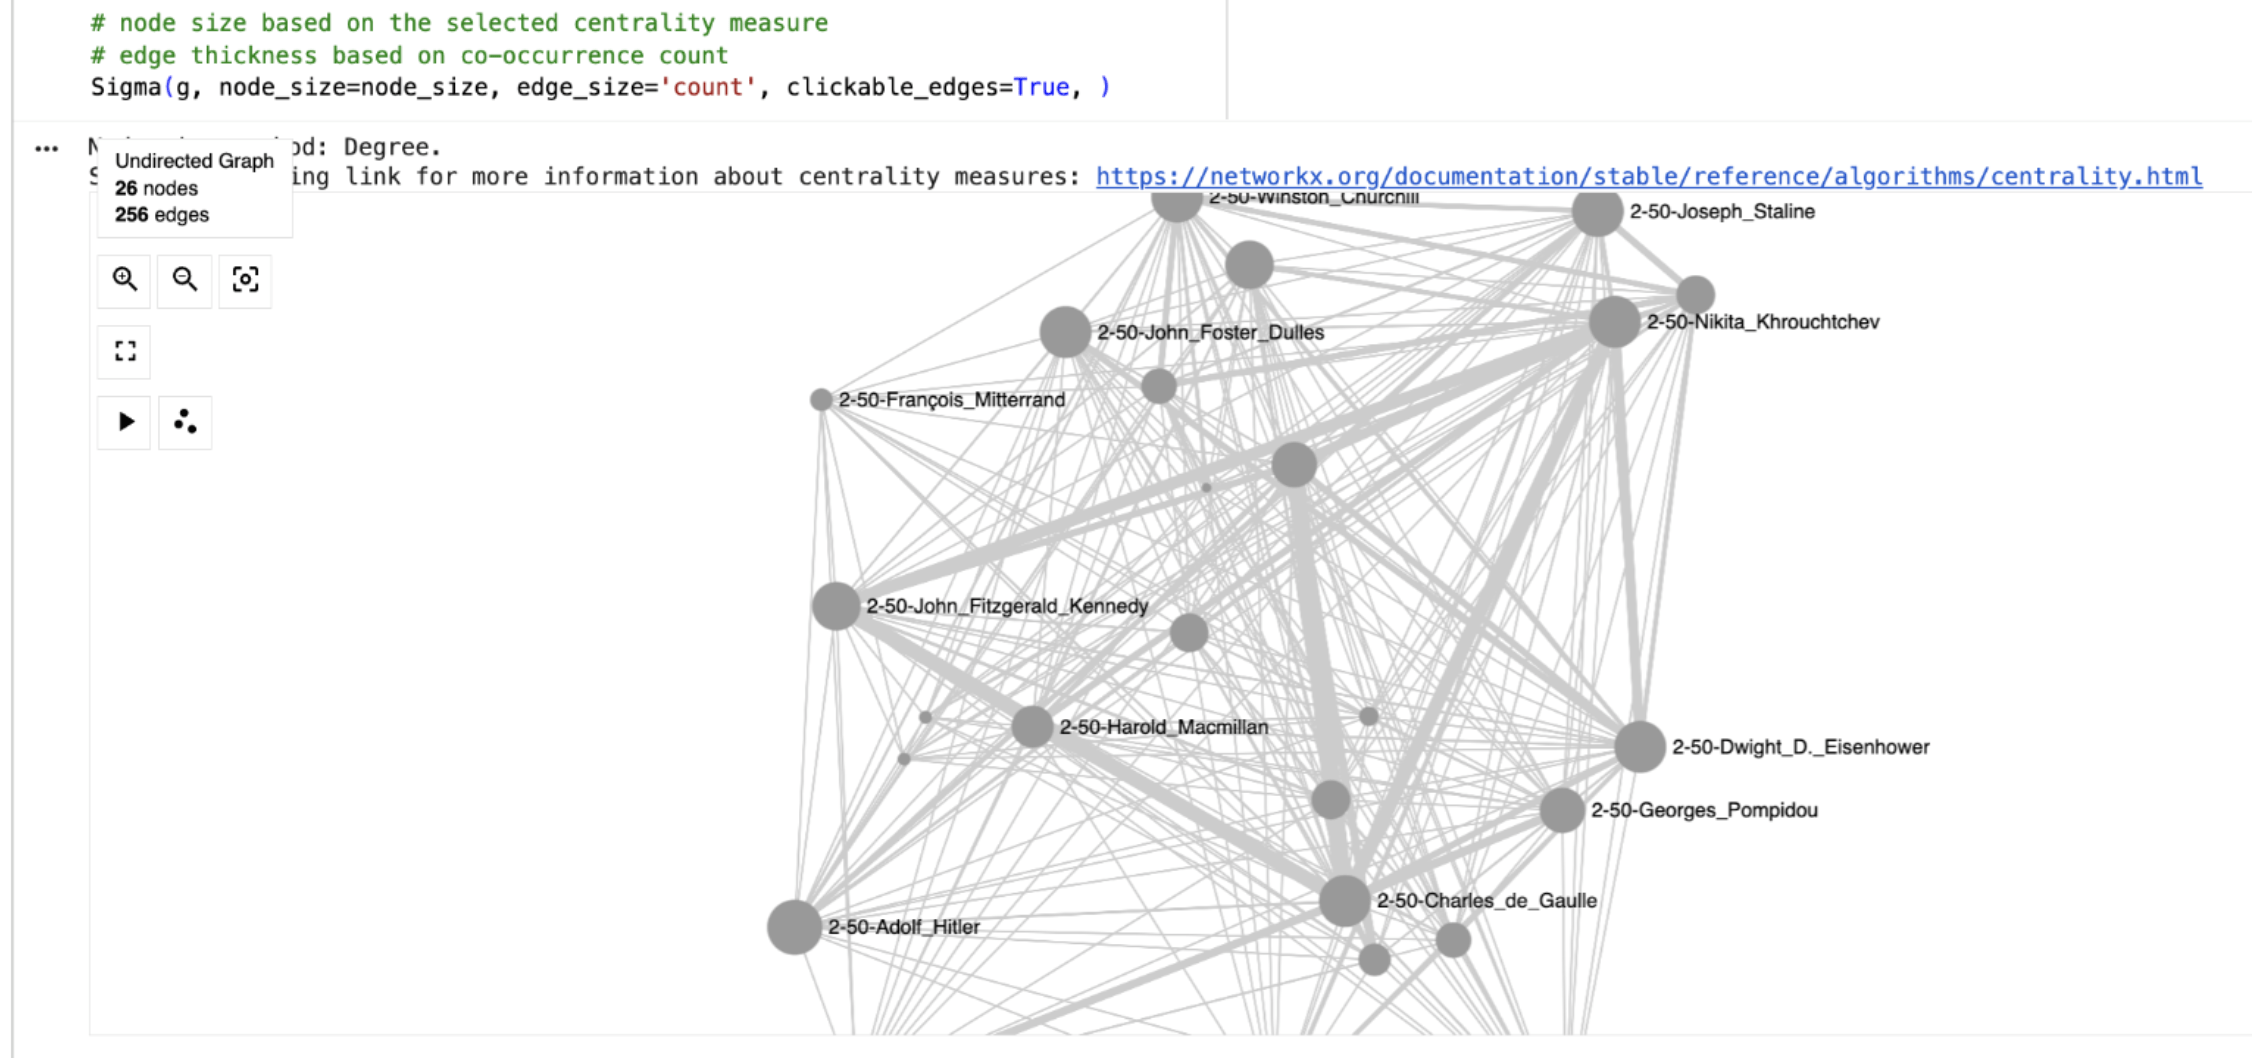
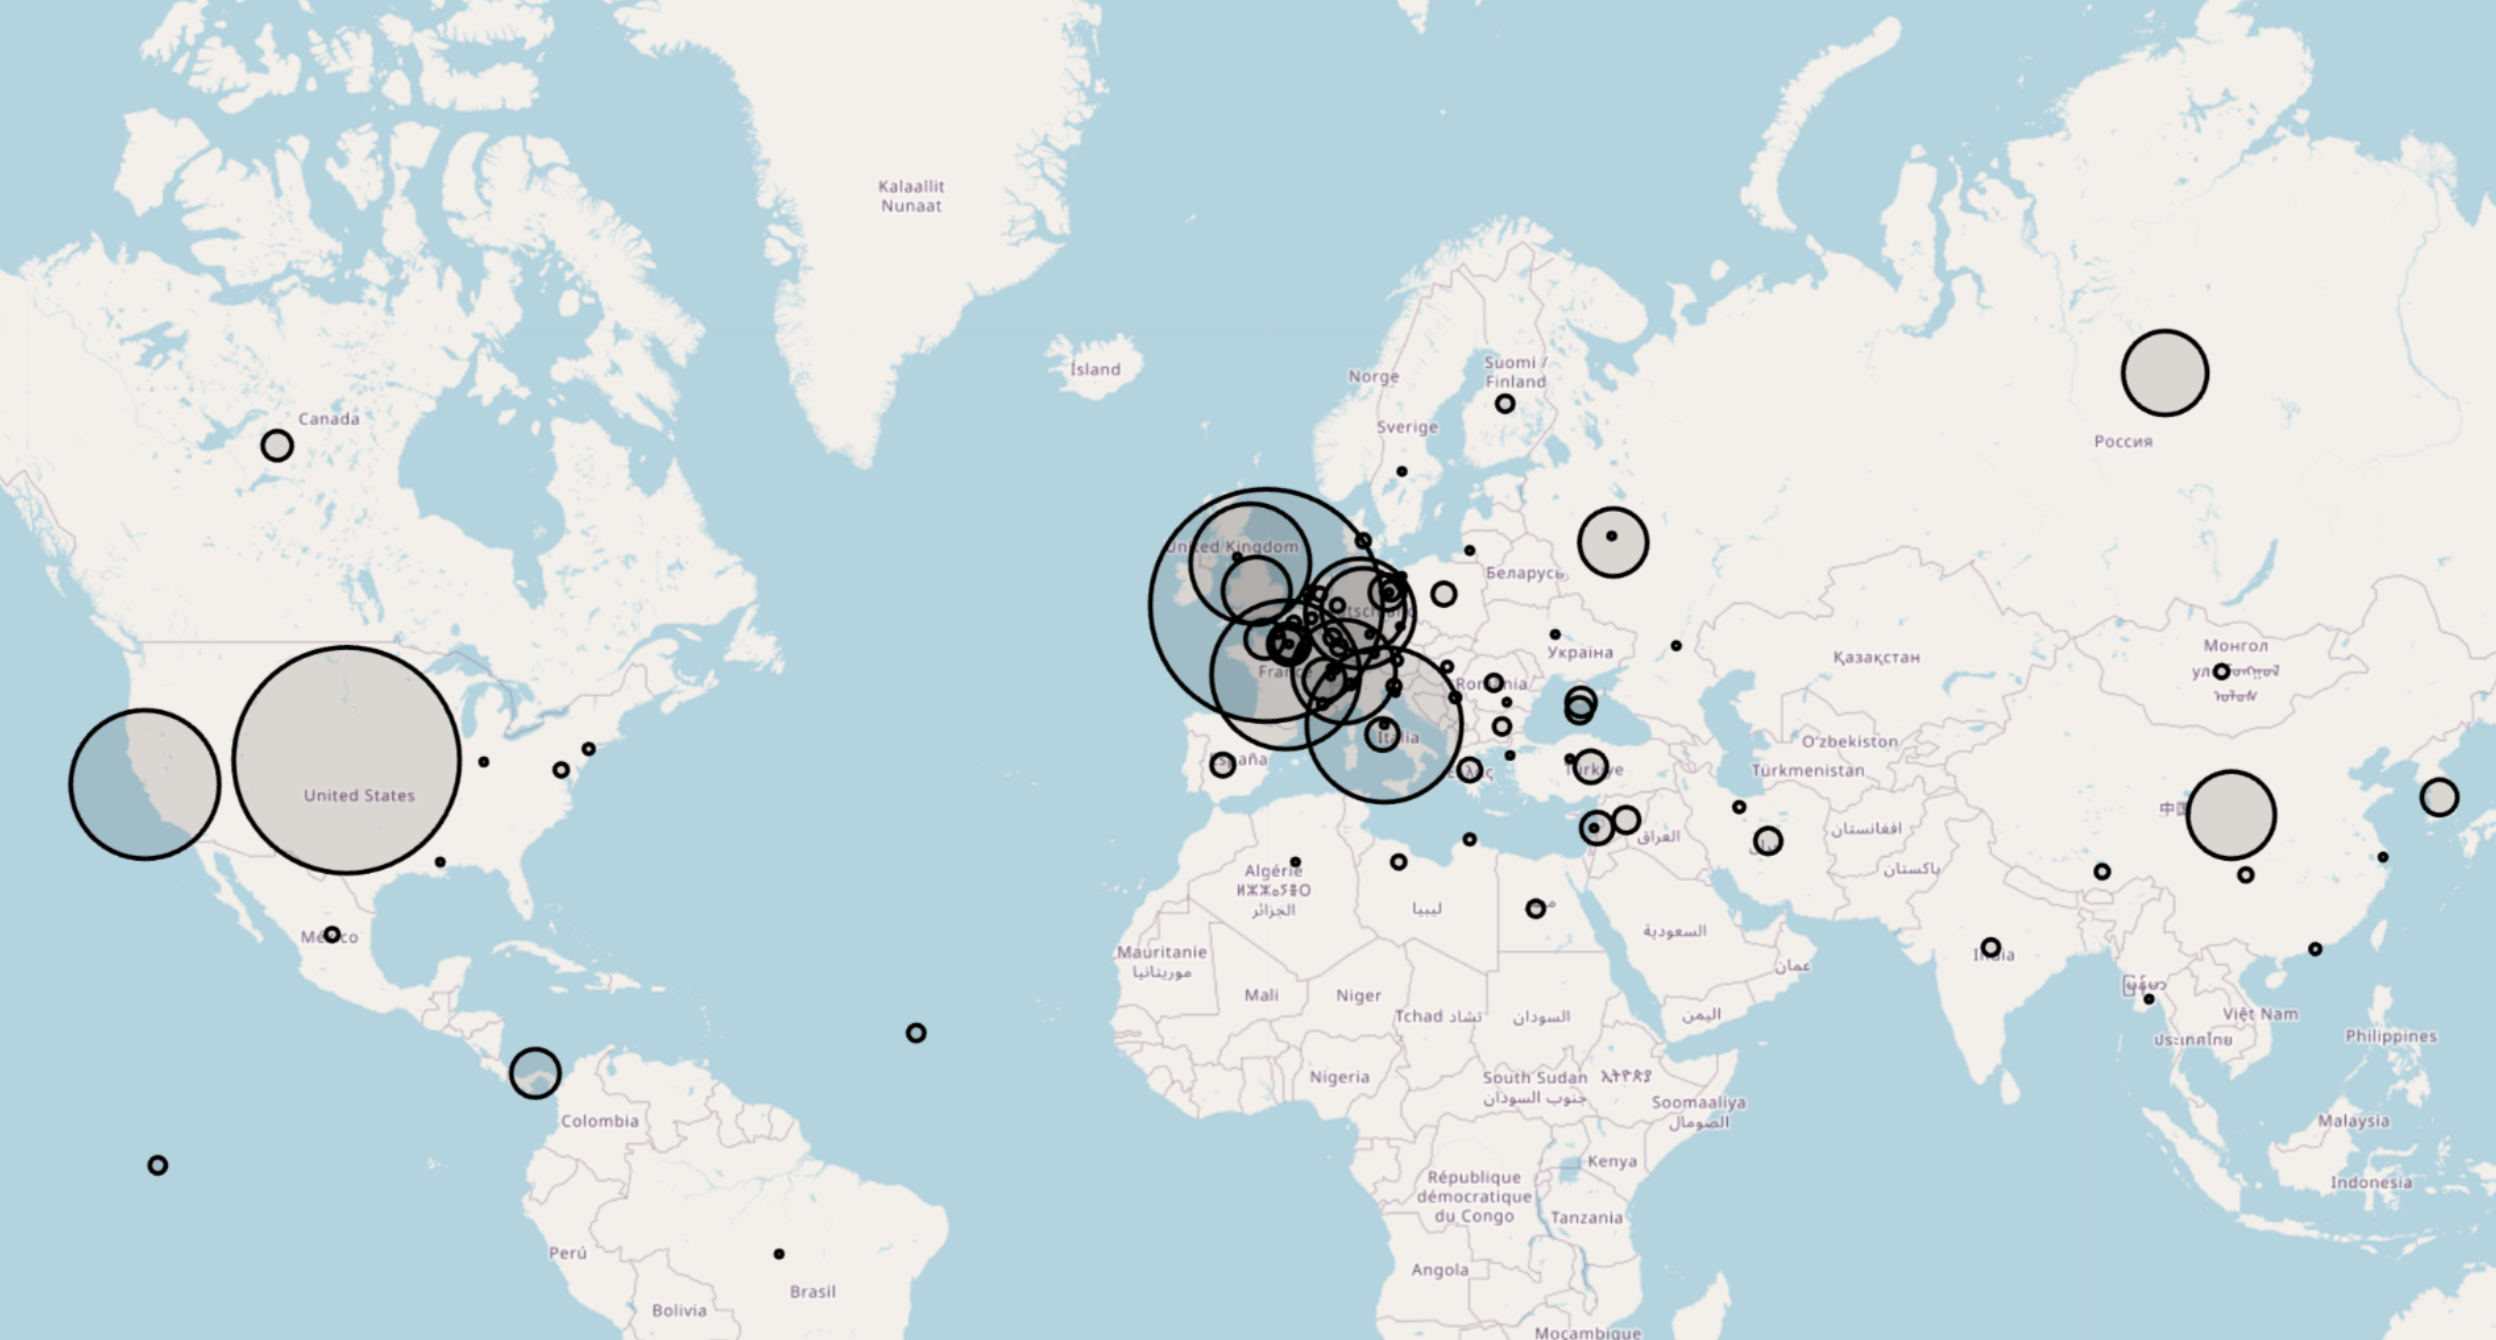
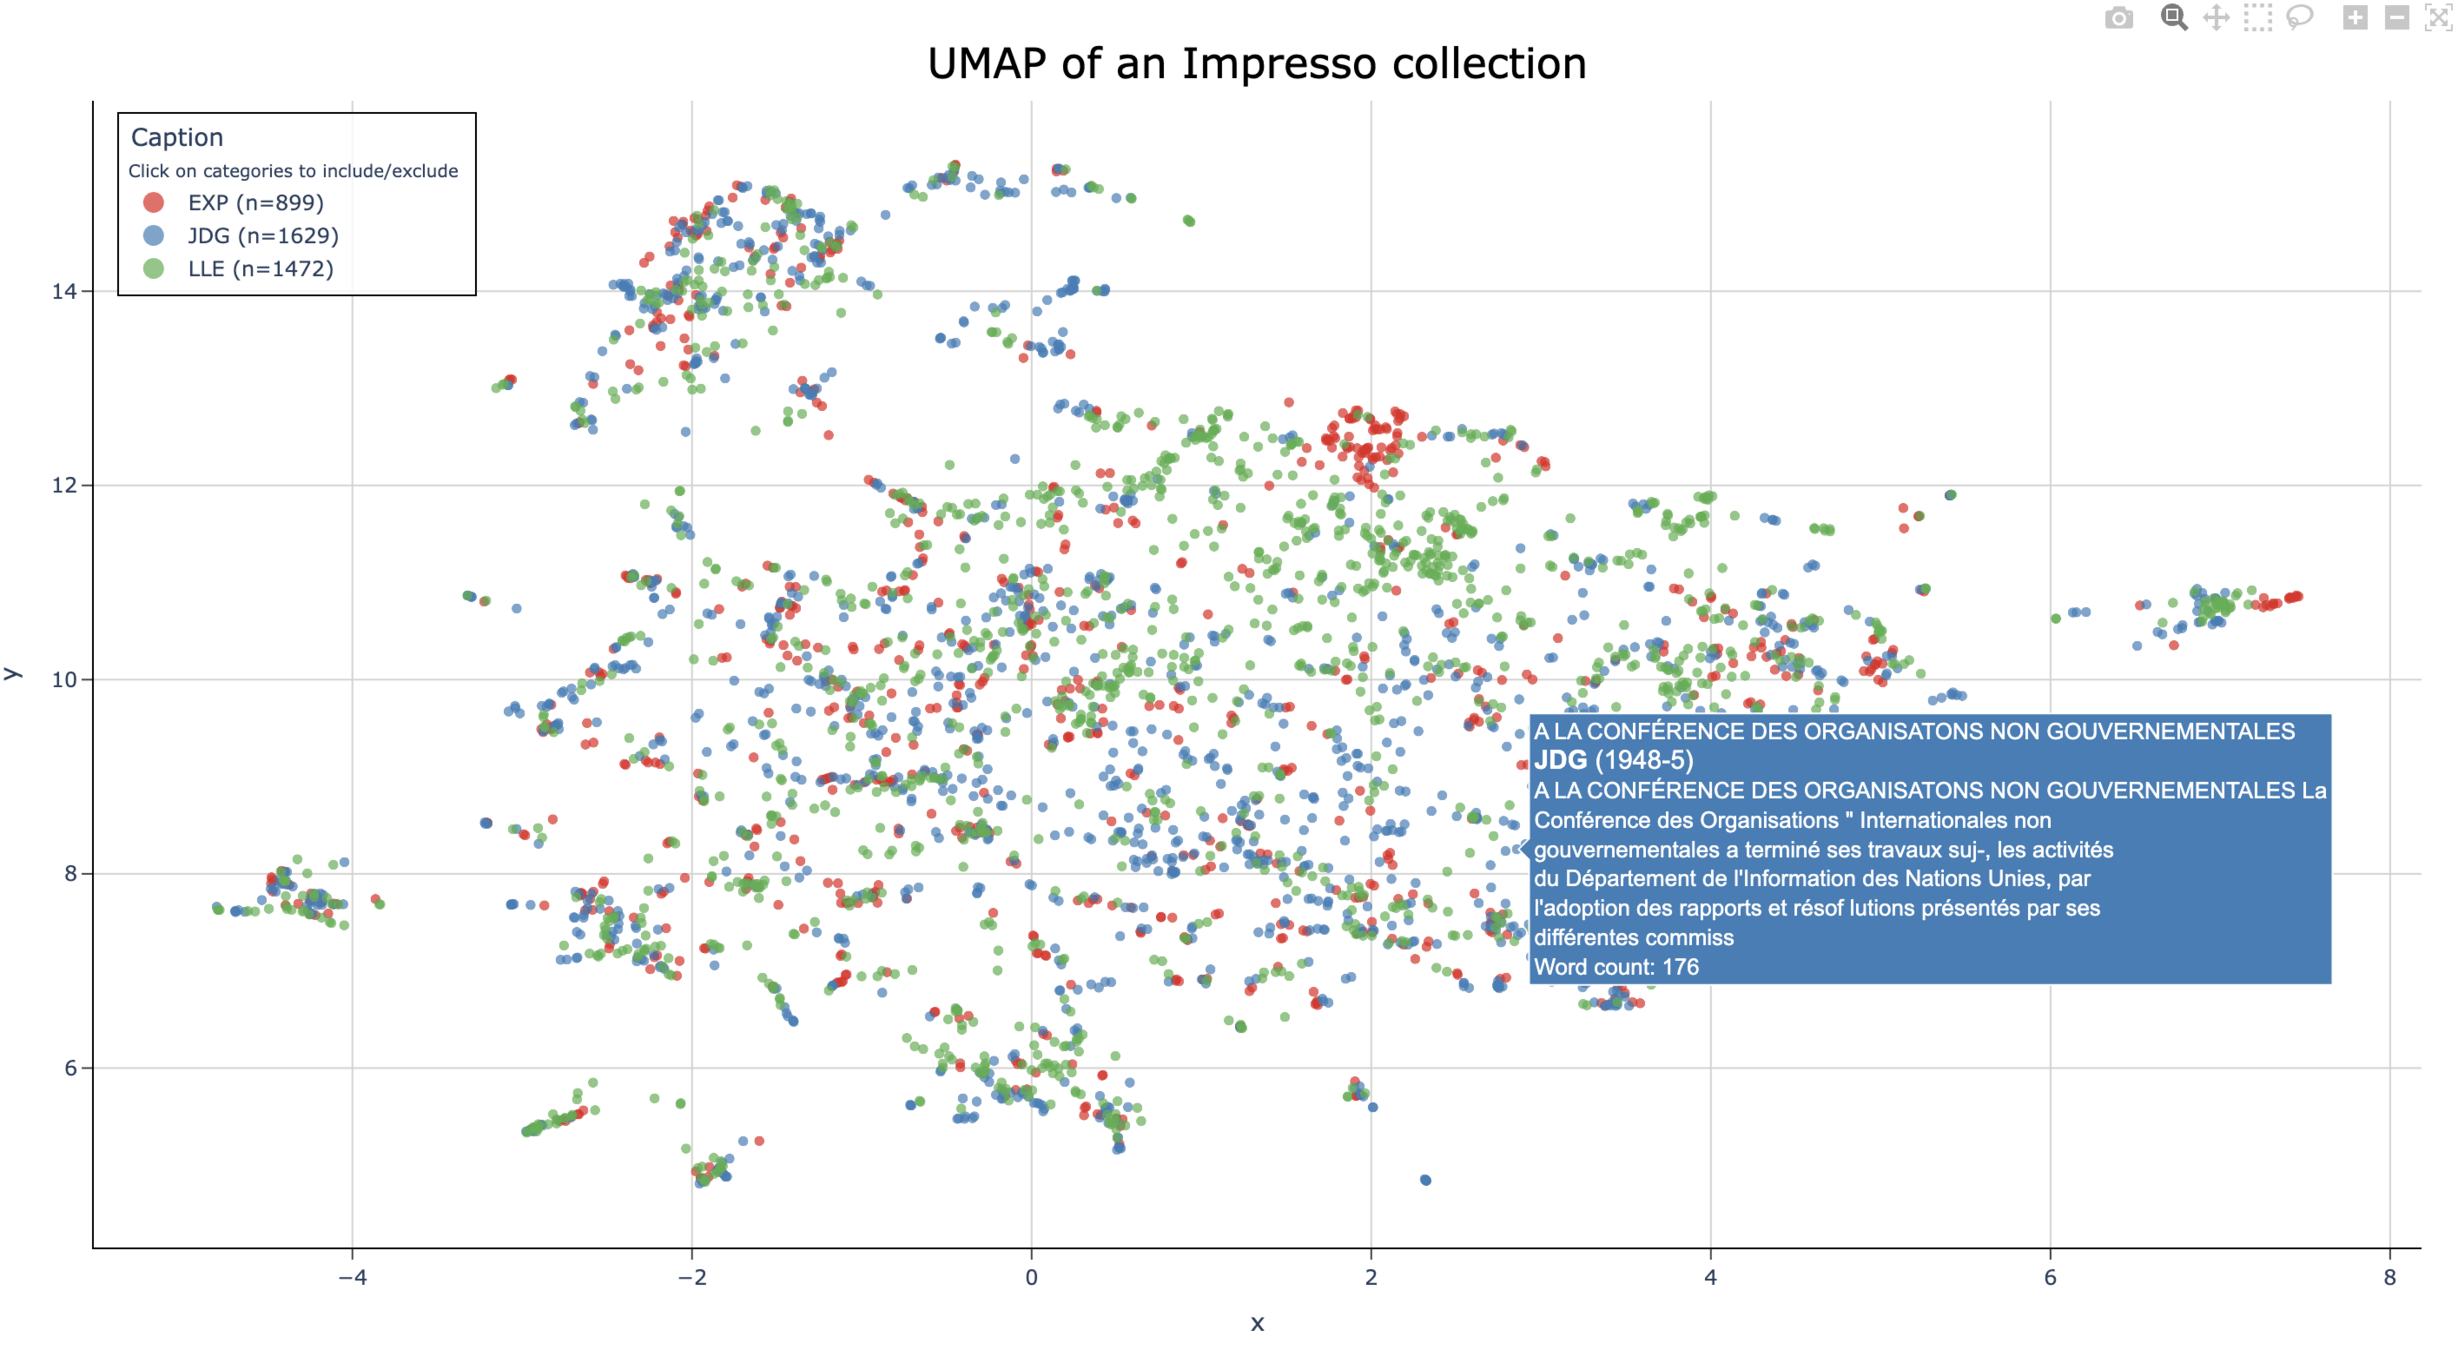
Network of entities
Map of locations
Semantic proximity
The goal is to spark users’ curiosity, make computational methods accessible to them, and encourage them to explore code without needing to master it.
The Impresso datalab
But what exactly is a notebook?
A Jupyter Notebook is an interactive, (often) web-based tool that lets you combine live code, visual graphics, mathematical equations, and narrative text into a single shareable document.
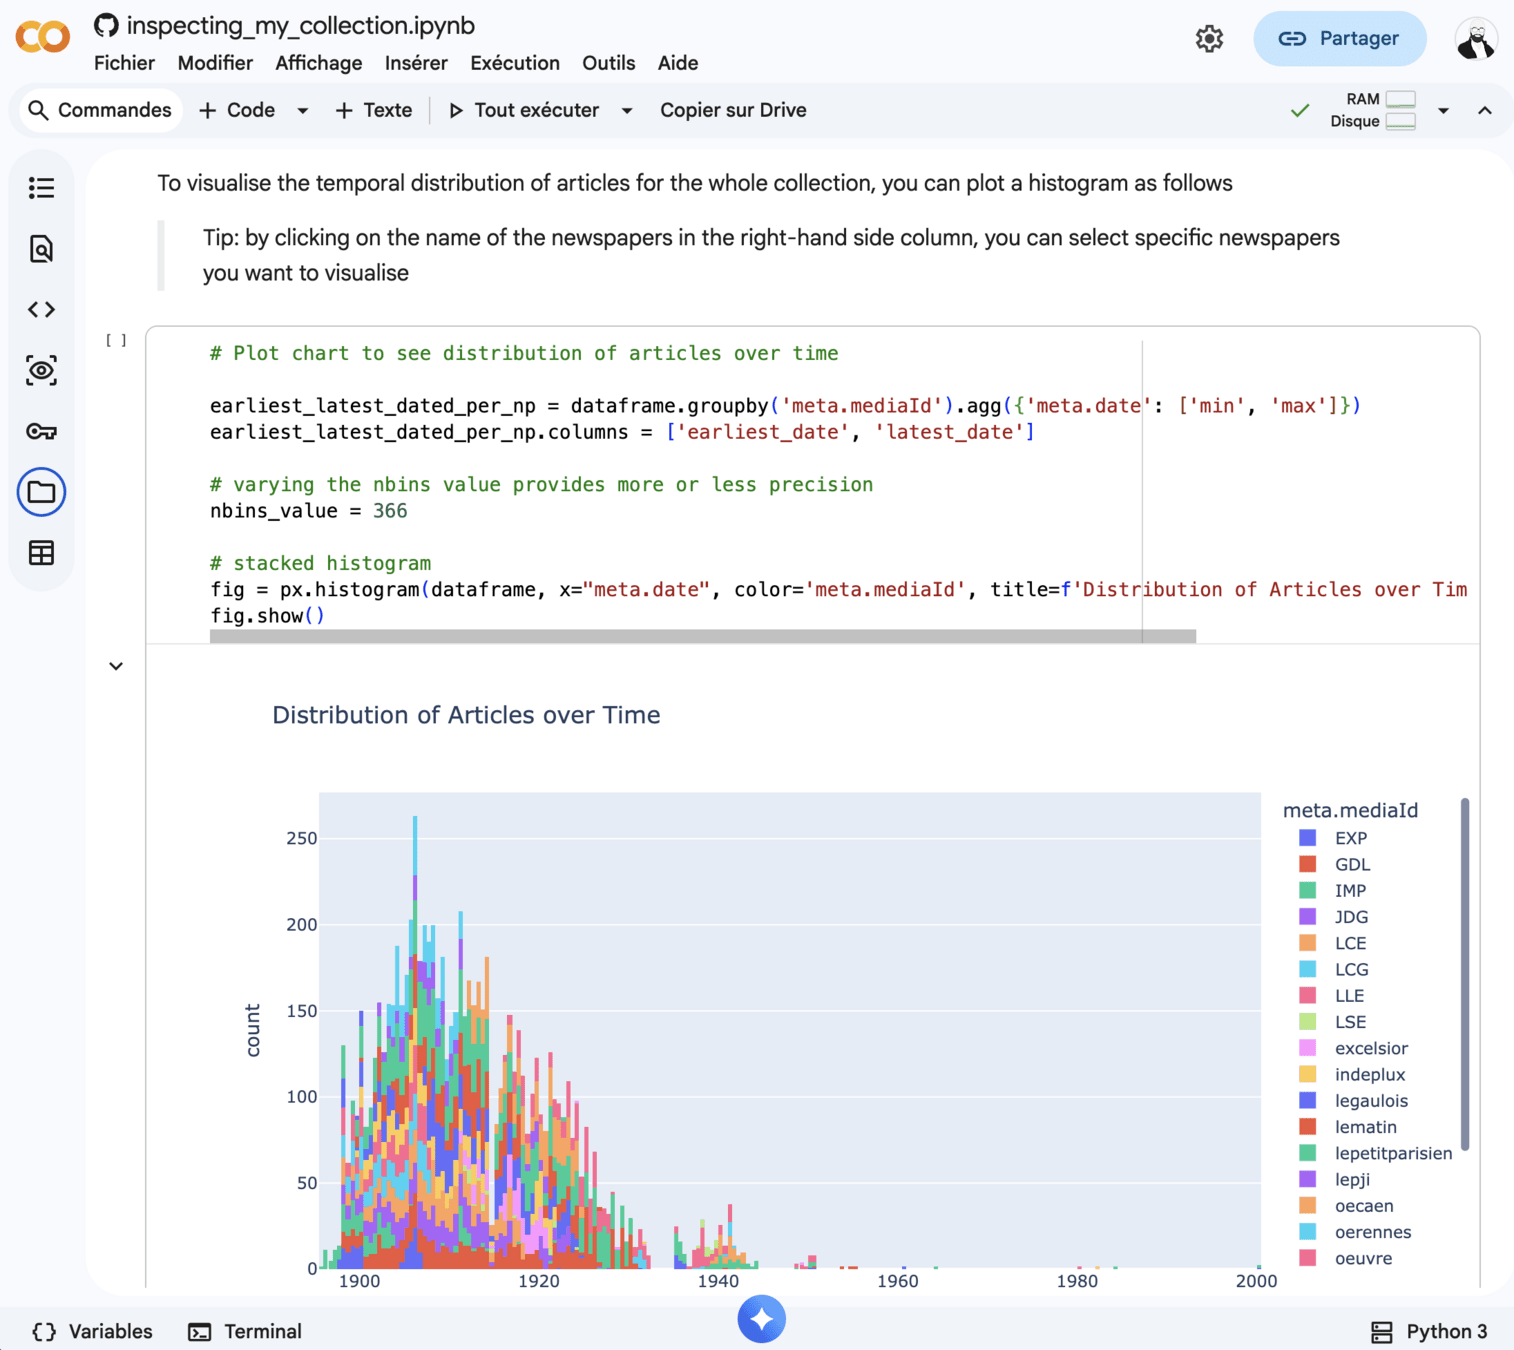
1. A notebook contains lines of code
2. It also includes comments explaining what we're doing
3. Each cell of code can be executed to see the result immediately
The Impresso datalab
A co-design process
But then, who develops these tools? And to meet what needs?
We can try to anticipate the needs of historians and students, but we can also identify them collectively.
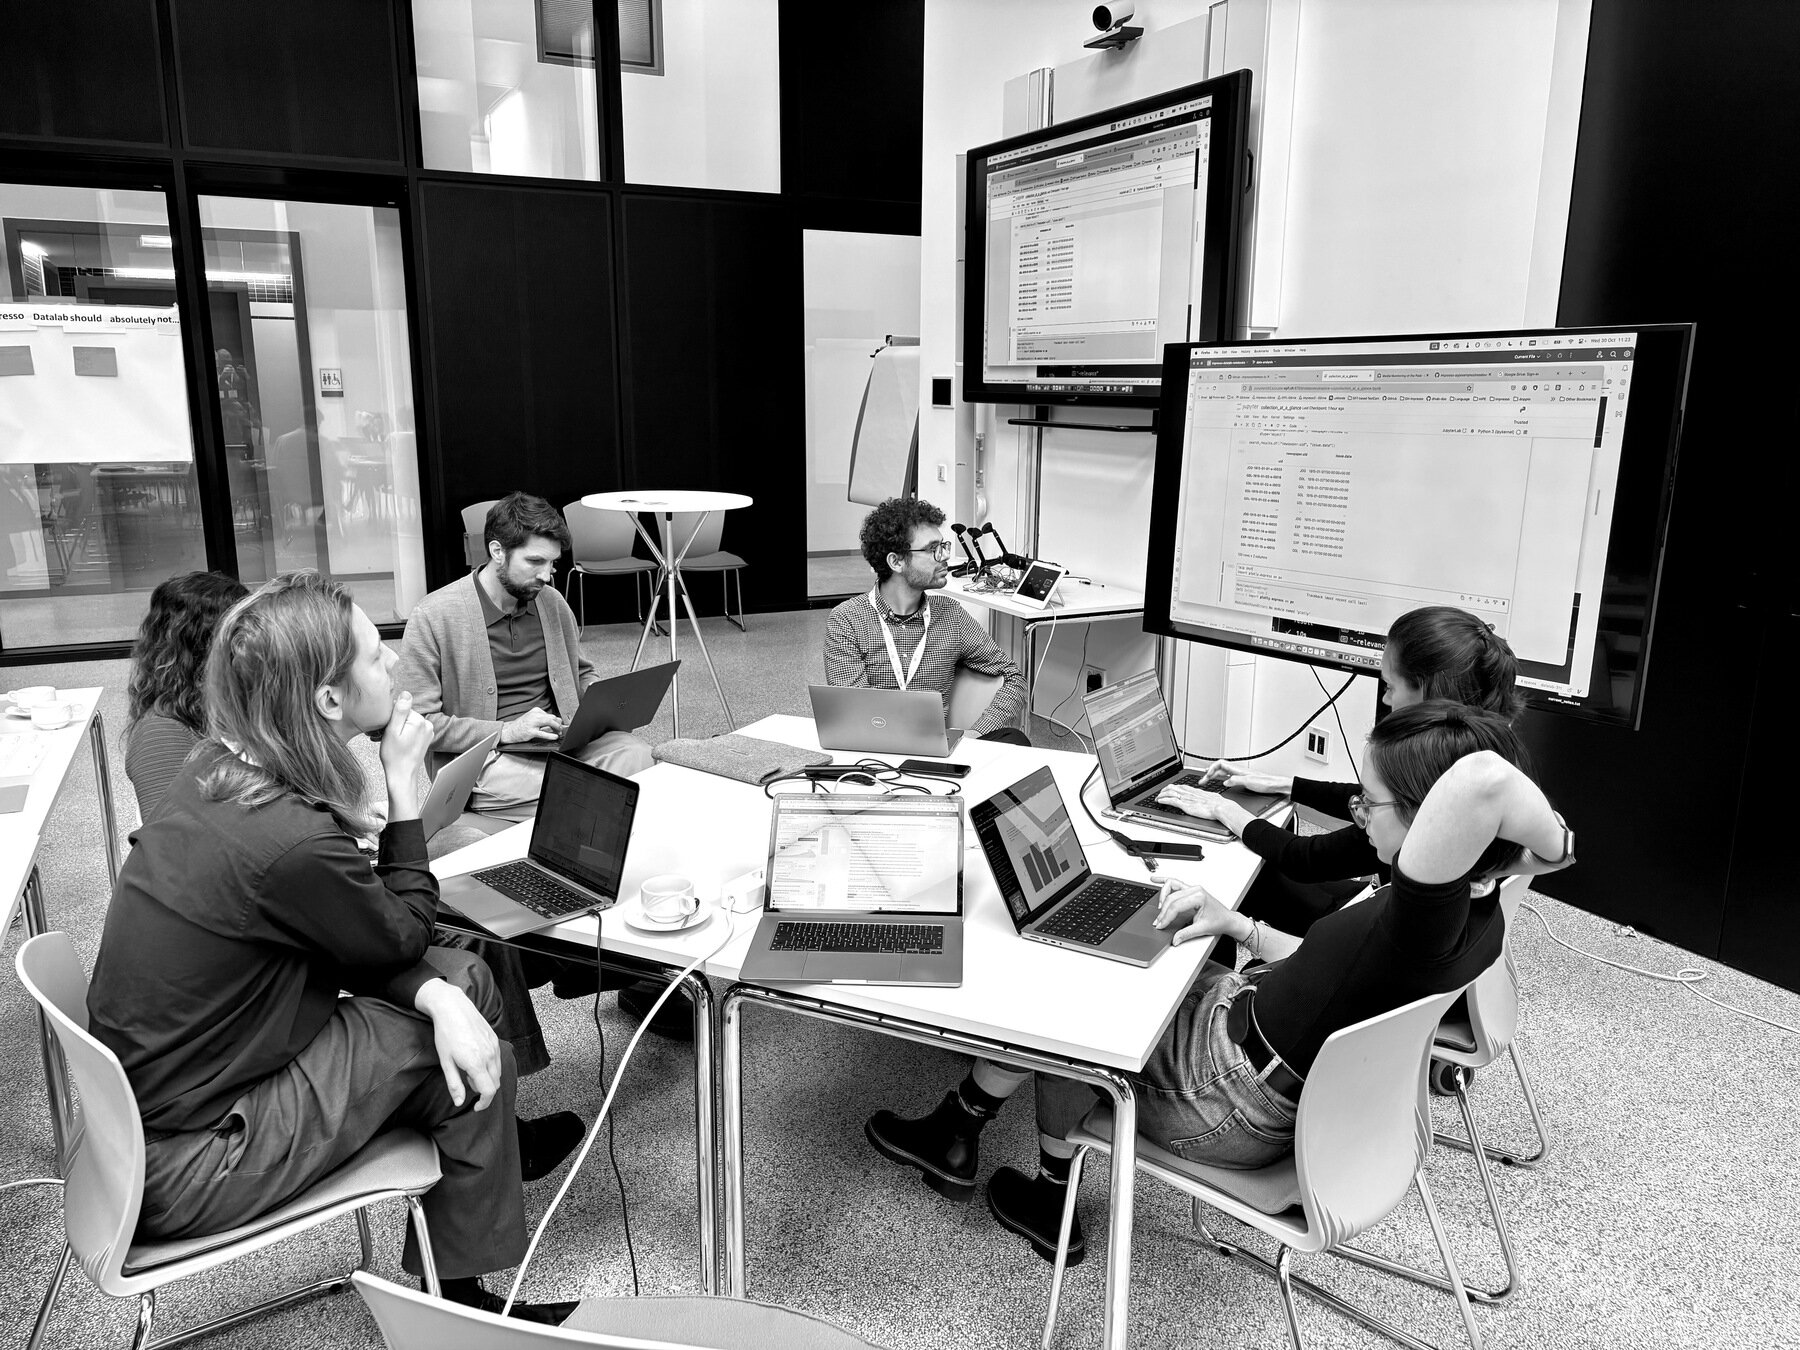
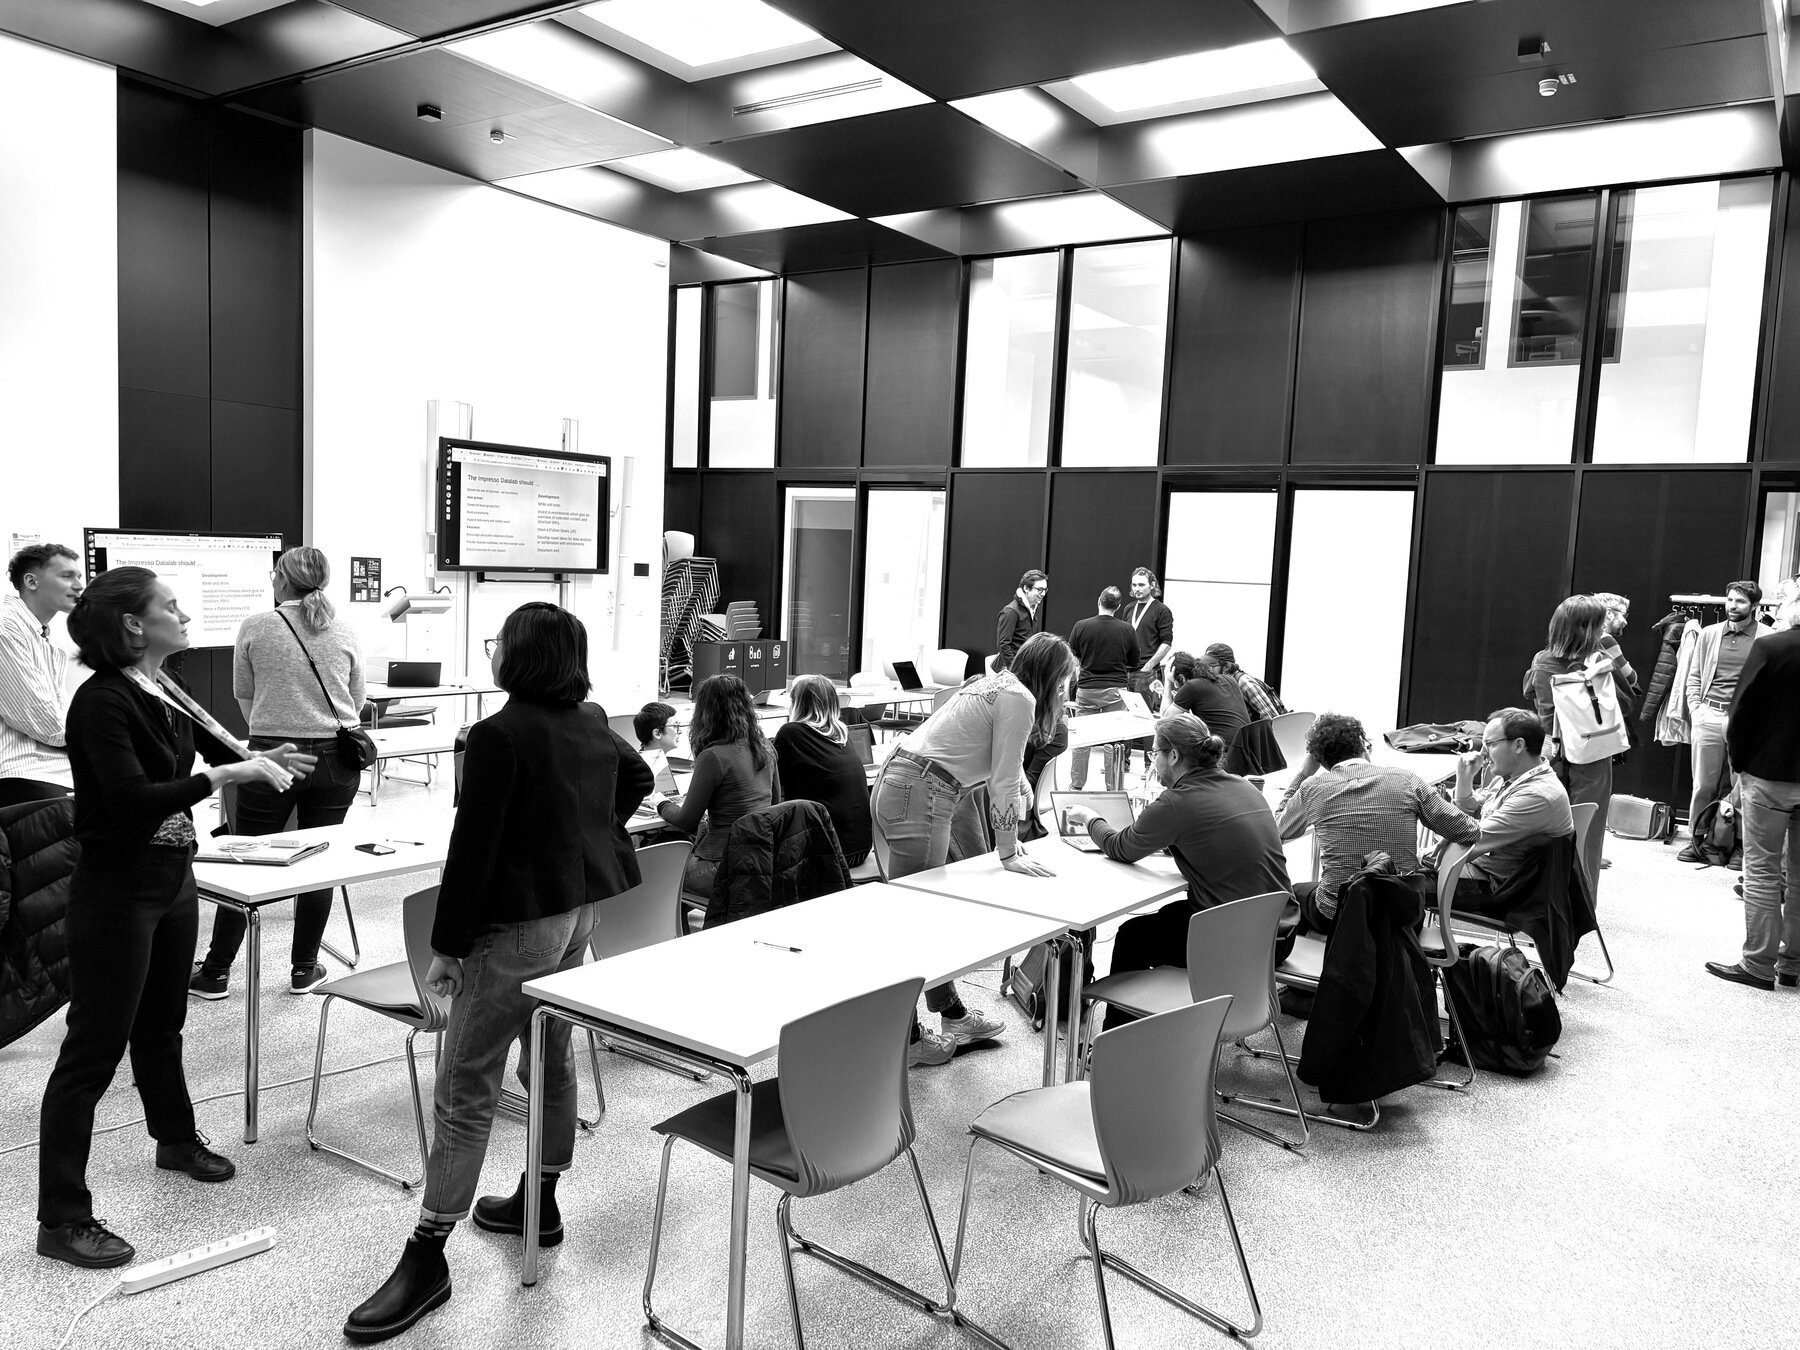
For example, we invited colleagues to a workshop to develop analytical scenarios together
(University of Luxembourg, fall 2024).
The process begins, therefore, with a face-to-face meeting between people from different professions, to “bridge the gap” in a practical way.
A co-design process
For example, one group came up with the idea of creating a small tool that would allow users to perform exploratory data analysis (EDA)—enabling them to generate a brief statistical report based on a collection of Impresso articles.
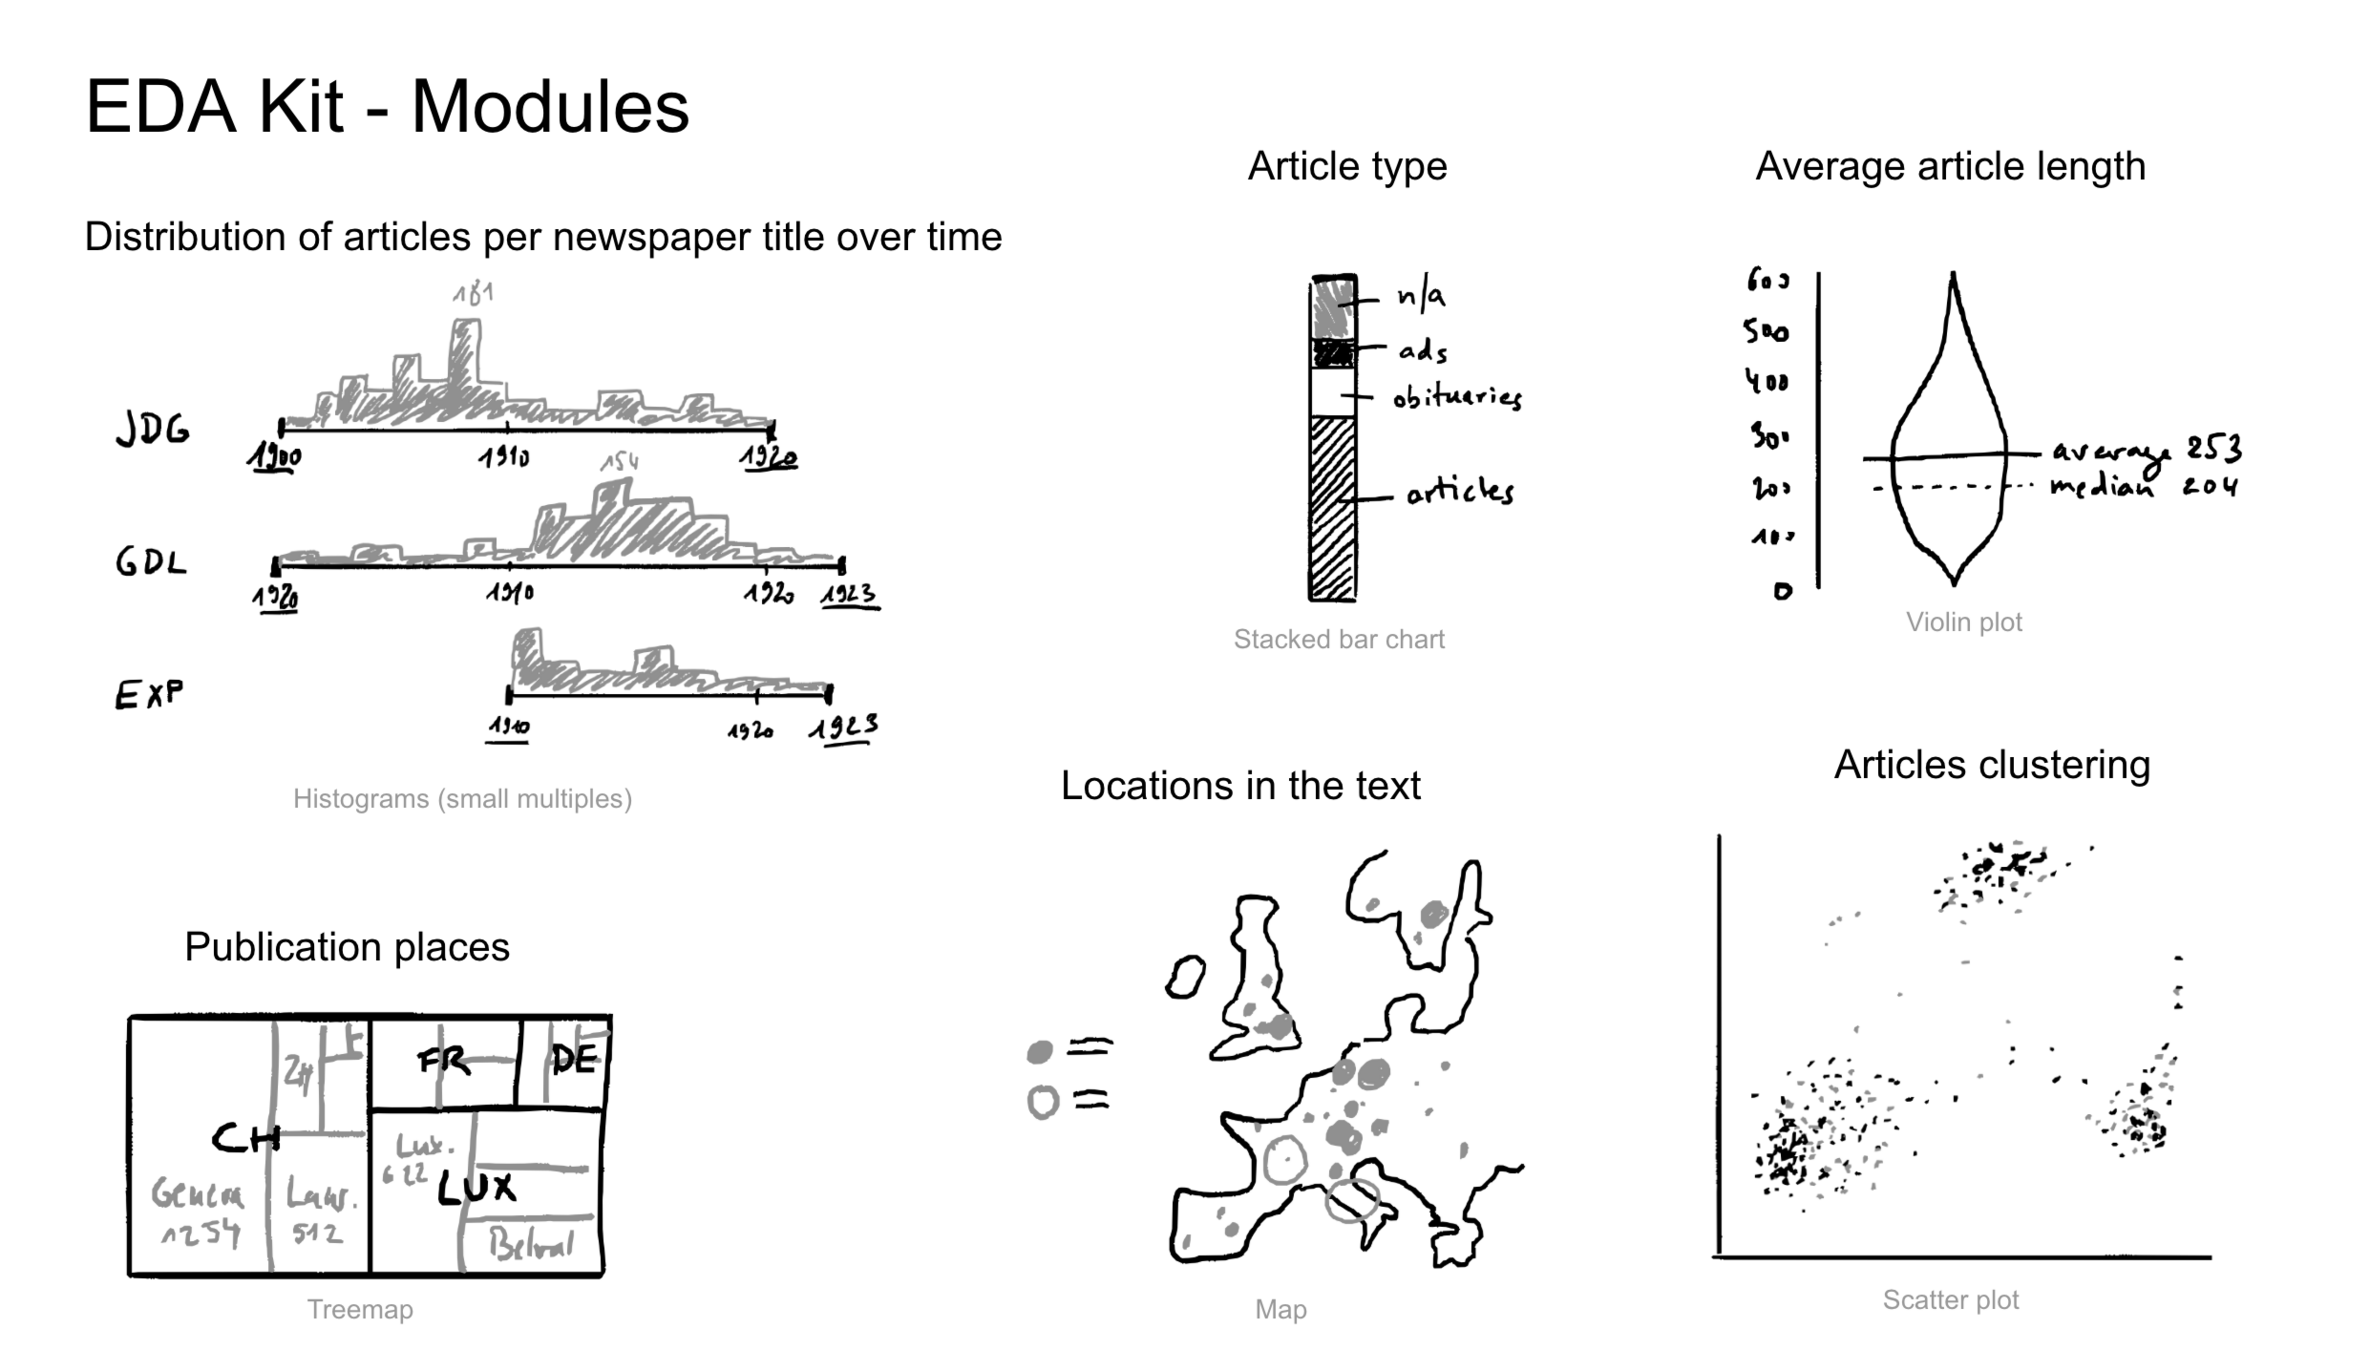
This drawing is literally the result of that group work session.
A co-design process
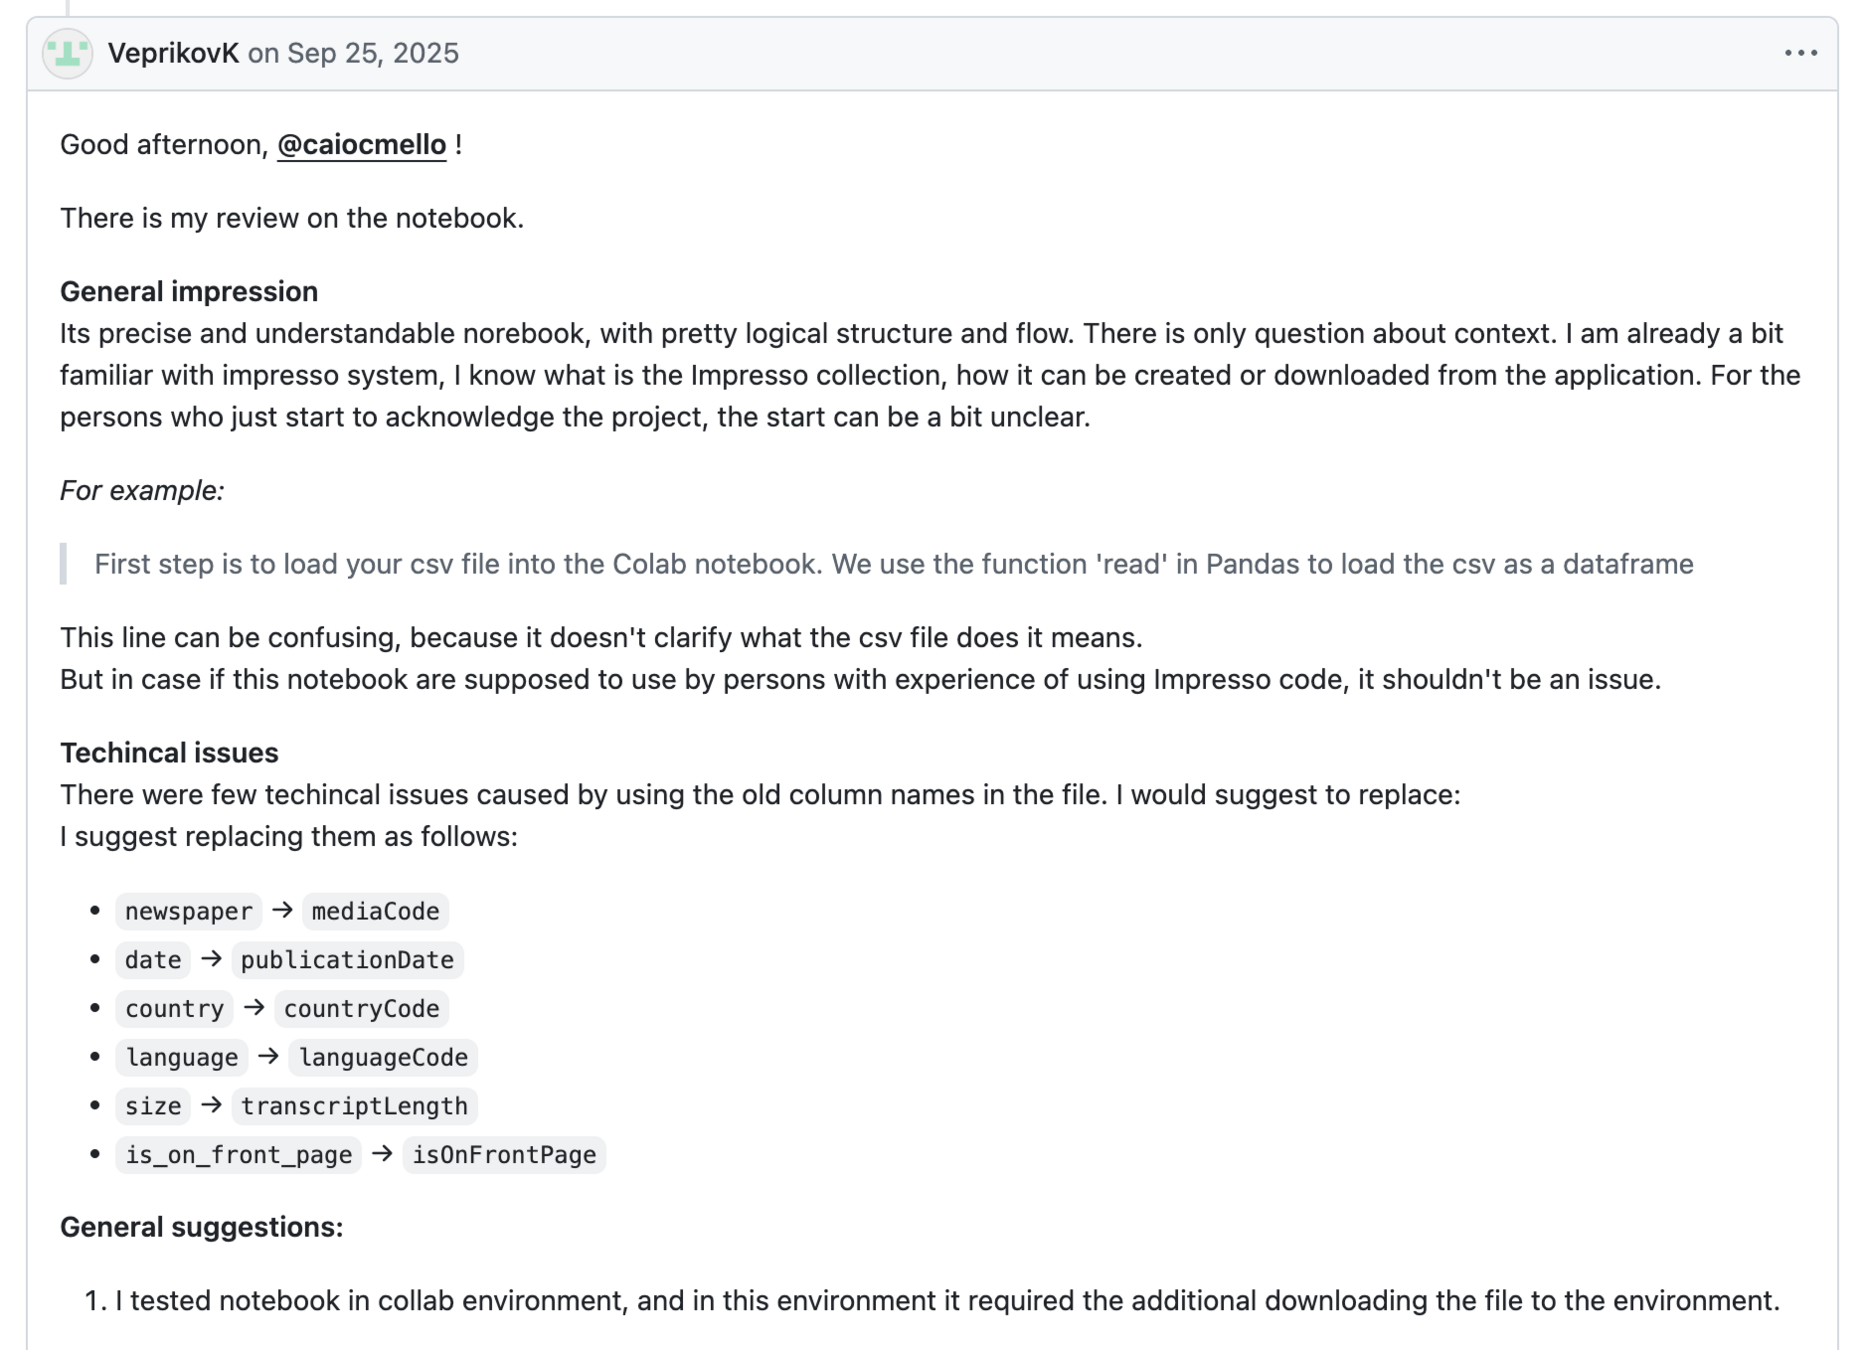
We have established a Datalab Editorial Board, which develops guidelines to standardize the notebooks and manage their development.
Development and internal/external review processes
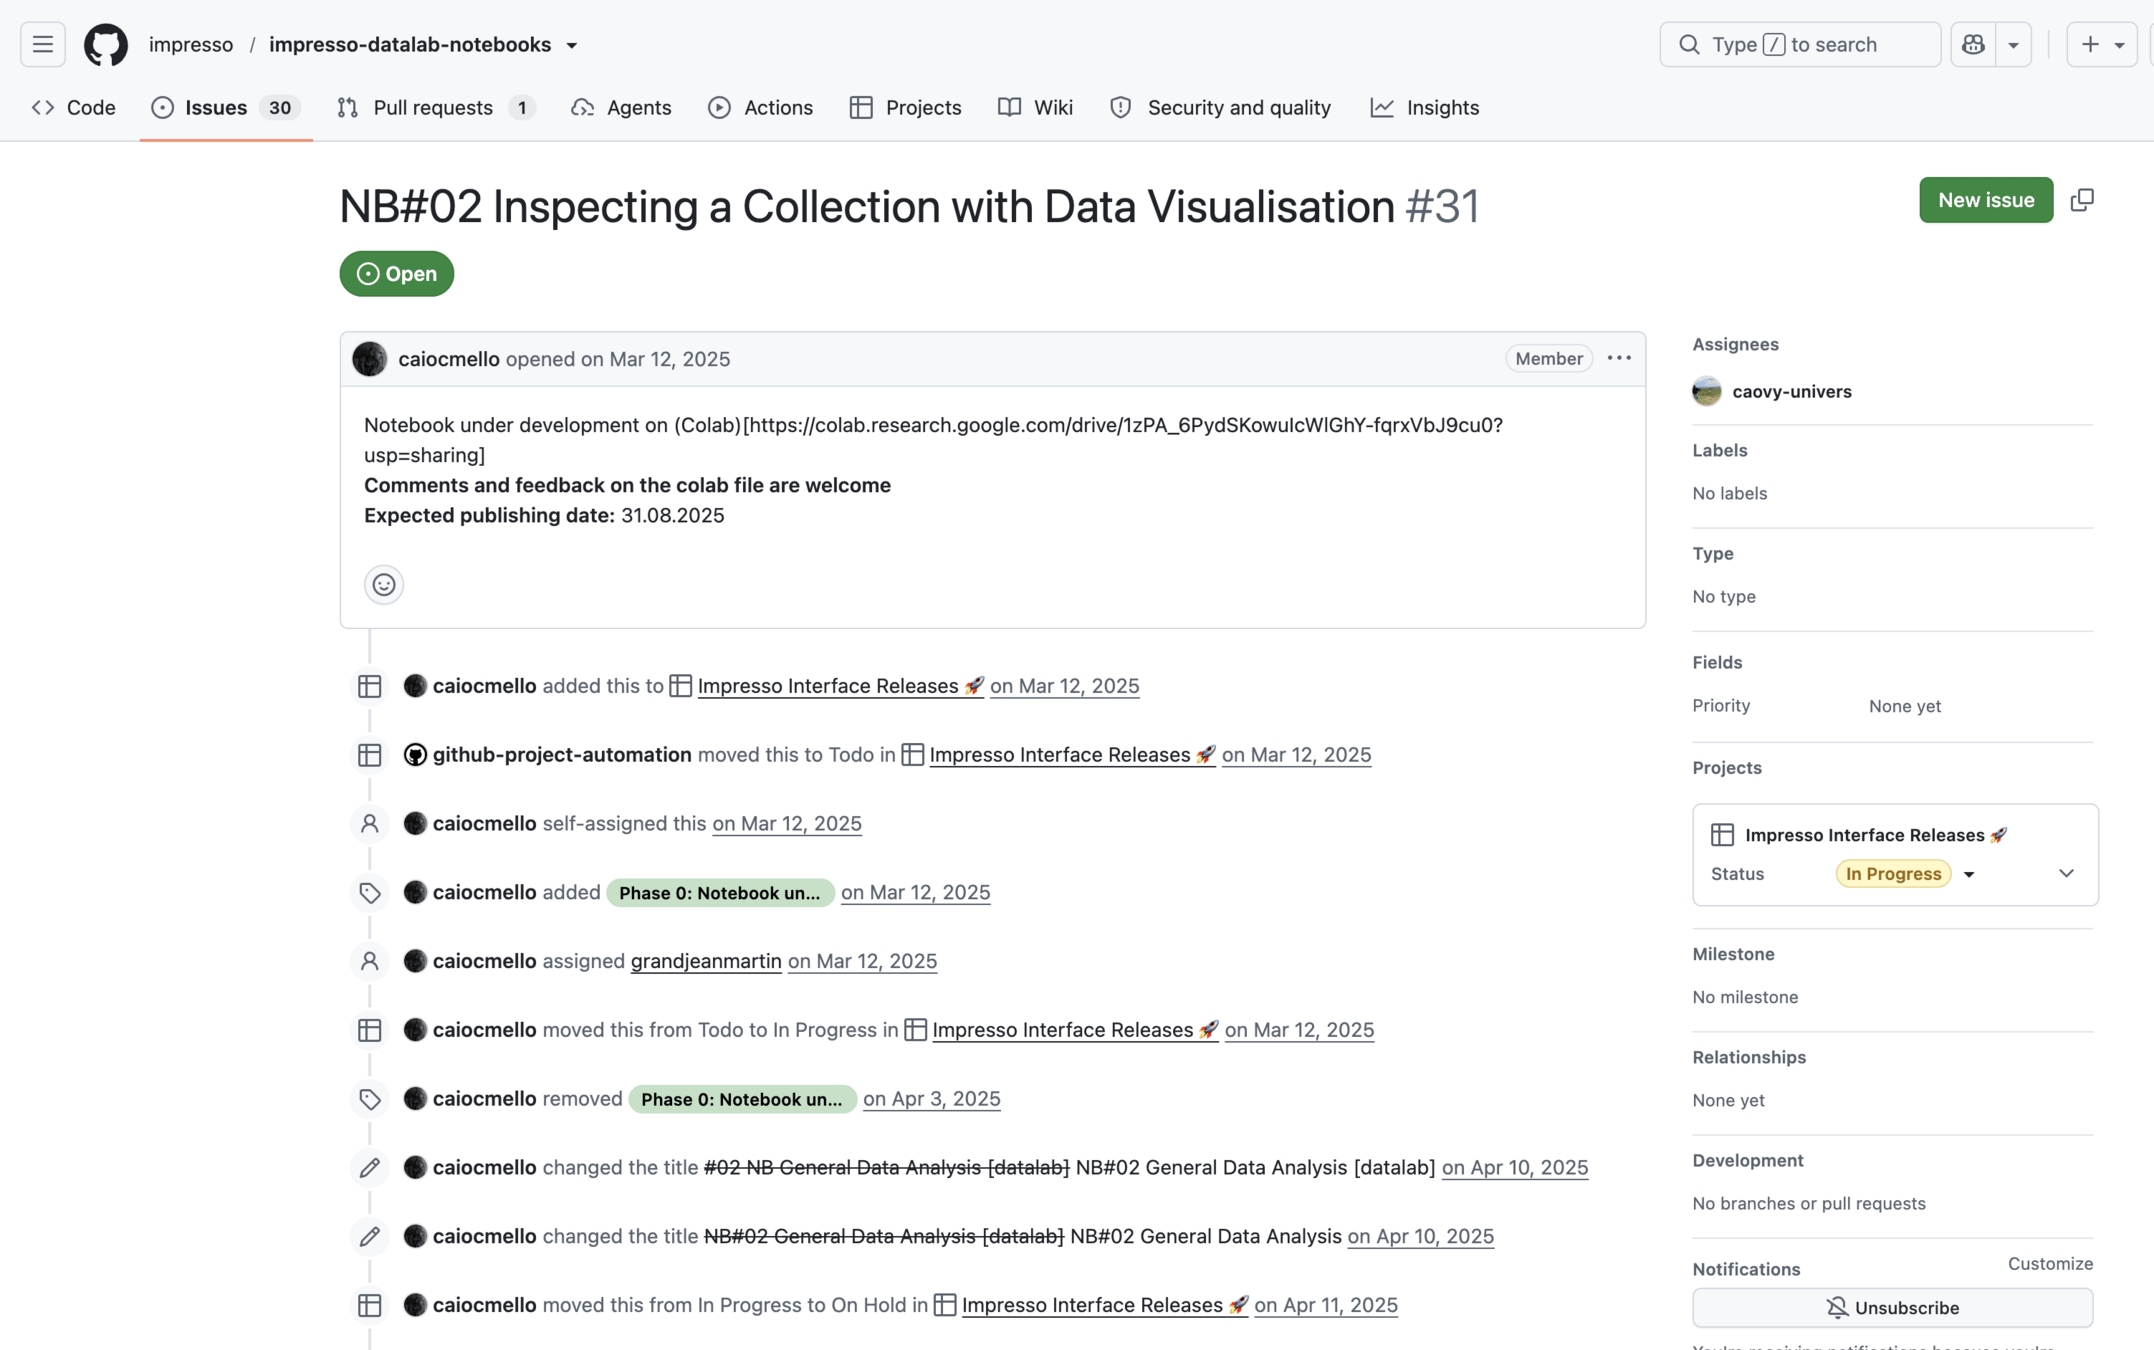
Internal review
External review
Drafting
The entire process is a transparent collaborative space that brings together historians, digital humanists, and developers.
A notebook for statistically describing a collection of sources
This is the result of this collaborative process: a notebook to "inspect" a collection of articles
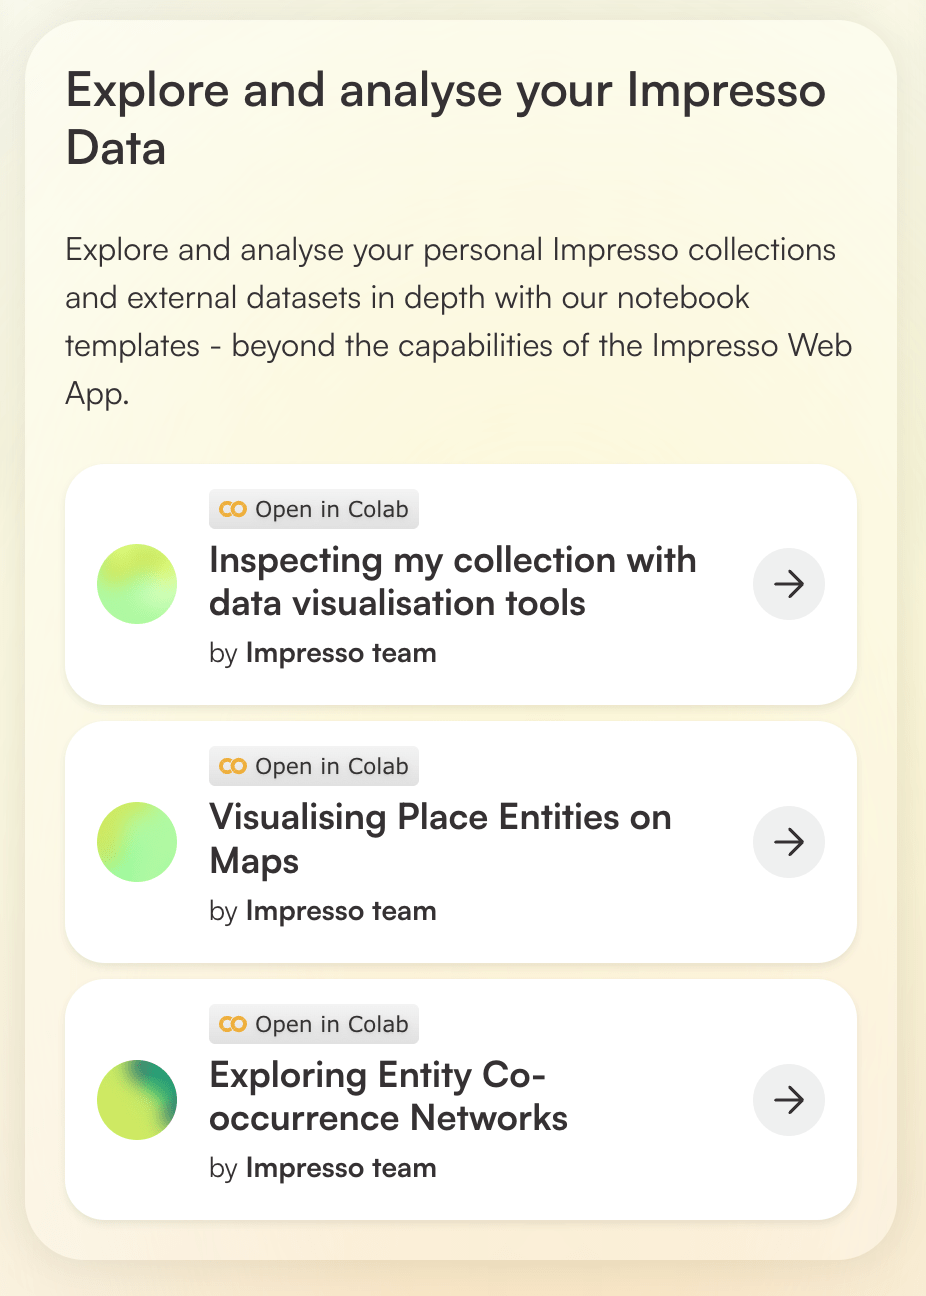
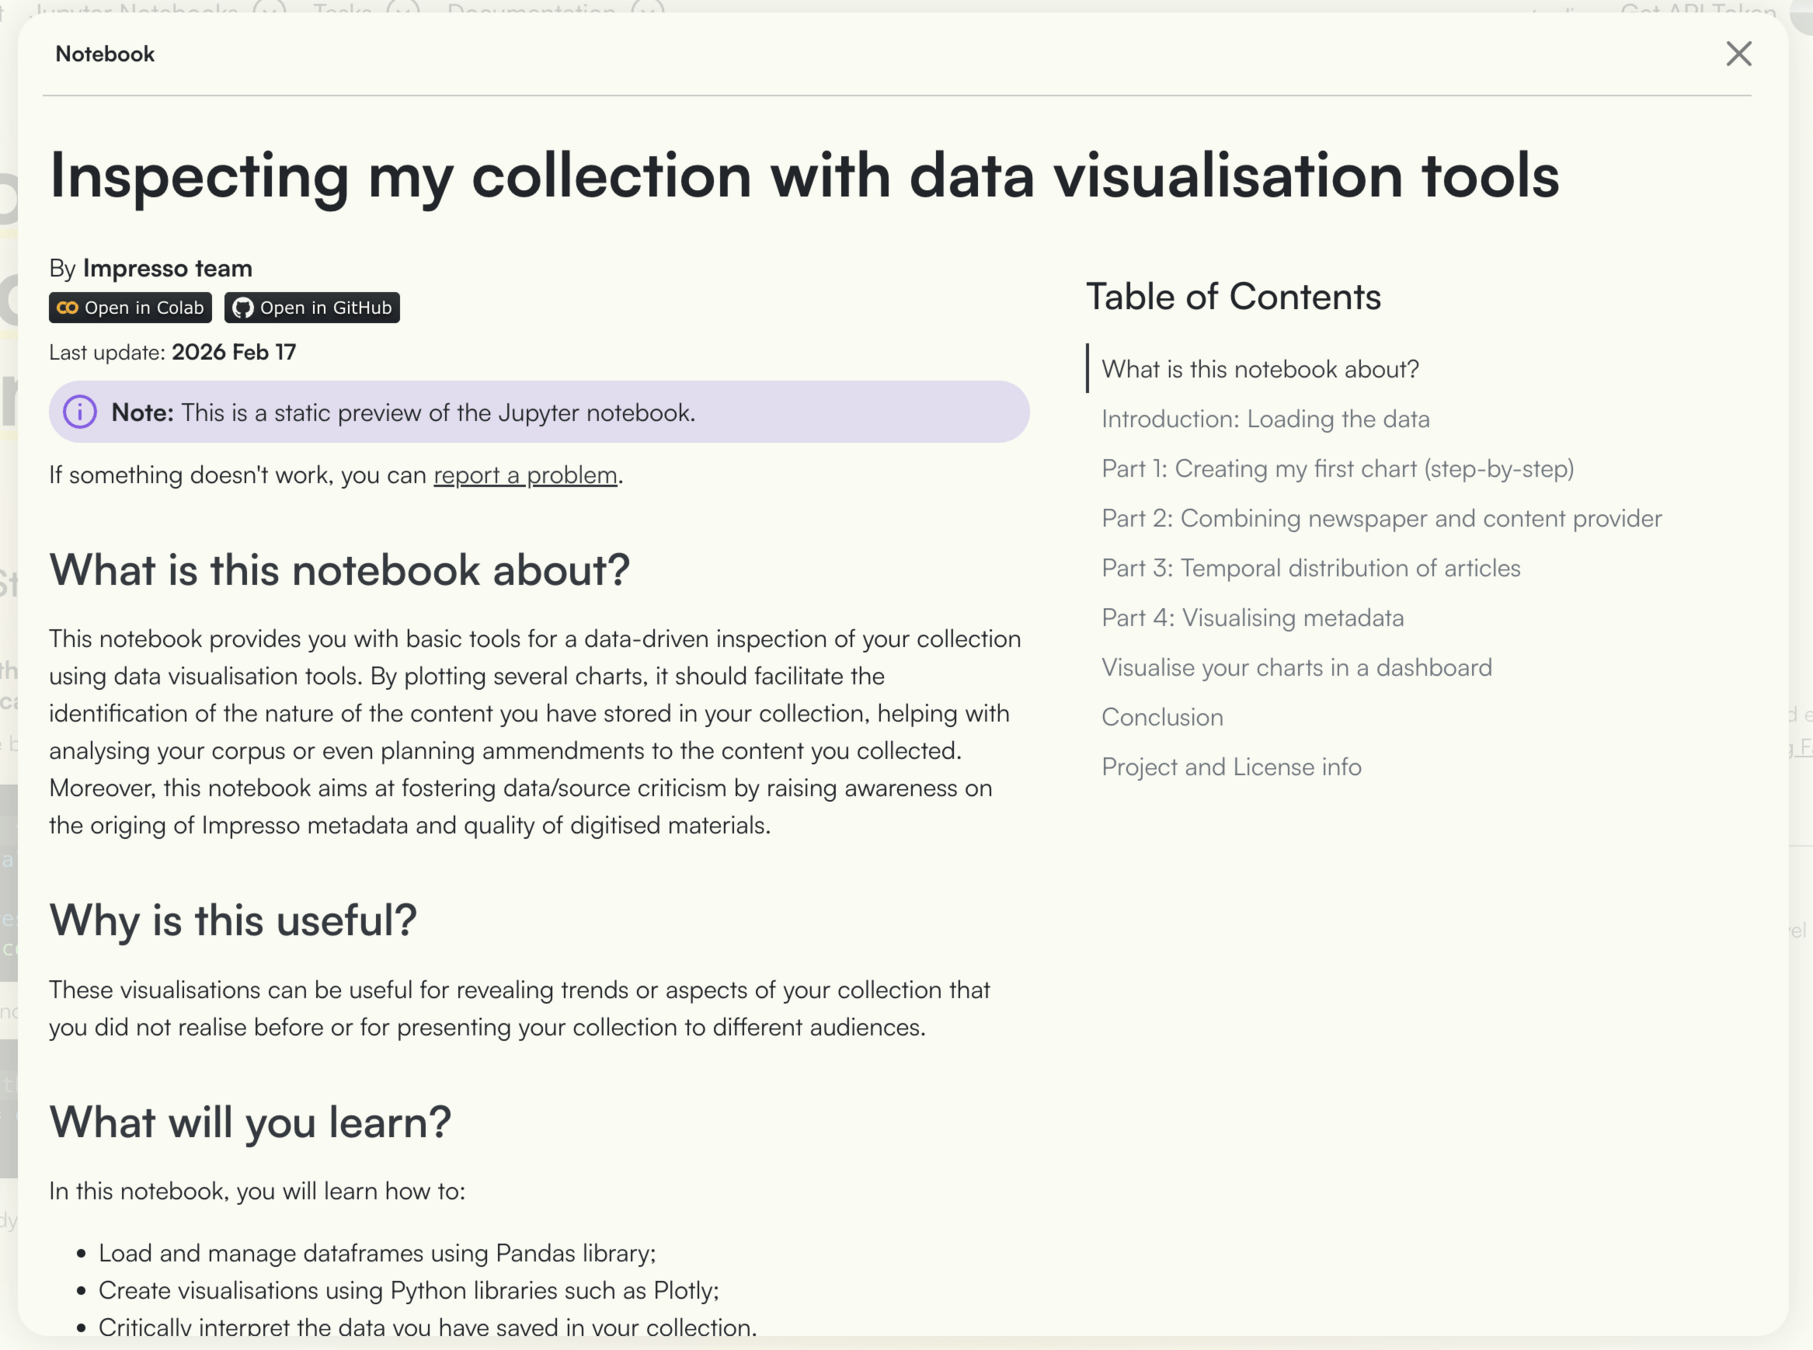
This notebook was created for educational purposes, to generate basic statistics based on an Impresso collection.
We open it in Google Colab, an interface that lets us work online with this Jupyter notebook
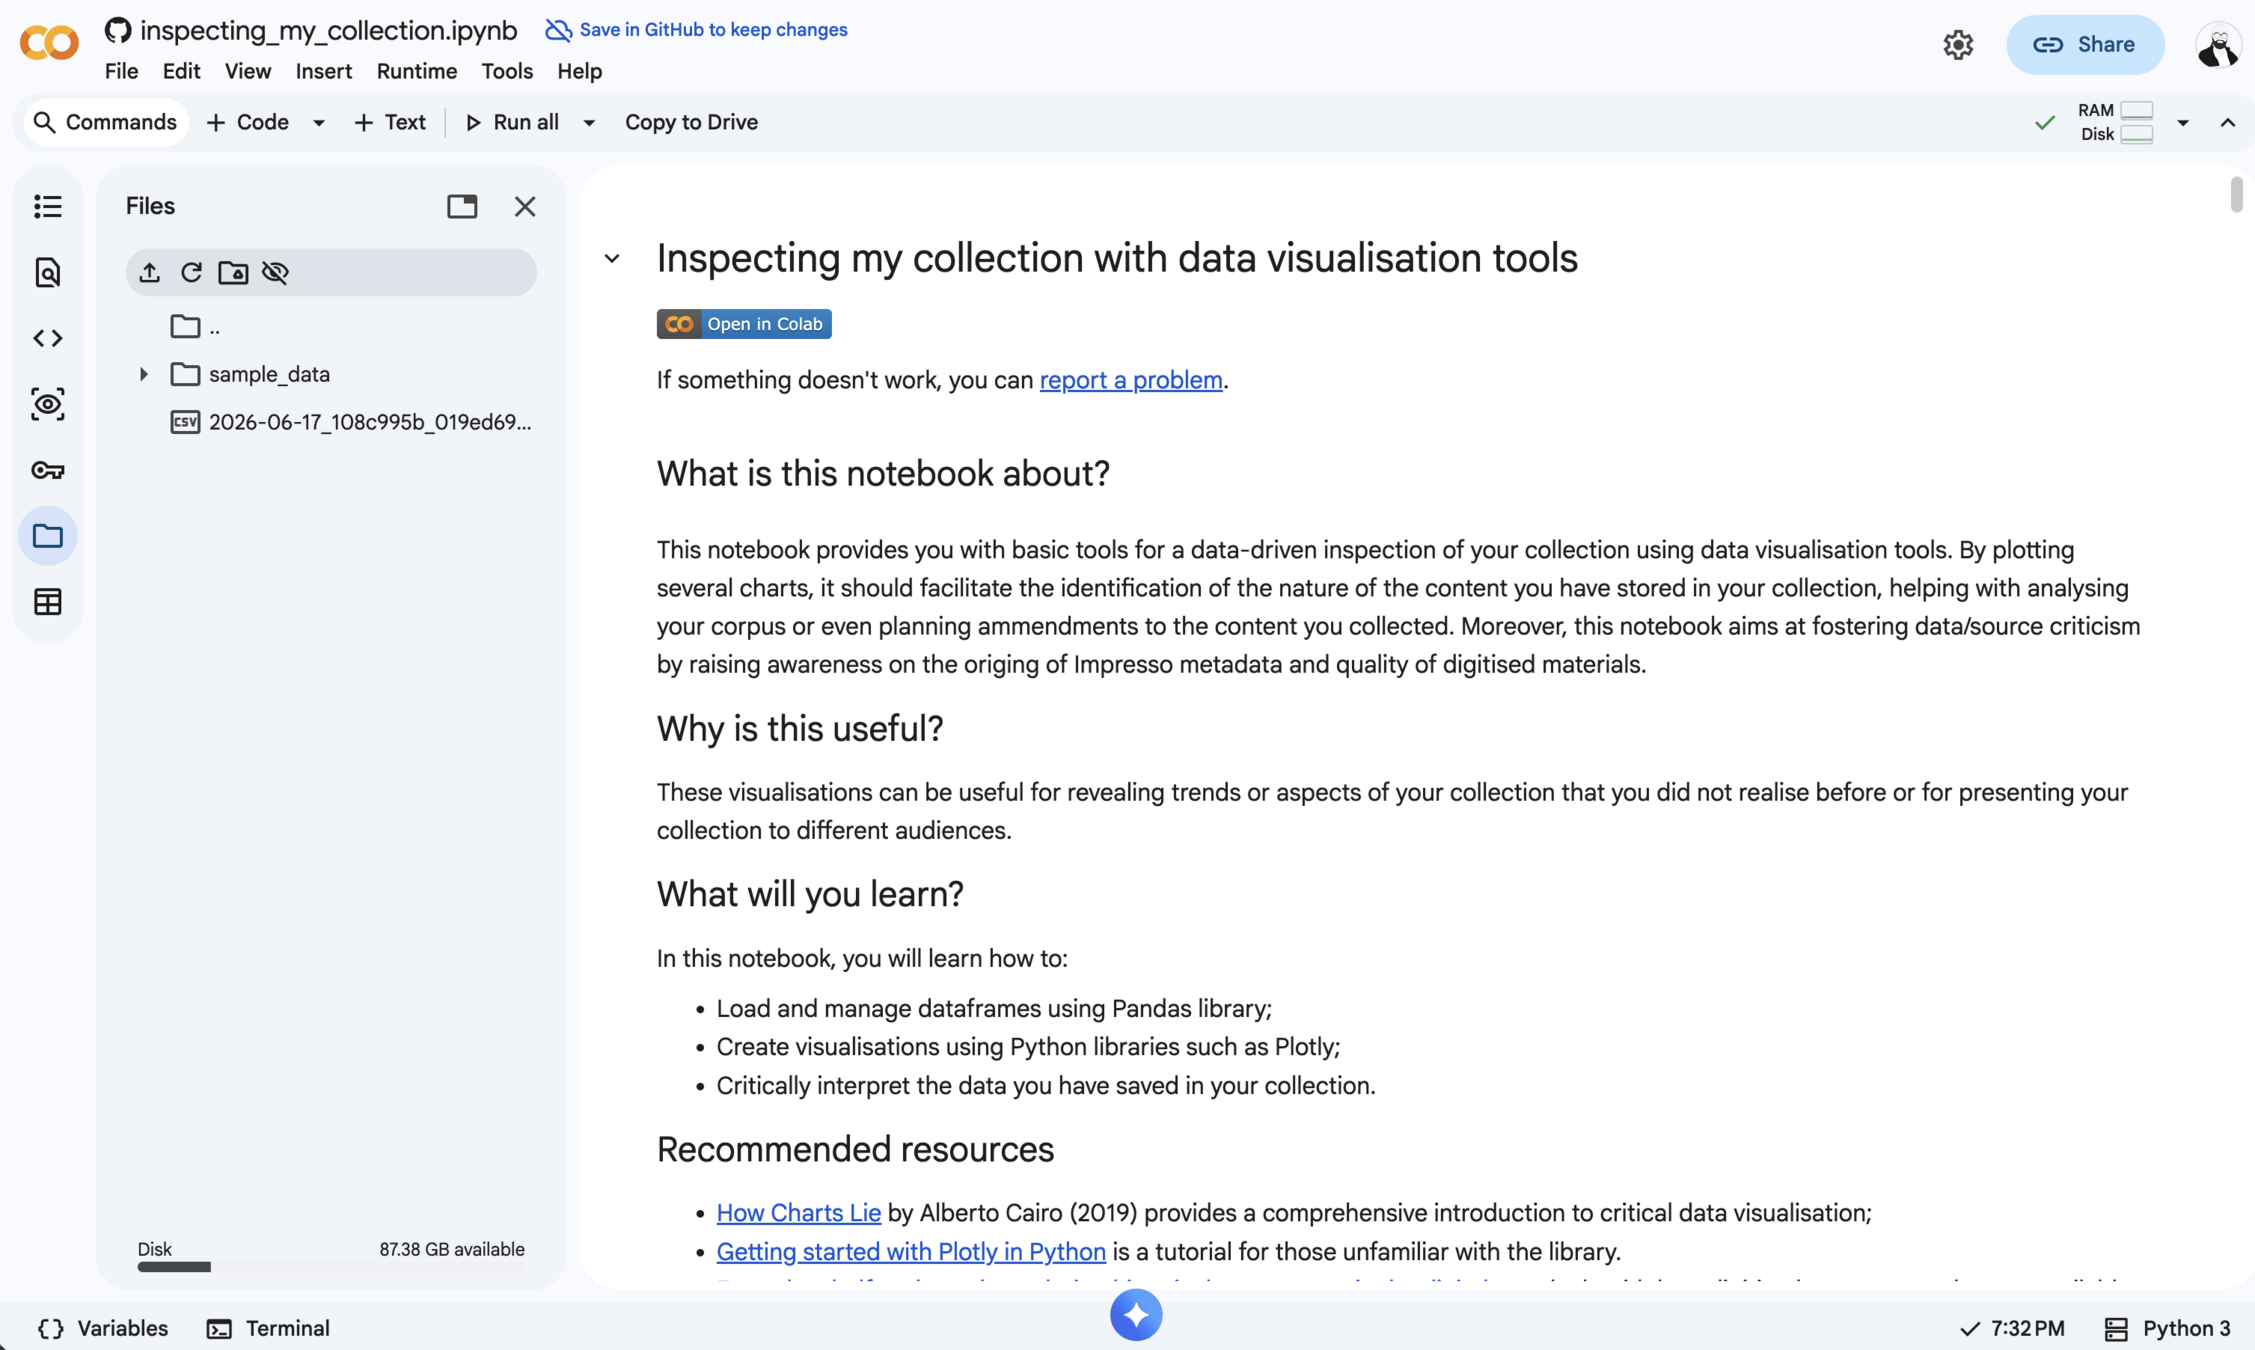
And we upload the CSV file of the collection we created during our previous exploration of radio coverage in the press.
A notebook for statistically describing a collection of sources
Each line of code is commented to guide the user
Here, we load the dataset
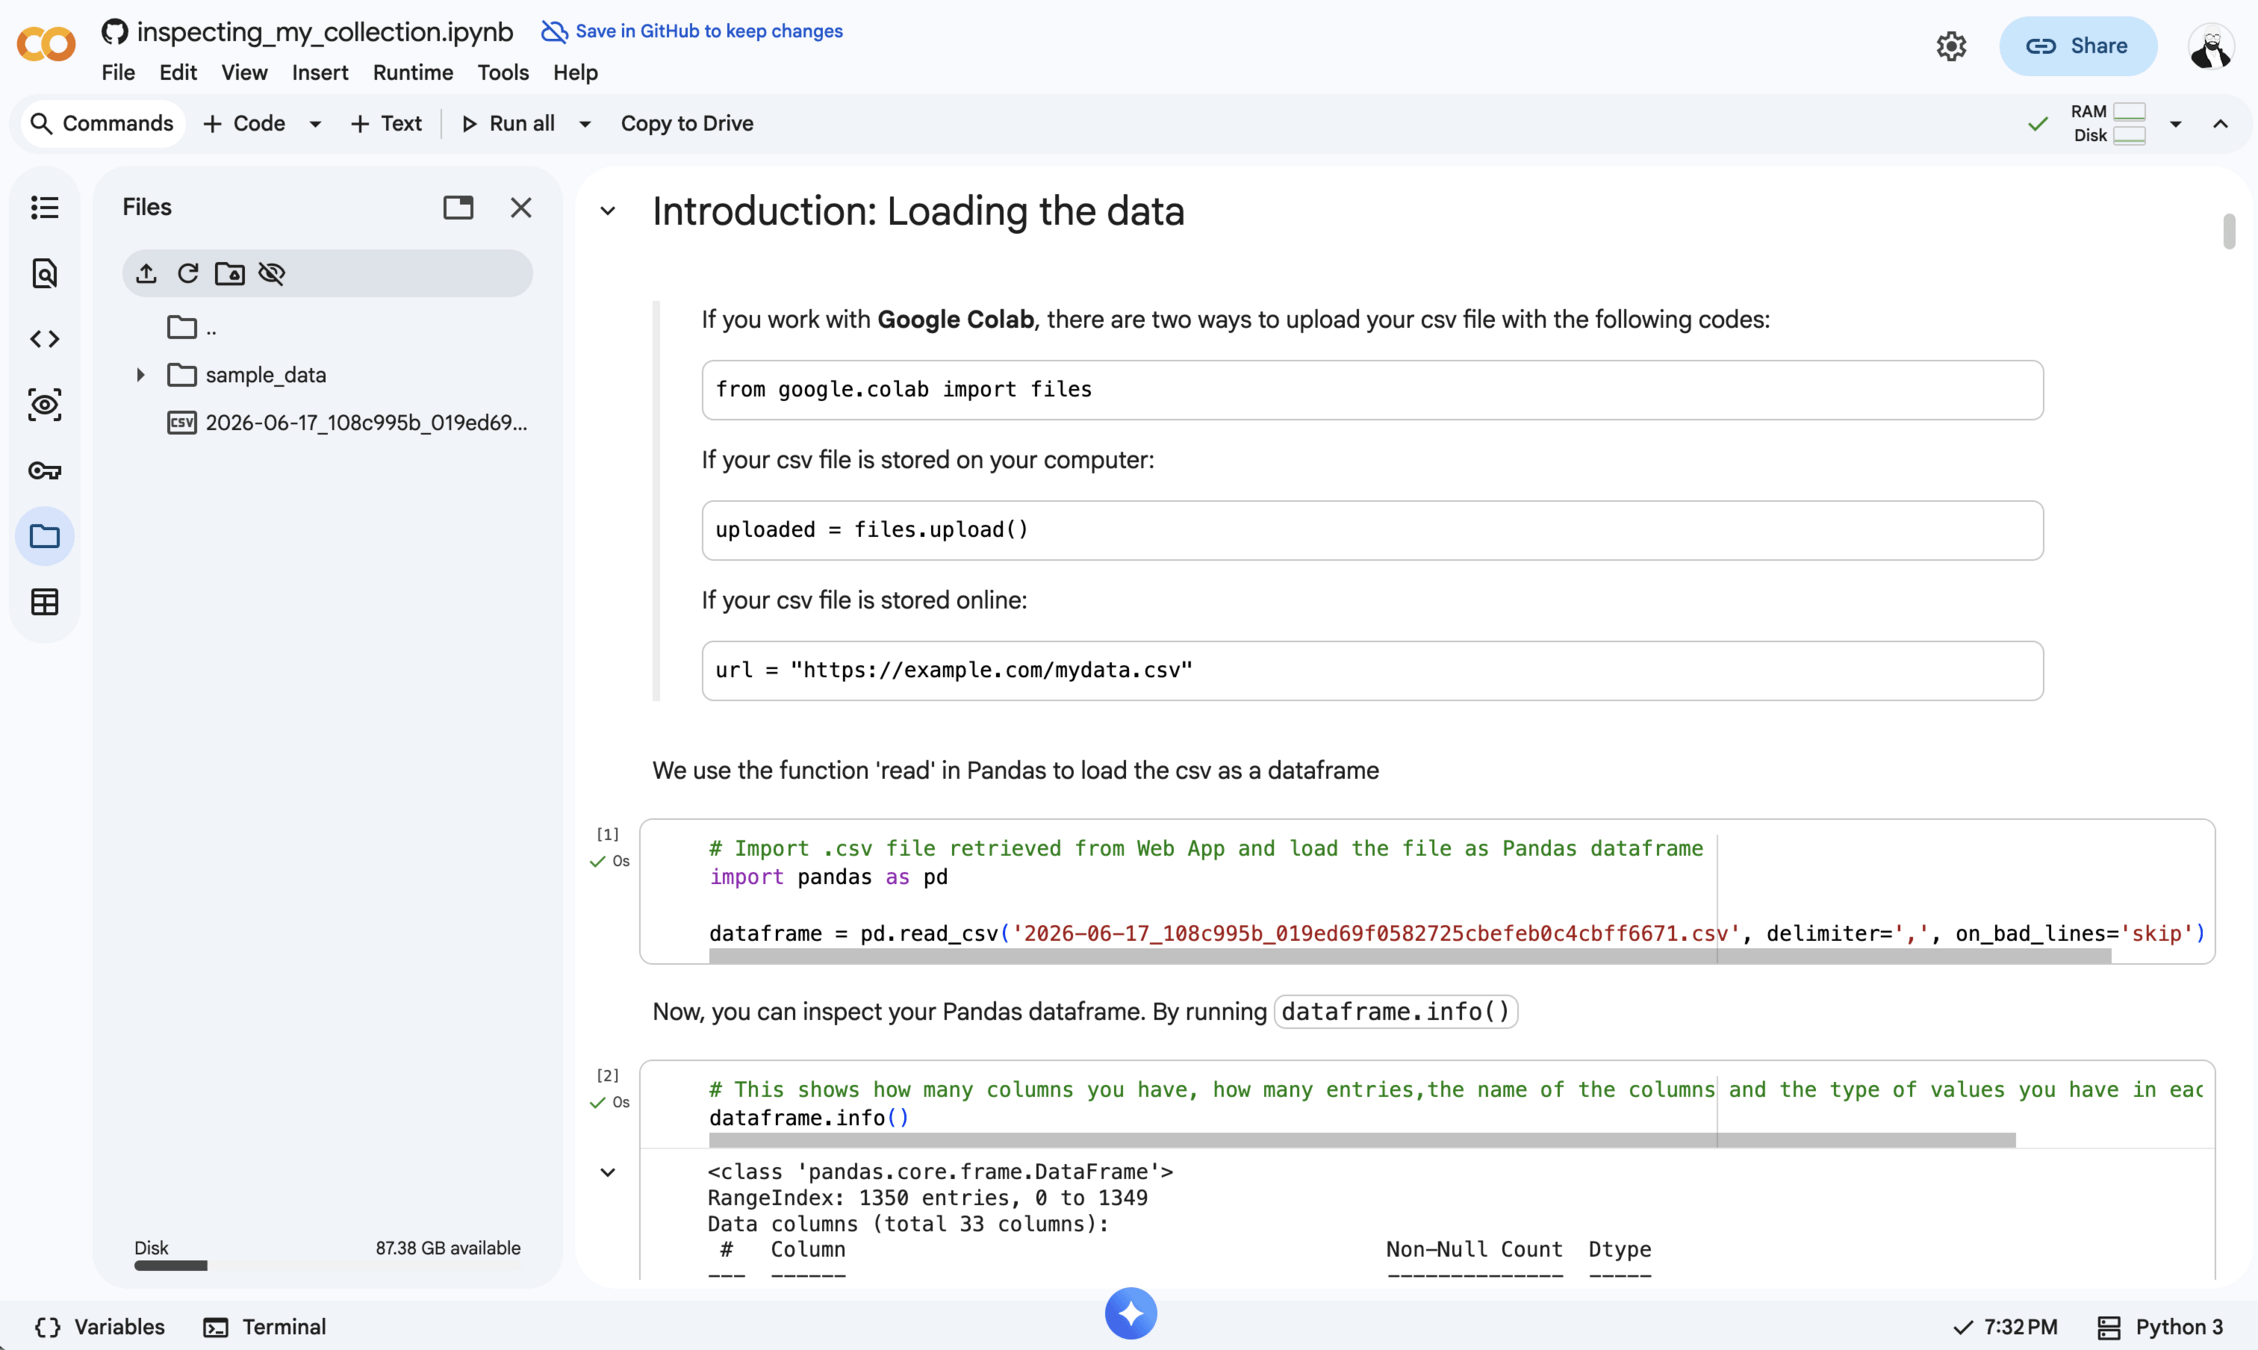
A notebook for statistically describing a collection of sources
This is literally where the two languages meet
In this example, we use the exact collection we created earlier
If there are any questions, Gemini helps you to understand or fix the code
One first way to bridge the gap?
The notebook guides us through the process of creating our first chart.
In this case, a histogram that shows how many articles in our collection come from which newspapers.
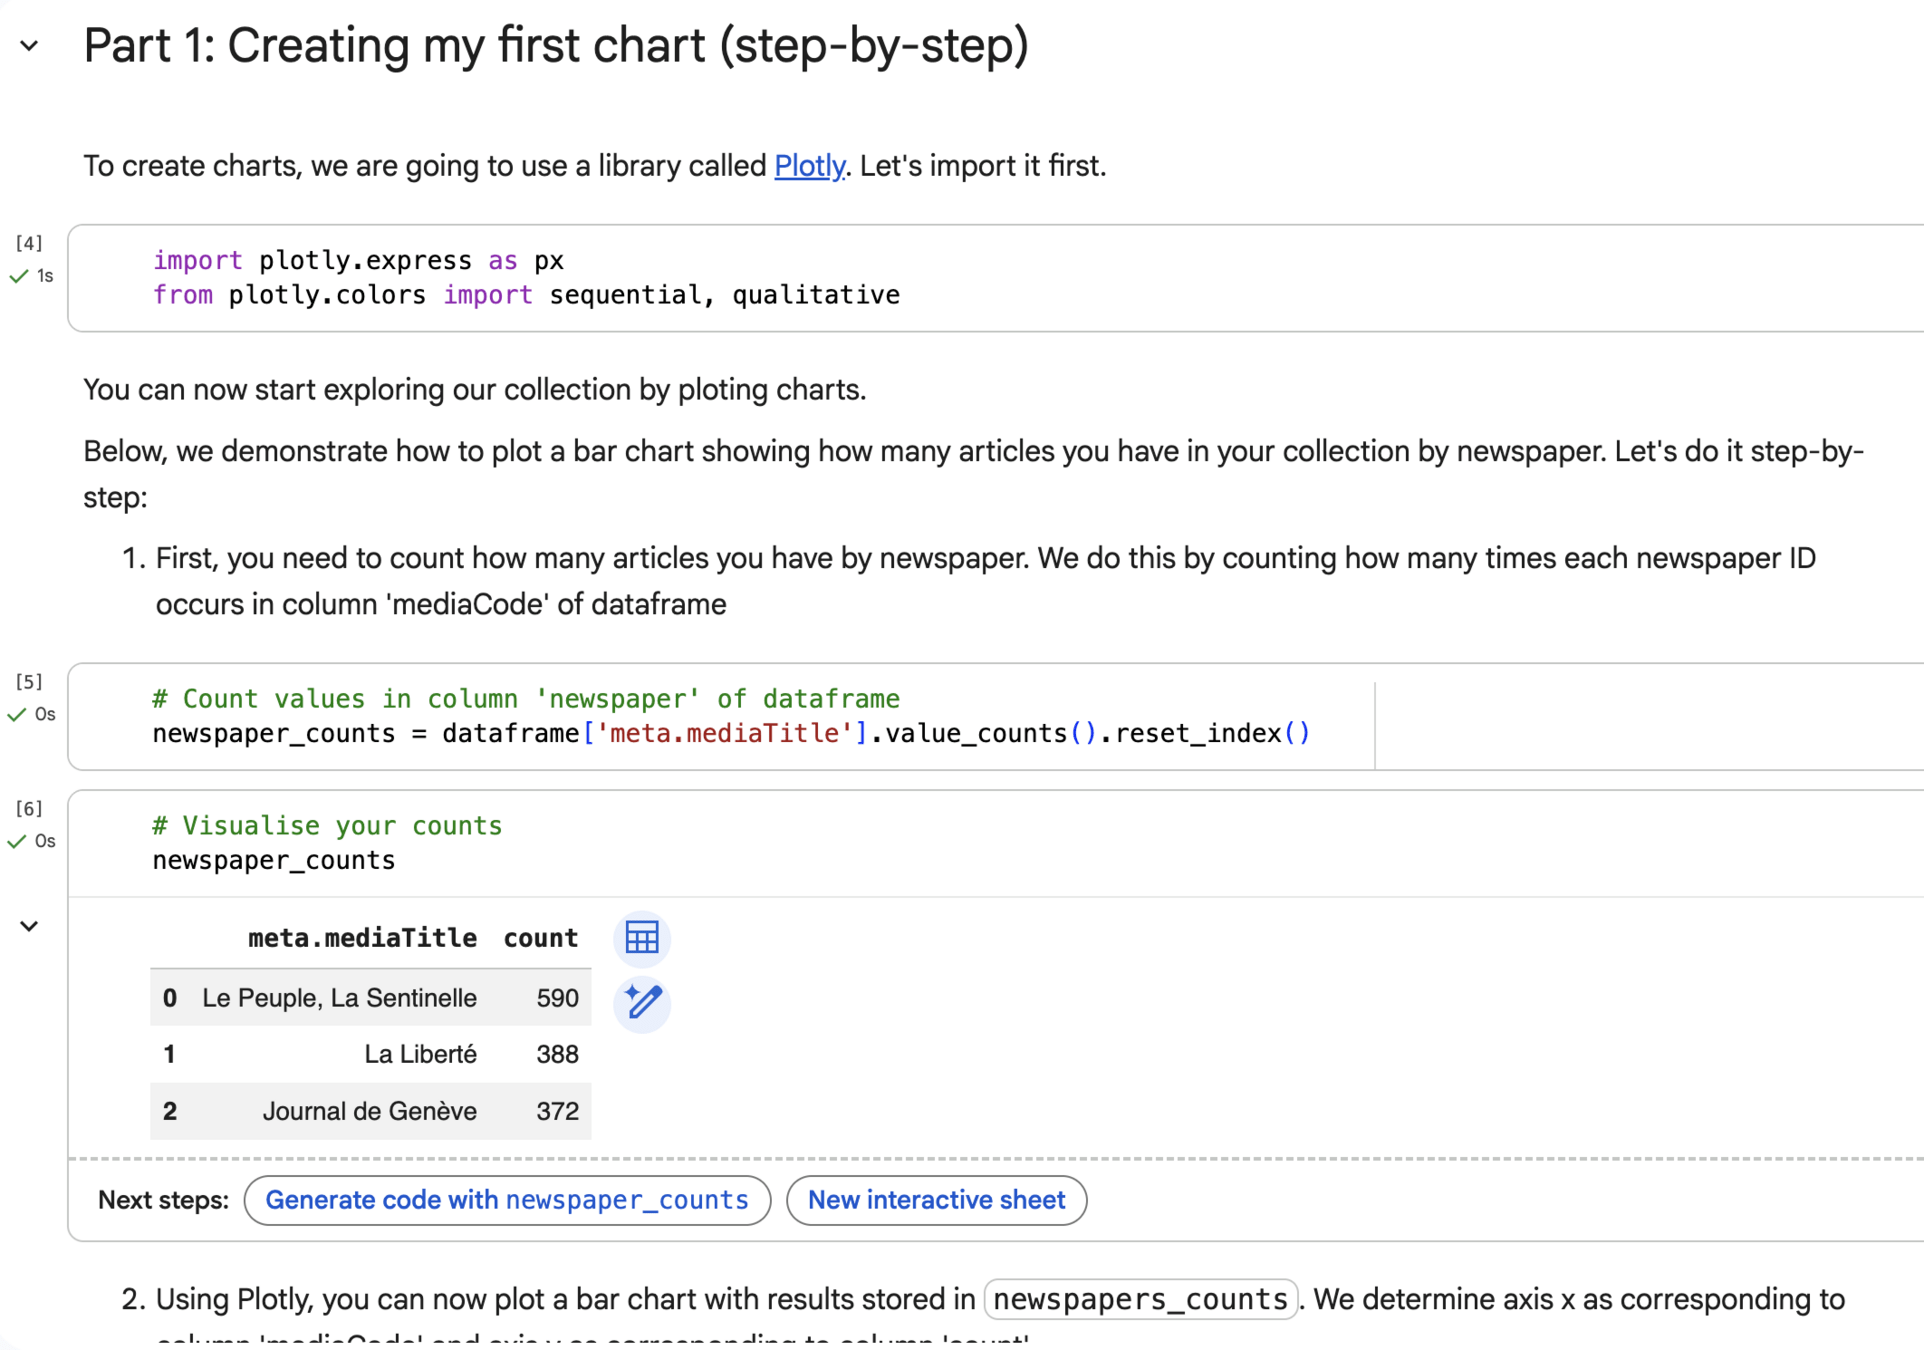
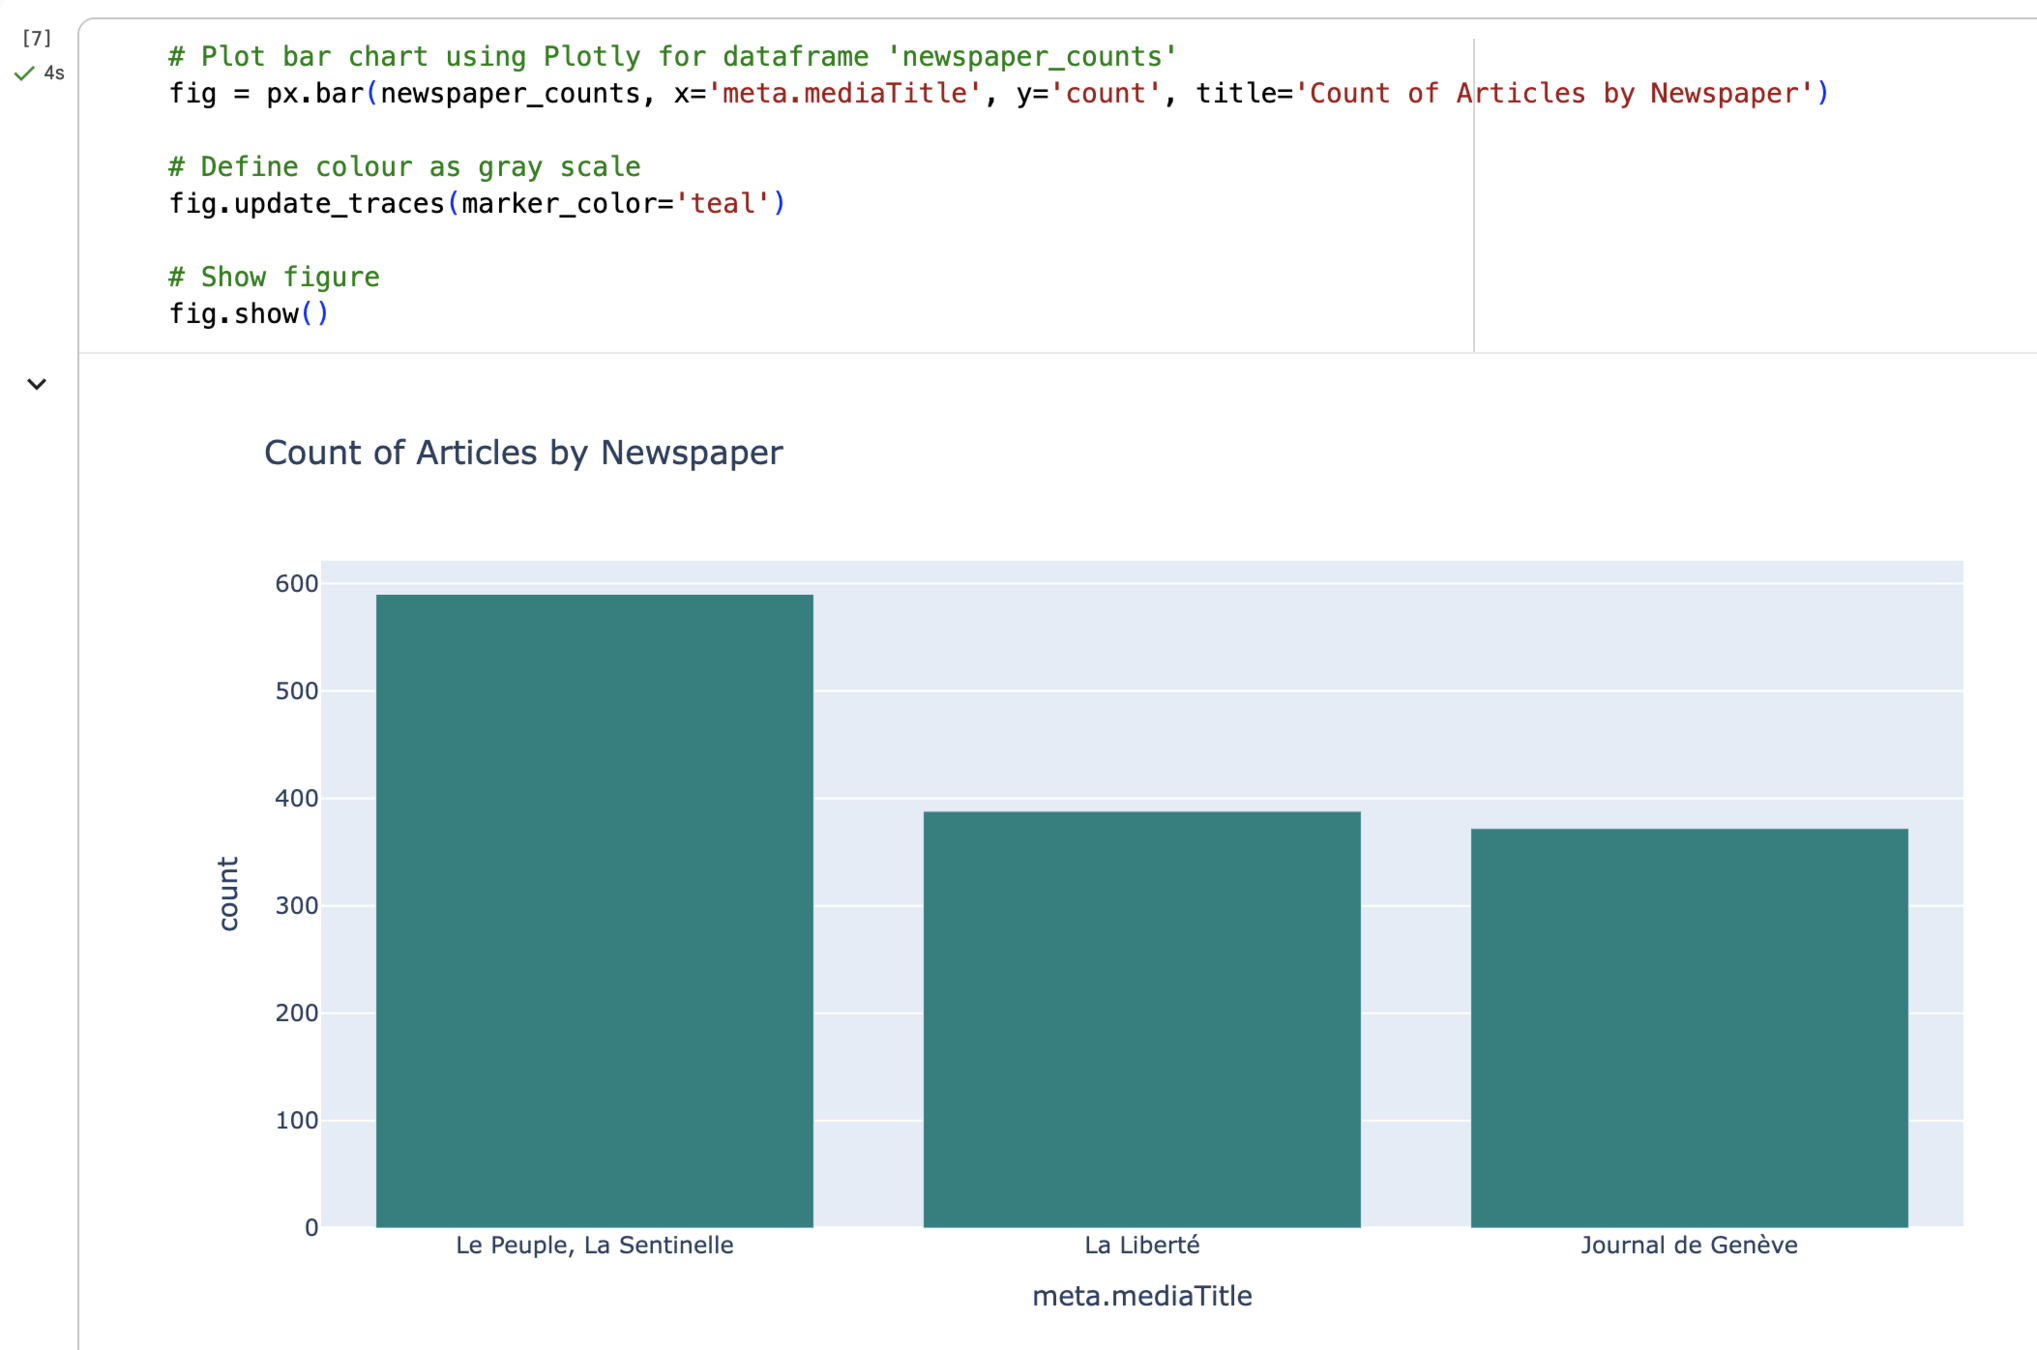
Here, our collection includes articles containing the keyword “radio” from three Swiss newspapers during the 1950s.
A notebook for statistically describing a collection of sources
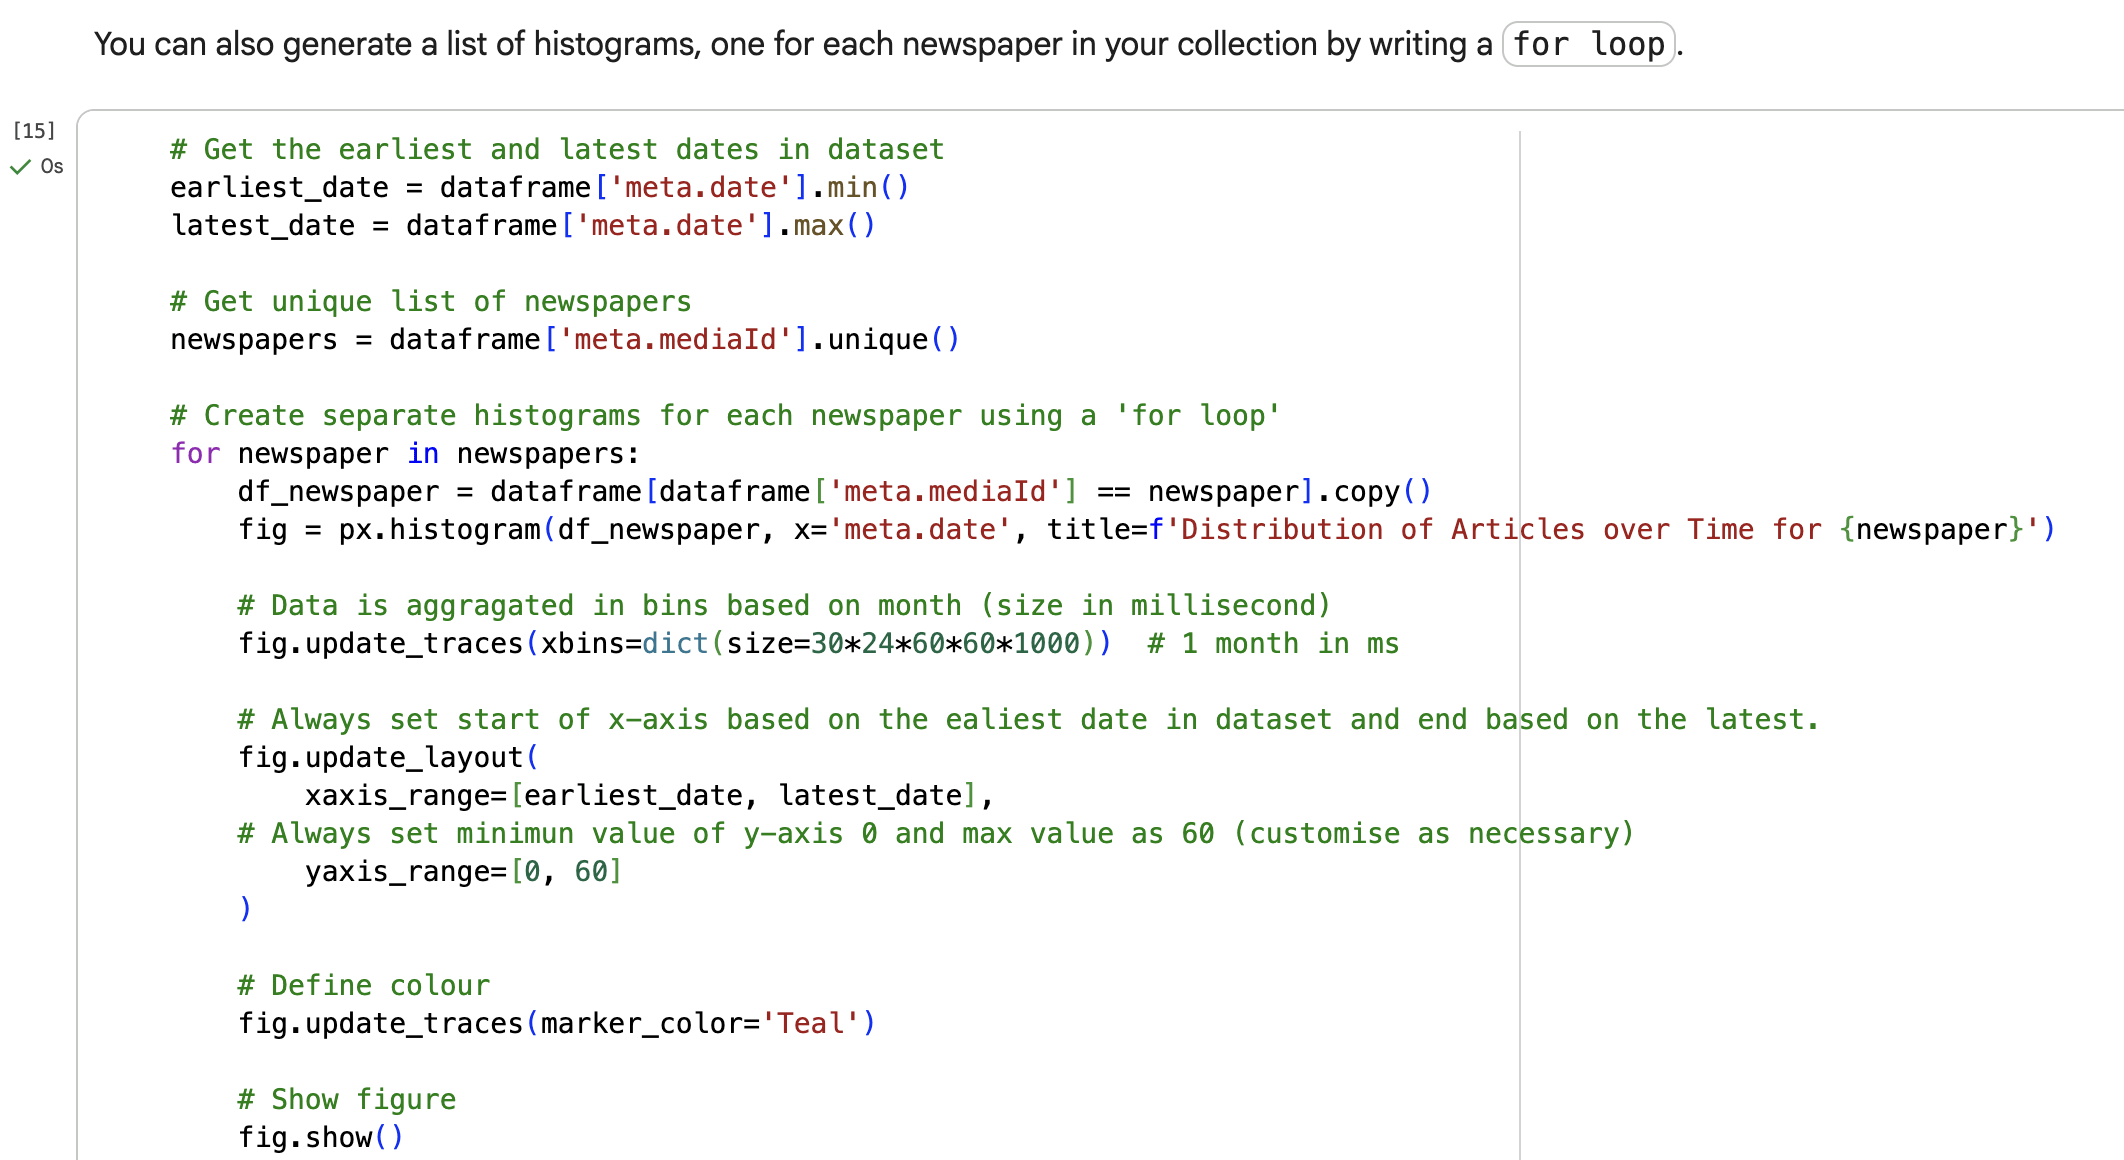
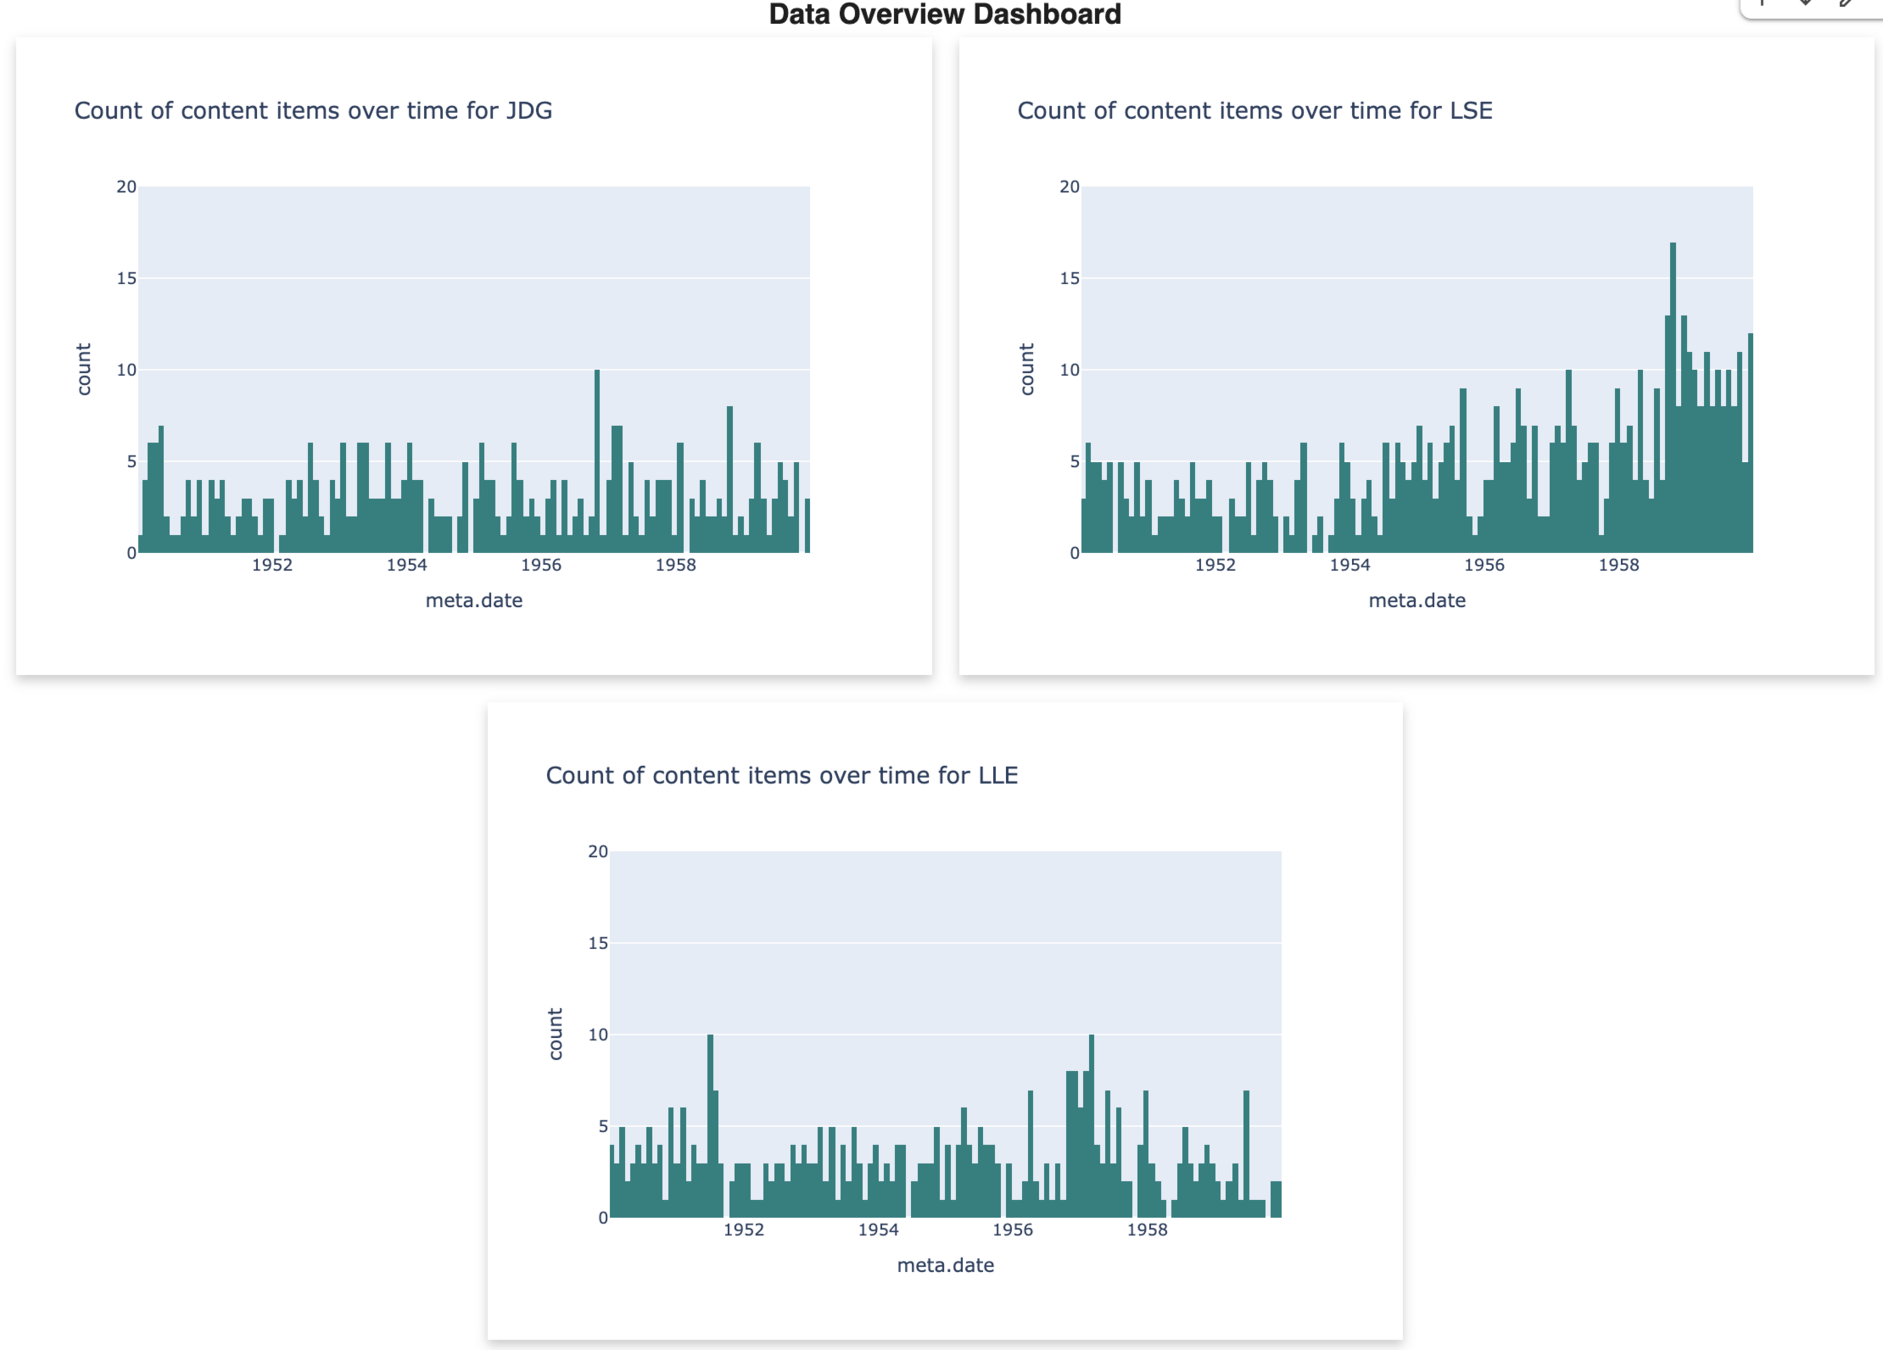
The notebook then generates a timeline of articles, organized by newspaper.
We can see that the number of articles in La Sentinelle (LSE) mentioning the radio increased toward the end of the decade
A notebook for statistically describing a collection of sources
The notebook then guides us through the process of generating other exploratory statistics.
For example, an analysis of article length
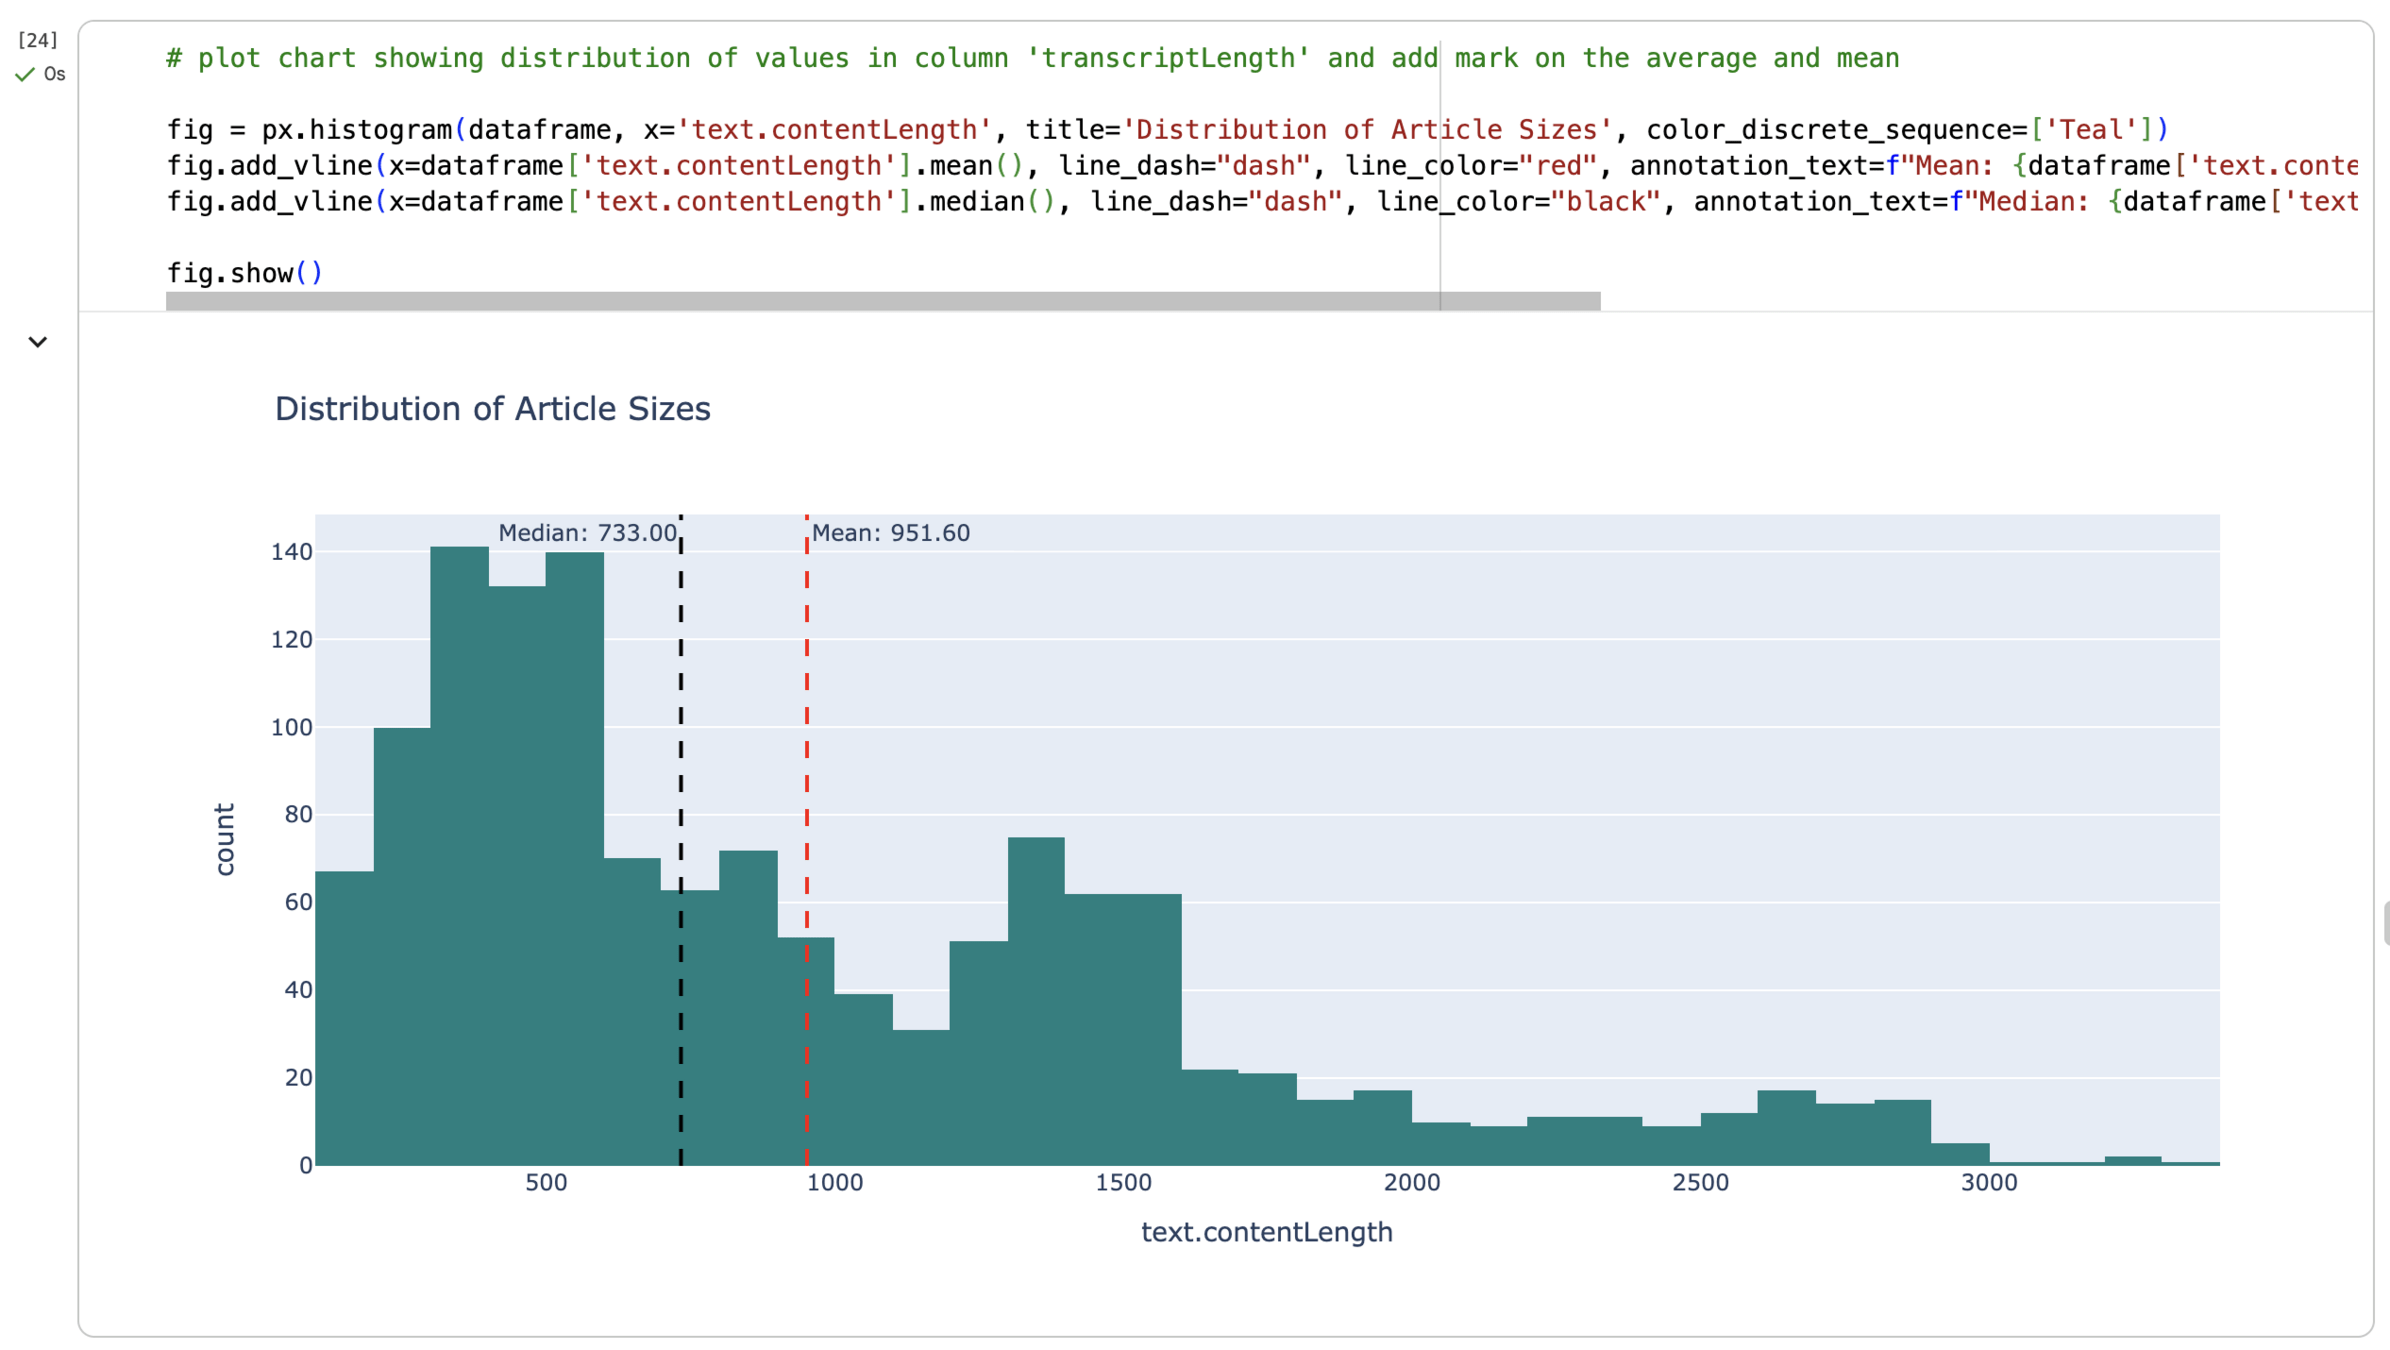
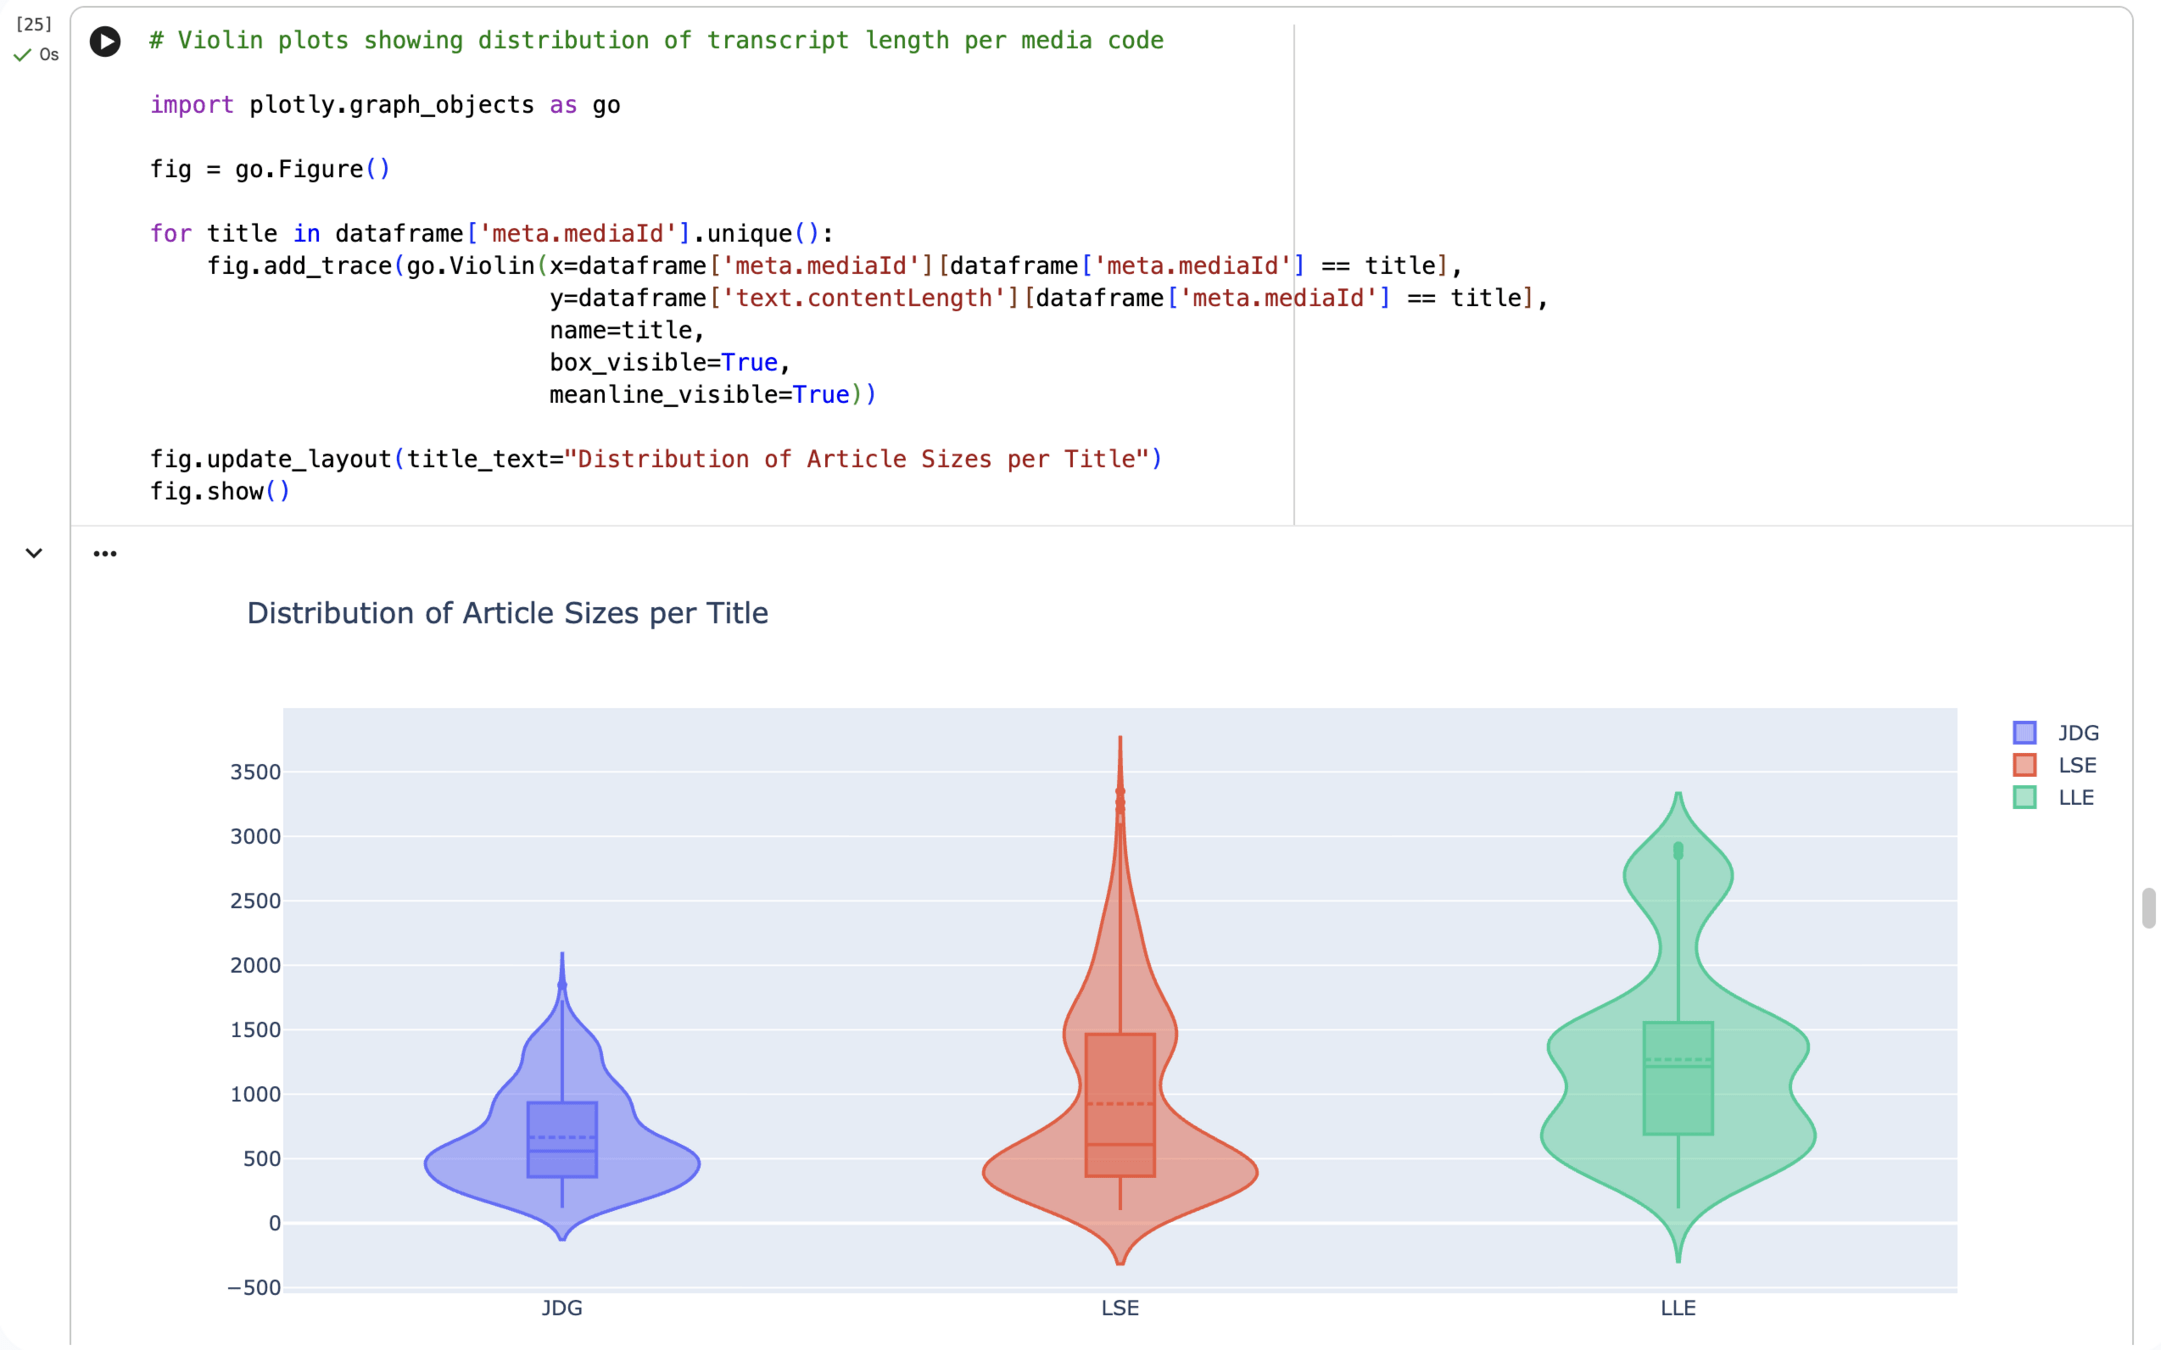
The length of articles varies from one newspaper to another: on average, articles about radio in La Liberté (LLE) are twice as long as those in Le Journal de Genève (JDG).
A notebook for statistically describing a collection of sources
Notebook 2: Network of named entities
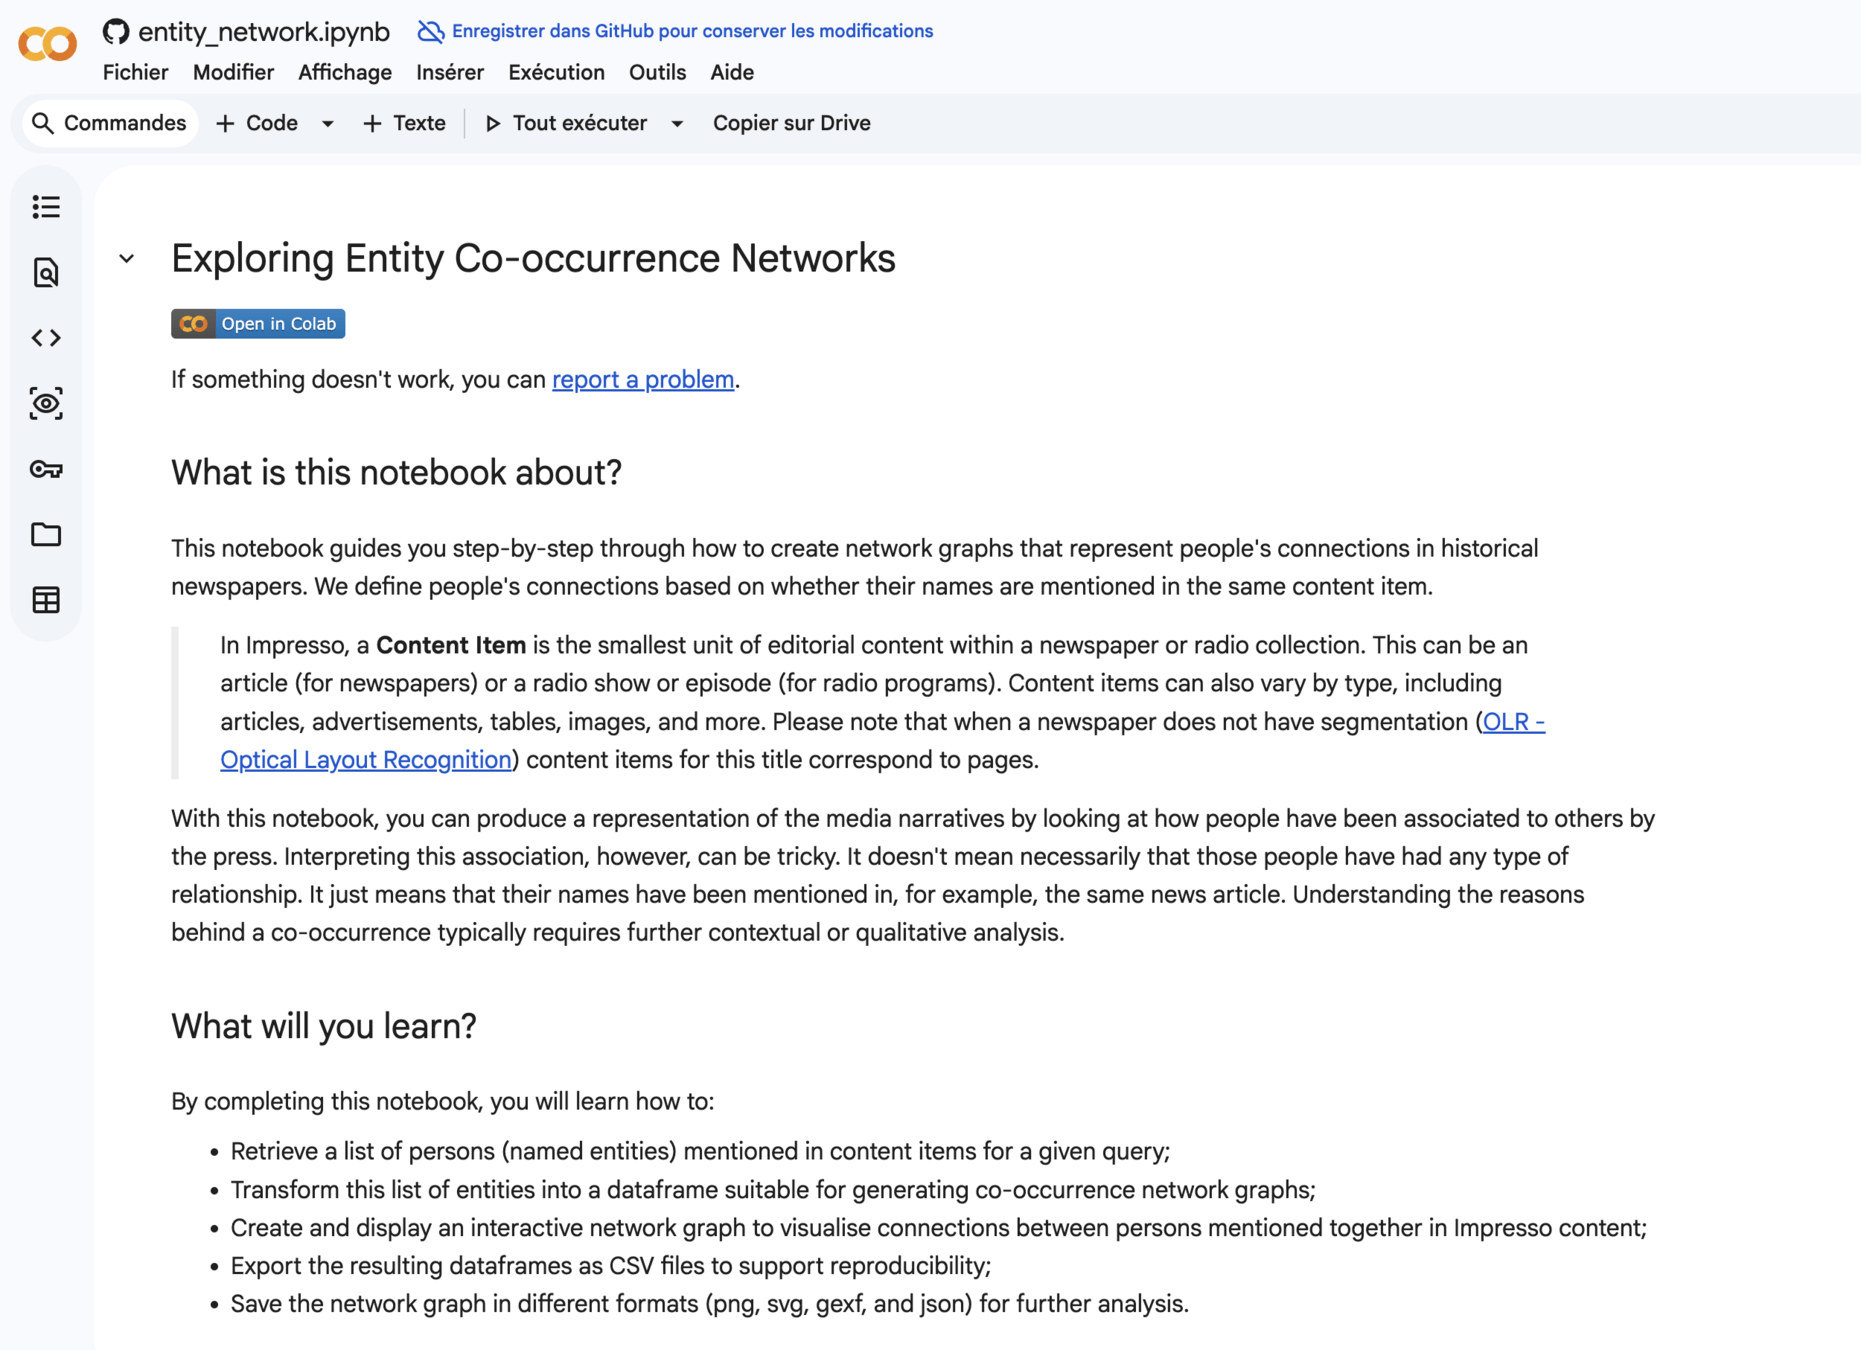
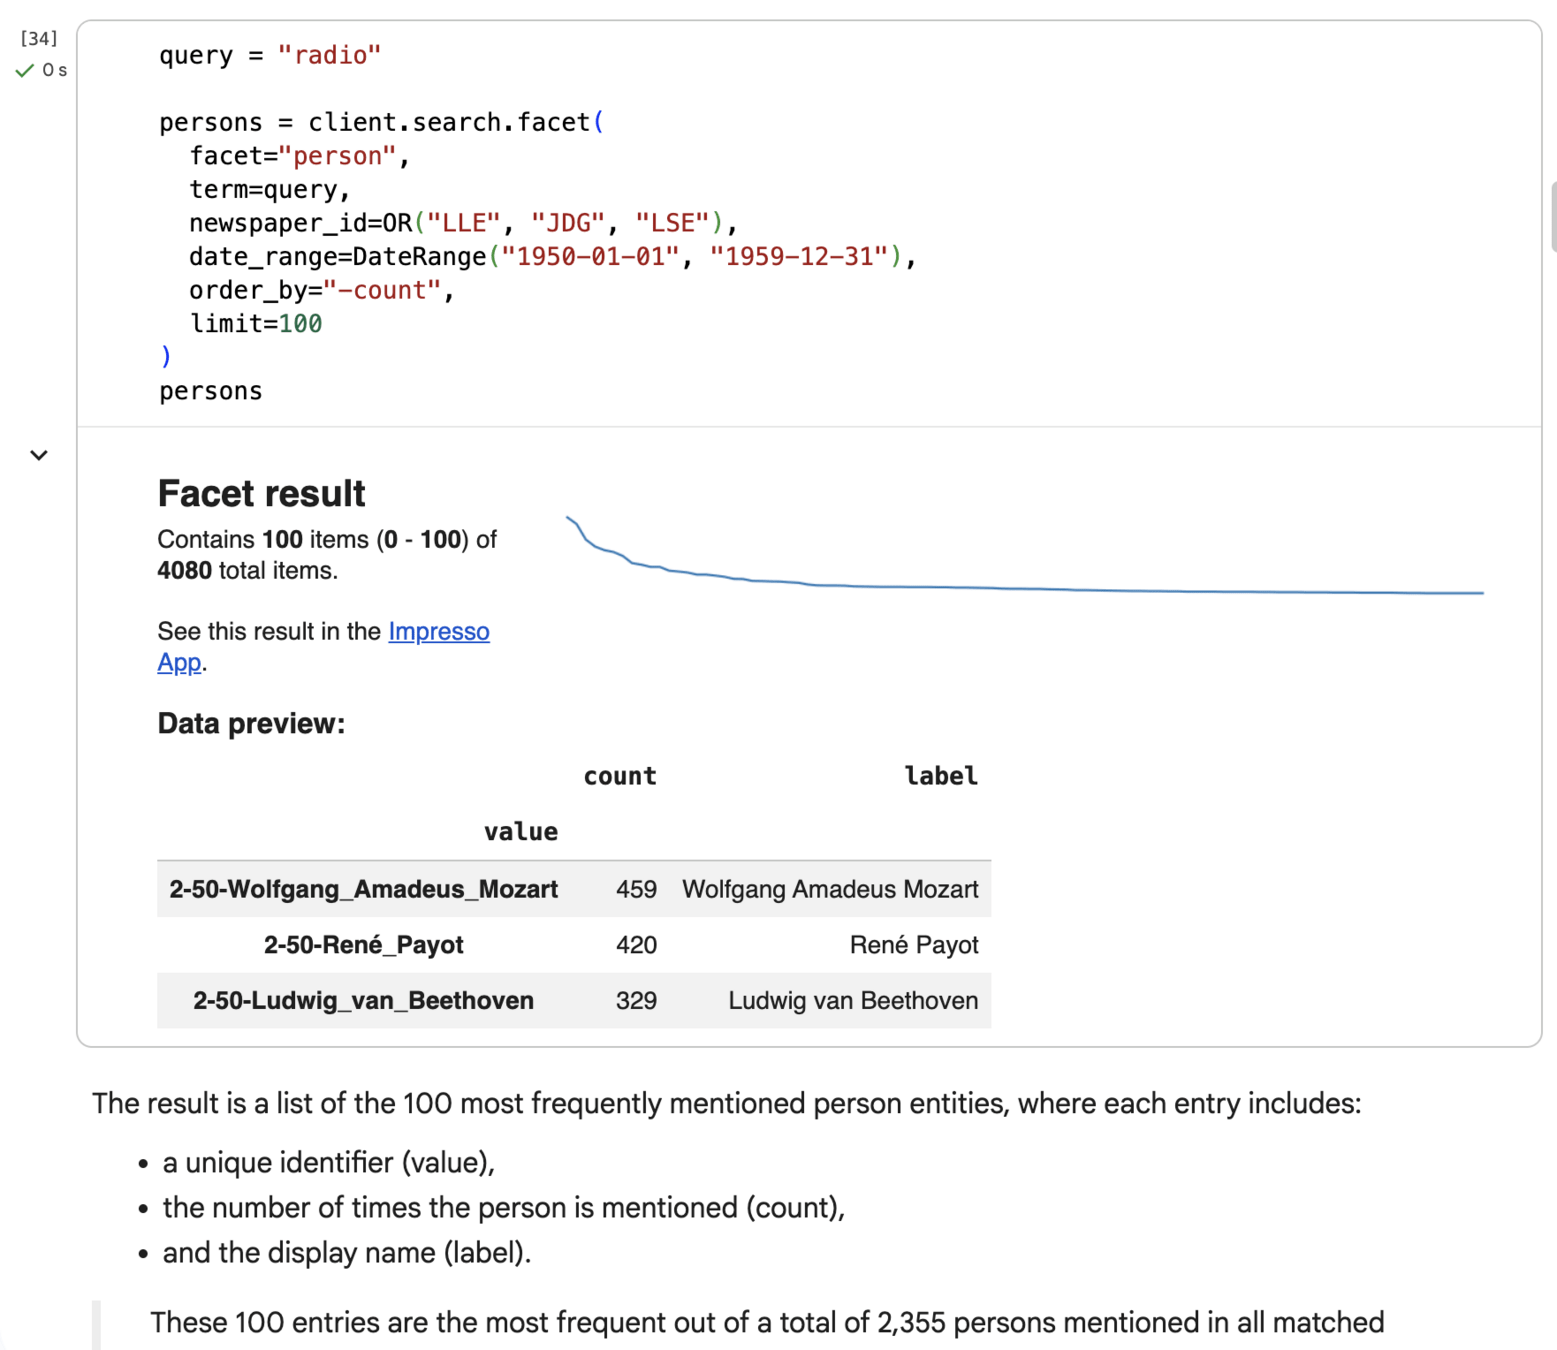
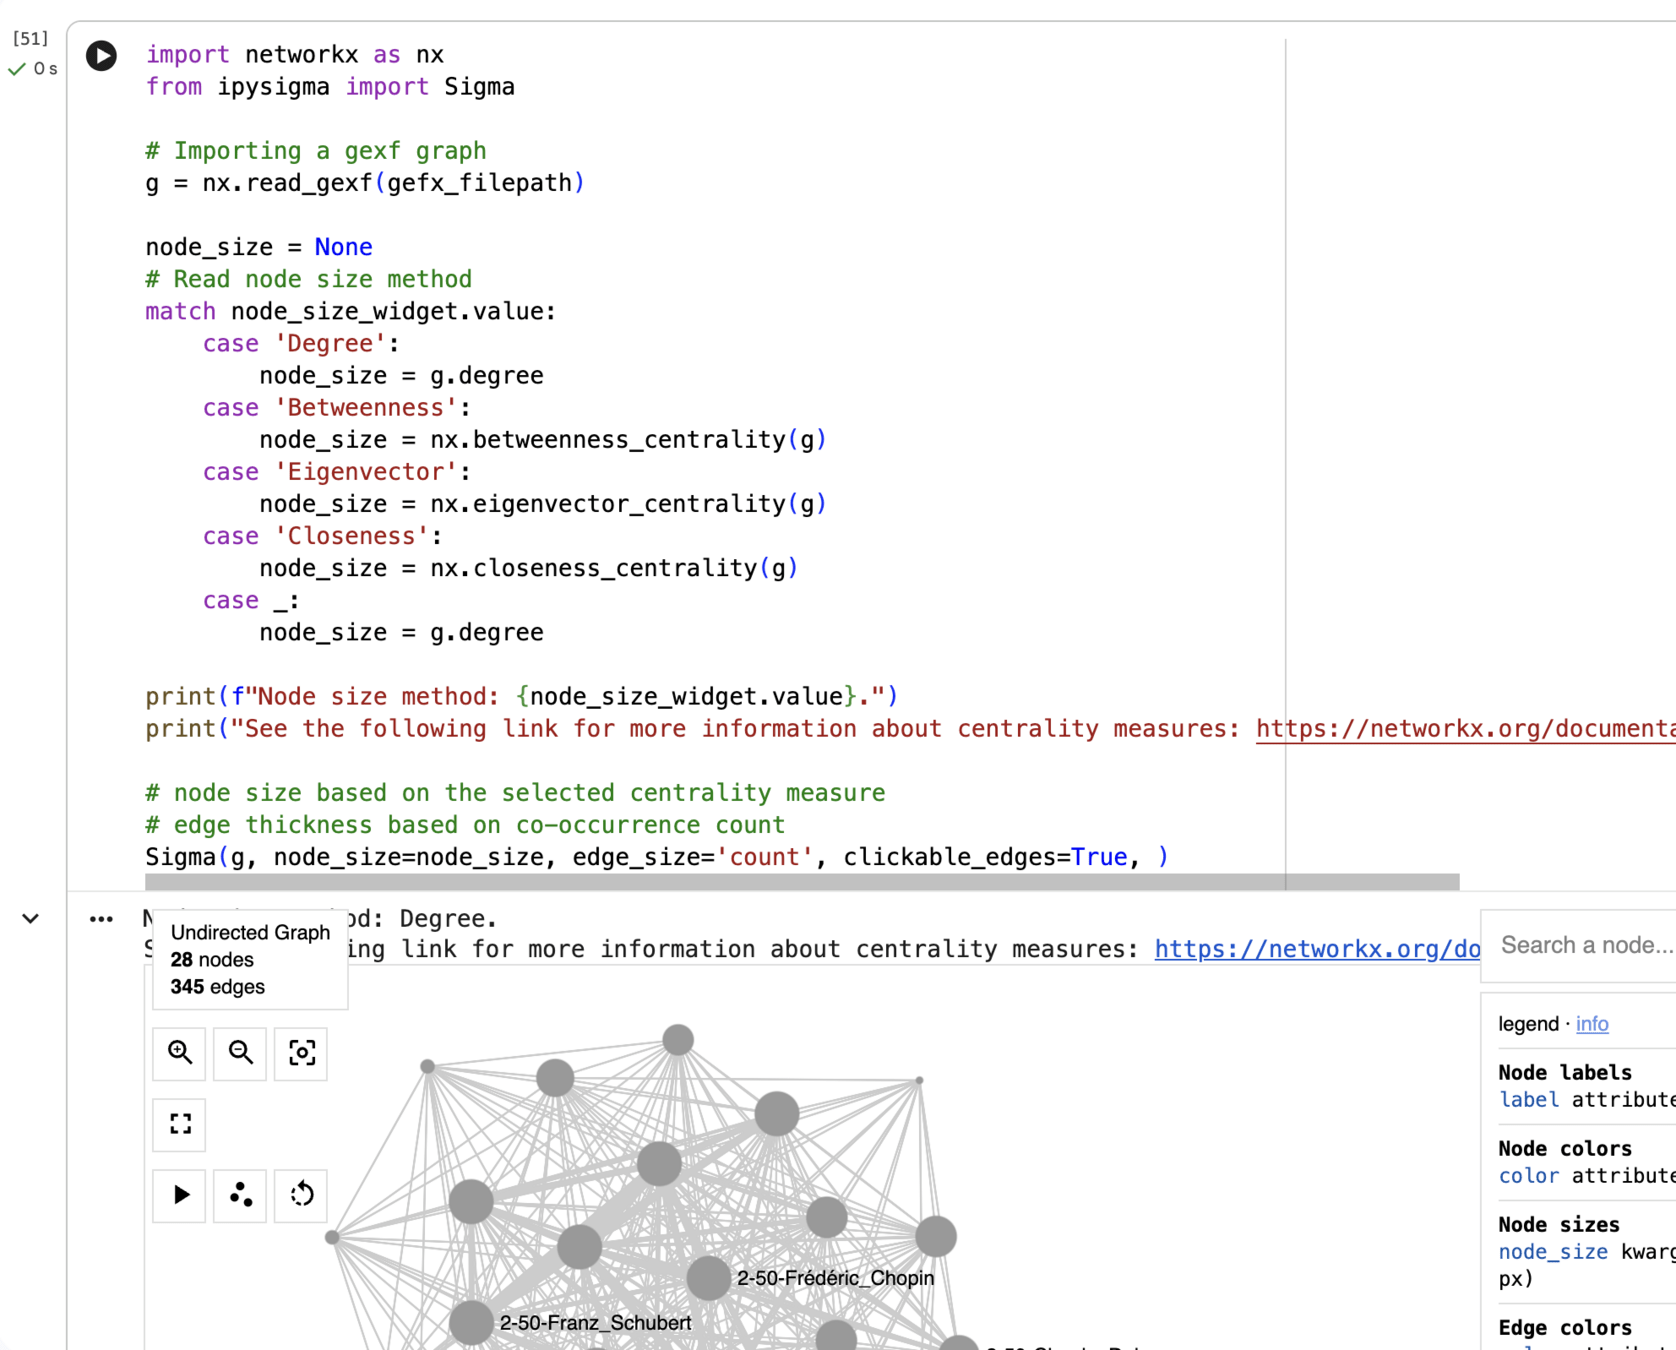
This second notebook helps highlight the main named entities that appear together in the articles
No need to create a collection beforehand; the notebook will connect to the Impresso data on its own.
So we can run a query directly in the notebook. For example, to find the 100 people who appear most frequently in articles containing the word “radio” in the three newspapers covered by our previous analyses for the same period.
Notebook 2: Network of named entities
It generates a network that shows how often the most frequently mentioned people appear in the same press articles.
This network can then be exported and viewed more clearly in software such as Gephi
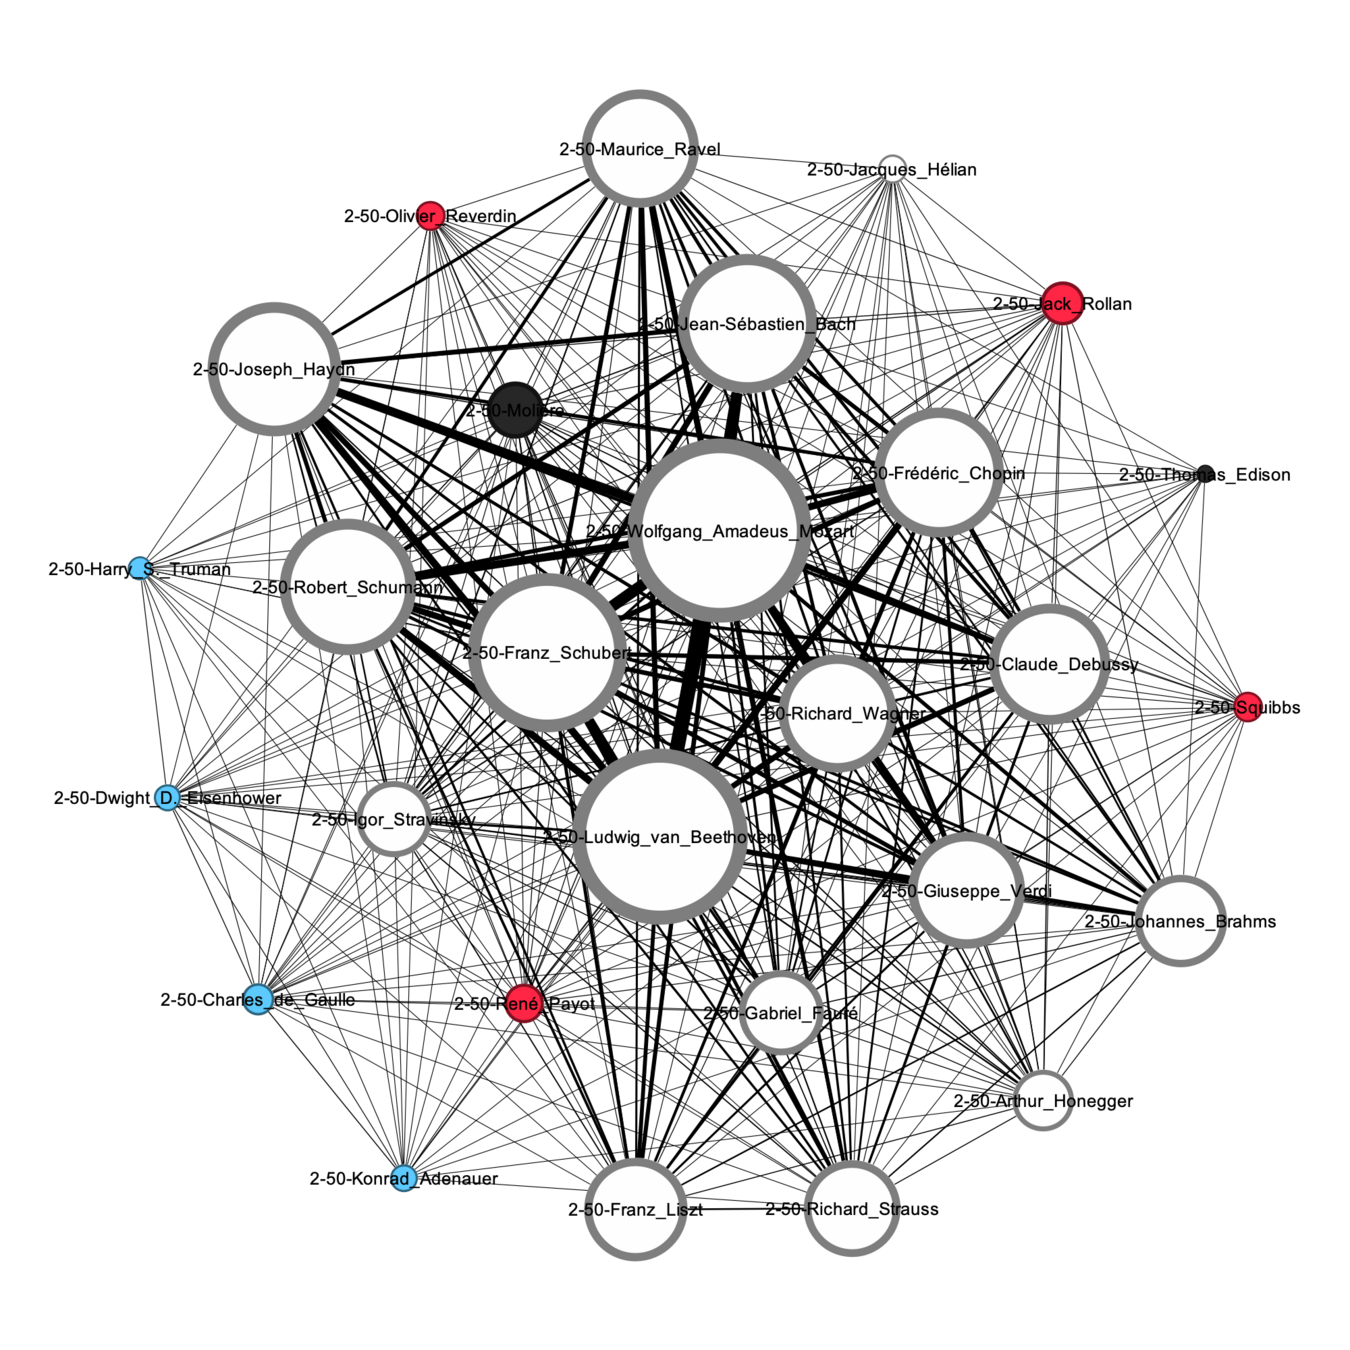
In the case of the "radio" keyword, the entities are very strongly influenced by the music programming. Composers (in white) are much more prominent than political figures (in blue) or media personalities (in red).
Notebook 3: Map of locations
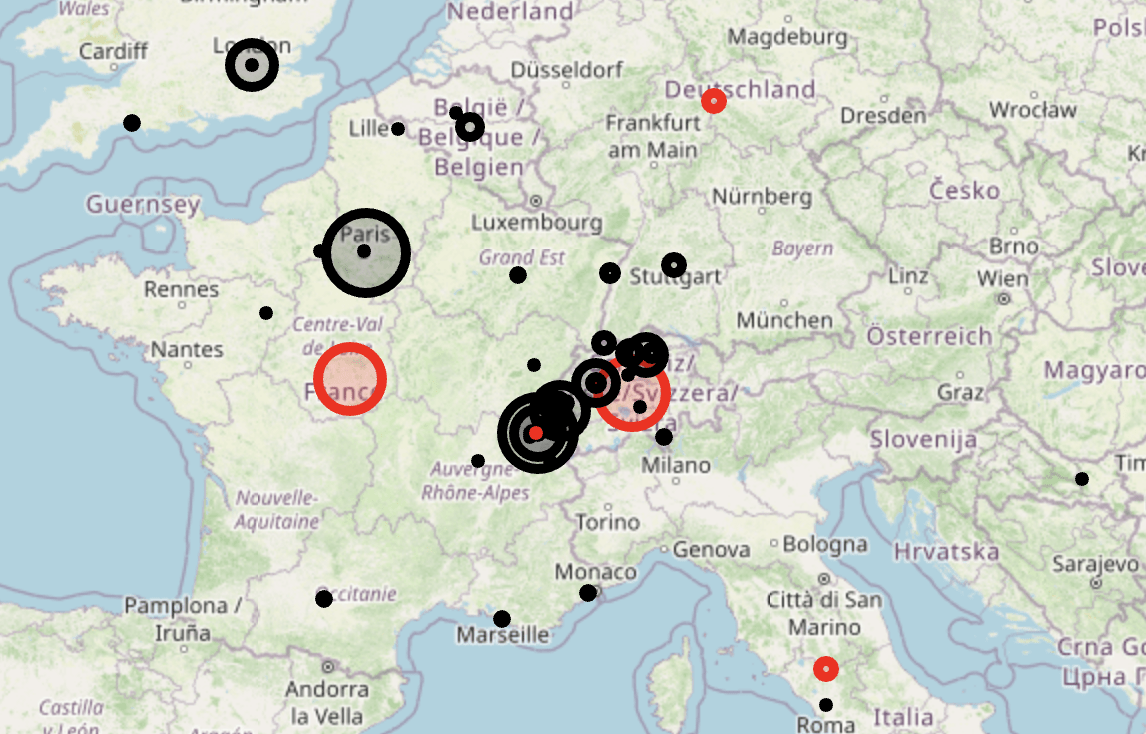
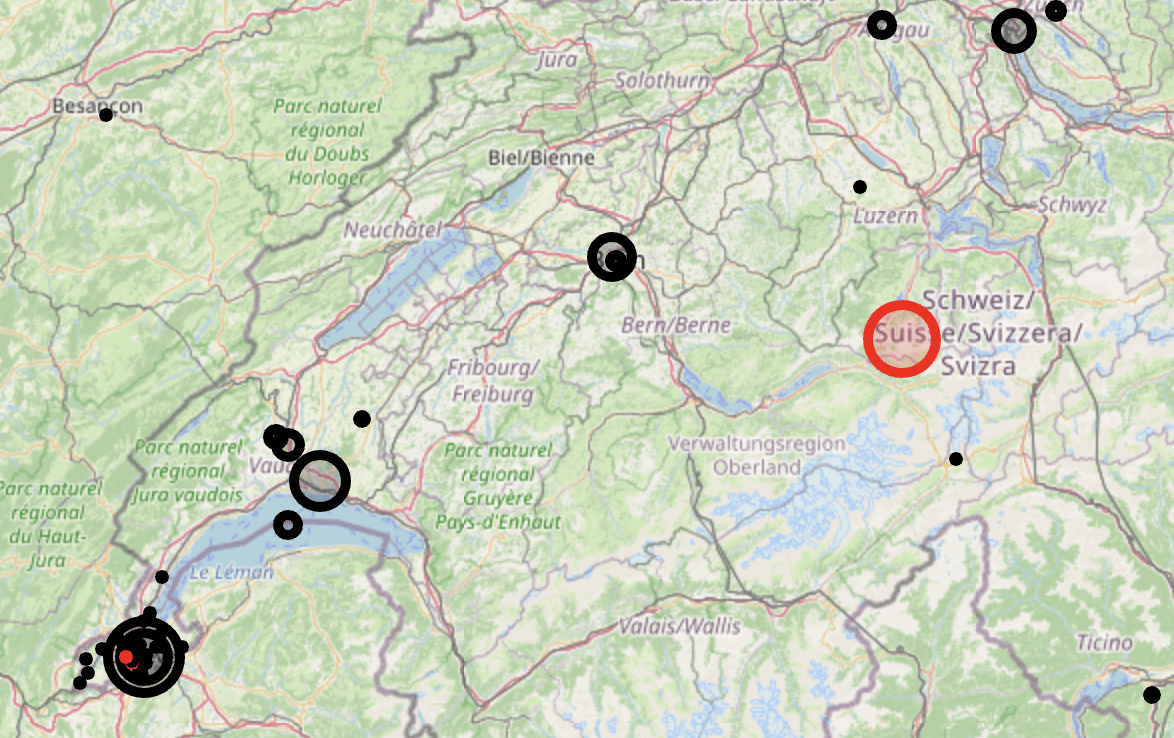
This third notebook will retrieve the geographic coordinates of the locations mentioned in the articles and generate a map.
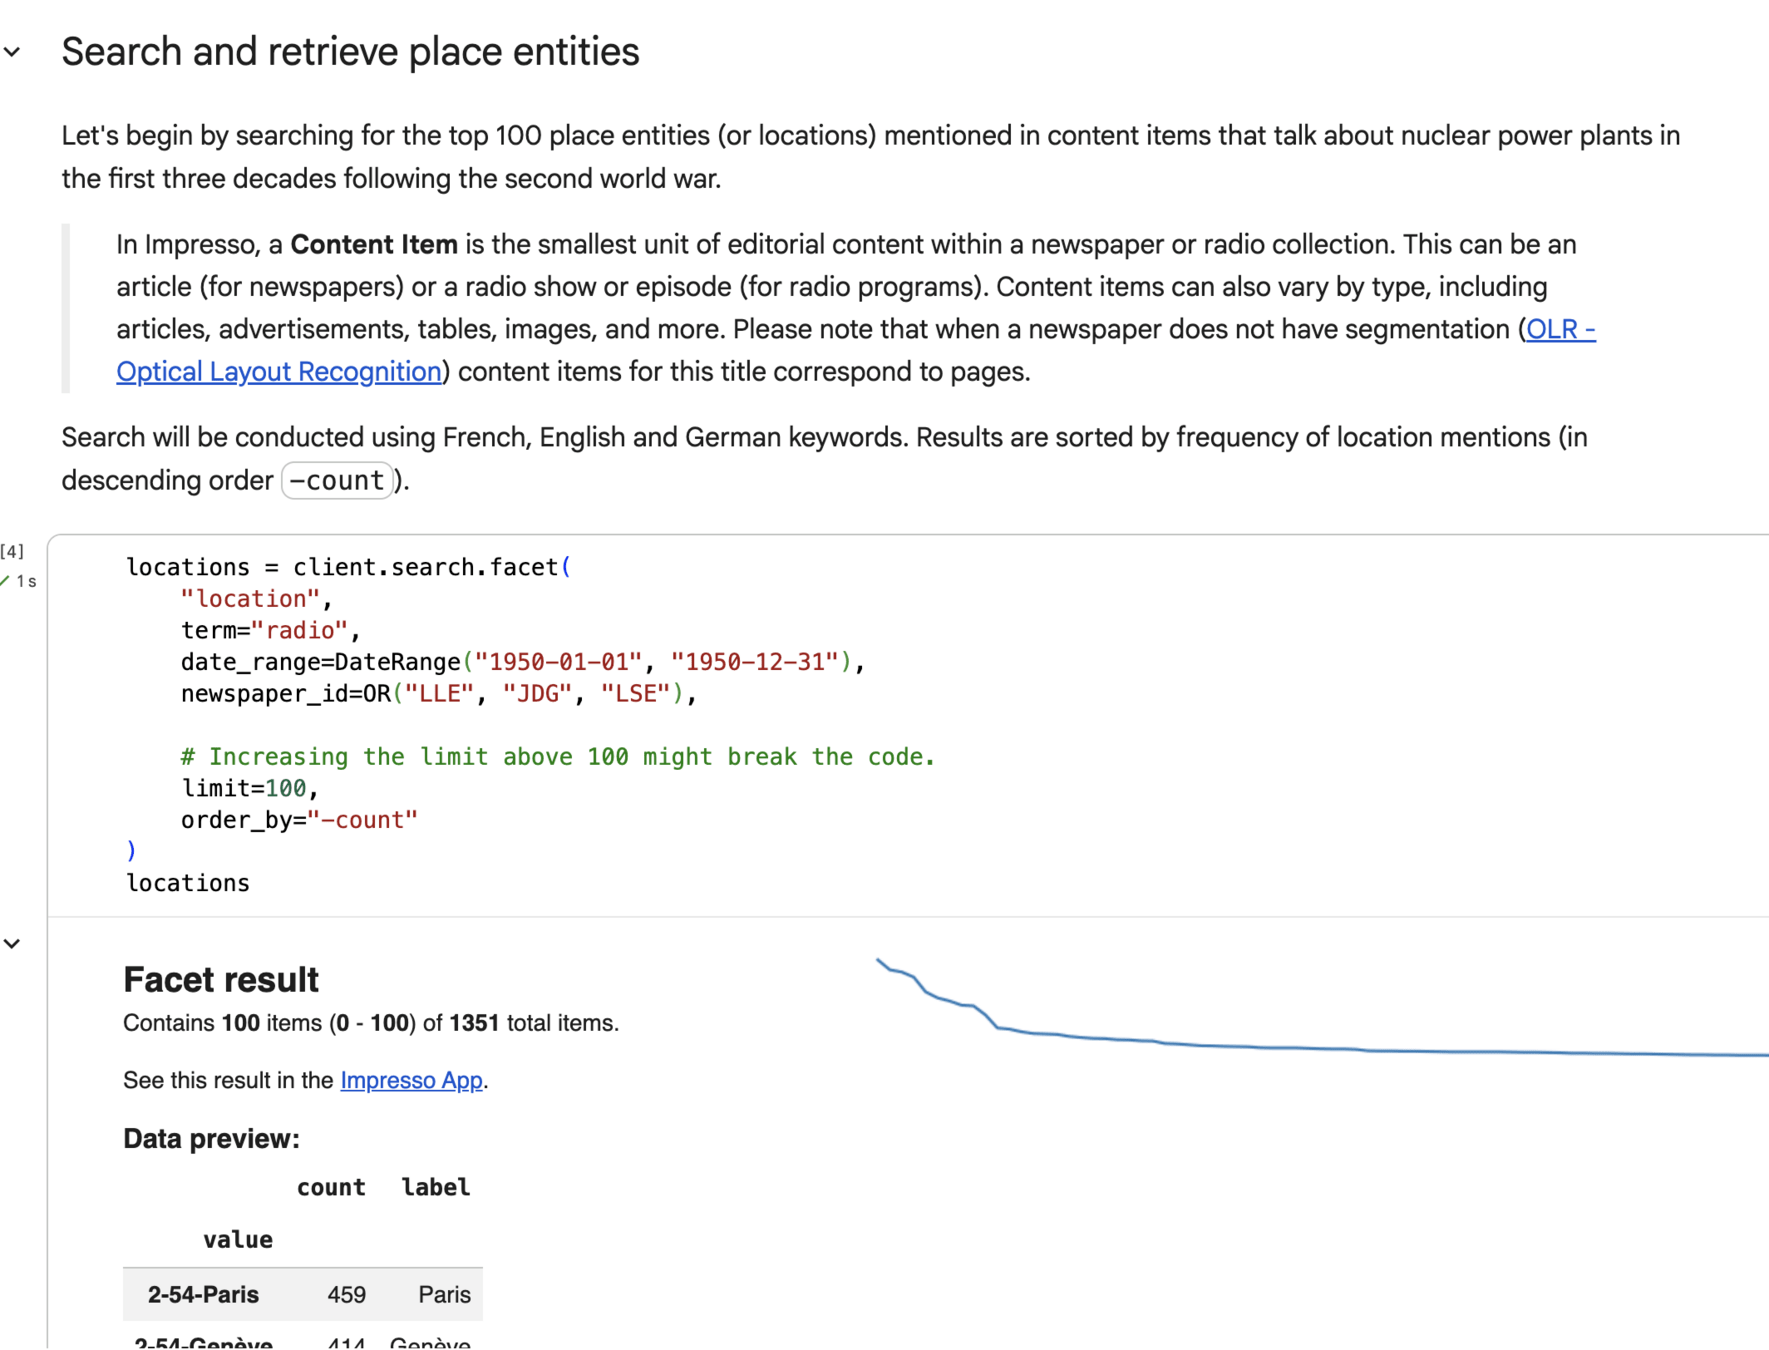
Just like in the previous notebook, we run the query directly here.
Next, the top 100 results are geolocated by querying Wikidata.
Notebook 3: Map of locations
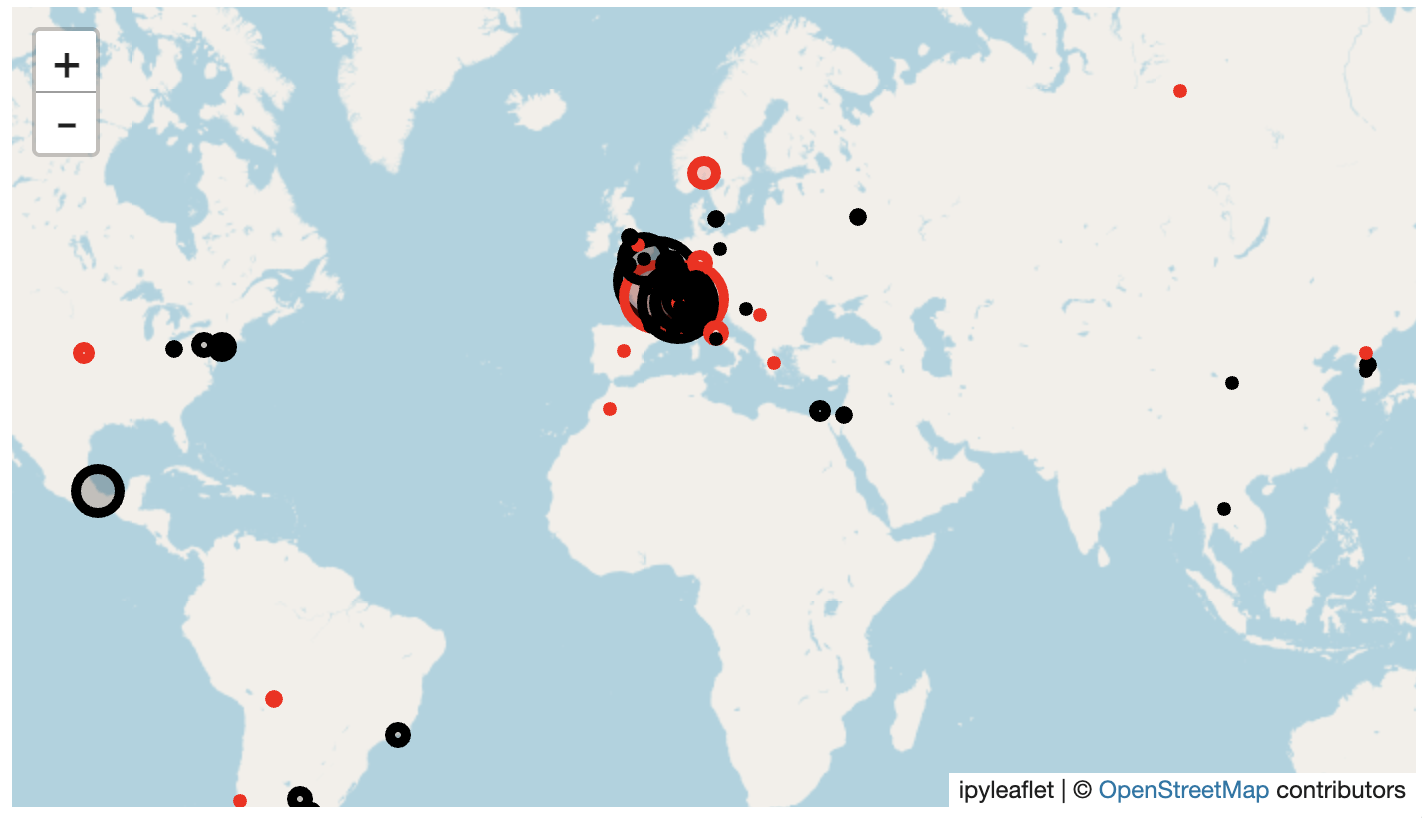
It generates a map showing the cities (in black) and countries (in red) mentioned in the news articles.
In the case of a corpus built around the keyword “radio,” the results aren’t very interesting: the locations are generally the cities where the broadcasts or concerts take place, with a few capital cities occasionally mentioned in news stories. This approach is much more interesting when working with a more general-purpose corpus.
Putting these tools to the test with our students
In recent years, we have been testing these tools in our classes. It’s always interesting to see how students—whether or not they have prior technical knowledge—use them to analyze these press archive collections.
Incorporating these tools into historians' toolkit
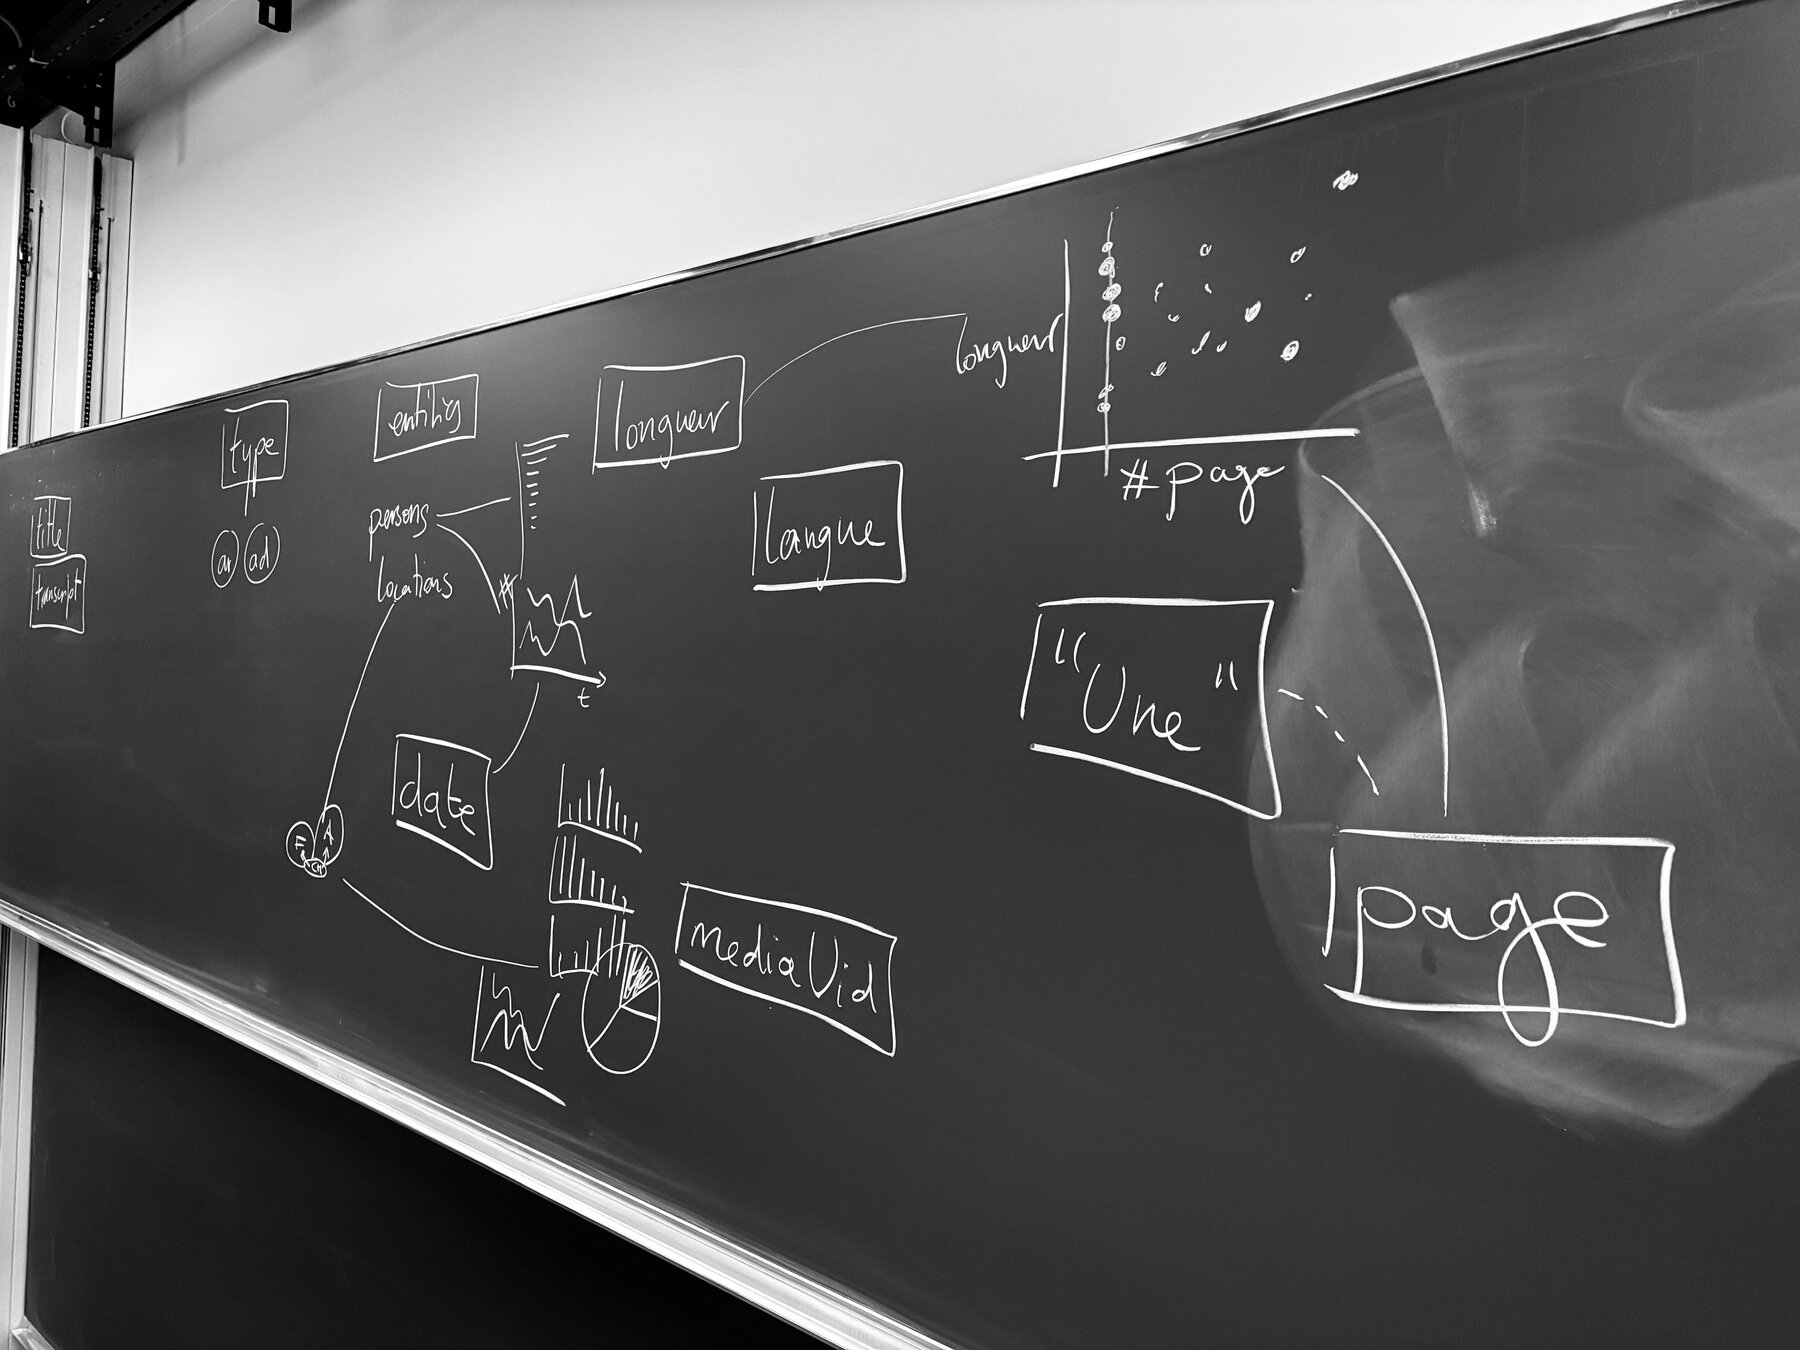
EPFL MA Course 2025-2026
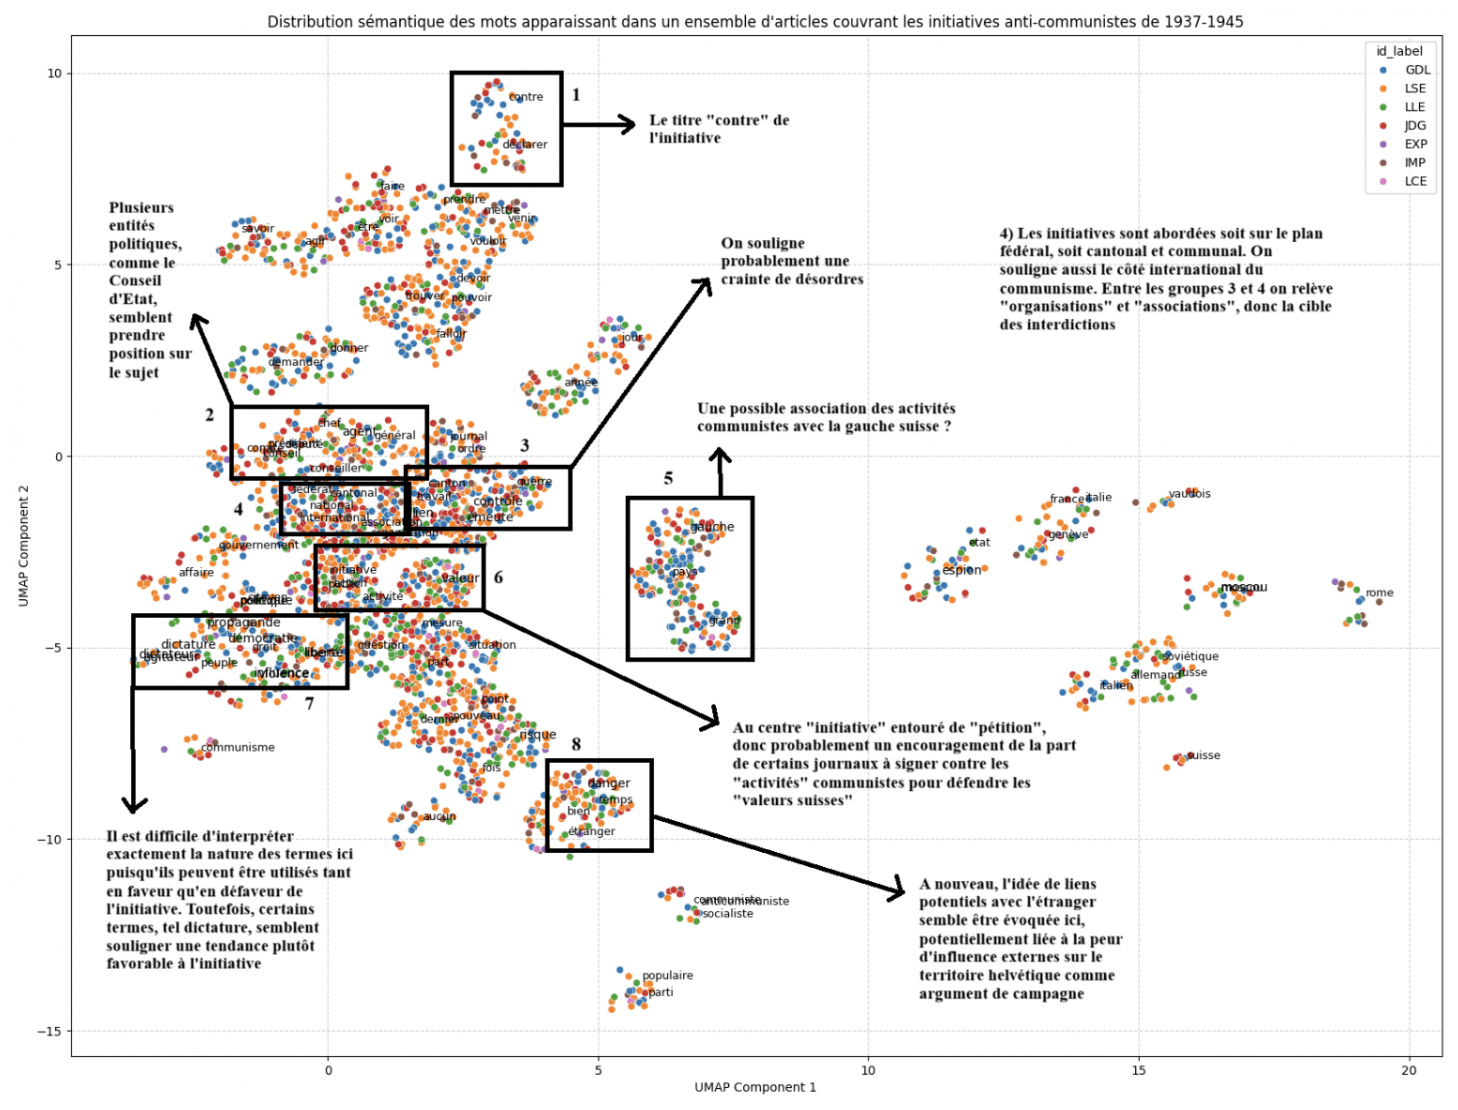
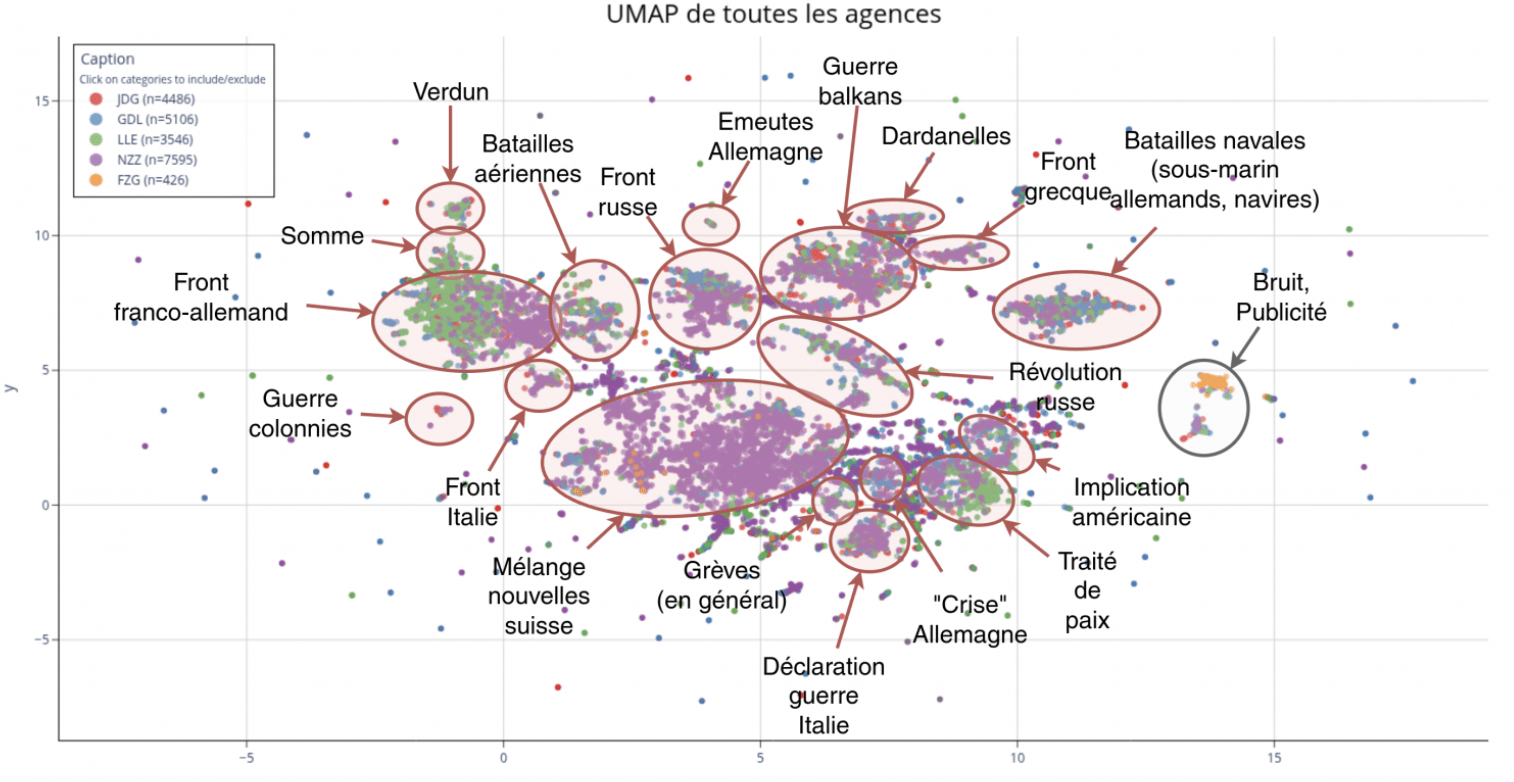
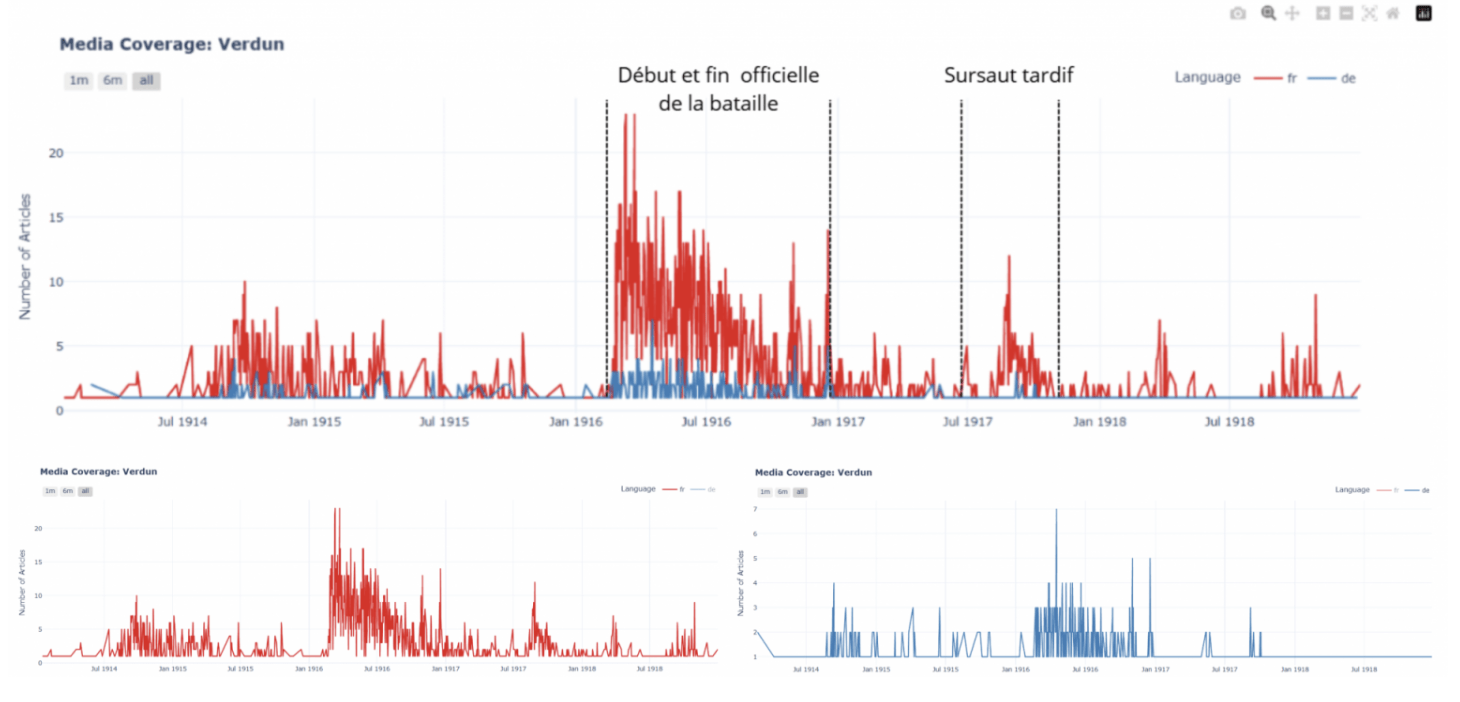
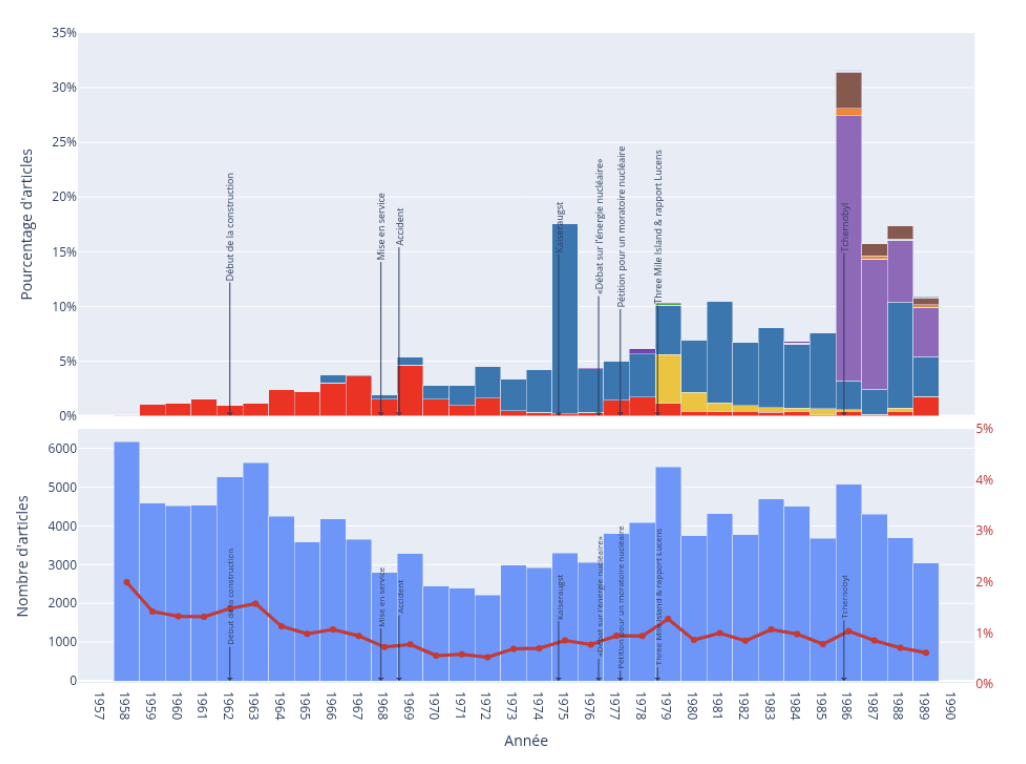
Examples of student works, made with the Impresso datalb
Developing innovative research
Opening up new possibilities through dialogue with computer scientists
Challenge 3
Interdisciplinary research
How can historians really learn from the kind of tools computer scientists use and develop instead of merely outsourcing specific tasks?
How do you NOT do what you did, simply differently or at greater scale, but do something that's genuinely new?
And conversely, how do historians avoid being relegated to "consultant" roles, providing a sort of historiographical guarantee?
How do you push research forward and not simply adapt it to new technology?
Embeddings
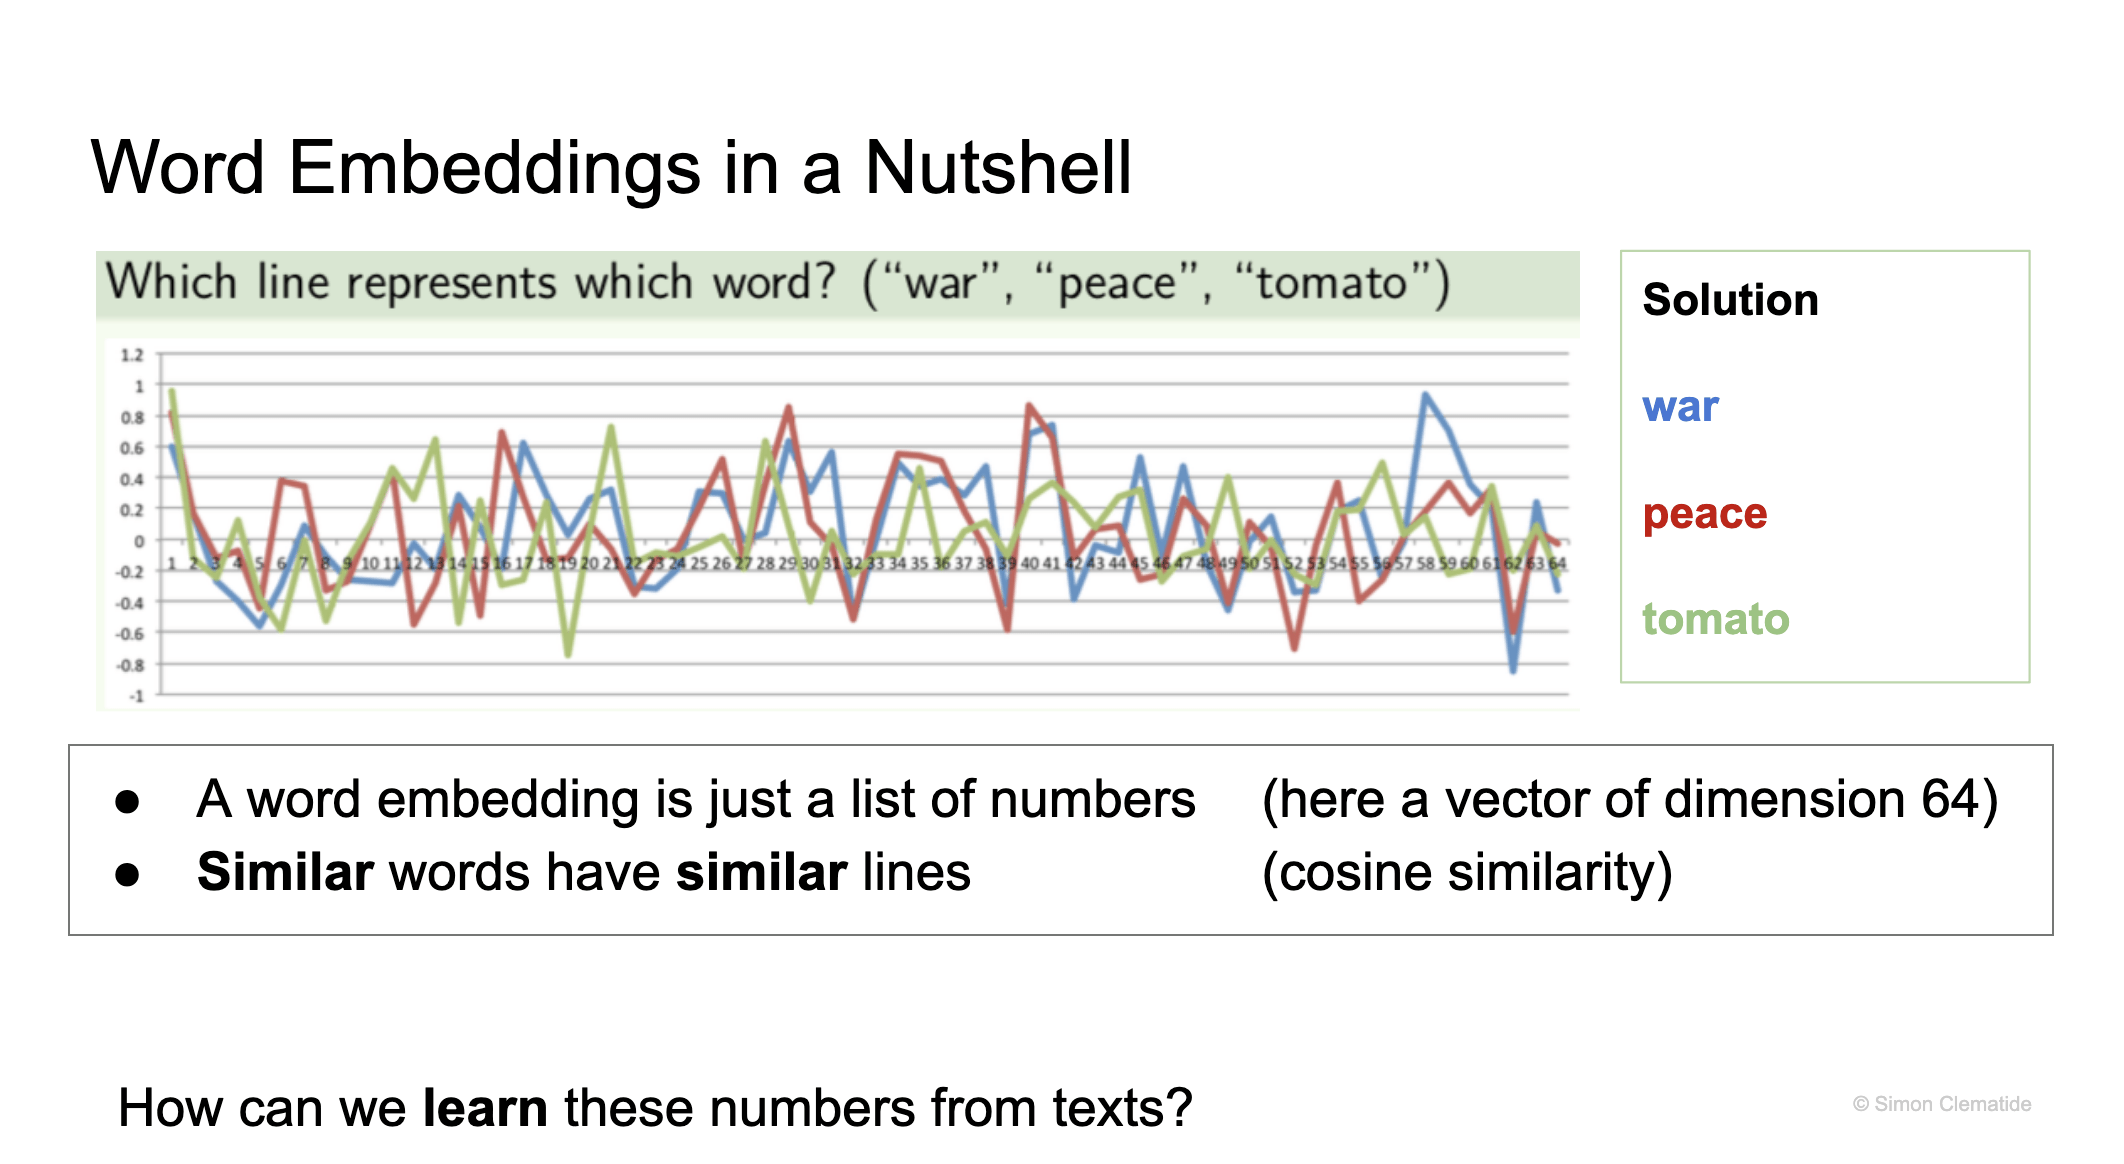
Embedding algorithms are trained, in similar fashion to LLMs, to map the position of words in relation to each other across billions of texts, and, based on these patterns, they generate vector representations for those texts: this is what we mean when we say that these algorithms embed words in their semantic context.
Here: war and peace appear more often in the same texts than peace and tomato—therefore the vectors of war and peace are closer than those of peace and tomato or war and tomato
Capturing semantic similarities
Embeddings
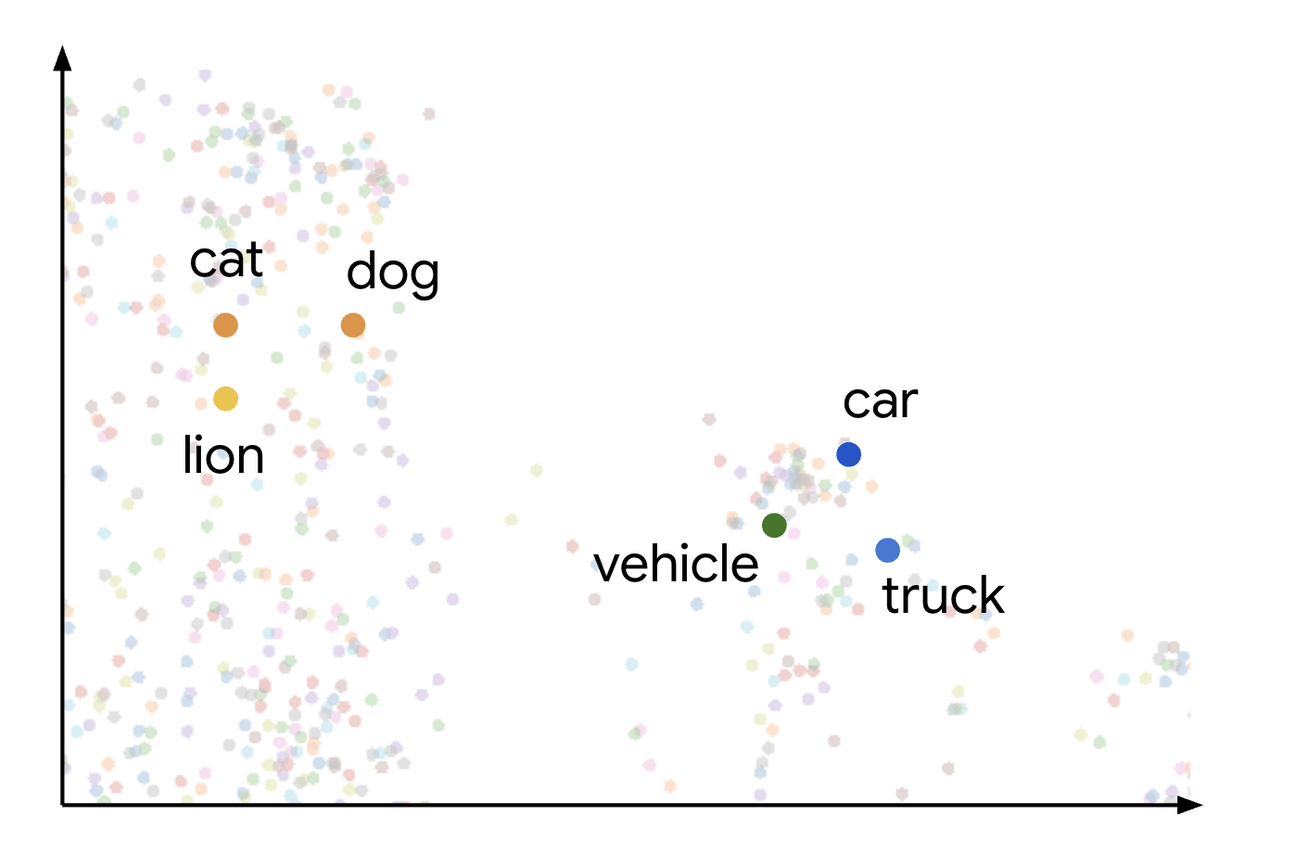
Capturing semantic similarities
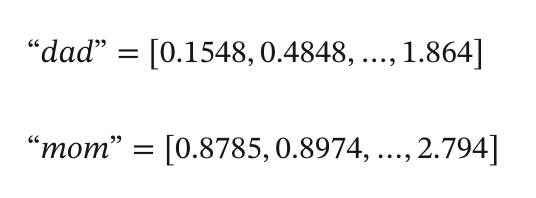
Embedding algorithms are trained, in similar fashion to LLMs, to map the position of words in relation to each other across billions of texts, and, based on these patterns, they generate vector representations for those texts: this is what we mean when we say that these algorithms embed words in their semantic context.
Here: war and peace appear more often in the same texts than peace and tomato—therefore the vectors of war and peace are closer than those of peace and tomato or war and tomato
Words are transformed into multidimensional vectors
A semantic map, reducing the complexity of the vectors to see their proximity
Embeddings
Integrate embeddings into the interface so that if we search for "bank" we get results about credit institutions rather than river banks
Original usage in the Impresso interface
Mapping the semantic space
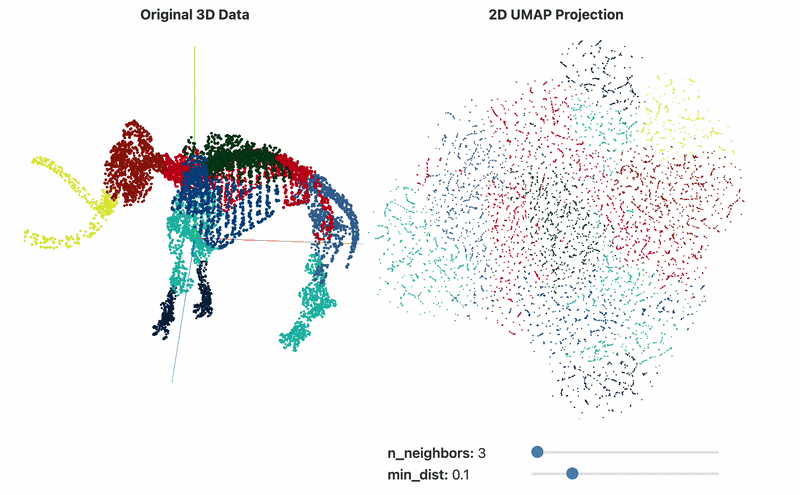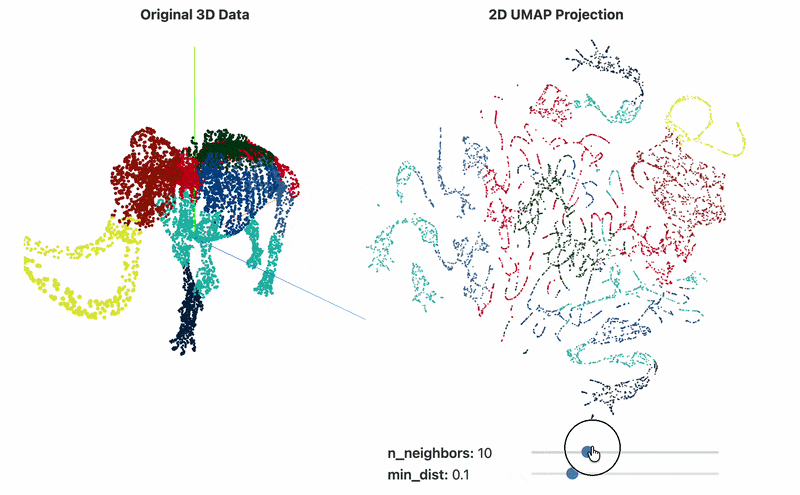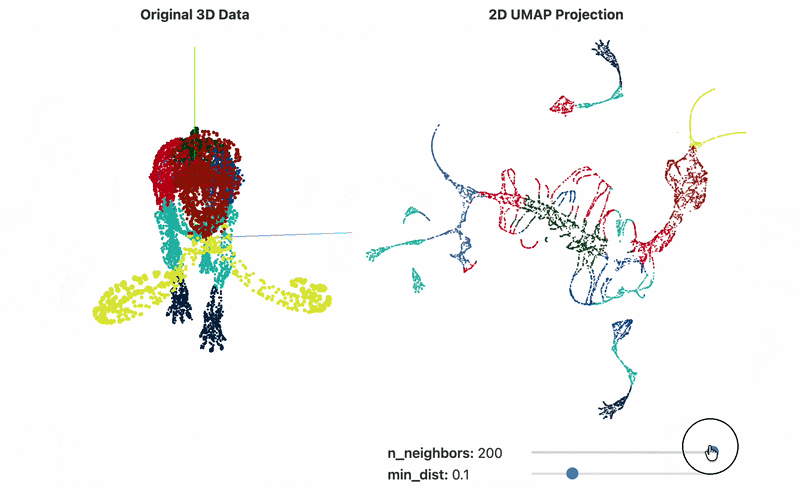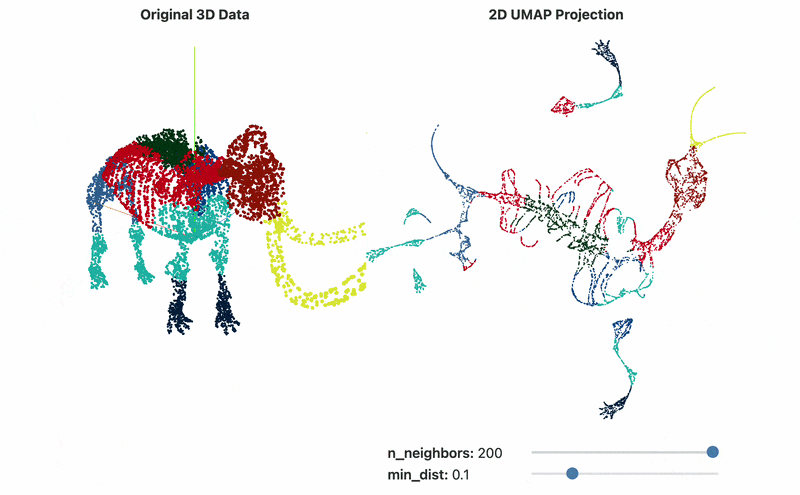
Animation: Coenen and Pearce, “Understanding UMAP”, https://pair-code.github.io/understanding-umap/
How can we interpret a UMAP, a cloud of dots that is a “flattened” version of our original multidimensional object (which is itself too complex to grasp)?
Visualizing vector representations of articles in 2D reduces the dimensionality of the semantic distance between them (from hundreds of dimensions to just 2).
Interpreting semantic proximity maps (UMAPs)
Mapping the semantic space
La Liberté (Catholic, Fribourg)
Journal de Genève (Liberal conservative, Geneva)
Feuille d'Avis de Neuchâtel (Generalist, Neuchâtel)
And a tool to compare newspaper biases?
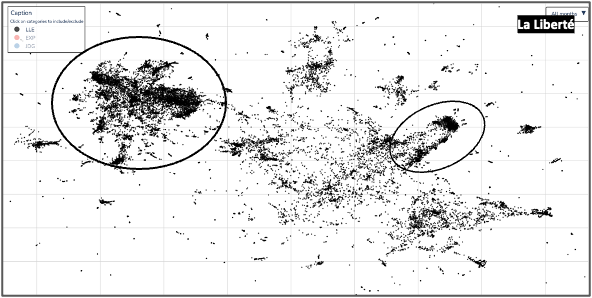
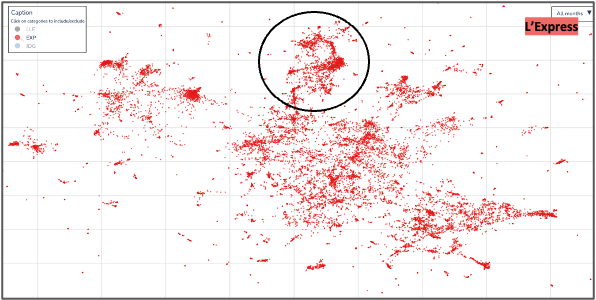
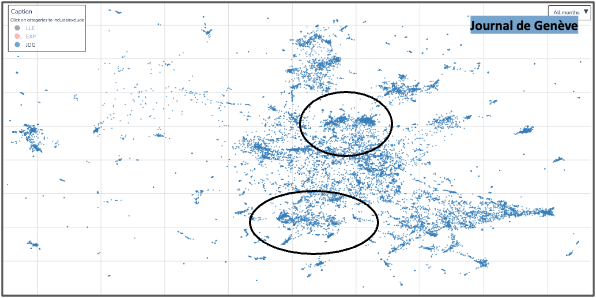
At first glance, we see that the colors (the newspapers) are not always evenly distributed within the groups of dots. This means that the newspapers do not cover the same areas, or not with the same intensity.
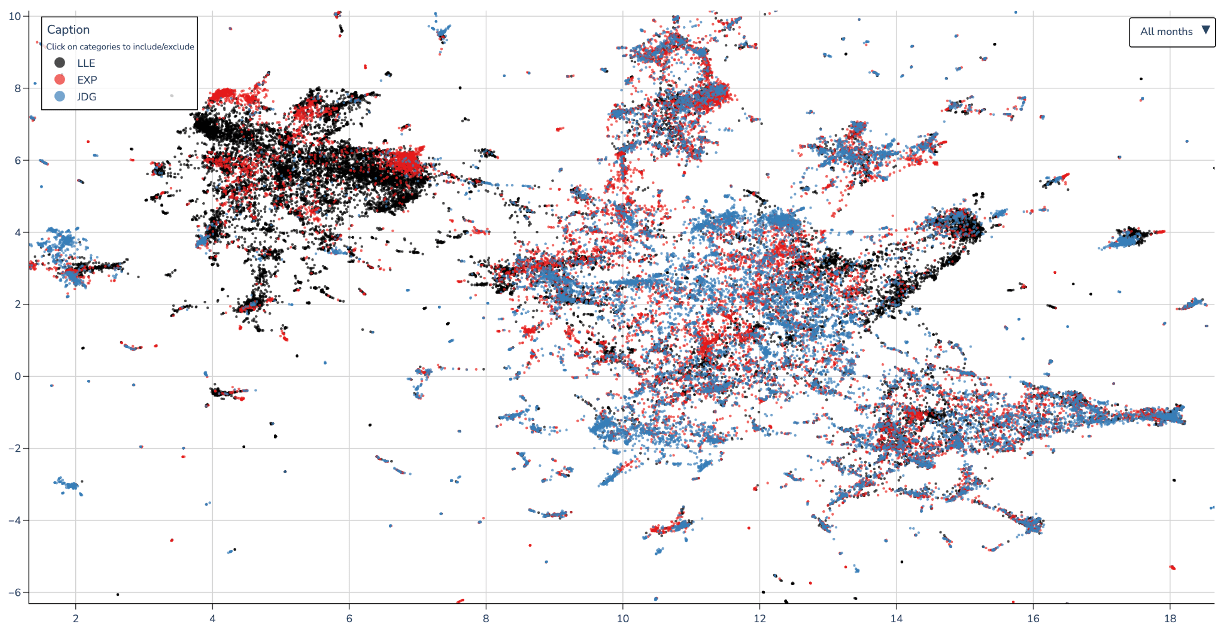
Back to our 60,000 articles published in 1950 in three newspapers.
Mapping the semantic space
La Liberté (Catholic, Fribourg)
Journal de Genève (Liberal conservative, Geneva)
Feuille d'Avis de Neuchâtel (Generalist, Neuchâtel)
A tool to compare newspaper biases?
We therefore need to explore the map to understand what is in these clusters.
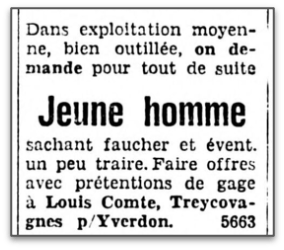
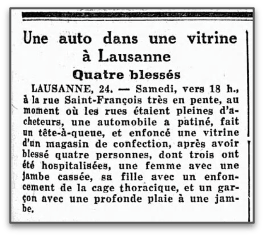
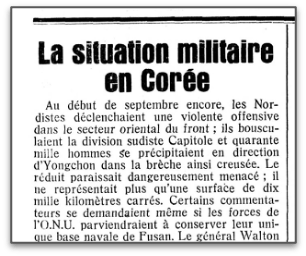
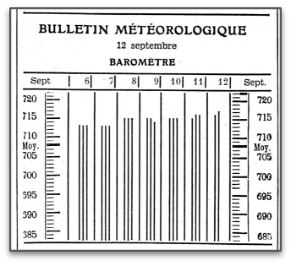
Accident
Korean War
International relations
Job advertisement
Weather
Mapping the semantic space
La Liberté (Catholic, Fribourg)
Journal de Genève (Liberal conservative, Geneva)
Feuille d'Avis de Neuchâtel (Generalist, Neuchâtel)
A tool to compare newspaper biases?
The editorial line of the newspapers becomes quite clear with this overall view.
Classified ads
Religion
Music, culture
Economic news
Crimes, accidents
Joint work
Can embeddings be transposed into historical research pipeline?
We worked on different scenarii to apply the tech on historical data
Fusing computer scientists' knowledge of the tech with historical lines of questionning
The process
Joint work
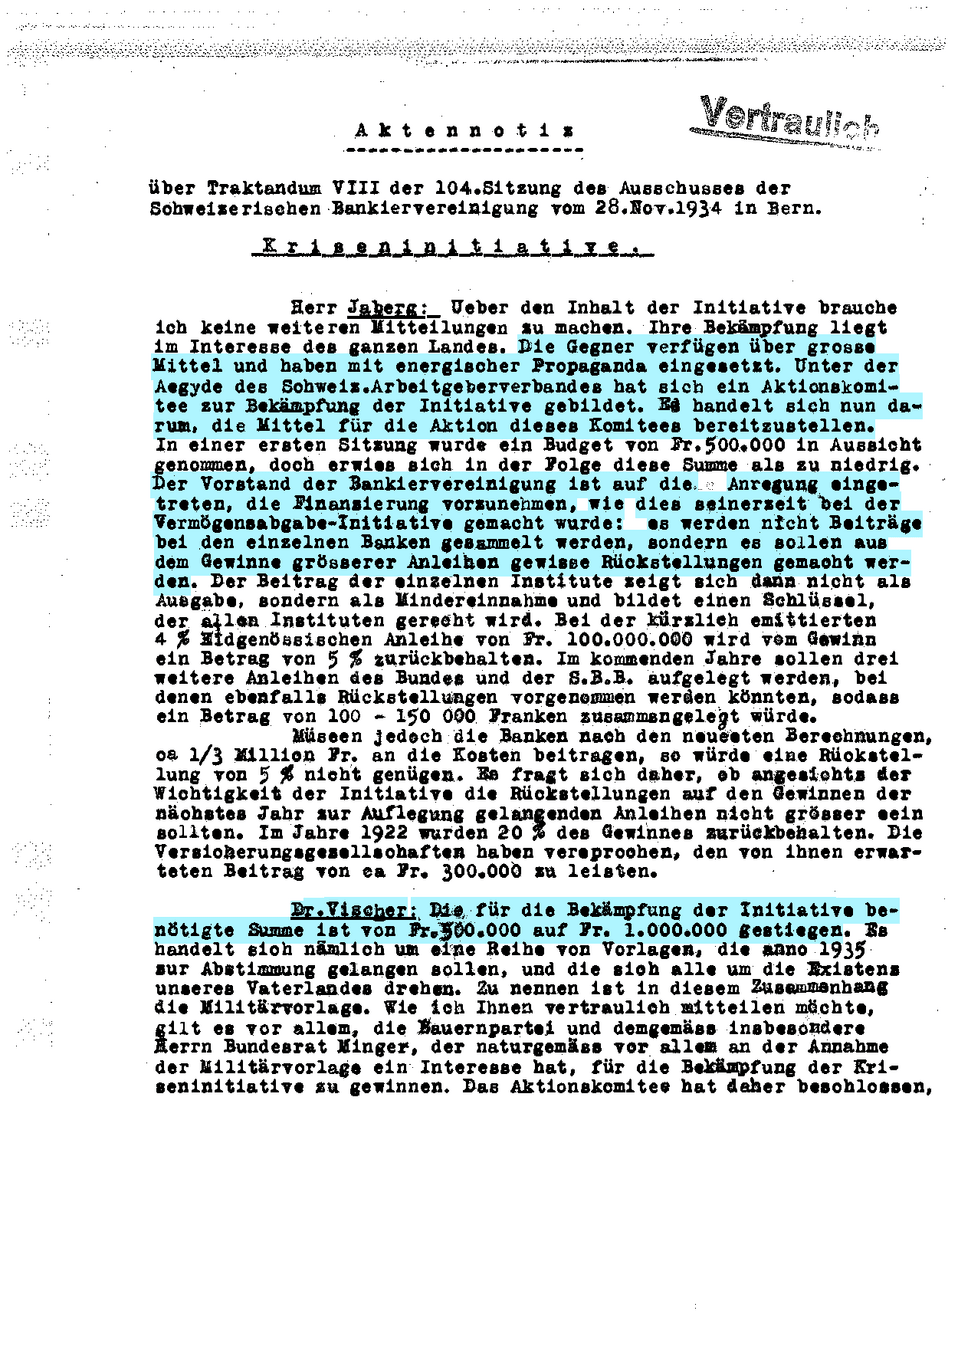
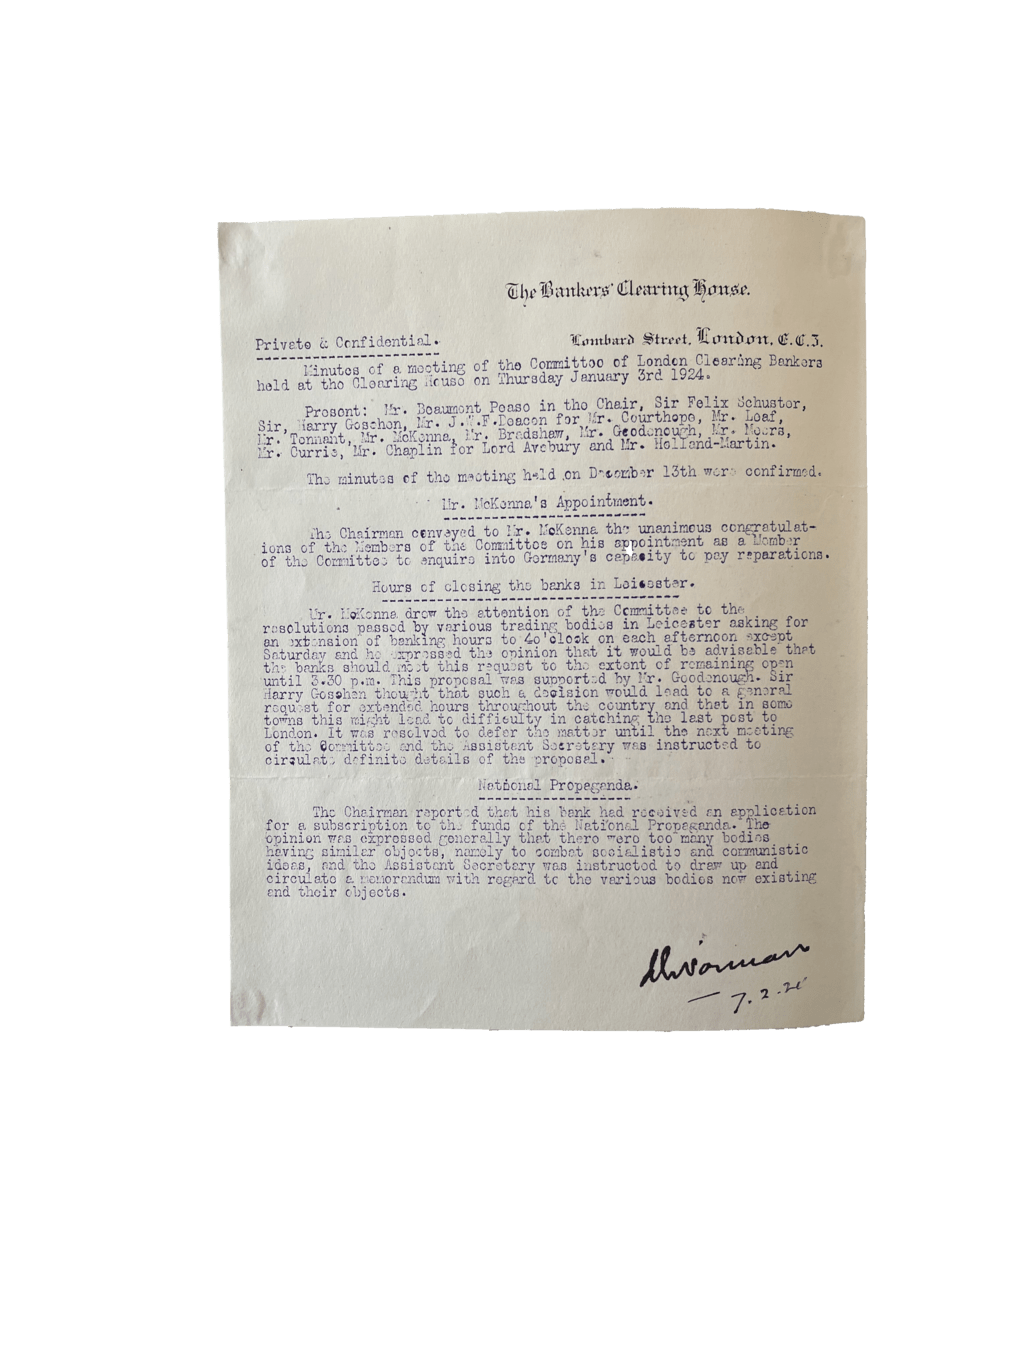
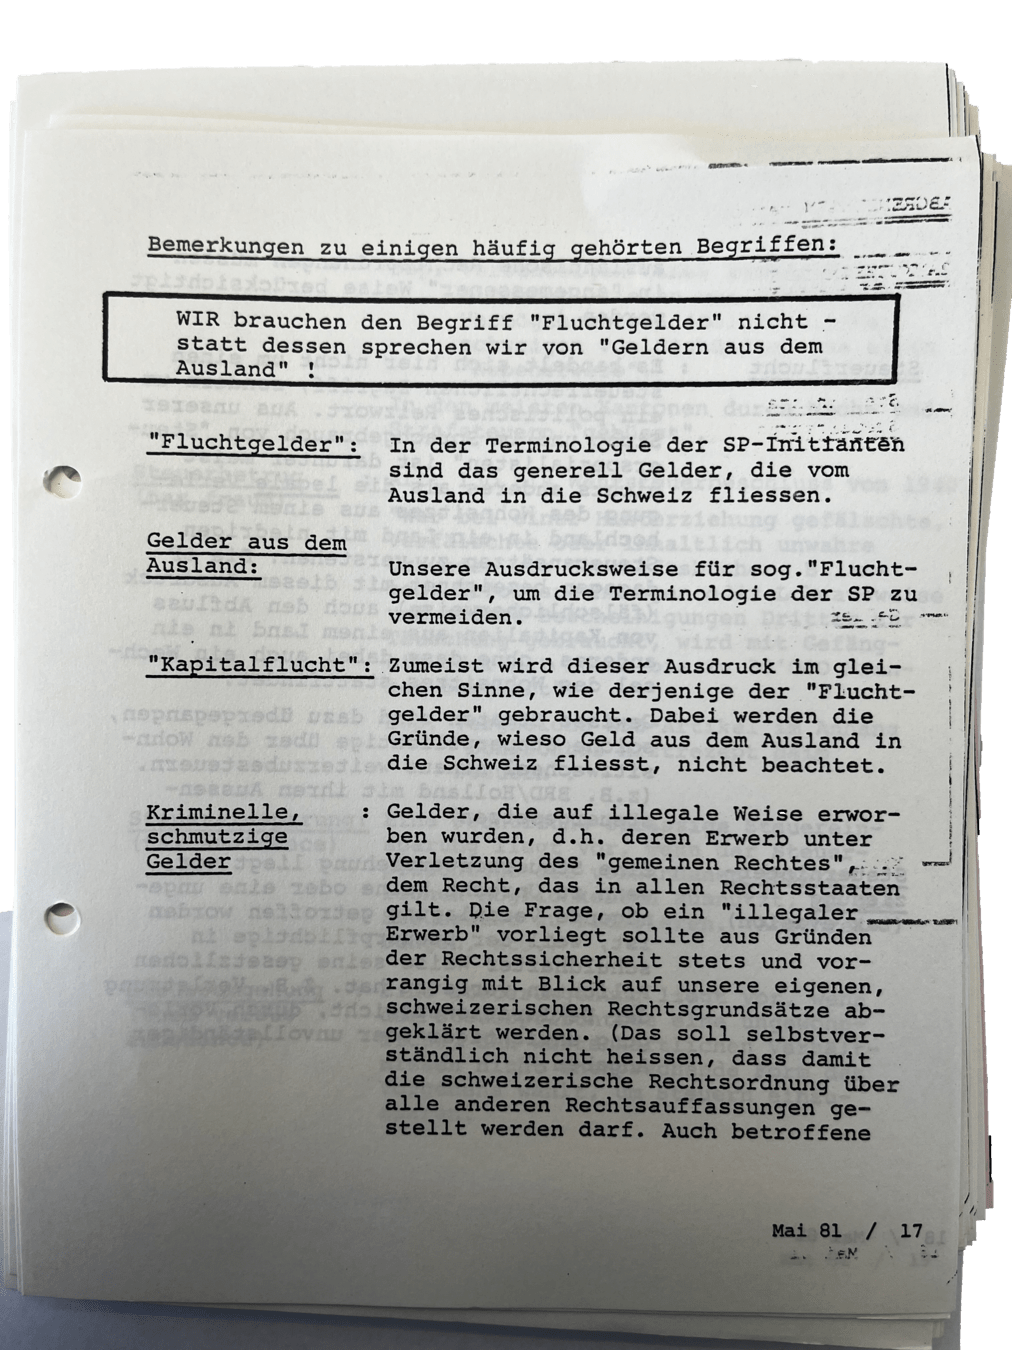
The scenario
Pictures of sources taken in archives
A collection retrieved from Impresso
How to visualise the semantic similarities between them?
Joint work
The scenario
Transcribe the sources in CSV
Download the collection in CSV
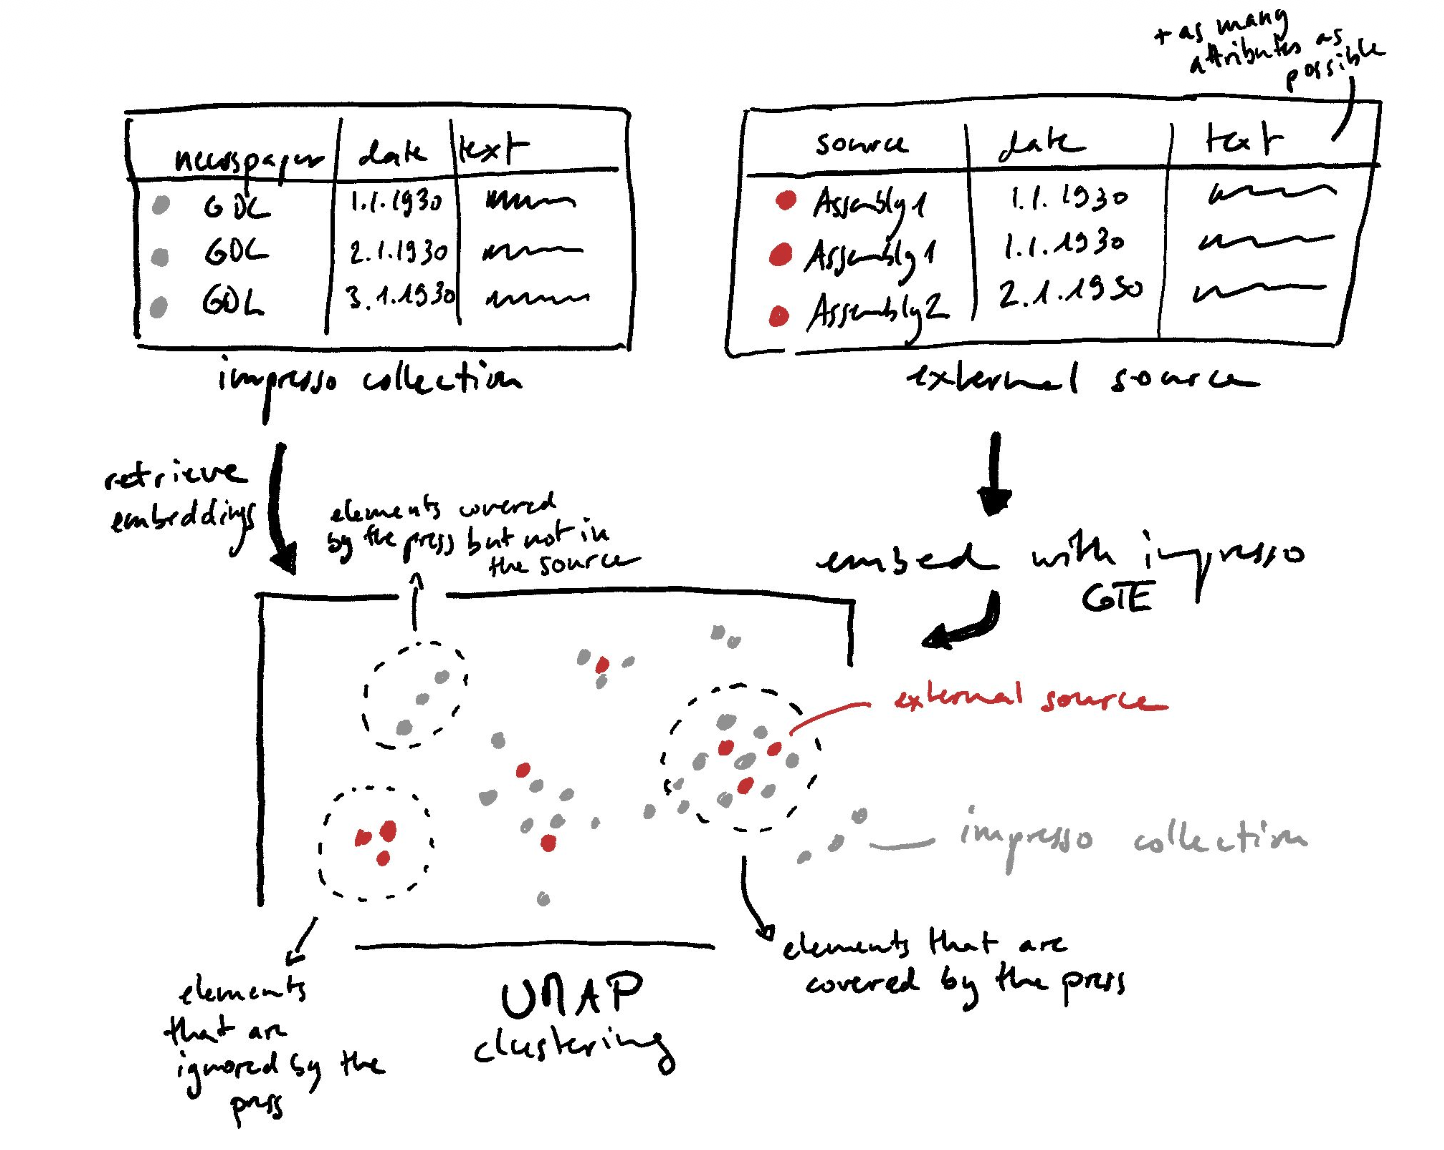
Use a semantic proximity map to visualise them in 2D
Embed the two datasets
Joint work
The first results
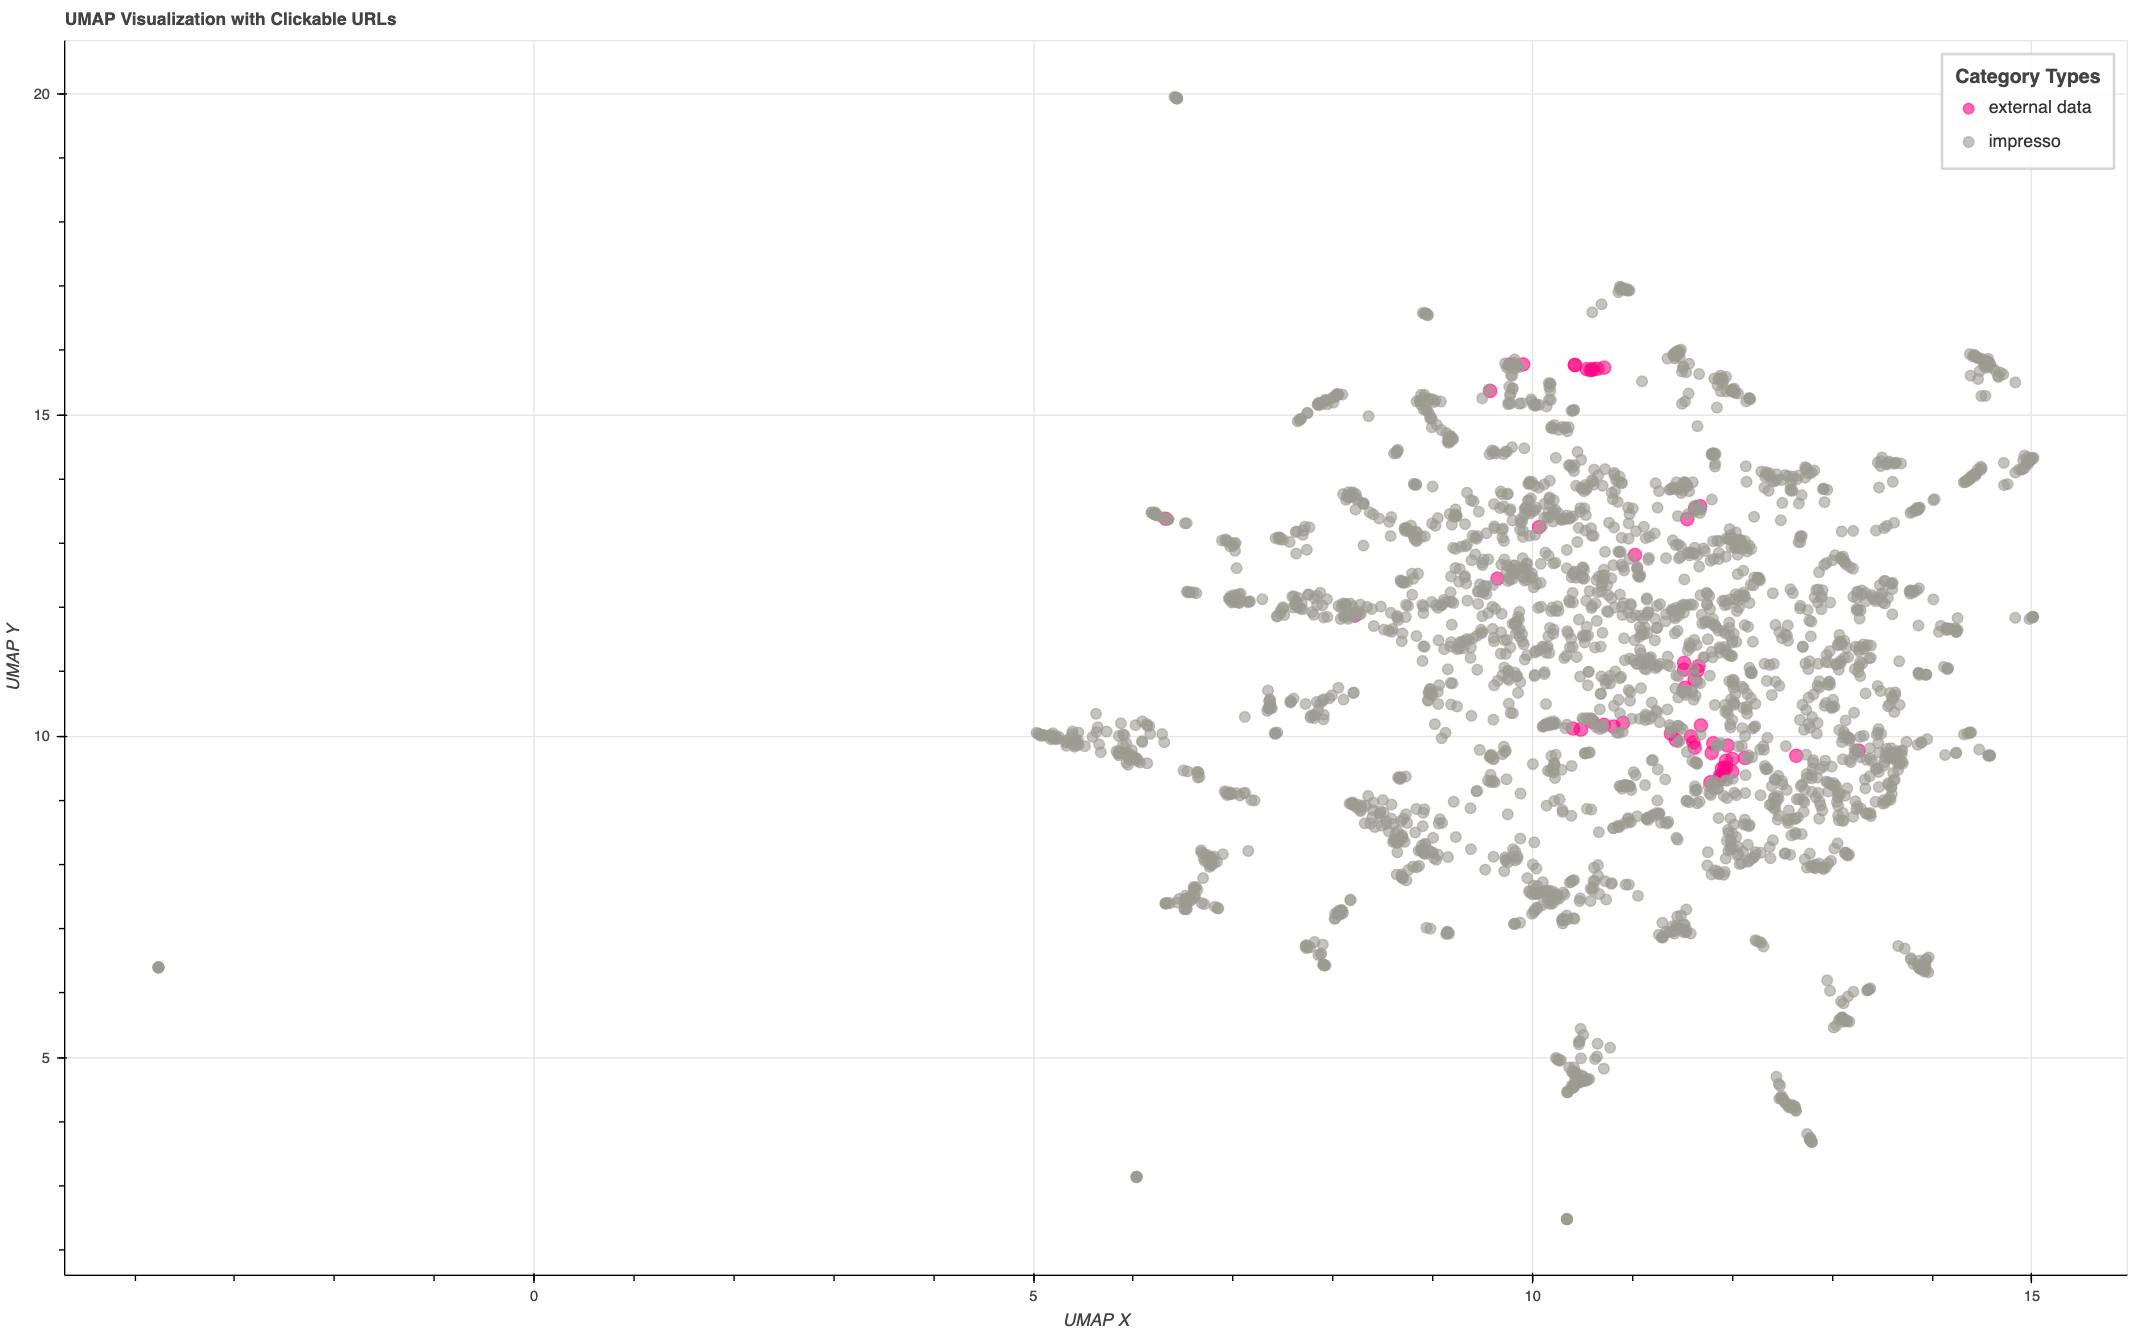
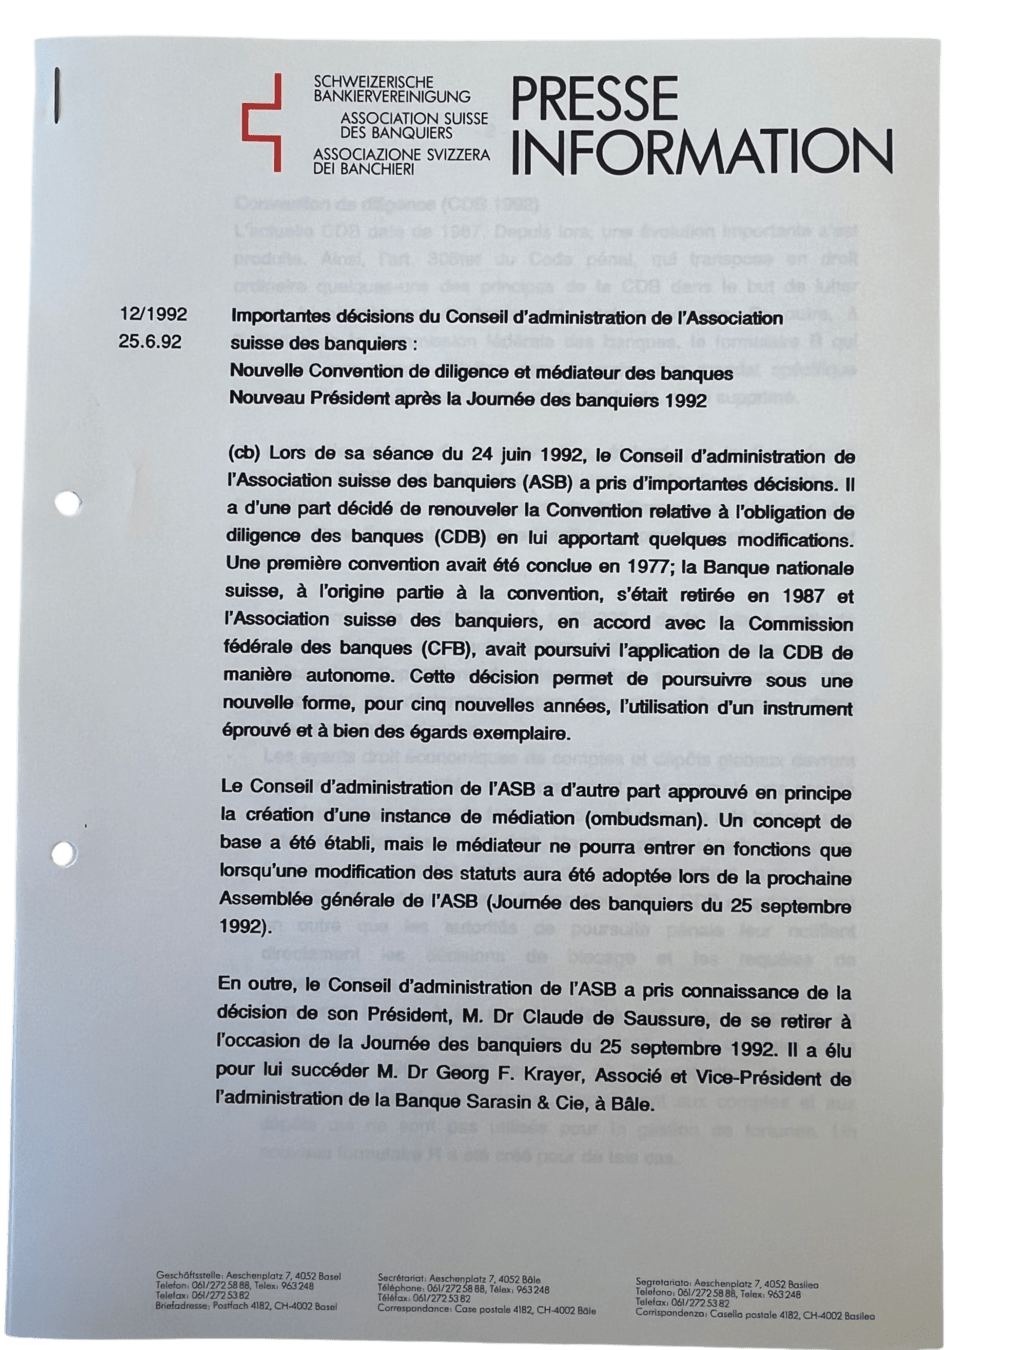
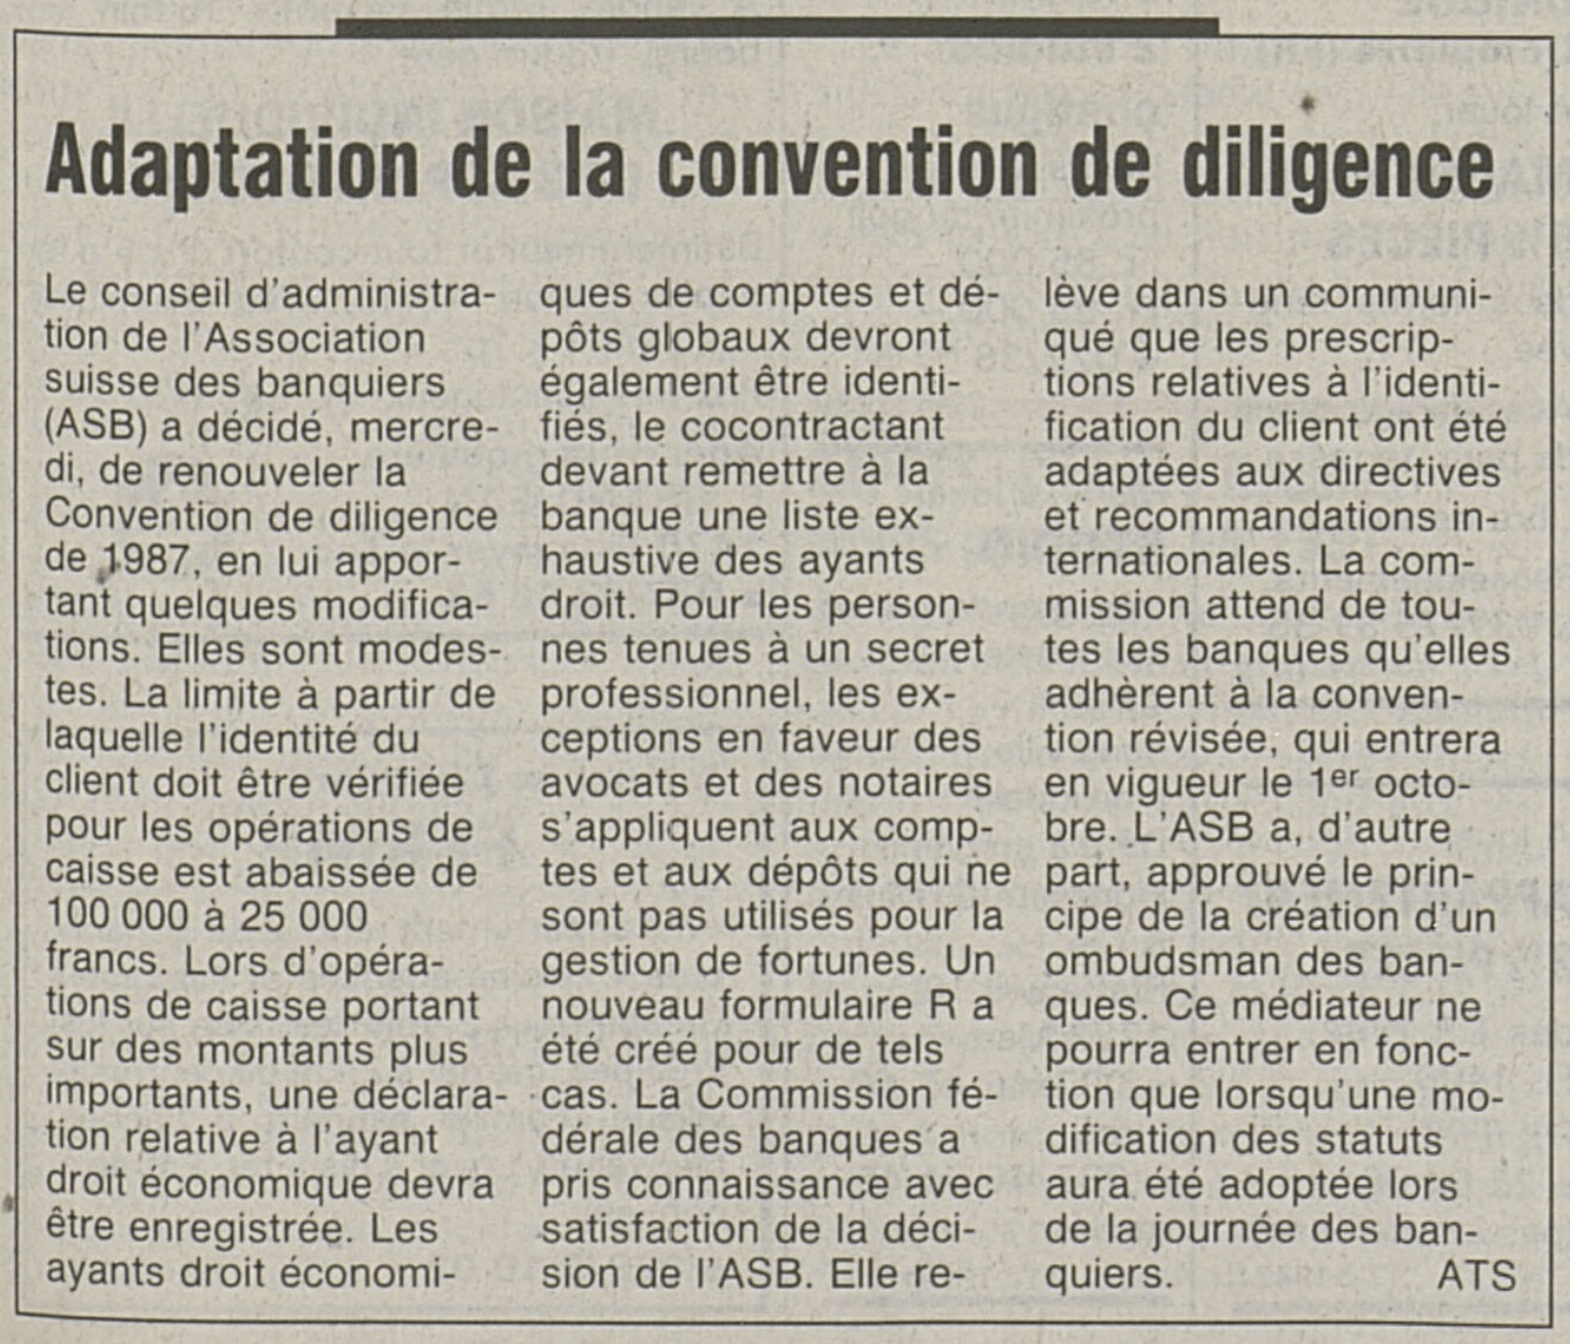
Original press release
Article in the press
Press articles
External collection
Into the historical research pipeline
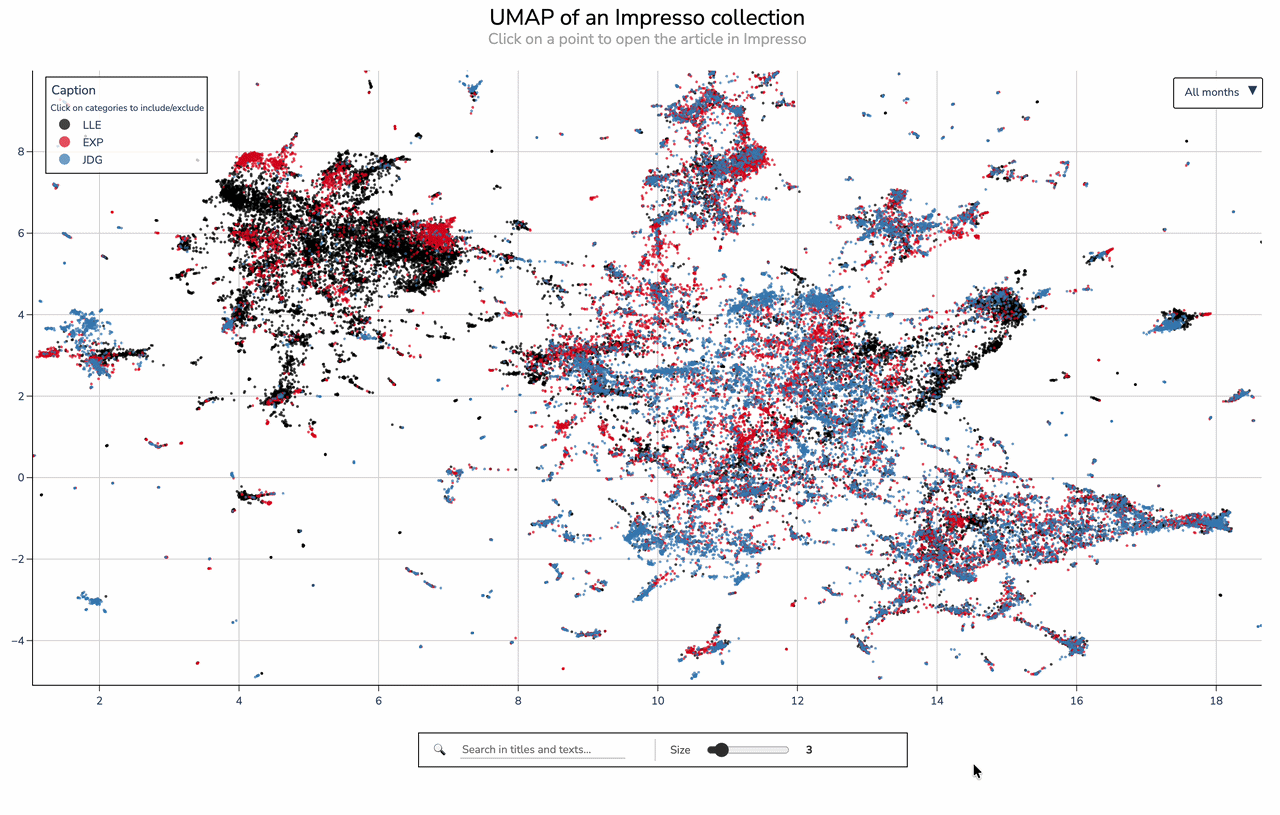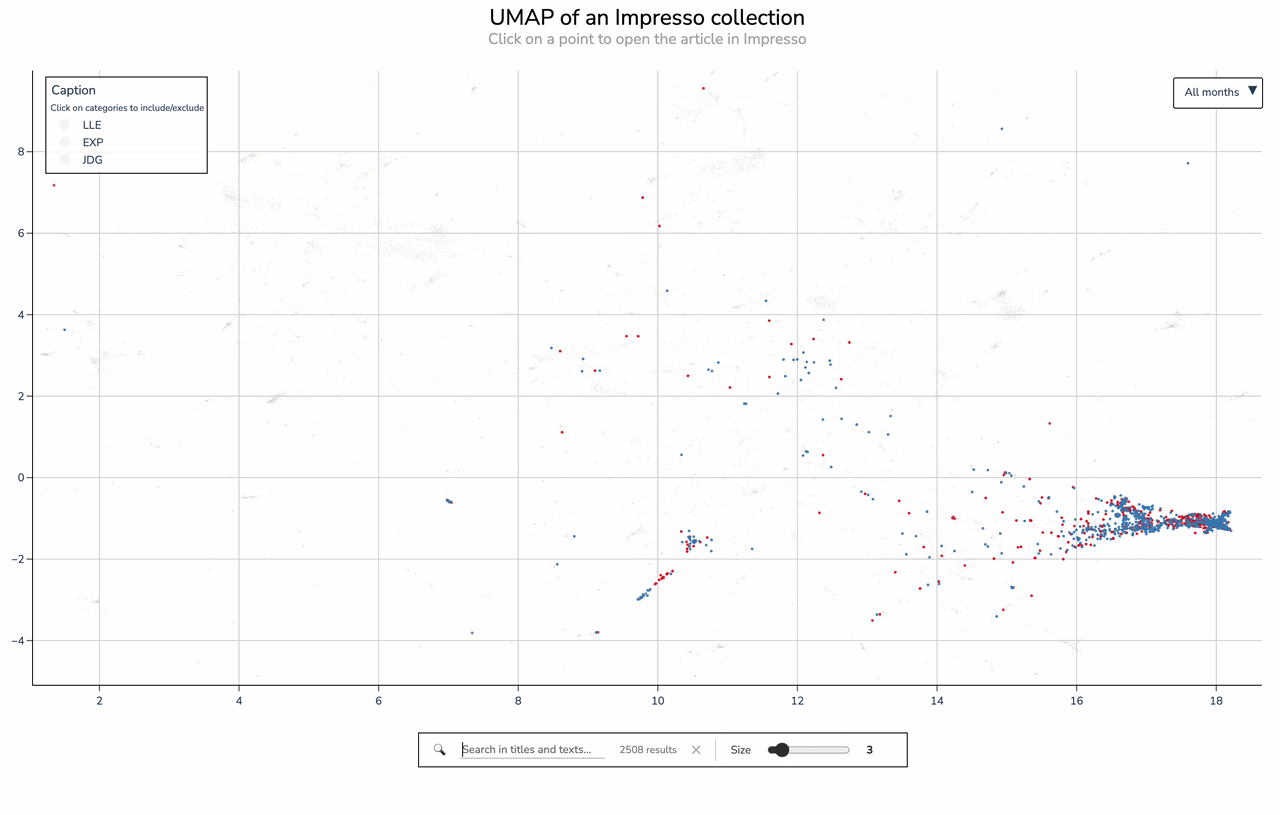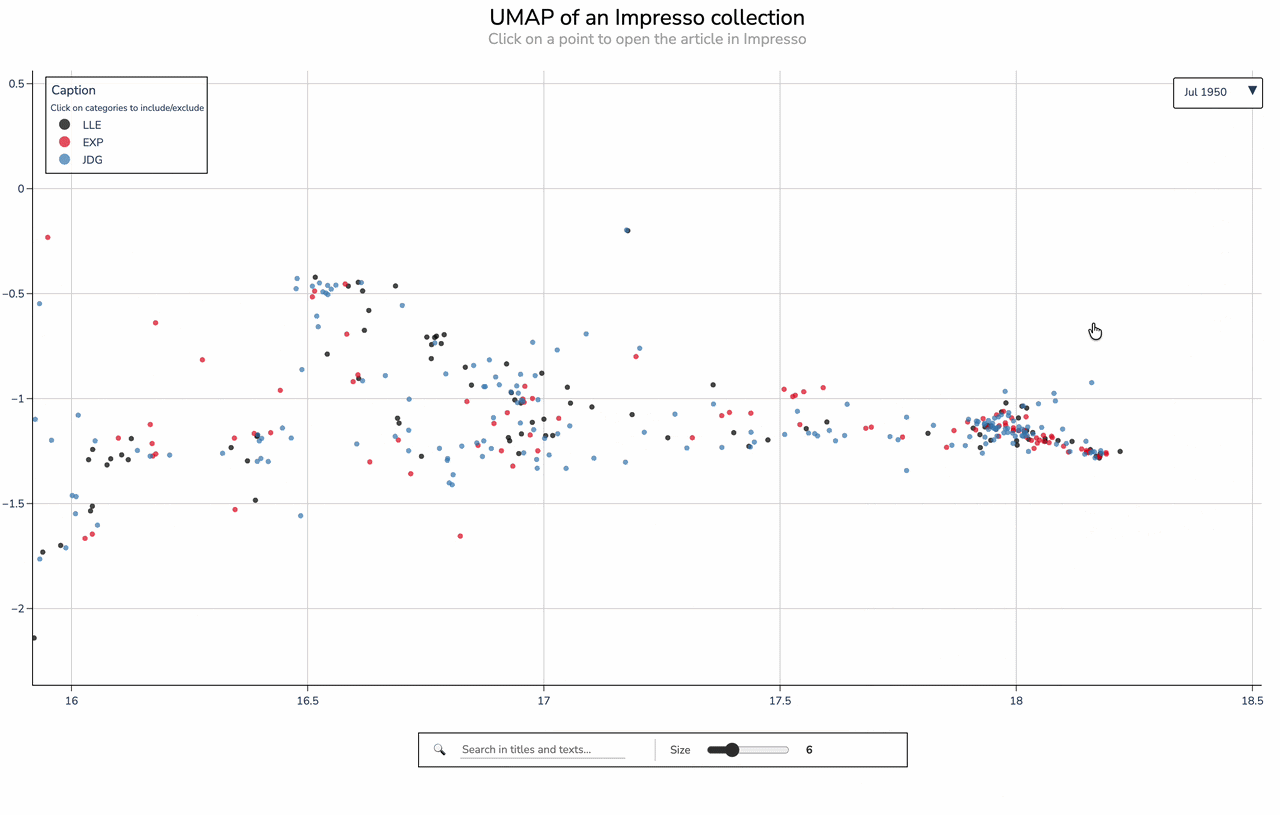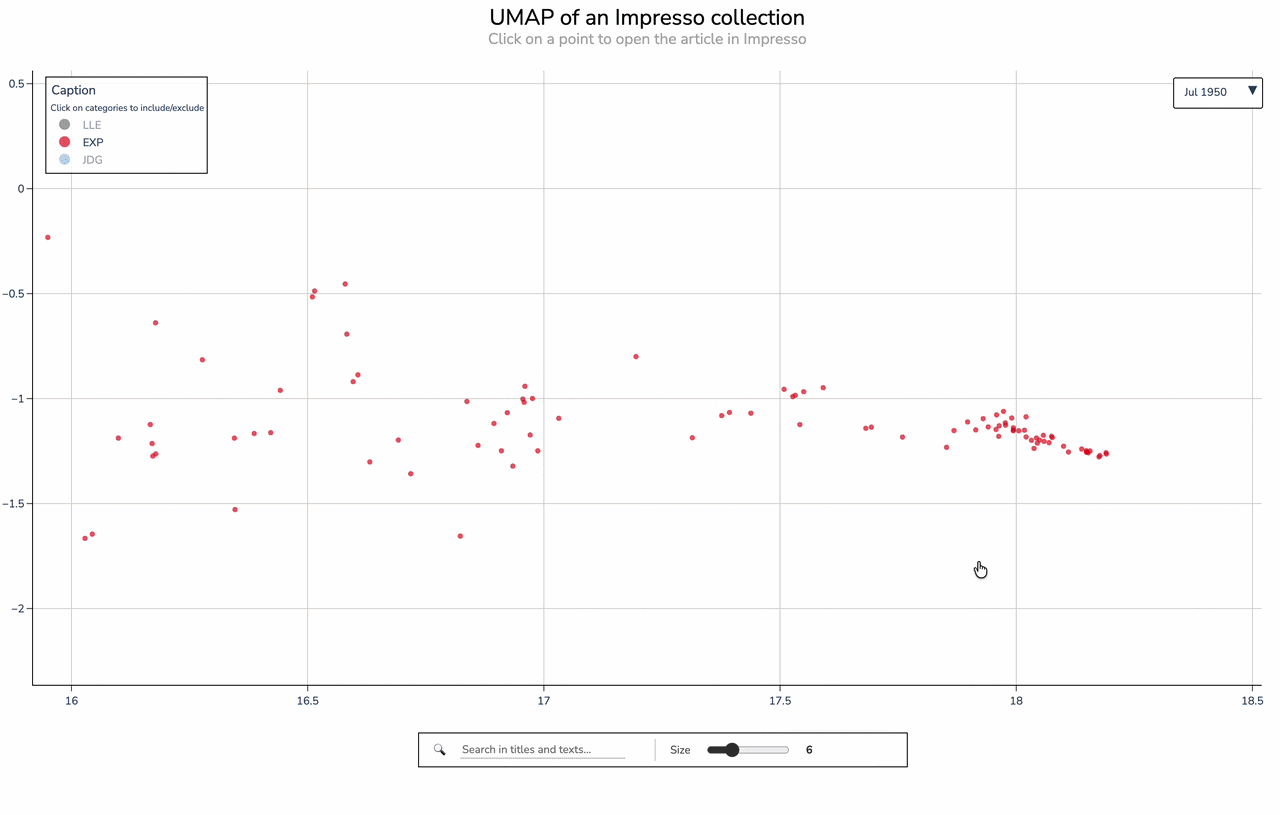
A tool for exploring large press corpora
An interactive interface to explore a collection, zoom in, select and get back to the original texts
Semantic analysis of article contents using embeddings
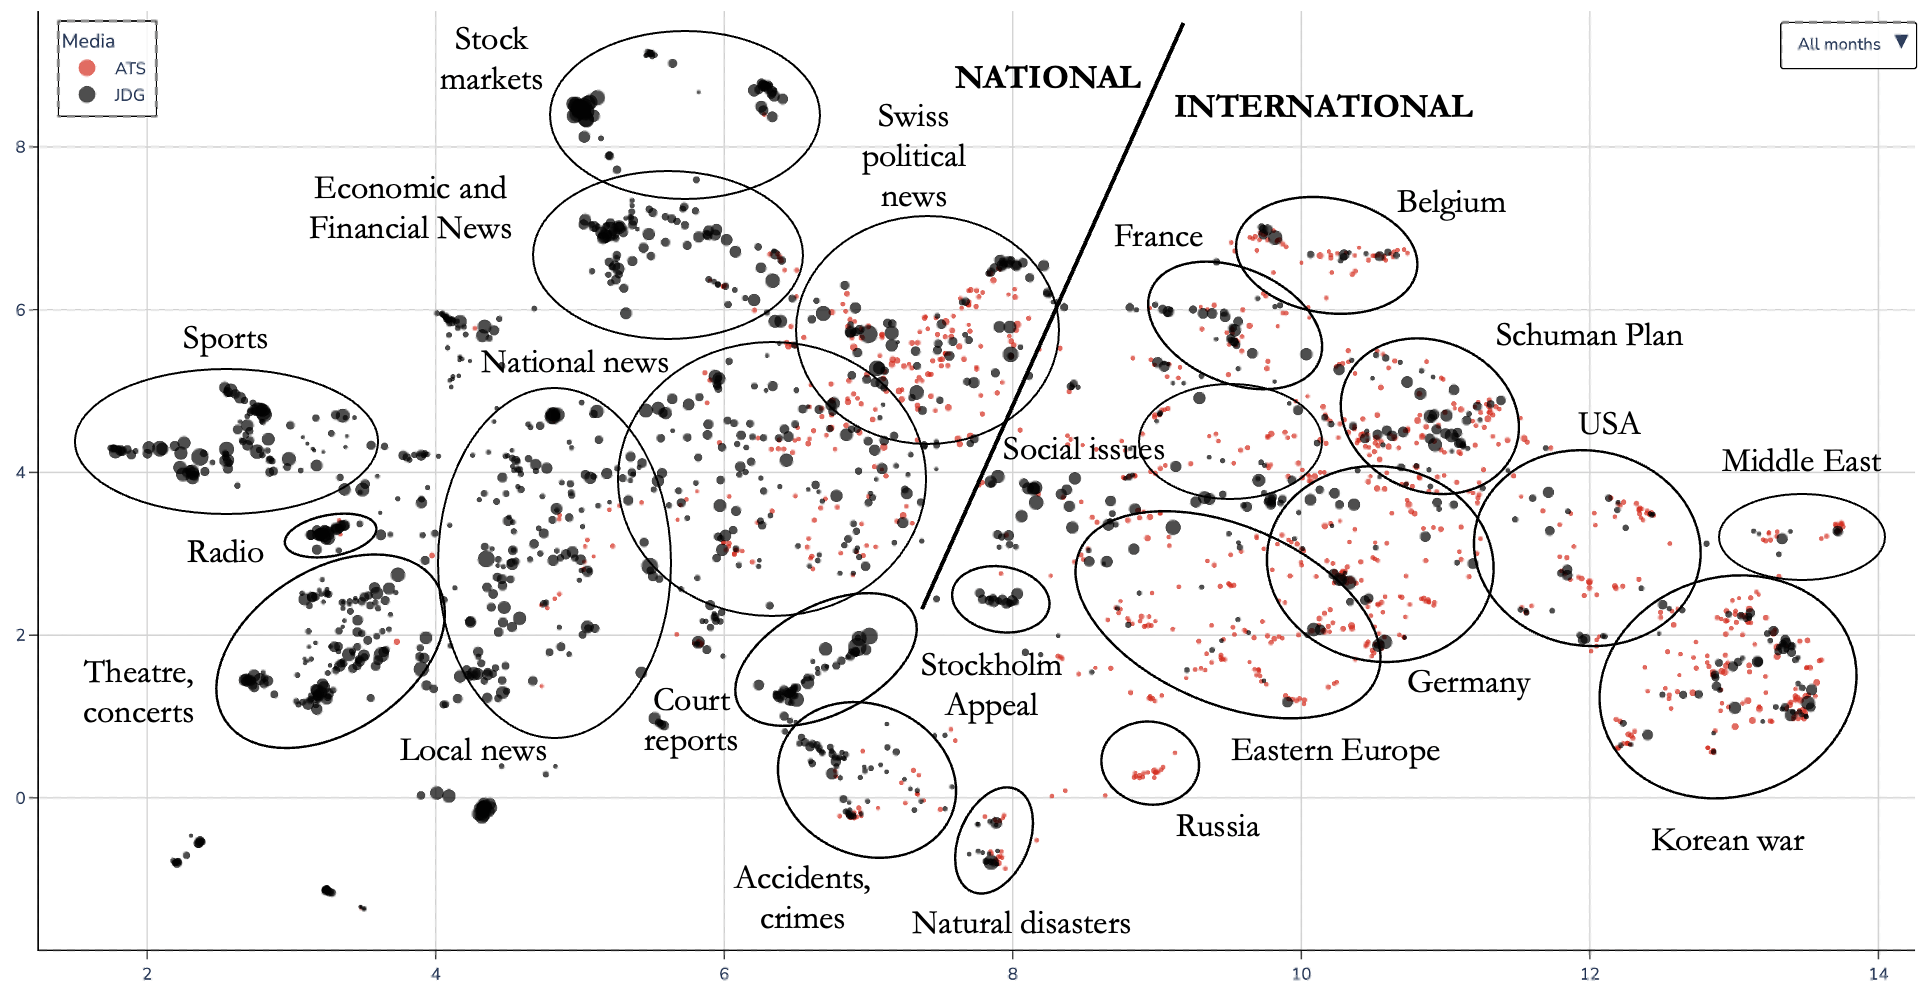
A tool for comparing press and radio
A semantic map showing that radio and the press do not cover the same news stories
Press
Radio
Making sense of all this for historical research
Conclusion
Conclusion
Writing history
This opens up new avenues for historiographical reflection
- How is the writing of history changing with these large-scale datasets and new methods?
- How should we interpret the results produced by these tools?
Conclusion
Writing history
We develop case studies to examine how certain phenomena are covered in the media.
Conclusion
Writing history
Bringing a community together and conducting historical research
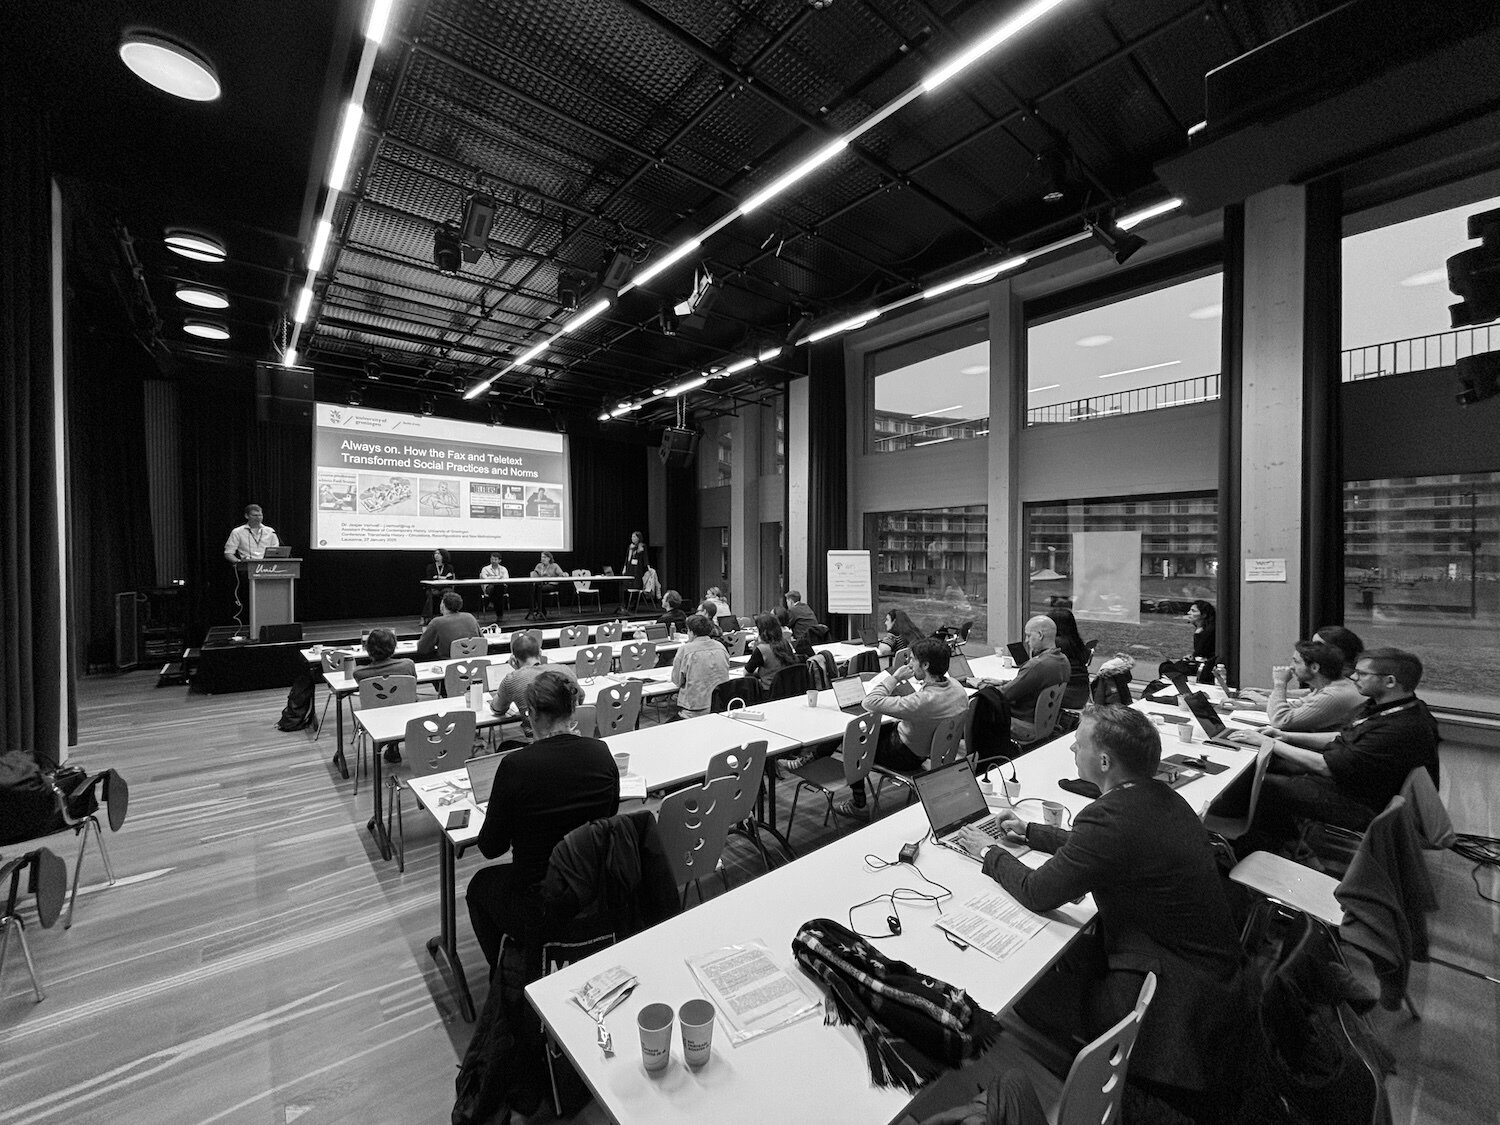
Impresso also organizes workshops and international conferences
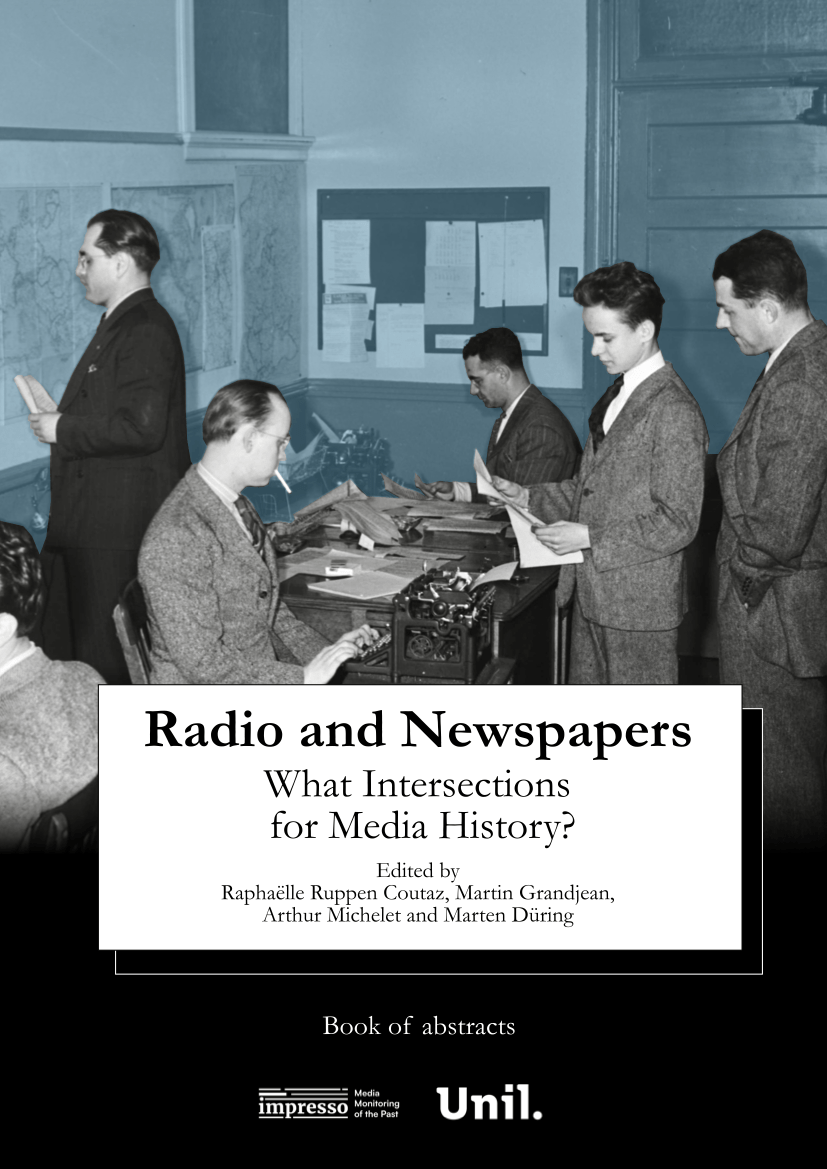
Beyond borders
28-29 Jan. 2027
Lausanne
coming soon!
Conclusion
Writing history
Bringing a community together and conducting historical research
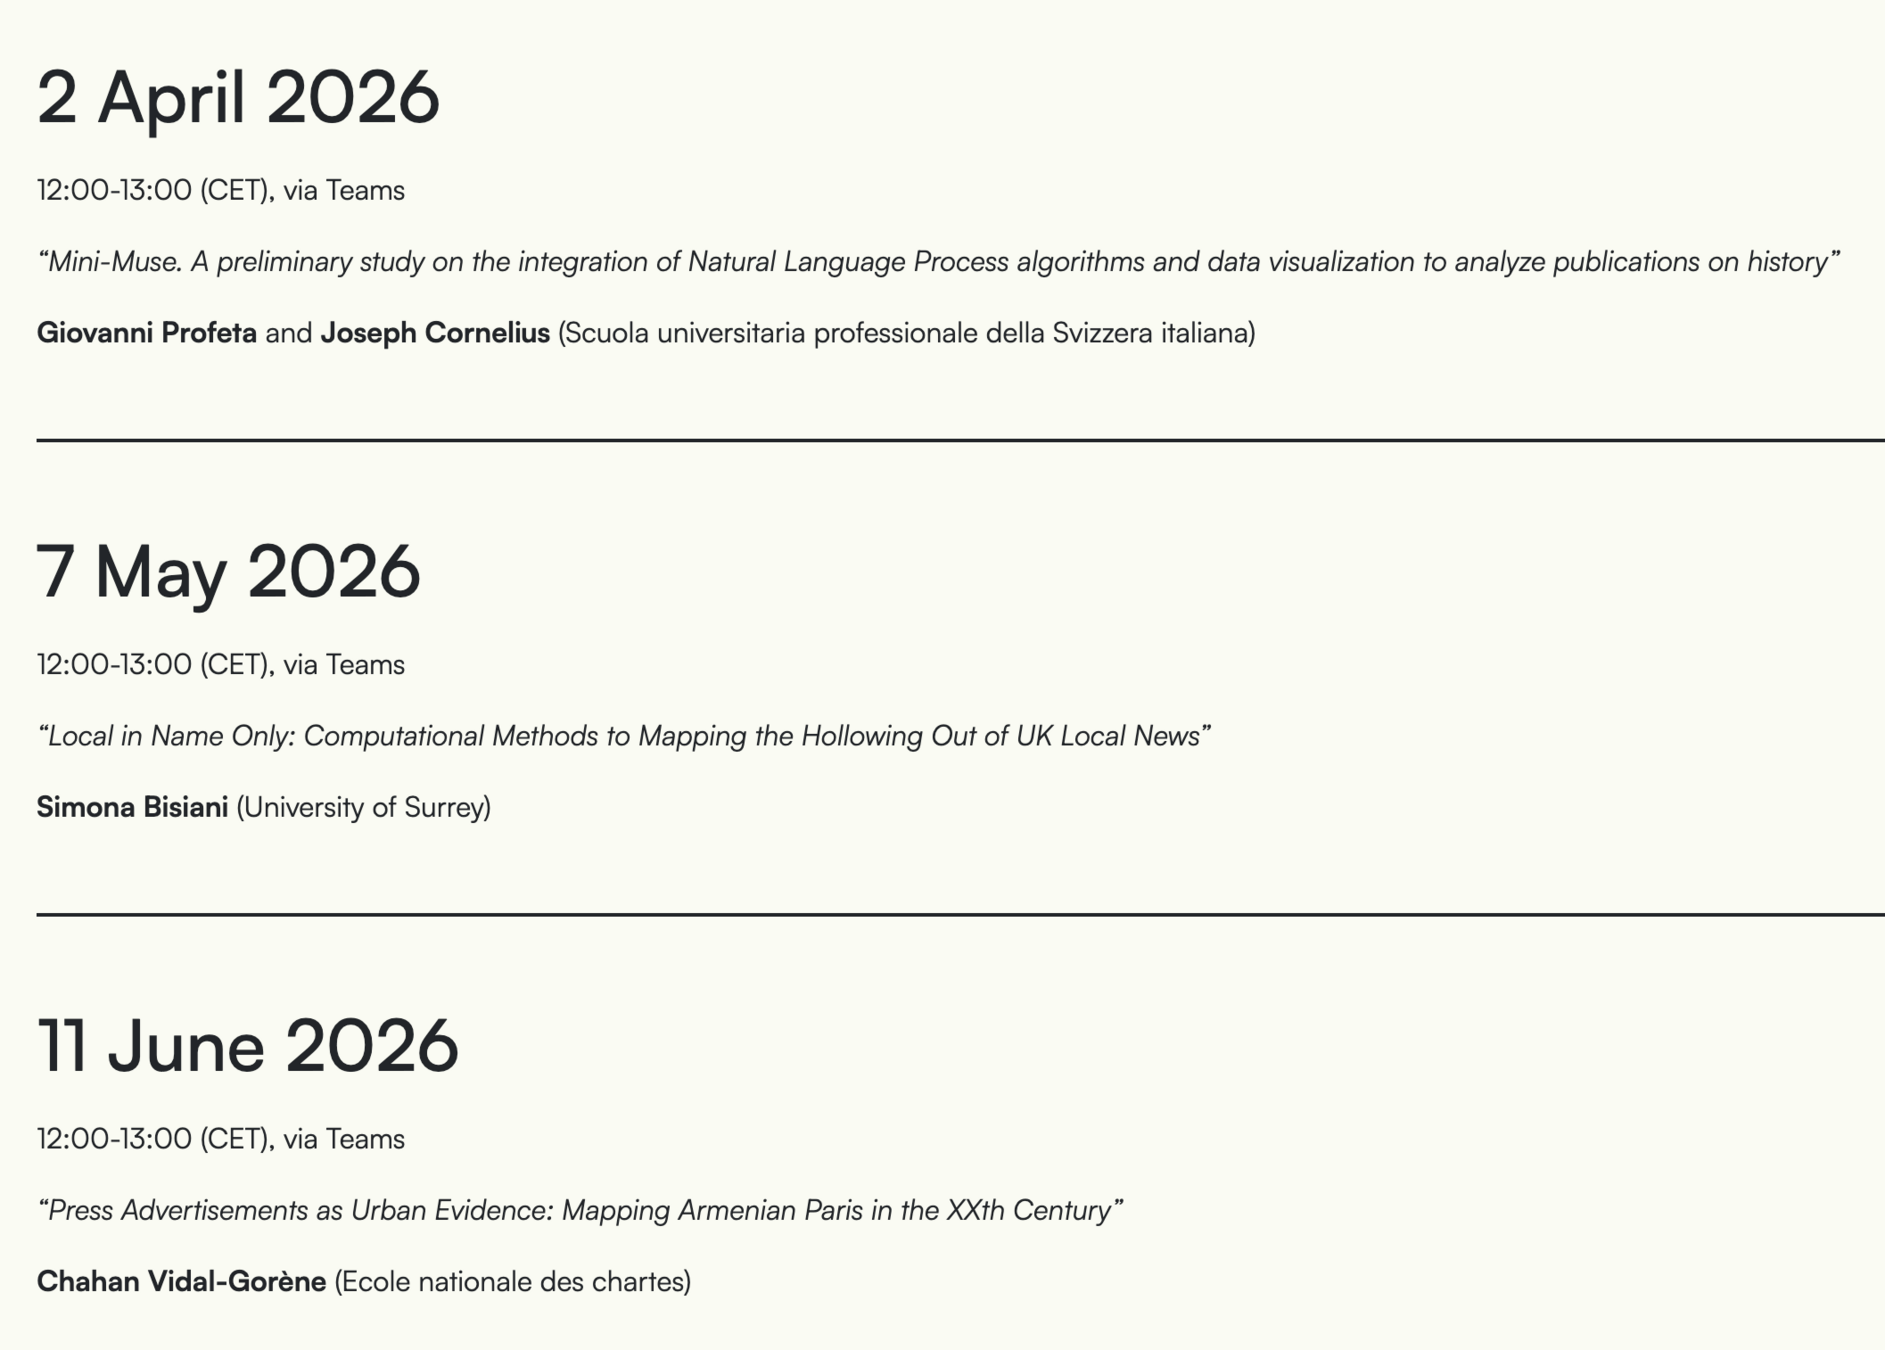
Impresso Seminar
Building bridges with existing communities
Conclusion
Ultimately, and as the project moves forward, we become increasingly aware that this interdisciplinary collaboration is not just a way of bridging the initial gap between collections and the general public.
It is also about bridging our scientific methods and knowledge, which has become a valuable outcome of the project in its own right.
Digital history: a way to bridge the gap(s)?
History
Computer science
Collections
Users
Thank you for your attention!
An example of how the tools developed by Impresso can be used to address a media history question
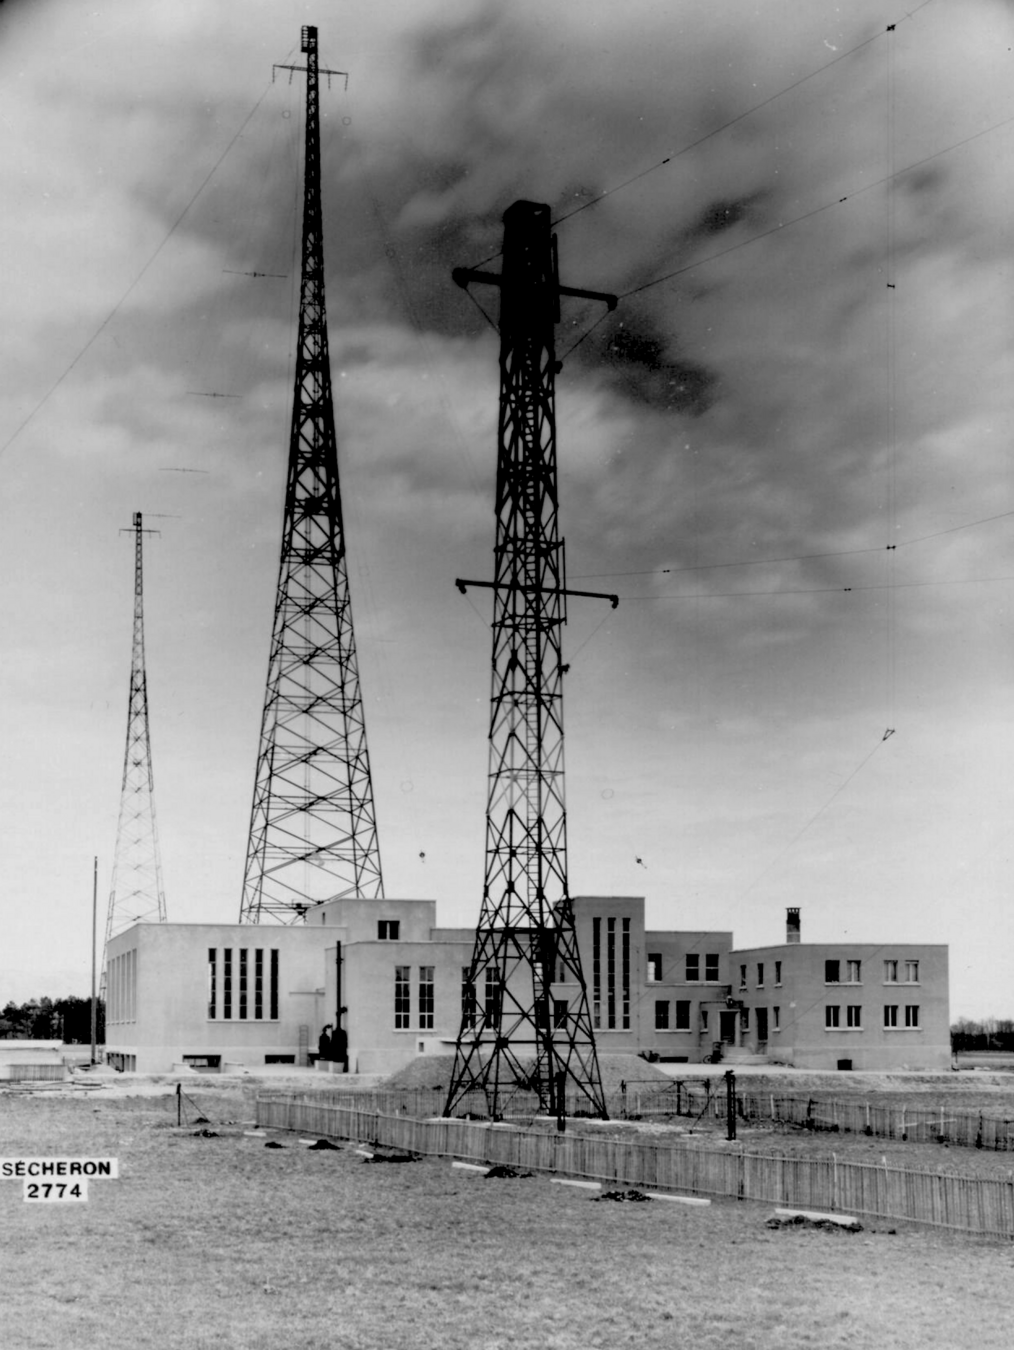
Radio Nations in Prangins in the 1930s
United Nations Archives Geneva (P132-01-007)
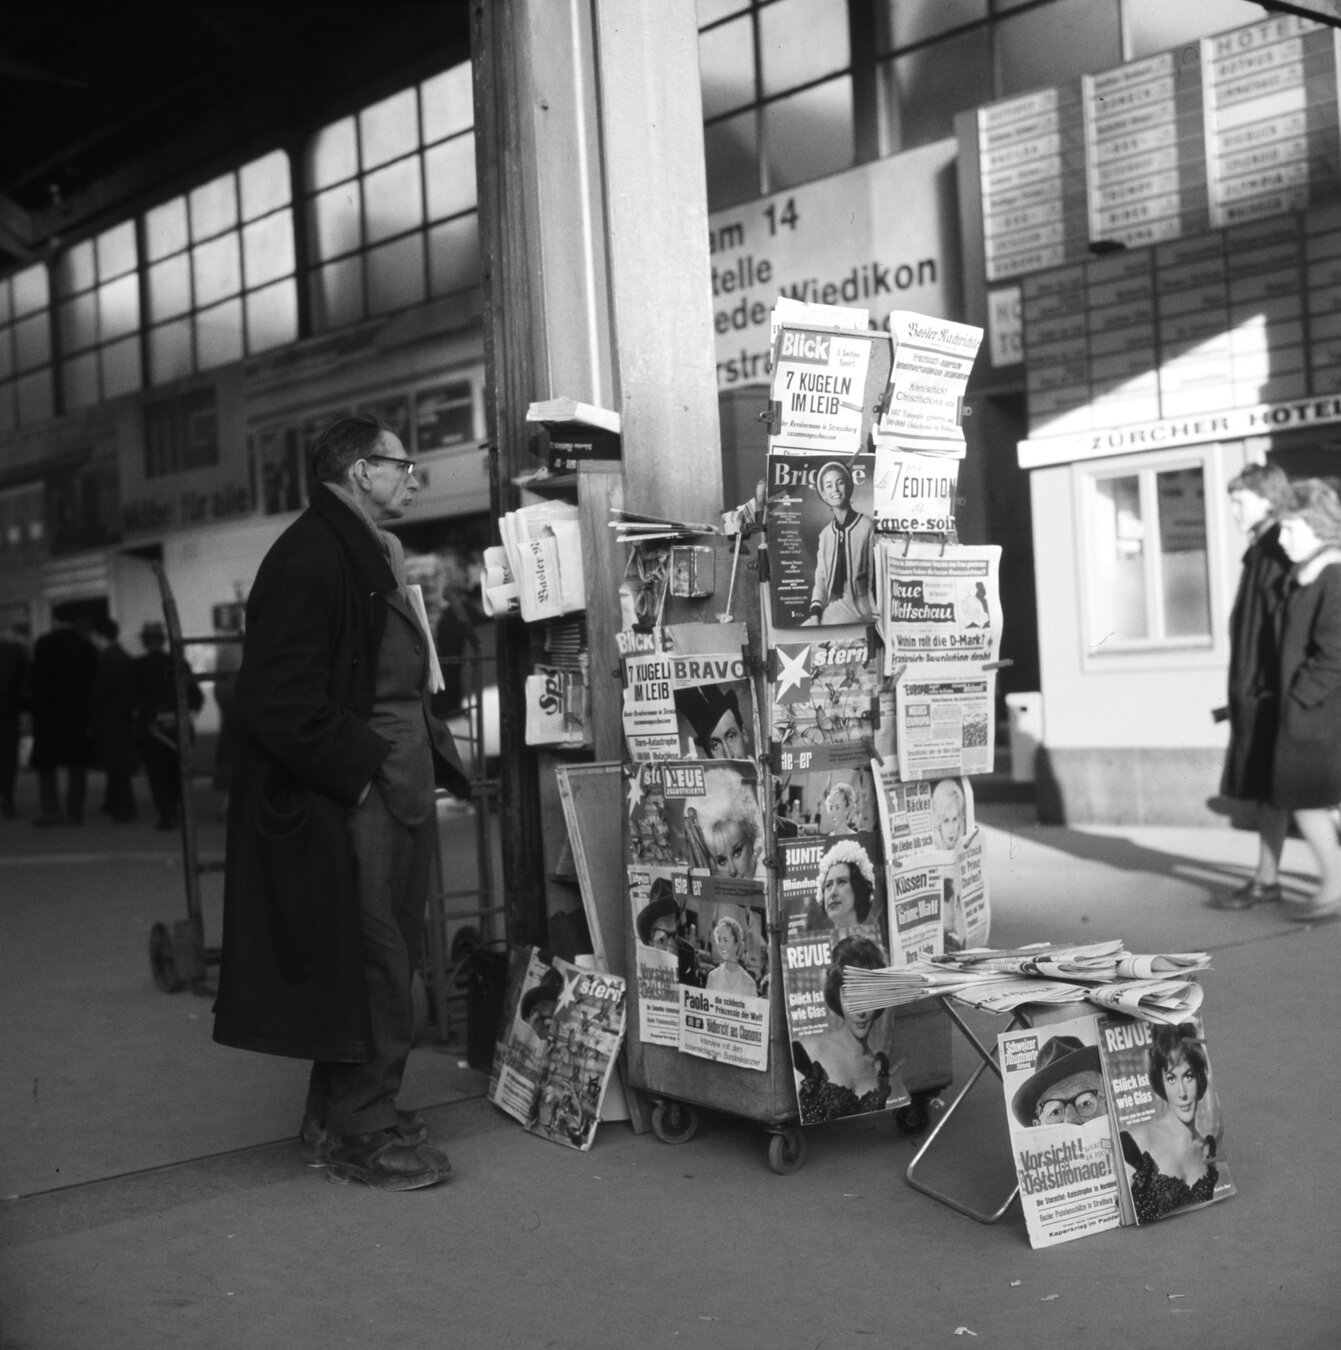
Newspaper stand at Zurich train station, 1962
ETH-Bibliothek Zürich (Com_C17-073-047-001-005)
What does the press have to say about radio?
BONUS
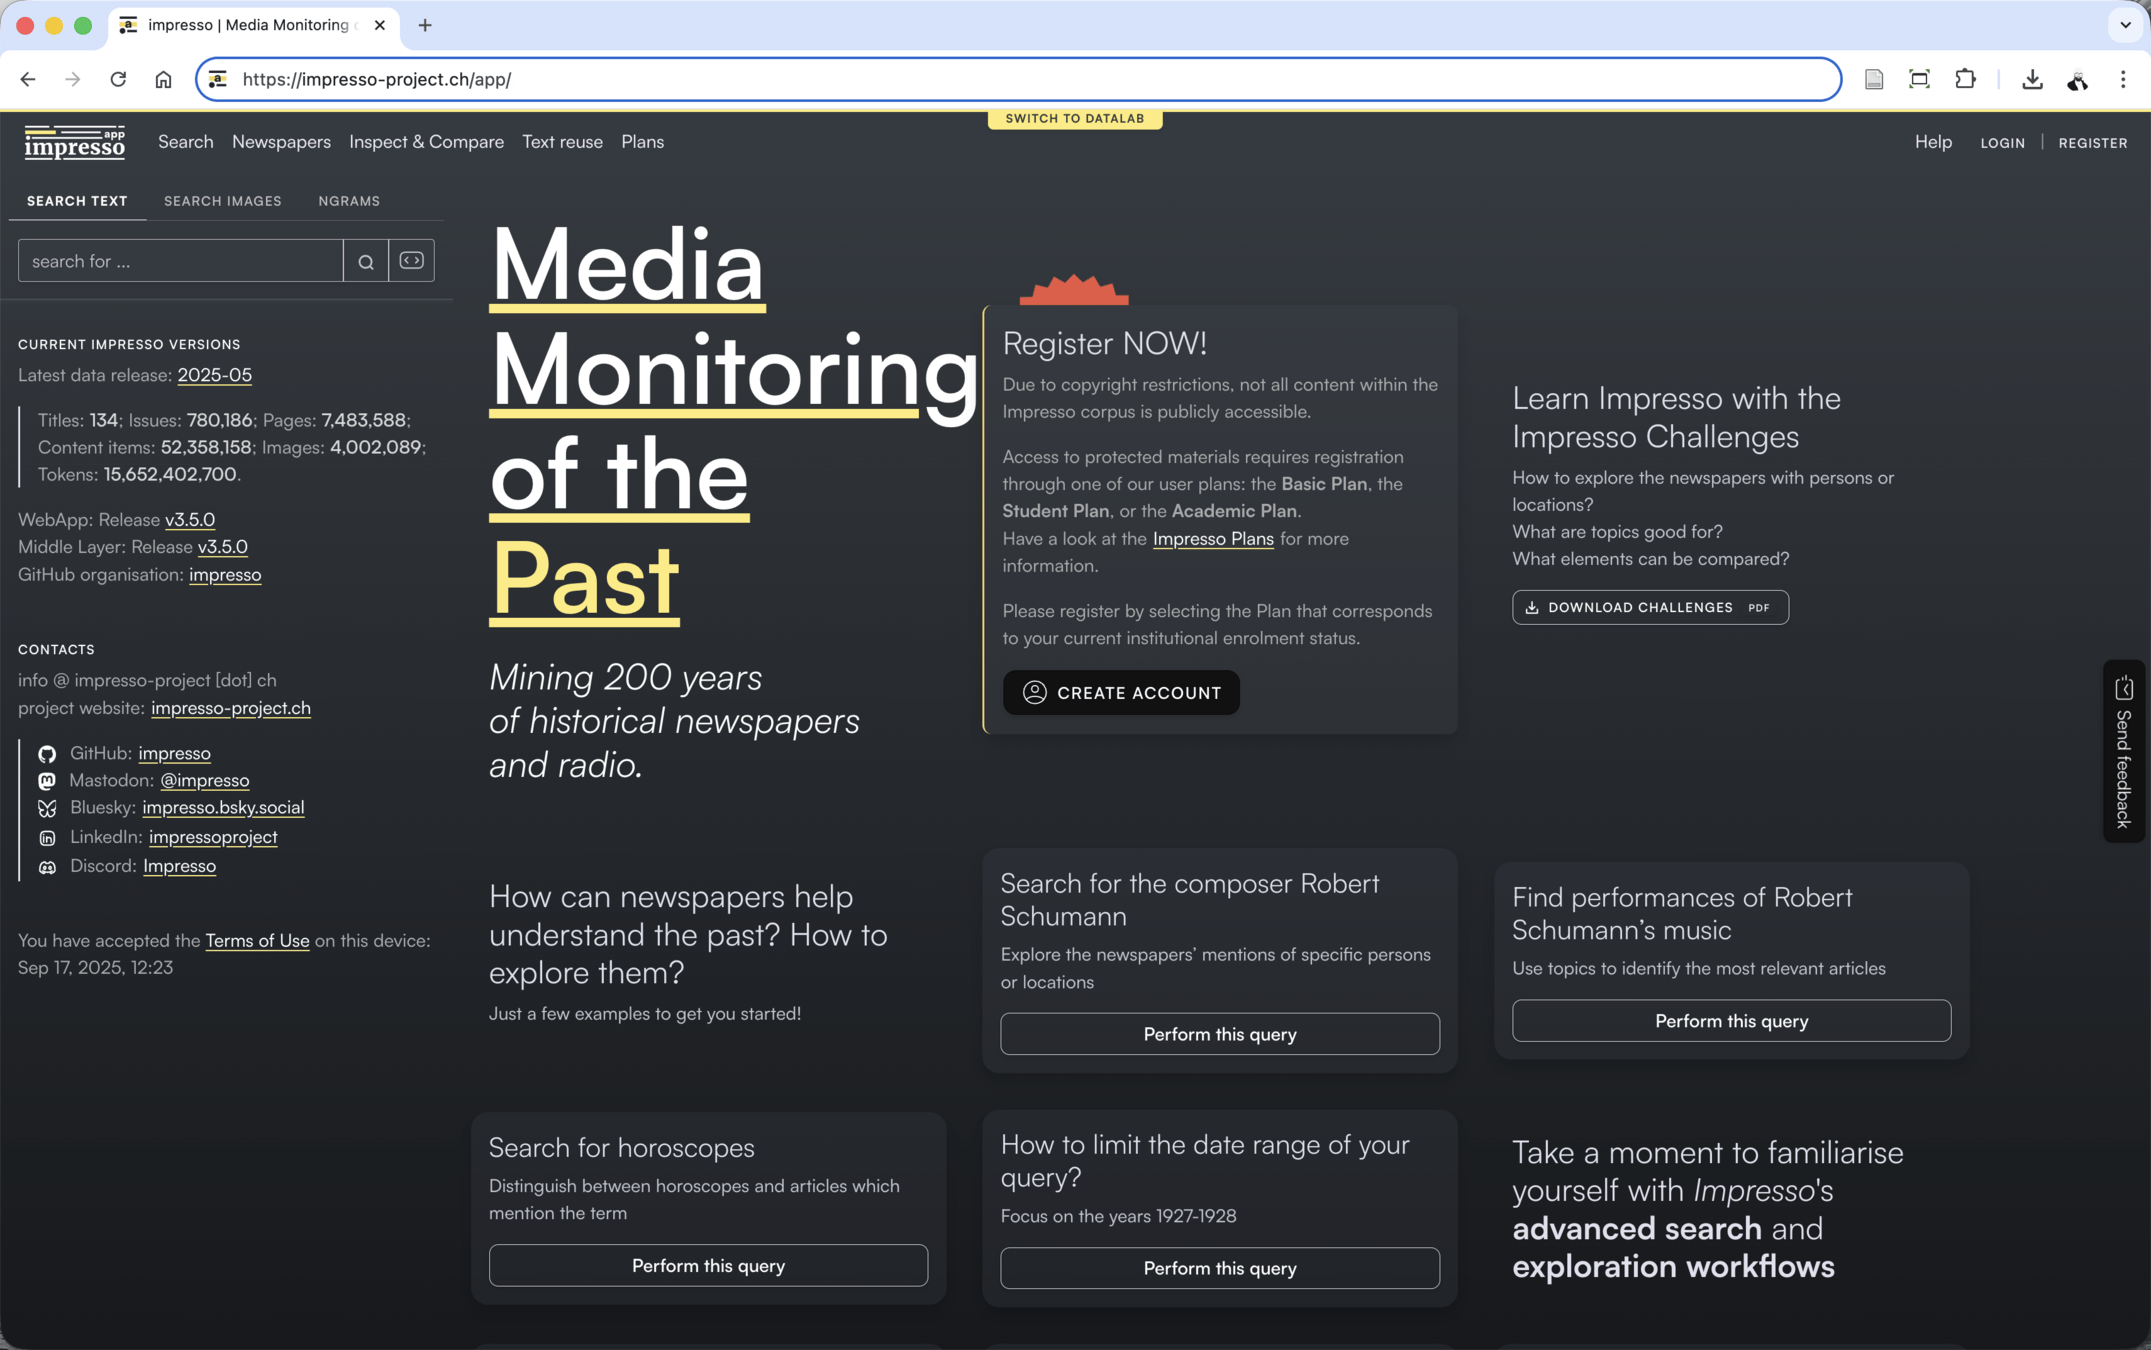
Let's browse the digitized press
Welcome to the Impresso web app
Before starting a search, log in to access more content and facsimiles.
Impresso app
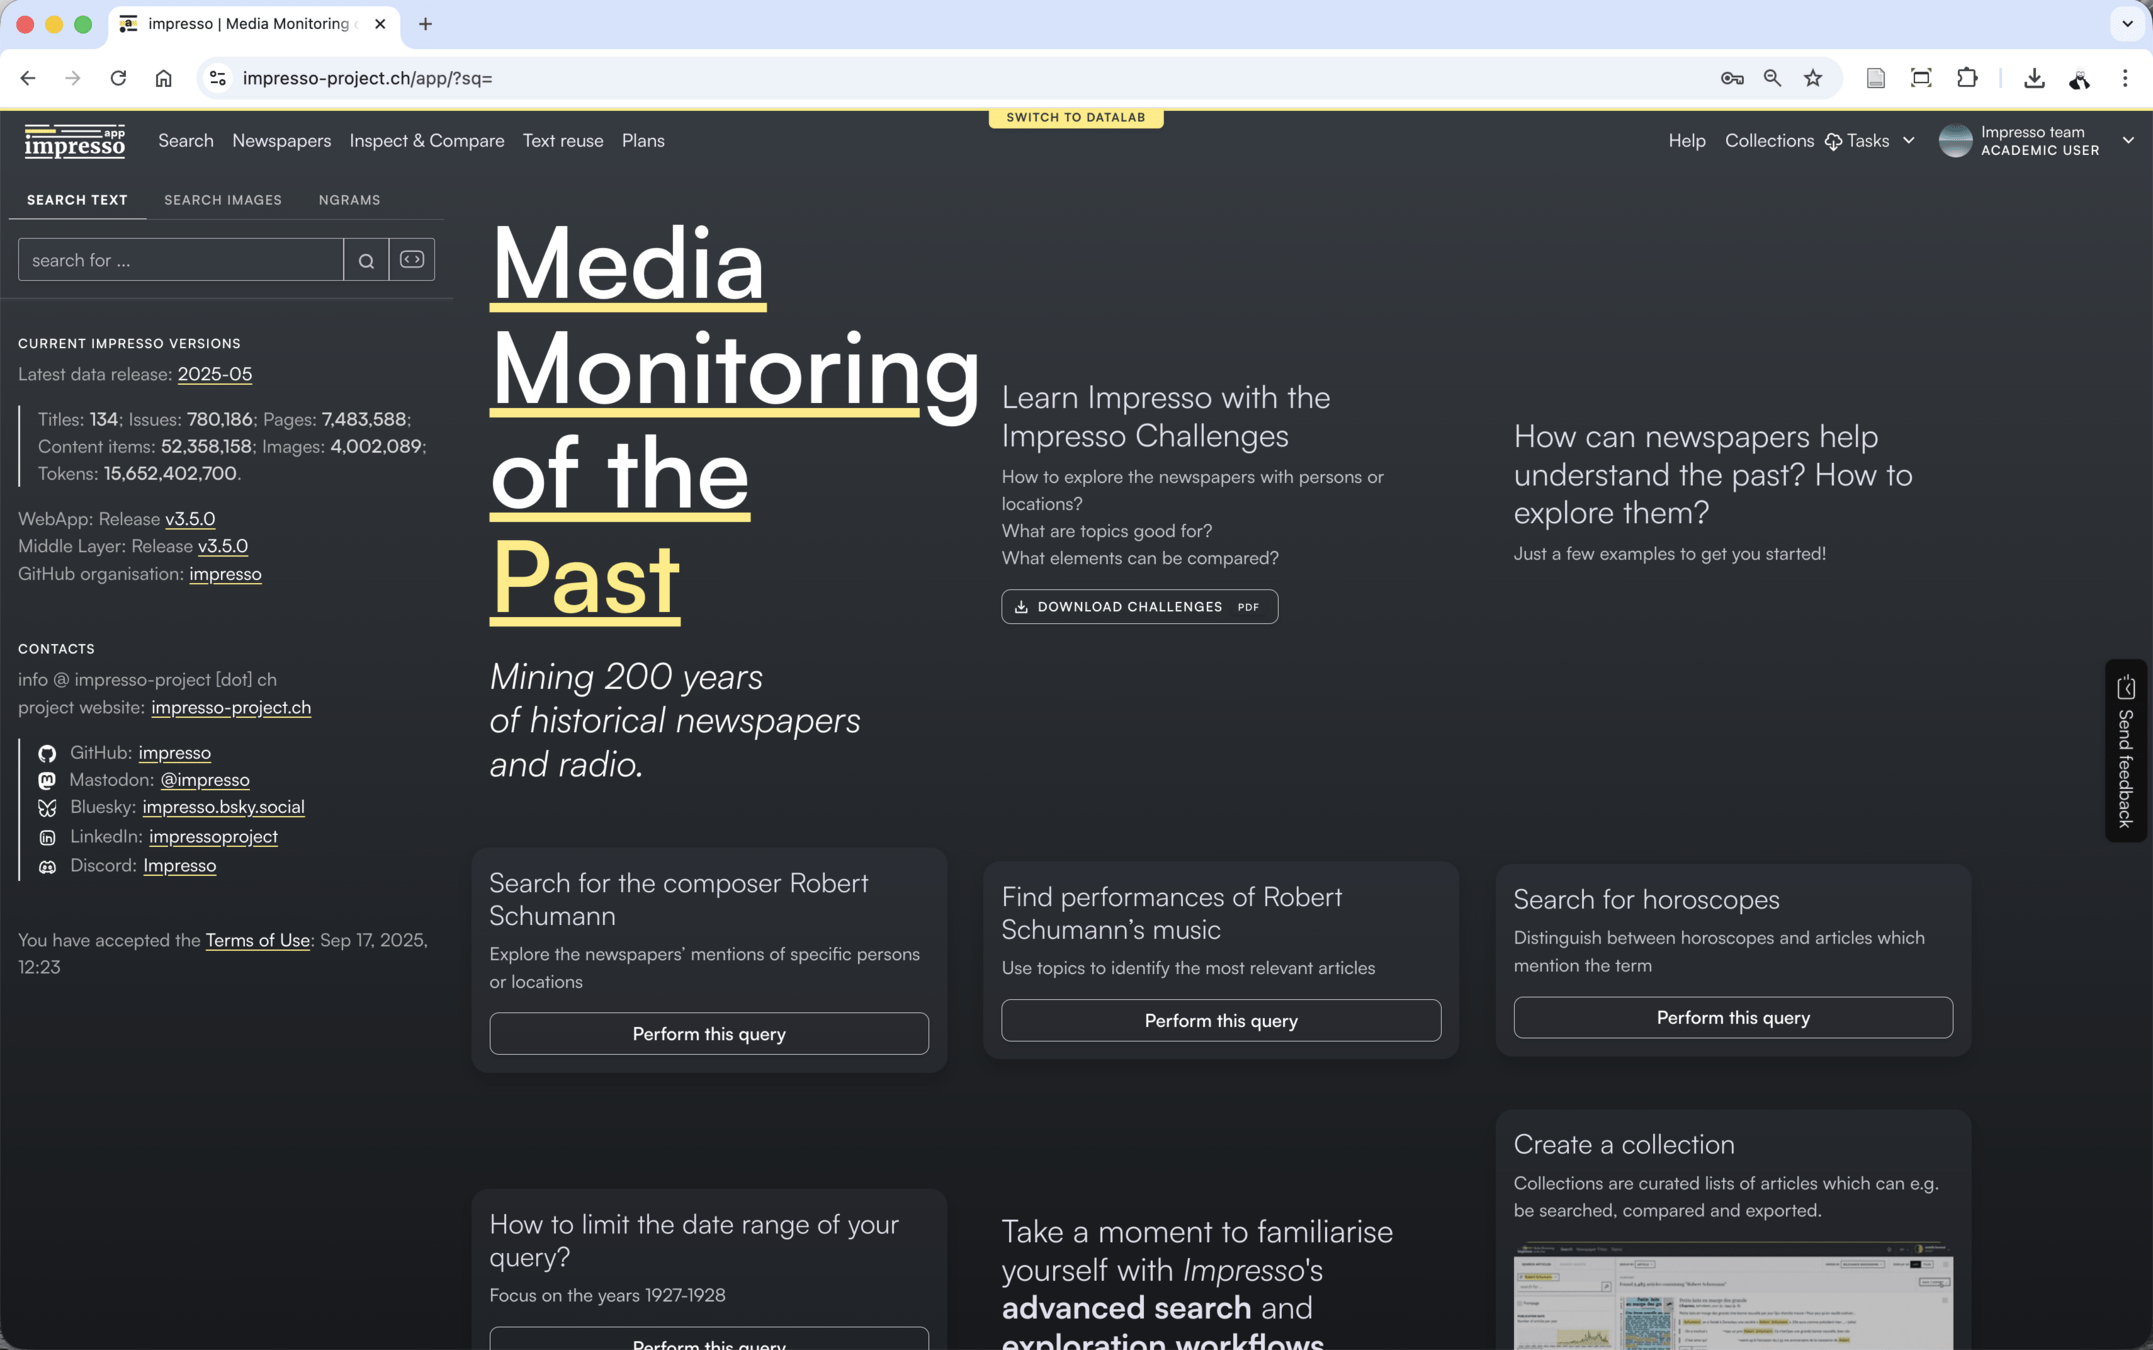
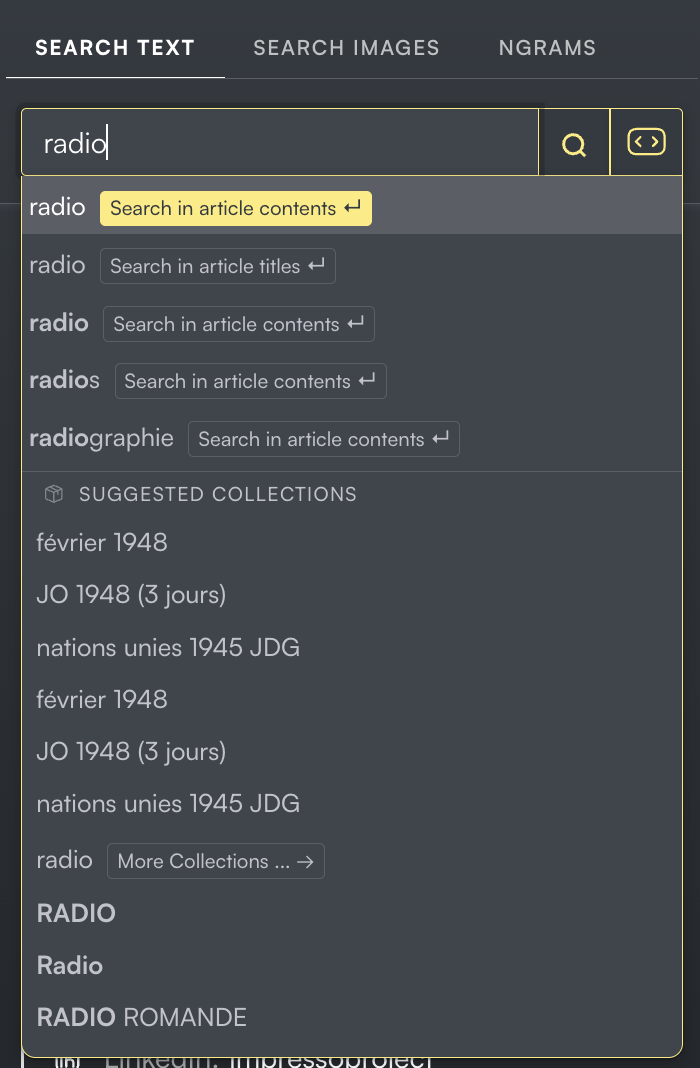
Let's search for "radio" in article contents
Impresso app
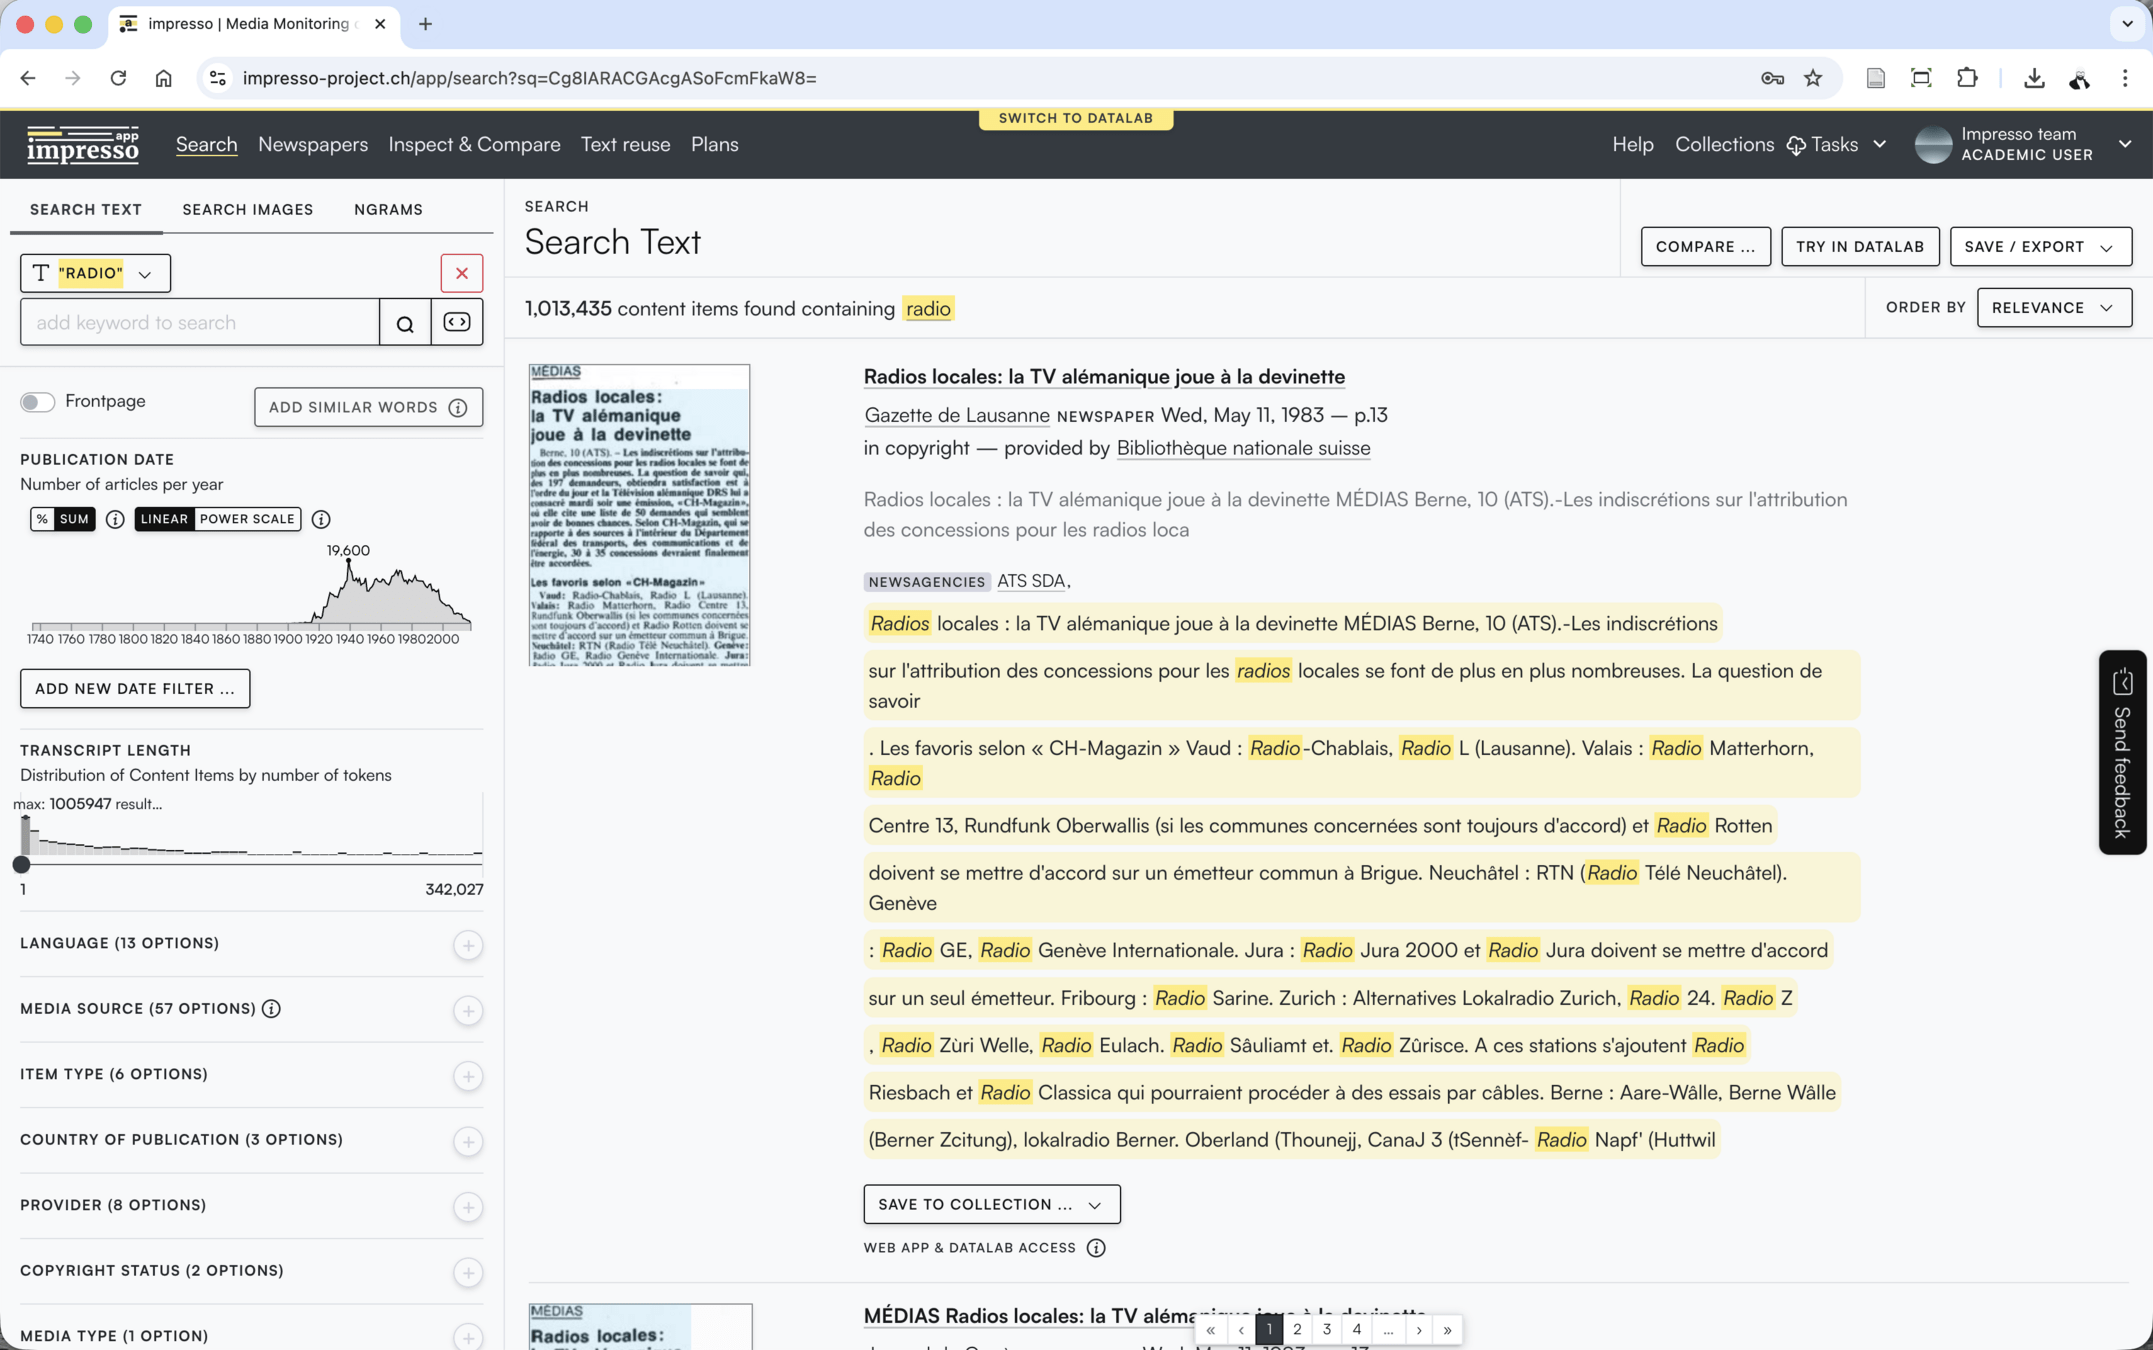
This very broad search returns over a million results
Search result
But what are we looking at?
Search result
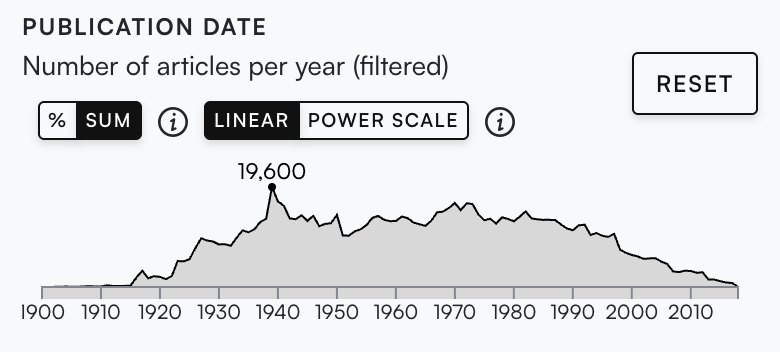
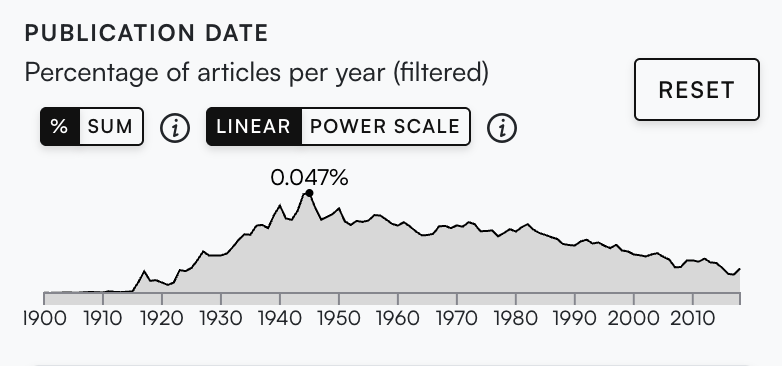
Total number of articles
Proportion (%)
For example: Is the result biased by the nature of the corpus, since some newspapers are only available during certain periods?
But what are we looking at?
Search result
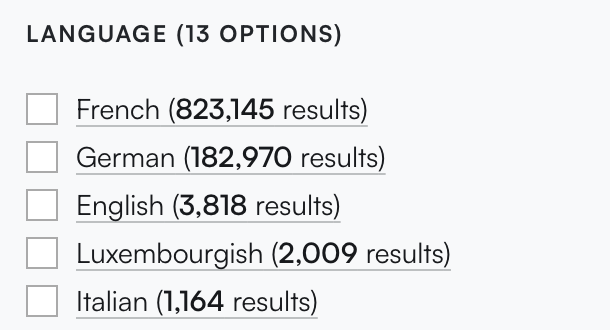
Or: Does this keyword mainly return results in a specific language, a specific country, or from specific news outlets?
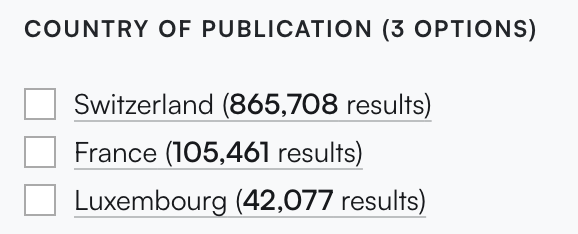
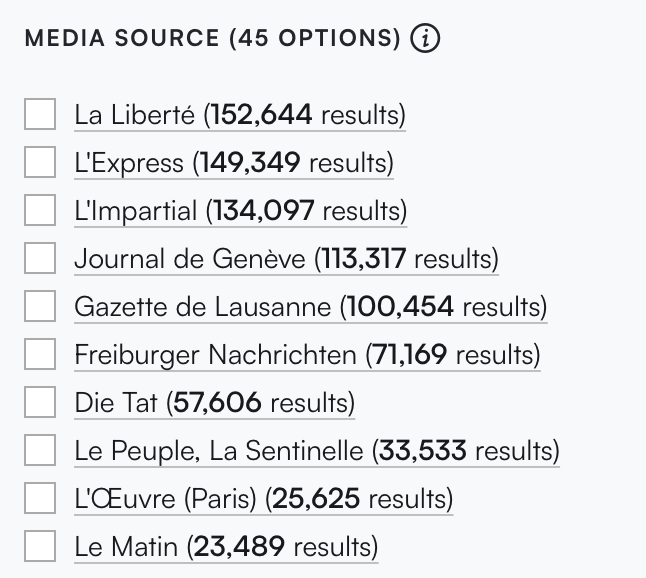
And is that even the right keyword?
Search result
This is a classic problem in searching large text corpora: keywords are an imperfect way to filter
- Is the keyword polysemous?
Radio = the device, the institution, the broadcast?
- Does it appear in any other word?
Radioactivity, Radiography, ...
- Is the concept we're looking for gradually being replaced by another one?
- Are there different ways to spell it?
(in the case of radio, no problem)
Radio -> Podcast
- Does this word often cause OCR issues?
radio, r4dio, radid, adio, 'radio, ...
- Should it be paired with other keywords?
Radio AND Broadcast, Radio OR Antenna
By selecting a date range (in this case, a decade), we reduced the number of results by a factor of 10.
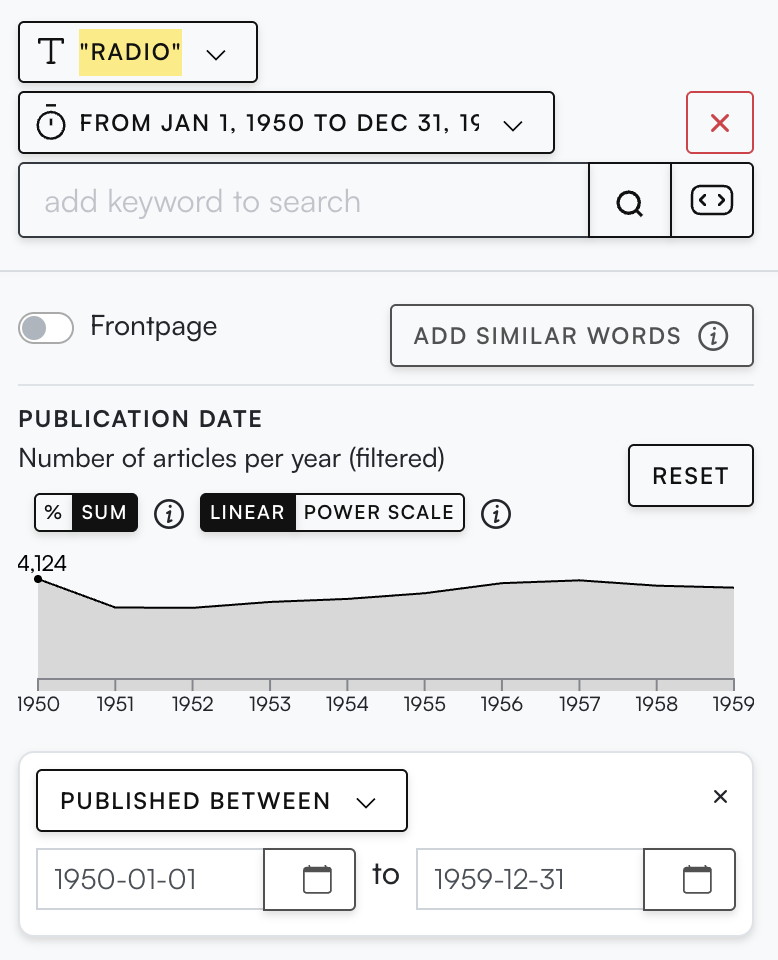

Filter by date
Let's narrow down the search using filters
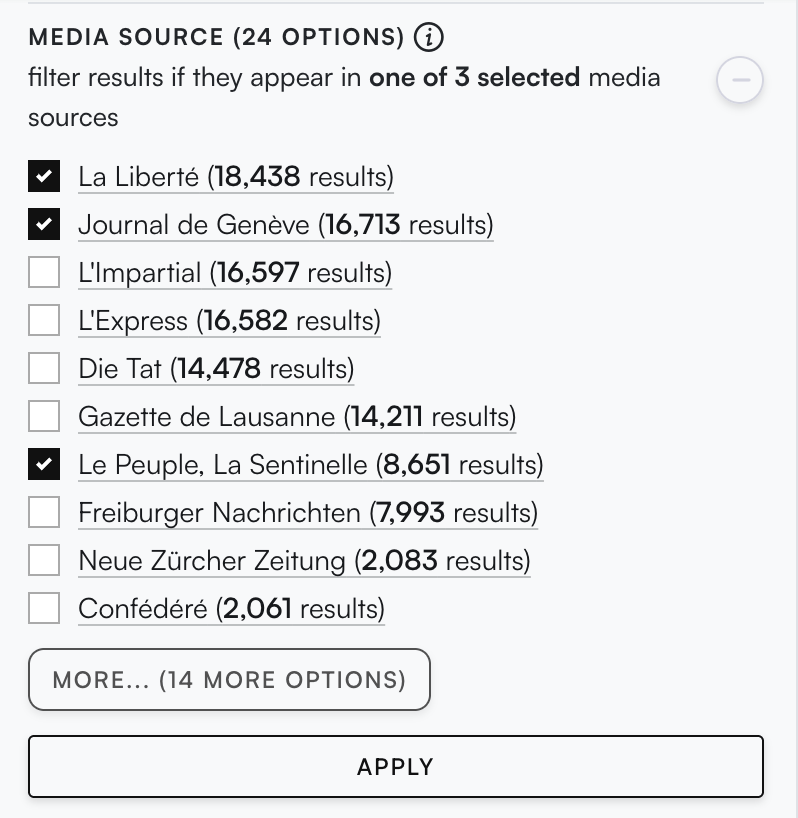

Filter by source
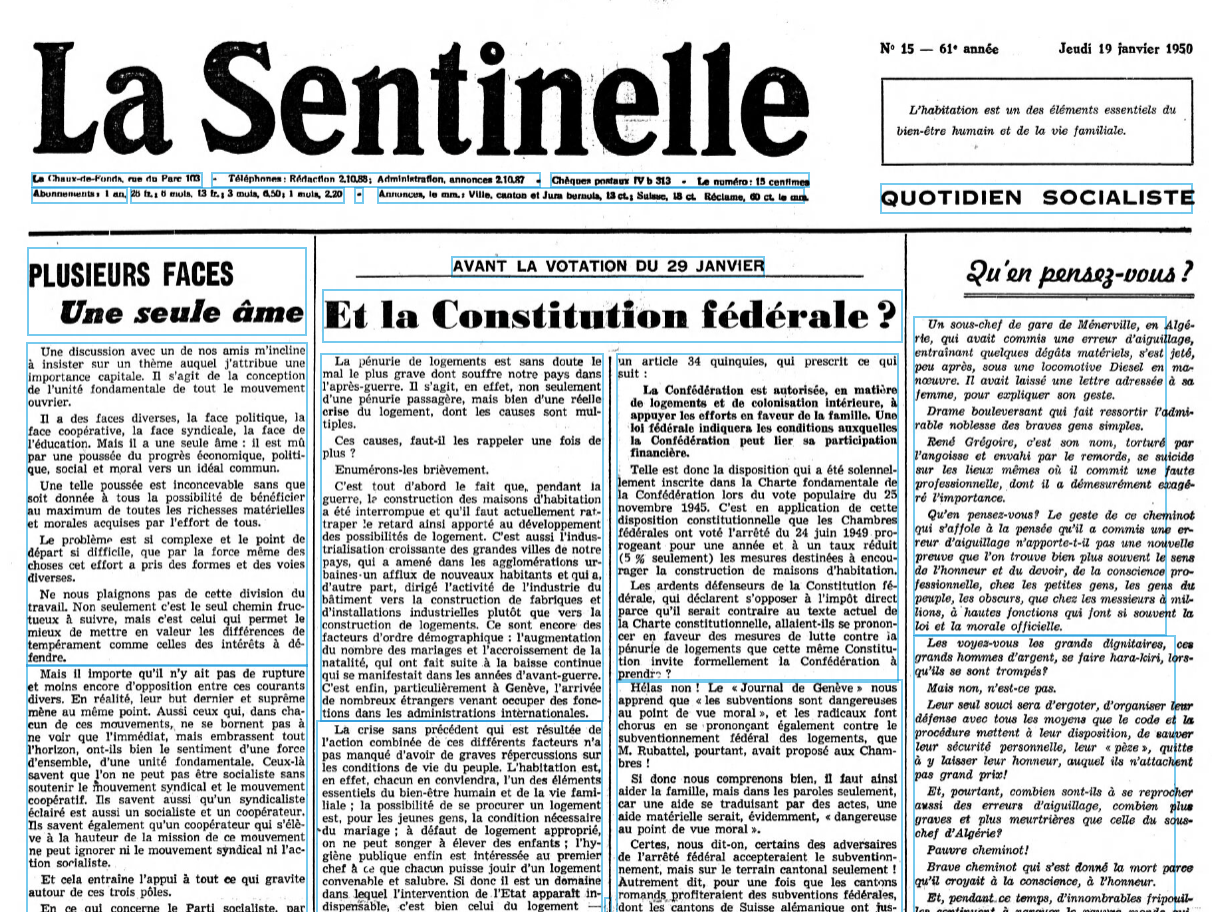
Here, three French-language Swiss newspapers from different regions and with different political leanings
Remove articles that are less than 100 words long
Separate articles from advertisements
Keep only what is featured on the front page
Using other filters to narrow the results
Search filters
Search summary
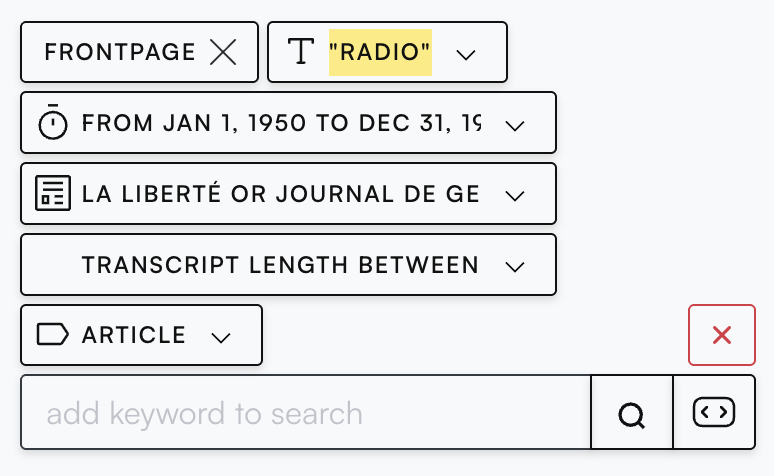

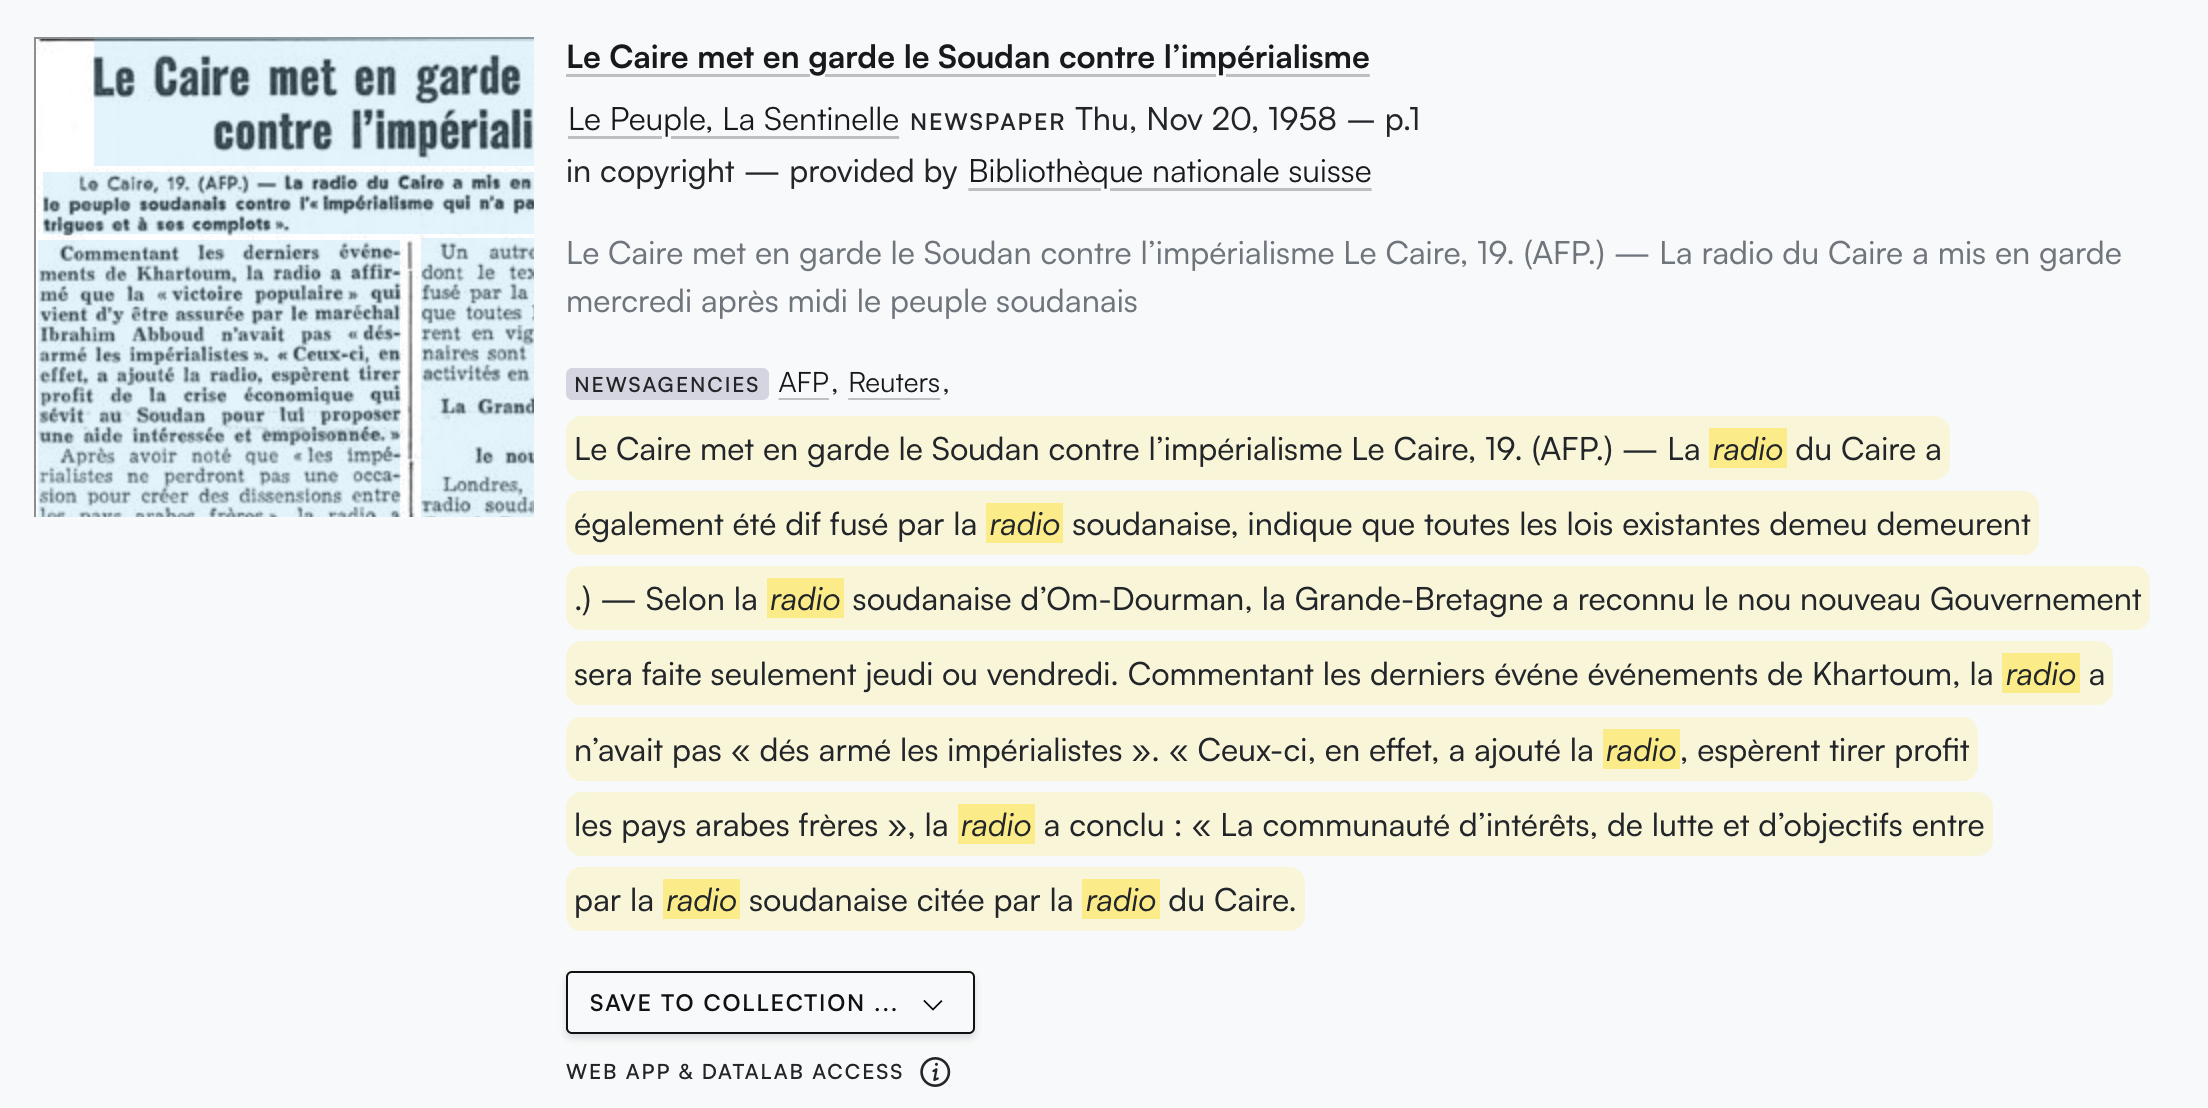
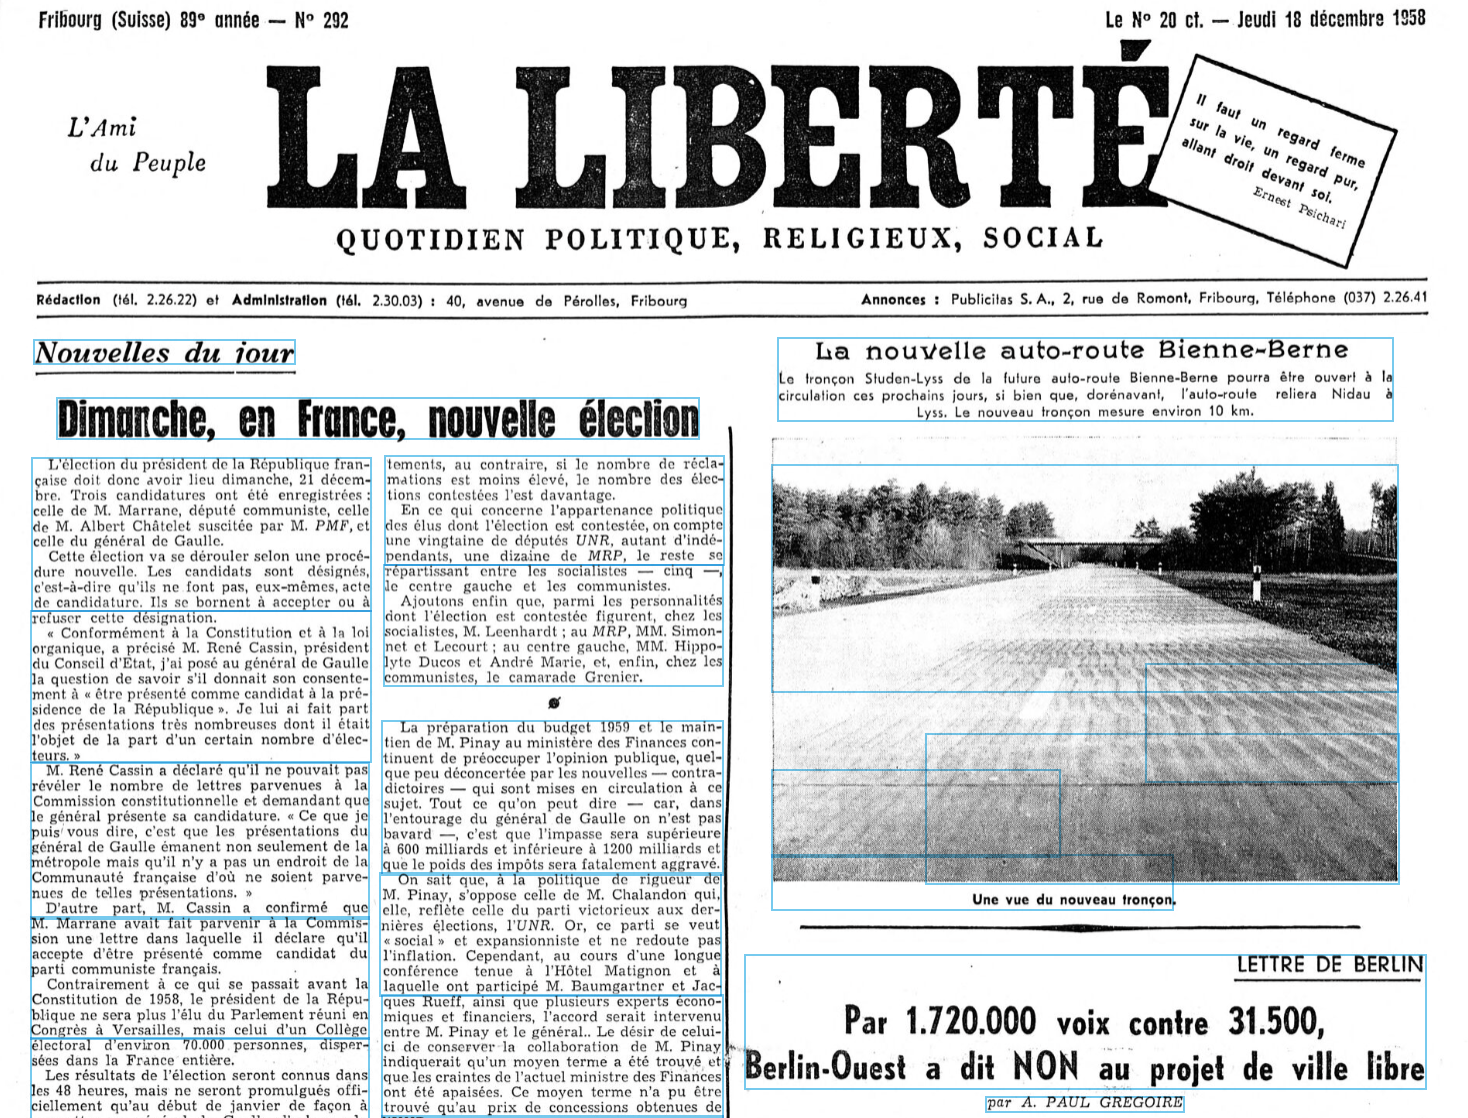
Content item
The facsimile is visible only if you have access rights
Exploration
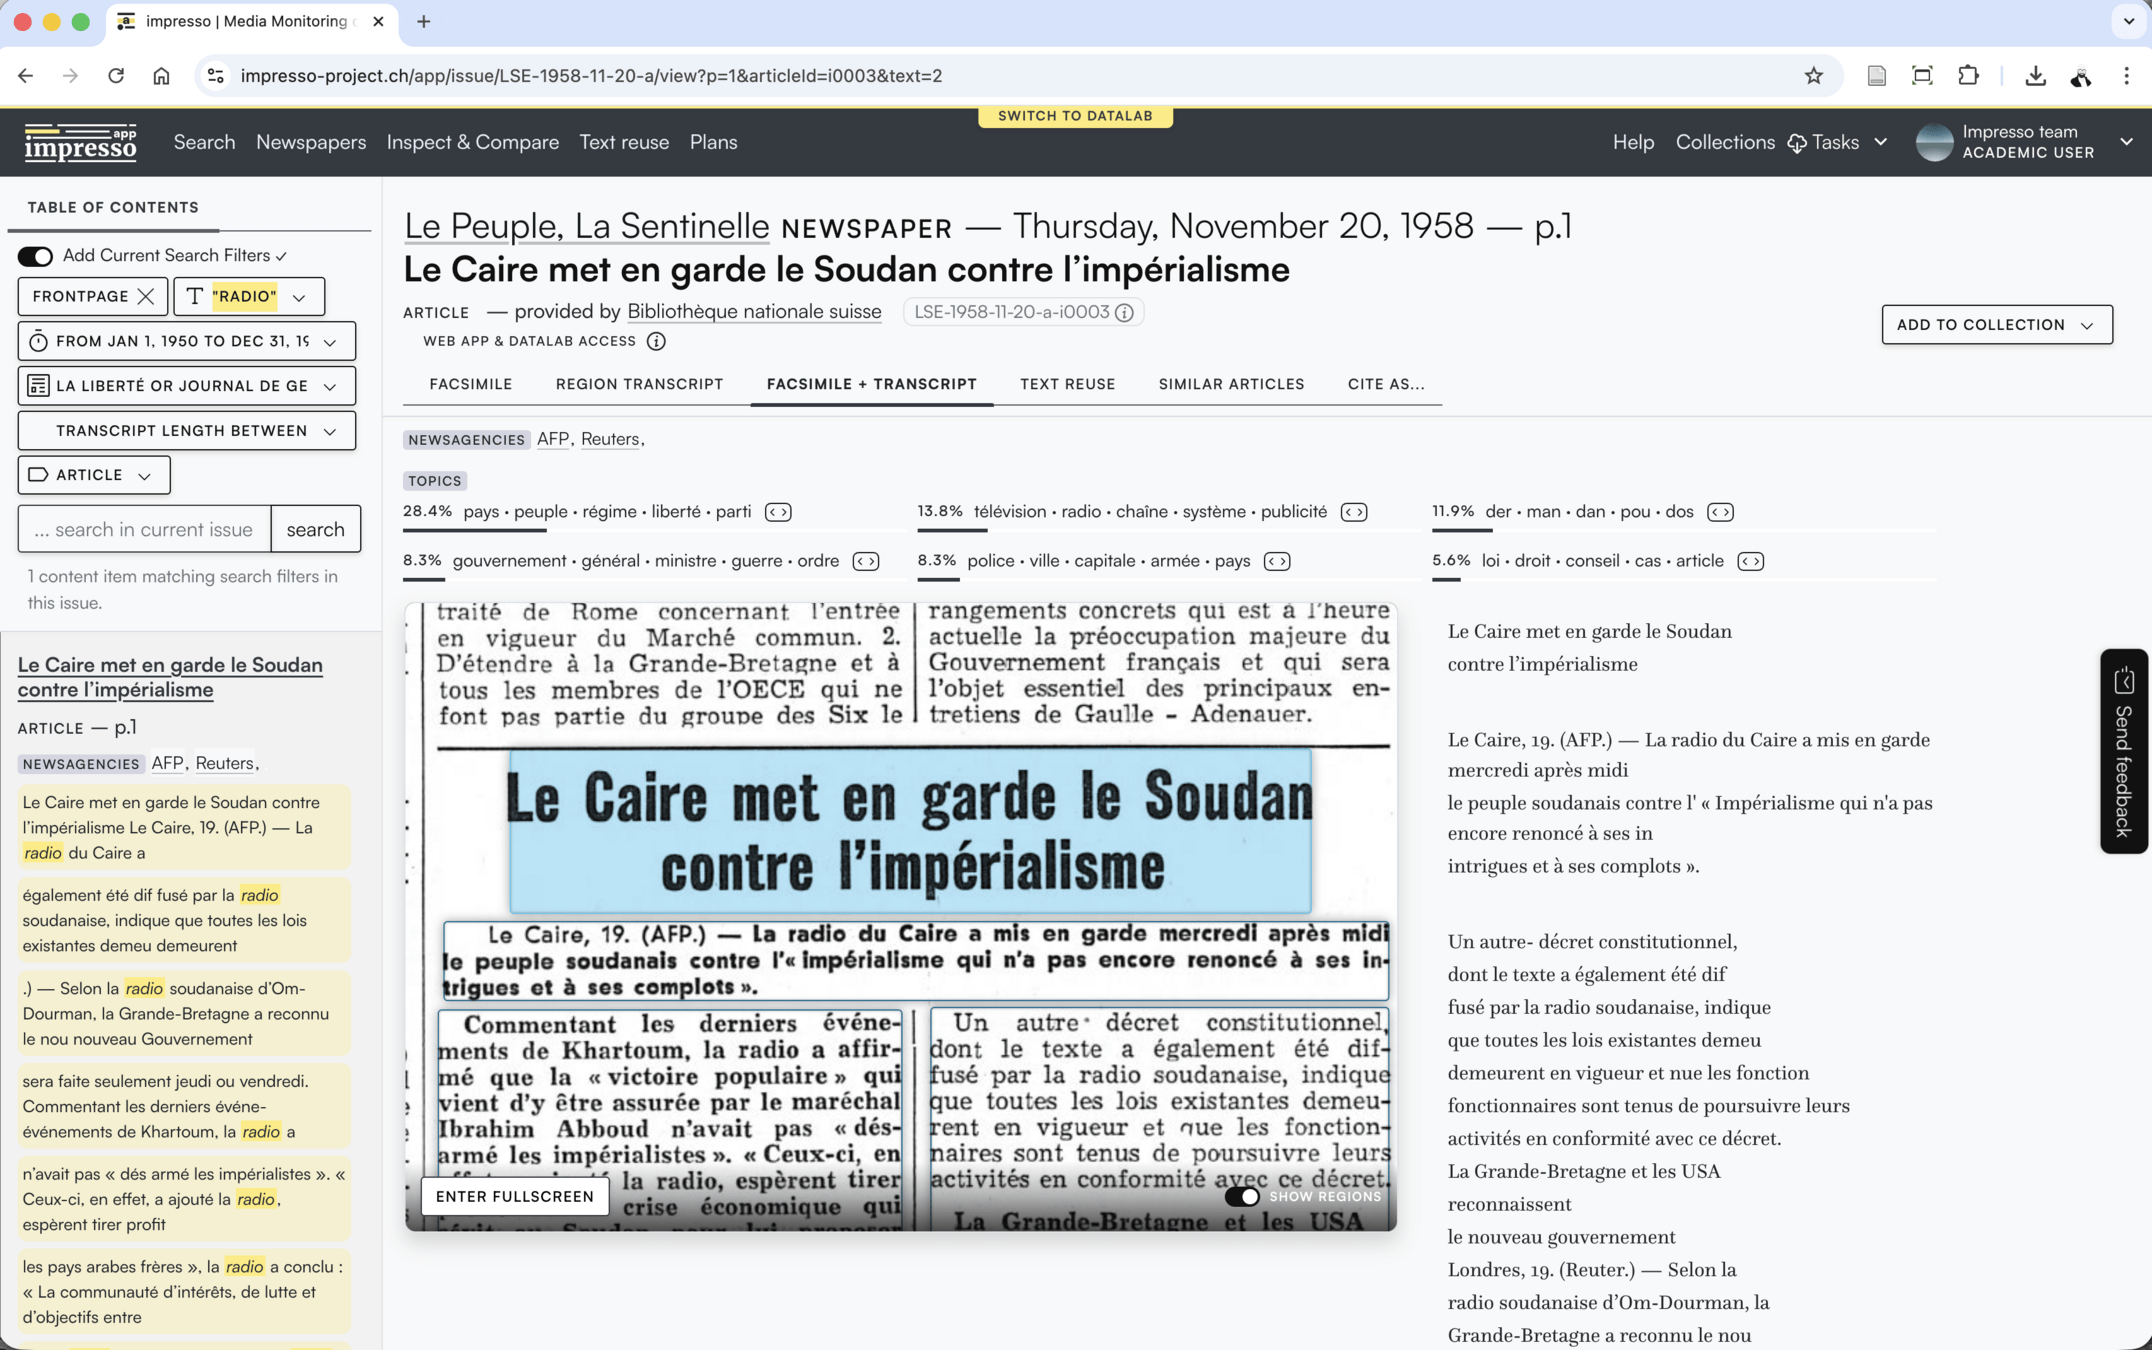
Each result is available as a facsimile and/or transcript
Exploration
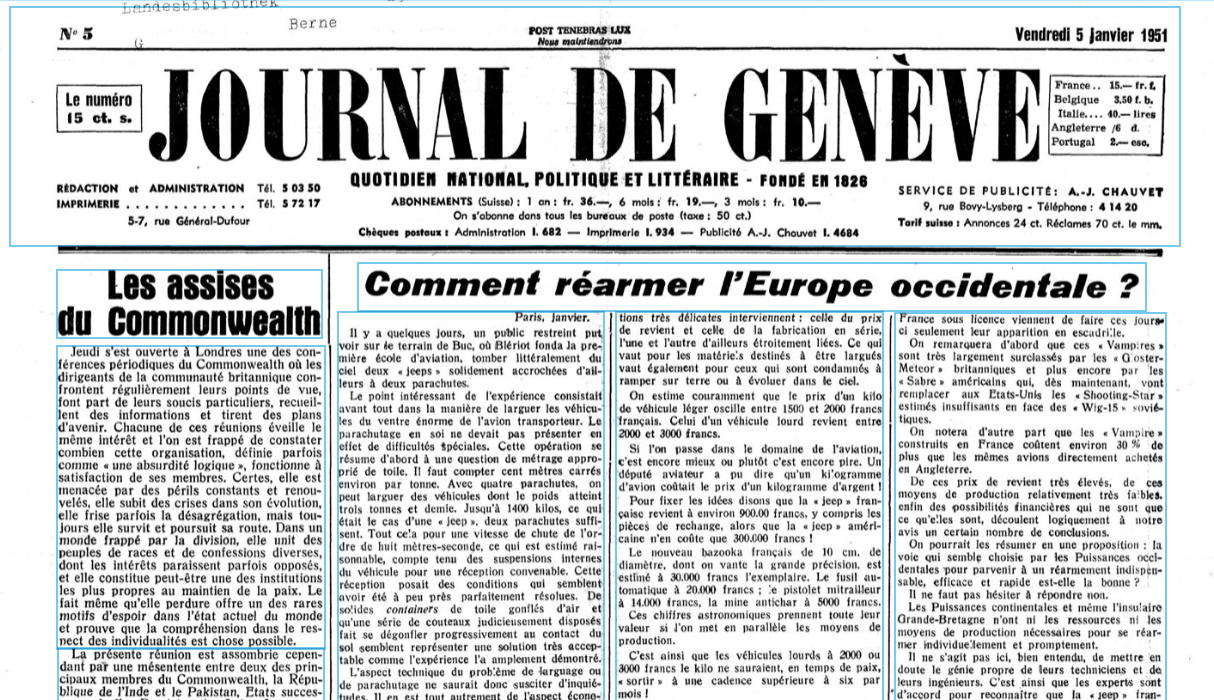
Article in context, along with the entire issue
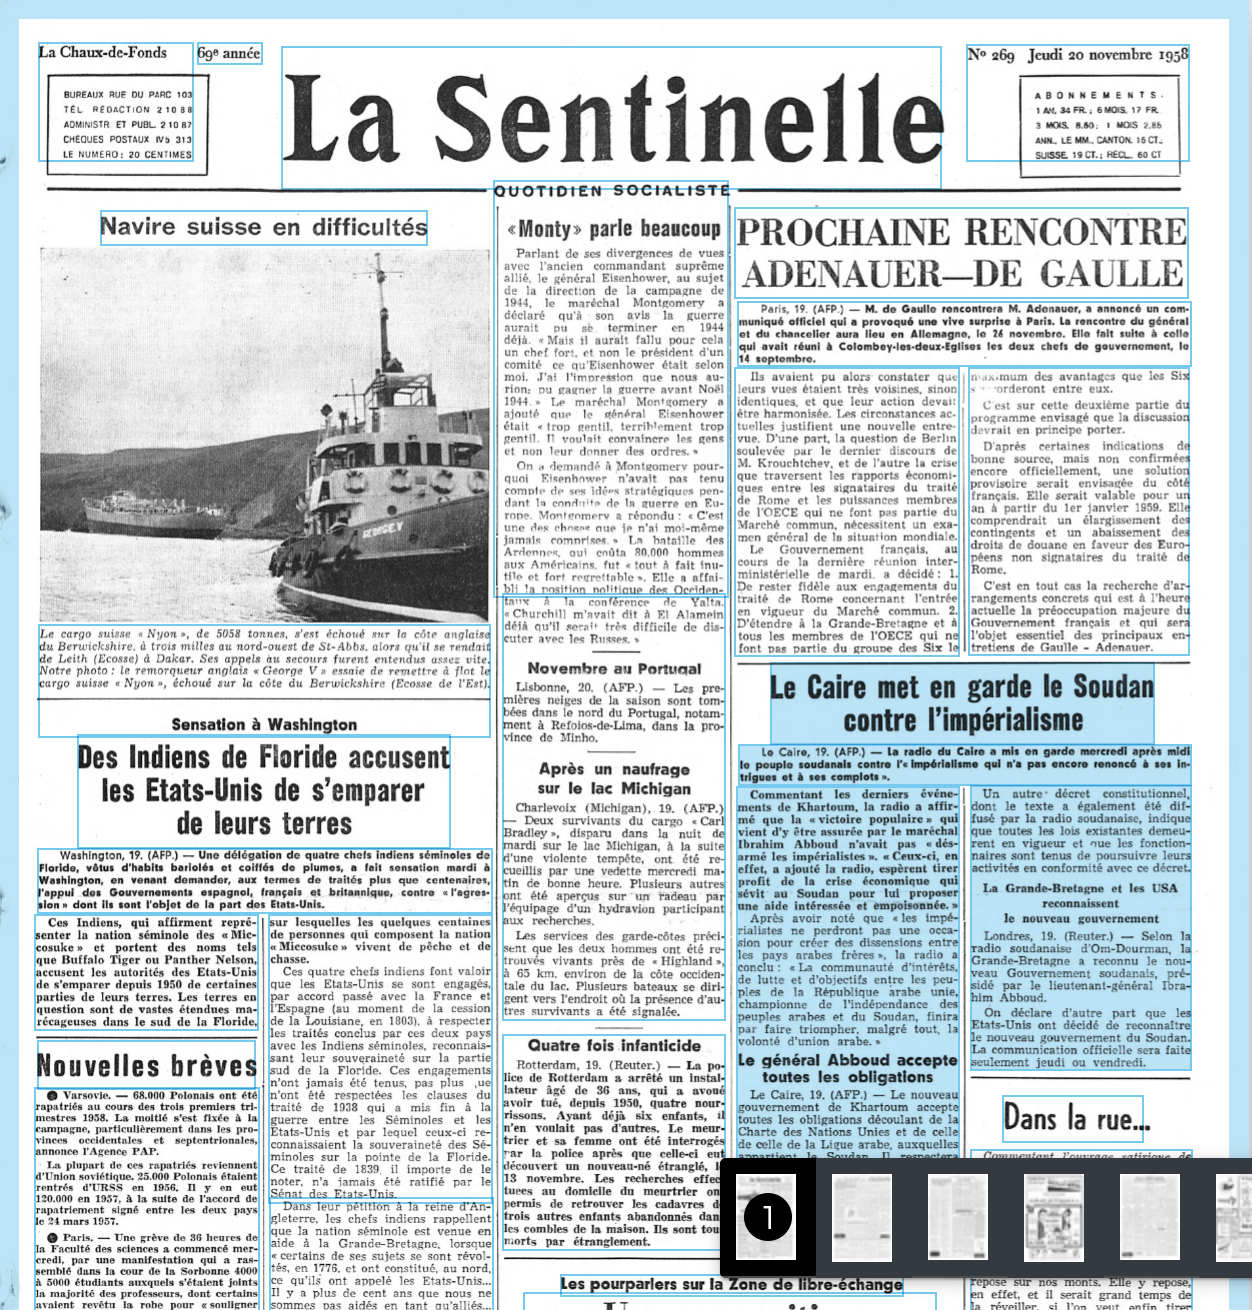
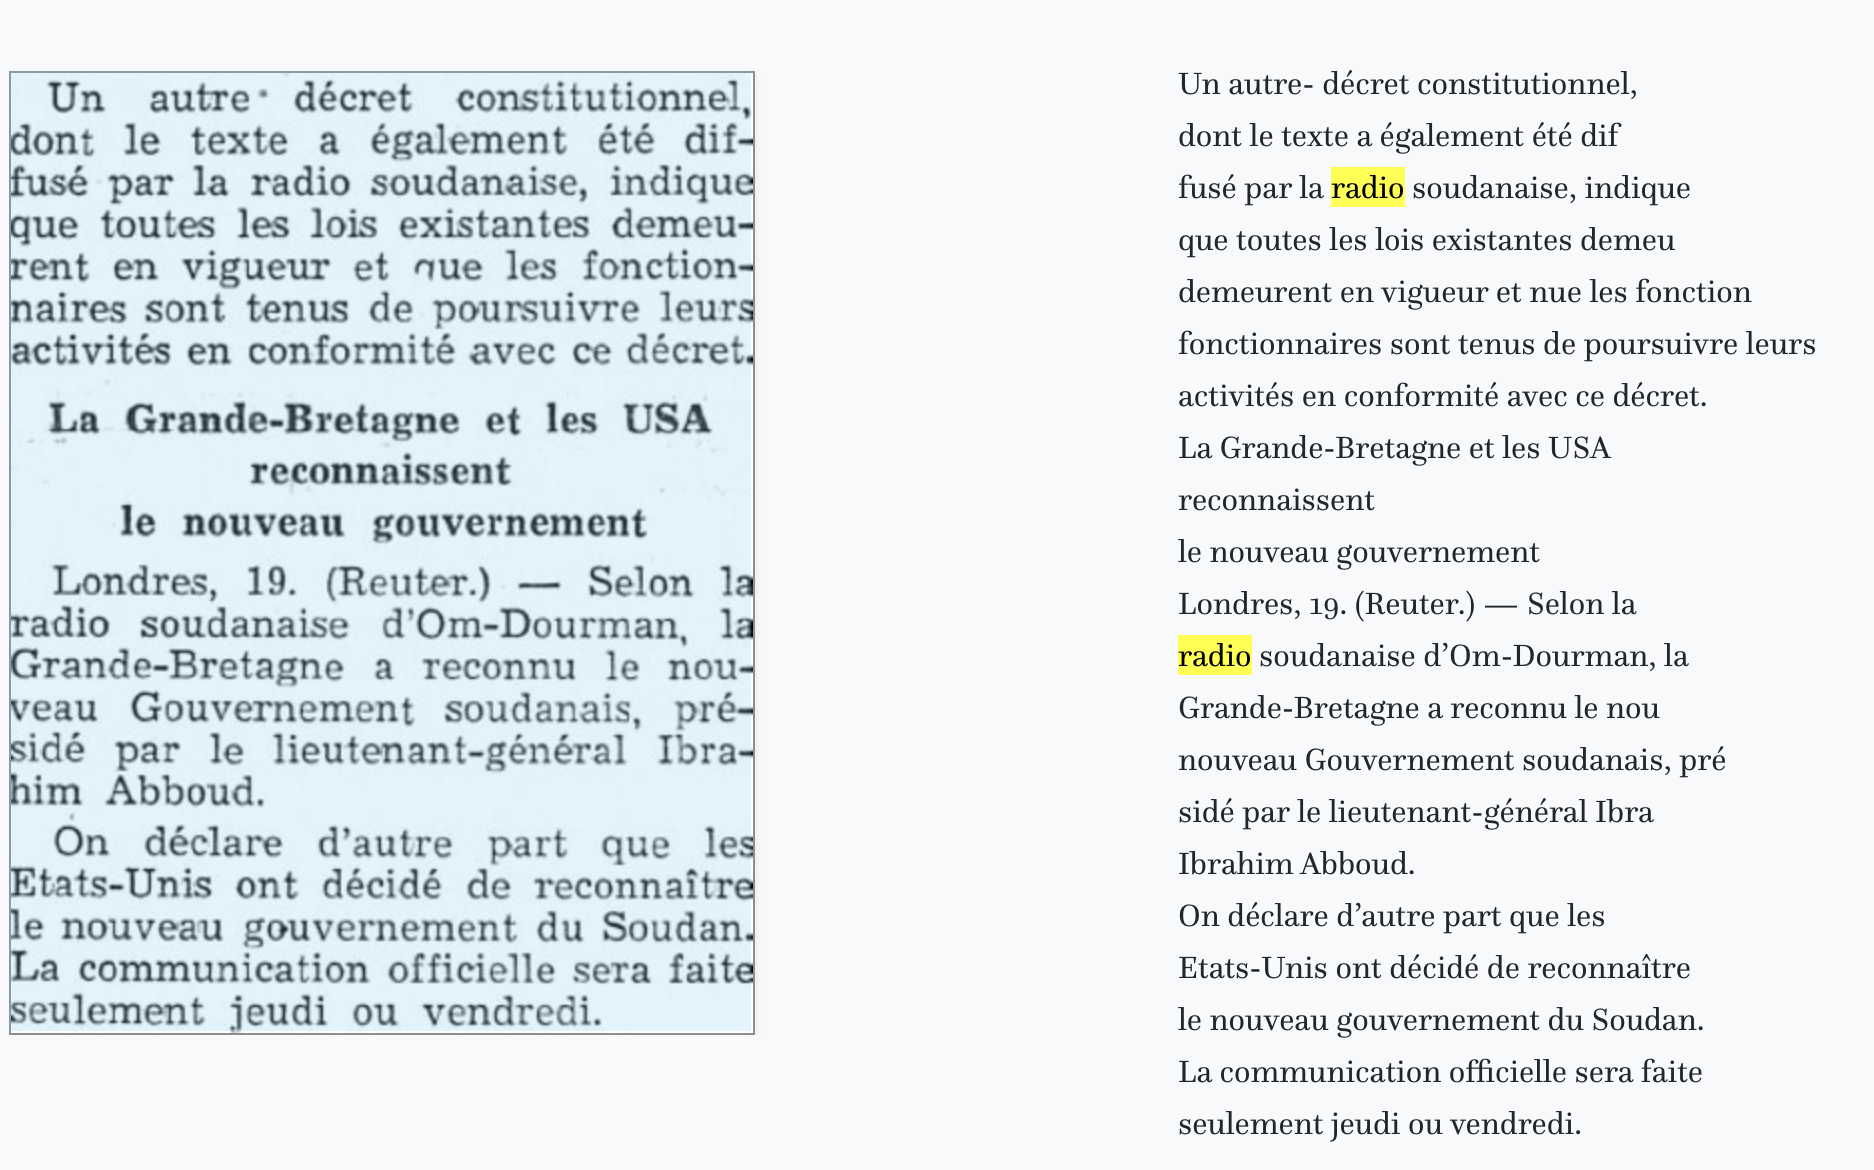
Block-by-block transcription, for close reading
Exploration
Now that we’ve explored our collection, how is radio depicted in print media?
Radio in the press?
Category 1.1 Advertisements
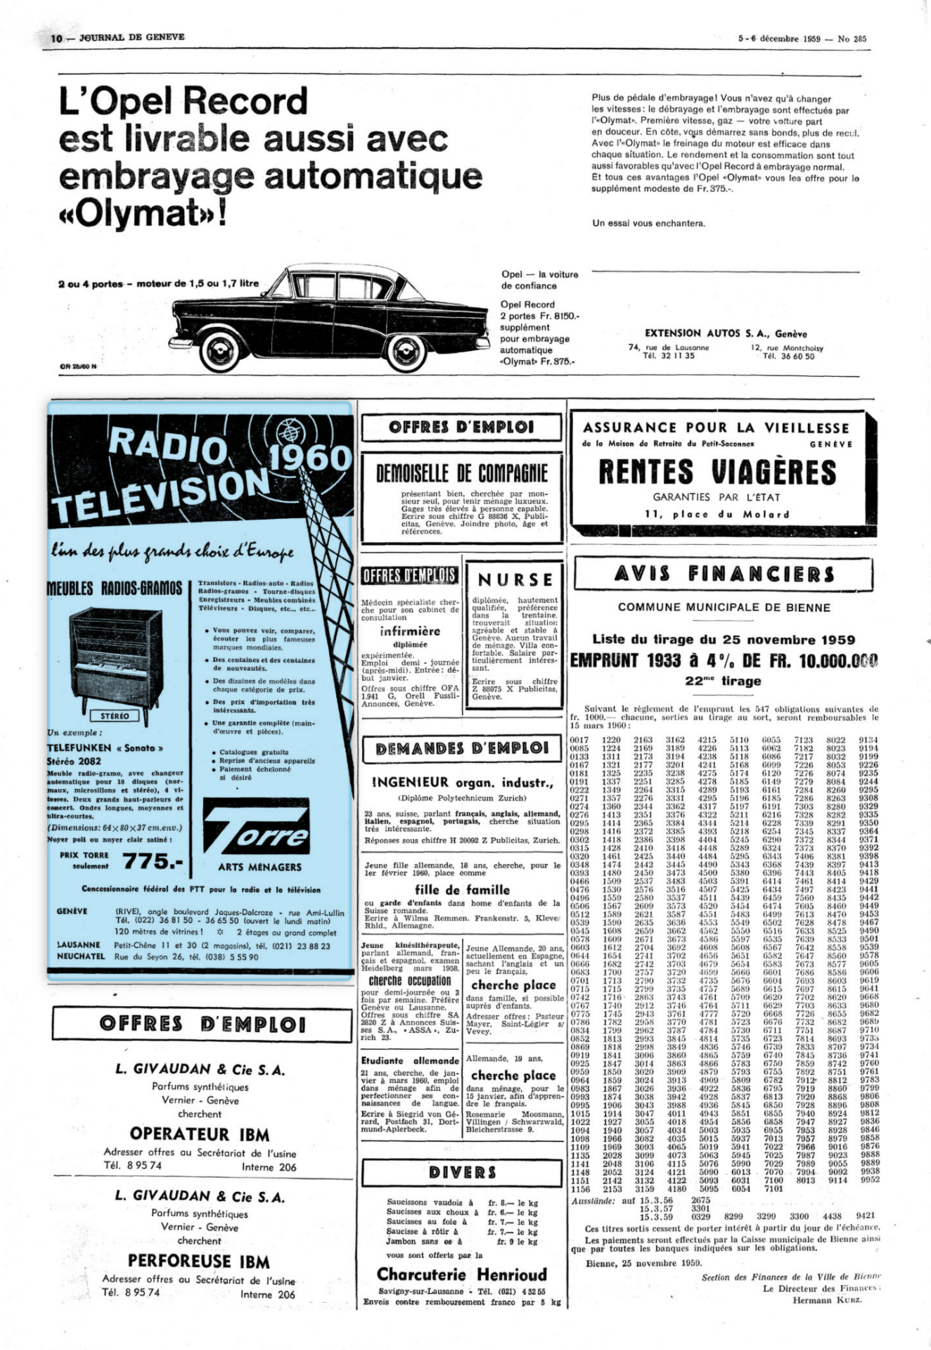
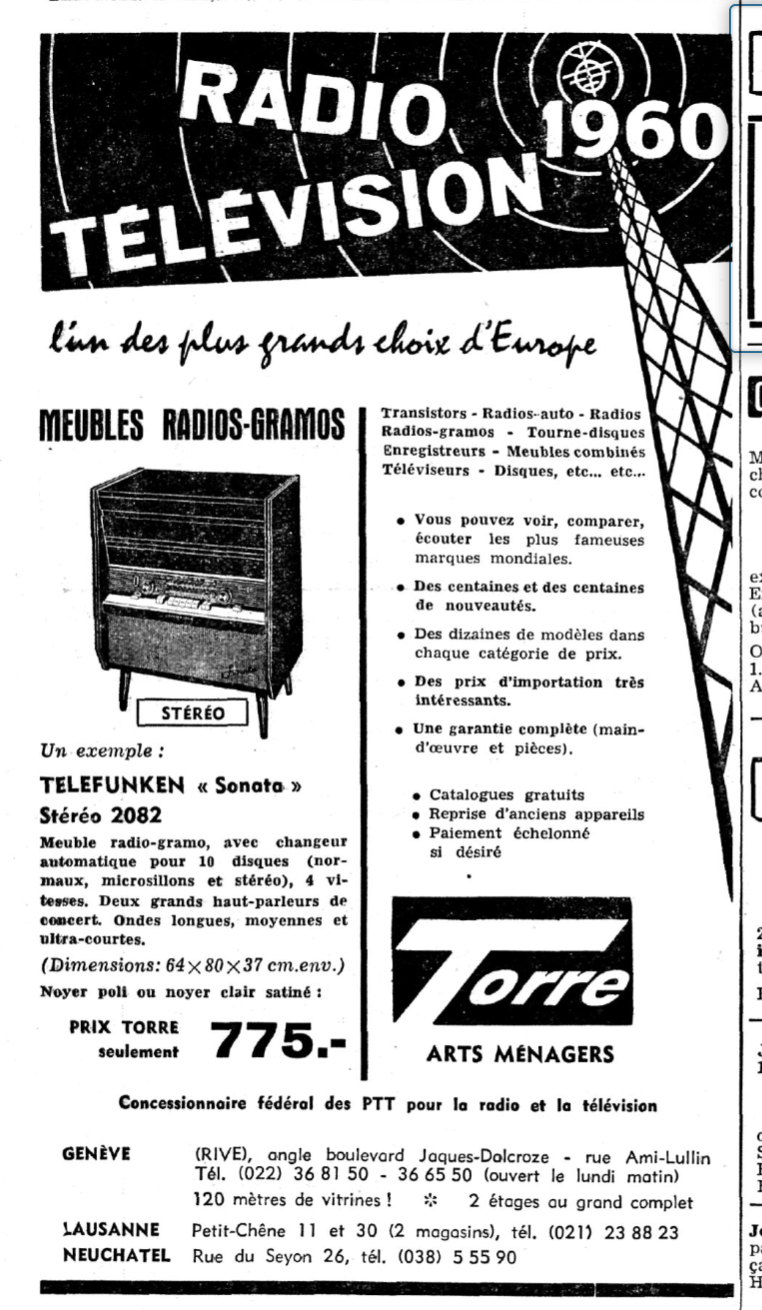
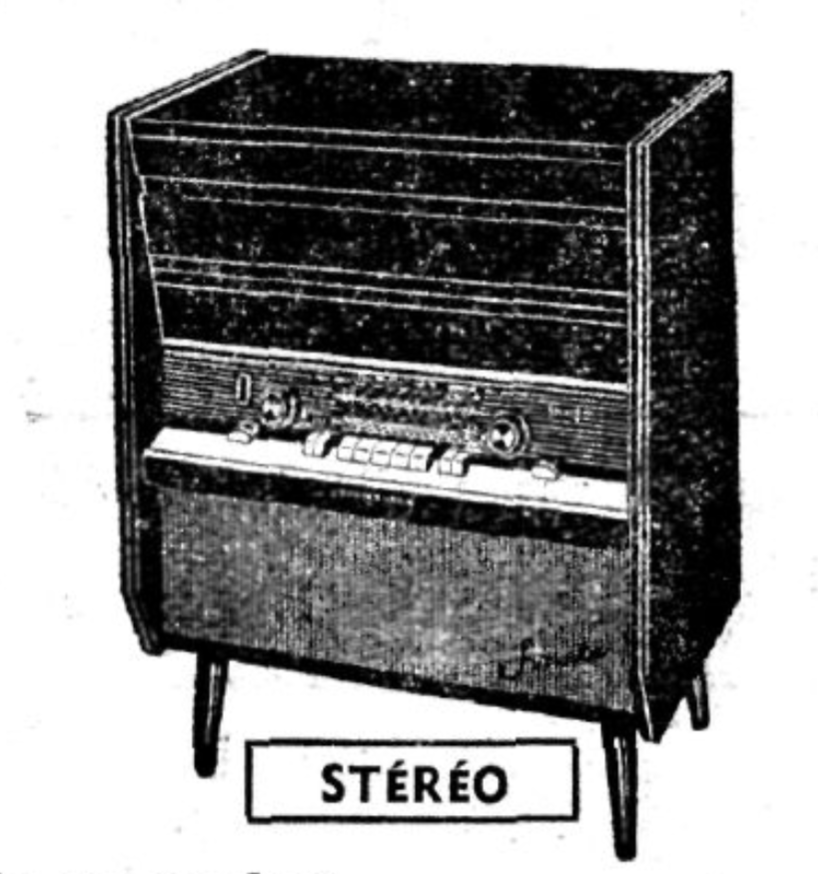
At first glance, this may not be what we’re looking for, but radio is widely present in the press as a commodity.
Radio in the press?
Radio can also serve as a selling point for other products, such as cars.
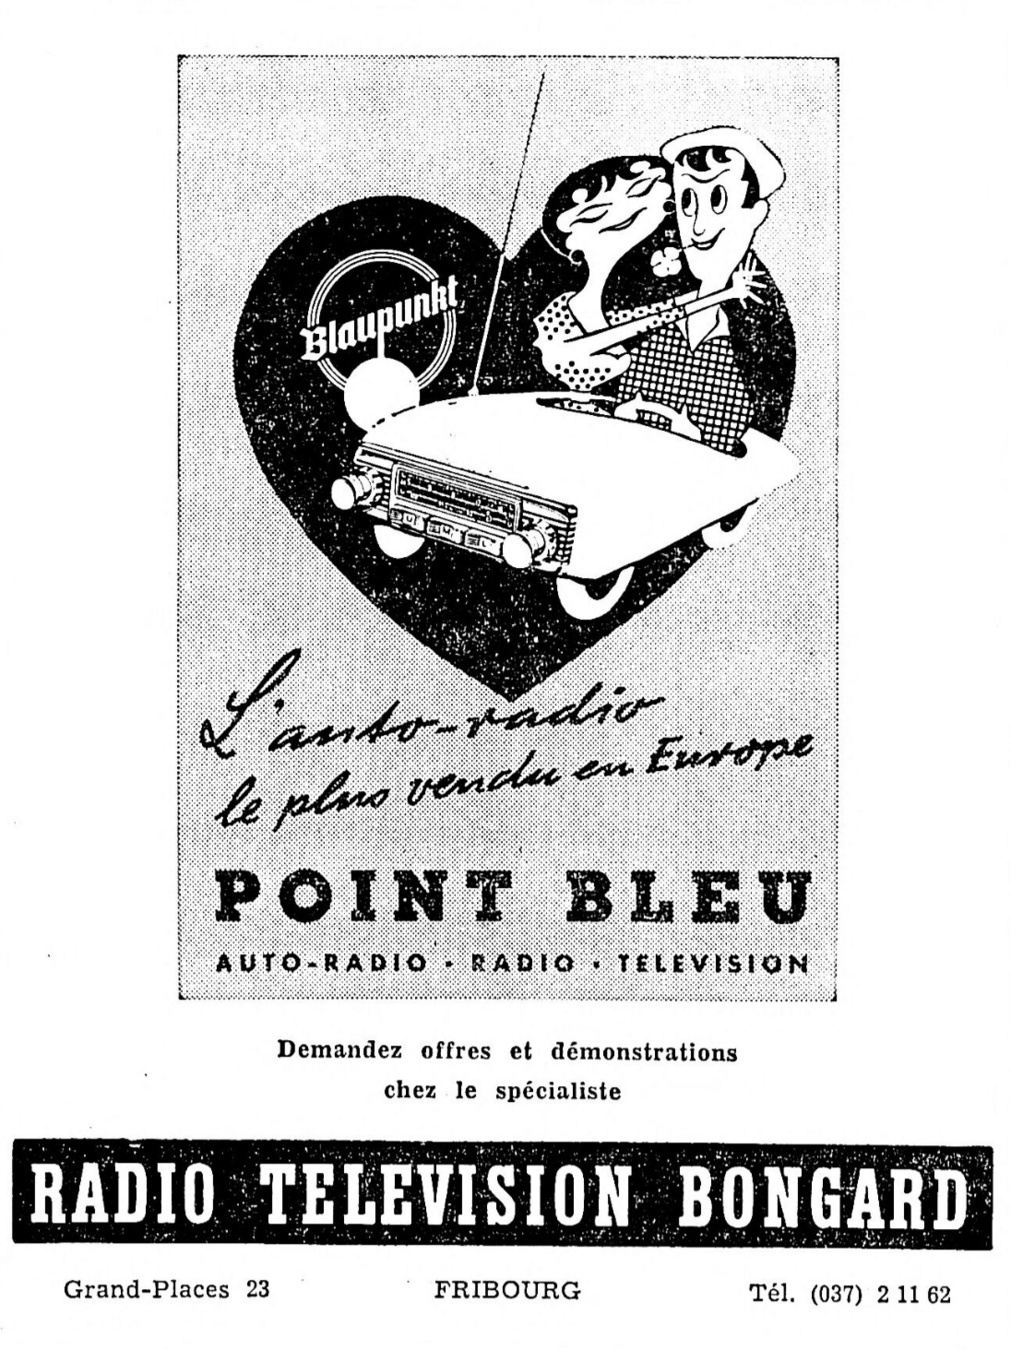
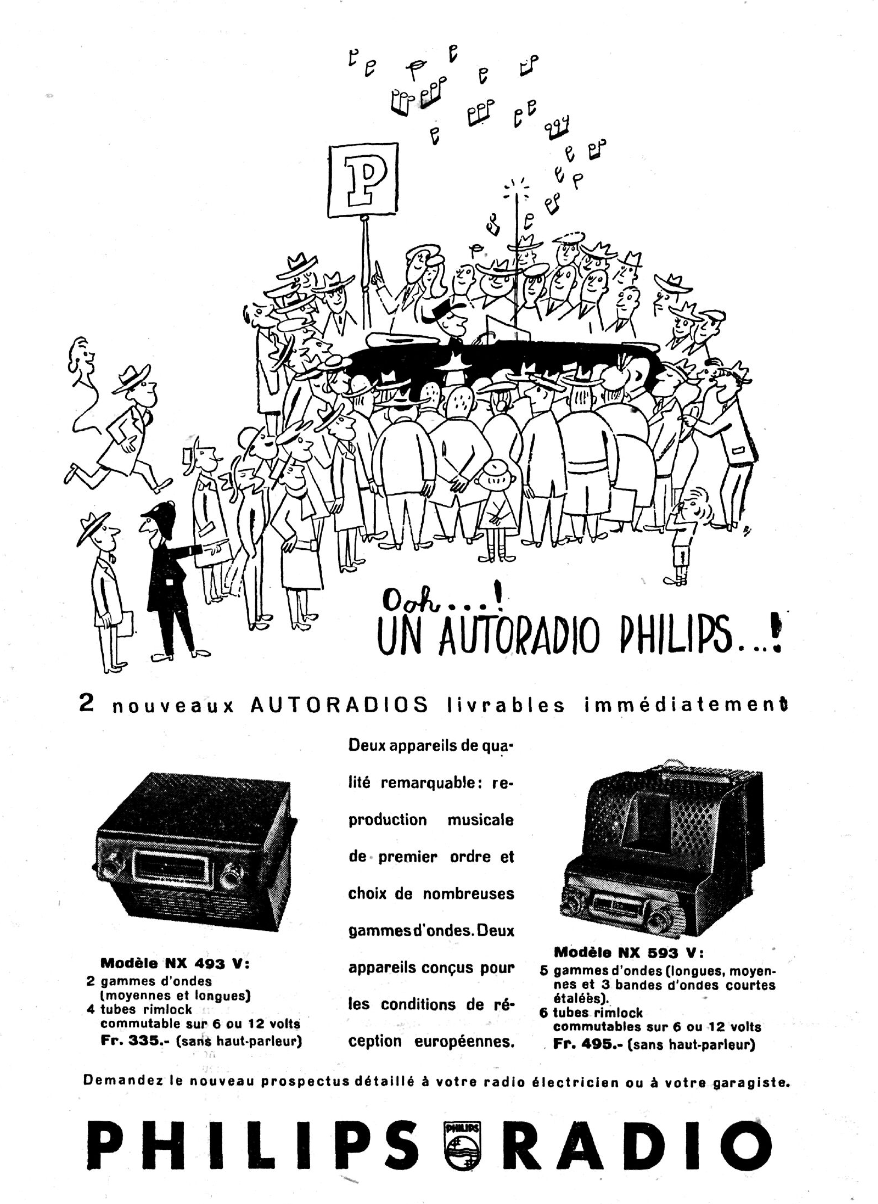
Category 1.1 Advertisements
Radio in the press?
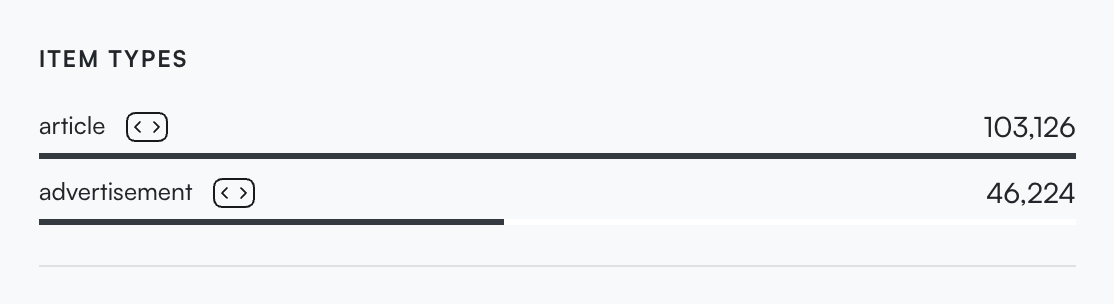
If we compare an opinion newspaper with a mainstream newspaper, the difference in the proportion of advertisements is clear.
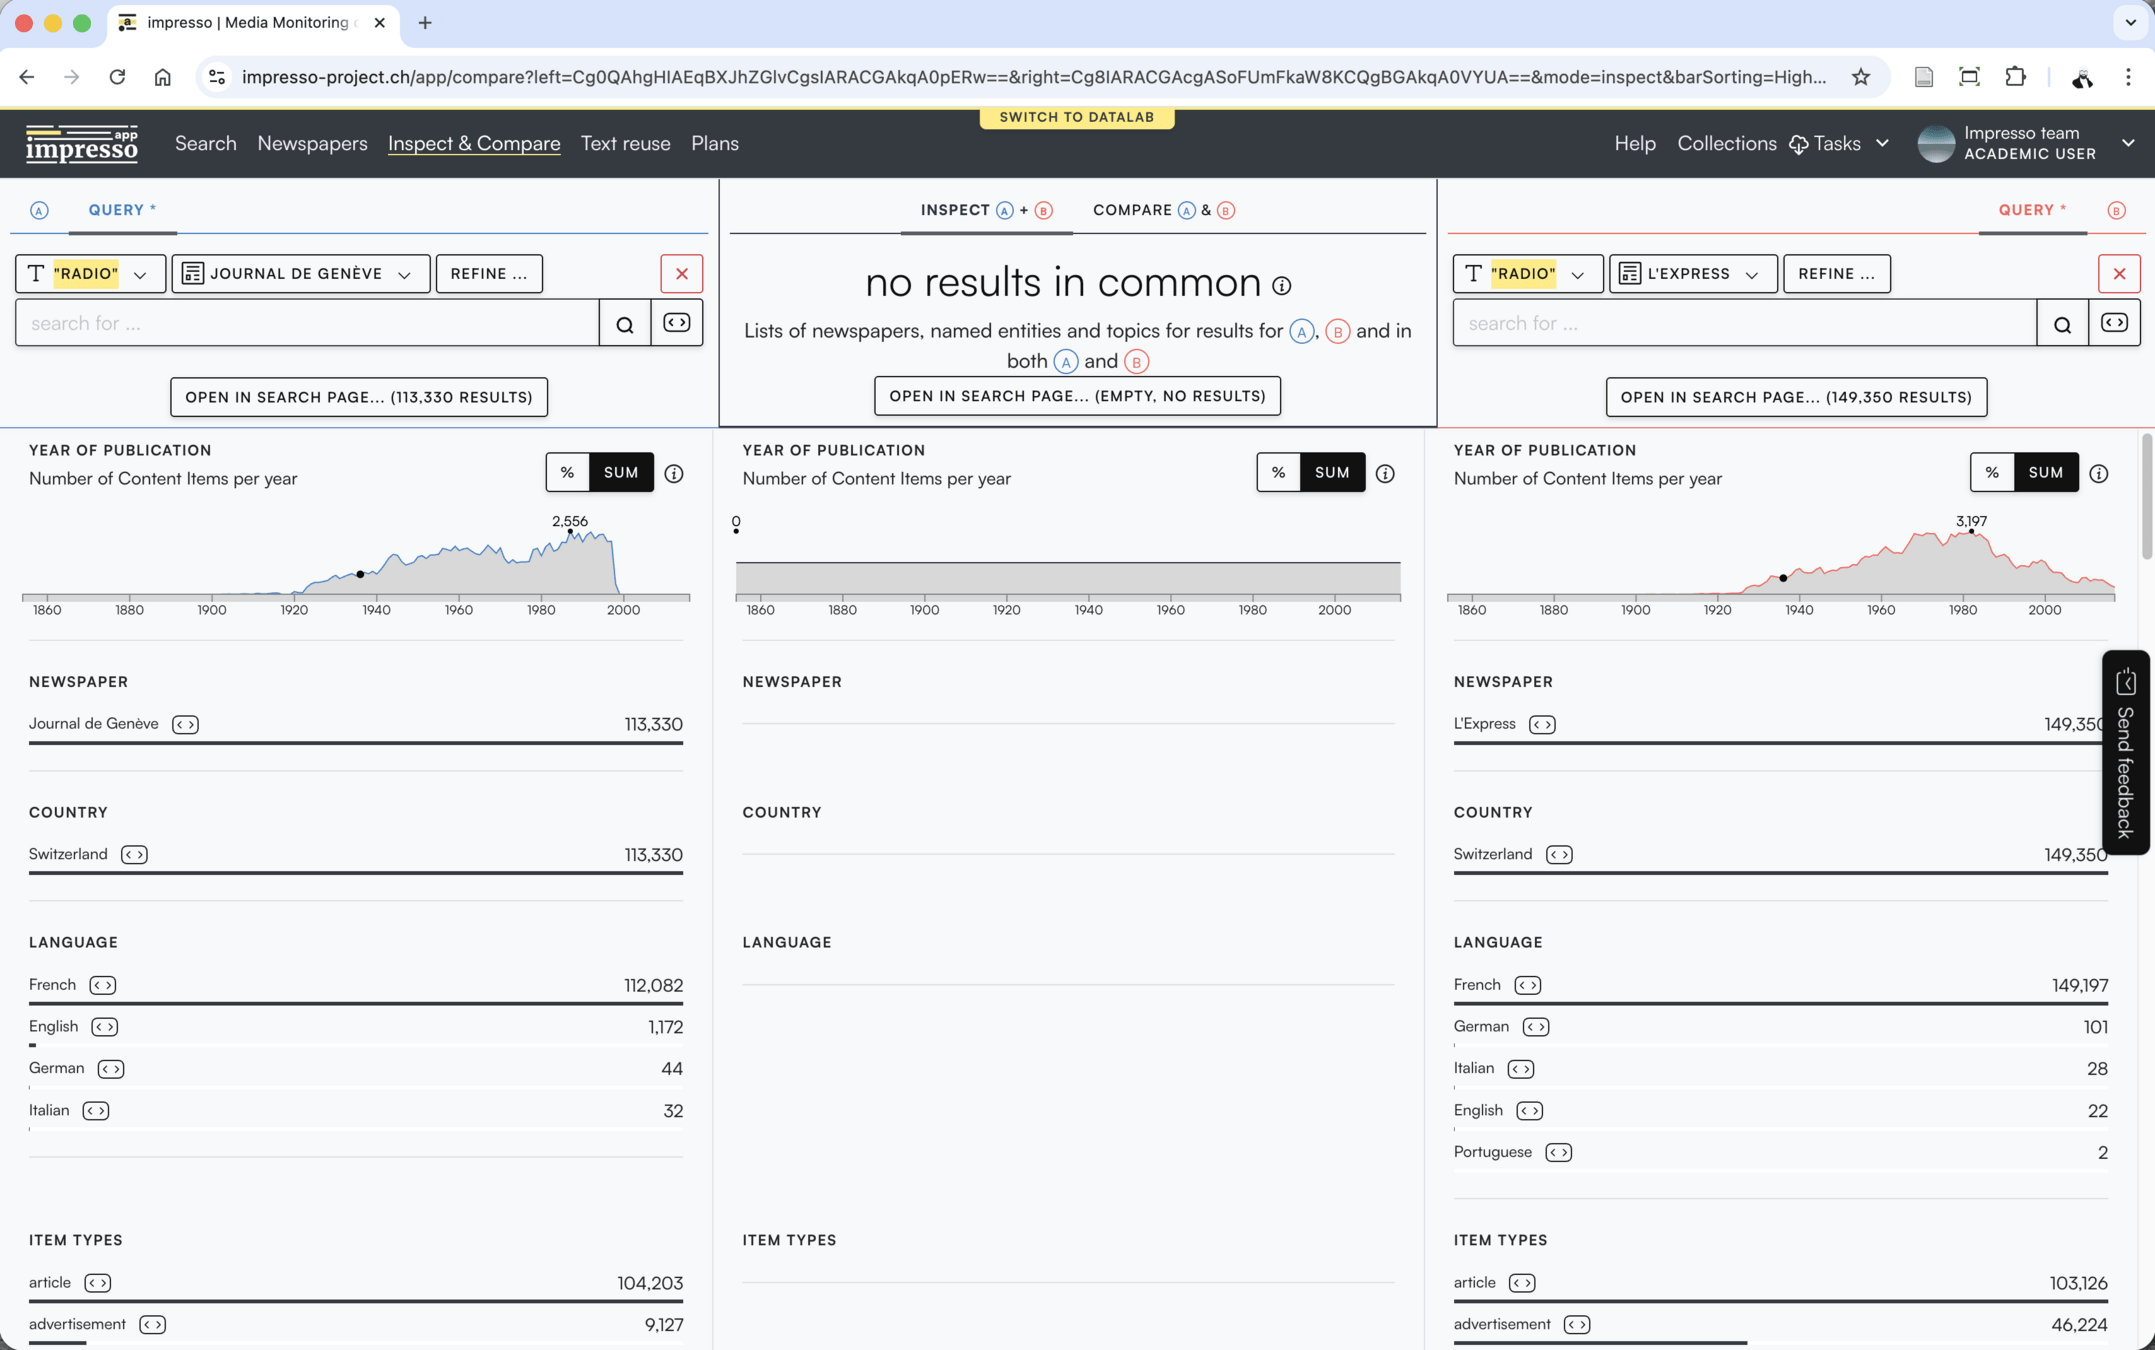
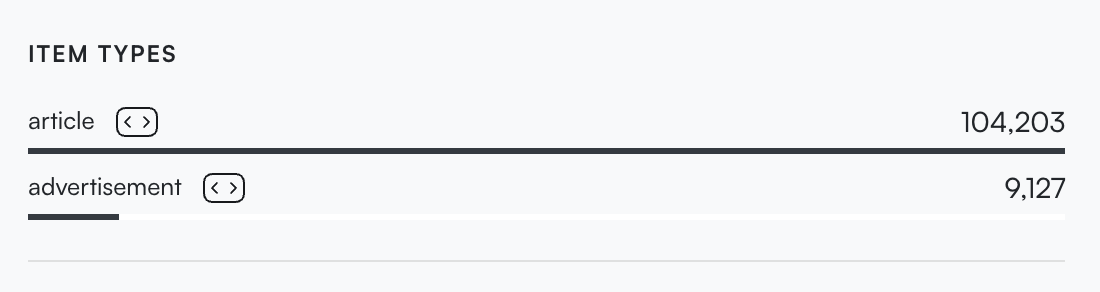
Journal de Genève
8 % of "radio" articles are ads
L'Express (Feuille d'Avis de Neuchâtel)
31 % of "radio" articles are ads
Category 1.1 Advertisements
Radio in the press?
Category 1.2
Job advertisements
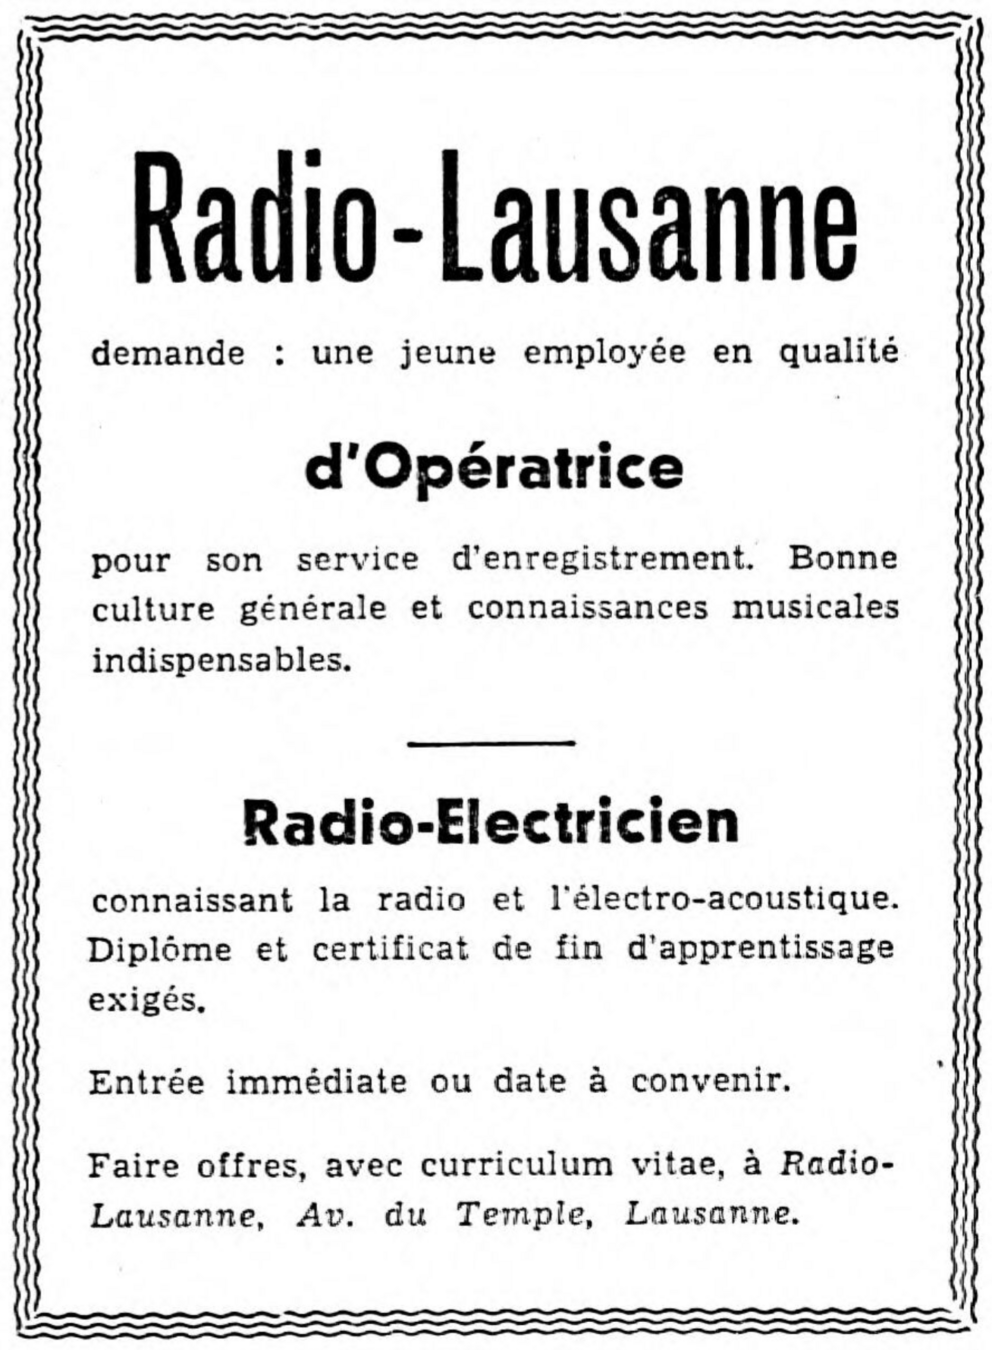
Radio isn't just a device, it's also an employer. Job listings in the press allow for documentation of this professional reality.
Radio in the press?
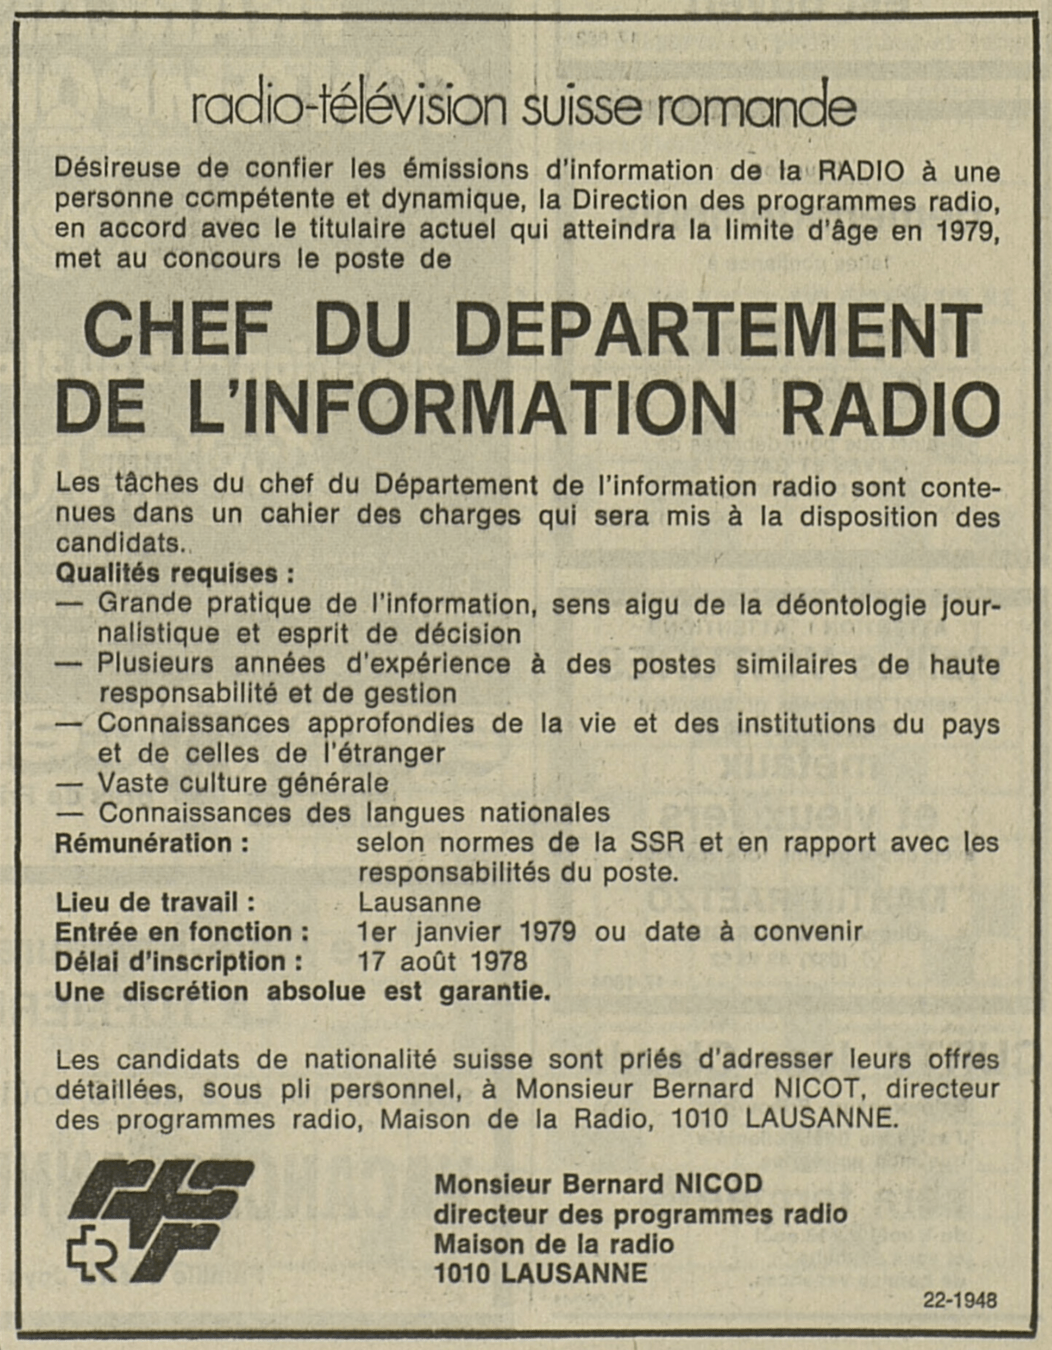
La Liberté 1956
La Liberté 1978
Category 2
Radio program
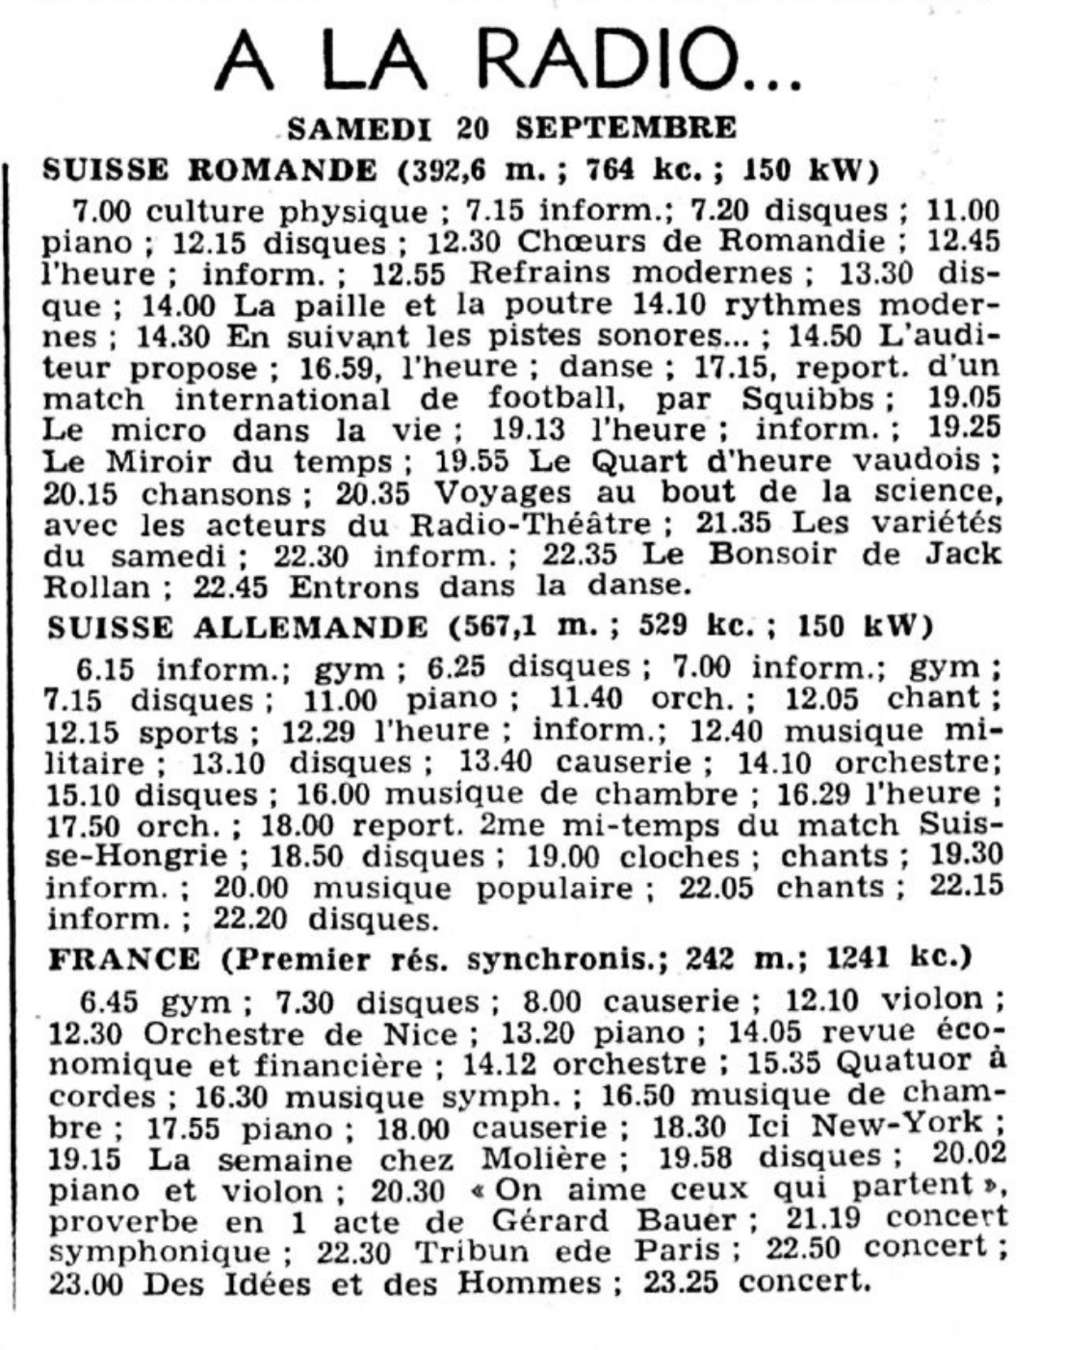
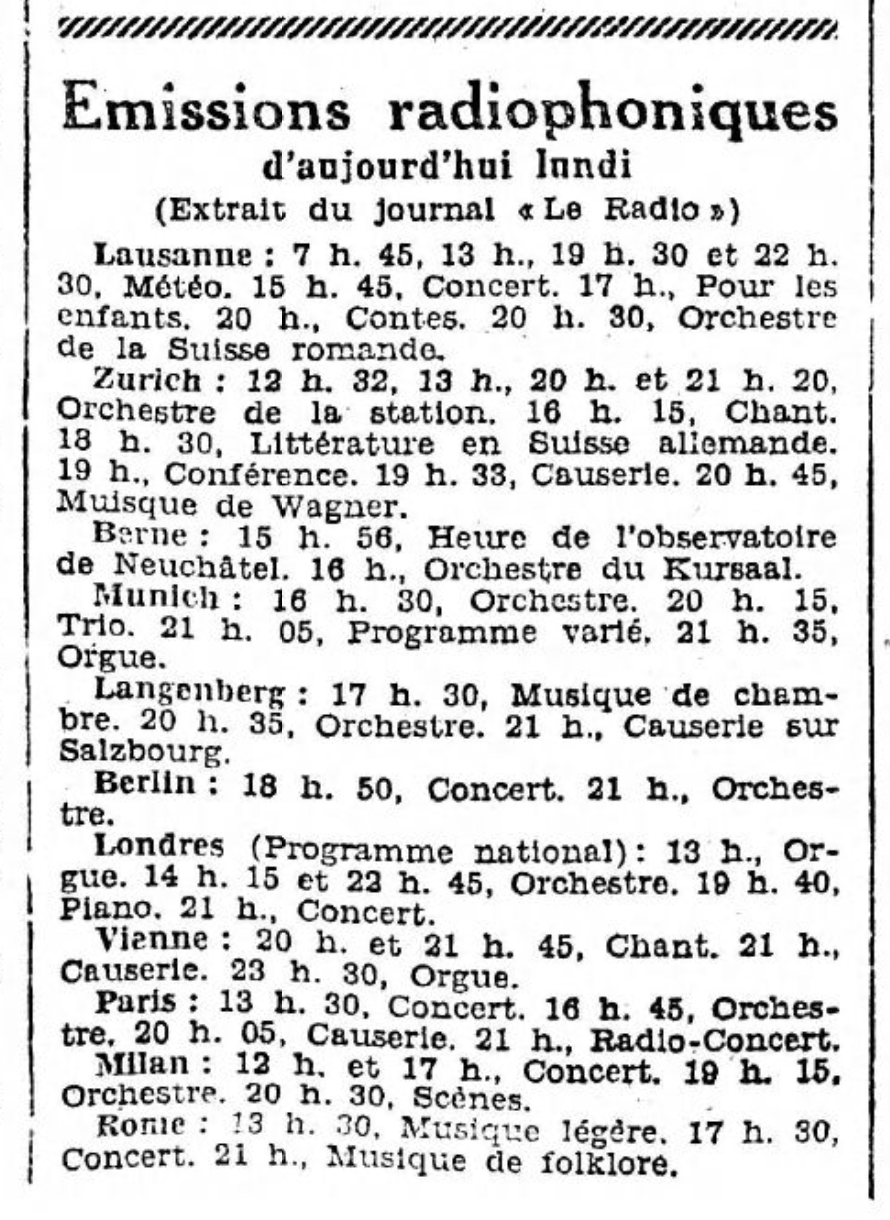
From the very beginning, the radio needed the press to publicize its weekly schedule.
Radio in the press?
Journal de Genève 1952
Feuille d'avis de Neuchâtel 1930
It is worth noting that even the dissemination of this very practical information creates synergies among the media
Category 2
Radio program
Radio in the press?
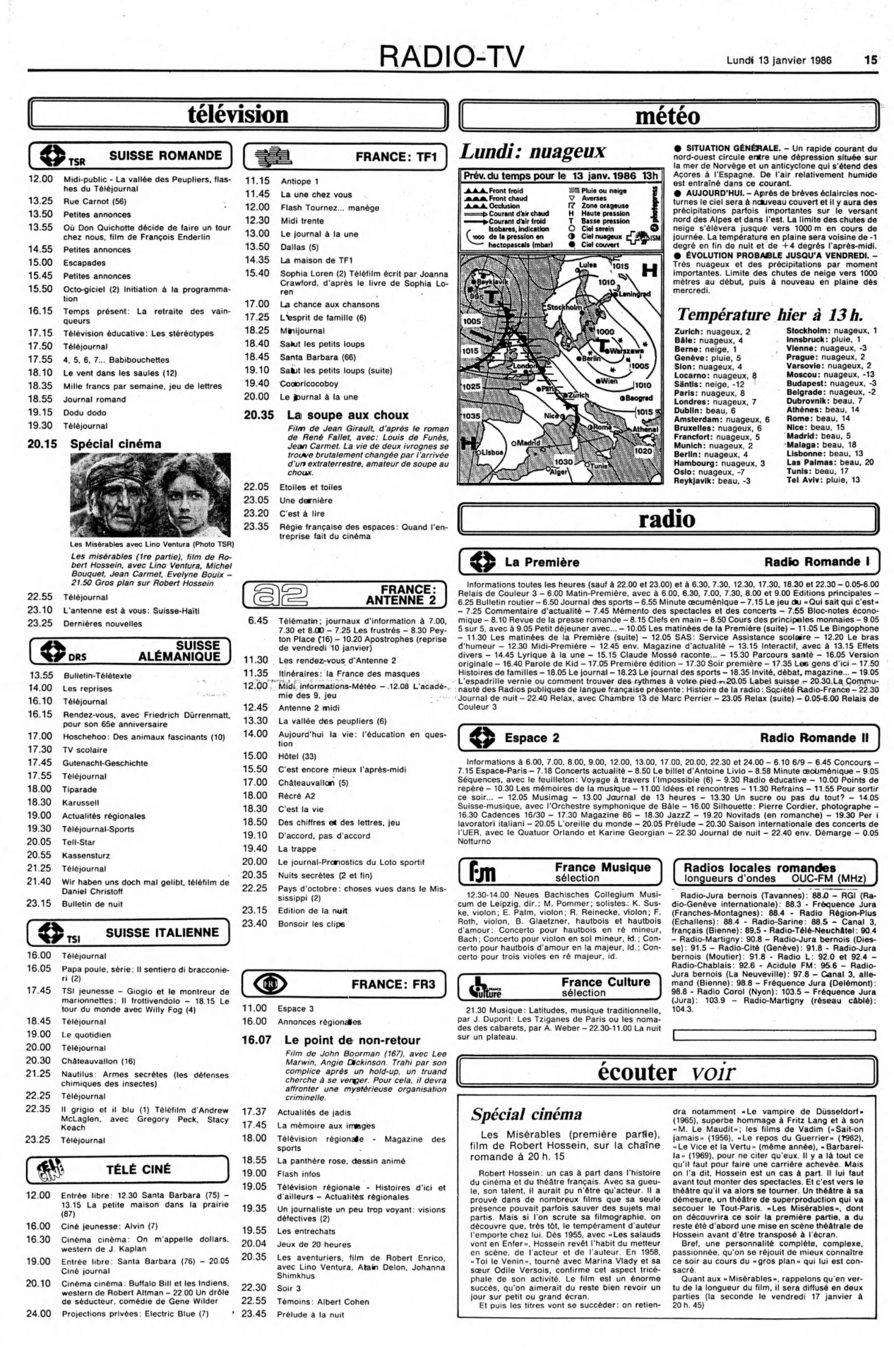
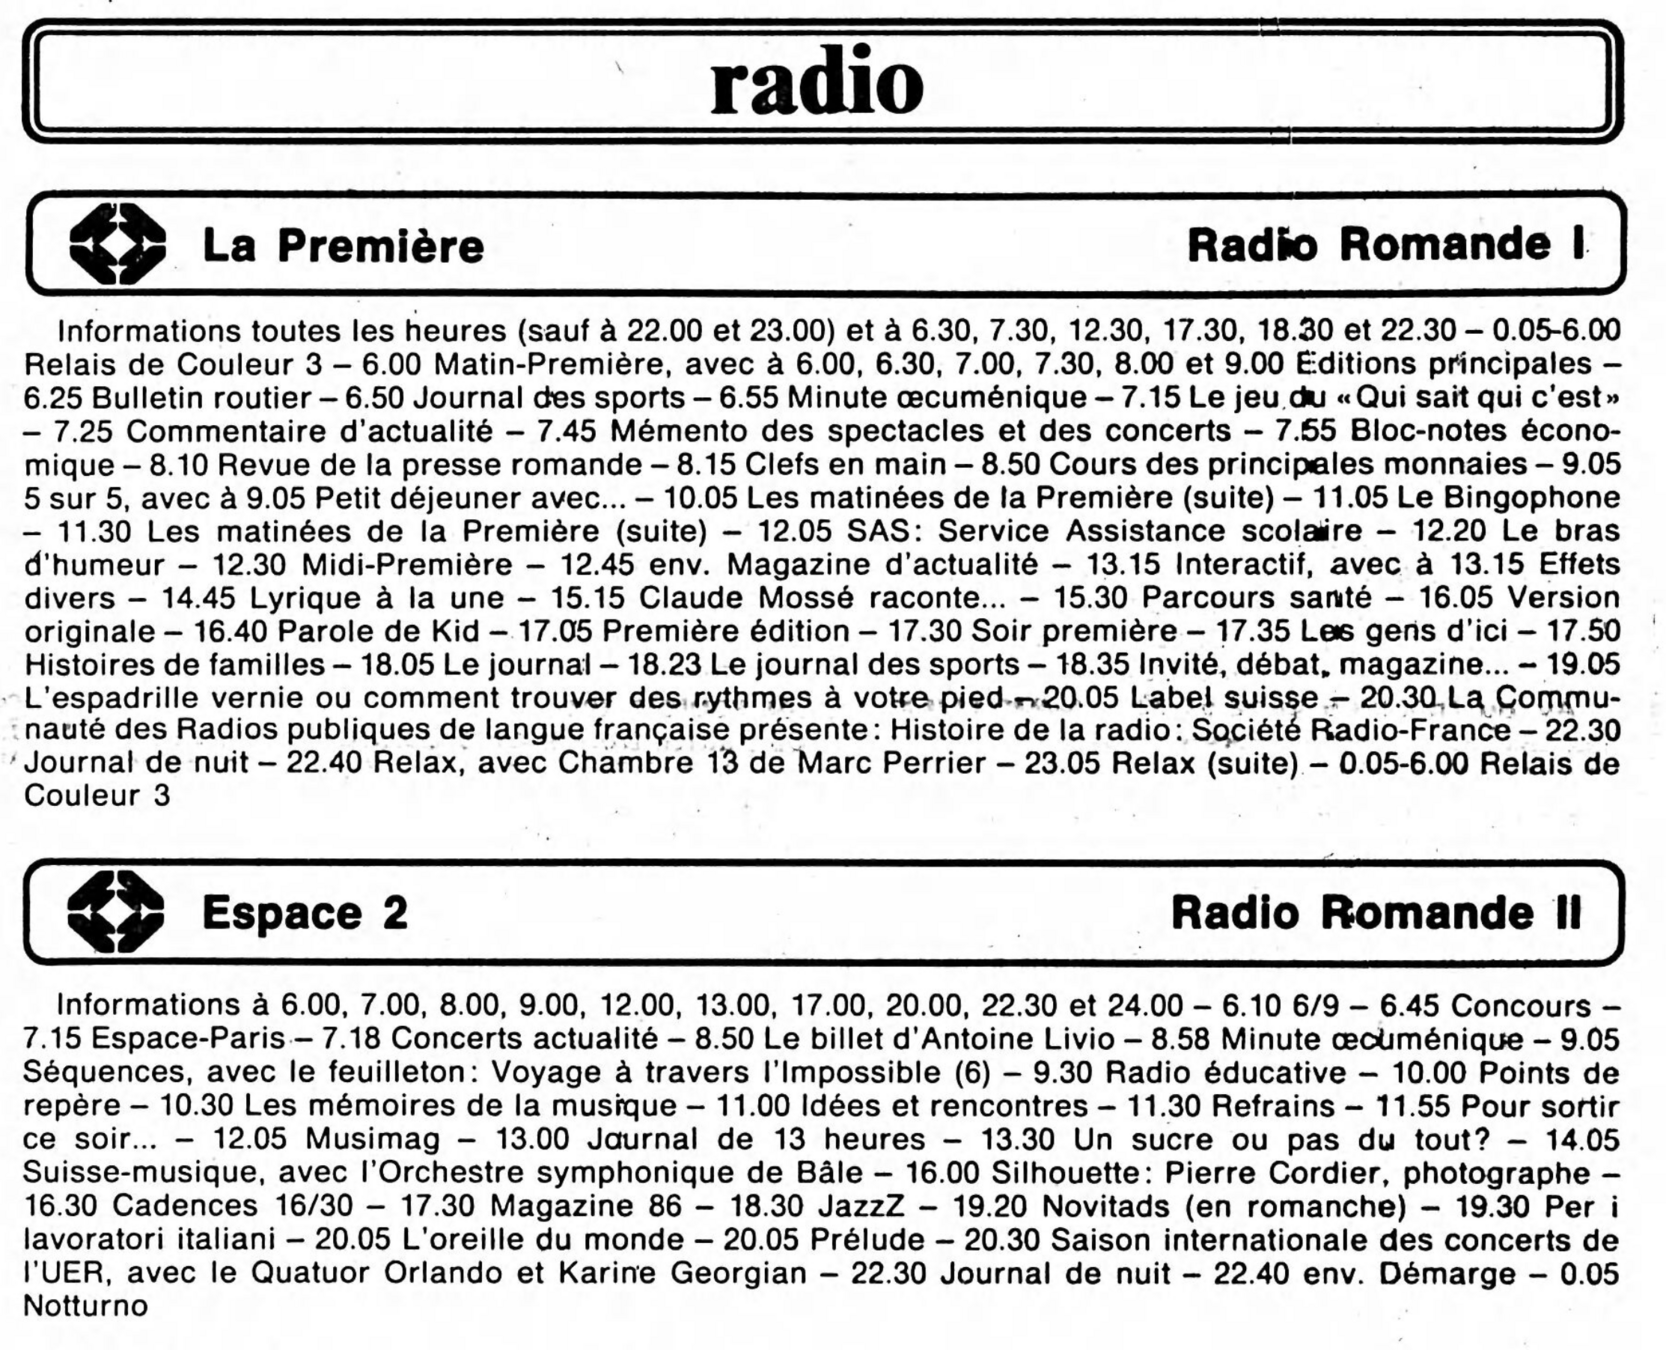
The opposite is also true: newspapers often include the schedules of many stations because they know this is an essential service for many of their readers.
Gazette de Lausanne 1986
Category 3
Radio as a source of information
Radio in the press?
More interesting than advertisements or radio programs, radio can also be cited as a source of information in news articles.
Feuille d'avis de Neuchâtel 1940
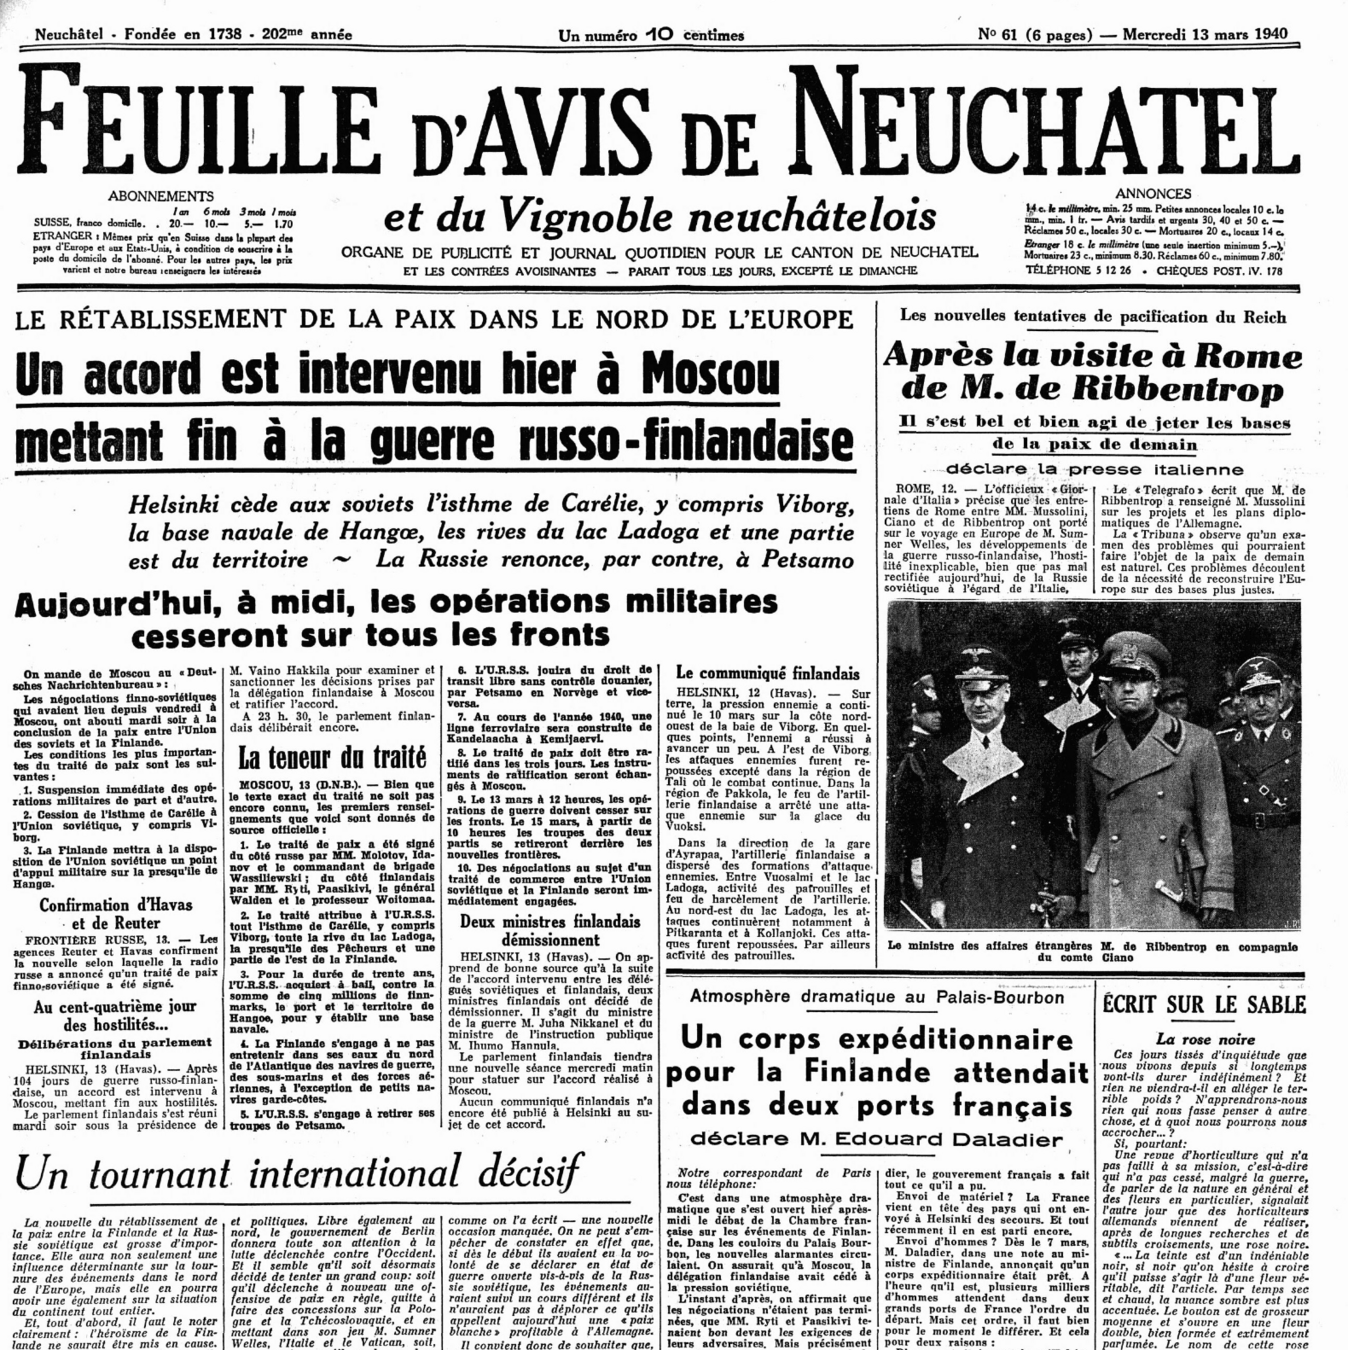
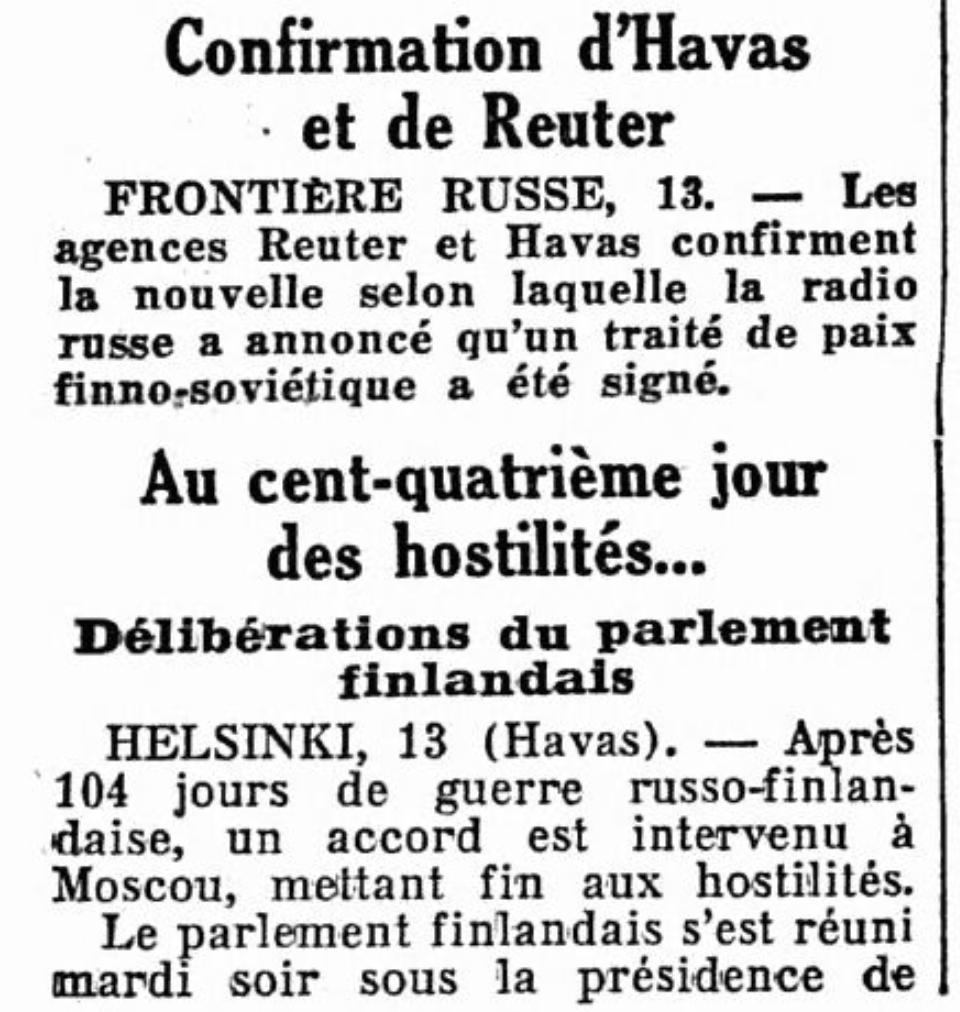
A search of the Impresso corpus shows that this was fairly rare in Swiss newspapers during the early decades (1920–1950), but it became more common thereafter.
Category 3
Radio as a source of information
Radio in the press?
An interesting observation: it is very often radio stations from communist countries that are mentioned in Swiss newspapers
Feuille d'avis de Neuchâtel 1950
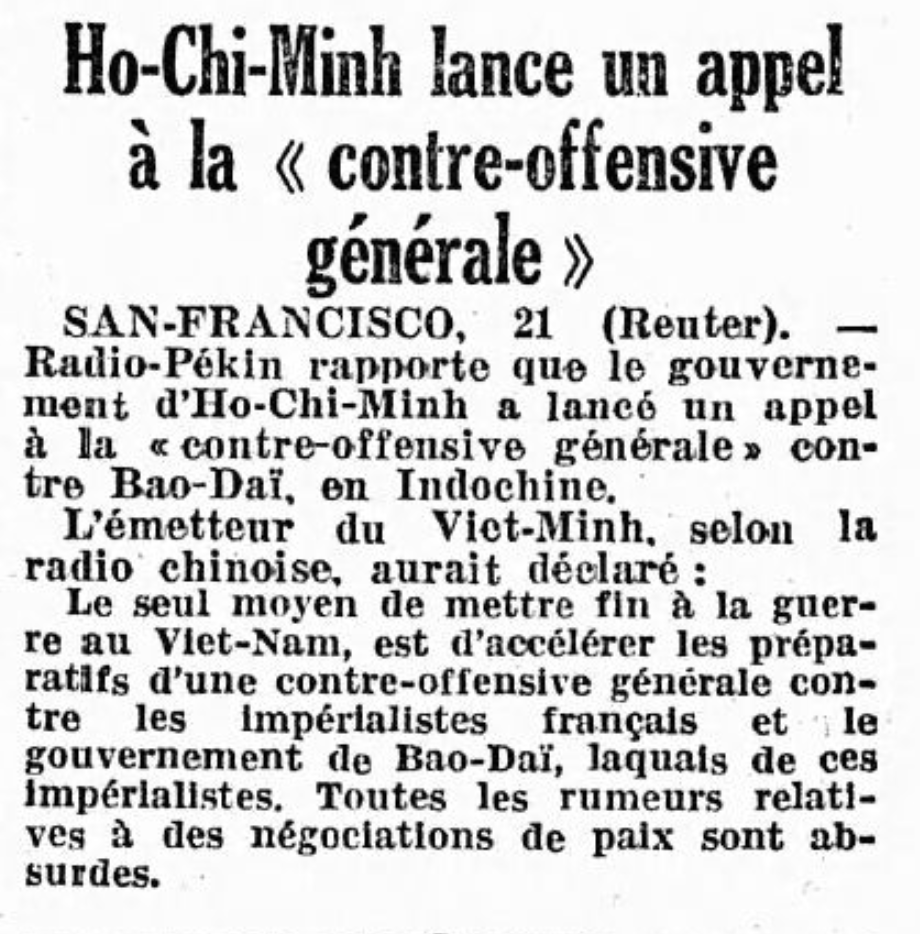
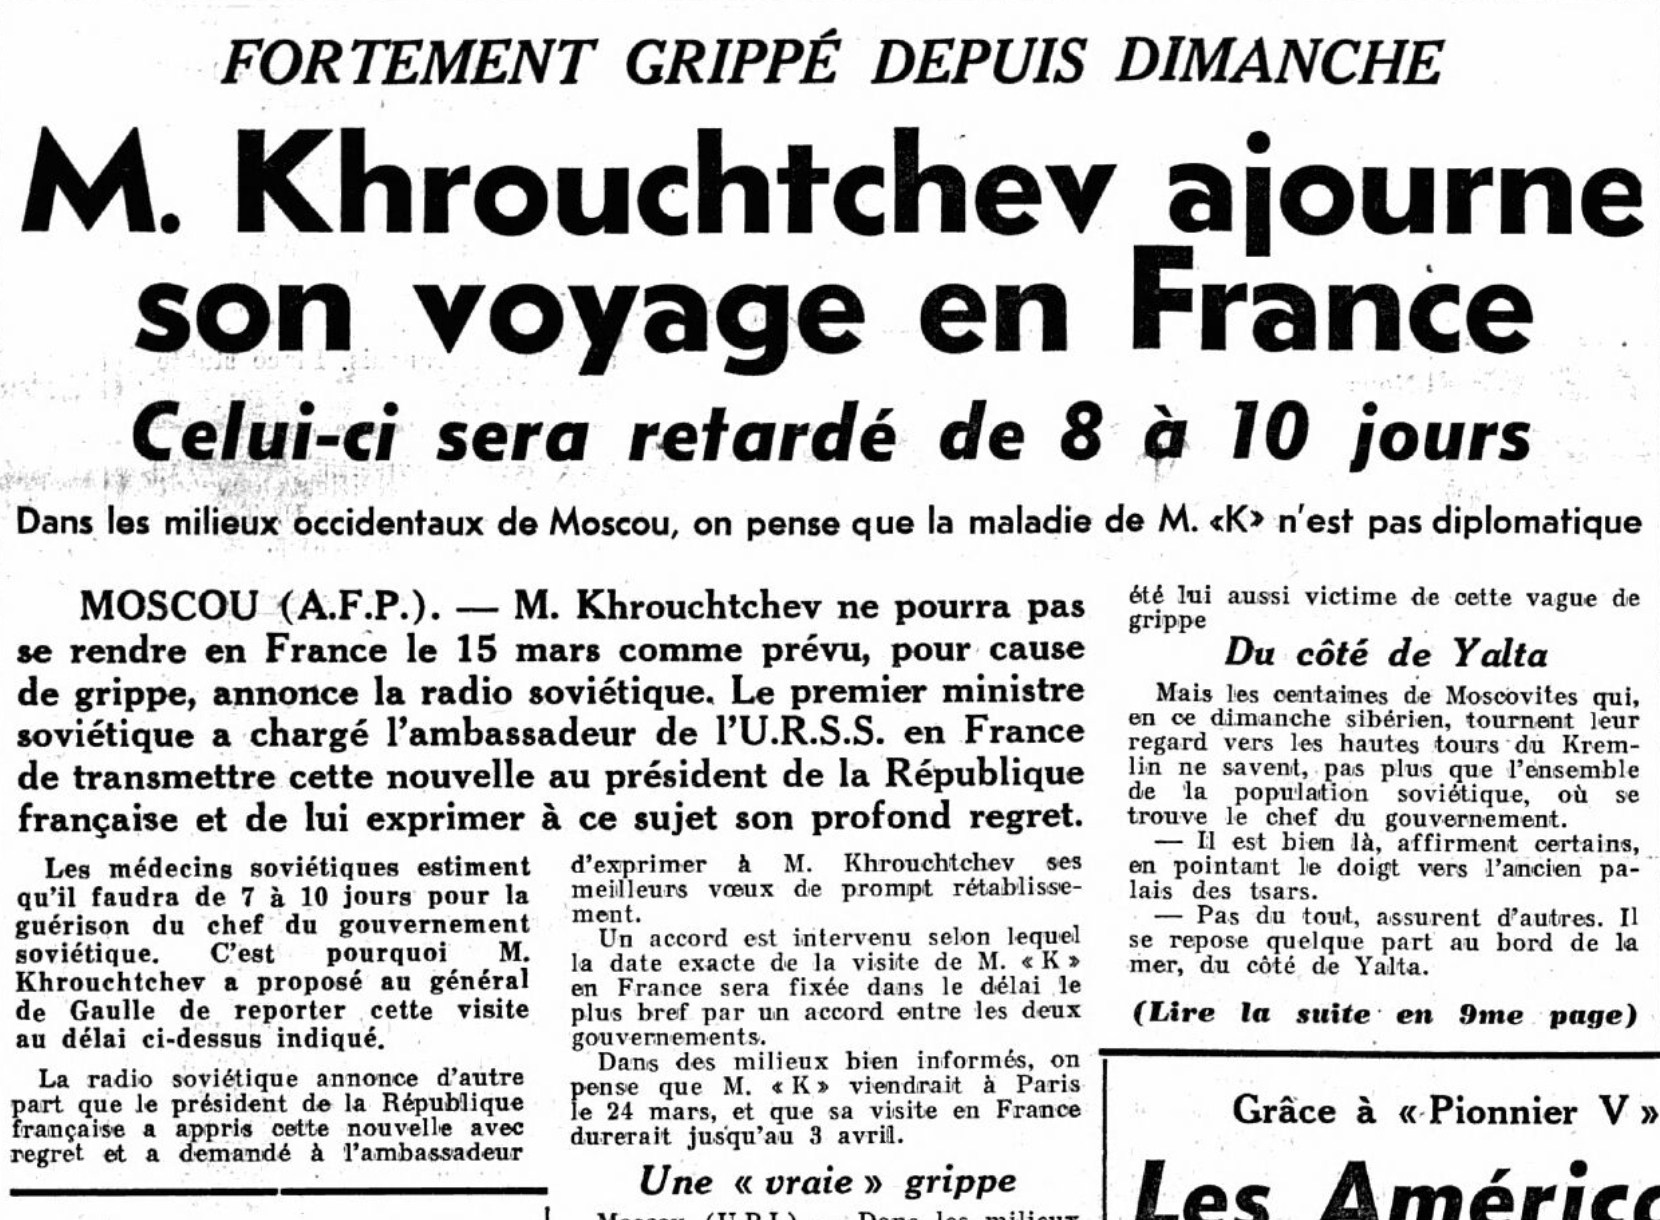
Feuille d'avis de Neuchâtel 1960
The Swiss media do not have correspondents in these countries and therefore rely on reports from government radio stations
Category 3
Radio as a source of information
Radio in the press?
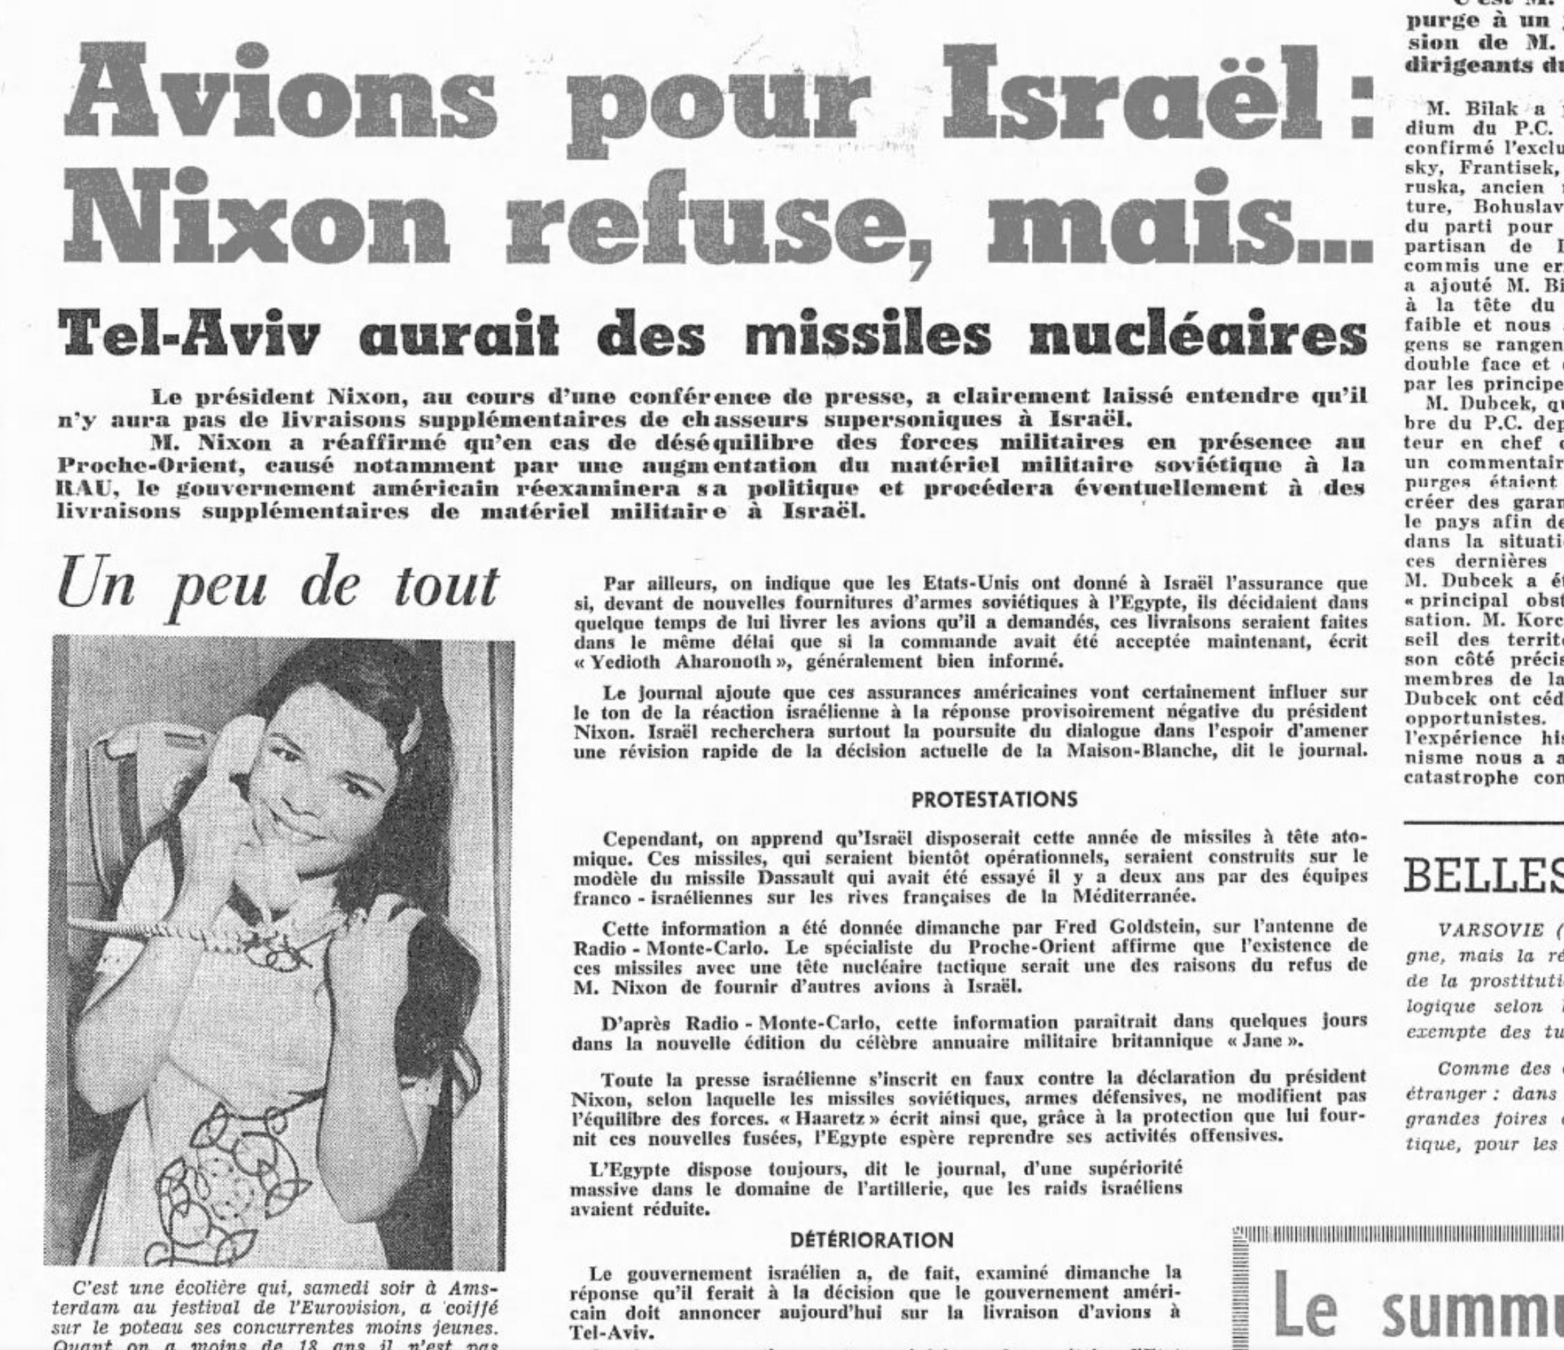
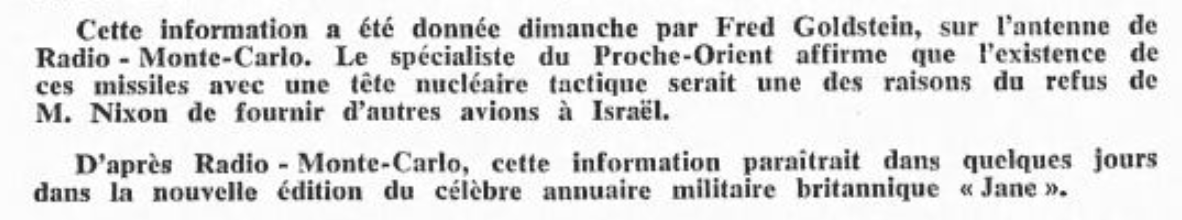
As the second half of the 20th century progresses, radio is cited more and more often as a source of information. It is increasingly becoming an integral part of the media landscape.
Feuille d'avis de Neuchâtel 1973
Category 4
Radio as a subject in the news
Radio in the press?
The “richest” occurrences in this corpus involve references to radio as the subject of a news article.
Feuille d'avis de Neuchâtel 1940
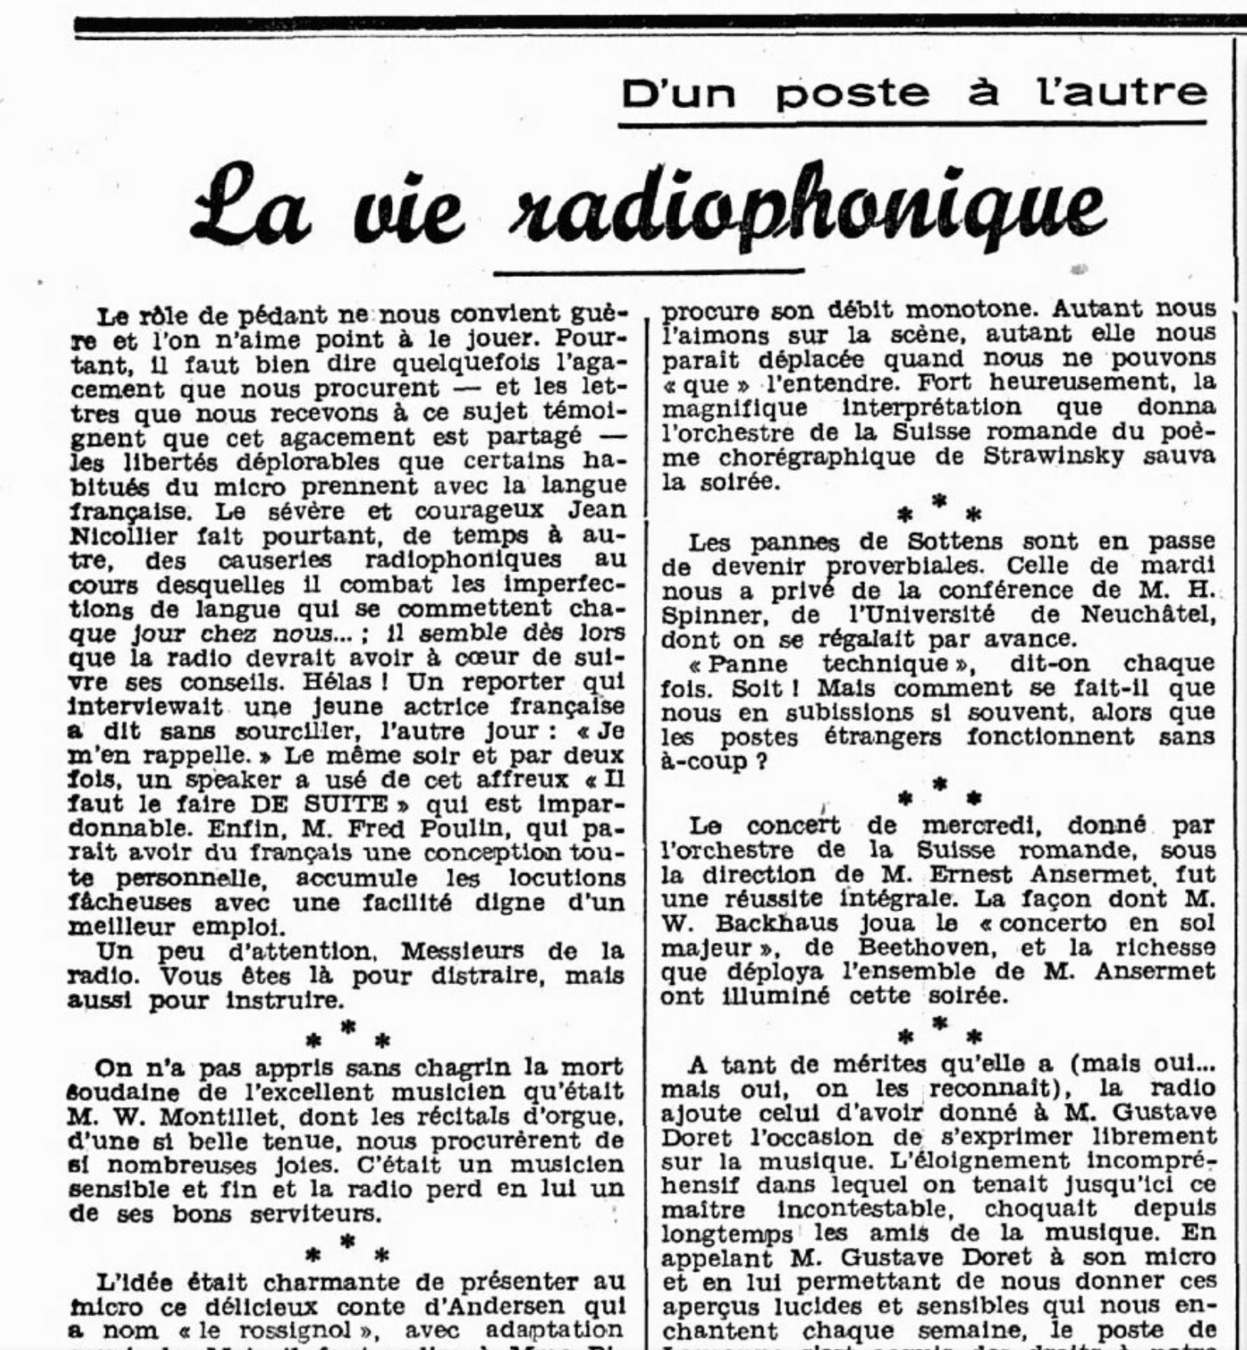
Here, the press is complaining about the poor language used by radio hosts!
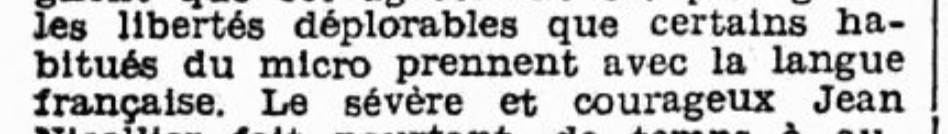
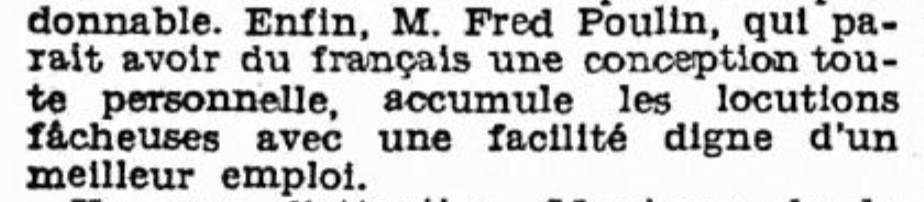
As soon as radio became widely accessible, it became a topic of discussion in its own right for the press. For example, newspapers began to review the programs themselves.
Category 4
Radio as a subject in the news
Radio in the press?
Feuille d'avis de Neuchâtel 1960
"Miroir du monde" is the flagship international news program on the Swiss French-speaking radio, coming soon in the Impresso app!
The press is becoming a platform for reacting to what is said on the radio, a forum for discussing the new profession of radio journalism.
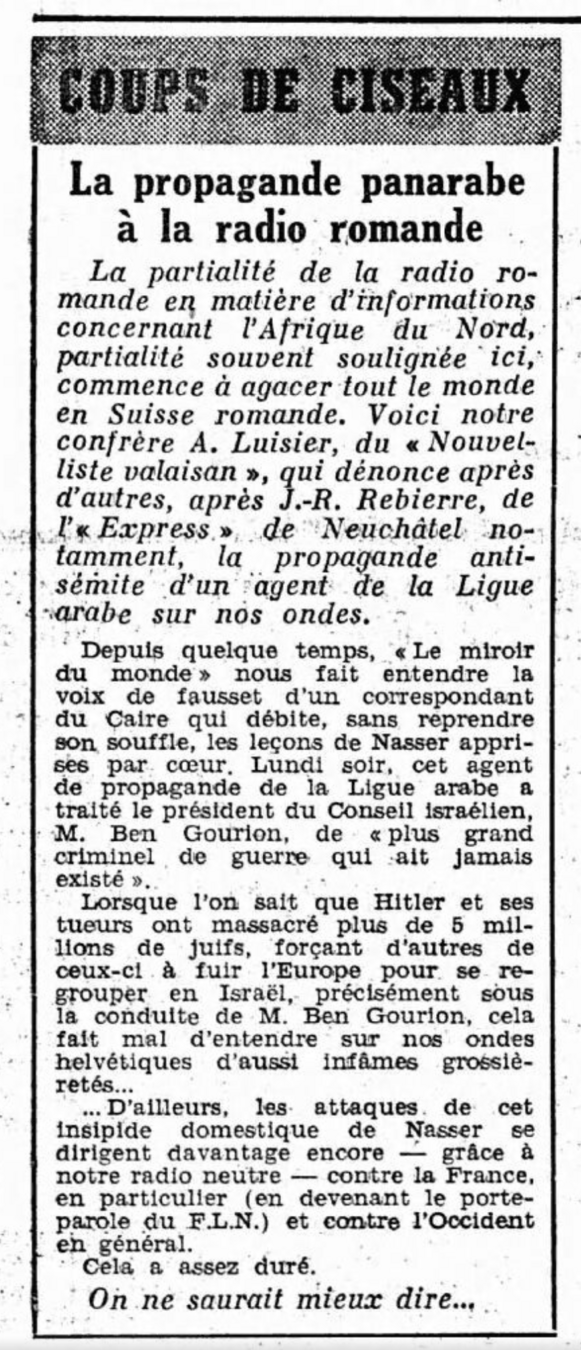
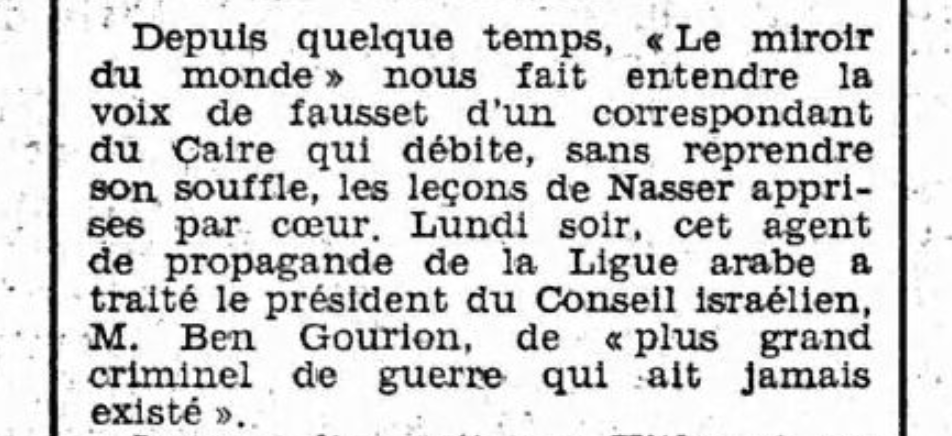
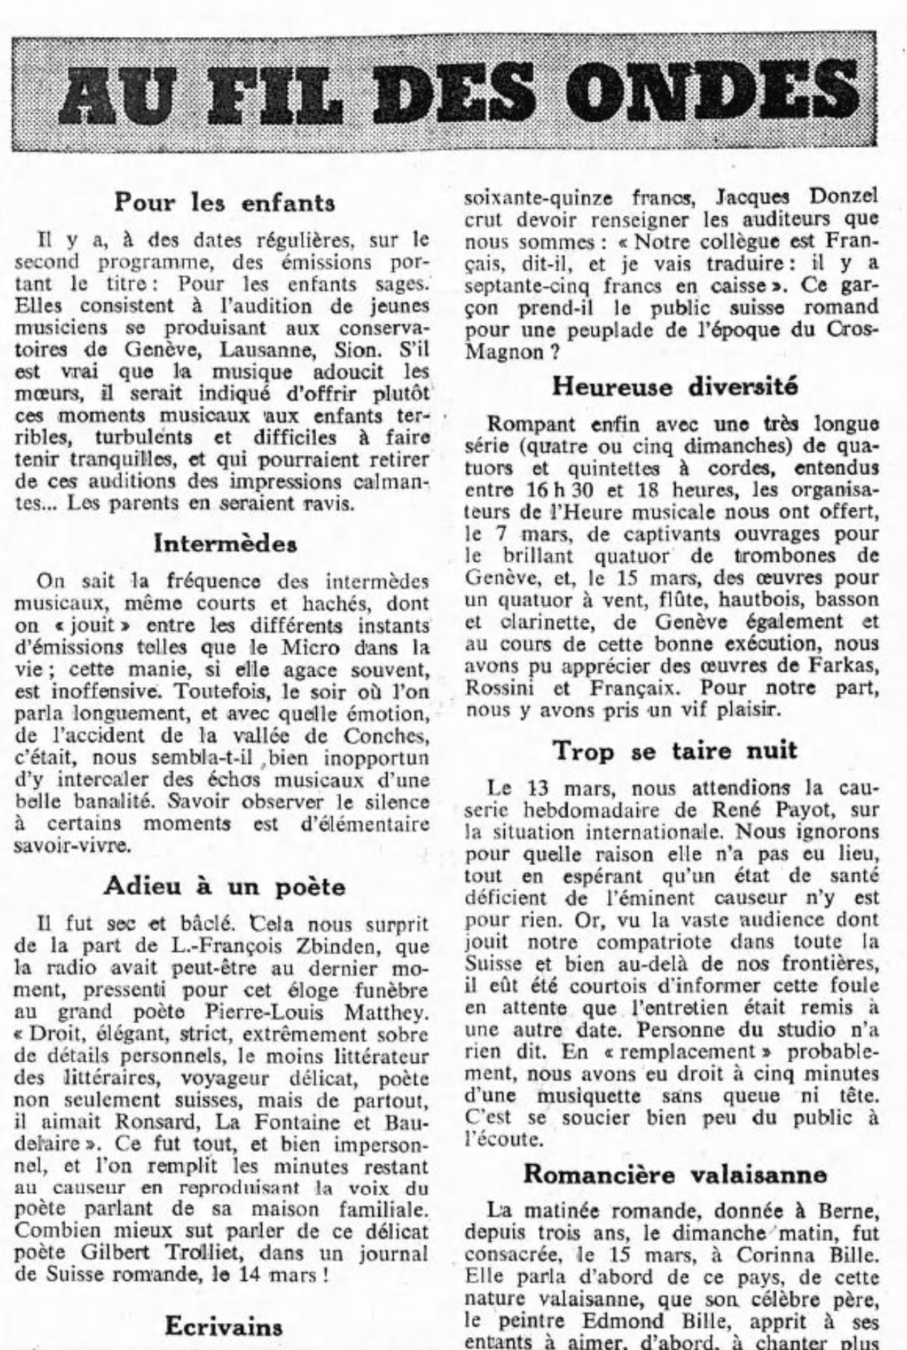
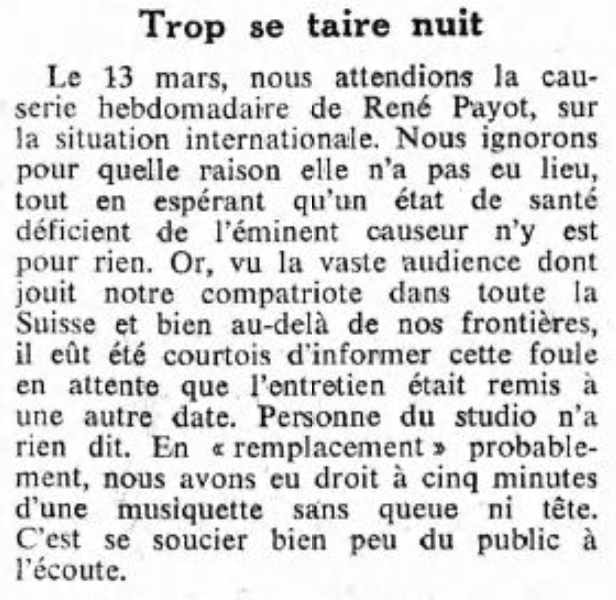
Feuille d'avis de Neuchâtel 1970
The "radio critique" section
Category 4
Radio as a subject in the news
Radio in the press?
Feuille d'avis de Neuchâtel 1940
The press is a valuable source for exploring the institutional history of radio.
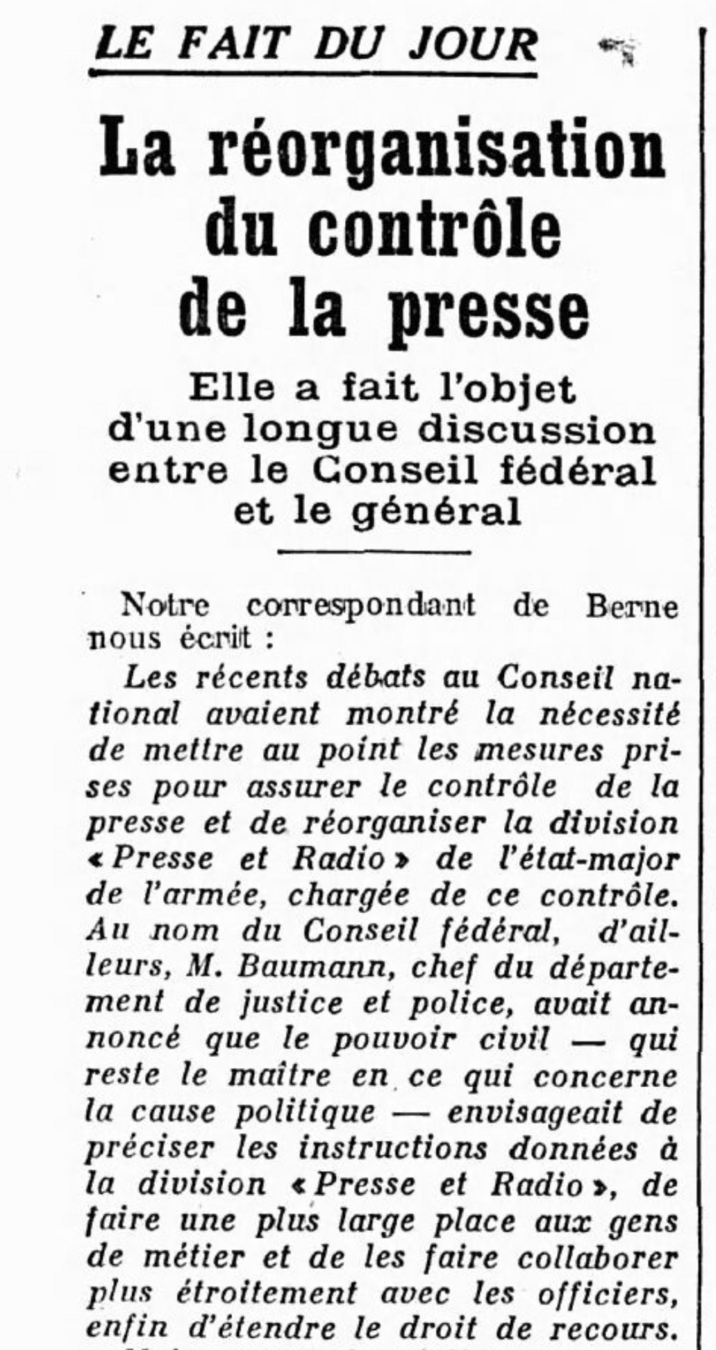
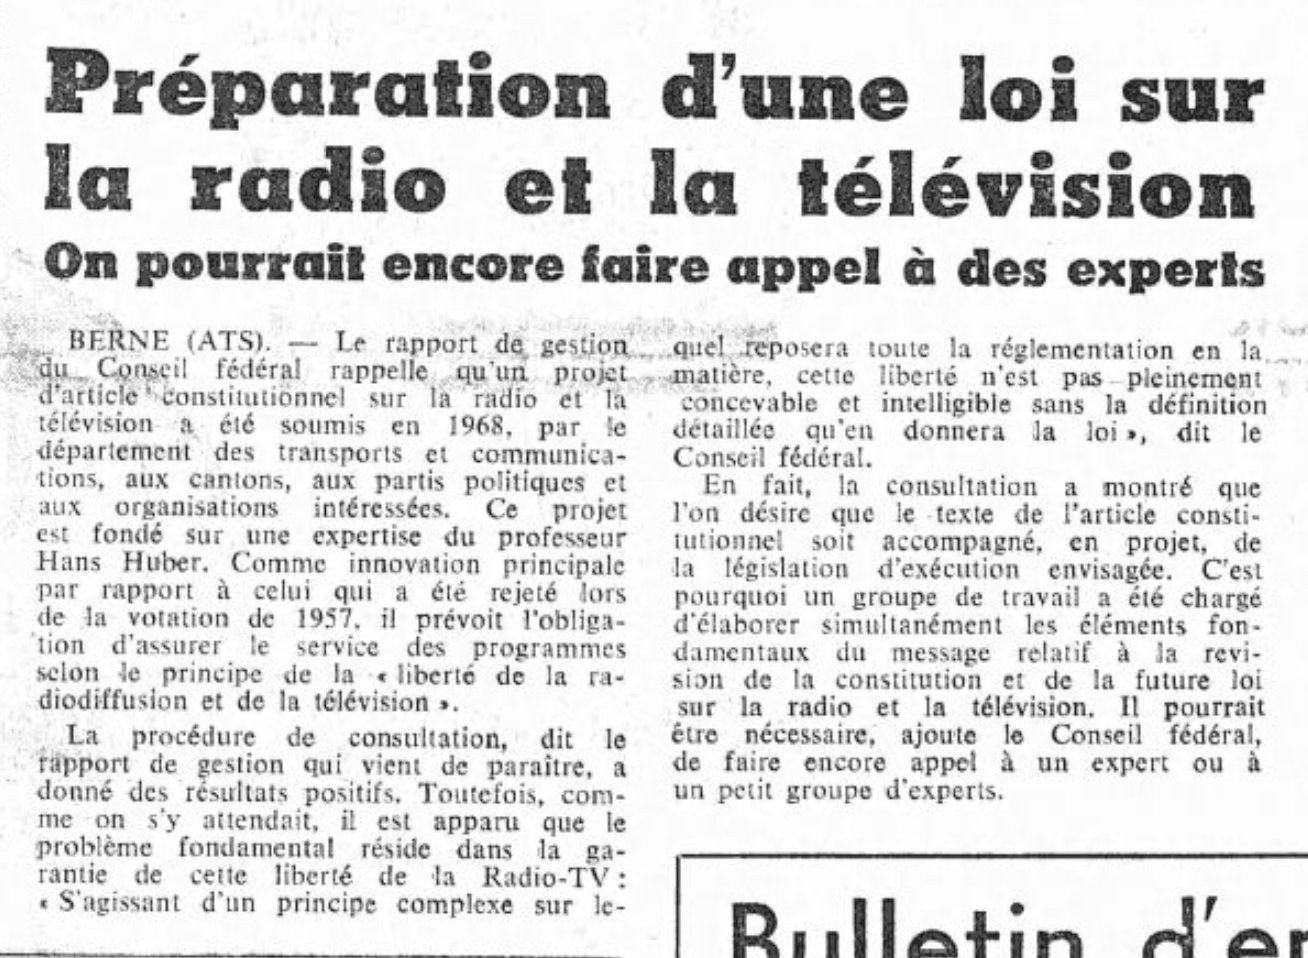
Feuille d'avis de Neuchâtel 1970
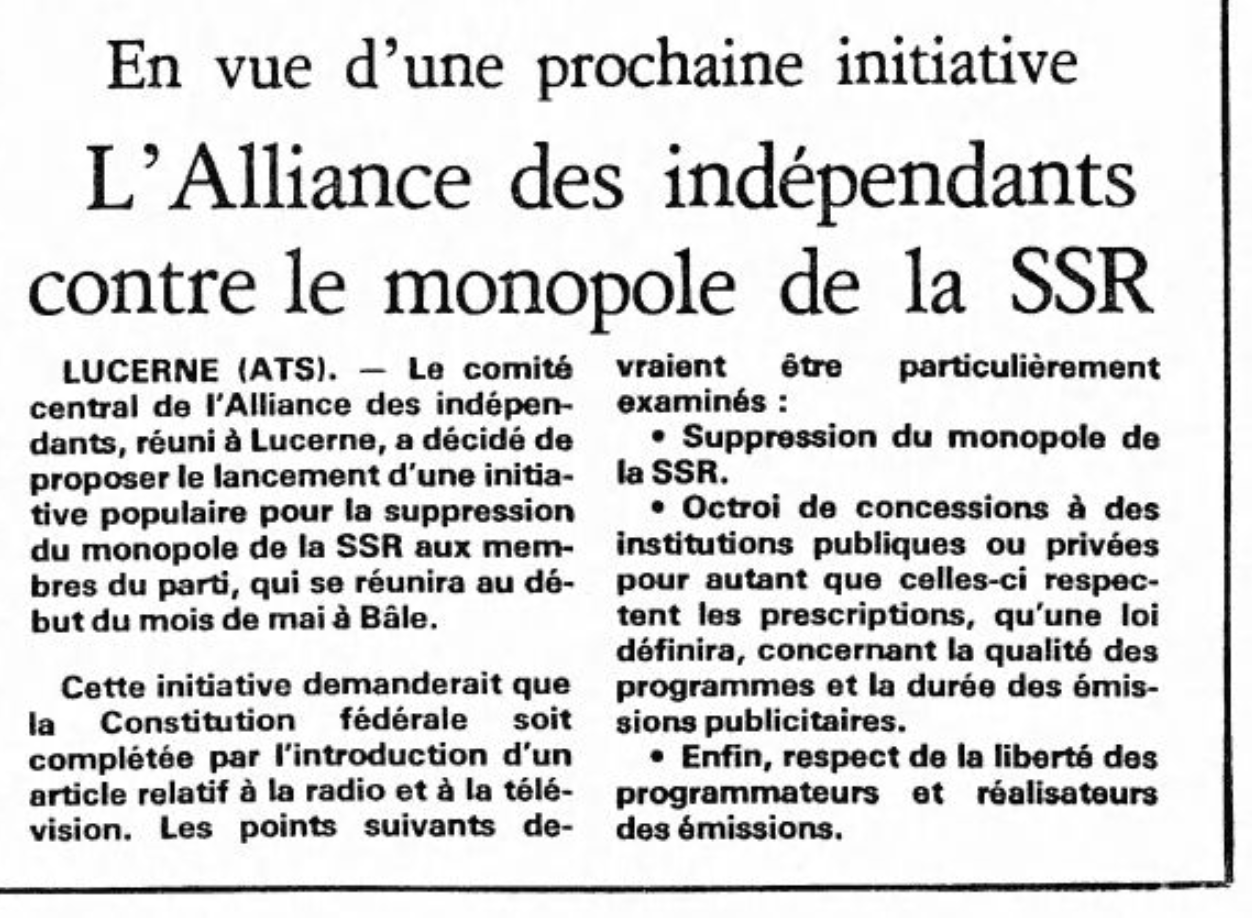
Feuille d'avis de Neuchâtel 1980
Category 4
Radio as a subject in the news
Radio in the press?
Feuille d'avis de Neuchâtel 1940
The press also shows us when and how radio becomes part of people’s daily lives.
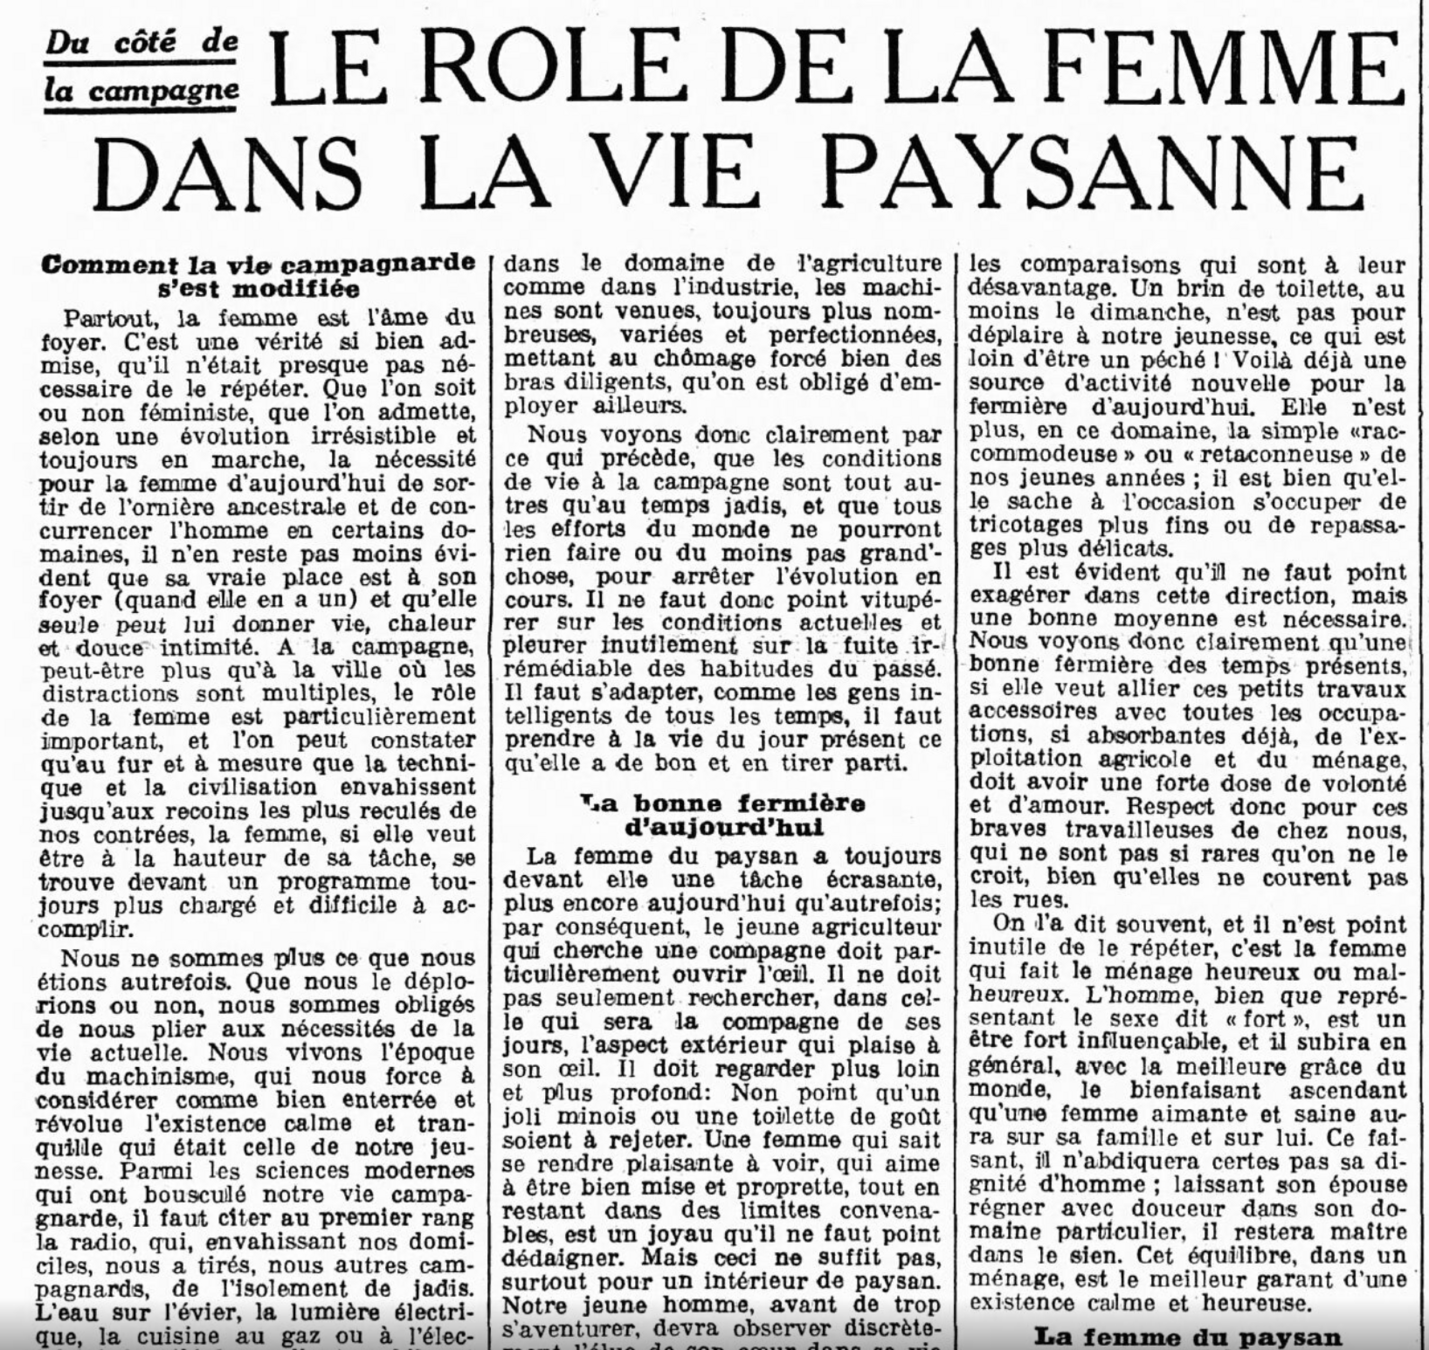
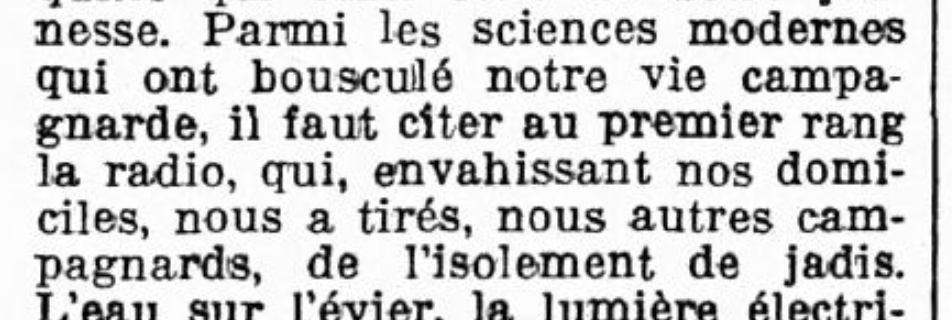
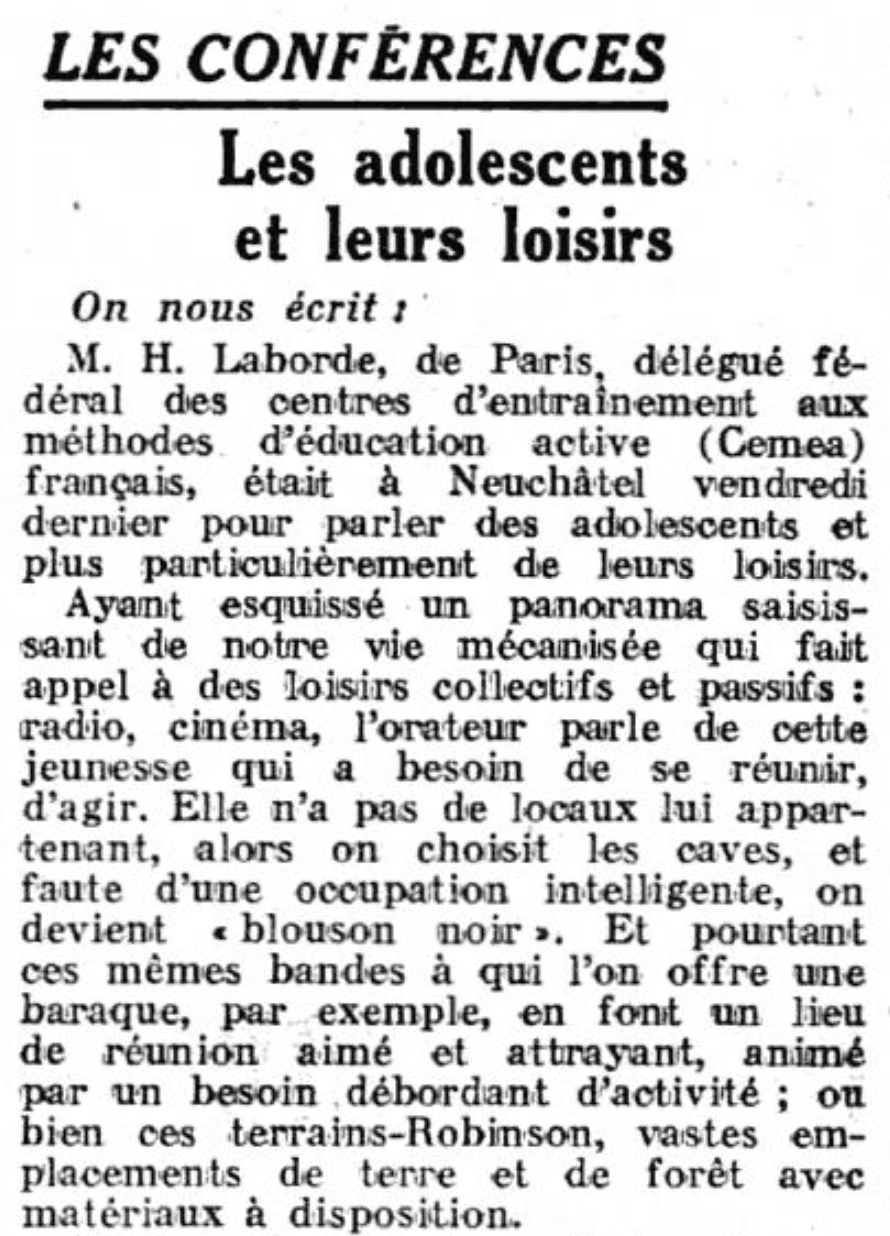
Feuille d'avis de Neuchâtel 1960
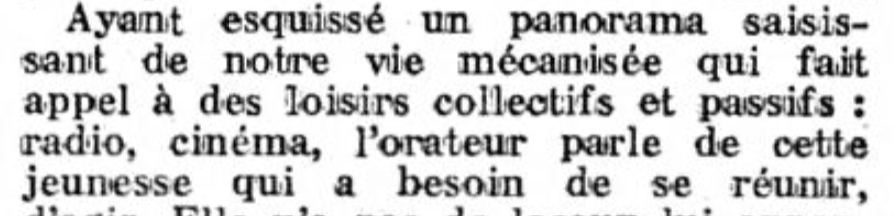
Category 4
Radio as a subject in the news
Radio in the press?
L'Impartial 1926
Finally, the press is also a source for studying the history of radio technology
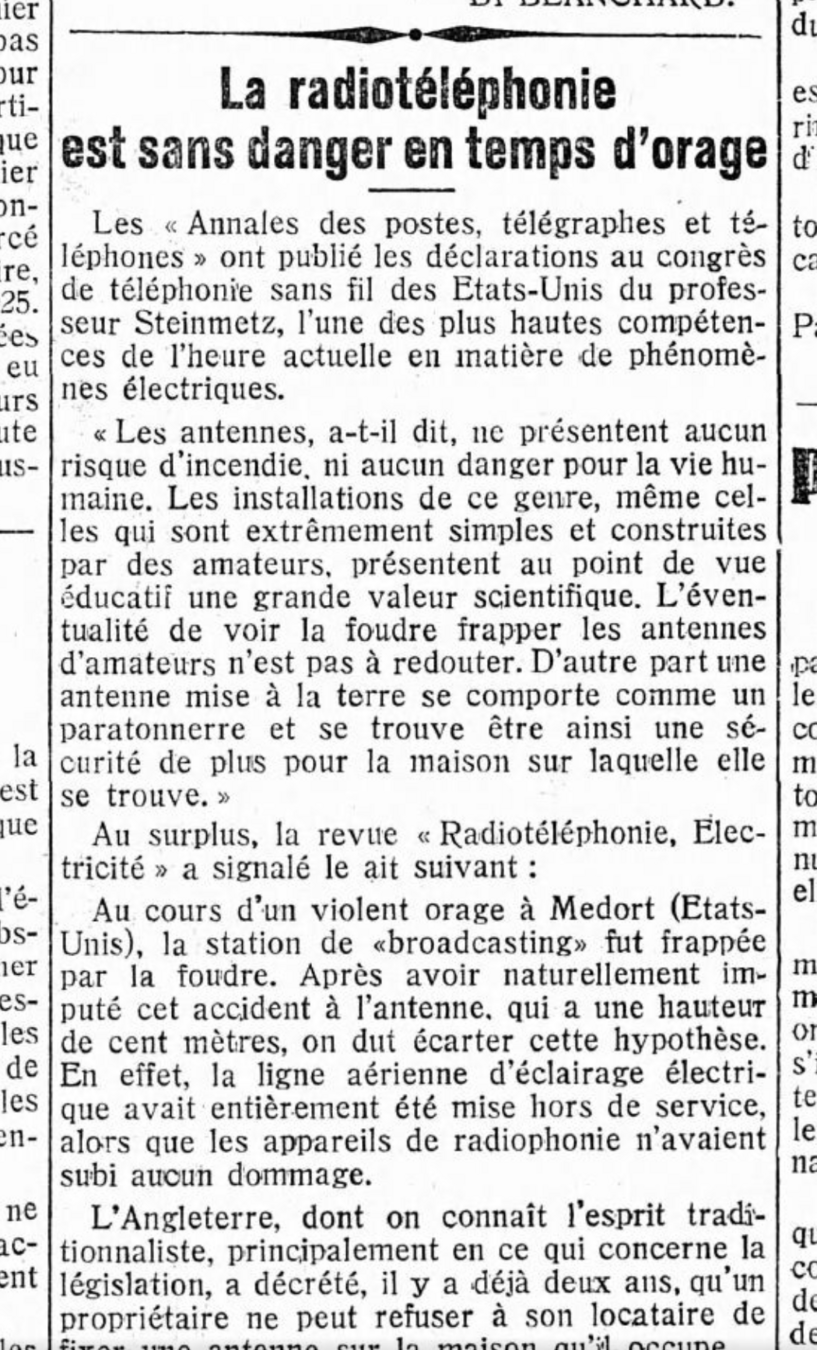
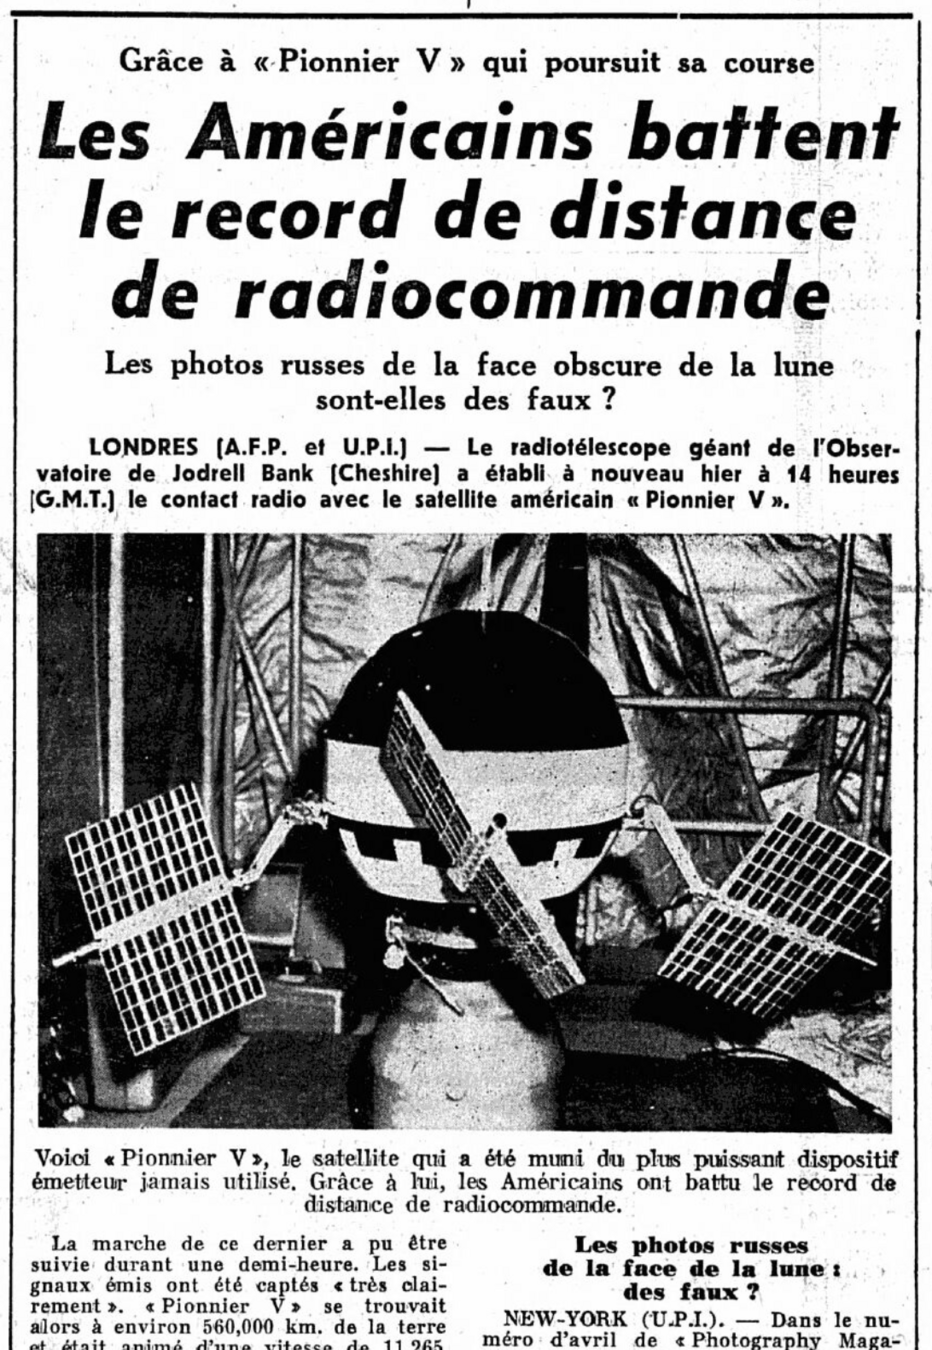
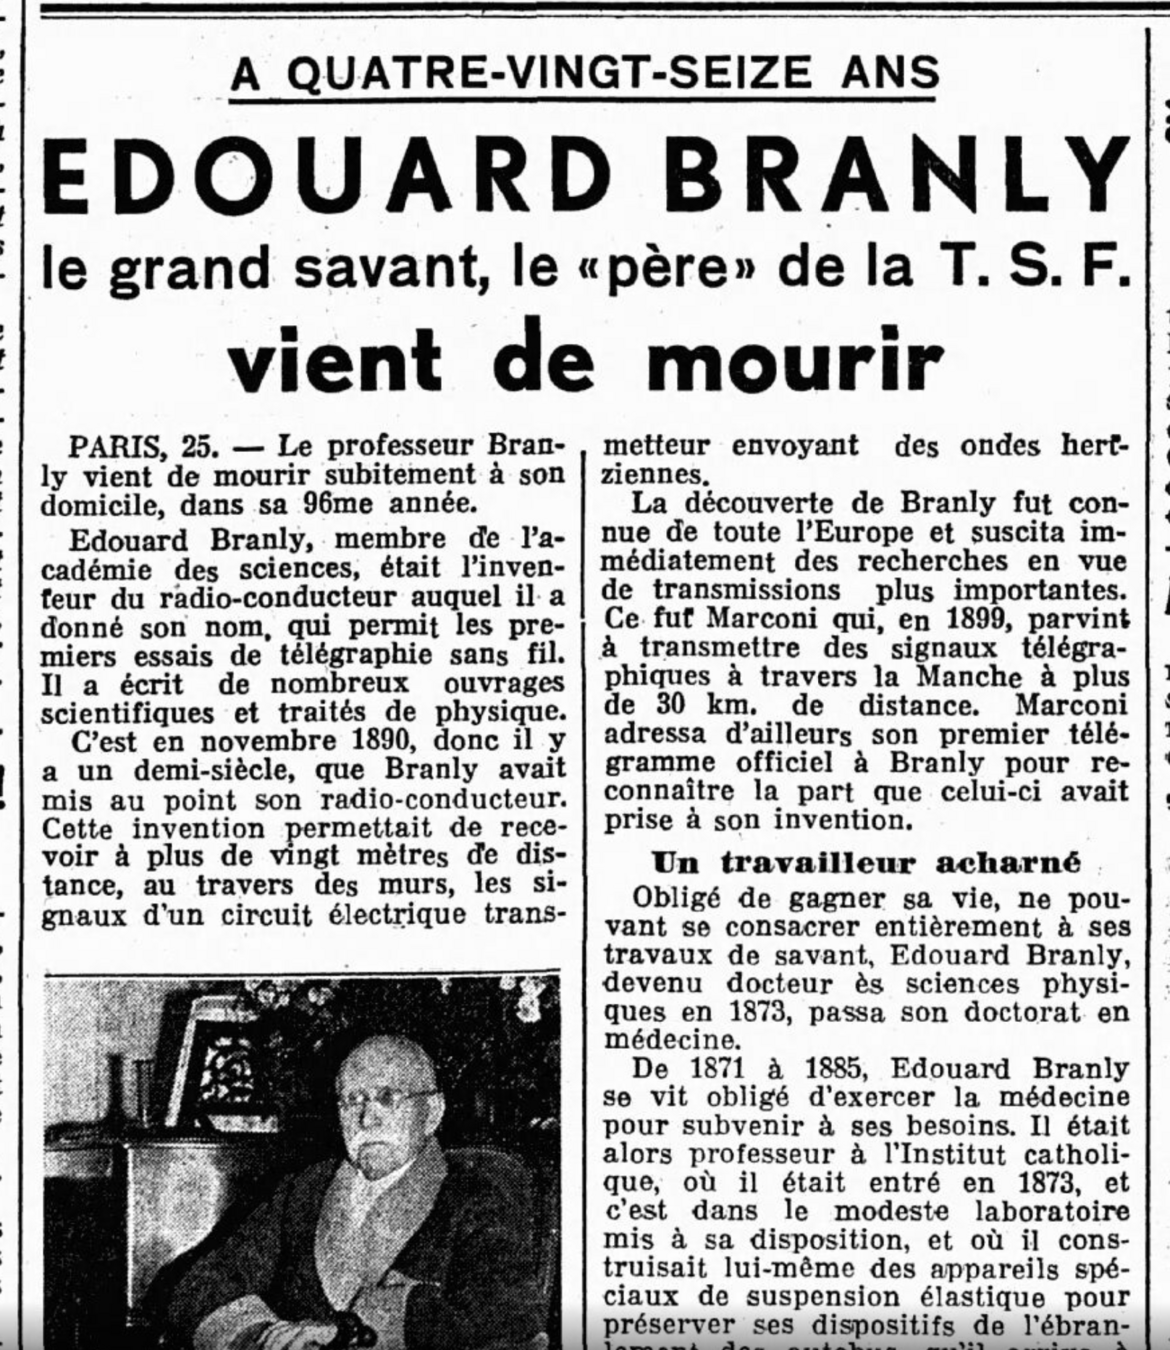
Feuille d'avis de Neuchâtel 1940
Feuille d'avis de Neuchâtel 1960
Category 4
Radio as a subject in the news
Radio in the press?
Feuille d'avis de Neuchâtel 1960
Worth noting: While radio and TV magazines would be a major source for writing about the people behind the radio, the press is also very valuable.
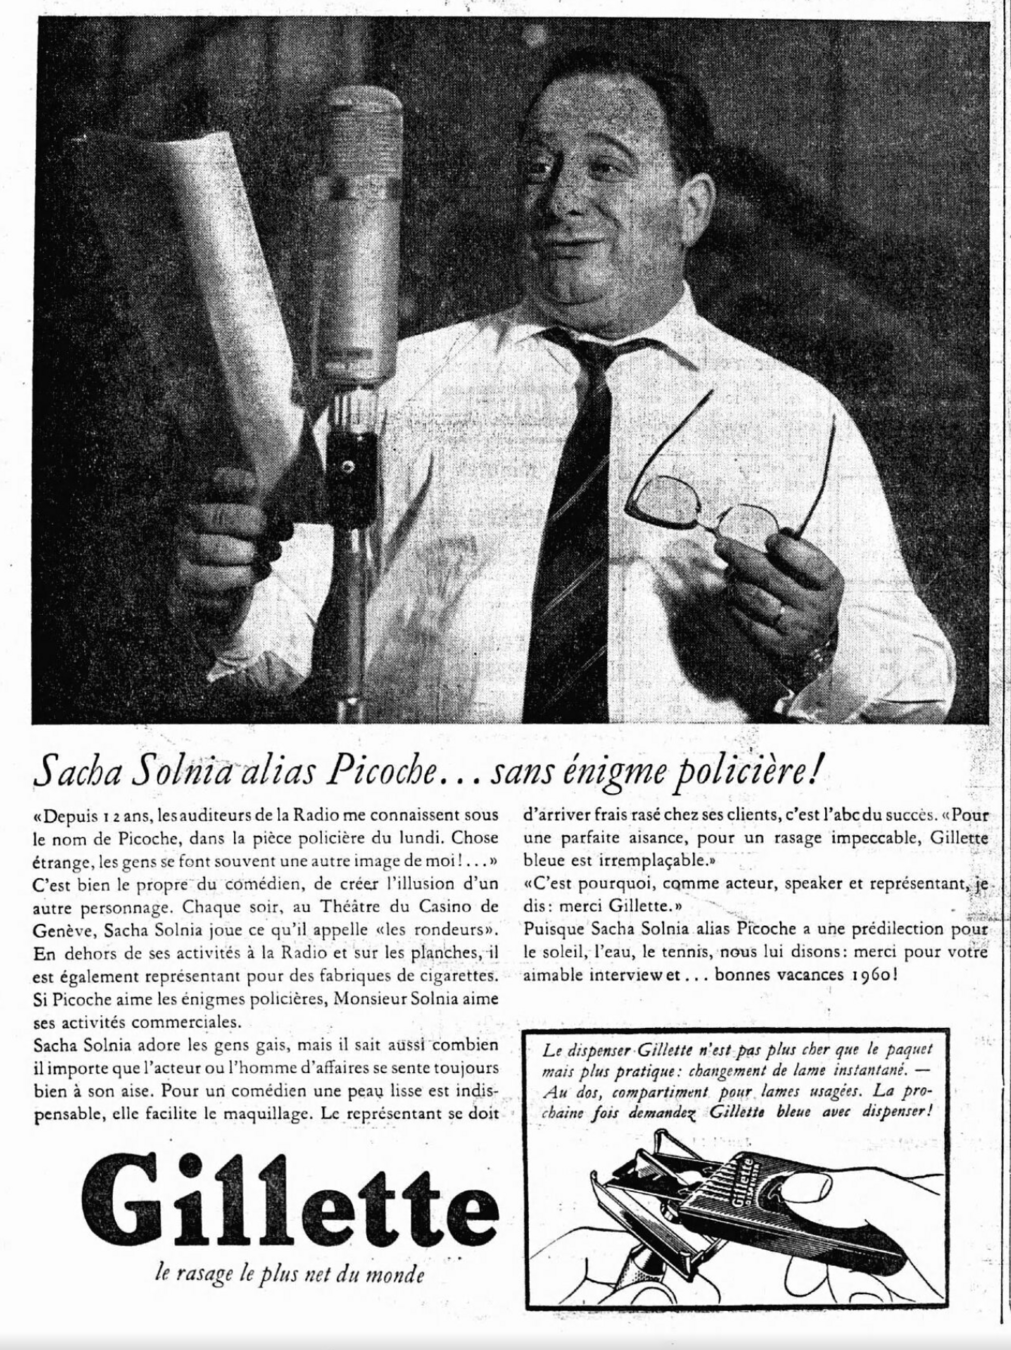
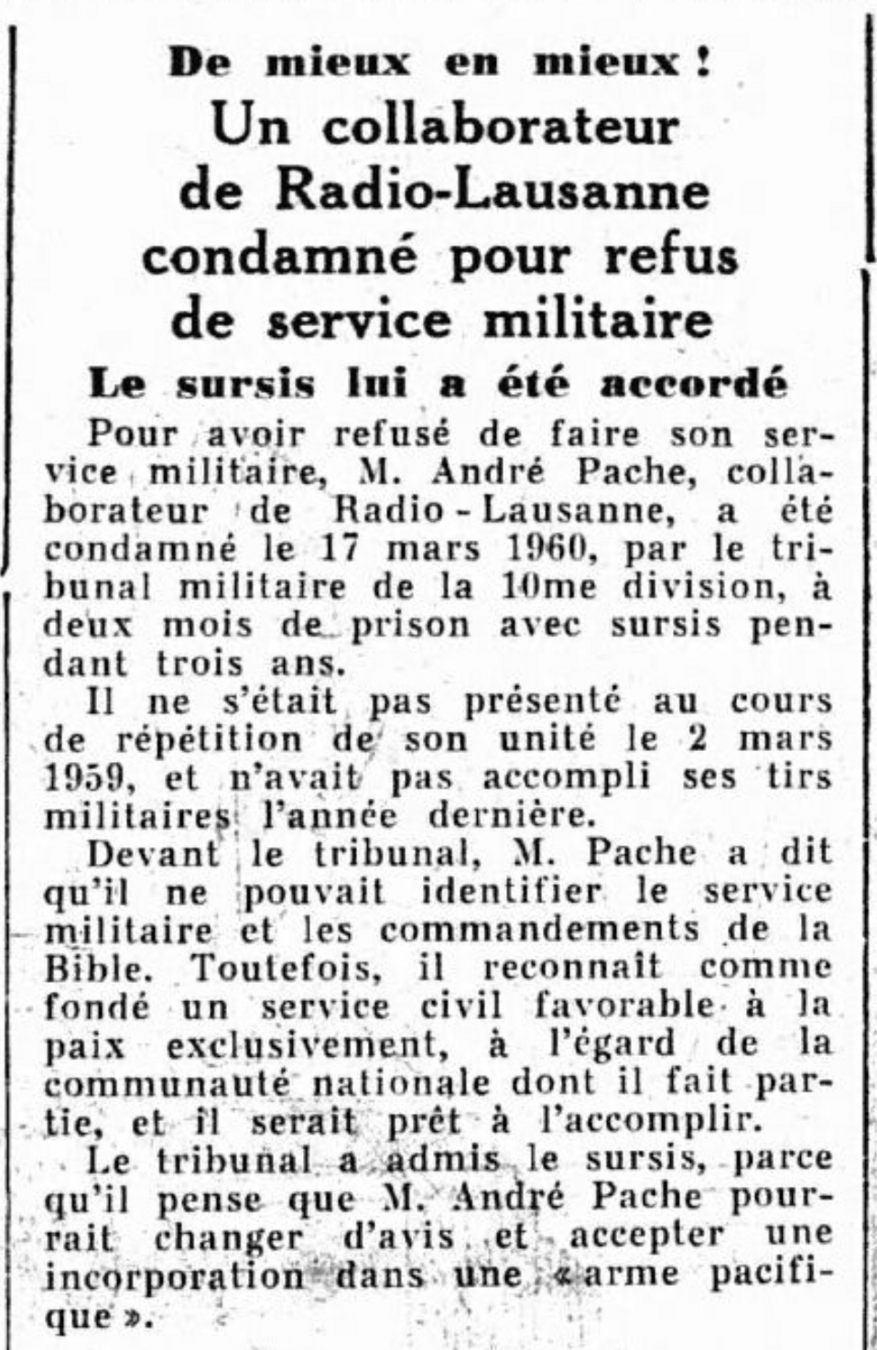
Feuille d'avis de Neuchâtel 1960
These two articles, published in the same issue on March 30, 1960, offer two unique perspectives on the people behind the microphone:
On the left, a popular radio host “reveals” himself in a photo… for an advertisement for a brand of razors! On the right, a report states that a radio employee has been convicted for refusing to serve in the Swiss army due to his pacifist and religious beliefs.
Named entities
This leads us down an interesting path: can we study the people who appear in the selected articles?
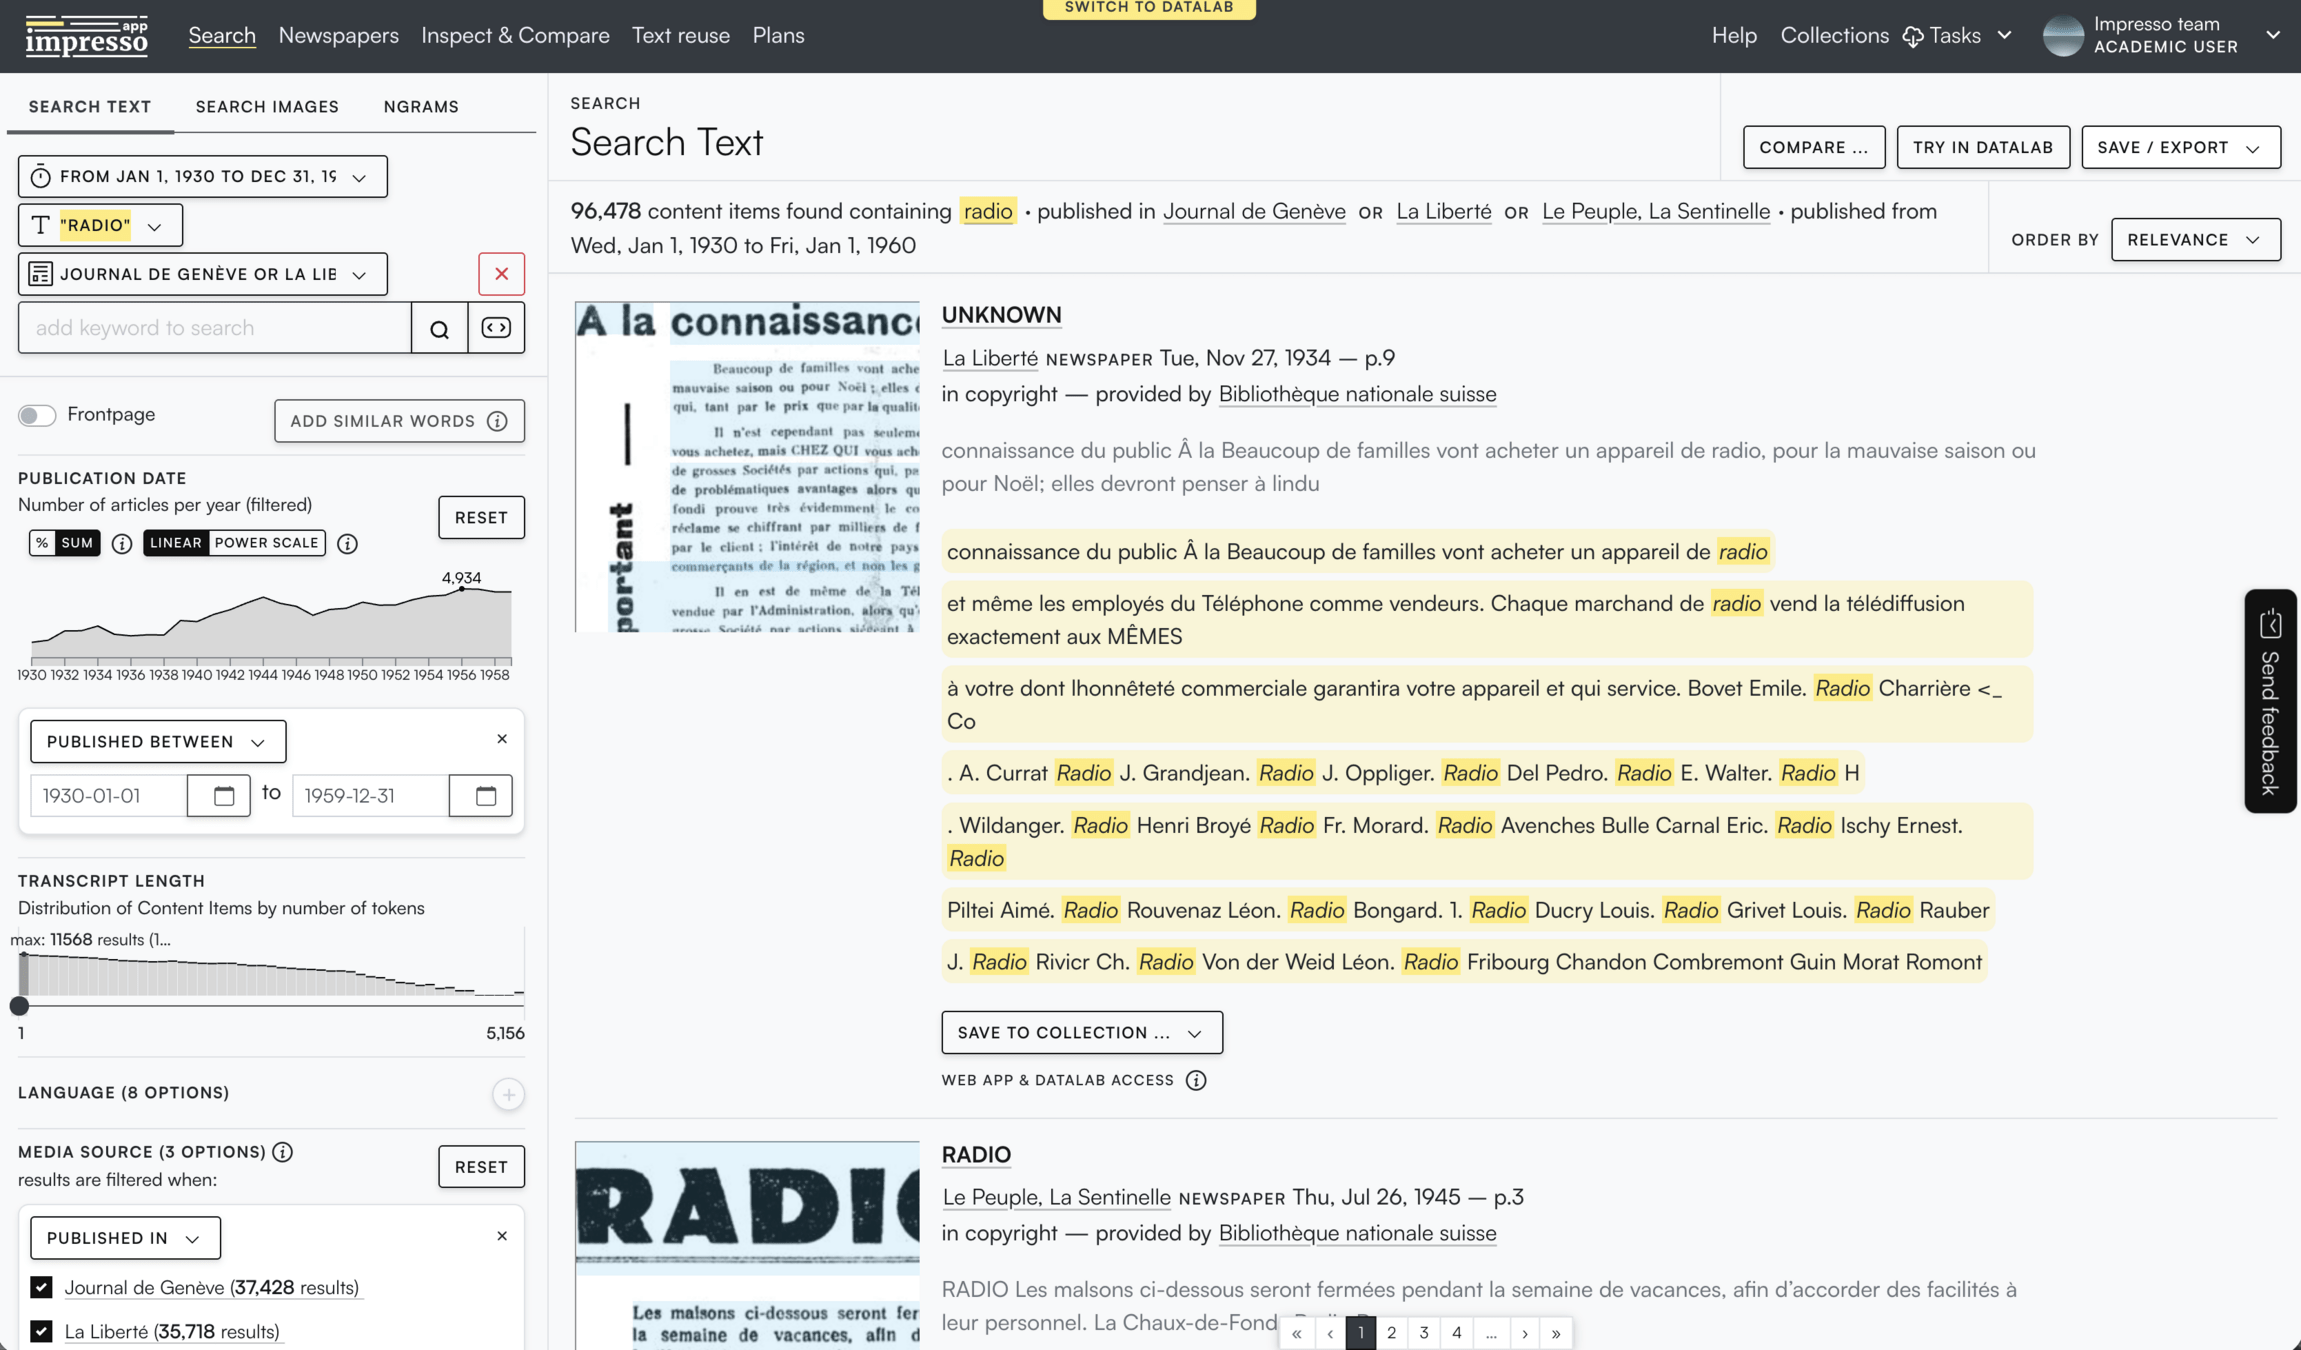
In the Impresso app, “named entities” (people, places, organizations) mentioned in articles are automatically identified.
Named entities
This leads us down an interesting path: can we study the people who appear in the selected articles?
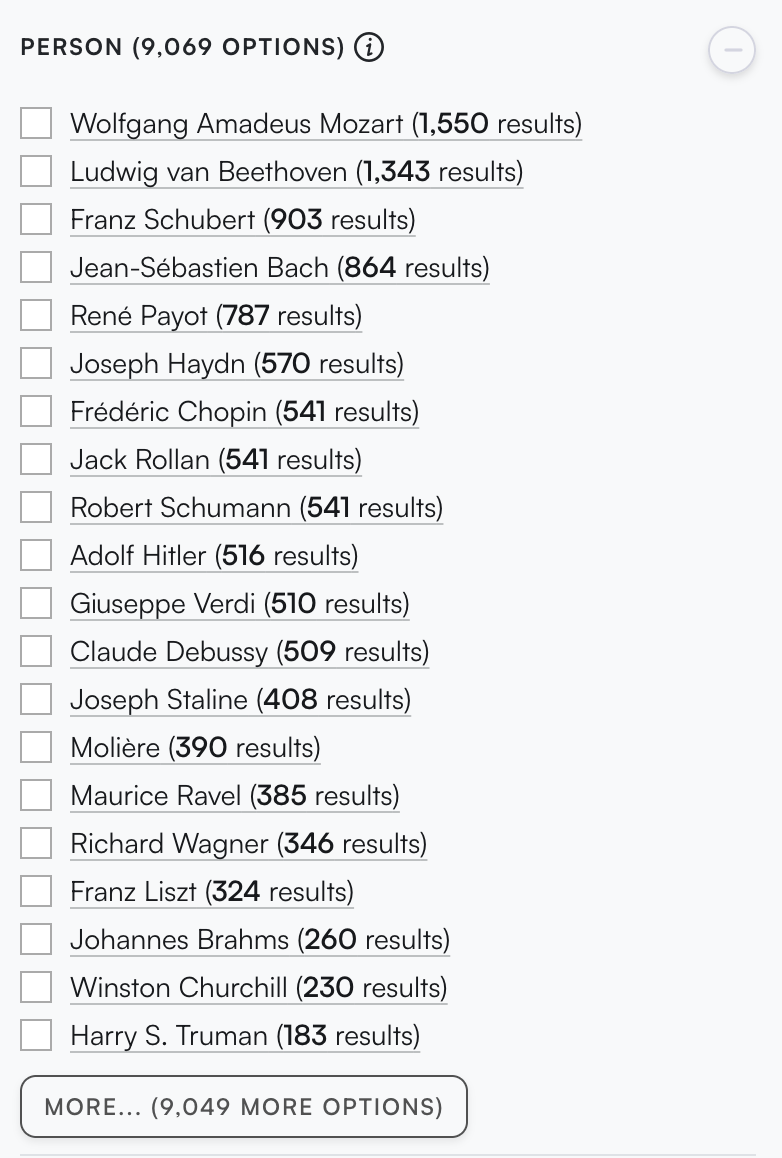
In a collection centered on the keyword “radio,” three categories of people emerge: composers, heads of state and prominent politicians, and… figures from the radio world.
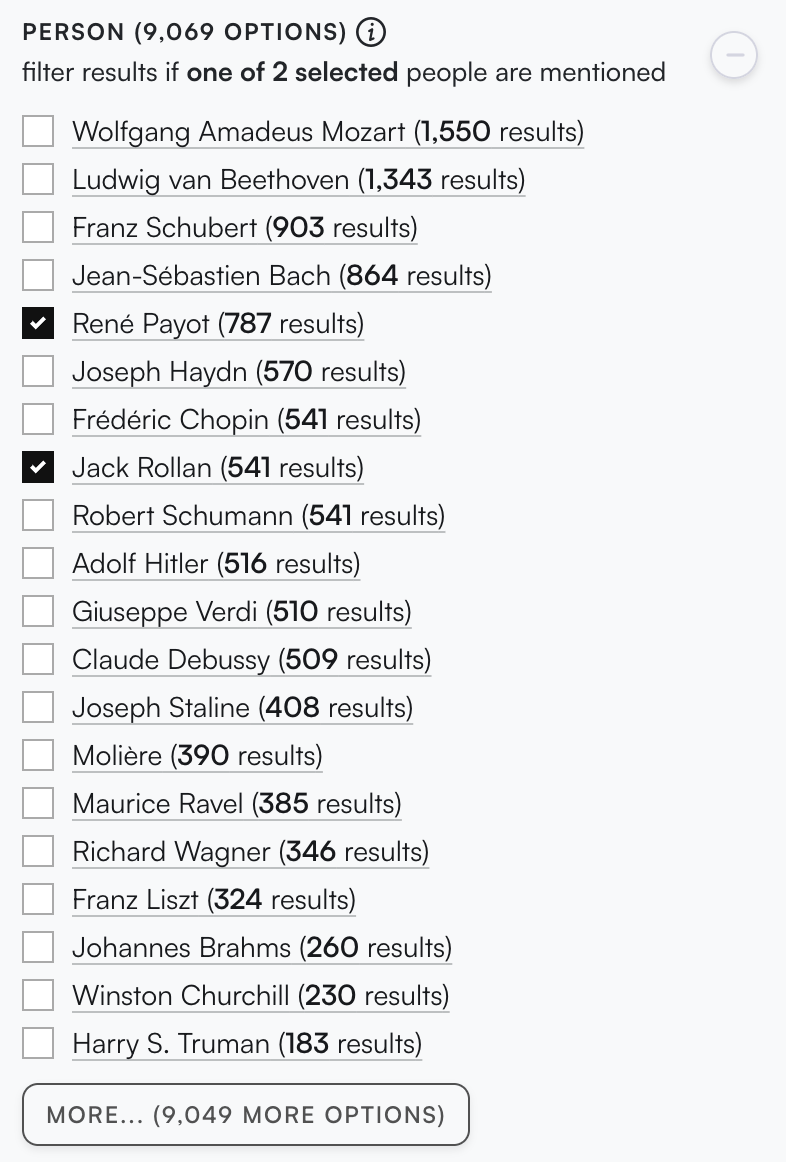
In our case, two individuals emerge: the journalist René Payot (who moved from print media to radio), and the satirist Jack Rollan (who did the opposite).
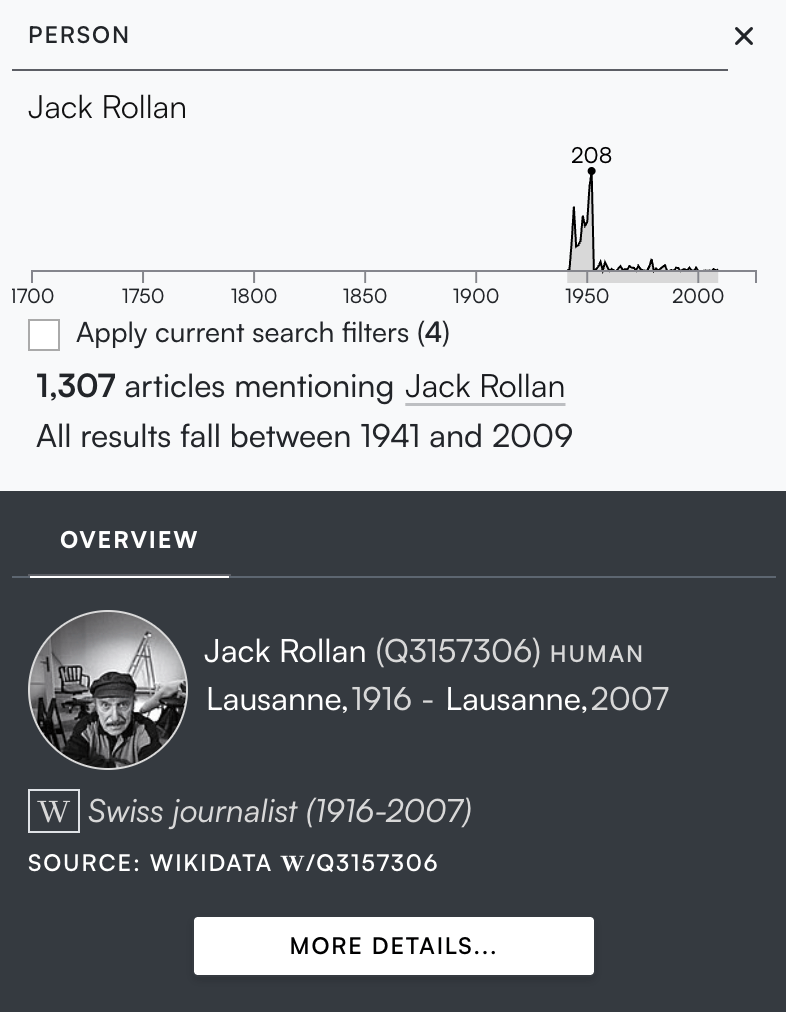
Entities are linked to the Wikidata entries for the relevant individuals, if such entries exist.
Named entities
The platform allows users to search for all instances of a named entity
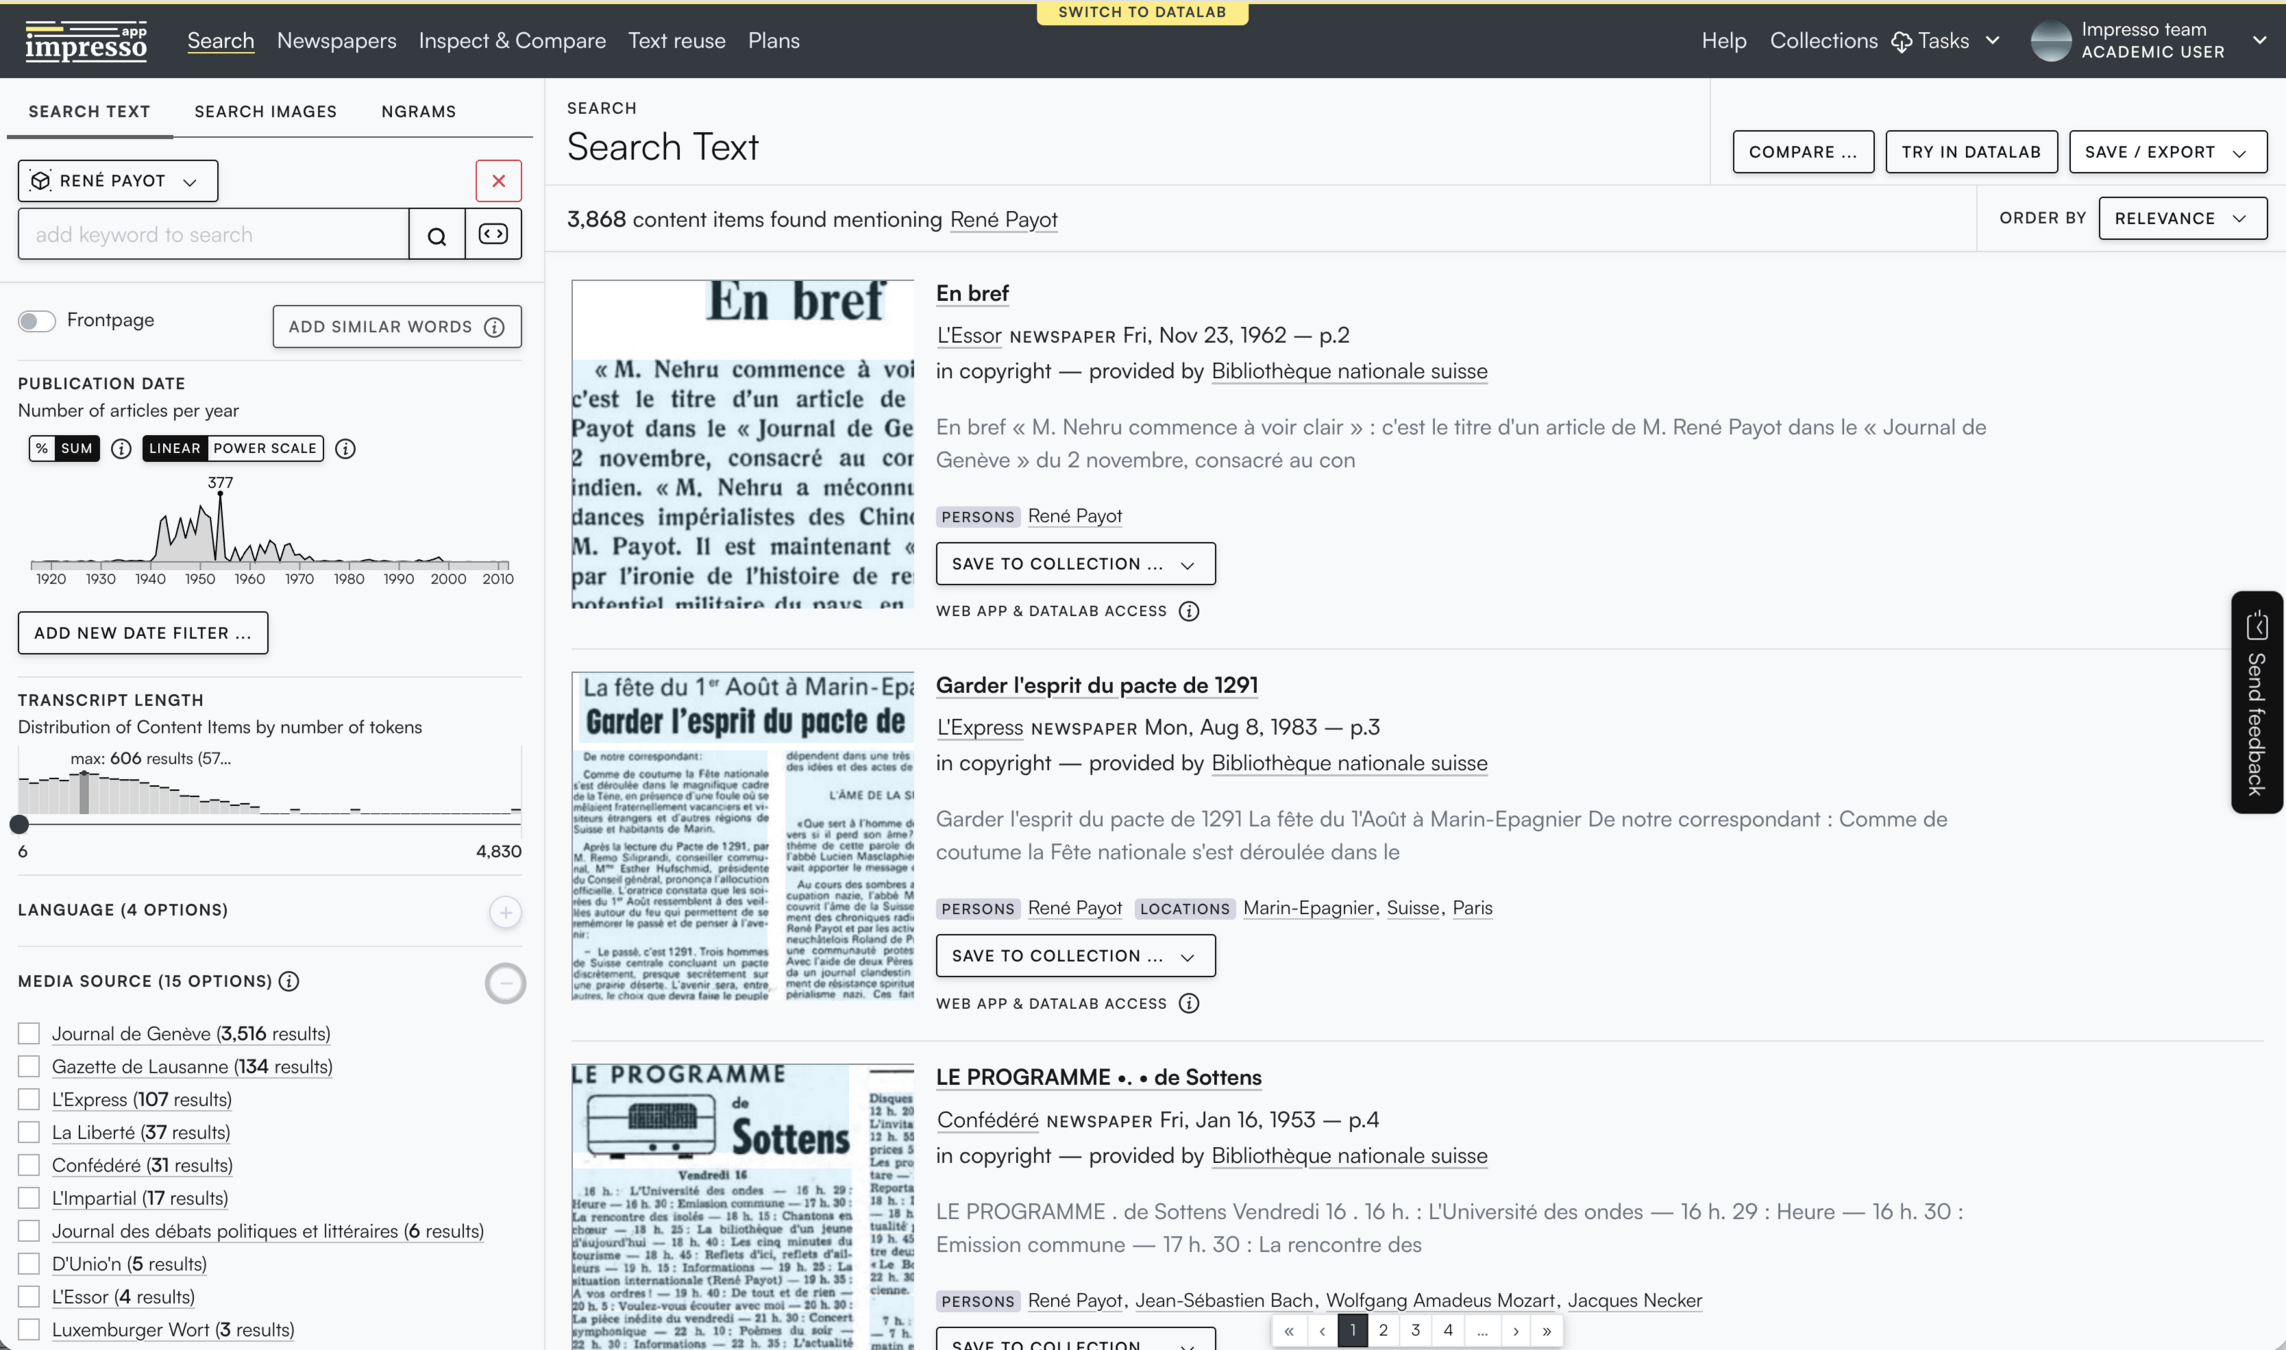
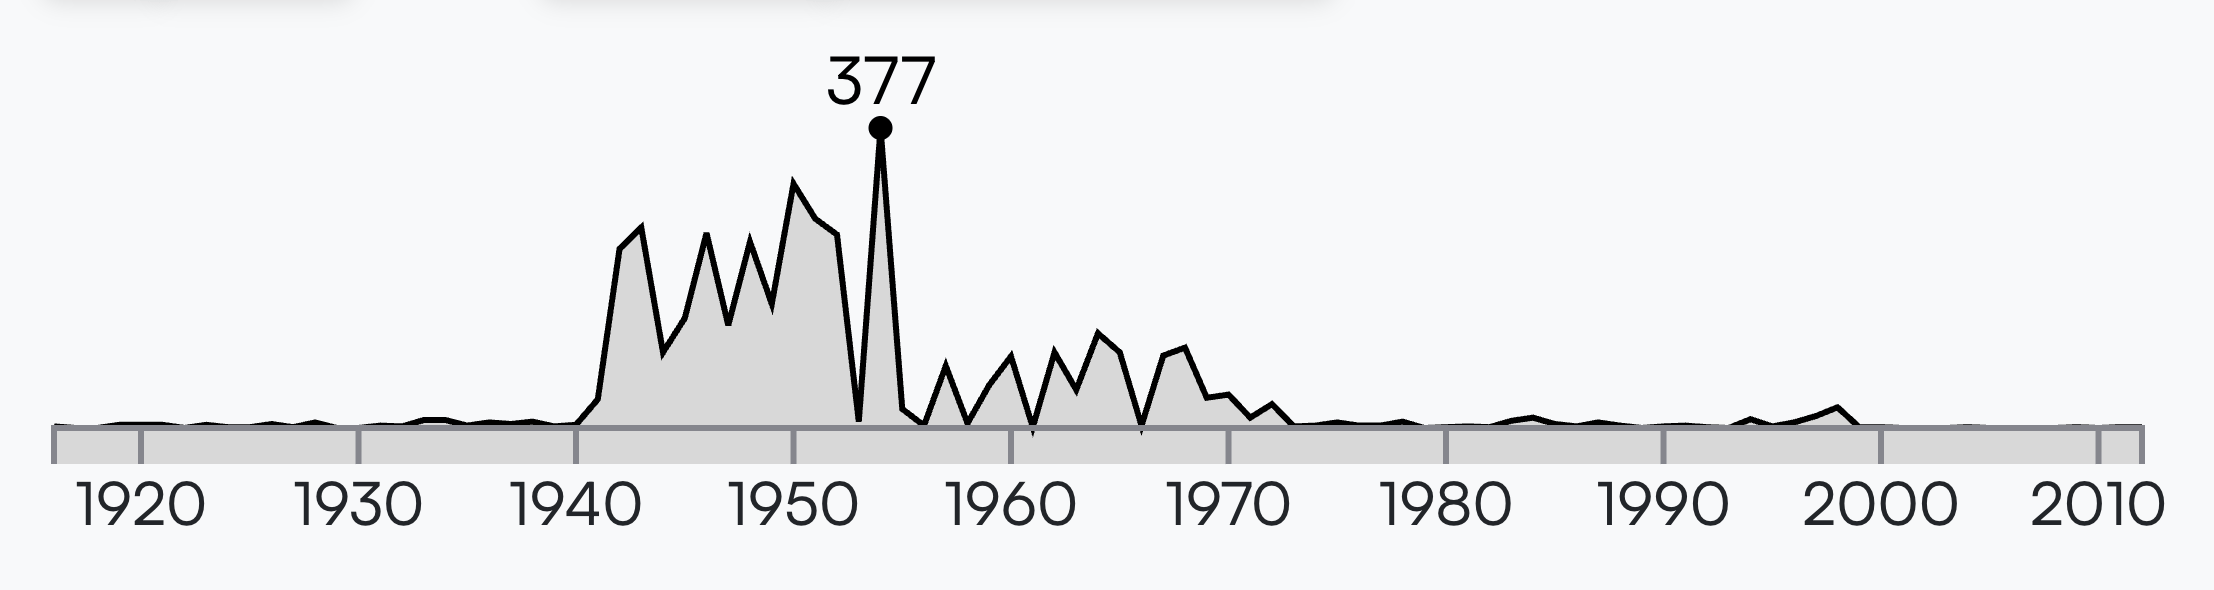
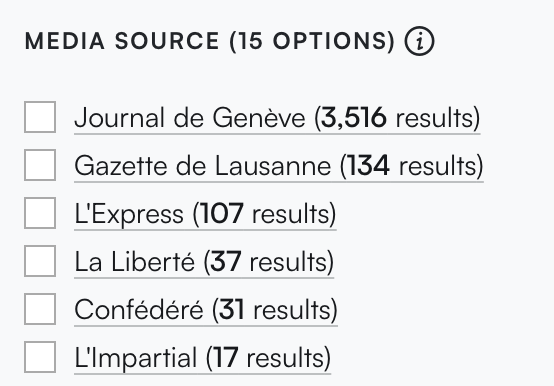
This provides insight into the timeline of René Payot’s career, a journalist for the Journal de Genève who went on to become a radio commentator on international news during World War II, before hosting widely listened-to international news programs for two decades.
Radio in Impresso
But very soon, there will also be radio collections available right in Impresso!
1. Radio in text format
Radio typescripts
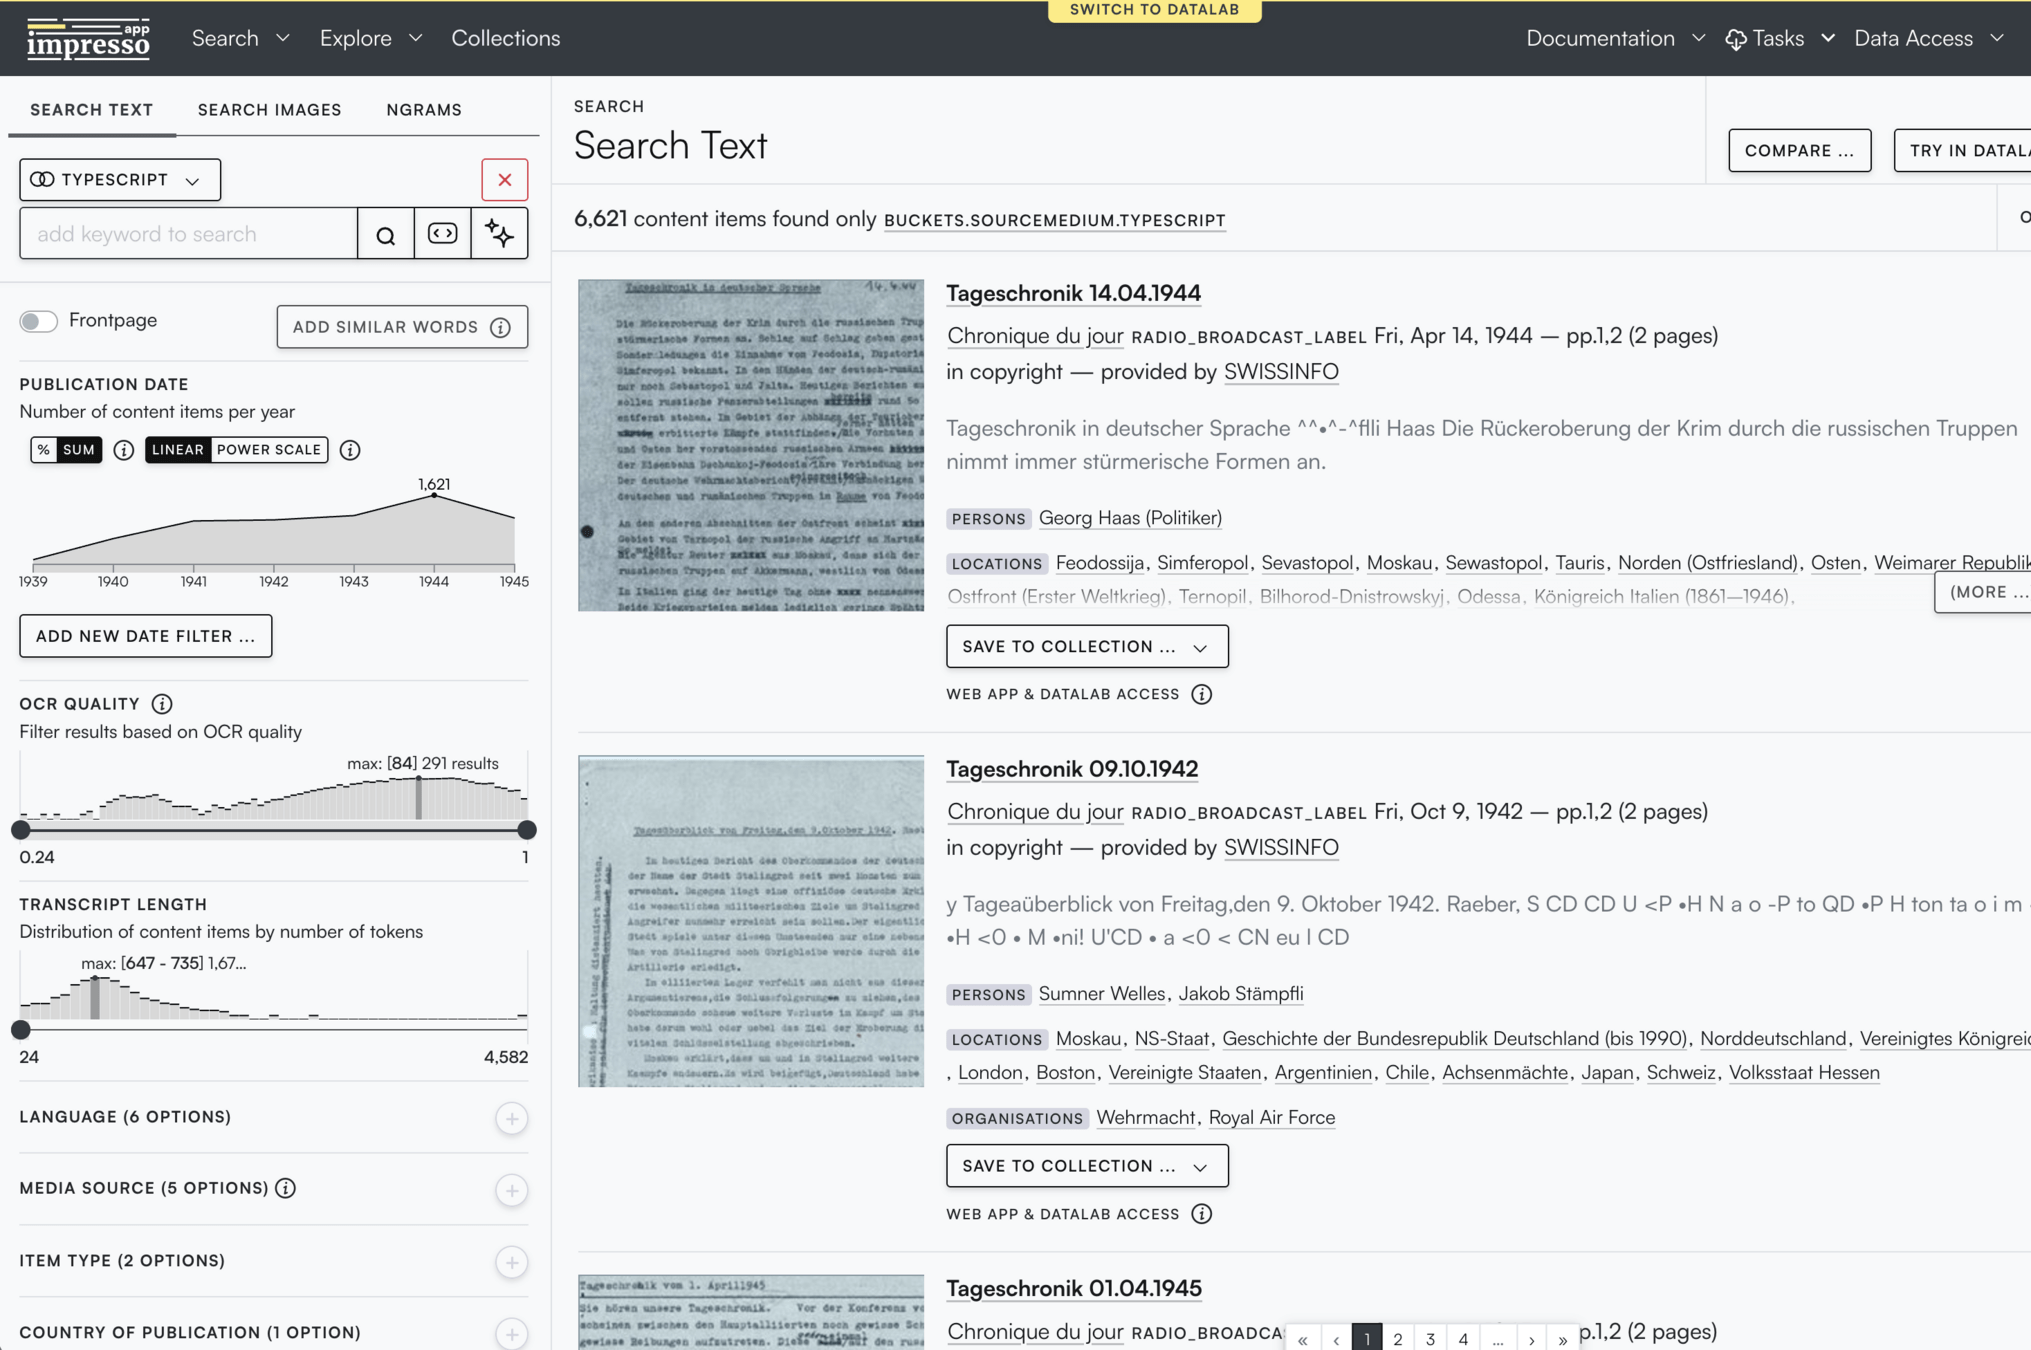
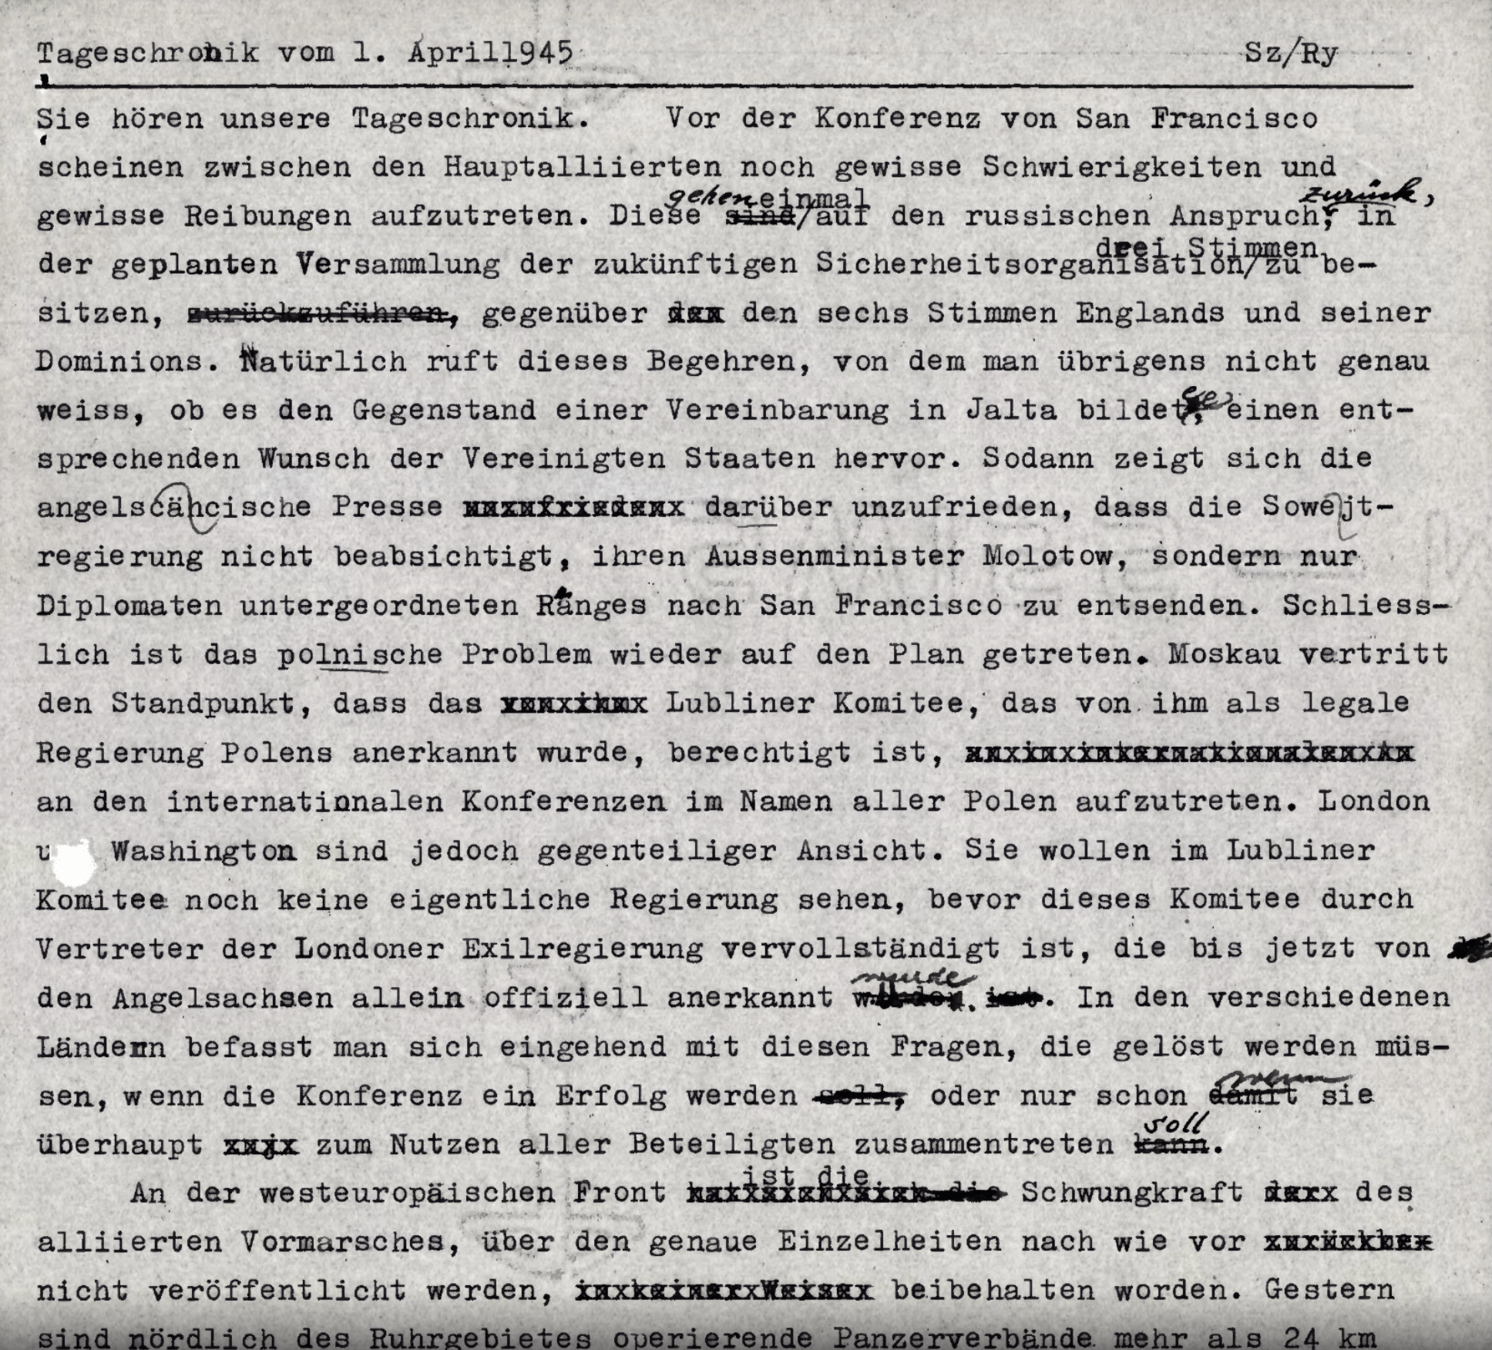
We have received the transcripts from Swissinfo, the Swiss international radio station, covering the period of World War II, in French and German.
Radio in Impresso
But very soon, there will also be radio collections available right in Impresso!
2. Radio in audio format
Radio broadcasts
We are making major changes to the platform to enable it to support audio.
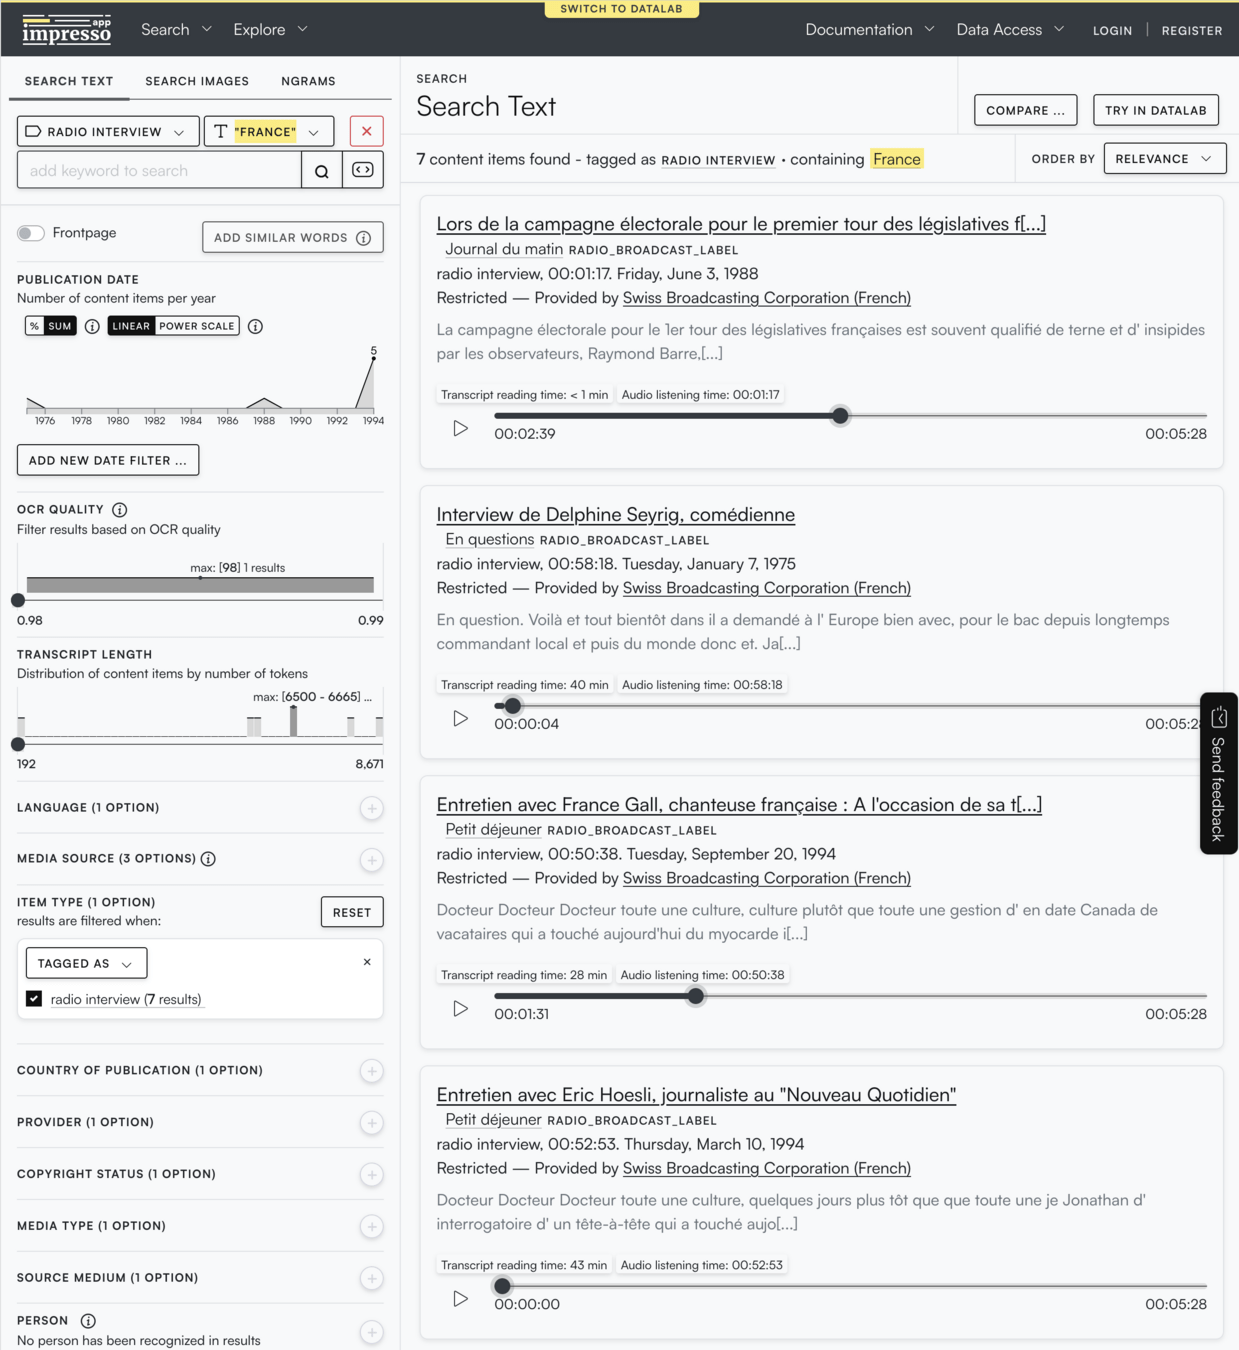
We have collections from RTS, radio stations in French-speaking Switzerland, and the INA, which archives French public radio, just waiting to be released.
Radio in Impresso
The key challenge is not only to integrate the audio, but also to ensure that the transcript can be used by users – for example, to find similar news articles.
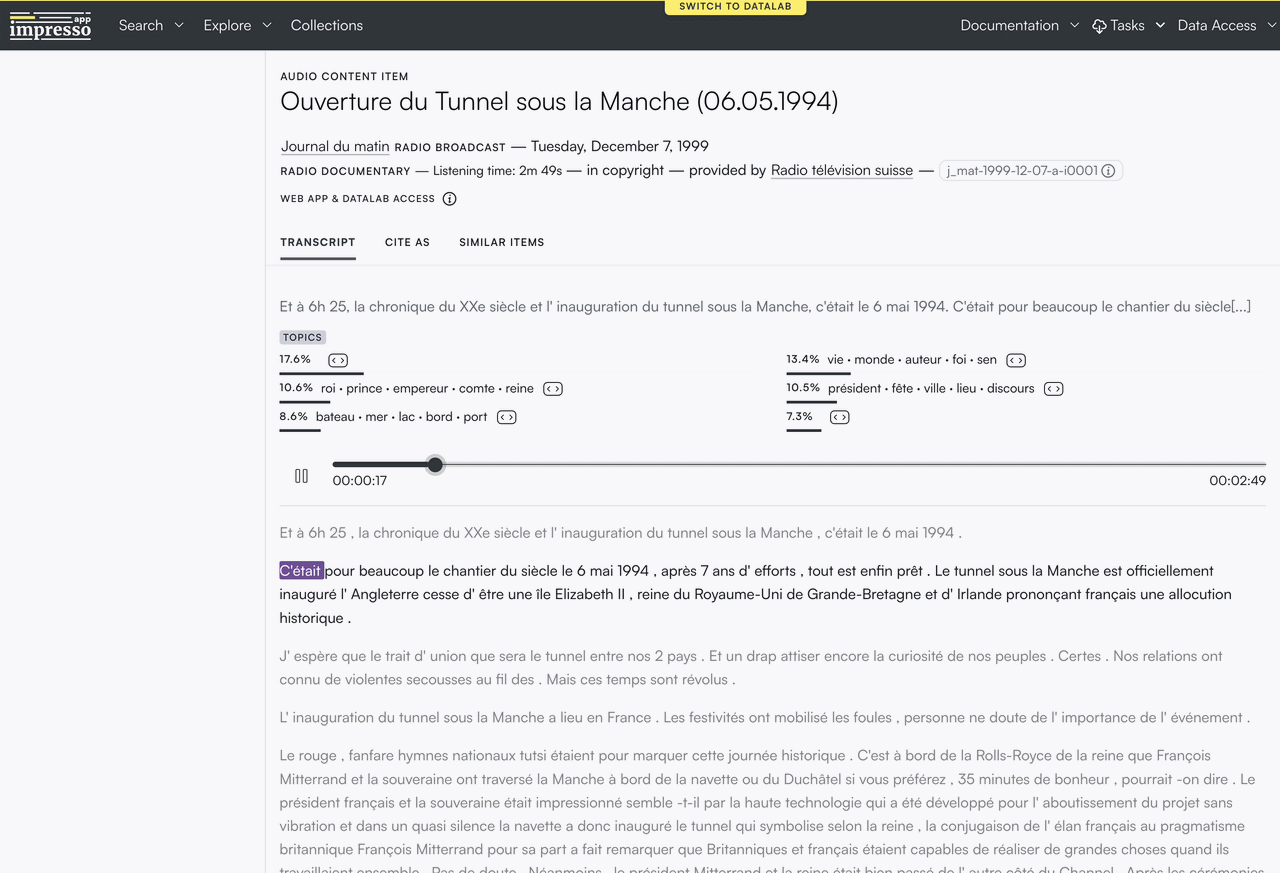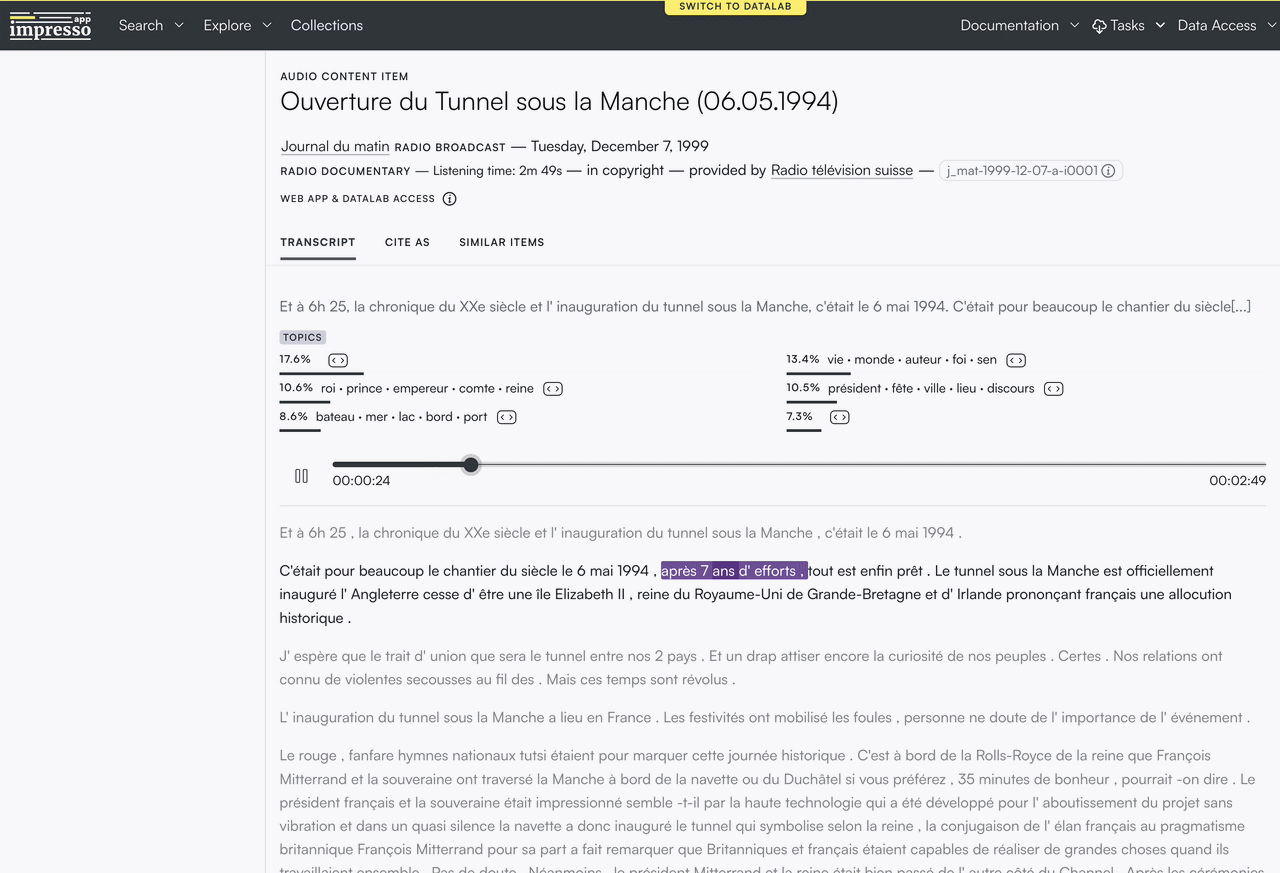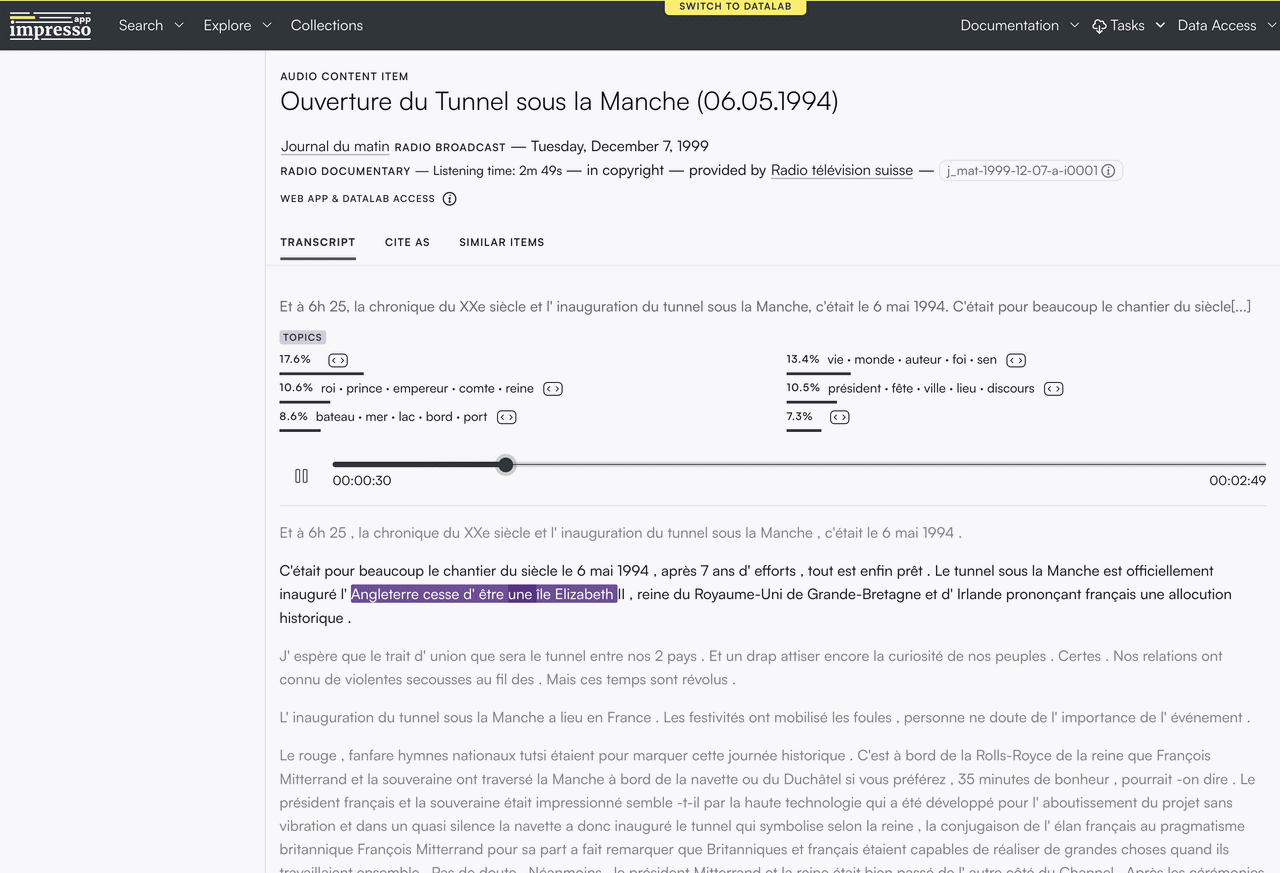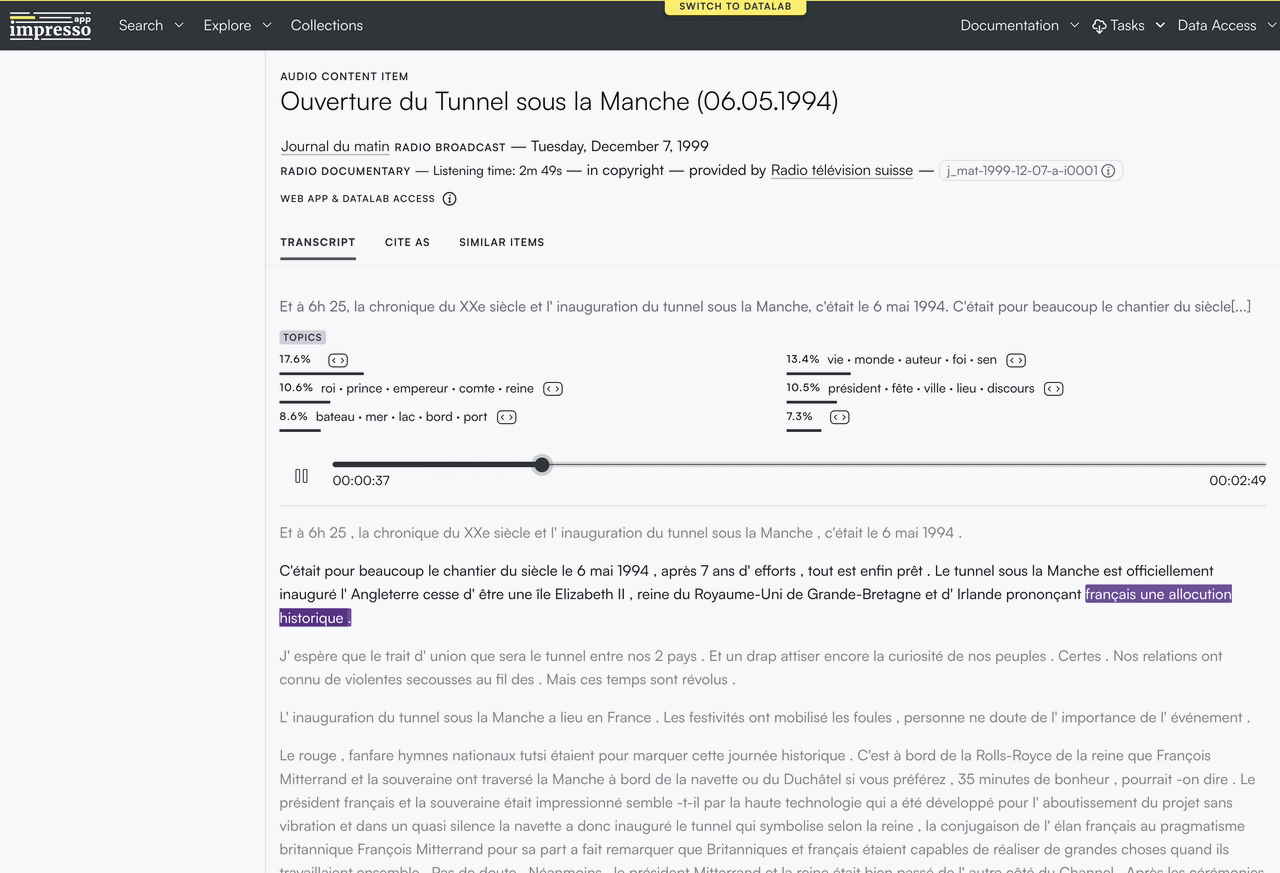
Next: Impresso datalab
In the next chapter, let’s see how digital humanities tools allow us to go further with the data from Impresso.

Challenges
In short, the Impresso project is a series of challenges:
I.
The data
Multiple sources, multiple formats, massive data, and numerous legal issues
II.
The design
Make all of this accessible and useful to the public
III.
The analysis
Enrich data to create added value and develop relevant analysis tools
IV.
Writing history
How should all of this be interpreted in the context of historical research?
Next: Impresso app
In the next chapter, let’s see how to use the Impresso app to explore the relationship between print media and radio
Challenge III.
The analysis
It's not just about collecting, it's about enriching and connecting
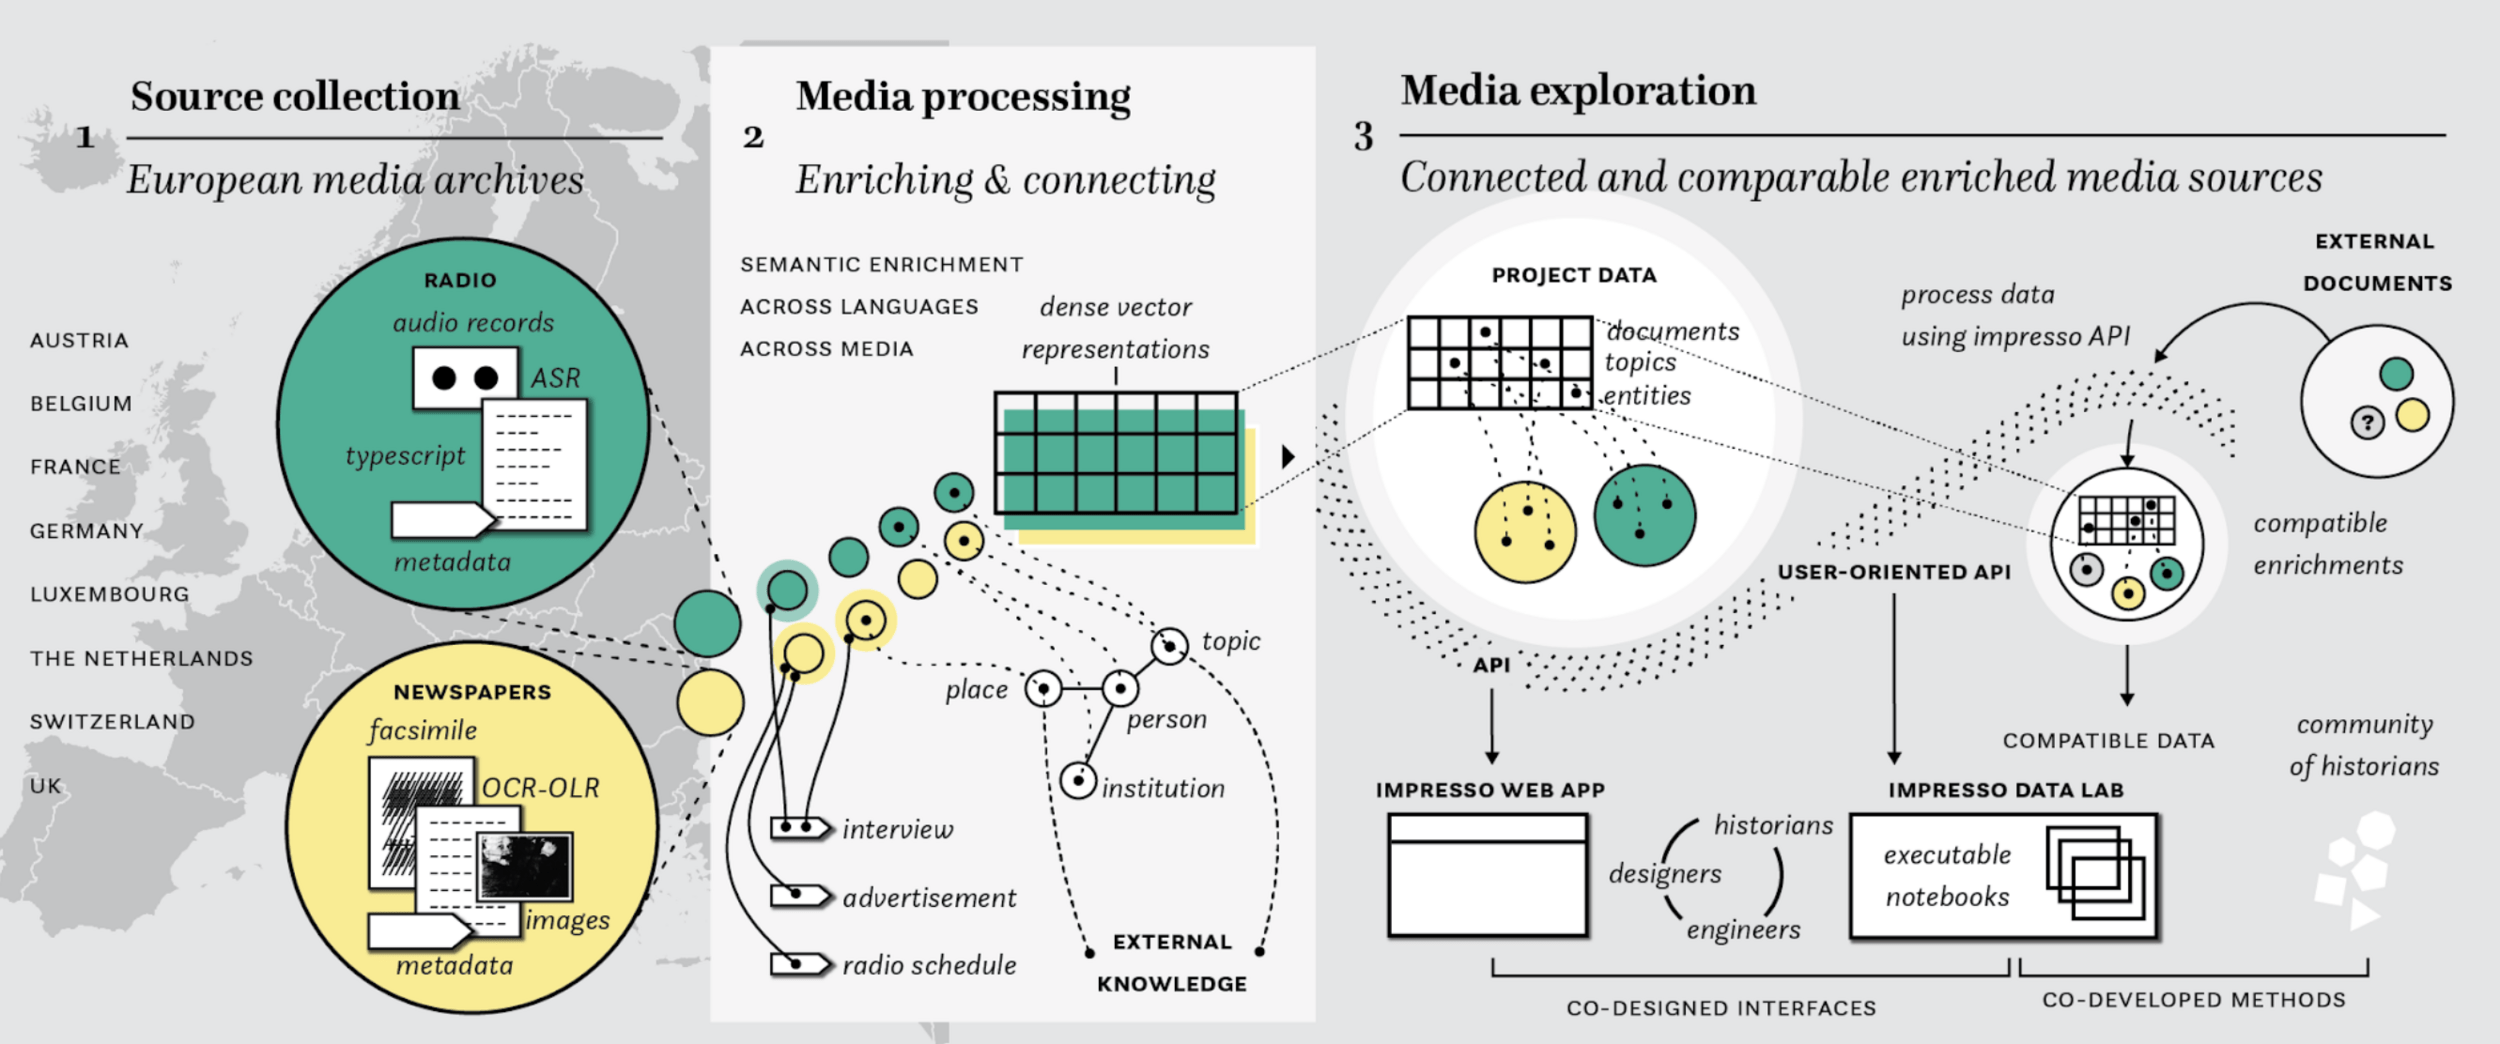
Conducting transmedia and transnational historical research using semantically enriched historical media sources
Impresso API
to process other sources
via notebooks in a datalab
and compare them to our data
Challenge III.
The analysis
It's not just about collecting, it's about enriching and connecting
Enriching and connecting historical sources by transforming noisy and heterogeneous sources into semantically enriched and structured data, ultimately connected in a common vector space.
The Impresso datalab
Welcome to the Impresso datalab
Sharing recipes so that people can embrace digital methods
The goal is to spark users’ curiosity, make computational methods accessible to them, and encourage them to explore code without needing to master it.
Descriptive statistics for a collection
Network of entities
Map of locations
Semantic proximity
The Impresso datalab
The Impresso datalab
First, you need to log in to the datalab to be then able create a temporary personal token.
The semantic space of a specific collection
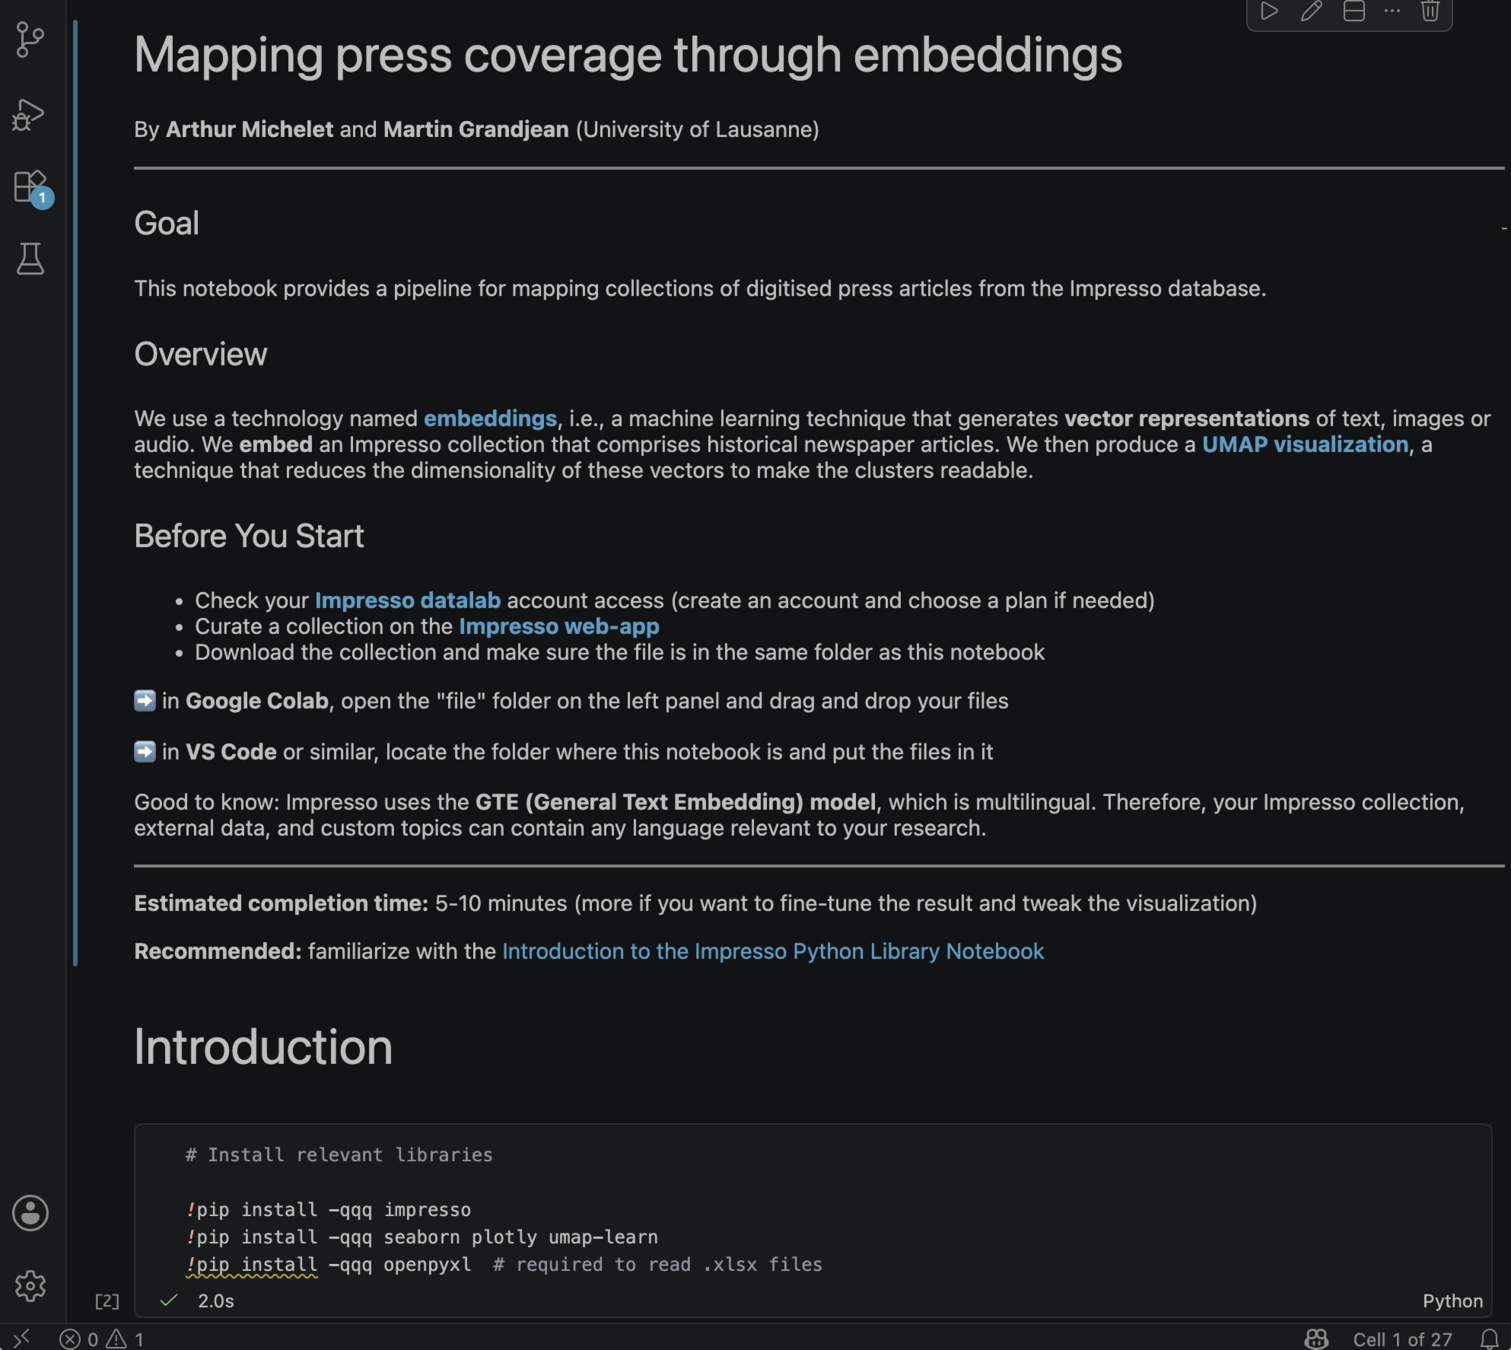
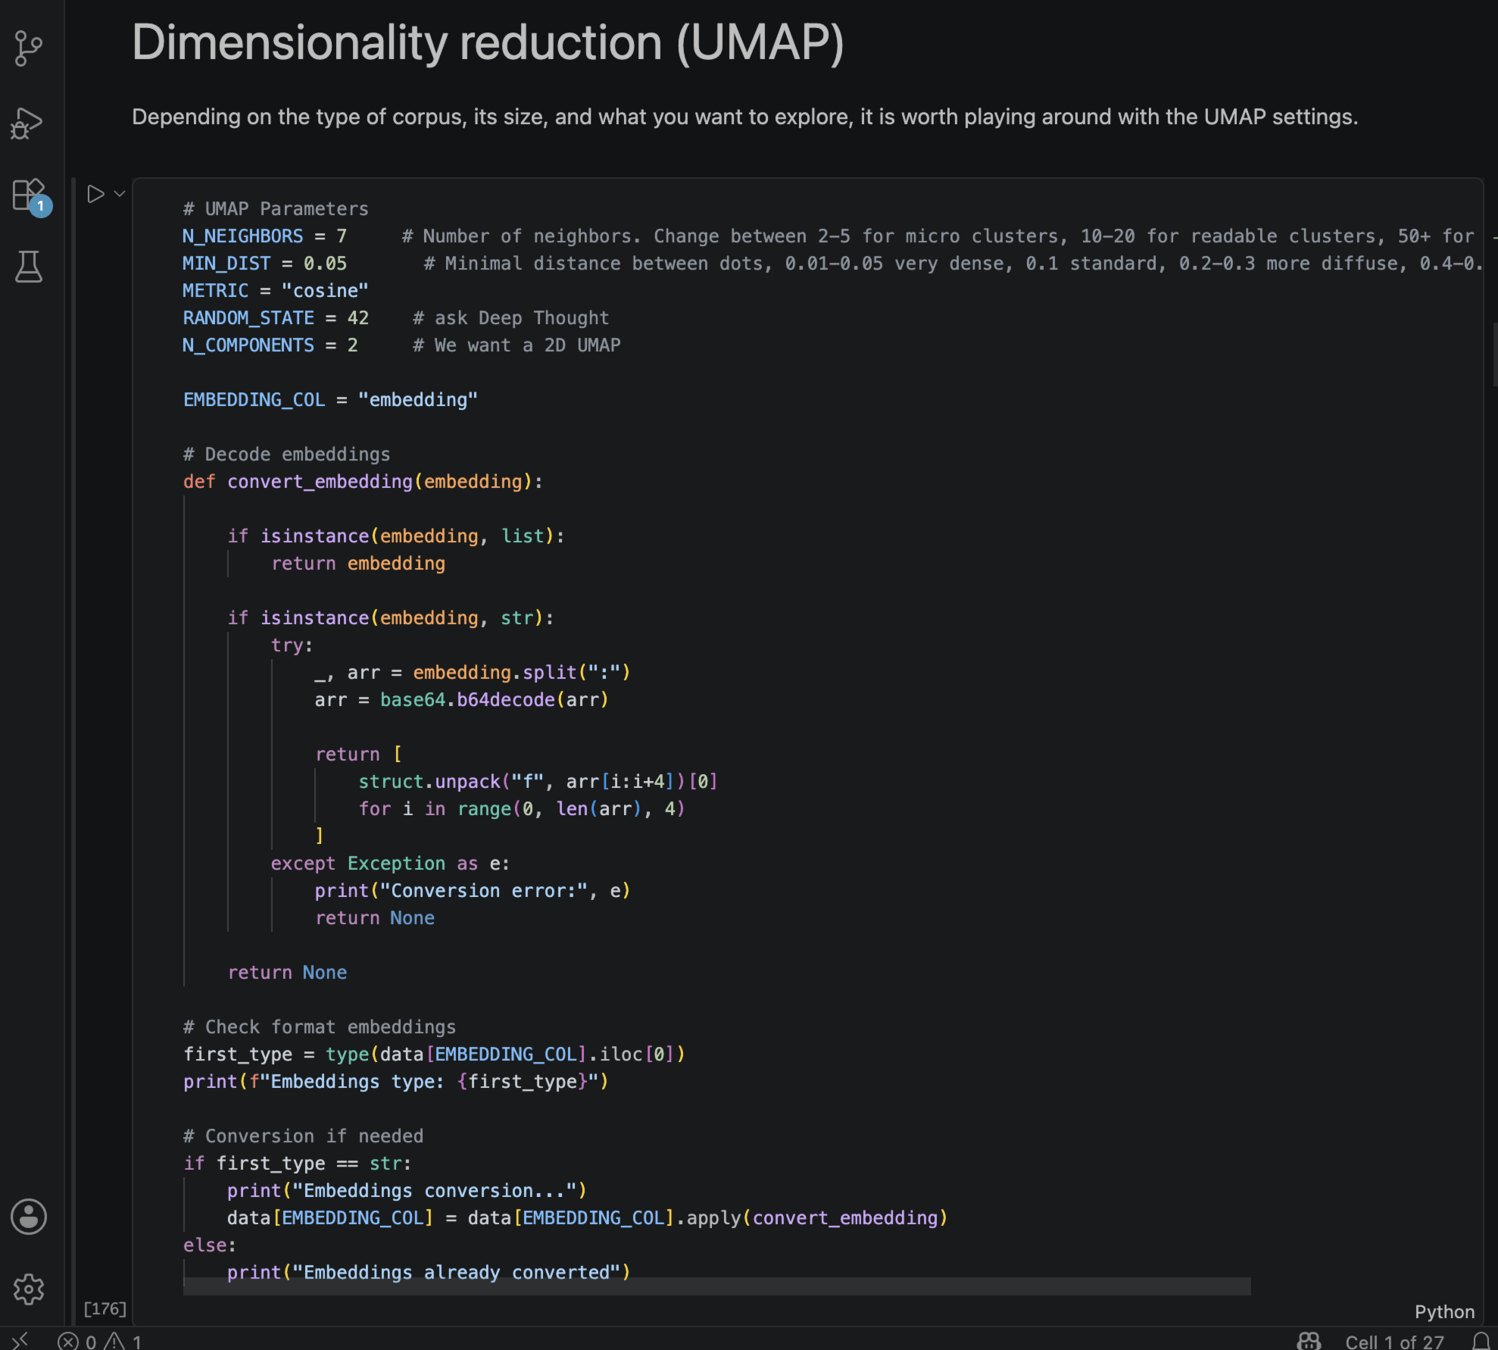
Let's analyze our collection about "radio" as a UMAP
This notebook, which is not yet available on the Datalab, retrieves the embeddings already calculated by Impresso or calculates them again if they are not provided by the API.
We've tweaked the collection's filters slightly to include advertisements and short articles that aren't on the front page, which results in a larger and more diverse corpus. This corpus of 4,000 articles is processed in about 20 minutes.
The semantic space of a specific collection
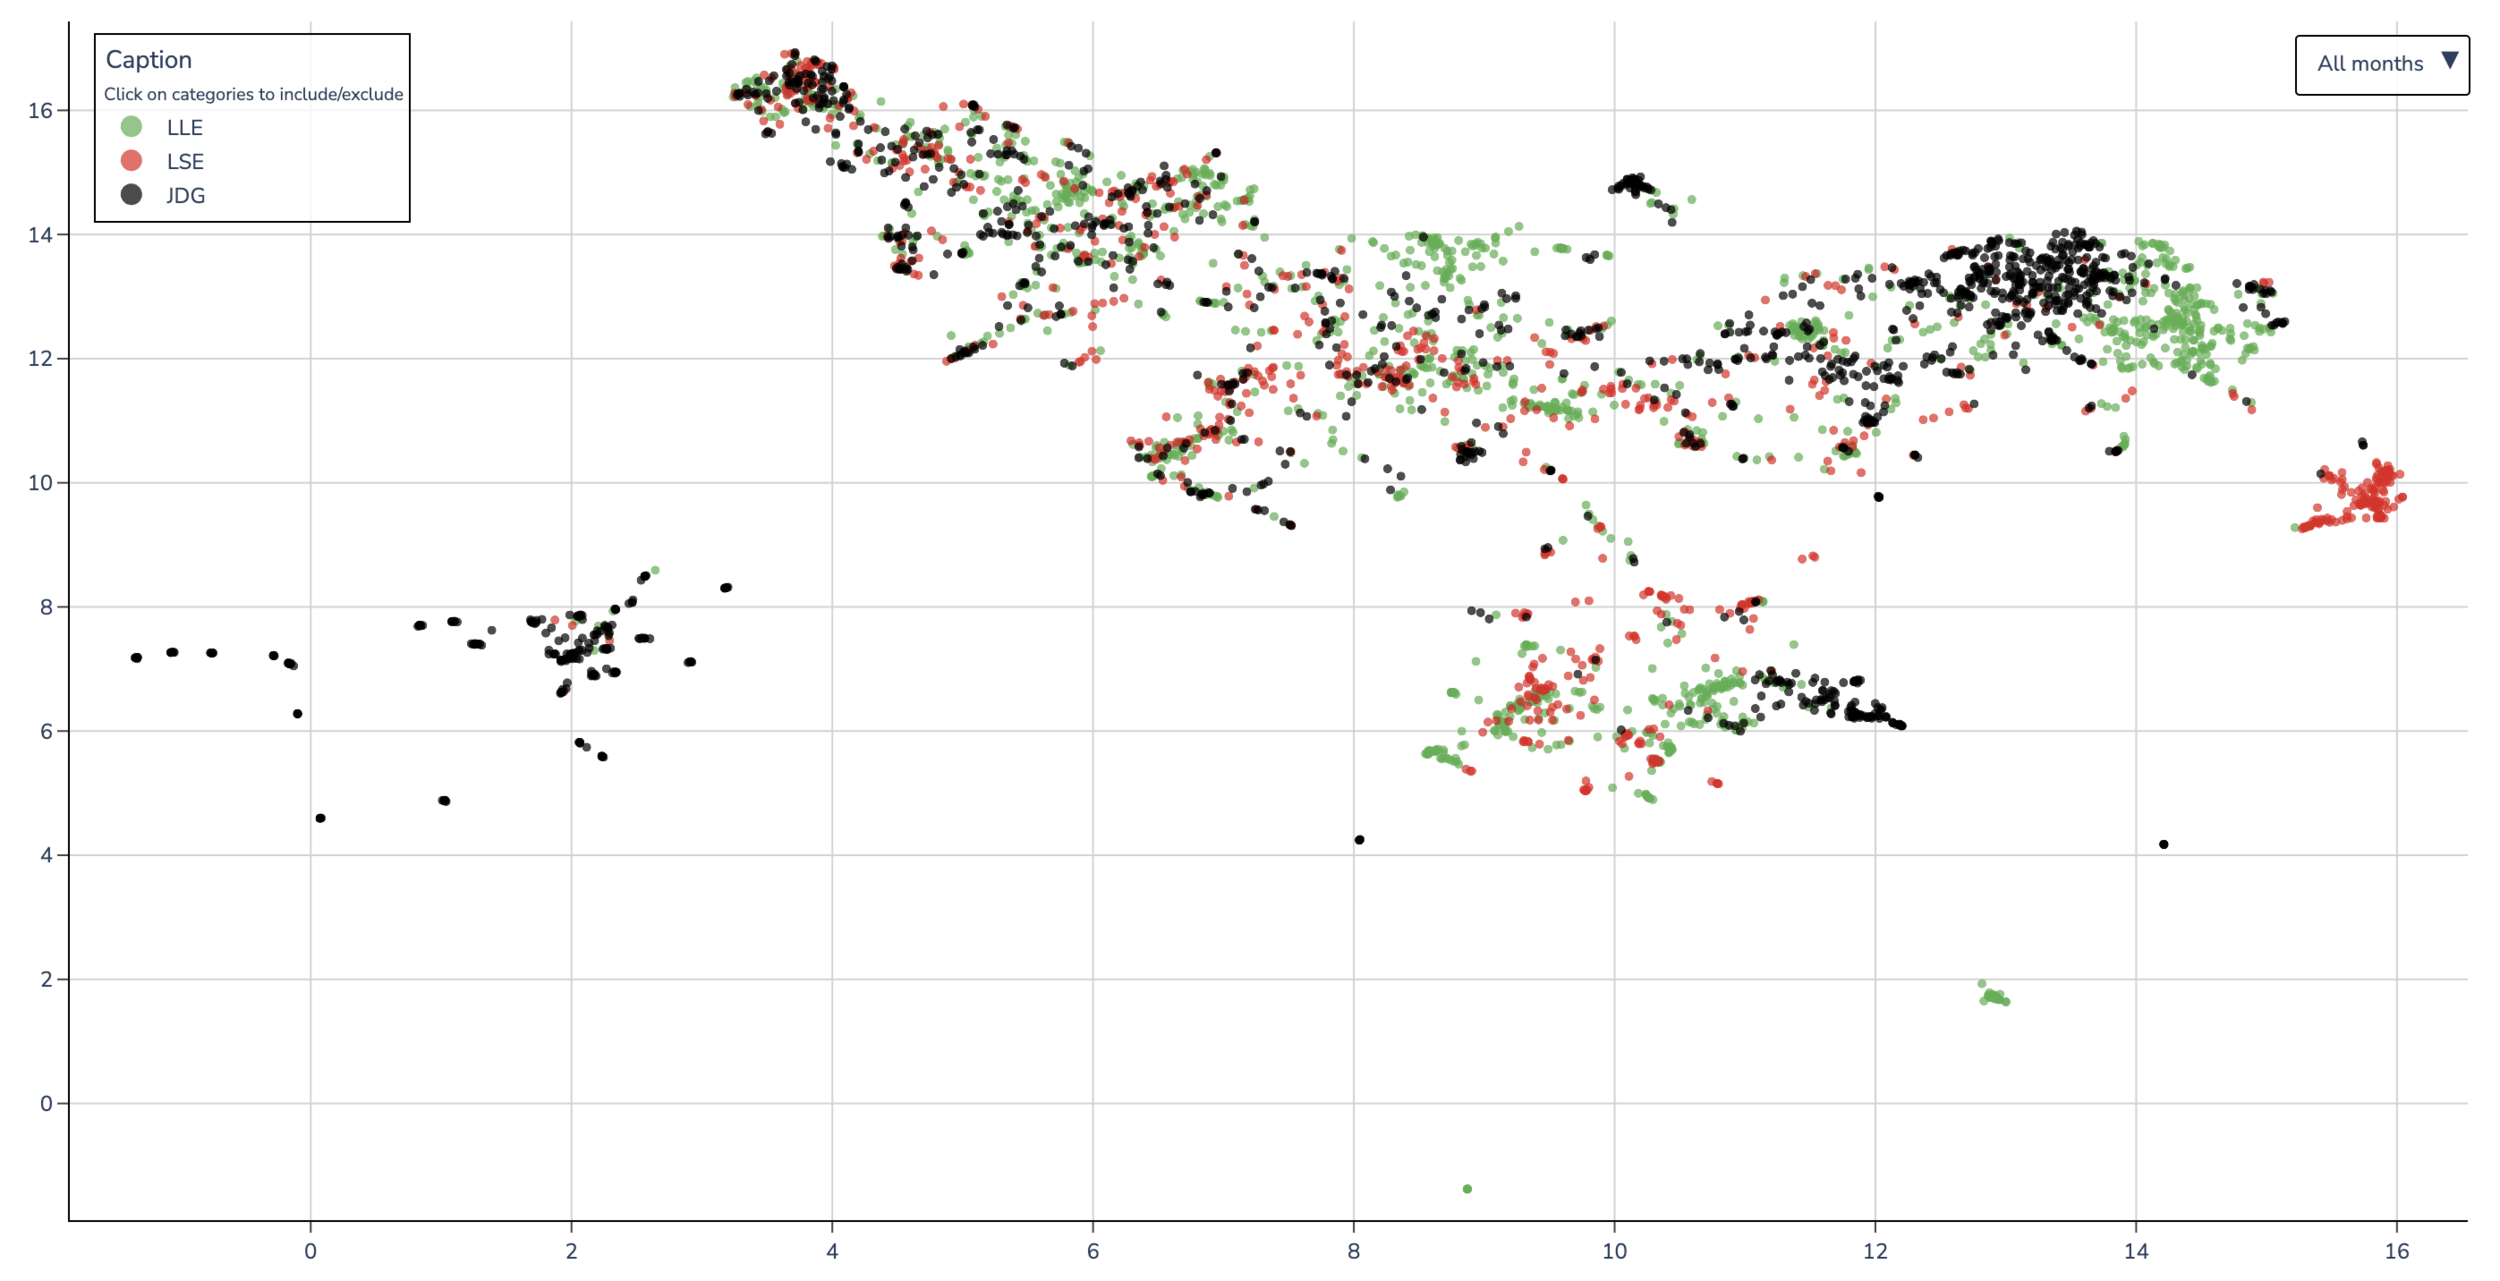
La Liberté (Catholic, Fribourg)
Journal de Genève (Liberal conservative, Geneva)
La Sentinelle (Socialist, La Chaux-de-Fonds)
A map for exploring a corpus of press articles about radio
Each dot represents an article from 1950 that contains the keyword “radio” in the three selected newspapers.
This UMAP “map” is a simplification of the semantic distance between all these articles; it makes significant compromises to ensure it is readable in 2D.
This doesn't mean that if two articles are close to each other, they are the most similar; it means that they probably belong to the same semantic register (that they are about the same thing). That's why we'll focus mainly on the groups rather than on individual situations.
The semantic space of a specific collection
La Liberté (Catholic, Fribourg)
Journal de Genève (Liberal conservative, Geneva)
La Sentinelle (Socialist, La Chaux-de-Fonds)
What can we see on this map?
Stock market and financial news
(Radio corporation of America stocks)
International news
Religious news
"Faits divers"
(accidents, crimes, unexpected)
National/local news
Foreclosure auctions
(A radio device is included among the items sold)
Radio programs
(Each newspaper has a different style)
Religious calendar
Culture
(music, cinema, theatre)
Radio critique
Advertisement
In fact, this seems like a very good way to broadly categorize the "poor" or "rich" uses of the term radio in our corpus (as we saw more qualitatively in the previous chapter).
The semantic space of a specific collection
La Liberté (Catholic, Fribourg)
Journal de Genève (Liberal conservative, Geneva)
La Sentinelle (Socialist, La Chaux-de-Fonds)
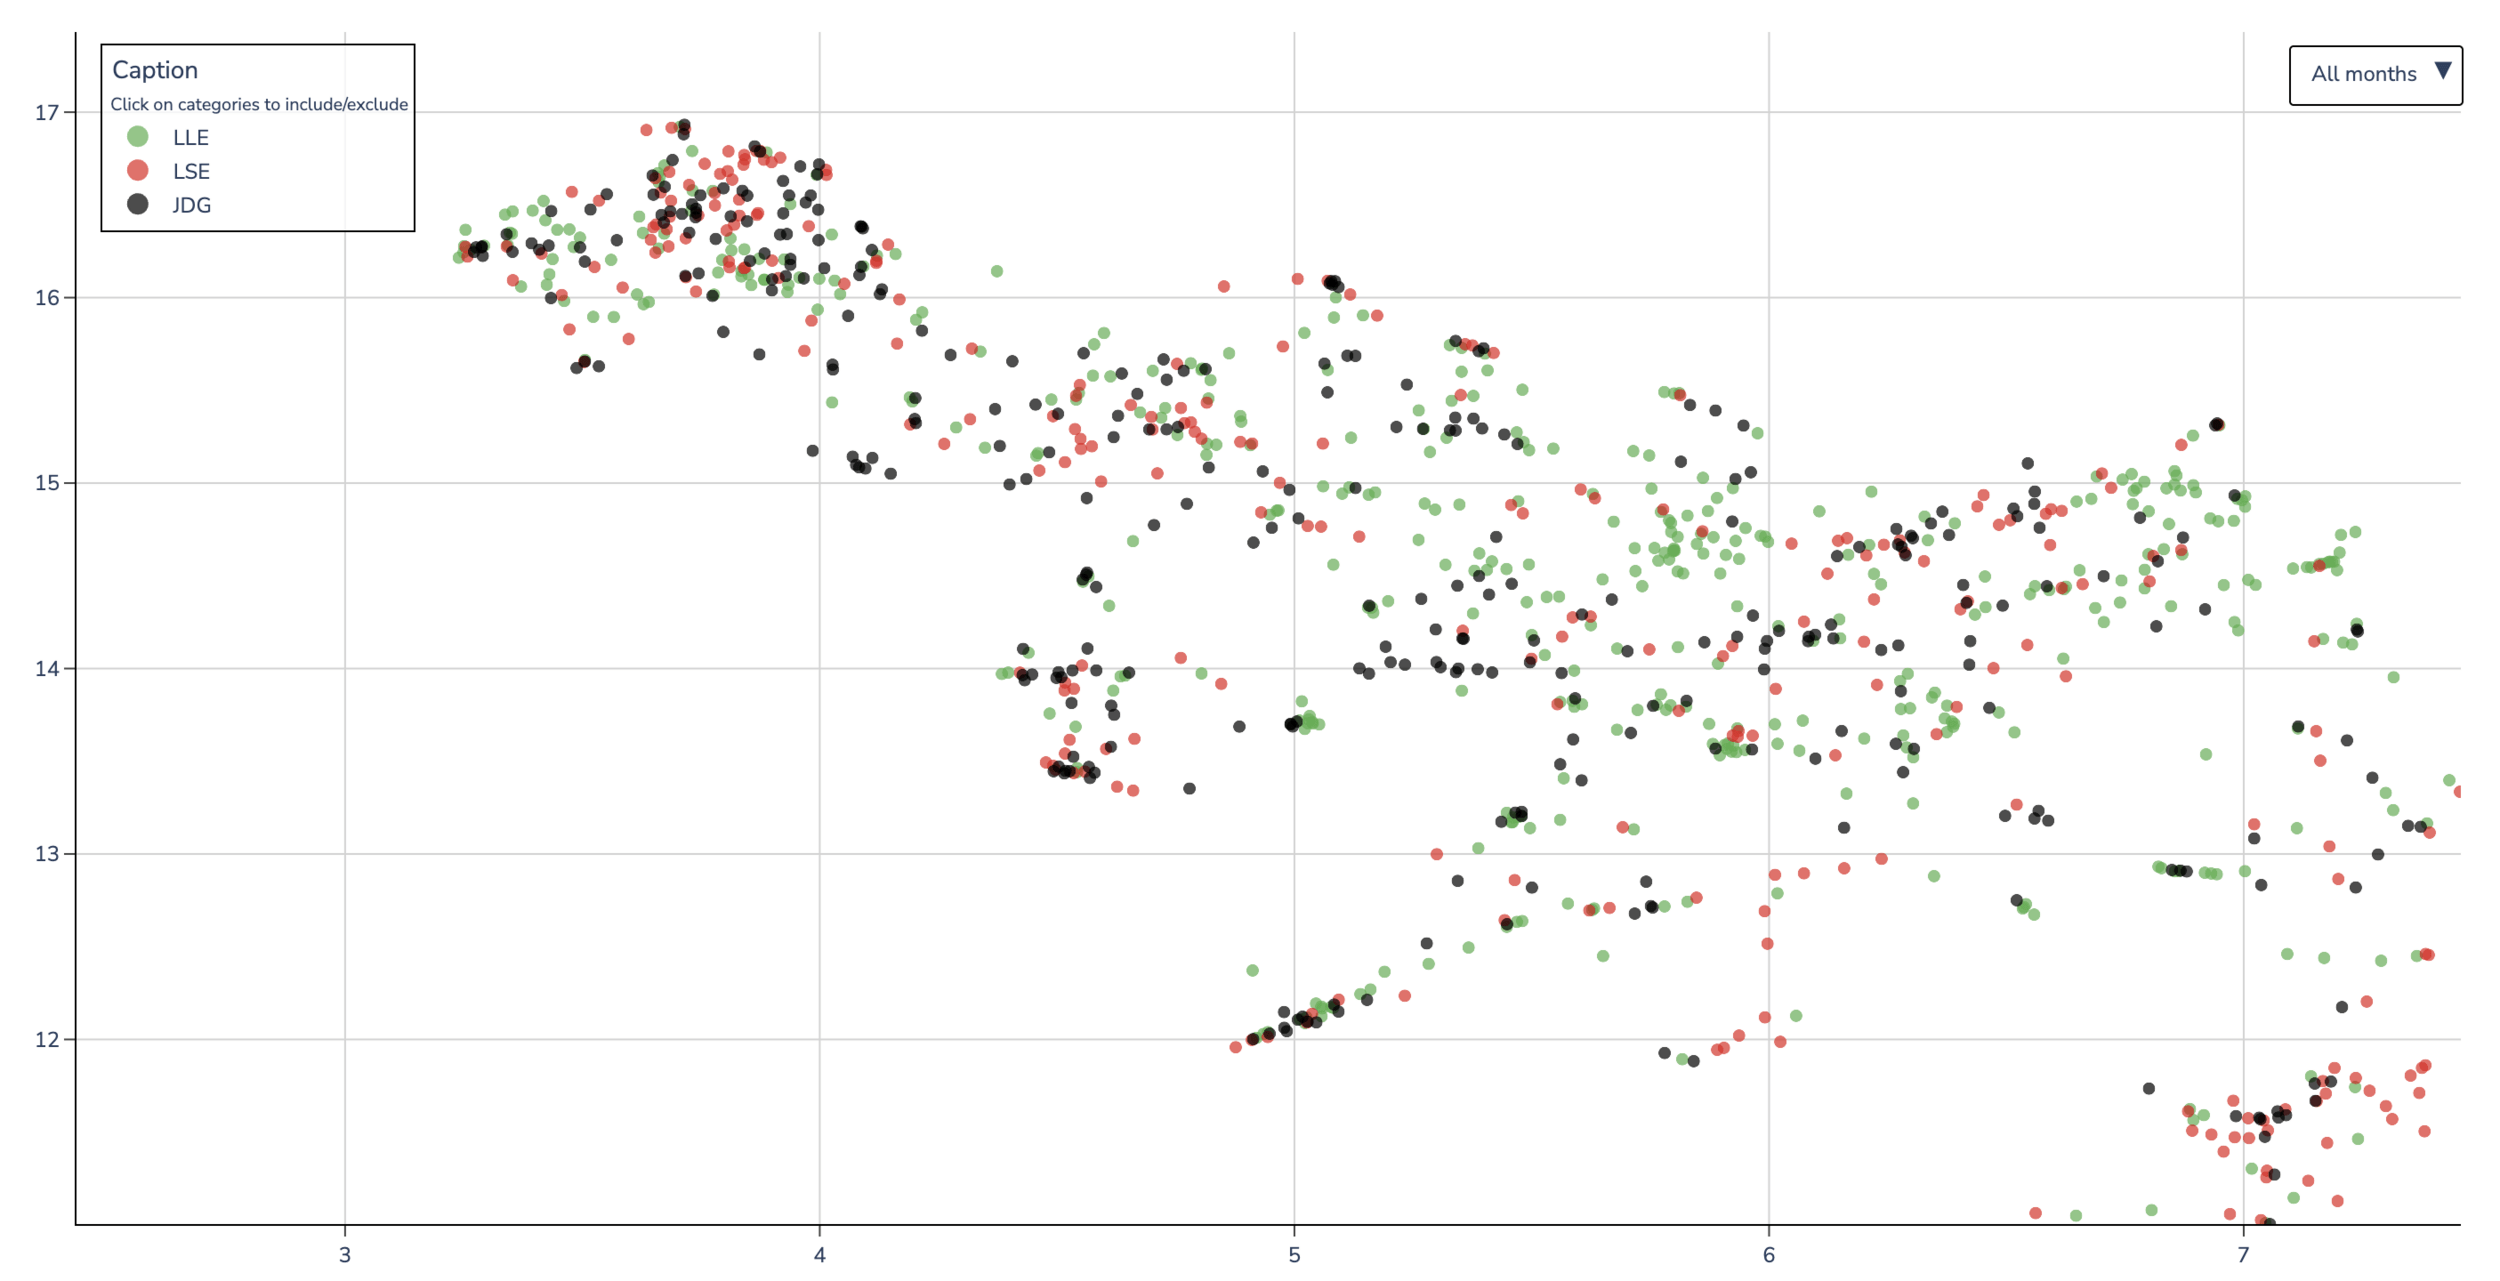
Focus on international news: Why is radio mentioned?
Korean war
(North Korean and Russian radios as sources)
United Kingdom
(In many cases, the government addressing the public via radio)
Belgium
(King Leopold III is facing criticism and addresses the nation on the radio)
Sweden
(The death of King Gustav V announced on Swedish radio)
Miscellaneous news
(Articles that contain a series of short news stories from around the world. Radio is often a source)
Various European news
Various Asian news
(China, Tibet, Indochina)
Since all the articles contain the word “radio,” this does not accurately reflect media coverage in 1950; it skews the results in favor of regions where news reaches Swiss newspapers via official (often communist) radio stations.
Comparing two collections
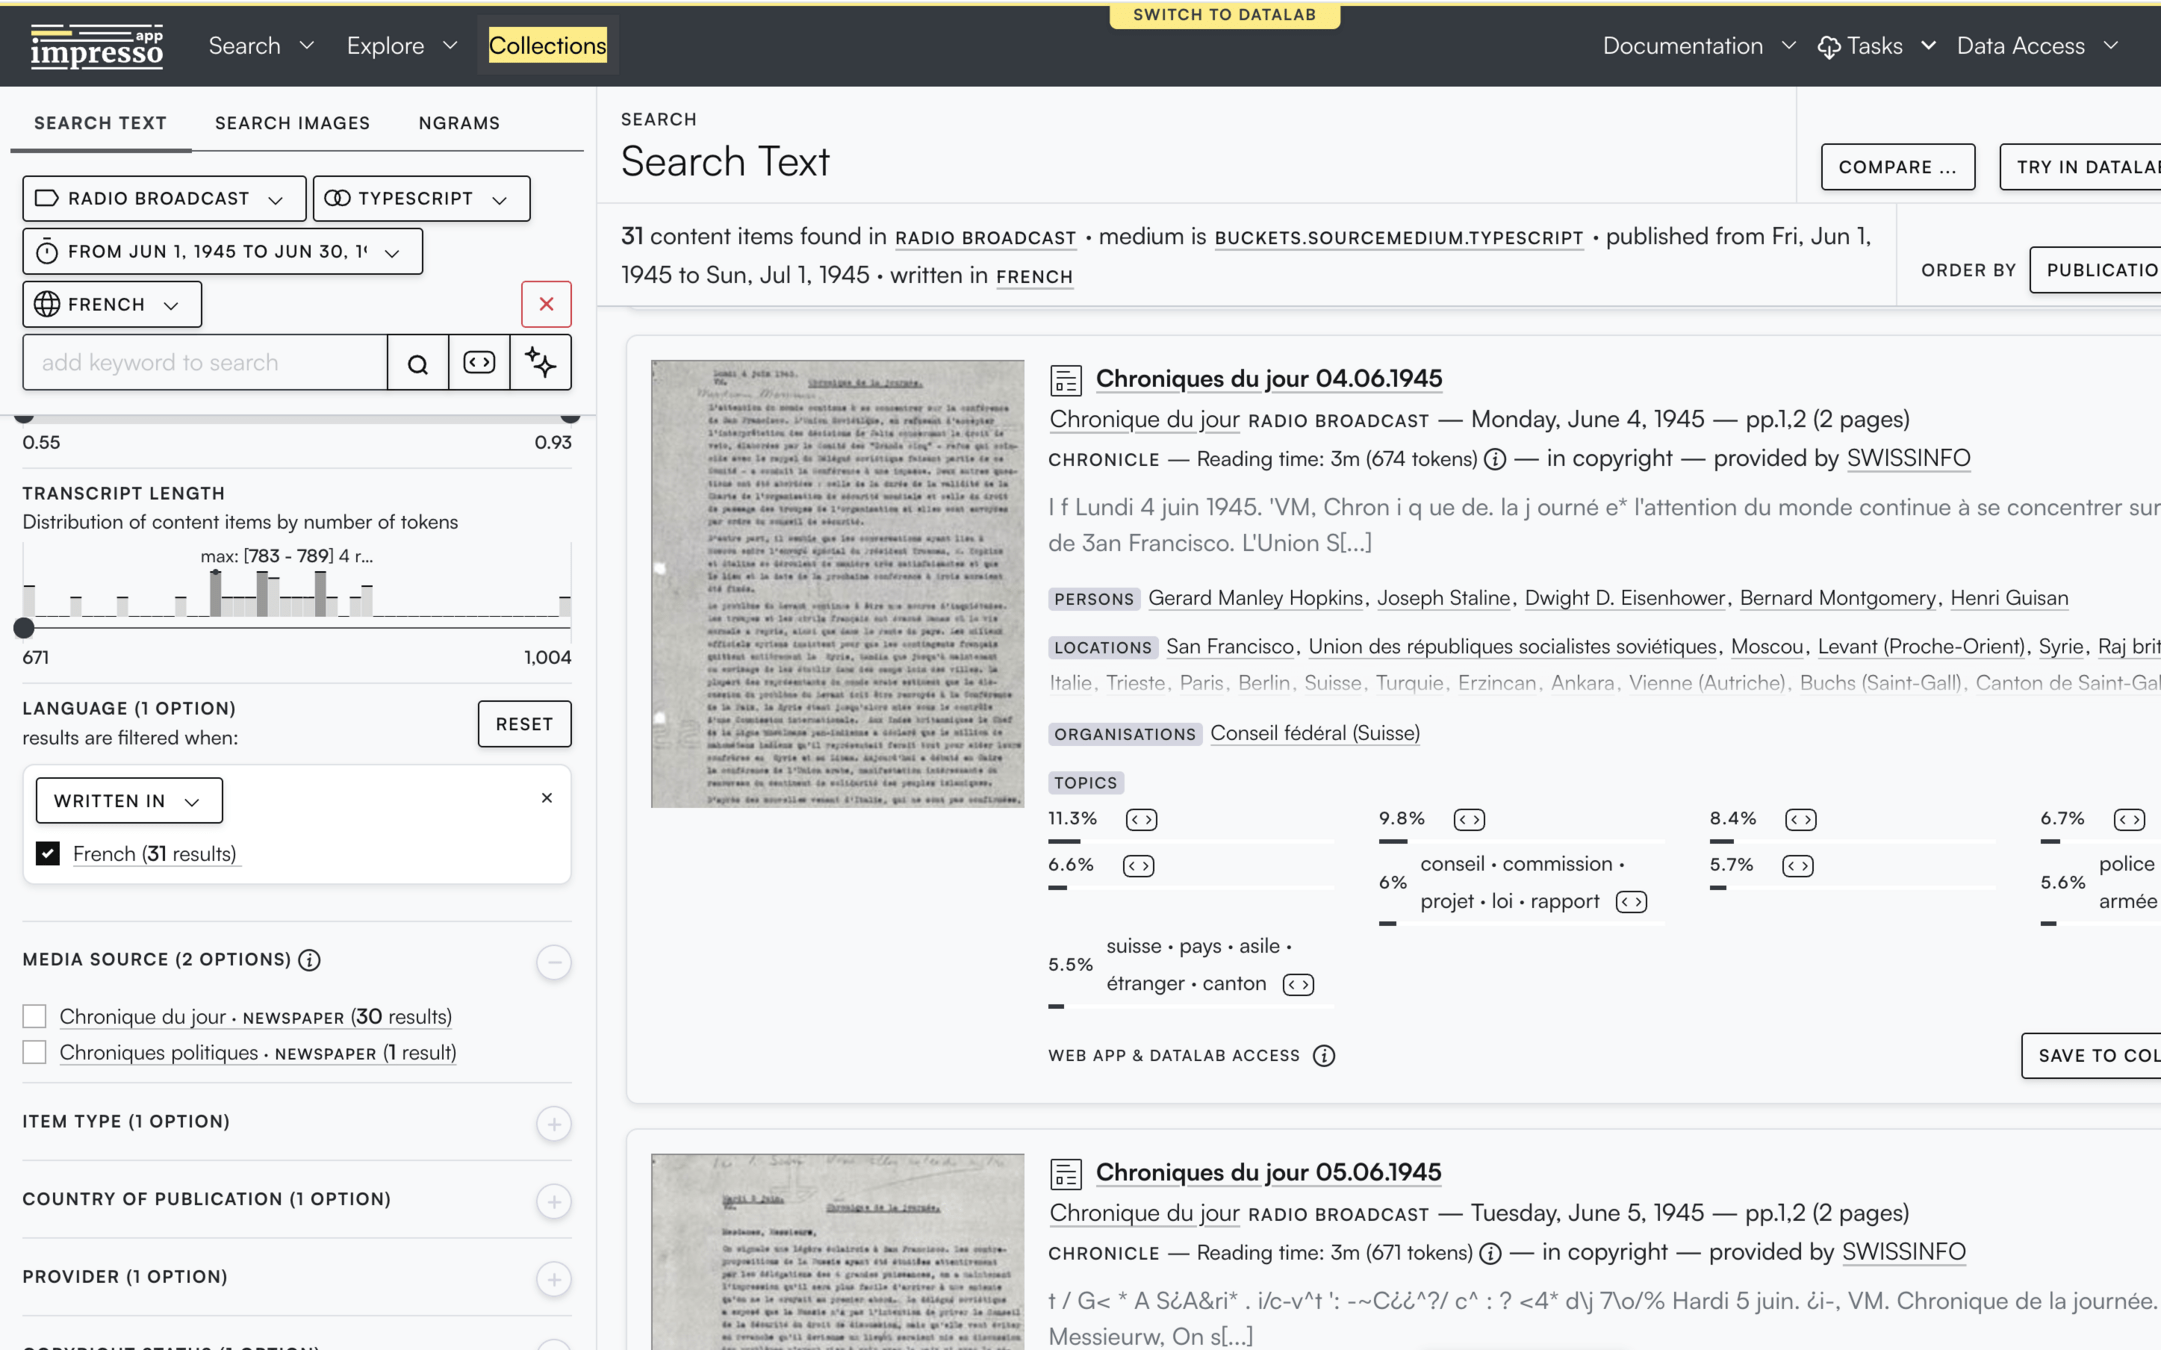
Now, we want to use embeddings to compare two collections.
For example, to study how radio news programs select information compared to the print media.
Here, we have selected a week's worth of news bulletins from Radio Suisse Internationale in June 1945.
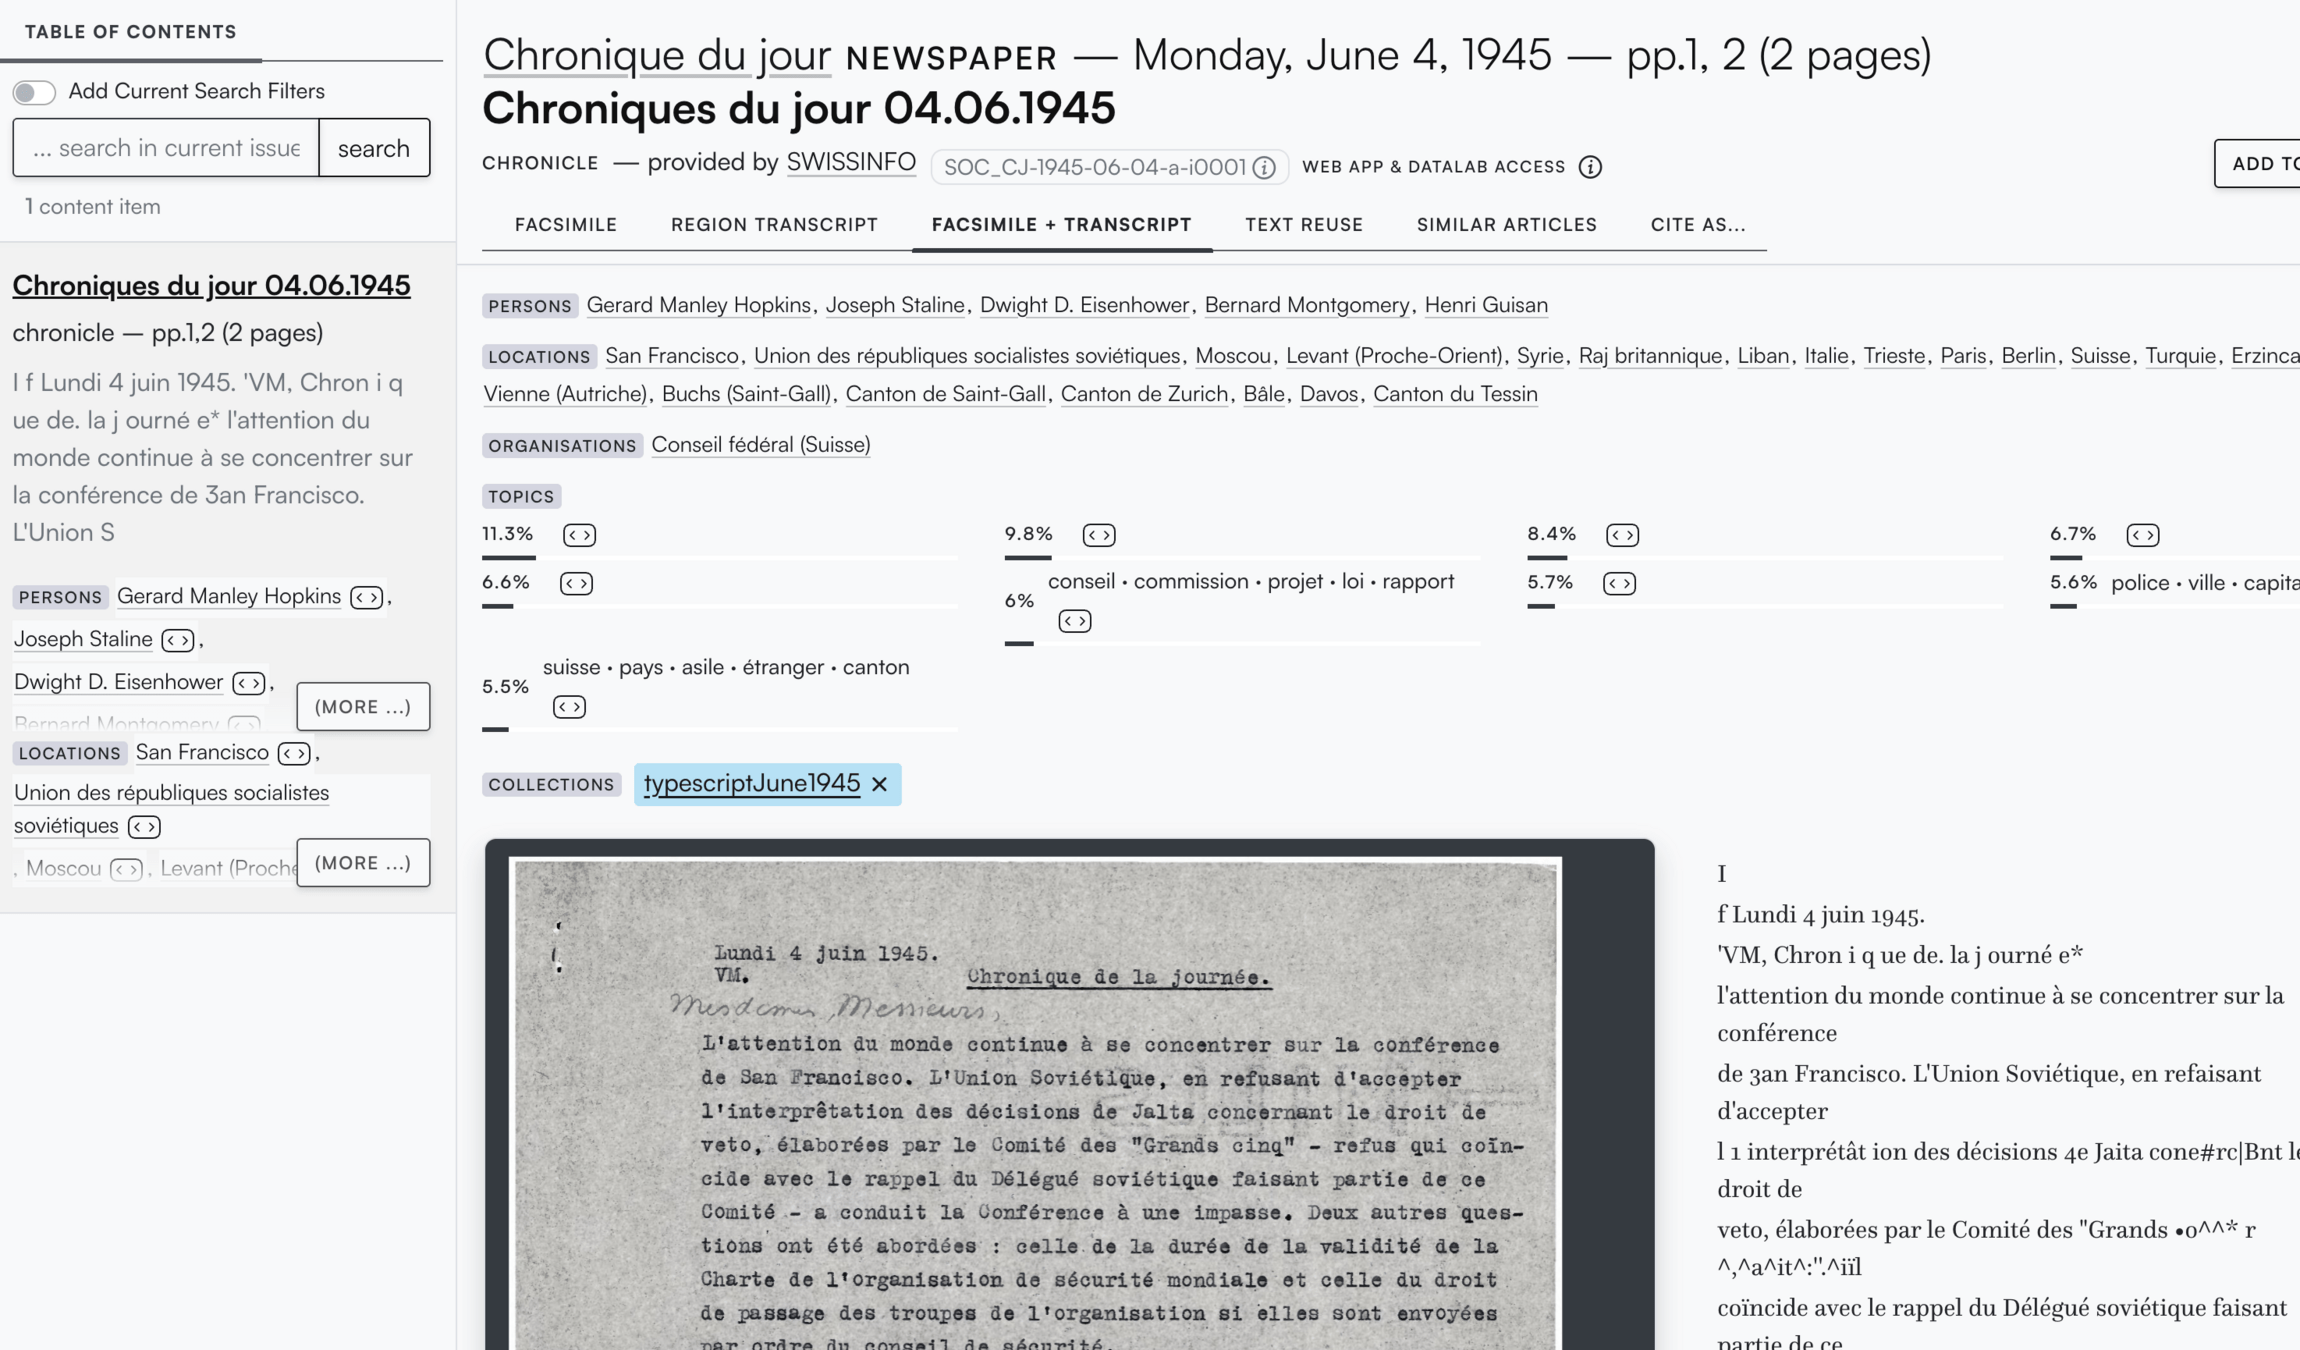
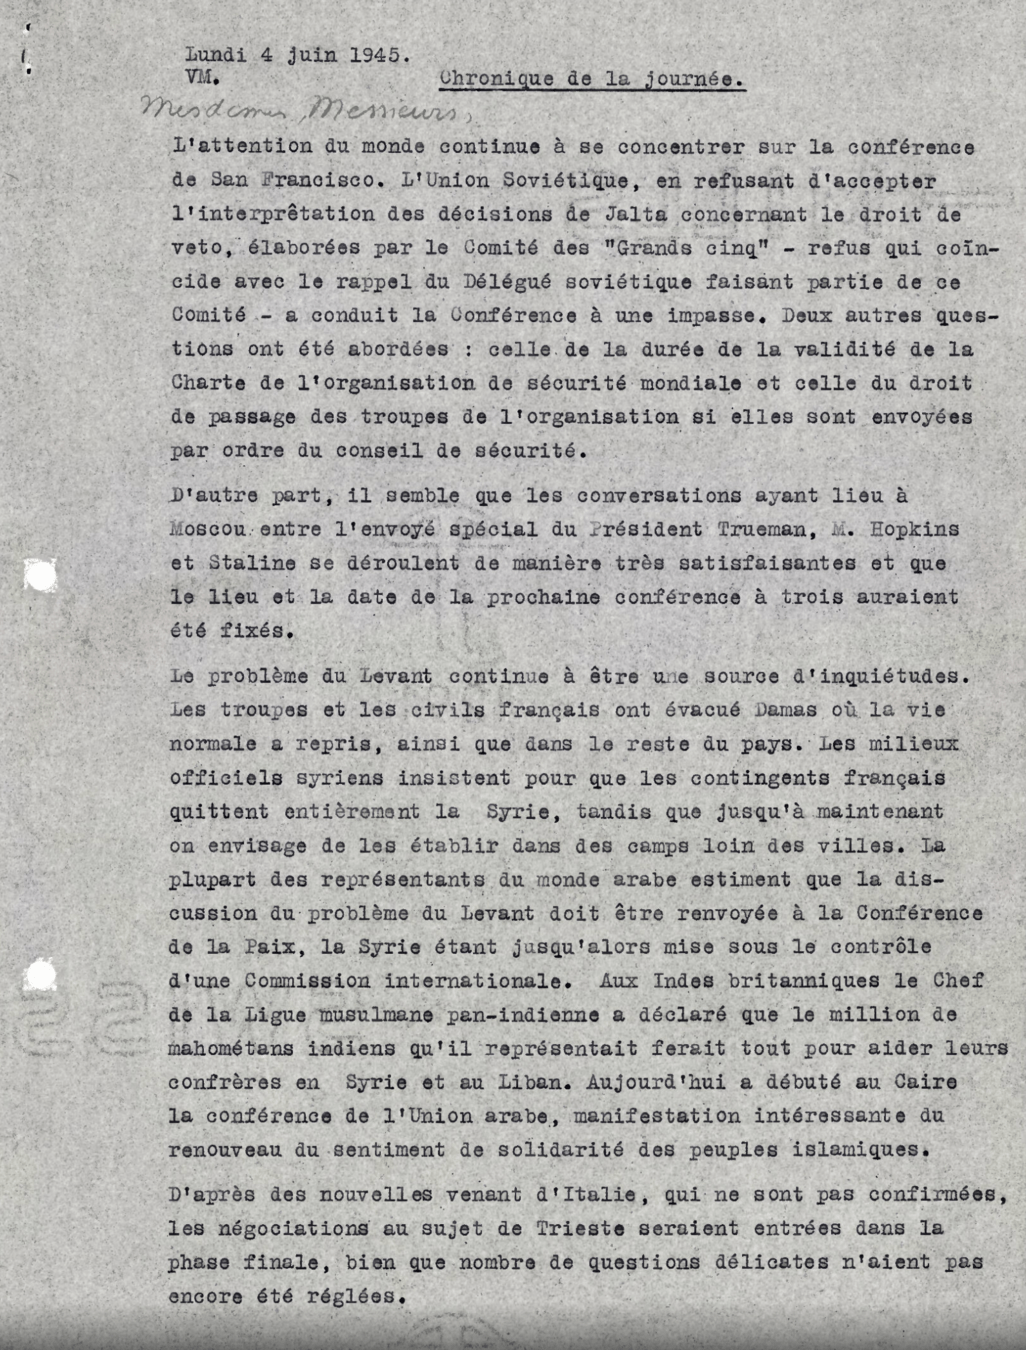
To make them comparable to news articles, these bulletins must first be broken down into segments of information.
This is the text that was read on the air. There’s one every day in French, German, English, and sometimes Spanish.
Comparing two collections
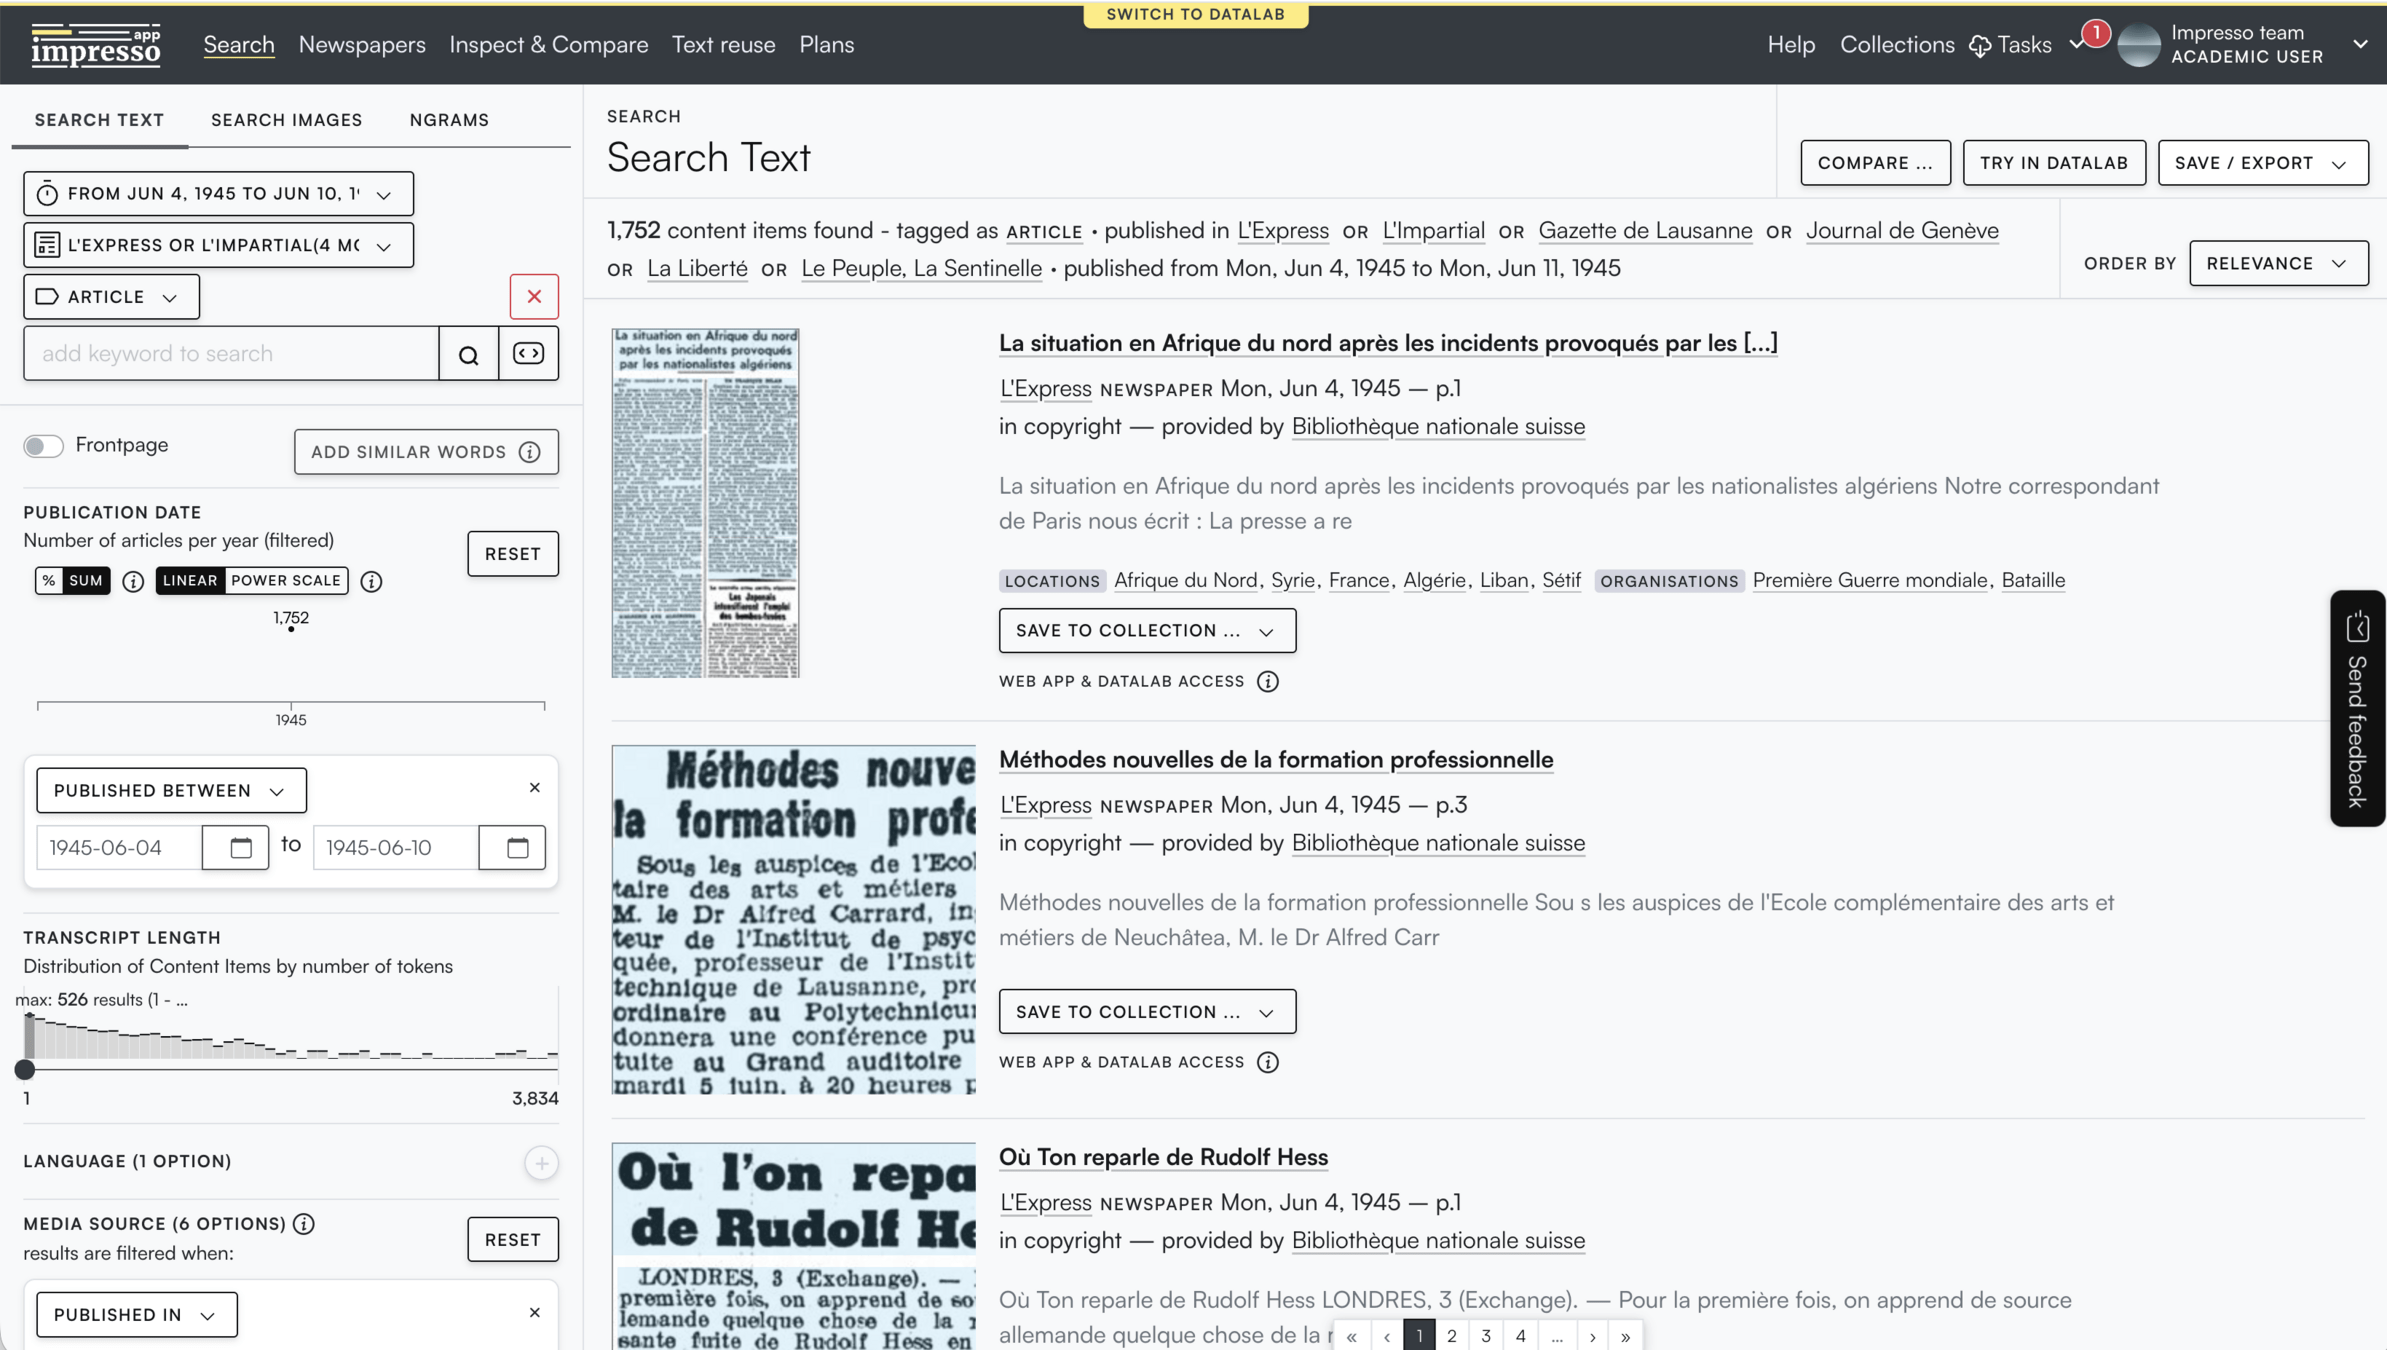
One of the major news stories this week is the diplomatic progress made at the San Francisco conference among the “Big Five” (establishment of the future UN).
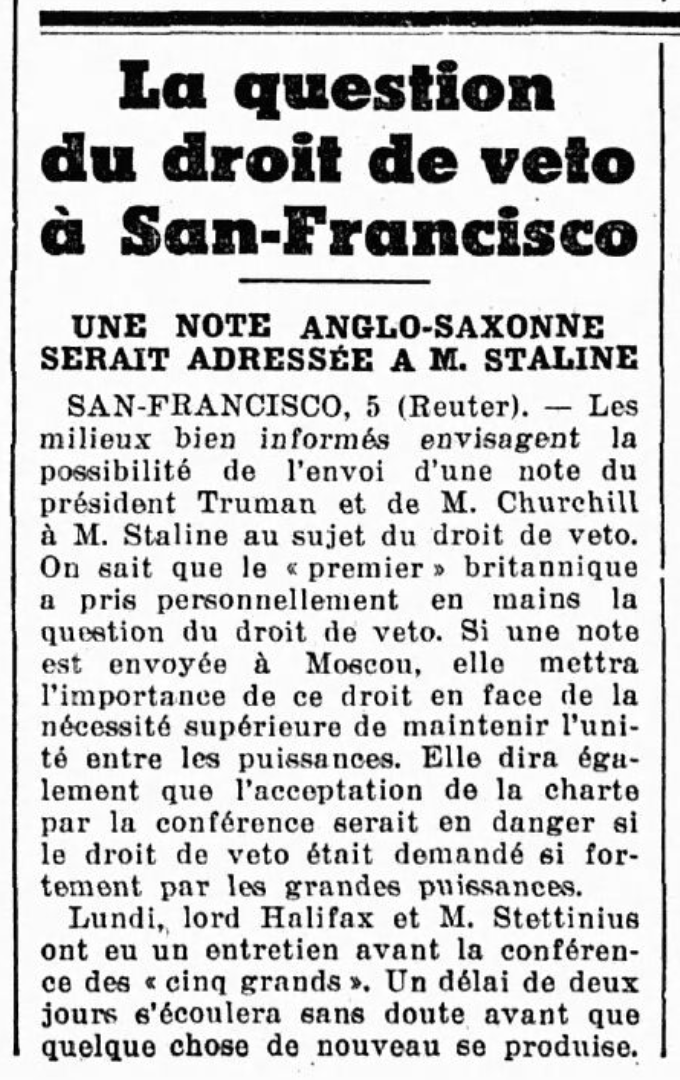
45 radio news
1674 press articles
Let's compare the news coverage in the press and on the radio for the week of June 4–10, 1945
All the articles (no ads) from the Journal de Genève, Gazette de Lausanne, La Sentinelle, Feuille d'Avis de Neuchâtel, L'Impartial and La Liberté.
Comparing two collections
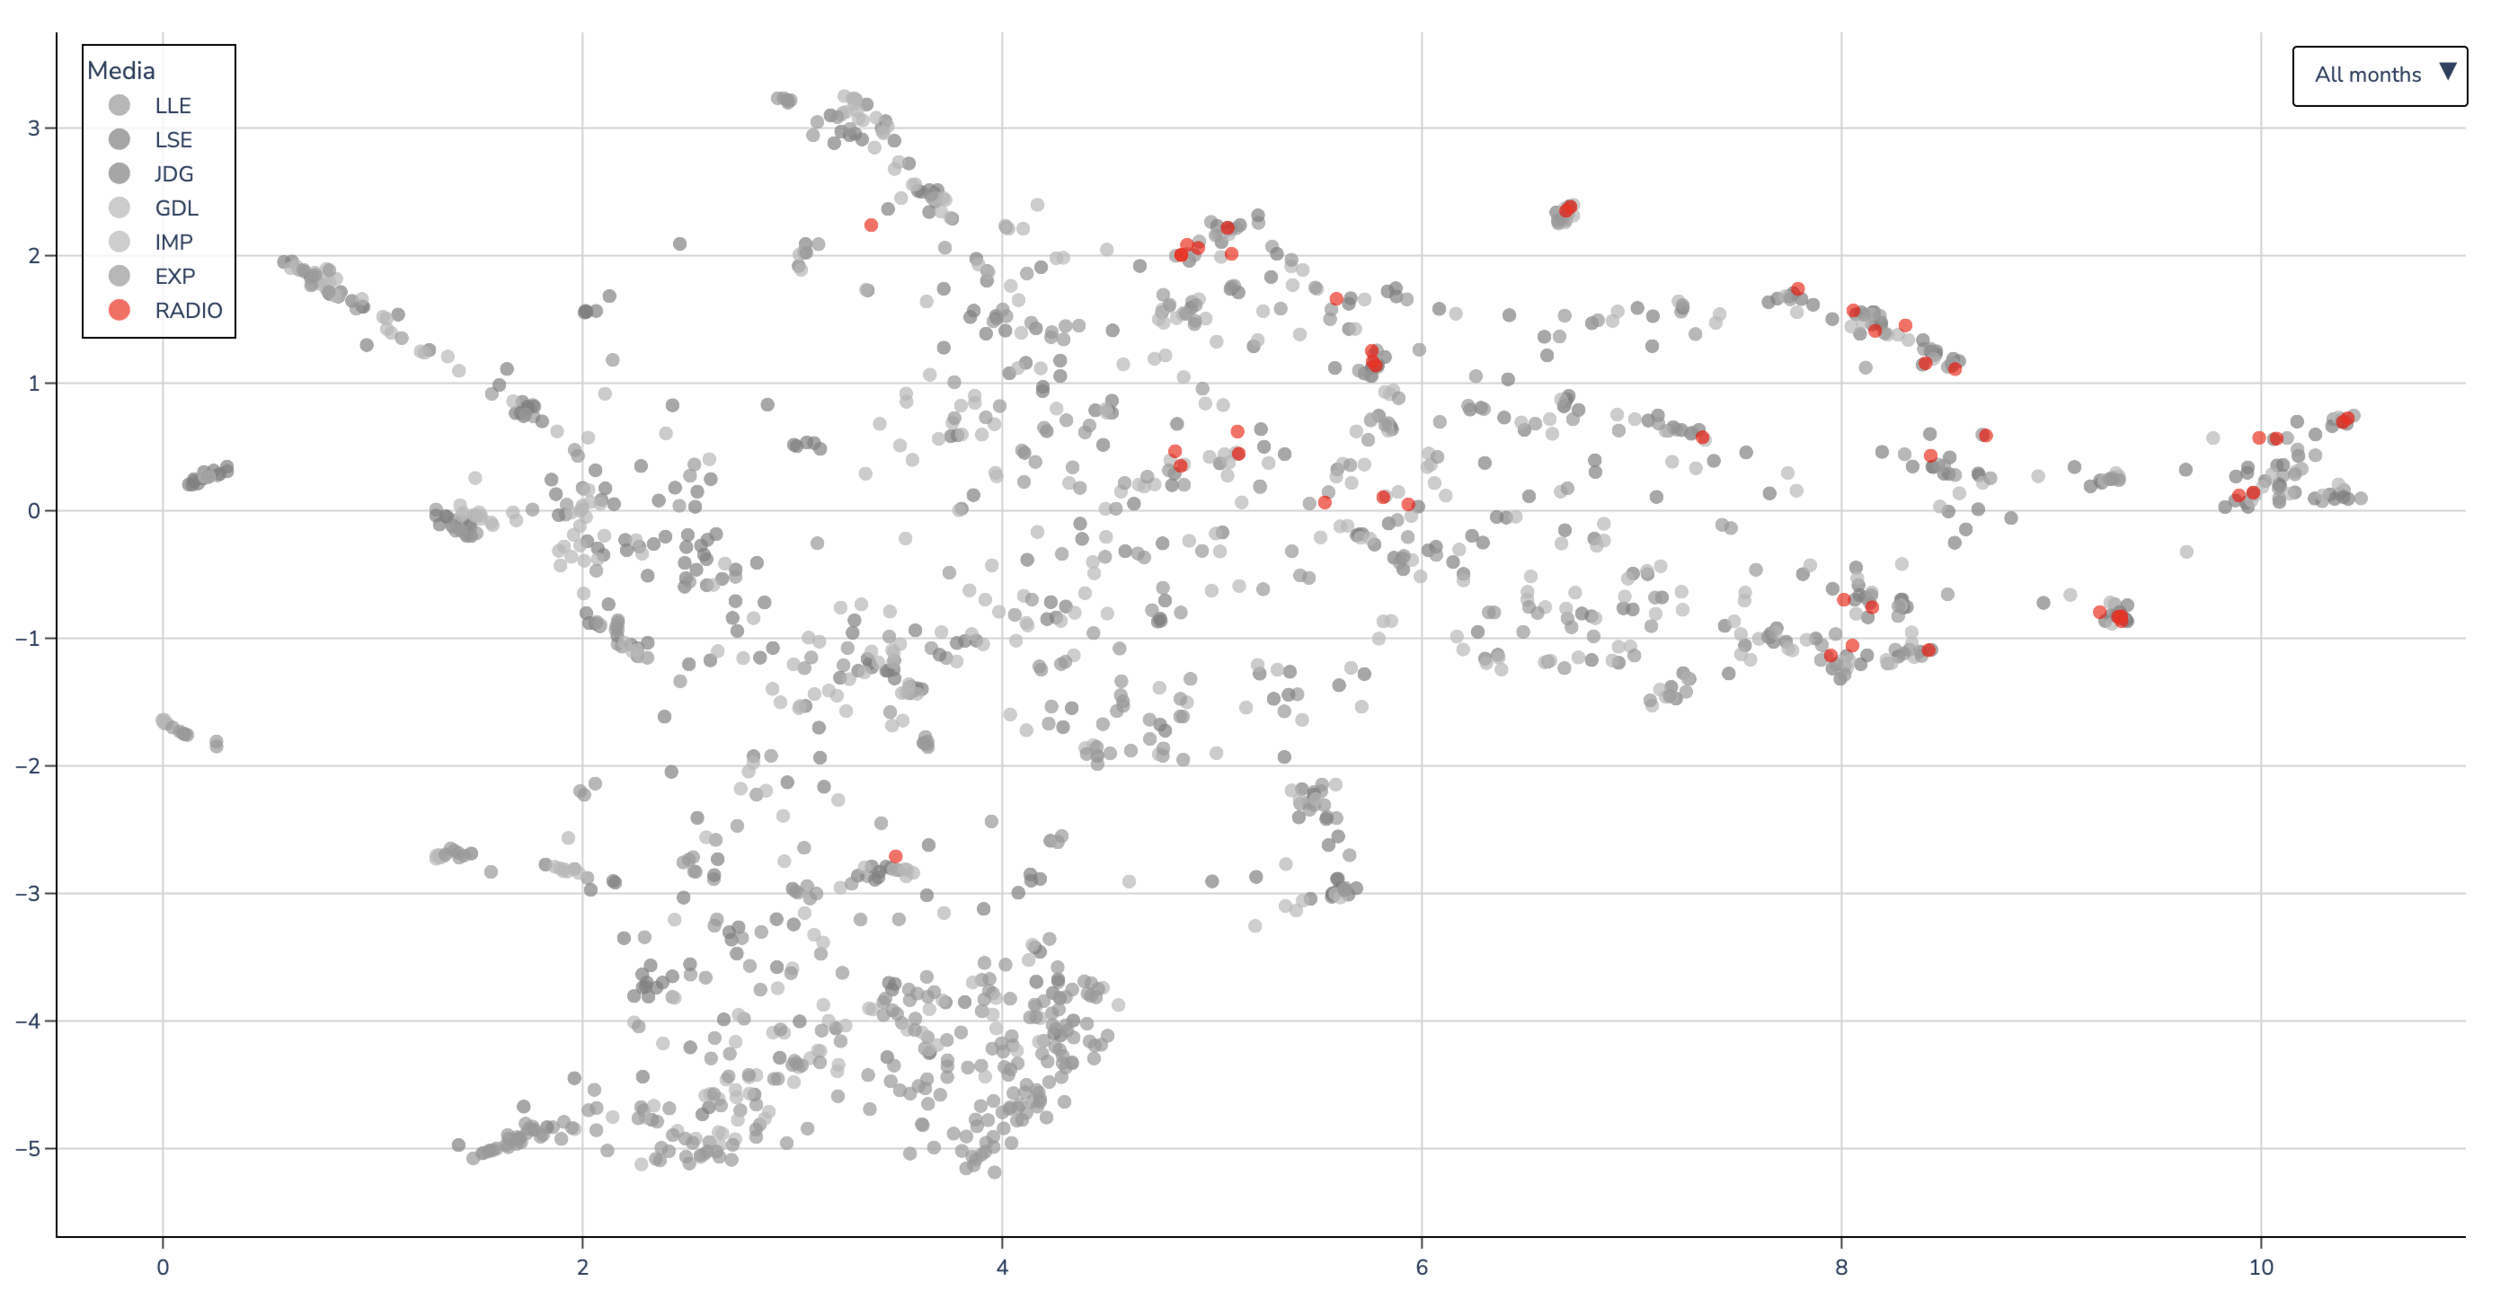
News coverage in the press and on the radio
June 4–10, 1945
Press articles
Radio broadcast segment
Area of the semantic map that is not covered by the radio bulletins
Comparing two collections
What is the order of priority in Radio Suisse Internationale's news bulletins?
June 4–10, 1945
Press articles
Radio broadcast segment
Crisis in the Levant
Syria, Lebanon, France
War in the Pacific
Invasion of Okinawa
Germany
Administrating liberated Berlin
The 'Big Five'
San Francisco conference
Tito in Trieste
Bonomi resignation
Italy
Expulsions of nazis
Release of prisonners
Humanitarian issues
Swiss parliament
Resignation of General Guisan
Economic news
INTERNATIONAL
SWITZERLAND
Obituaries
"Faits divers"
Radio programs
Culture
Sports
Swiss international relations
Classified ads
Commercial ads