Attention is all you need
Transformers: Attention is all you need

*RNN seq2seq models
I
enjoyed
the
movie
transformers
Naan
transfarmar
padaththai
rasiththen
Naan
transfarmar
padaththai
Transition to Transformers
Encoder
Decoder
Naan
transfarmar
padaththai
rasiththen
Naan
transfarmar
padaththai
Transition to Transformers
Encoder
Decoder
With Attention
I
enjoyed
the
movie
transformers
Naan
transfarmar
padaththai
rasiththen
Transition to Transformers
Encoder
Decoder
Feed Forward Networks
Self-Attention
Self-Attention
Encoder-Decoder Attention
Feed Forward Networks
We will see each of these components (and a few more) one at a time in detail and connect them together to synthesize the final architecture
Word Embedding
I
enjoyed
the
movie
transformers
Self-Attention
Encoder
Self-Attention
Note that the inputs are vectors (word embeddings) and the outputs are also vectors
| 1 | 0 | 0 |
|---|
| 0 | 1 | 0 |
|---|
| 1 | 1 | 0 |
|---|
| 1 | 0 | 1 |
|---|
| 1 | 1 | 1 |
|---|
You can think of these word embeddings as \(h_i\) in RNN encoder (if you wish to compare)
It is important to establish a strong connection between the word "it" to the word "trophy" or "suitcase" based on the context.
It is called self-attention as it identify the attention within the context. It is different from cross-attention which we will see later.
The goal
Given a word in a sentence, we want to compute the relational score between the word and the rest of the words in the sentence.
| The | animal | didn't | cross | the | street | bacause | it | |
|---|---|---|---|---|---|---|---|---|
| The | ||||||||
| animal | ||||||||
| didn't | ||||||||
| cross | ||||||||
| the | ||||||||
| street | ||||||||
| because | ||||||||
| it |
The goal
Given a word in a sentence, we want to compute the relational score between the word and the rest of the words in the sentence....
| The | animal | didn't | cross | the | street | bacause | it | |
|---|---|---|---|---|---|---|---|---|
| The | 0.6 | 0.1 | 0.05 | 0.05 | 0.02 | 0.02 | 0.02 | 0.1 |
| animal | 0.02 | 0.5 | 0.06 | 0.15 | 0.02 | 0.05 | 0.01 | 0.12 |
| didn't | 0.01 | 0.35 | 0.45 | 0.1 | 0.01 | 0.02 | 0.01 | 0.03 |
| cross | . | |||||||
| the | . | |||||||
| street | . | |||||||
| because | . | |||||||
| it | 0.01 | 0.6 | 0.02 | 0.1 | 0.01 | 0.2 | 0.01 | 0.01 |
...such that the score is higher if they are related contextually
The goal
| The | animal | didn't | cross | the | street | bacause | it | |
|---|---|---|---|---|---|---|---|---|
| The | 0.6 | 0.1 | 0.05 | 0.05 | 0.02 | 0.02 | 0.02 | 0.1 |
| animal | 0.02 | 0.5 | 0.06 | 0.15 | 0.02 | 0.05 | 0.01 | 0.12 |
| didn't | 0.01 | 0.35 | 0.45 | 0.1 | 0.01 | 0.02 | 0.01 | 0.03 |
| cross | . | |||||||
| the | . | |||||||
| street | . | |||||||
| because | . | |||||||
| it | 0.01 | 0.6 | 0.02 | 0.1 | 0.01 | 0.2 | 0.01 | 0.01 |
Now both the vectors \((s_i)\) and \((h_j)\), for all \(i,j\) are available for all the time (whereas in the seq2seq model, \(h_j\) for all \(j\) were available and \(s_i\) was obtained one at a time)
I
enjoyed
the
movie
transformers
Self-Attention
| 1 | 0 | 0 |
|---|
| 0 | 1 | 0 |
|---|
| 1 | 1 | 0 |
|---|
| 1 | 0 | 1 |
|---|
| 1 | 1 | 1 |
|---|
Let's focus on first calculating the first output from self-attention layer
I
transformers
Self-Attention
| 1 | 0 | 0 |
|---|
| 1 | 1 | 1 |
|---|
| 0.3 | 0.2 |
|---|
| 0.1 | 0.5 |
|---|
| -0.1 | 0.25 |
|---|
| 0.11 | 0.89 |
|---|
| 0 | 0.4 |
|---|
| 0.2 | 0.7 |
|---|
Fixed
variable
Score func: dot product
What about the \(z_2\)?
Let's focus on first calculating the first output from self-attention layer
I
transformers
Self-Attention
| 1 | 0 | 0 |
|---|
| 1 | 1 | 1 |
|---|
Let's focus on first calculating the first output from self-attention layer
| 0.3 | 0.2 |
|---|
| 0.1 | 0.5 |
|---|
| -0.1 | 0.25 |
|---|
| 0.11 | 0.89 |
|---|
| 0 | 0.4 |
|---|
| 0.2 | 0.7 |
|---|
Fixed
variable
Repeat the procedure for all other \(z\).
Score func: dot product
Wait, can we vectorize all these computations and compute the outputs (\(z_1,z_2,\cdots,z_T\)) in one go?
Wait, can we vectorize all these computations and compute the outputs (\(z_1,z_2,\cdots,z_T\)) in one go?
Wait, can we vectorize all these computations and compute the outputs (\(z_1,z_2,\cdots,z_T\)) in one go?
Where \(d_k\) is the dimension of key vector.
Since \(d_k\) scales the values of \(Q^TK\), it is called a scaled-dot product.
Vectorized Output
\(^*\)Note: The original paper follows \(softmax(\frac{QK^T}{\sqrt{d_k}})V\) as it represents embedding \(h_j\) as a row vector
Scaled Dot Product
Head
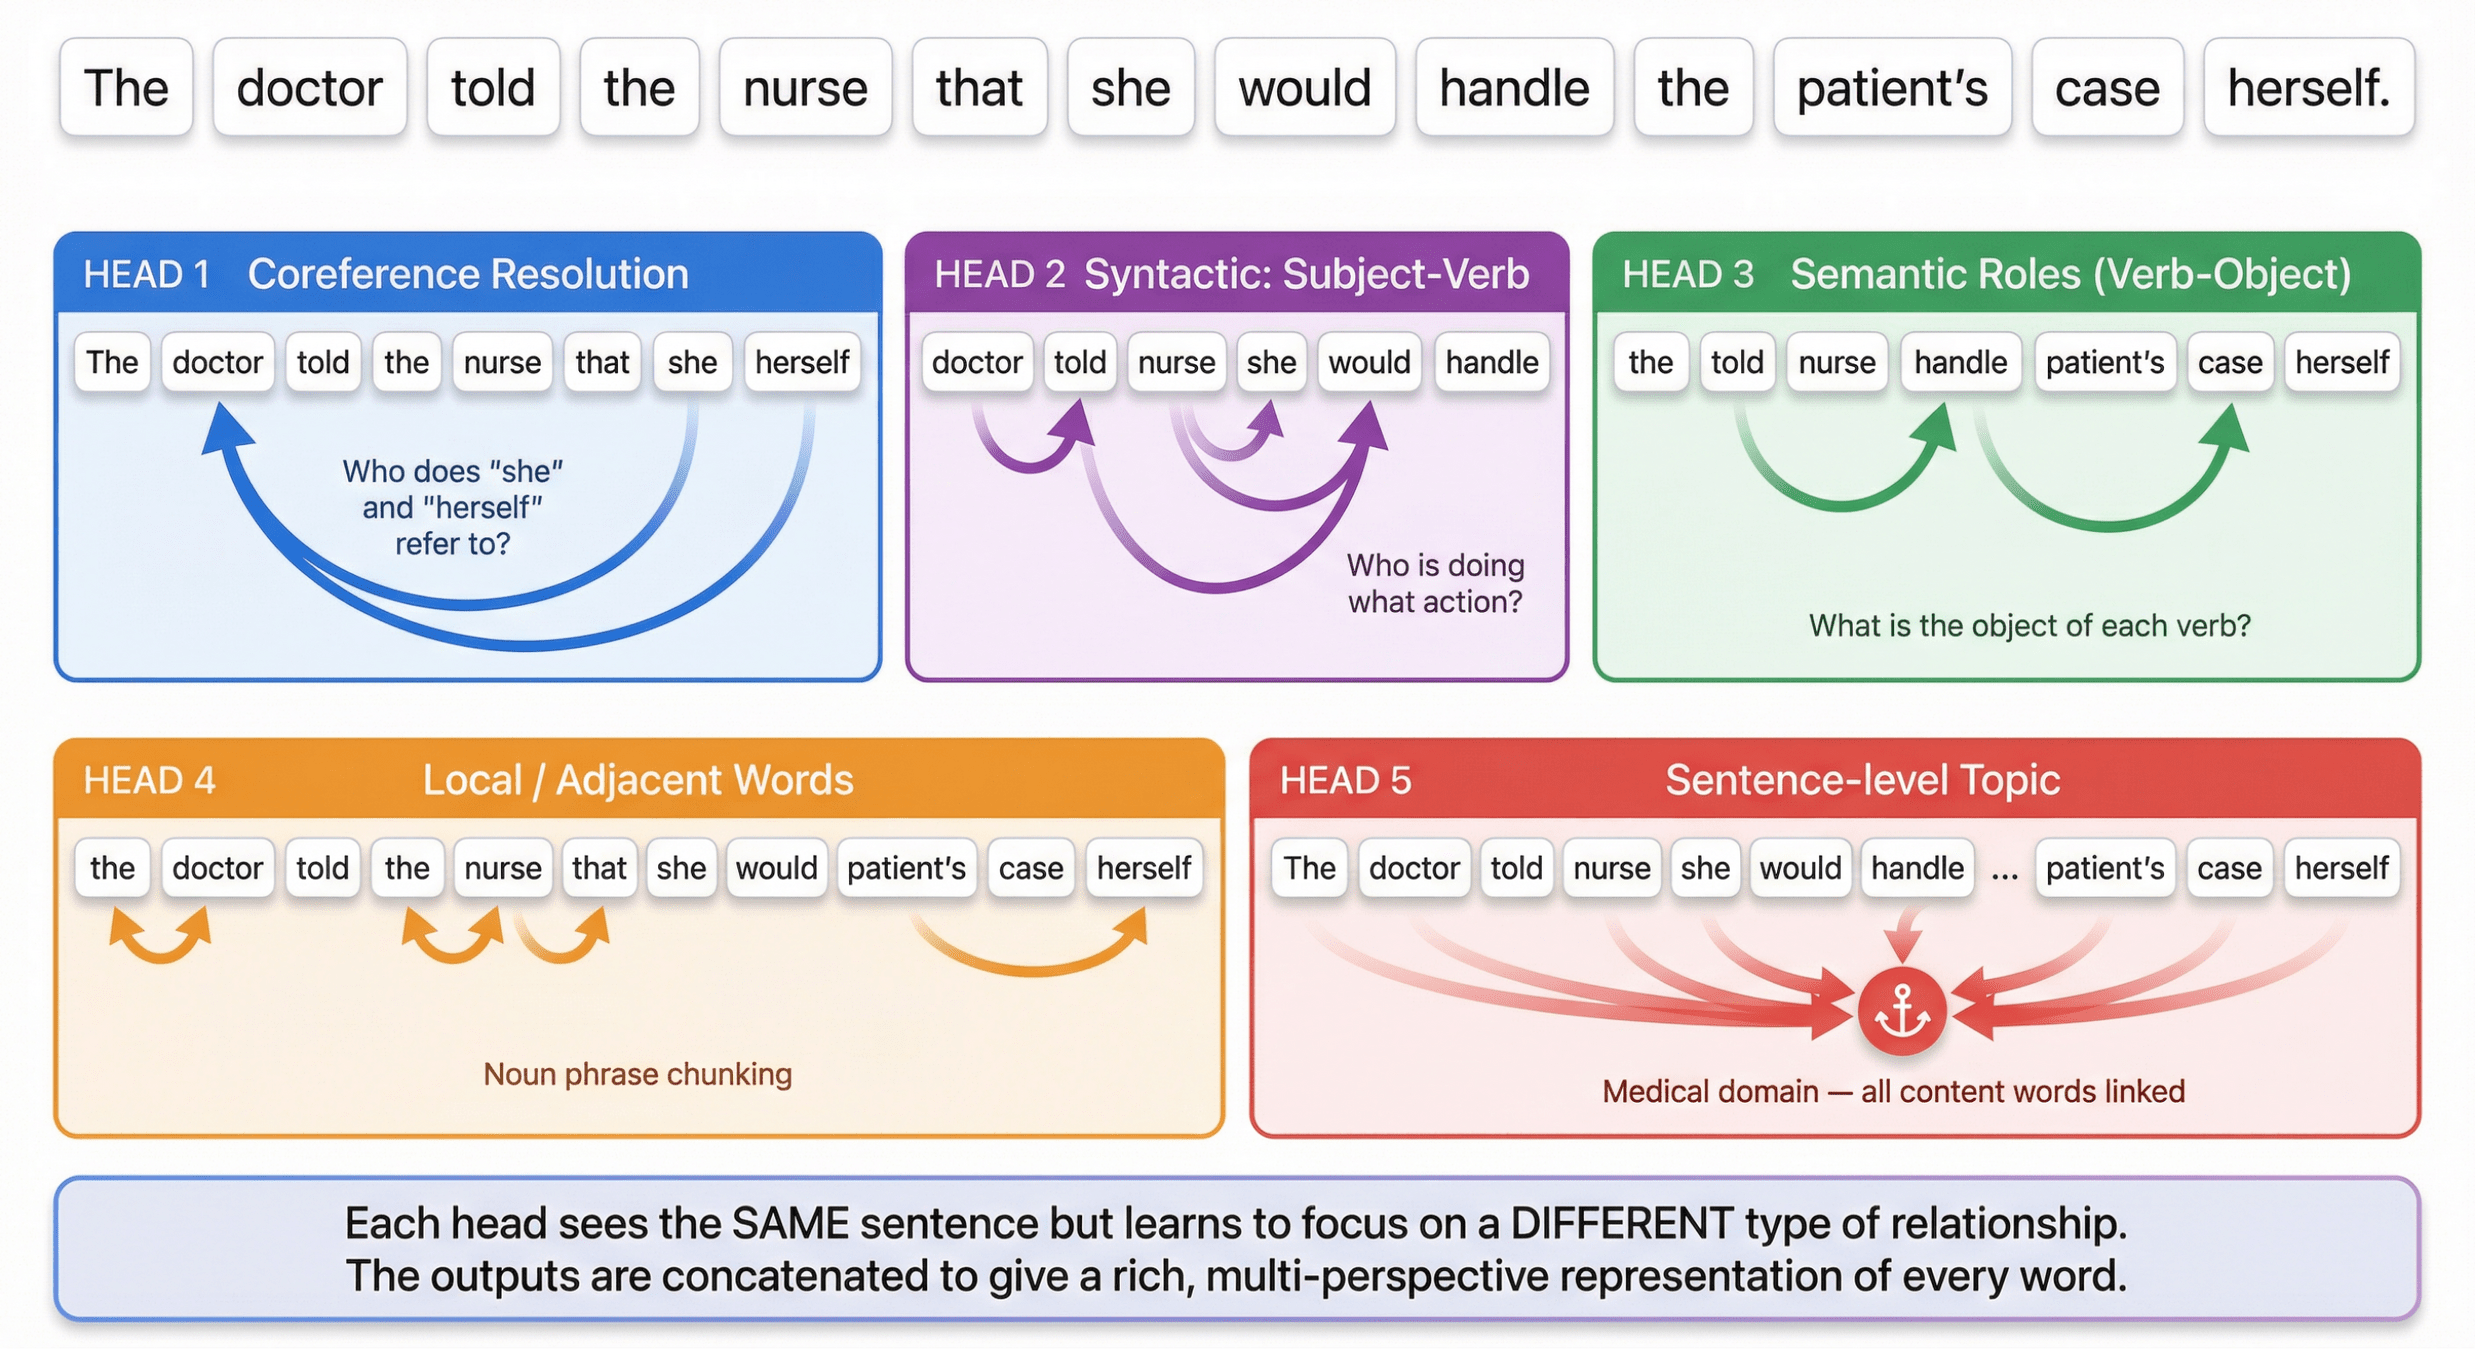
Two-head Attention
Scaled Dot Product
Head-1
Scaled Dot Product
Head-2
Scaled Dot Product
Attention
Scaled Dot Product
Attention
Two head Attention
Concatenate
Linear
How do we extend this to multi-head attention?
Recall How \(Q,K,V\) are obtained from \(H\).
Scaled Dot Product
Attention
Scaled Dot Product
Attention
Scaled Dot Product
Attention
Concatenate (:\(T \times 512\))
Linear
Multi-Head Attention
Concatenate (:\(T \times 512\))
Linear
Scaled Dot Product
Attention
Scaled Dot Product
Attention
Scaled Dot Product
Attention
Multi-Head Attention
Concatenate (:\(T \times 512\))
Linear
Multi-Head Attention
Scaled Dot Product
Attention
Scaled Dot Product
Attention
Scaled Dot Product
Attention
The input is projected into \(h=8\) different representation subspaces.
So, the multi-head attention allows the model to jointly
attend to information from different representation
subspaces at different positions.
Back to Basic Block
I
enjoyed
the
movie
transformers
Encoder
Feed Forward Network
Multi-Head Attention
The encoder is composed of a stack of \(N=6\) layers
Each layer in the encoder is composed of two sublayers, namely, multi-head attention and feed forward neural networks
I
enjoyed
the
movie
transformers
Multi-Head Attention
FFN
1
FFN
2
FFN
5
FFN
4
FFN
3
I
enjoyed
the
movie
transformers
Multi-Head Attention
FFN
1
FFN
2
FFN
5
FFN
4
FFN
3
I
enjoyed
the
movie
transformers
Multi-Head Attention
FFN
1
FFN
2
FFN
5
FFN
4
FFN
3
Identical network for each position \(z_i\)
Let's calculate the number of learnable parameters in the encoder layer
Feed Forward Network
Multi-Head Attention
I
enjoyed
the
movie
transformers
Therefore, about 3 million parameters per layer
Considering 8 heads
Encoder Stack
The encoder is composed of \(N\) identical layers and each layer is composed of 2 sub-layers.
Number of Parameters: \(N \times 3 \times 10^6\)
Number of Parameters: \(6 \times \) 3 million
about 18 million parameters
The computation is parallelized in the horizontal direction (i.e., within a training sample) of the encoder stack, not along the vertical direction.
I
enjoyed
the
movie
transformers
Layer-1
Layer-2
Layer-6
Let us denote the output sequence of vectors from the encoder as \(e_j\), for \(j=1,\cdots,?\)
Decoder
I
enjoyed
the
movie
transformers
Encoder
Decoder
Naan
transfarmar
padaththai
rasithen
What will be the output dimension?
Decoder Stack
Naan
transfarmar
padaththai
rasithen
Layer-1
Layer-2
Layer-6
The decoder is a stack of \(N=6\) Layers. However, each layer is composed of three sublayers.
Feed Forward Network
Masked Multi-Head (Self)Attention
Multi-Head (Cross) Attention
Masked (Self) Attention
With one important difference:
Recall that in self-attention we computed the query, key, and value vectors \(q,k\&v\) by multiplying the word embeddings \(h_1,h_2,\cdots,h_T\) with the transformation matrices \(W_Q,W_K,W_V\),respectively.
The same is repeated in the decoder layers. This time the \(h_1,h_2,\cdots,h_T\) are the word embeddings of target sentence. But,
With one important difference: Masking to implement the teacher-forcing approach during training.
Note: Encoder block also uses masking in attention sublayer in practice to mask the padded tokens in sequences having length < T
Of course, we can't use teacher forcing during inference. Instead, the decoder act as a auto-regressor.
Recall that in self-attention we computed the query, key, and value vectors \(q,k\&v\) by multiplying the word embeddings \(h_1,h_2,\cdots,h_T\) with the transformation matrices \(W_Q,W_K,W_V\),respectively.
The same is repeated in the decoder layers. This time the \(h_1,h_2,\cdots,h_T\) are the word embeddings of target sentence. But,
Feed Forward Network
Masked Multi-Head (Self)Attention
Multi-Head (Cross) Attention
First decoder layer
Naan
transfarmar
padaththai
rasiththen
<Go>
Feed Forward Network
Naan
transfarmar
padaththai
rasiththen
<Go>
Number of Parameters:
About 2 million parameters from FFN layer
About 1 million parameters from Masked-Multi Head Attention layer
About 1 million parameters from Multi Head Cross Attention layer
About 4 million parameter per decoder layer
Decoder output
Feed Forward Network
Linear \(W_D\)
Softmax
The output from the top most decoder layer is linearly transformed by the matrix \(W_D\) of size \(512 \times |V|\) where \(|V|\) is the size of the vocbulary.
The probability distribution for the predicted words is obtained by applying softmax function.
This alone contributes about 19 million parameters of the total 65 million parameters of the architecture.
Positional Encoding
Positional Encoding
The position of words in a sentence was encoded in the hidden states of RNN based sequence to sequence models.
However, in transformers, no such information is available to either encoder or decoder. Moreover, the output from self-attention is permutation-invariant.
How do we embed positional information in the word embedding \(h_j\) (of size 512)?
I
Enjoyed
So, it is necessary to encode the positional information.
Positional Encoding
I
How do we fill the elements of the positional vector \(p_0\)?
Could it be a constant vector (i.e, all elements are of constant (position) value \(j\), for \(p_j\))?
Can we use one hot encoding for the position \(j\), \(j=0,1,\cdots,T\)?
or learn embedding for all possible positions?
Not suitable if the sentence length is dynamic.
Sinusoidal encoding function
Hypothesis: Embed a unique pattern of features for each position \(j\) and the model will learn to attend by the relative position.
How do we generate the features?
For the fixed position \(j\), the value for \(i\) is sampled from \(sin()\) if \(i\) is even or \(cos()\) if \(i\) is odd
Let's evaluate the function \(PE_{(j,i)}\) for \(j={0,1,\cdots,8}\) and \(i={0,1,\cdots,63}\)
Then, we can visualize this matrix as a heat map.

This alternating 0's and 1's will be added to the first word(embedding) of all sentences.
Multi-Head Attention
Feed forward NN
Add&Norm
Add&Norm
Multi-Head cross Attention
Feed forward NN
Add&Norm
Add&Norm
Multi-Head Maksed Attention
Add&Norm