Deep Implicits
with Differential Rendering
Daniel Yukimura
scene
parameters
2D image
- camera pose
- geometry
- materials
- lighting
- ...

rendering
differentiable
Feedback
(Learning)
Differentiable Volumetric Rendering

Can we infer implicit 3D representations without 3D supervision?
Differentiable Volumetric Rendering
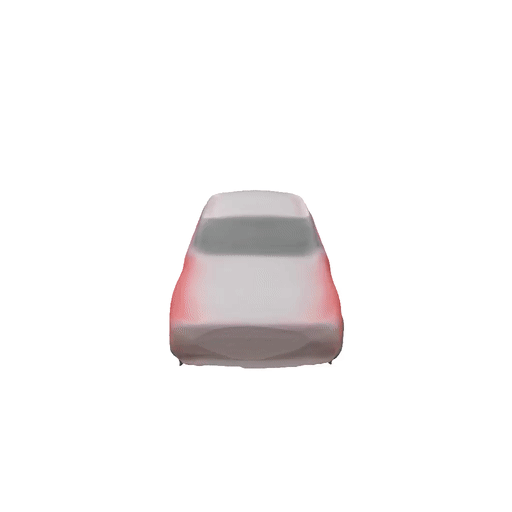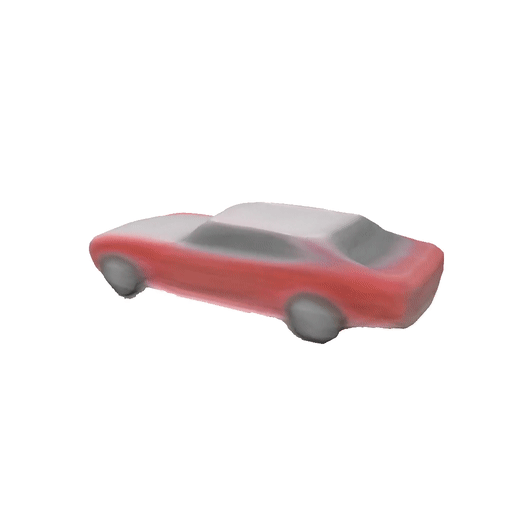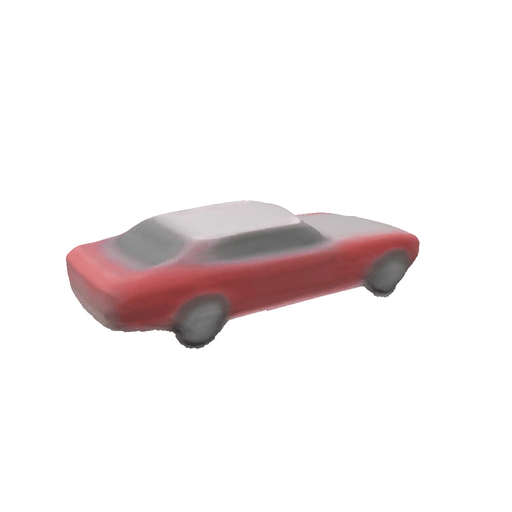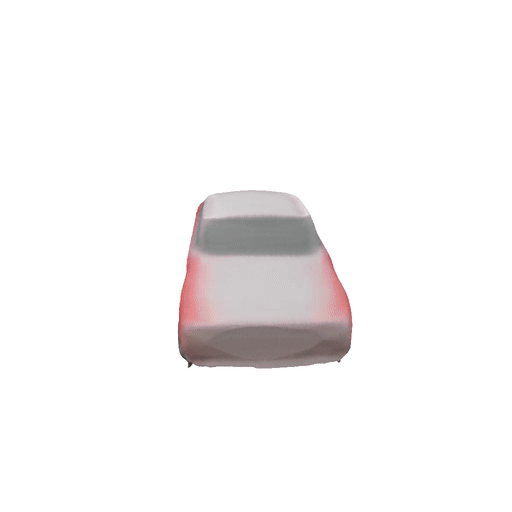
single-view 3D reconstruction
Architecture

f_\theta: \mathbb{R}^3 \times \mathcal{Z} \rightarrow [0,1]
t_\theta: \mathbb{R}^3 \times \mathcal{Z} \rightarrow \mathbb{R}^3
Forward Pass - Rendering:
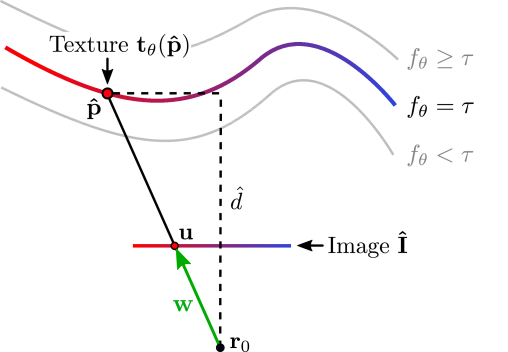
\hat{p} = \text{``first intersection with } \{p\in \mathbb{R}^3 | f_\theta(p) = \tau \} \text{"}
Backward Pass - Gradients:
\mathcal{L}(\hat{I}, I) = \sum\limits_u \|\hat{I}_u - I_u \|
Loss function
Differentiable Rendering
\frac{\partial \mathcal{L}}{\partial\theta} = \sum\limits_u \frac{\partial \mathcal{L}}{\partial \hat{I}_u} \frac{\partial \hat{I}_u}{\partial \theta} \\
= \sum\limits_u \frac{\partial \mathcal{L}}{\partial \hat{I}_u} \left( \frac{d t_\theta (\hat{p})}{d \theta} + \frac{\partial t_\theta (\hat{p})}{\partial \hat p} \frac{\partial \hat{p}}{\partial\theta}\right)
KNOWN
??
Depth Gradients:
r(d) = r_0 + d w
\exists\hspace{1mm} \hat{d} \text{ s.t. } \hspace{2mm} \hat{p} = r(\hat{d})
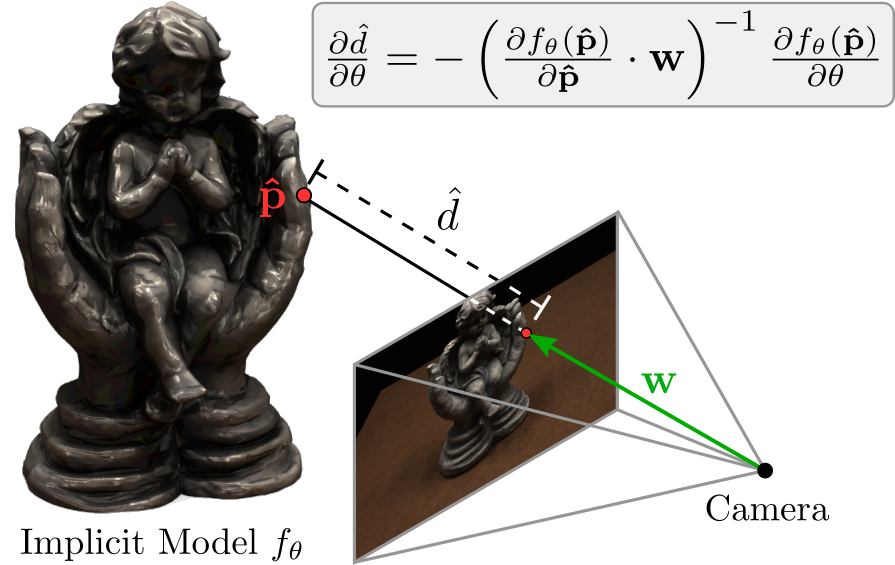
Single-View Reconstruction:
- Multi-View Supervision
- Single-View Supervision
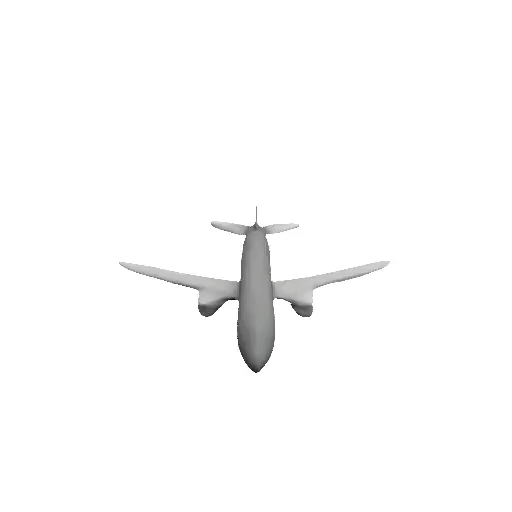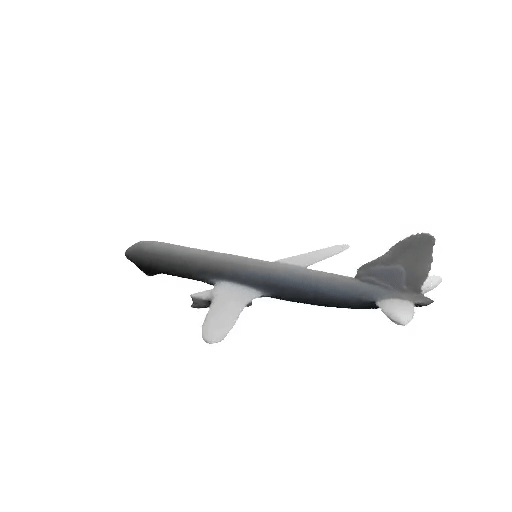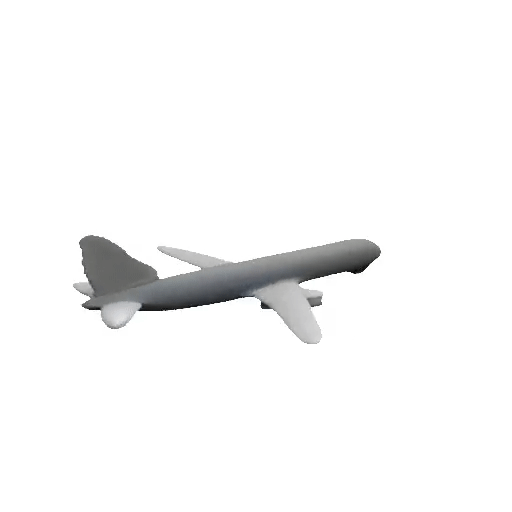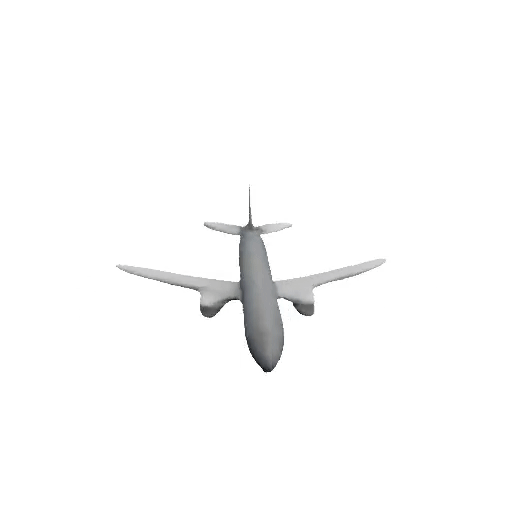
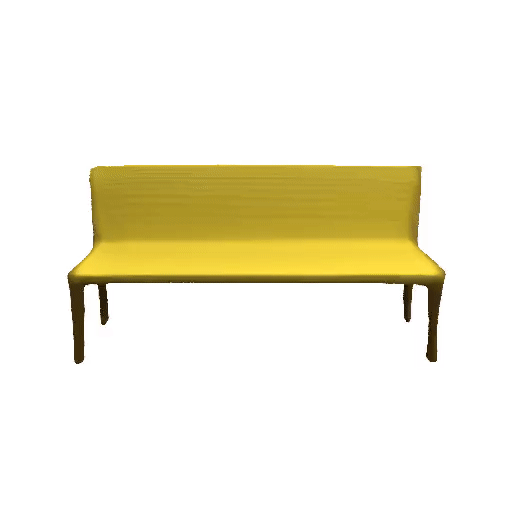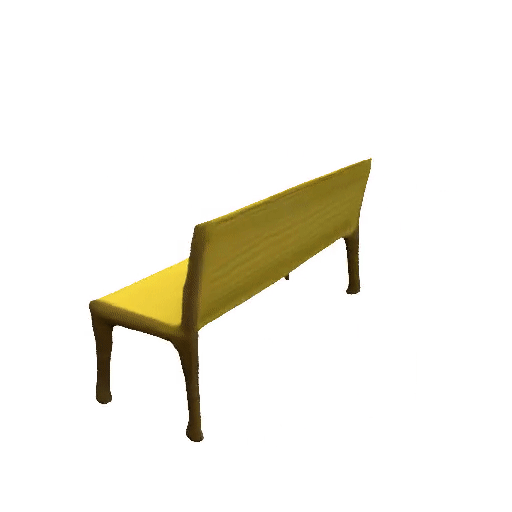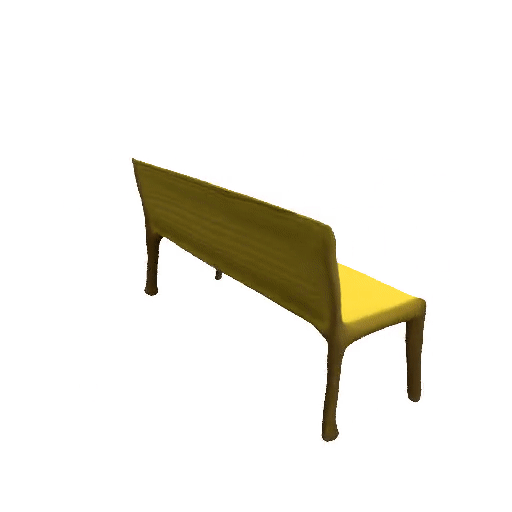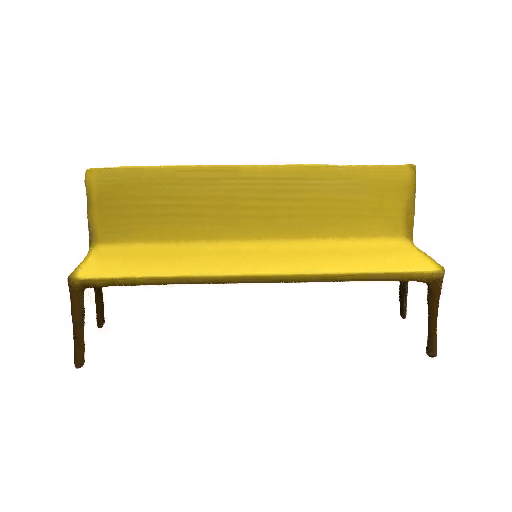
Experiments:
Multi-View Reconstruction:
Experiments:
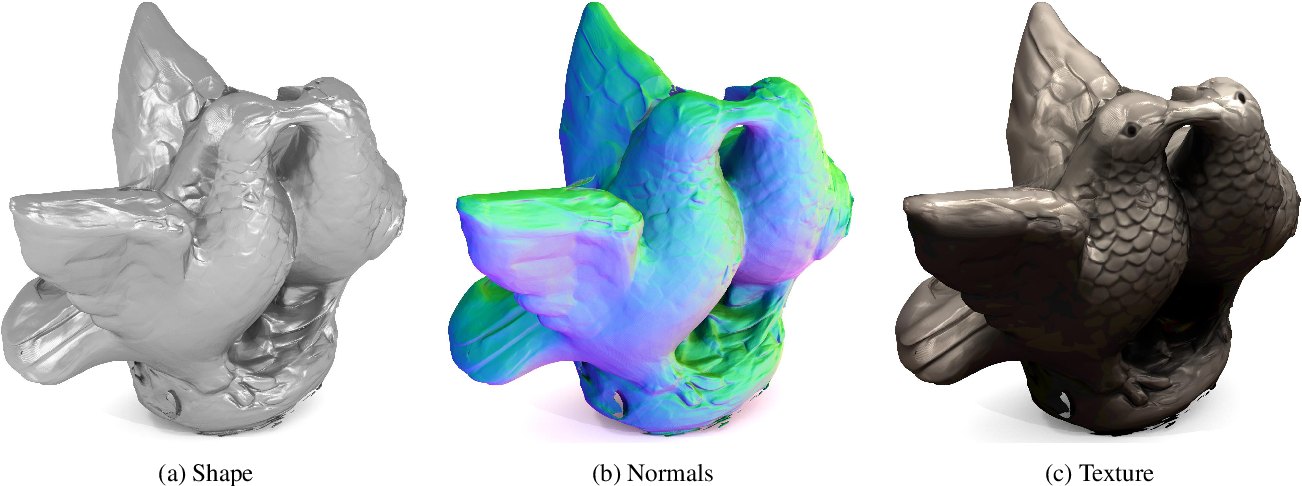
Implicit Differentiable Rendering
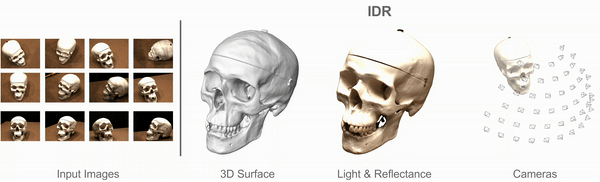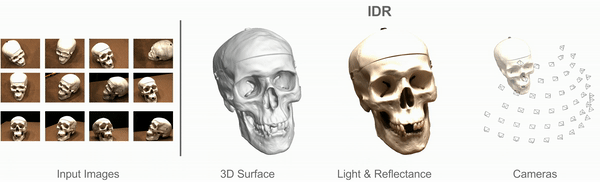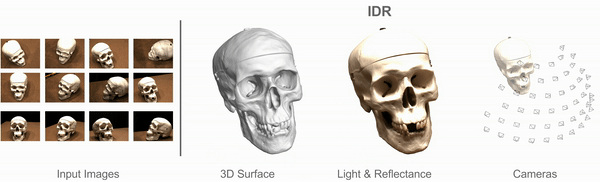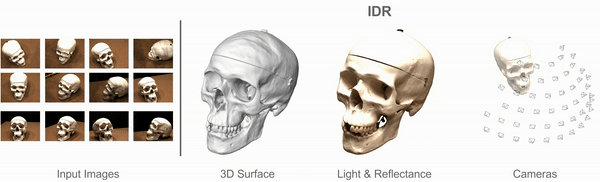
Multiview 3D Surface Reconstruction
Input: Collection of 2D images (masked)
with rough or noisy camera info.
Targets:
- Geometry
- Appearance (BRDF, lighting conditions)
- Cameras
Method:
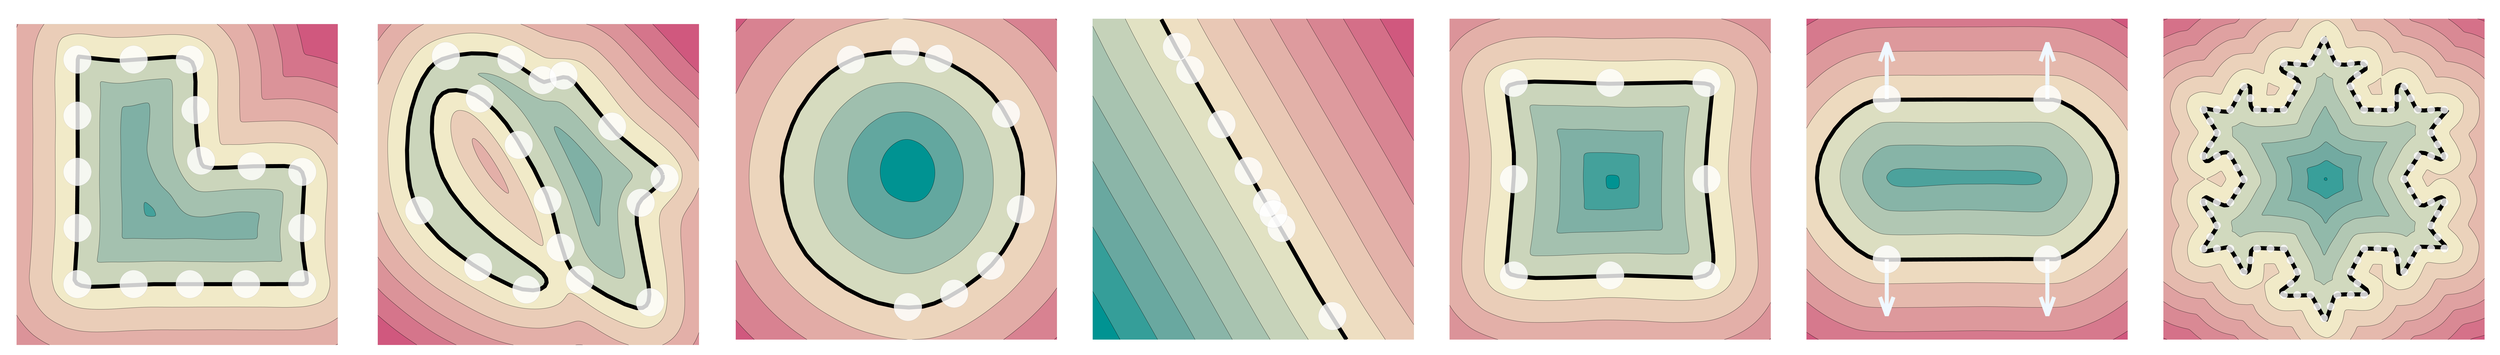
Geometry:
\mathcal{S}_\theta = \{ x\in \mathbb{R}^3 | f(x;\theta) = 0 \}
signed distance function (SDF) +
implicit geometric regularization (IGR)
\theta
- geometry parameters
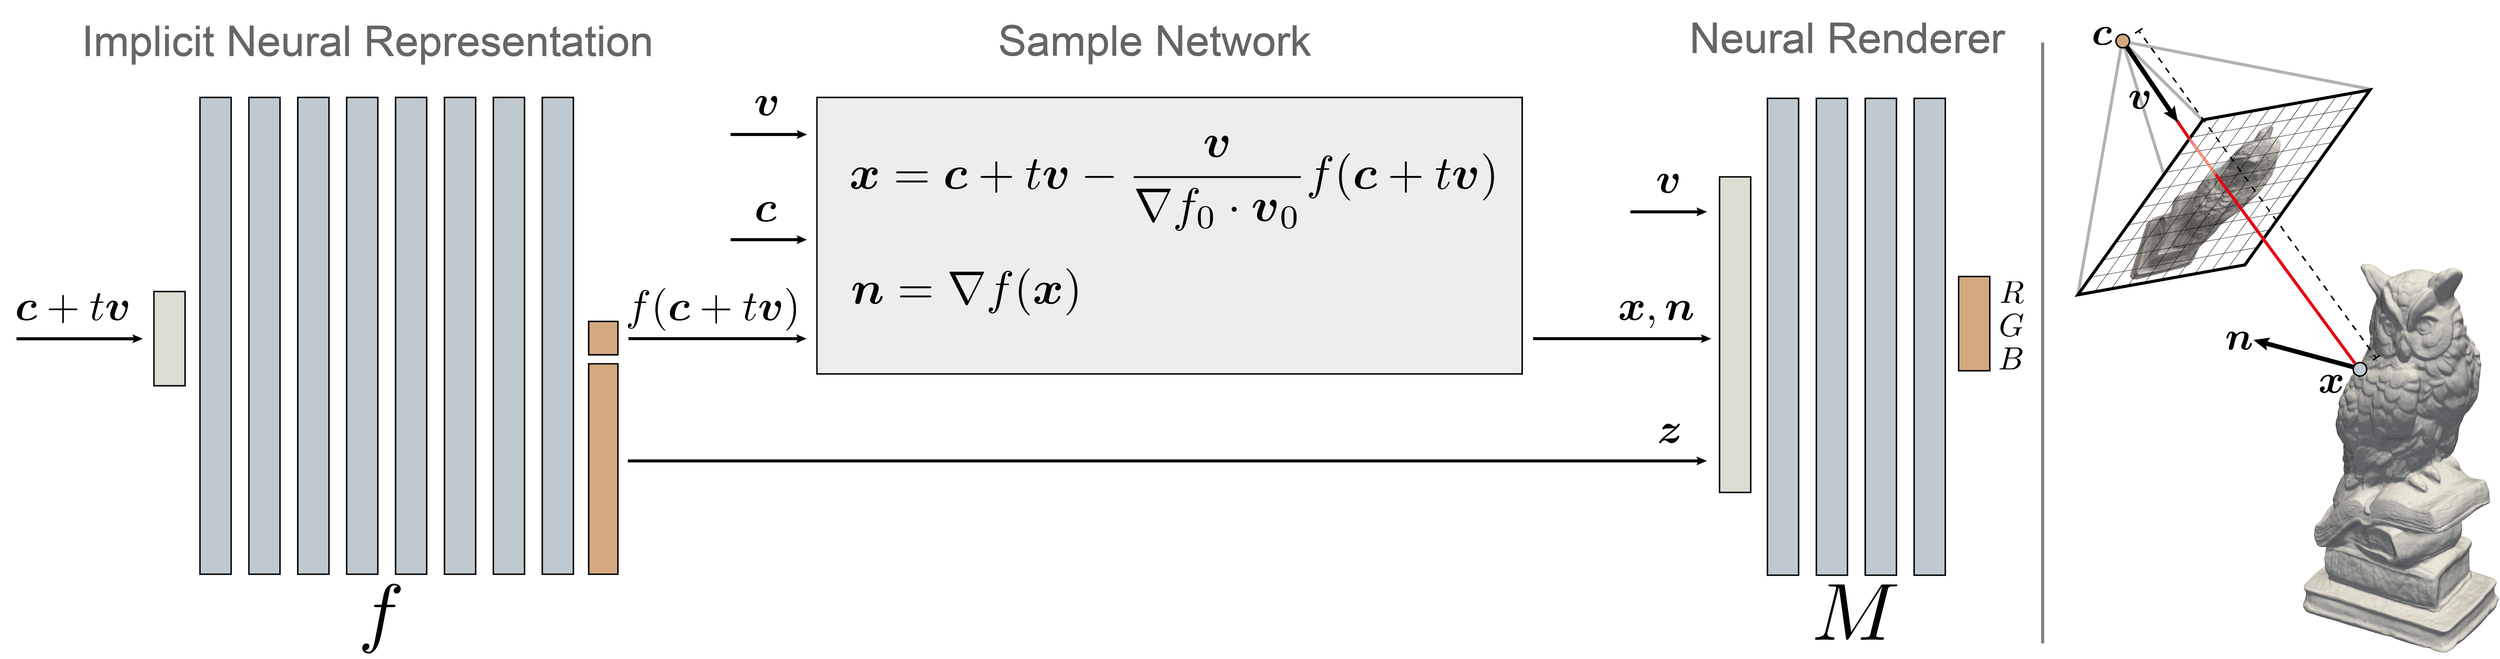
IDR - Forward pass

R_p(\tau) = \{ c_p + t v_p | t \geq 0 \}
\hat{x}_p = \hat{x}_p(\theta, \tau) = R_p(\tau) \cap \mathcal{S}_\theta
\tau
- camera parameters
Ray cast:
(first intersection)
IDR - Forward pass
L_p(\theta, \gamma, \tau) = M(\hat{x}_p, \hat{n}_p, \hat{z}_p, v_p; \gamma)
\gamma
- appearance parameters
Output (Light Field):
Surface normal
\hat{n}_p(\theta)
Global gometry feature vector
\hat{z}_p(\hat{x}_p; \theta)
Differentiable intersections
\theta_0, \tau_0 - \text{current parameters}
\hat{x}(\theta, \tau) = c + t_0 v - \frac{v}{\nabla_x f(x_0; \theta_0) \cdot v_0} f(c + t_0 v; \theta)
Lemma:
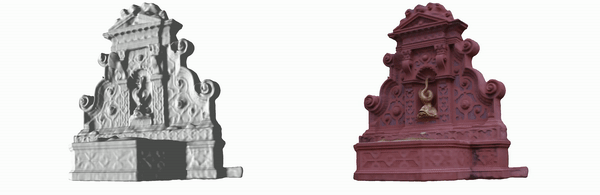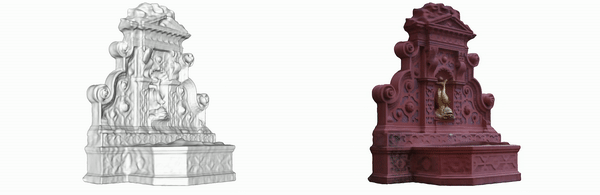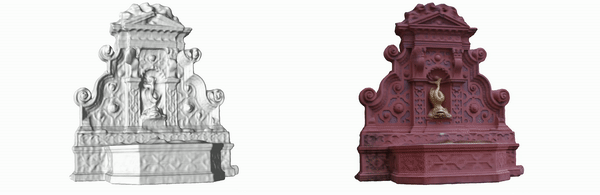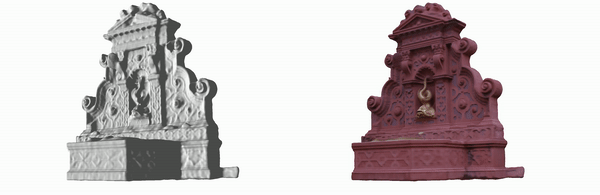
Experiments:
Multi-View Reconstruction:
Experiments:
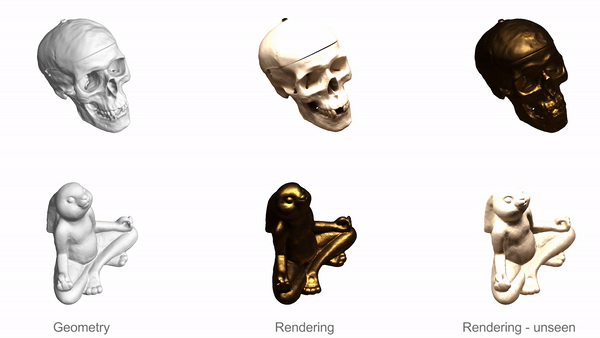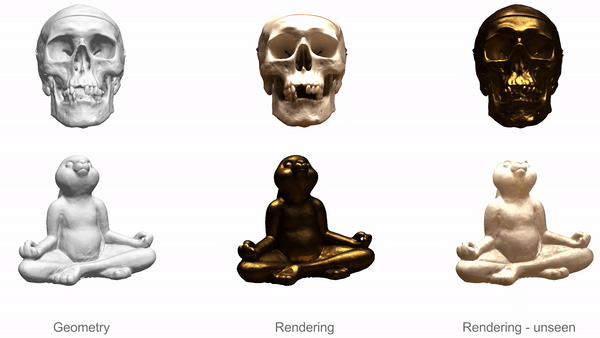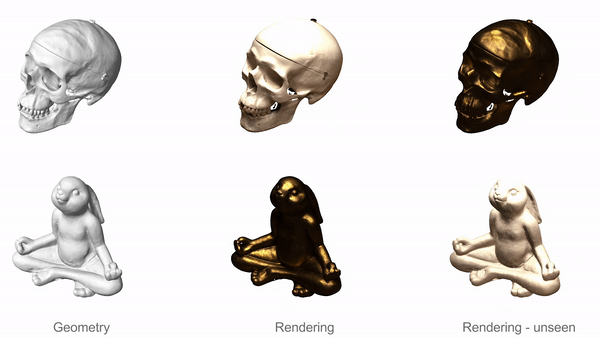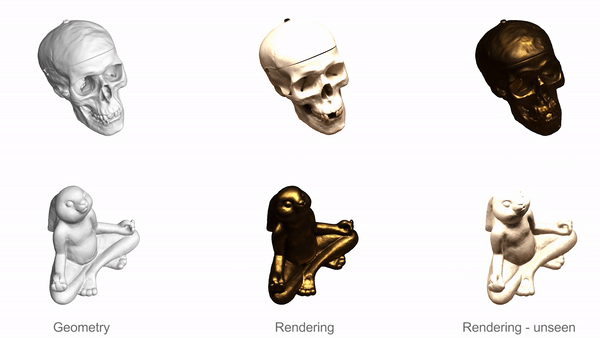
Disentangling Geometry and Appearance:
Copy of Deep Implicits
By Daniel Yukimura


