Bring parity in AI technology for Indian languages with English
Make fundamental contributions to state-of-the-art across language technologies - NLP, Speech, Sign language, OCR
Open source all datasets and AI models with permissible licenses
Build a coalition of partners to collect datasets and deploy models
Associate Professor, IIT Madras PhD, IIT Bombay
Areas - NLP, Deep Learning
Mitesh M. Khapra
Pratyush Kumar
Our Team
Anoop Kunchukuttan
Assistant Professor, IIT Madras PhD, ETH Zürich
Areas - Deep Learning, Systems
Researcher, Microsoft
PhD, IIT Bombay
Areas - NLP
+ many hard-working students and volunteers
What have we done so far (last 18 months)
IndicNLPSuite
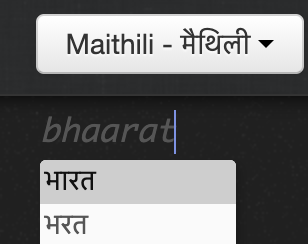
Input Tools
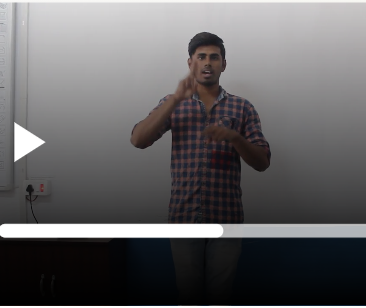
INCLUDE
Samanantar
বা
ગુ
हि
ಕ
म
ਪੰ
த
తె
ଓ
മ
অ
E
বা
ગુ
हि
ಕ
म
ਪੰ
த
తె
ଓ
മ
অ
Corpora, benchmarks, models for 11 Indic languages
Romanized keyboards for under-represented languages
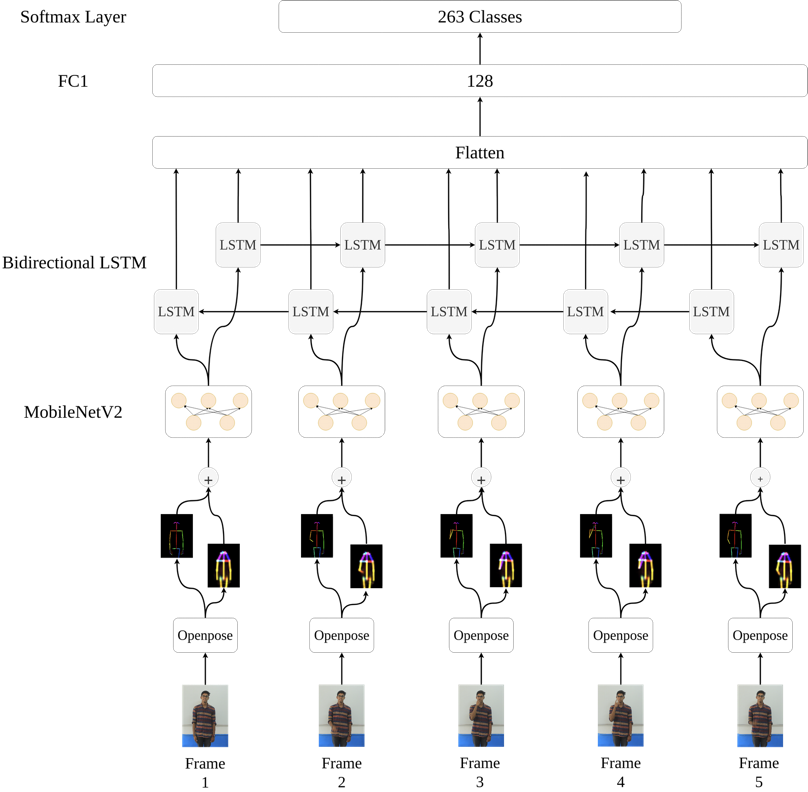
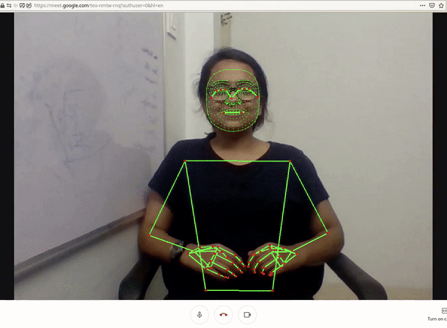
Datasets and efficient models for isolated Indian Sign Language
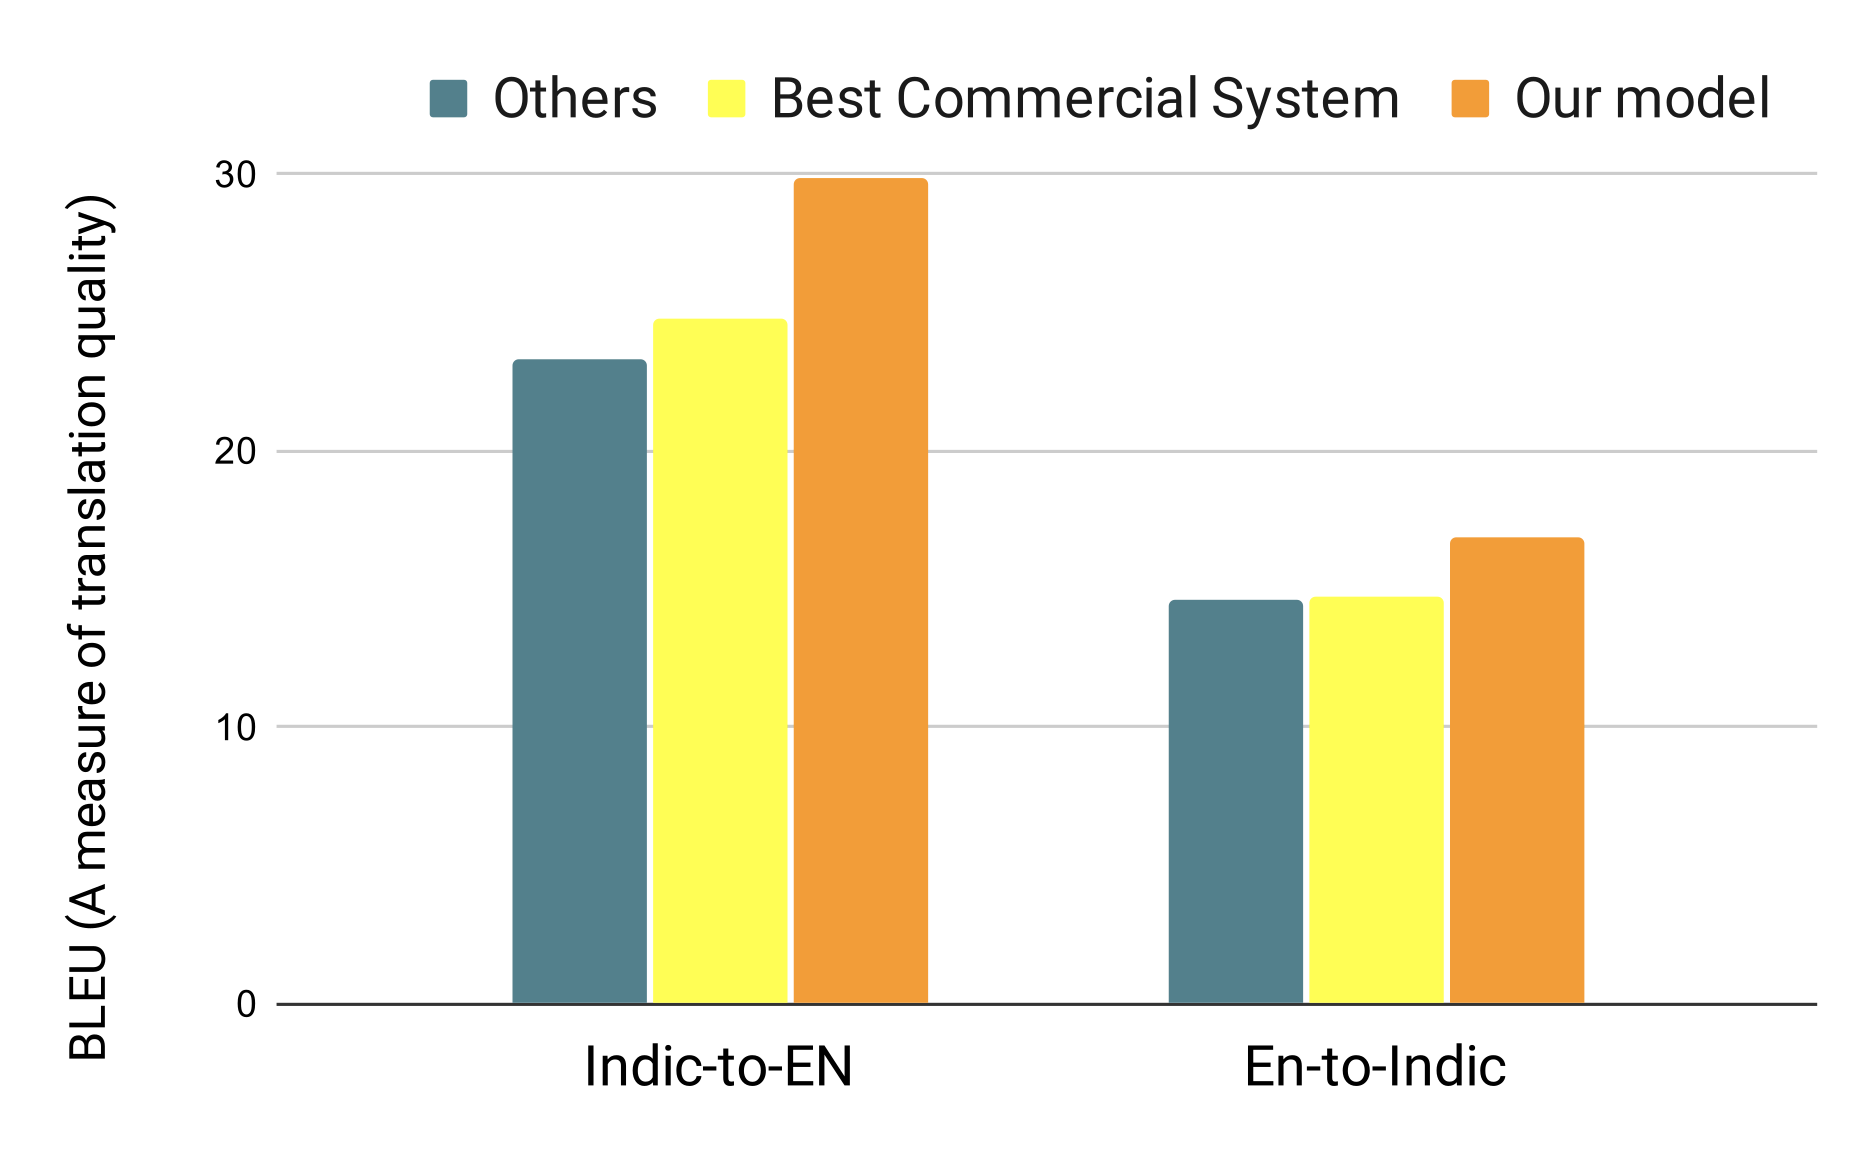
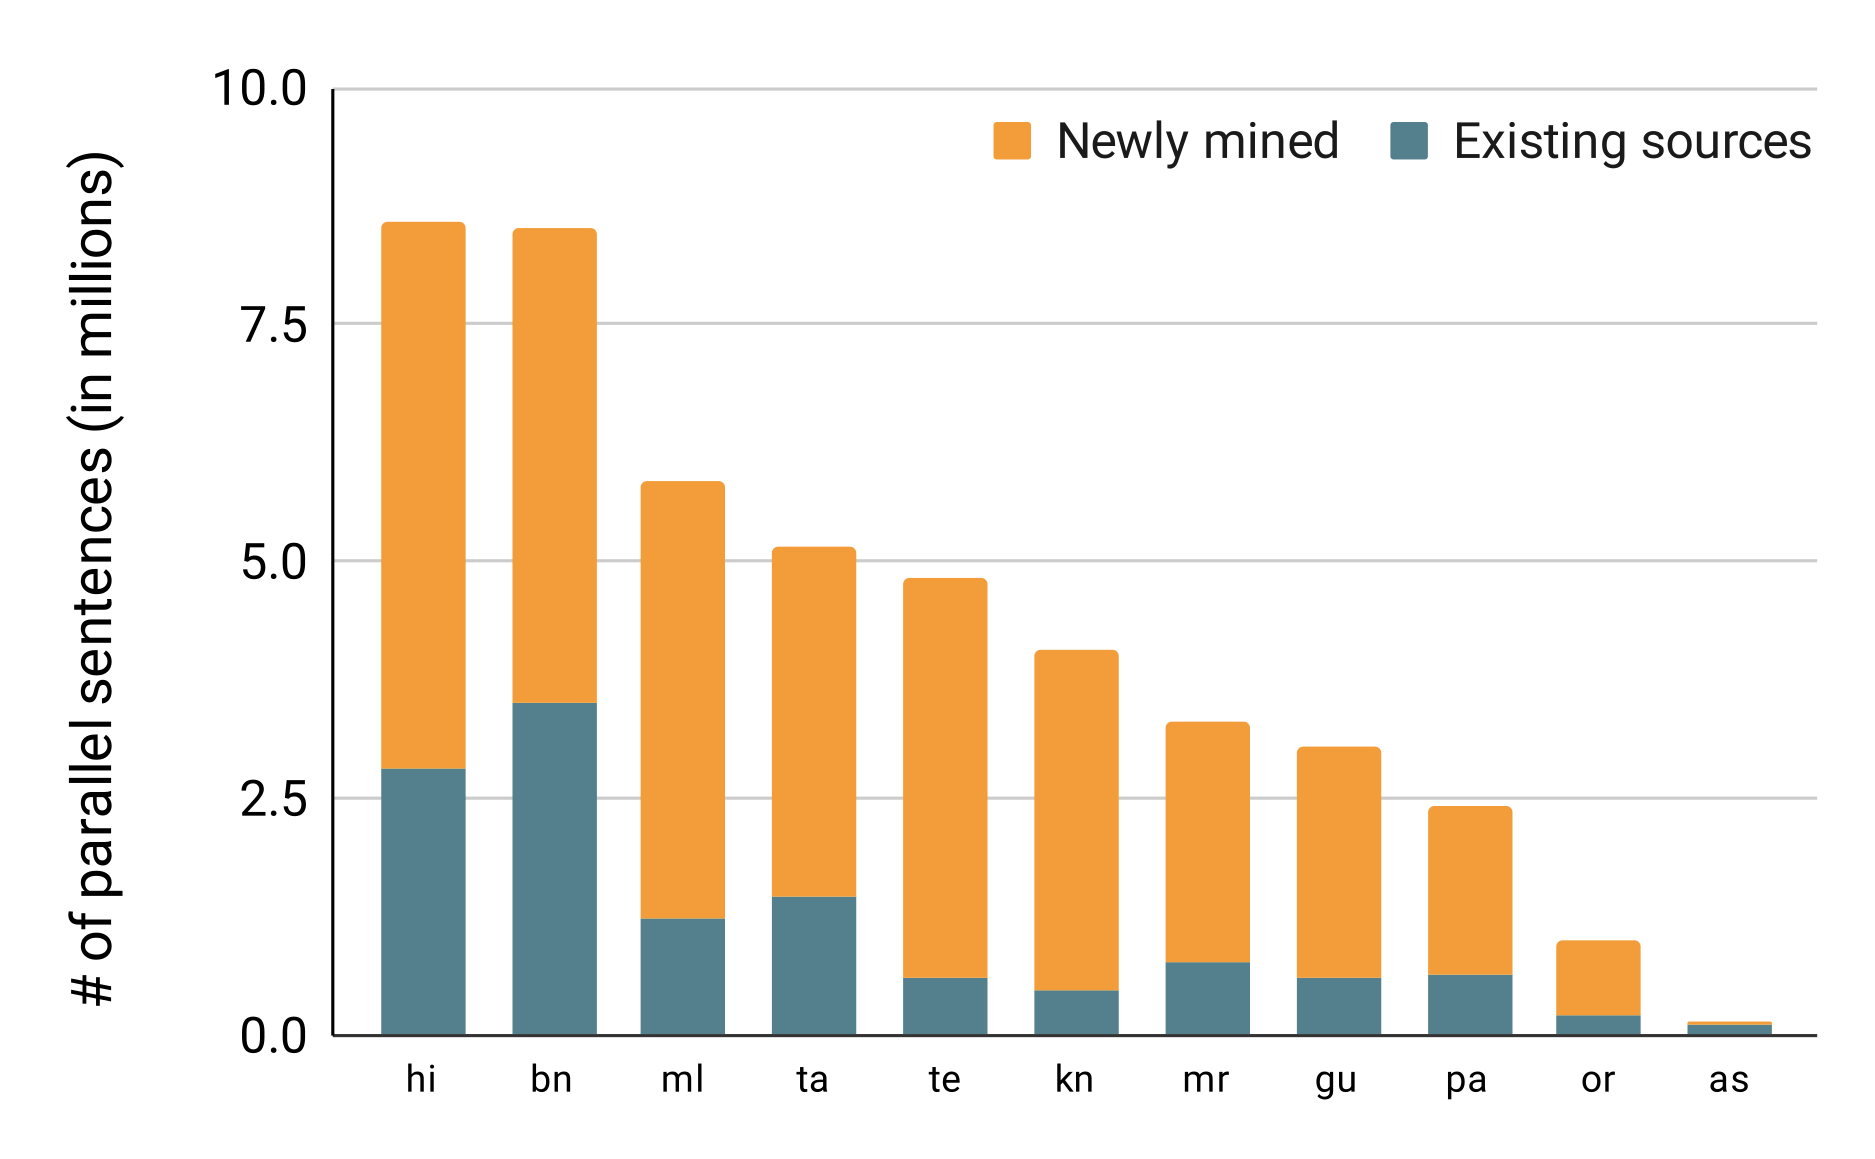
Parallel corpus, translation models between English & 11 Indic languages
What have we done so far?
IndicNLPSuite
Input Tools
INCLUDE
Samanantar
Largest task-agnostic monolingual corpus
Pre-trained
language models
Benchmark set on NLU tasks
9 billion tokens
14 tasks
10,000 downloads
Impact: Indian startups and academia can now use large pre-trained models to support downstream tasks such as sentiment analysis, question answering, semantic matching, etc in 11 Indic languages
Across 11 Indian languages:
বা
ગુ
हि
ಕ
म
ਪੰ
த
తె
ଓ
മ
অ
\dots
\dots
C
T_1
T_N
T_{[SEP]}
T_1'
T_M'
\dots
\dots
[CLS]
E_1
E_N
E_{[SEP]}
E_1'
E_M'
\dots
\dots
[CLS]
Tok1
Tok N
[SEP]
Tok 1
TokM
Masked Sentence 1
Masked Sentence 2
What have we done so far?
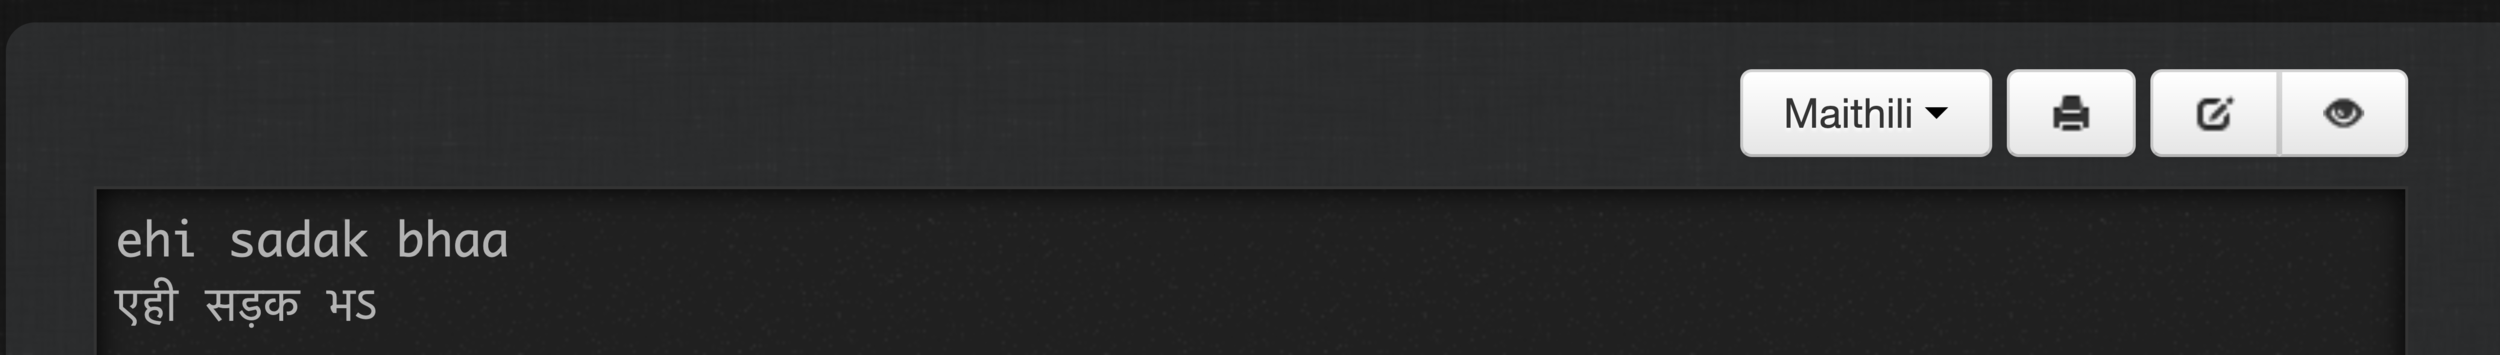
User types using English script
Automatically converted to Maithili script
IndicNLPSuite
Input Tools
INCLUDE
Samanantar
Impact: Input tools become significantly more efficient for a long list of Indian languages. Impacts all content creation including writing storybooks for children
Deployed to write storybooks at
What have we done so far?
IndicNLPSuite
Input Tools
INCLUDE
Samanantar
Impact: The first large-scale AI work on Indian Sign Language. Won the first AI4Accessibility global challenge run by Microsoft for scaling up data collection to continuous sign language through 2021-22
Largest public dataset on Indian Sign Language
263 signs, 4000+ videos
Efficient AI models for recognising signs
>90% accuracy
What have we done so far?
AI model for translating between English and 12 Indic languages
IndicNLPSuite
Input Tools
INCLUDE
Samanantar
46M parallel sentences mined from the web (3X improvement)
Impact: The translation models (which are shown to be more accurate than commercial APIs) are being used to assist human translators in translating supreme court judgements with a significant increase in efficiency
What are some of our ongoing activities?
Creating a robust, standardised benchmark for Machine Translation
Mining high quality text to speech data for building ASR models
Building models for continuous signs in video call apps
What next? (A long tail of NLP tasks)
What does it take to build a typical NLP application?
Full NLP stack
A chatbot for Aaarogya Setu
Input Tools
Keyboards
Spell checkers
.... ....
Text Analysers
.... ....
Sentiment Analysis
Content Filters
Inference Engines
QA
Natural Language Inference
.... ....
Text Generators
.... ....
Dialog
Build this full stack for each Indic language
Text Generators
.... ....
Translation
Dialog
Summarisation
Inference Engines
QA
NLI
Paraphrase Detection
.... ....
Text Analysers
.... ....
Named Entity Recognition
Sentiment Analysis
Topic Classification
Content Filters
Input Tools
Keyboards
Spell checkers
.... ....
Beyond 2023
Build swipe based keyboards for all 22 languages
What will we do?
A long tail of tasks and languages
... ... ...
What will be our guiding principle?
Focus on delivery-oriented, cutting edge research which is relevant to government, industry, academia and society
How will we sustain this?
Depend on benefactor to broaden the reach of our work in sectors with a definitive need (government, industry, startups)
Bundelkhandi, Gondi, Garhwali, ... ...
What do we need?
Set up "The AI4Bharat Initiative" @
House a best-in-class team of researchers, engineers and developers
Build capacity by conducting workshops for startups, industry and academia
Rent/set up world class compute infrastructure for building cutting edge AI models
Build datasets and benchmarks by partnering with annotation service providers
Yearly budget
Total: 850K USD
Equipment
Laptops, Storage
50K
Outreach
Workshops, Contests
100K
250K
Cloud resources
Compute
60K
Rent, consumables
Infra
Outsourced (200 man months)
Labelling
120K
20K
15K
15K
1 Admin Head
1 System Admin
3 Support Staff
Admin
1 Outreach Lead
15K
1 Post Doc
2 Senior Researchers
10 AI Residency Fellows
RnD
30K
40K
100K
2 Software Engineers
40K
Supreme Court
of India
pilot ongoing
CDAC - evaluating for website translation
Ongoing field test to translate a fiction book
Deployed in
internal tool
Android keyboards
Impact - This year
Supreme Court
of India
pilot ongoing
CDAC - evaluating for website translation
Ongoing field test to translate a fiction book
Deployed in
internal tool
Android keyboards
Impact - Over years
Government
Be-spoke solutions
Commercial applications
(led by others)
NGOs
Free mobile tools
Dissemination
AI Residency Program (400 + applicants in inaugural year)
AI Winter School (premier hands-on workshop in AI in the country)
Govt's NLTM (play a horizontal role)
To be managed professionally by
a function head
Sustainability of the Initiative
We are committed to run this initiative for 10 years
given the size, complexity, and foundational impact of the language technology piece in India
Our core approach would continue to be a focus on
open sourcing datasets, models, and tools
Sustainability of the initiative would be based on donors recognising value generated through the yearly mandates
For each year, we would declare the Initiative's mandate - a set of key goals for datasets, models, and tools
Potential Donors
Govt's funding
Philanthropy
Corporate Research
Potential Donors
Govt's funding (eg. NLTM)
Philanthropy (eg. EkStep)
Corporate Research (eg. Microsoft)
Focus on Speech - Our current roadmap
Release a joint speech-to-text model on 12 major
Indian languages in 2021
Create an automated approach to collect parallel
speech and text data from the web by mid 2022
Release efficient, privacy-preserving speech-to-text models for smartphones on 12 major languages by end 2022