Predicting High Uncertainty Events to Train Working Memory
Artyom Sorokin
18 December 2021
Memory is Important
in many tasks, but we start from Reinforcement Learning...
Markov Decision Process
Basic Theoretical Results in Model-Free Reinforcement Learning are proved for Markov Decision Processes.
Markovian propery:
In other words: "The future is independent of the past given the present."
p(s_{t+1}, r_{t} | s_t, a_t, s_{t-1}, a_{t-1}, ..., s_{1}, a_{1}, s_{0}) = p( s_{t+1}, r_{t} | s_t, a_t )
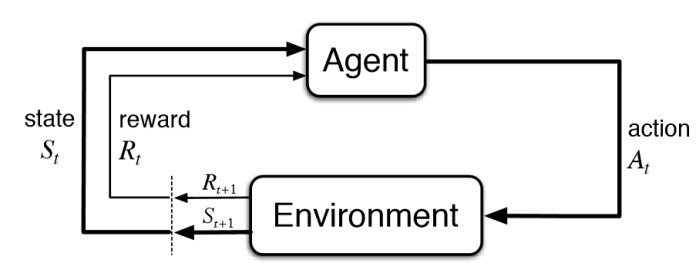
When does agent observe the state?
Memory in RL
Why We Need Working Memory?
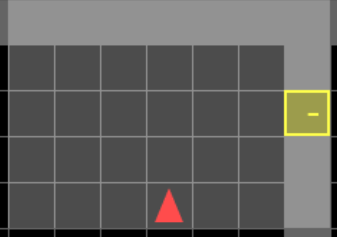
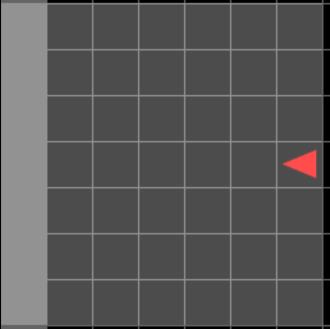
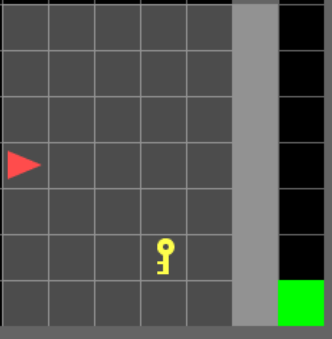
\(obs_{t=10}\)
\(obs_{t=12}\)
\(obs_{t=20}\)
\(act_{t=10}\)
\(act_{t=12}\)
\(act_{t=13}\)
We need this information
At this moment!
Memory
. . .
. . .
Recurrent Memory:
\(obs_{t=10}\)
\(obs_{t=12}\)
\(obs_{t=20}\)
\(act_{t=10}\)
\(act_{t=12}\)
\(act_{t=20}\)
\(h_{10}\)
. . .
. . .
\(h_9\)
\(h_{19}\)
. . .
. . .
. . .
Information
Gradients
Window Based Memory
\(obs_{t=10}\)
\(obs_{t=12}\)
\(obs_{t=20}\)
\(act_{t=10}\)
\(act_{t=12}\)
\(act_{t=20}\)
. . .
. . .
Information
Gradients
Memory Window
Transformer is a window-based memory architecture
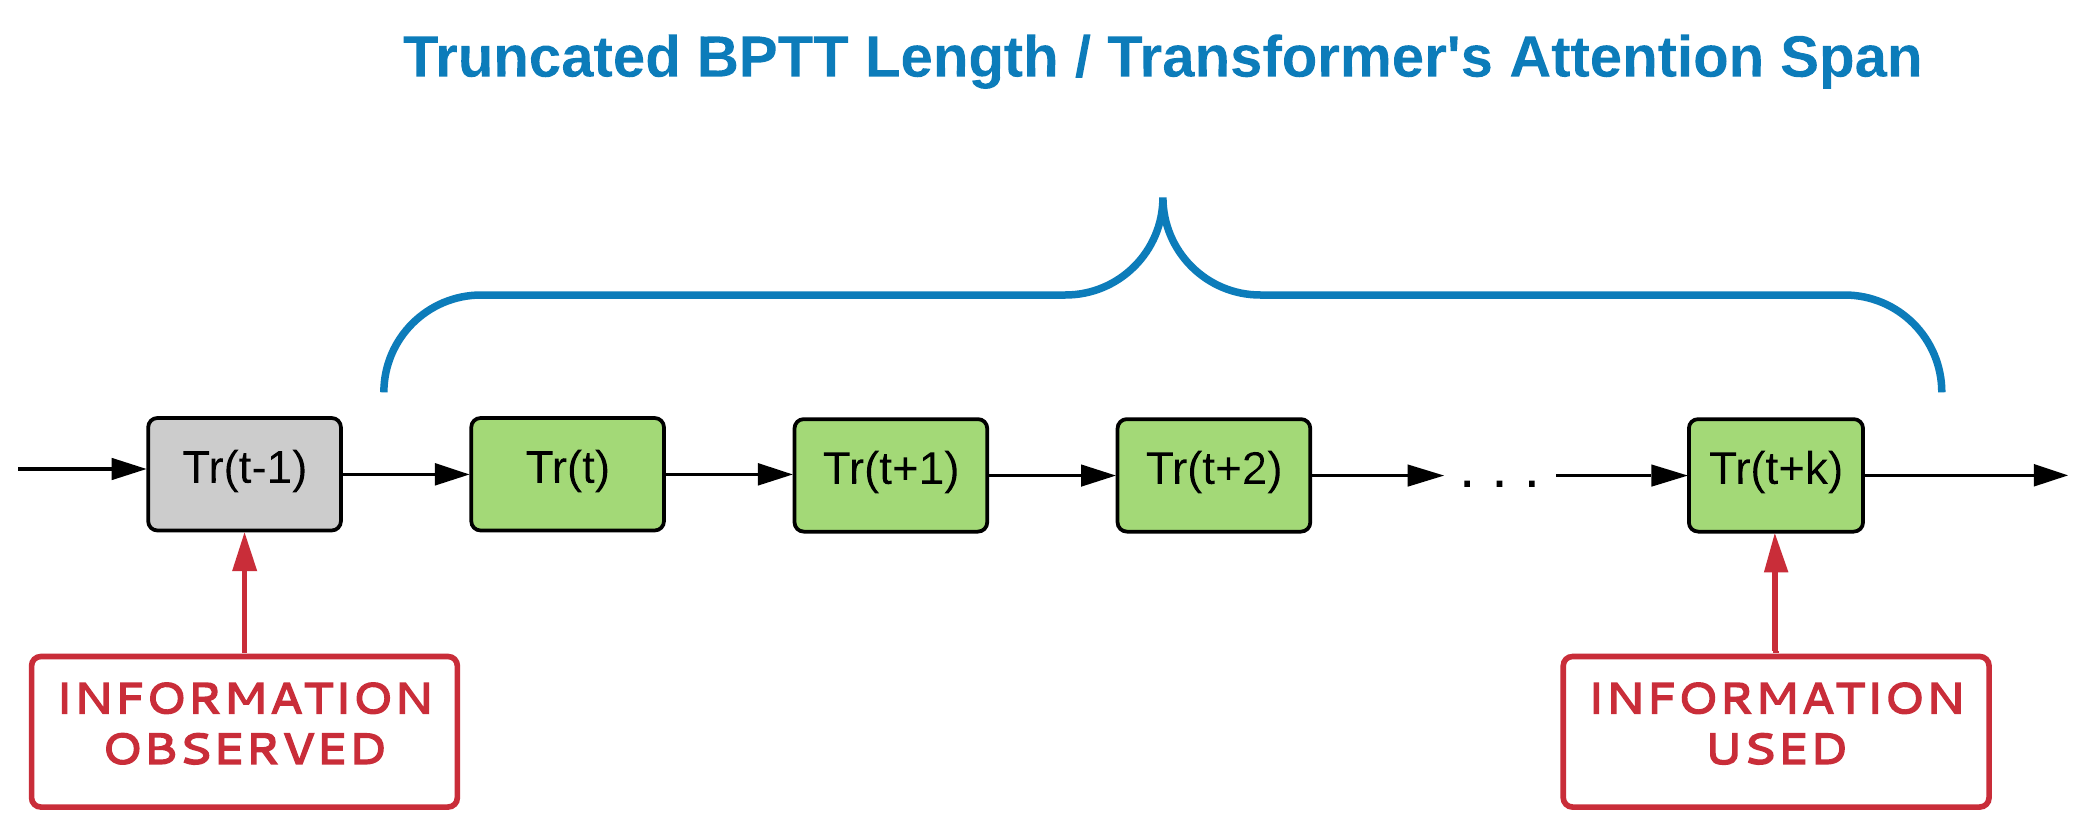
Problems with RNN and Transformers
-
Temporal dependency should fully fit into TBPTT or Attention Span to be learned
-
You need to process all intermediate steps to implement backpropagation over Attention Span/TBPTT
Problem with RNN and Transformers
Problem:
We need to backpropagate through all intermediate steps
to find and learn temporal dependency
Temporal dependency should fit into TBPTT/Attention Span to be learned
As we can't detect temporal dependency locally
? ? ? ? ?
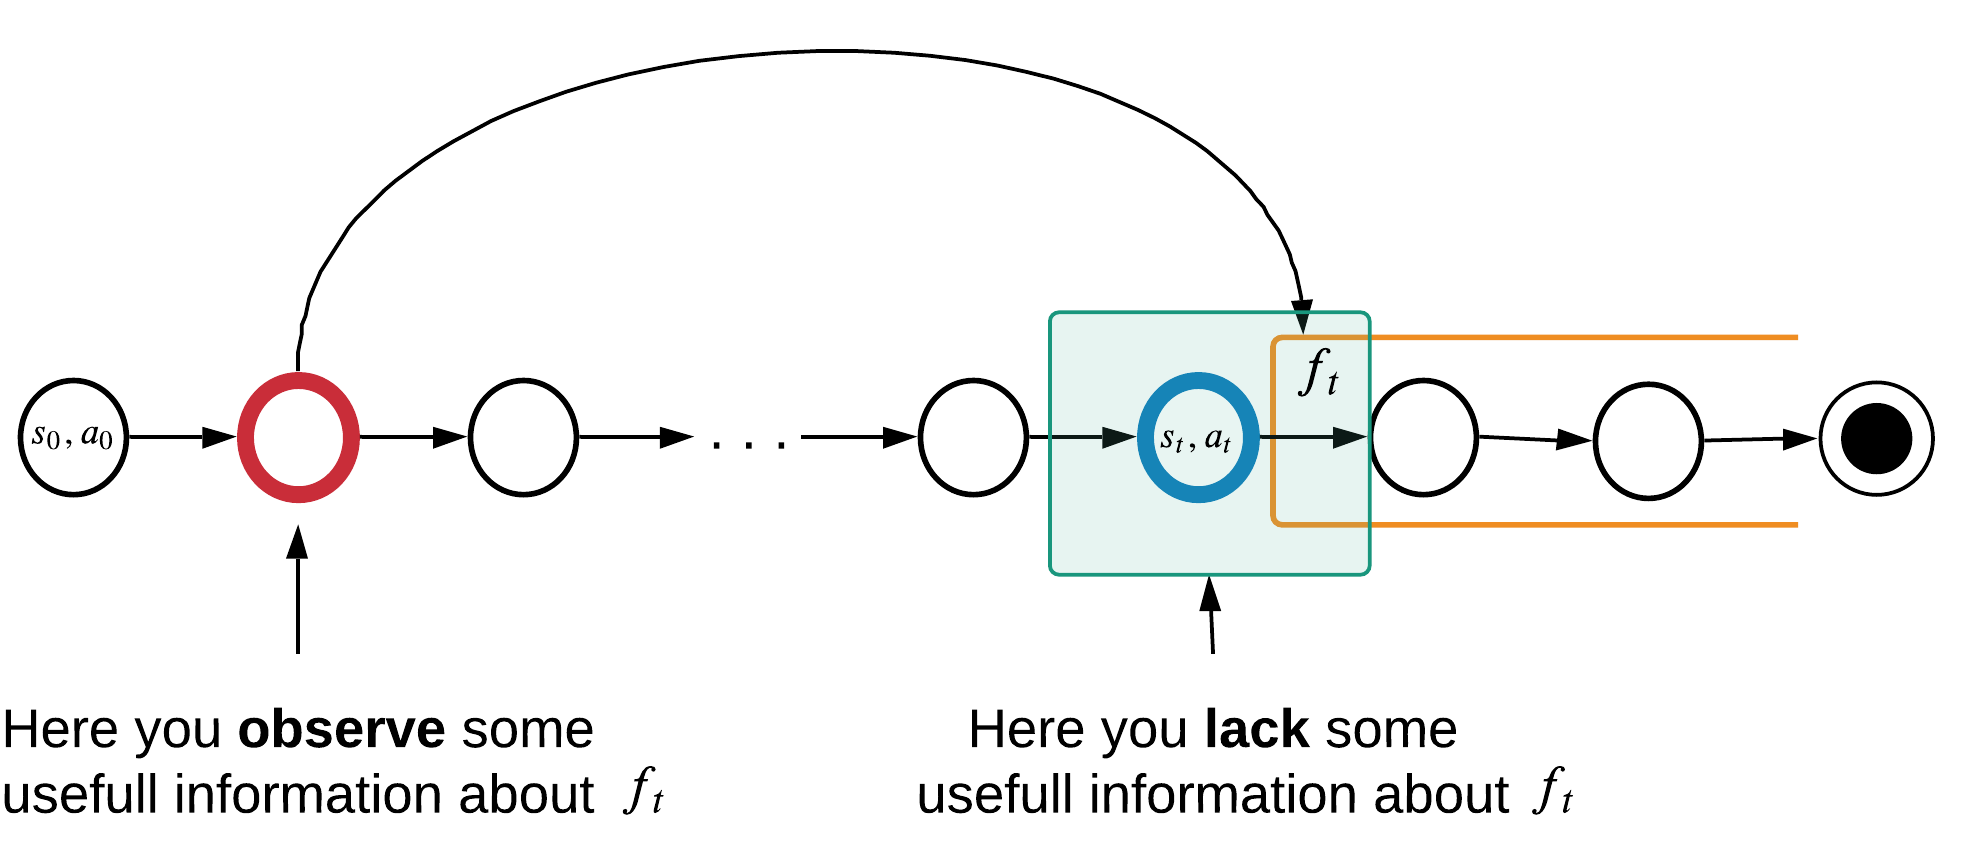
What if we could detect temporal dependencies locally?
Temporal dependency between t-1 and t+k
Idea: long version
Can we find temporal dependencies locally?
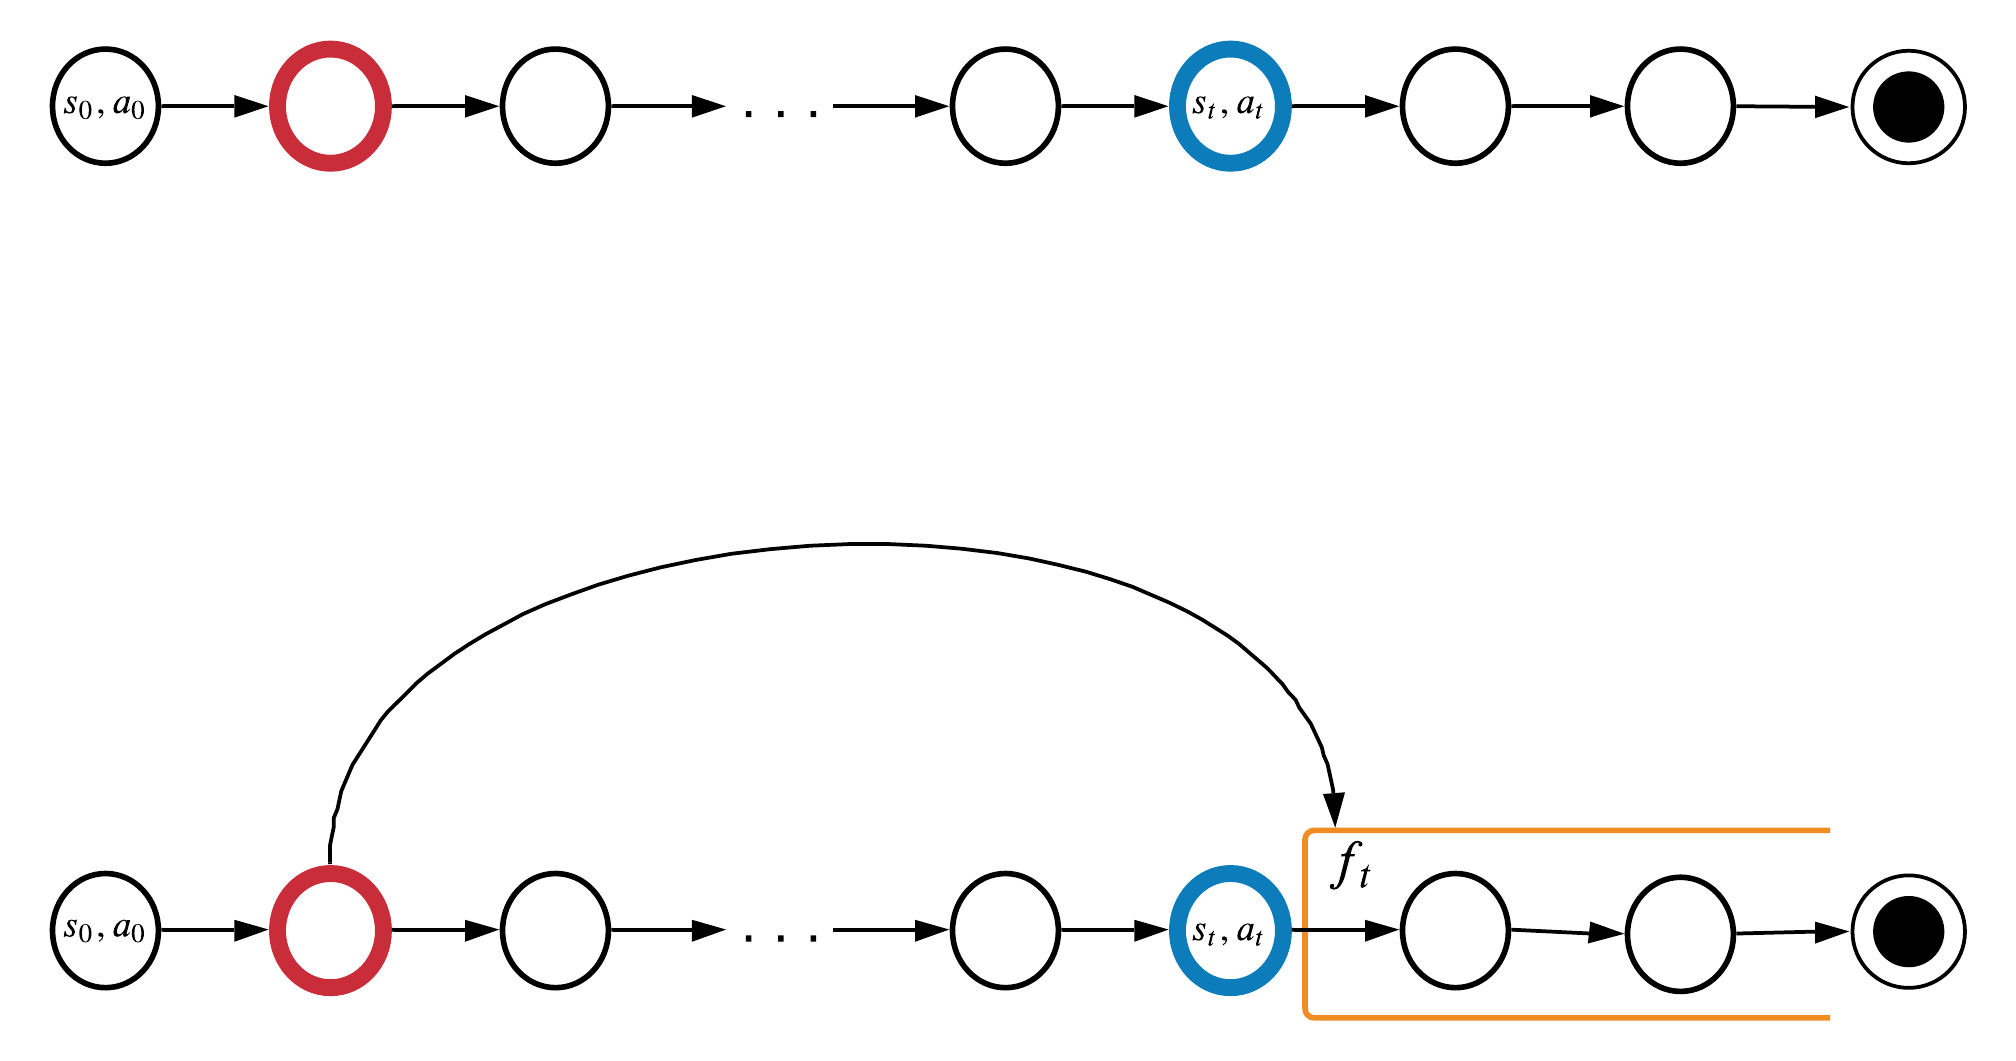
Information from red timestep could help at blue timestep.
Markov property doesn't work for these timesteps:
P(y_{t}|\textcolor{blue}{x_t}, \textcolor{red}{x_{t-k}}) \ne P(y_{t}|\textcolor{blue}{x_t})
How important it is to remember the red timestep?
\(y_t\) can be Q-value, \(s_{t+1}\), \(r_{t+1}\), etc.
s_0, a_0
s_t, a_t
y_t
Can we find temporal dependencies locally?
Information from red timestep could help at blue timestep.
Markov property doesn't work for these timesteps:
P(f_{t}|\textcolor{blue}{o_t, a_t}, \textcolor{red}{o_{t-k}}) \ne P(f_{t}|\textcolor{blue}{o_t, a_t})
How important it is to remember the red timestep?
\mathbb{E}_{o_t,a_t \sim P(\tau)} D_{KL}[P(f_{t}, \textcolor{red}{o_{t-k}}|\textcolor{blue}{o_t, a_t}) || P(f_{t}|\textcolor{blue}{o_t, a_t})P(\textcolor{red}{o_{t-k}}|\textcolor{blue}{o_t, a_t})]
= I(f_{t} ; \textcolor{red}{o_{t-k}}| \textcolor{blue}{o_t, a_t})
\(f_t\) can be Q-value, \(s_{t+1}\), \(r_{t+1}\), etc.
multiplied by \(P(o_{t-k}| o_t, a_t)\)
s_0, a_0
s_t, a_t
f_t
Memory's Objective
The best memory would maximize the following sum:
\sum_{t=0}^{T} I(f_{t} ; m_t = g_\textcolor{black}{\theta}(o_t, a_t, m_{t-1}) | o_t, a_t)
= \sum_{t=0}^{T} I(f_{t} ; m^{\theta}_t | o_t, a_t)
But training \(m_t\) to maximize Mutual Information (MI) at step \(t\) doesn't help with our problem:
what if at information from step \(t-k\) is already lost at step \(t\)
It is better to optimize the following sum:
\sum_{t=0}^{T} \textcolor{blue}{\sum_{i=t}^{T}}
I(f_\textcolor{blue}{i} ; m^{\theta}_\textcolor{black}{t} | o_\textcolor{blue}{i}, a_\textcolor{blue}{i})
s_0, a_0
s_t, a_t
f_t
Memory's Objective
The best memory would maximize the following sum:
\sum_{t=0}^{T} \sum_{k=t}^{T} I(y_{k} ; m_t = g_\textcolor{black}{\theta}(x_t, m_{t-1}) | x_k)
= \sum_{t=0}^{T} \sum_{k=t}^{T} I(y_{k} ; m^{\theta}_t | x_k)
But training \(m_t\) to maximize Mutual Information (MI) at step \(t\) doesn't help with our problem:
what if at information from step \(t-k\) is already lost at step \(t\)
It is better to optimize the following sum:
\sum_{t=0}^{T} \textcolor{blue}{\sum_{i=t}^{T}}
I(f_\textcolor{blue}{i} ; m^{\theta}_\textcolor{black}{t} | o_\textcolor{blue}{i}, a_\textcolor{blue}{i})
s_0, a_0
s_t, a_t
f_t
Memory's Objective
Train memory to maximize MI for all future steps:
\(O(T^2)\) in time!
Idea:
Instead of optimizing the whole second sum it would be cheaper to optimize w.r.t. to the moments where memory is the most important for model's predictions!
\sum_{t=0}^{T} \textcolor{blue}{\sum_{i=t}^{T}}
I(f_\textcolor{blue}{i} ; m^{\theta}_\textcolor{black}{t} | o_\textcolor{blue}{i}, a_\textcolor{blue}{i})
still requires to process full sequence to update \(m_t\)
- Not all future events depends on all information from the past
- Not all \(I(f_\textcolor{blue}{i} ; m_\textcolor{black}{t} | o_\textcolor{blue}{i}, a_\textcolor{blue}{i})\) are created equal!
Locality of Reference
Finding Important Moments
how important memory can be in \(f_t\) prediction
If \(H(f_{t}|m_{t}^*, o_{t}, a_{t})\) doesn't fluctuate as much as \(H(f_{t}| o_{t}, a_{t})\), e.g. \(H(f_{t}|m_{t}^*, o_{t}, a_{t}) = c\) for any \(t\)
\textcolor{black}{\sum_{t=0}^{T}}
I(f_\textcolor{black}{t} ; m^\textcolor{black}{*}_t | o_\textcolor{black}{t}, a_\textcolor{black}{t})
\(f_t\) uncertainty without memory
= \textcolor{black}{\sum_{t=0}^{T}} [H(f_\textcolor{black}{t}| o_\textcolor{black}{t}, a_\textcolor{black}{t})
- H(f_\textcolor{black}{t}|m^*, o_\textcolor{black}{t}, a_\textcolor{black}{t})]
\(f_t\) uncertainty with perfect memory
Then \(I(f_{t} ; m_{t}^* | o_{t}, a_{t})\) is proportional to \(H(f_t|o_t, a_t)\)
Goal: Find moments where memory is the most important for model's predictions!
specify how much memory from step \(t\) can improve prediction.
Problem: To find steps were memory is useful we first need to have a useful memory :(
Let's assume we have a perfect memory \(m^{*}_t\)! Then:
I(f_{i} ; m^{\theta}_t | o_{i}, a_{i})
Resume
Train memory to maximize MI at moments that would benefit the most from using memory:
where \(U_t\) is a set of steps with the highest ; \(|U| \ll T\)
\sum_{t=0}^{T} \textcolor{green}{\sum_{k \in U_t}}
I(f_\textcolor{green}{k} ; m^{\theta}_\textcolor{black}{t} | o_\textcolor{green}{k}, a_\textcolor{green}{k})\,,
Before:
After:
Train memory to maximize MI for all future steps:
\sum_{t=0}^{T} \textcolor{blue}{\sum_{k=t}^{T}}
I(f_\textcolor{blue}{k} ; m^{\theta}_\textcolor{black}{t} | o_\textcolor{blue}{k}, a_\textcolor{blue}{k})
\hat{H}_\textcolor{green}{\psi}(f_\textcolor{black}{i} | o_\textcolor{black}{i}, a_\textcolor{black}{i})
max_\theta \textcolor{blue}{\sum_{k=t}^{T}}
I(y_\textcolor{blue}{k} ; m^{\theta}_\textcolor{black}{t} | x_\textcolor{blue}{k})
Idea: short version
memory potential:
how important memory can be in \(f_t\) prediction
If \(H(f_{t}|m_{t}^*, o_{t}, a_{t})\) doesn't fluctuate as much as \(H(f_{t}| o_{t}, a_{t})\), e.g. \(H(f_{t}|m_{t}^*, o_{t}, a_{t}) = c\) for any \(t\)
\(f_t\) uncertainty without memory
\(f_t\) uncertainty with a perfect memory
Then \(I(f_{t} ; m_{t}^* | o_{t}, a_{t})\) is proportional to \(H(f_t|o_t, a_t)\)
Imagine we have a perfect memory state \(m^*_t\) for each t!
Local Metric: Conditional mutual Information
Can we find temporal dependencies locally?
I(f_\textcolor{black}{t} ; m^\textcolor{black}{*}_t | o_\textcolor{black}{t}, a_\textcolor{black}{t})
= H(f_\textcolor{black}{t}| o_\textcolor{black}{t}, a_\textcolor{black}{t})
- H(f_\textcolor{black}{t}|m^*_t, o_\textcolor{black}{t}, a_\textcolor{black}{t})
detects the end of a temporal dependency
find ends of temporal dependencies by estimating this
memory potential:
how important memory can be in \(f_t\) prediction
If \(H(f_{t}|m_{t}^*, o_{t}, a_{t})\) doesn't fluctuate as much as \(H(f_{t}| o_{t}, a_{t})\), e.g. \(H(f_{t}|m_{t}^*, o_{t}, a_{t}) = c\) for any \(t\)
\(f_t\) uncertainty without memory
\(f_t\) uncertainty with a perfect memory
Then \(I(f_{t} ; m_{t}^* | o_{t}, a_{t})\) is proportional to \(H(f_t|o_t, a_t)\)
Imagine we have a perfect memory state \(m^*_t\) for each t!
Local Metric: Conditional mutual Information
Can we find temporal dependencies locally?
I(f_\textcolor{black}{t} ; m^\textcolor{black}{*}_t | o_\textcolor{black}{t}, a_\textcolor{black}{t})
= H(f_\textcolor{black}{t}| o_\textcolor{black}{t}, a_\textcolor{black}{t})
- H(f_\textcolor{black}{t}|m^*_t, o_\textcolor{black}{t}, a_\textcolor{black}{t})
detects the end of a temporal dependency
find ends of temporal dependencies by estimating this
Memory's Objective
Train memory to maximize MI at moments that would benefit the most from using memory:
where \(U_t\) is a set of steps with the highest
\sum_{t=0}^{T} \textcolor{green}{\sum_{k \in U_t}}
I(f_\textcolor{green}{k} ; m_\textcolor{black}{t} = g_\textcolor{blue}{\theta}(o_t, a_t, m_{t-1}) | o_\textcolor{green}{k}, a_\textcolor{green}{k})\,,
Given lower bound from Barber, Agakov (2004) you can show that training
with Cross-Entropy Loss is enough to Maximize MI
\hat{H}_\textcolor{blue}{\psi}(f_\textcolor{black}{i} | o_\textcolor{black}{i}, a_\textcolor{black}{i})
\hat{f}_k = q_\textcolor{blue}{\phi}(g_\textcolor{blue}{\theta}(o_t,a_t, m_{t-1}), o_k, a_k)
simply learn to predict \(f_k\) from \(U_t\) steps
Long-Term memory objective
Train memory to maximize MI at moments that would benefit the most from using memory:
where \(U_t\) is a set of steps with the highest
\sum_{t=0}^{T} \textcolor{green}{\sum_{k \in U_t}}
I(f_\textcolor{green}{k} ; m_\textcolor{black}{t} = g_\textcolor{blue}{\theta}(o_t, a_t, m_{t-1}) | o_\textcolor{green}{k}, a_\textcolor{green}{k})\,,
Given lower bound from Barber, Agakov (2004) you can show that training
with Cross-Entropy Loss is enough to Maximize MI
\hat{H}_\textcolor{blue}{\psi}(f_\textcolor{black}{i} | o_\textcolor{black}{i}, a_\textcolor{black}{i})
\hat{f}_k = q_\textcolor{blue}{\phi}(g_\textcolor{blue}{\theta}(o_t,a_t, m_{t-1}), o_k, a_k)
simply learn to predict \(f_k\) from \(U_t\) steps
Intuition
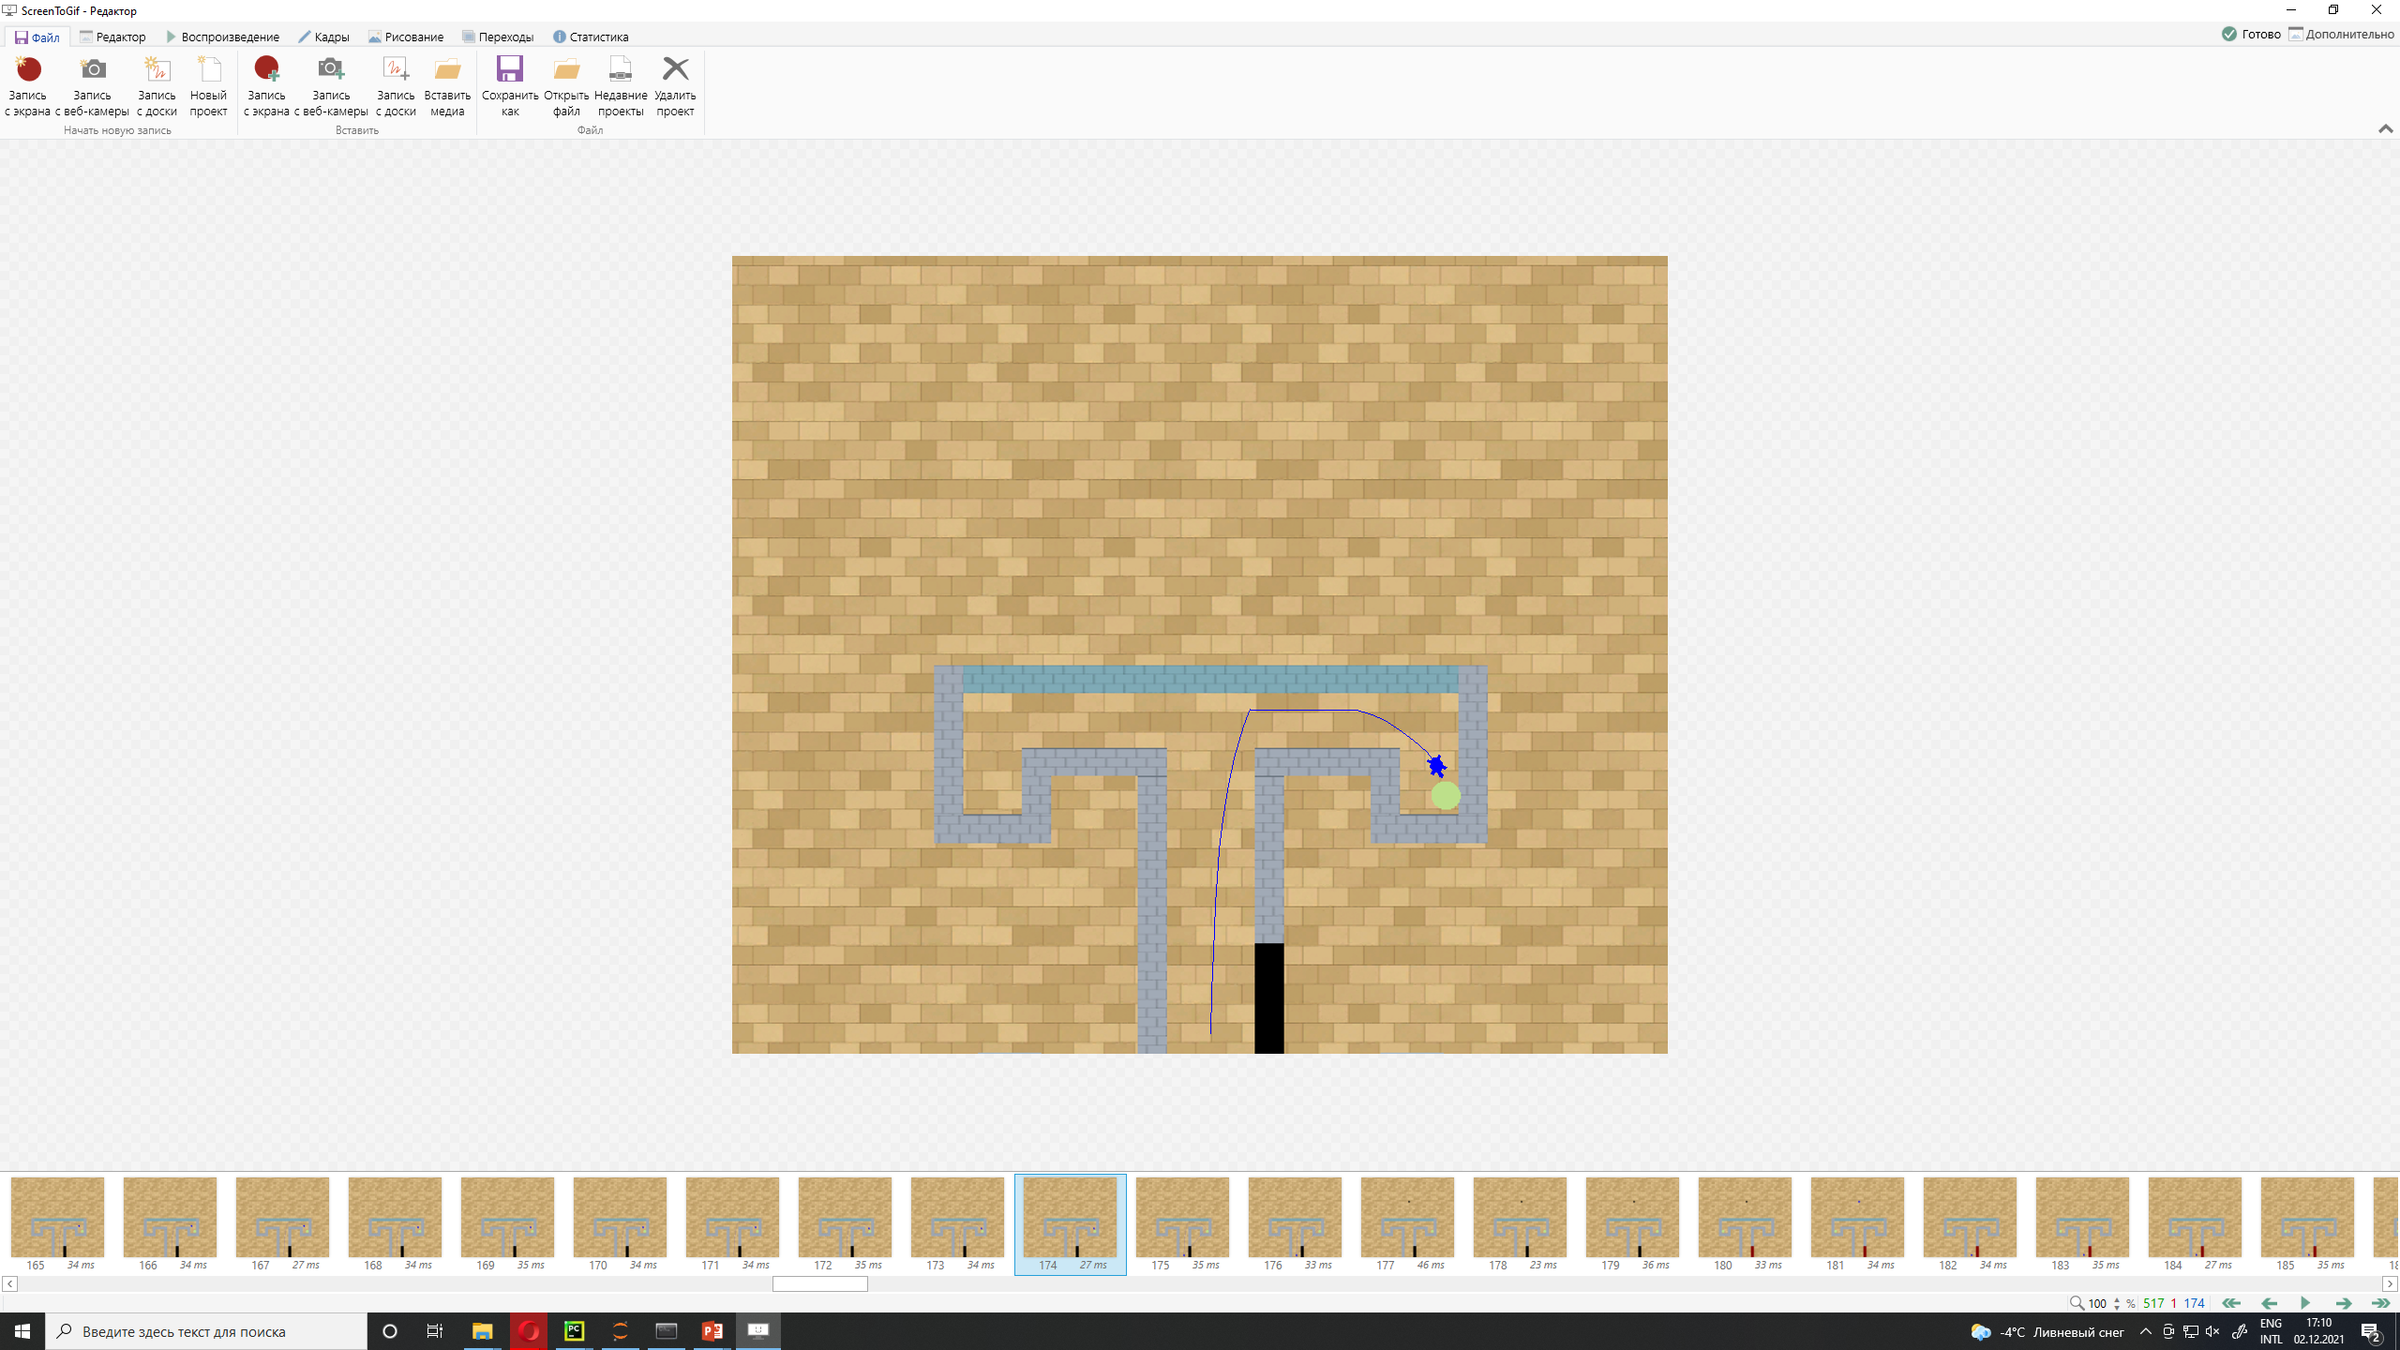
T-Maze Example
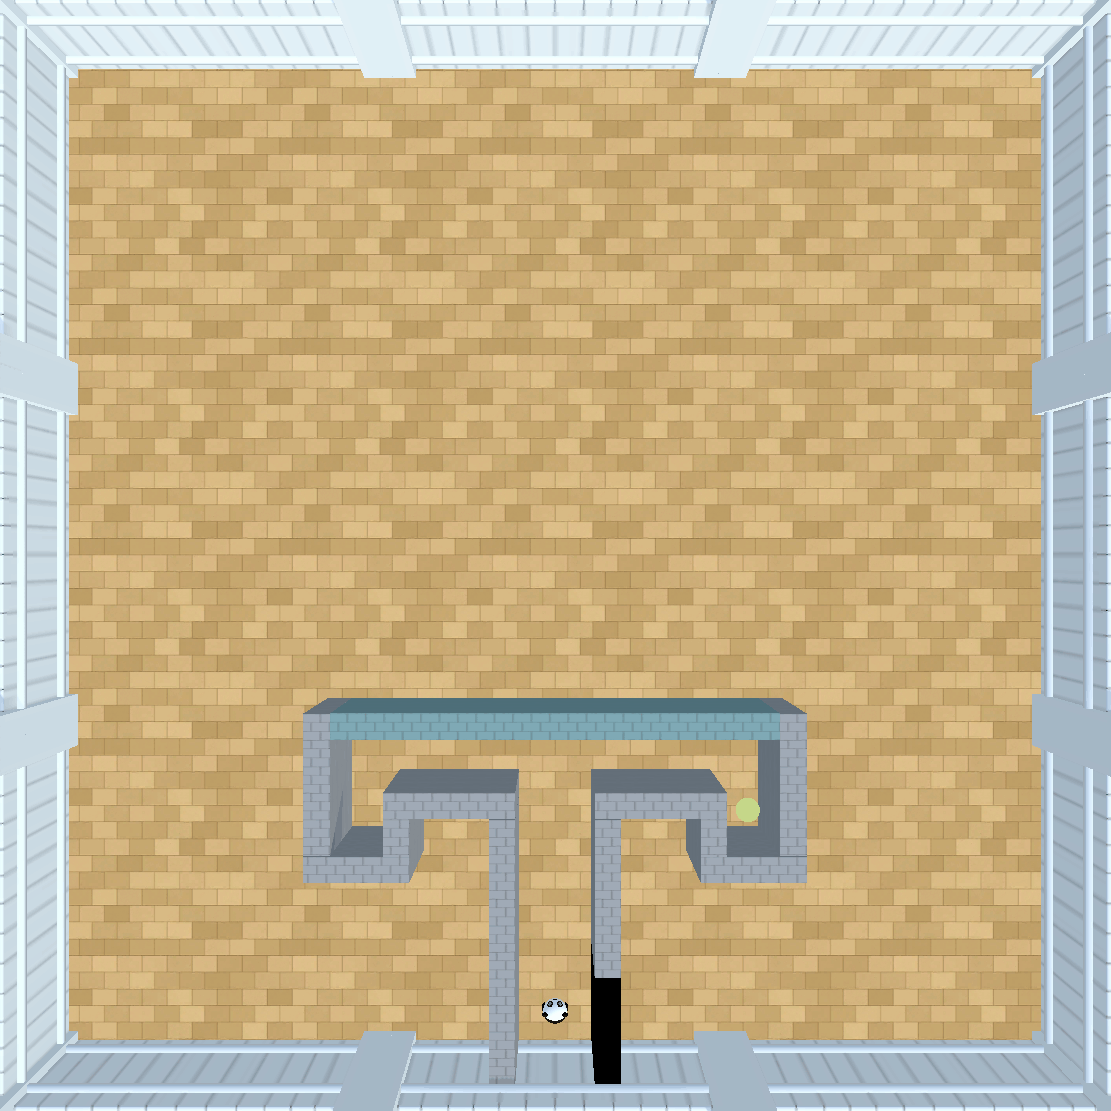
hint: stores information about reward placement
reward
- black wall: reward is on the right
- red wall: reward is on the left
agent panda
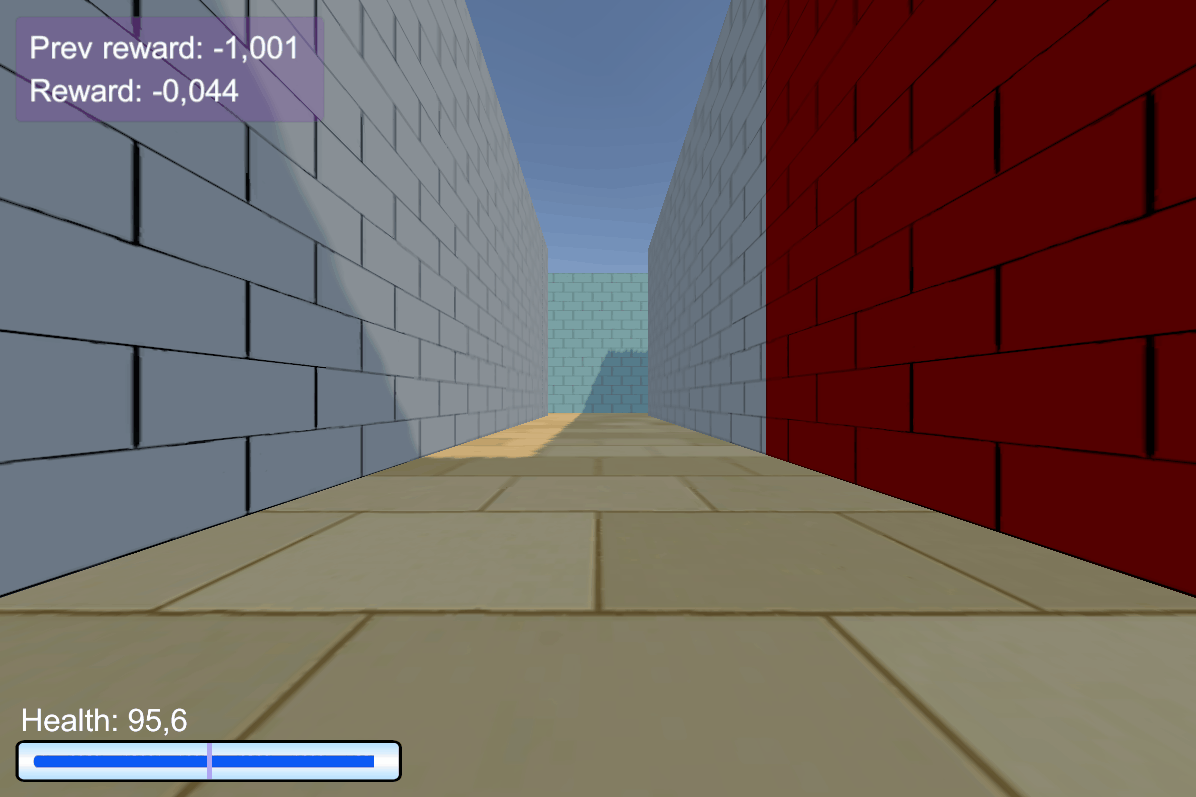
Intuition
Learning Algorithm:
- Estimate Uncertainty for each step in a trajectory
- Select K steps with highest uncertainty
- Traverse trajectory with memory
- Train memory to predict future at selected high uncertainty steps
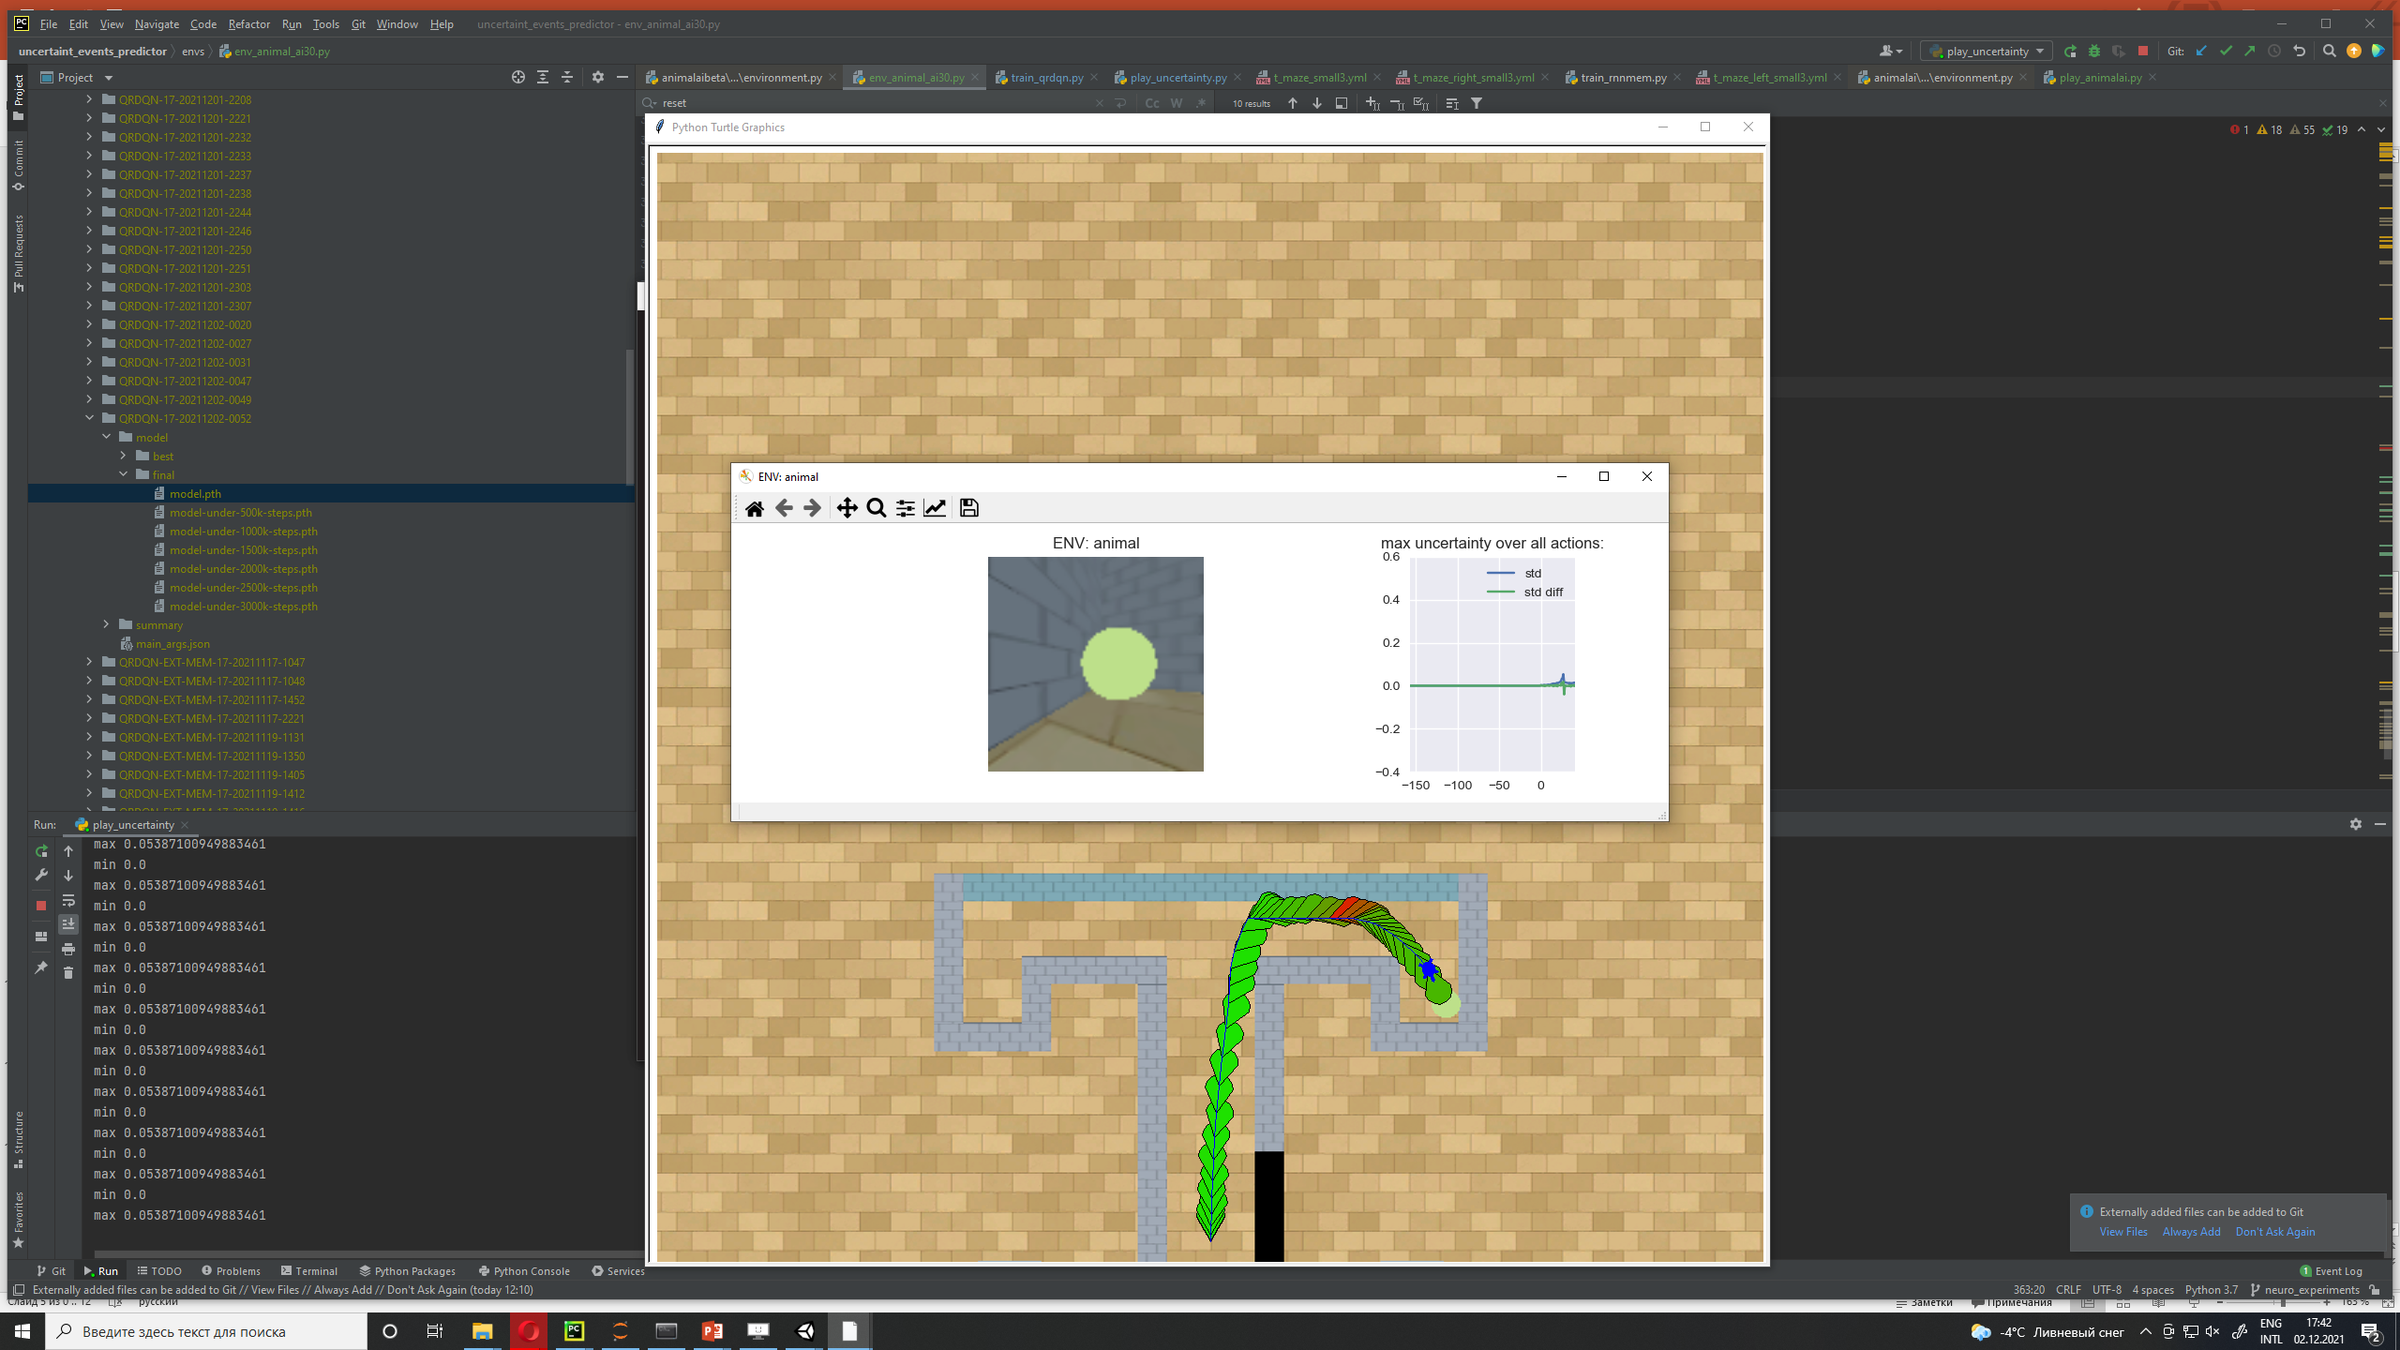
high uncertainty estimate
Uncertainty
detector
Memory
Predictor net
g_{\theta}
q_{\phi}
d_{\psi}
Intuition:
Two main steps:
- First we find the most surprising/uncertain events in a sequence
- Then we search sequence for information that explains these events and store it in memory
this means high uncertainty: \(H(f_i|o_i,a_i)\)
Implementation
Practical Implementation for RNN
Memory Pretraining Modules:
- Uncertainty Detector D - Estimates uncertainty \(H(f_i|o_i, a_i)\)
- Memory Module M - learns to store important information
- Predictor P - used to minimize \(H(f_i| m_t, o_i, a_i)\)/ maximize MI
Learning is divided in two phases:
- Memory Pretraining Phase - we train memory without improving agent's policy
- Policy Learning Phase - We train PPO agent, that receives output of the pretrained memory as an additional input.
We use cumulative discounted future reward as prediction target: \(f_t = \sum_k \gamma^k r_{t+k}\)
Practical Implementation for RNN
- Get estimates of local uncertainty for each time step in the episode
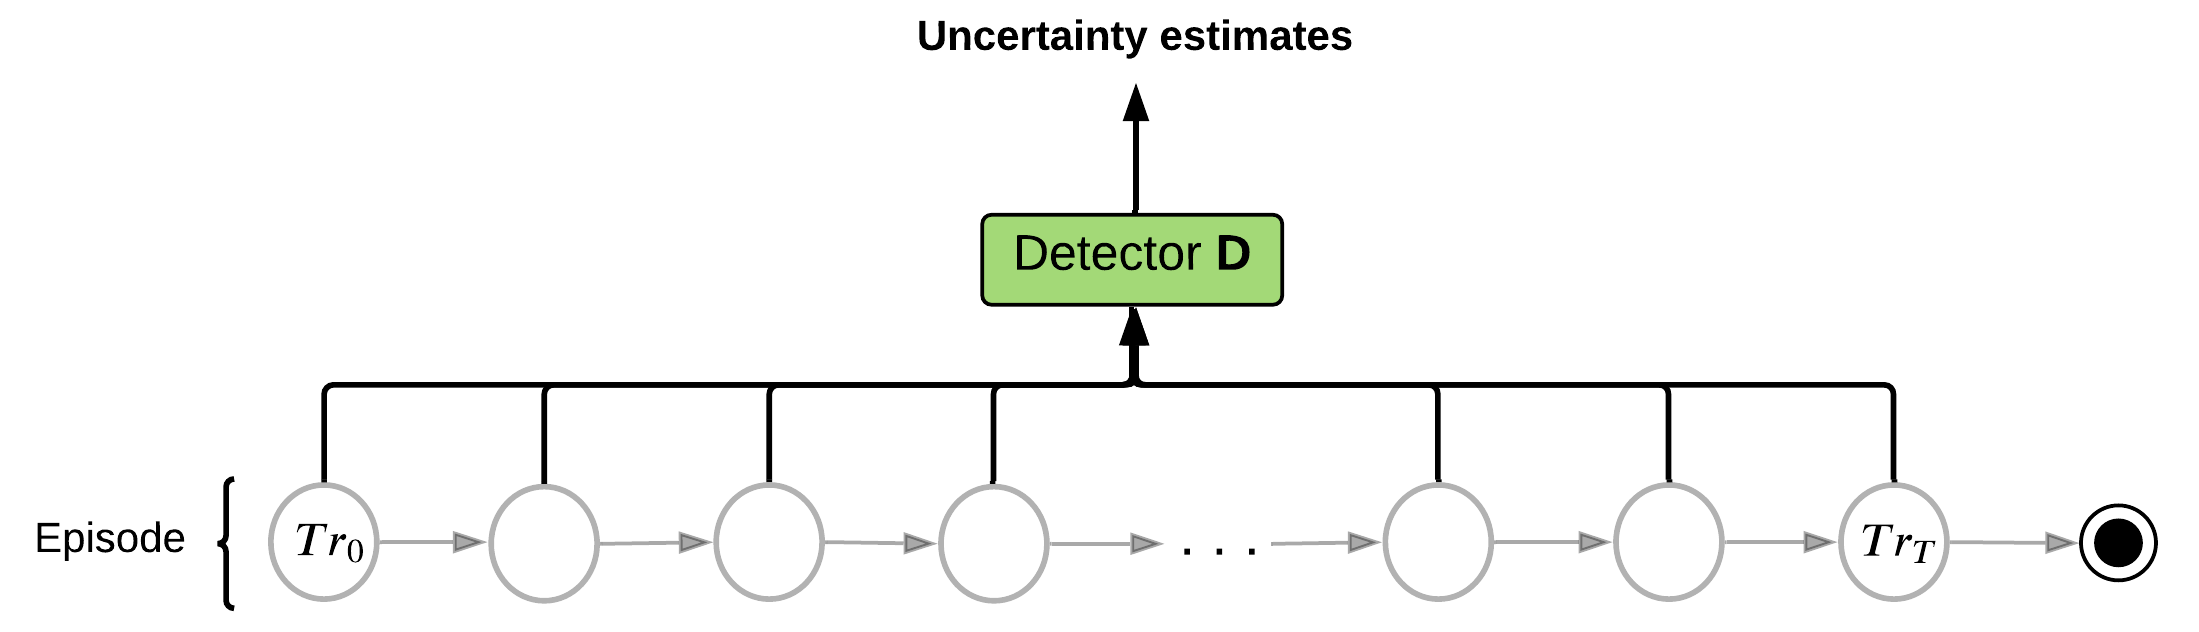
Practical Implementation for RNN
- Get estimates of local uncertainty for each time step in the episode
- Select top K moments in episode with highest uncertainty
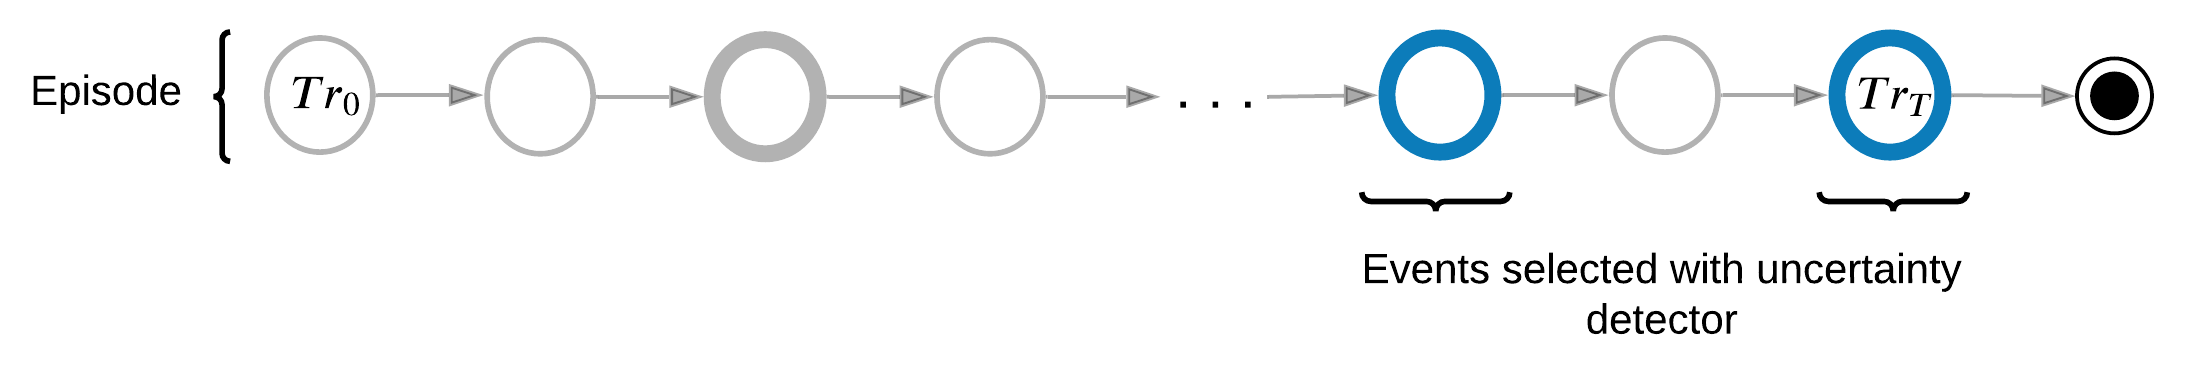
Practical Implementation for RNN
- Get estimates of local uncertainty for each time step in the episode
- Select top K moments in episode with highest uncertainty
- Pass through the episode and train a memory model to store information that improves predictions at the selected moments
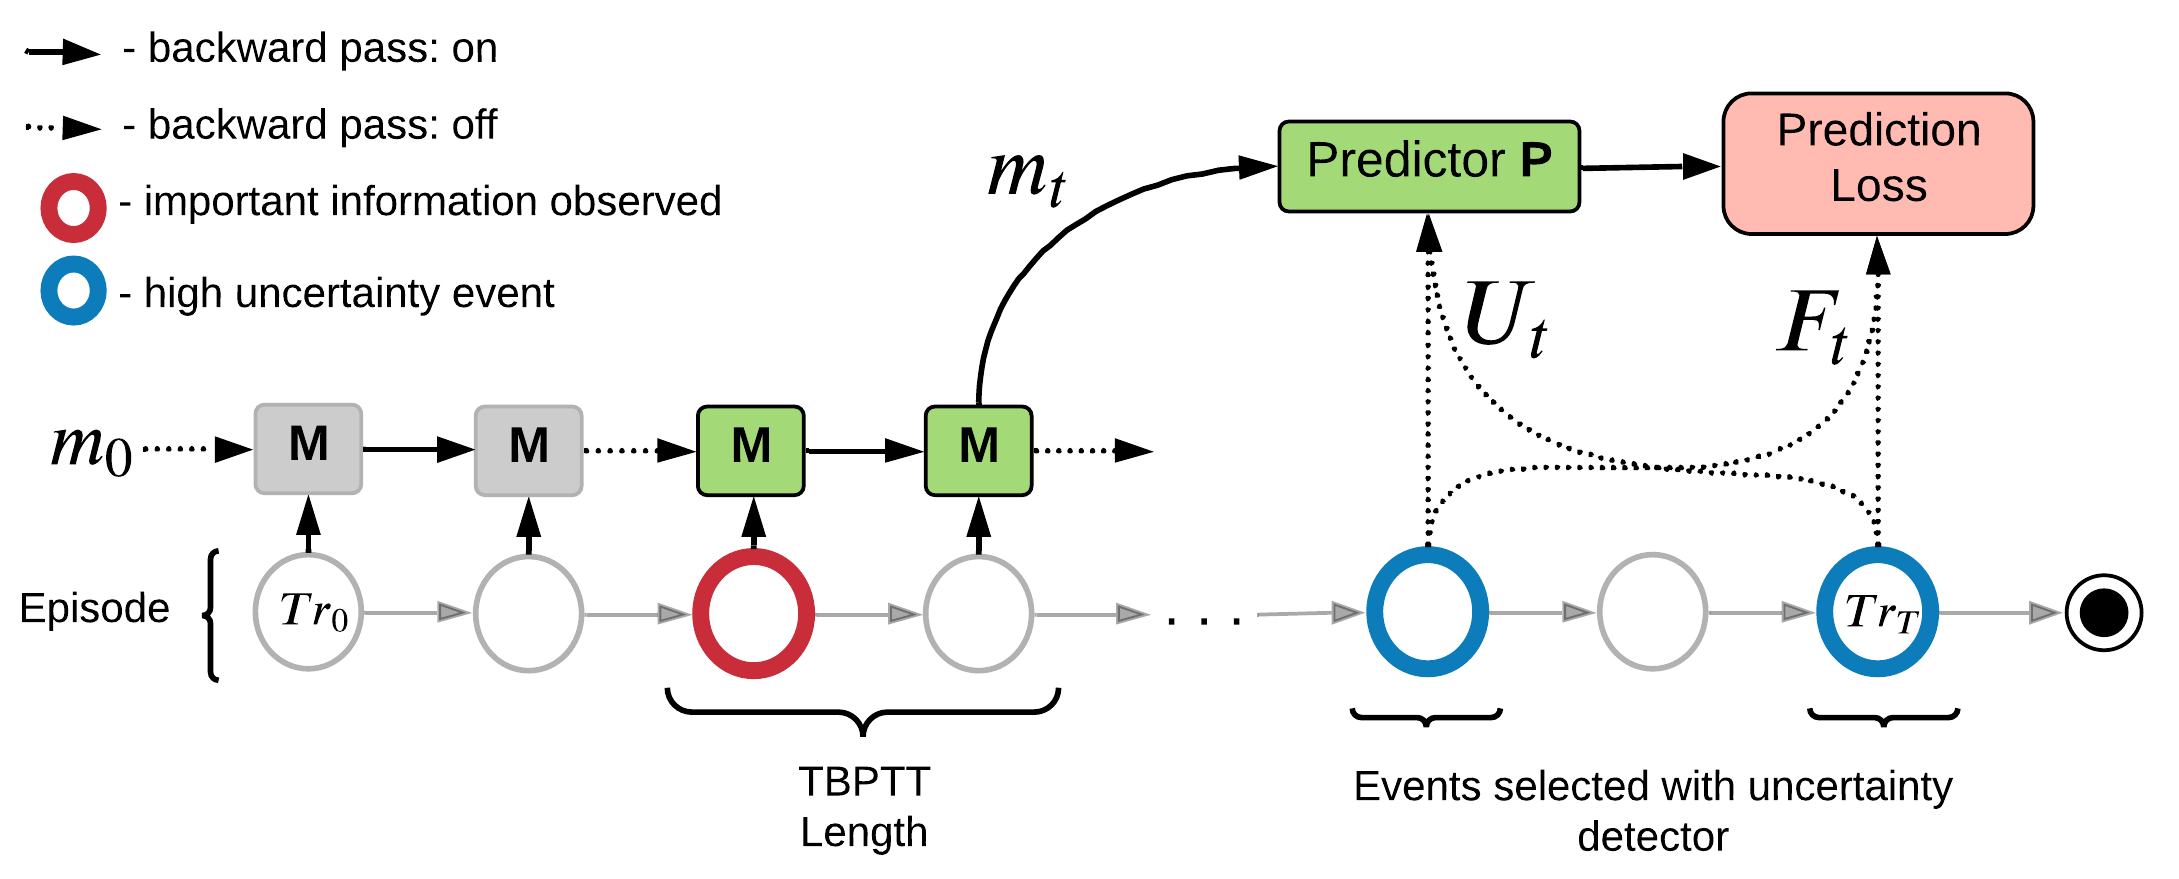
Experiments
Experiments
Baselines
We compare MemUP (Memory via Uncertainty Prediction) with the following baselines:
- PPO-LSTM is a recurrent version of PPO with a single LSTM-layer.
- IMPALA-ST is an IMPALA agent with Transformer-based architecture. The Stabilized Transformer architecture was presented by Parisotto et al. (2020)
-
AMRL is proposed by Beck et al. (2020) for the Noisy T-Maze Task. AMRL
is similar to PPO-LSTM baseline, but extends LSTM with AMRL Layer.
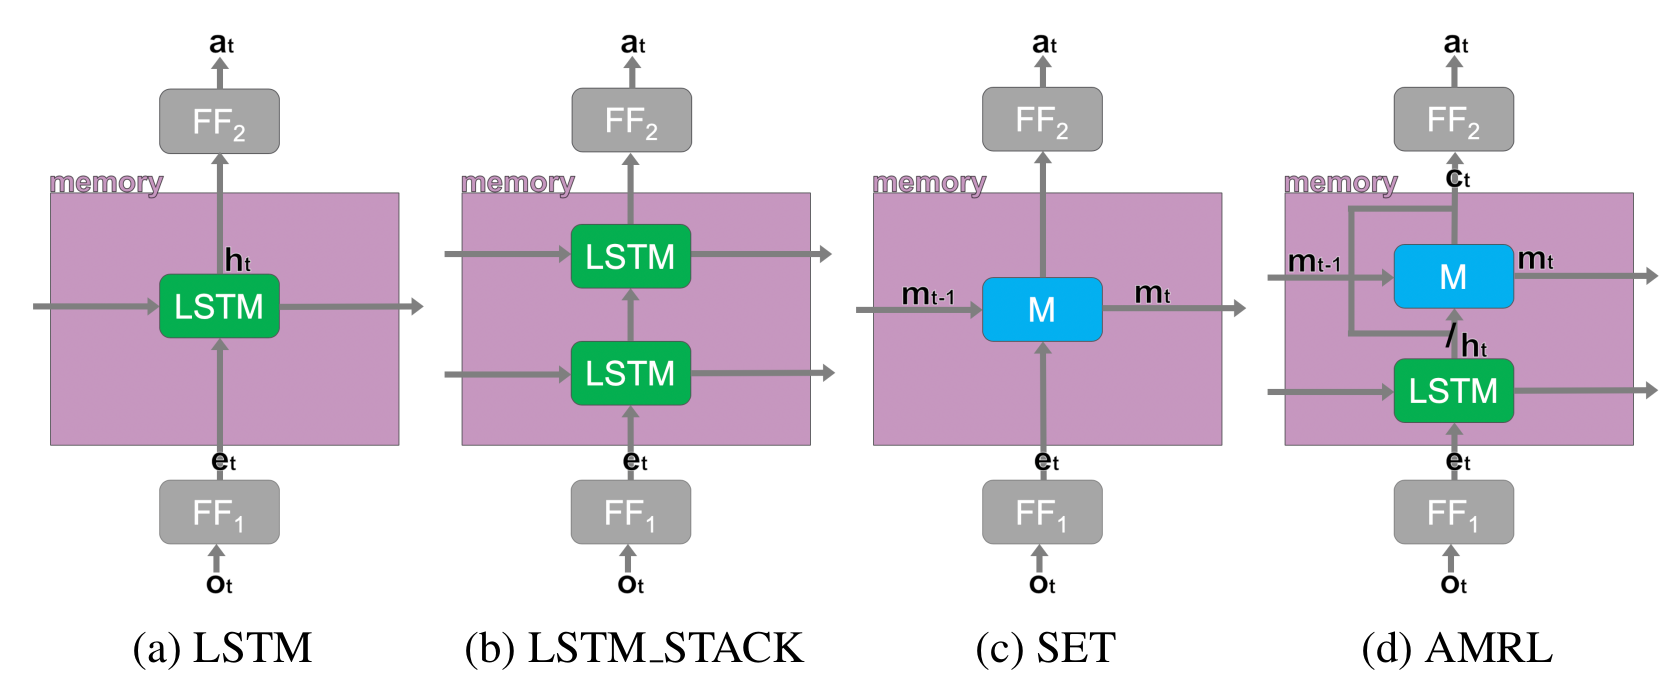
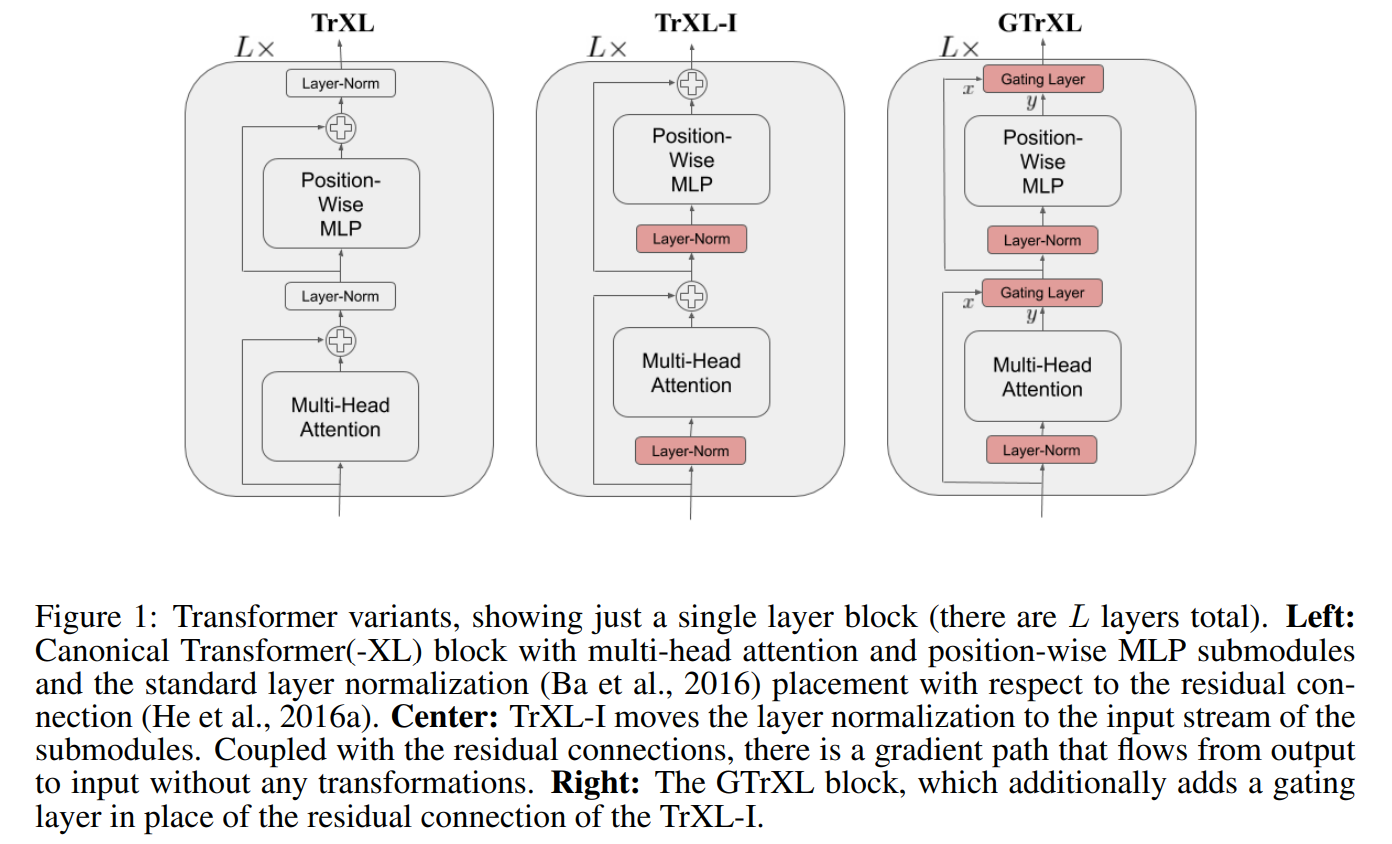
IMPALA-ST
Experiments: Noisy T-Maze
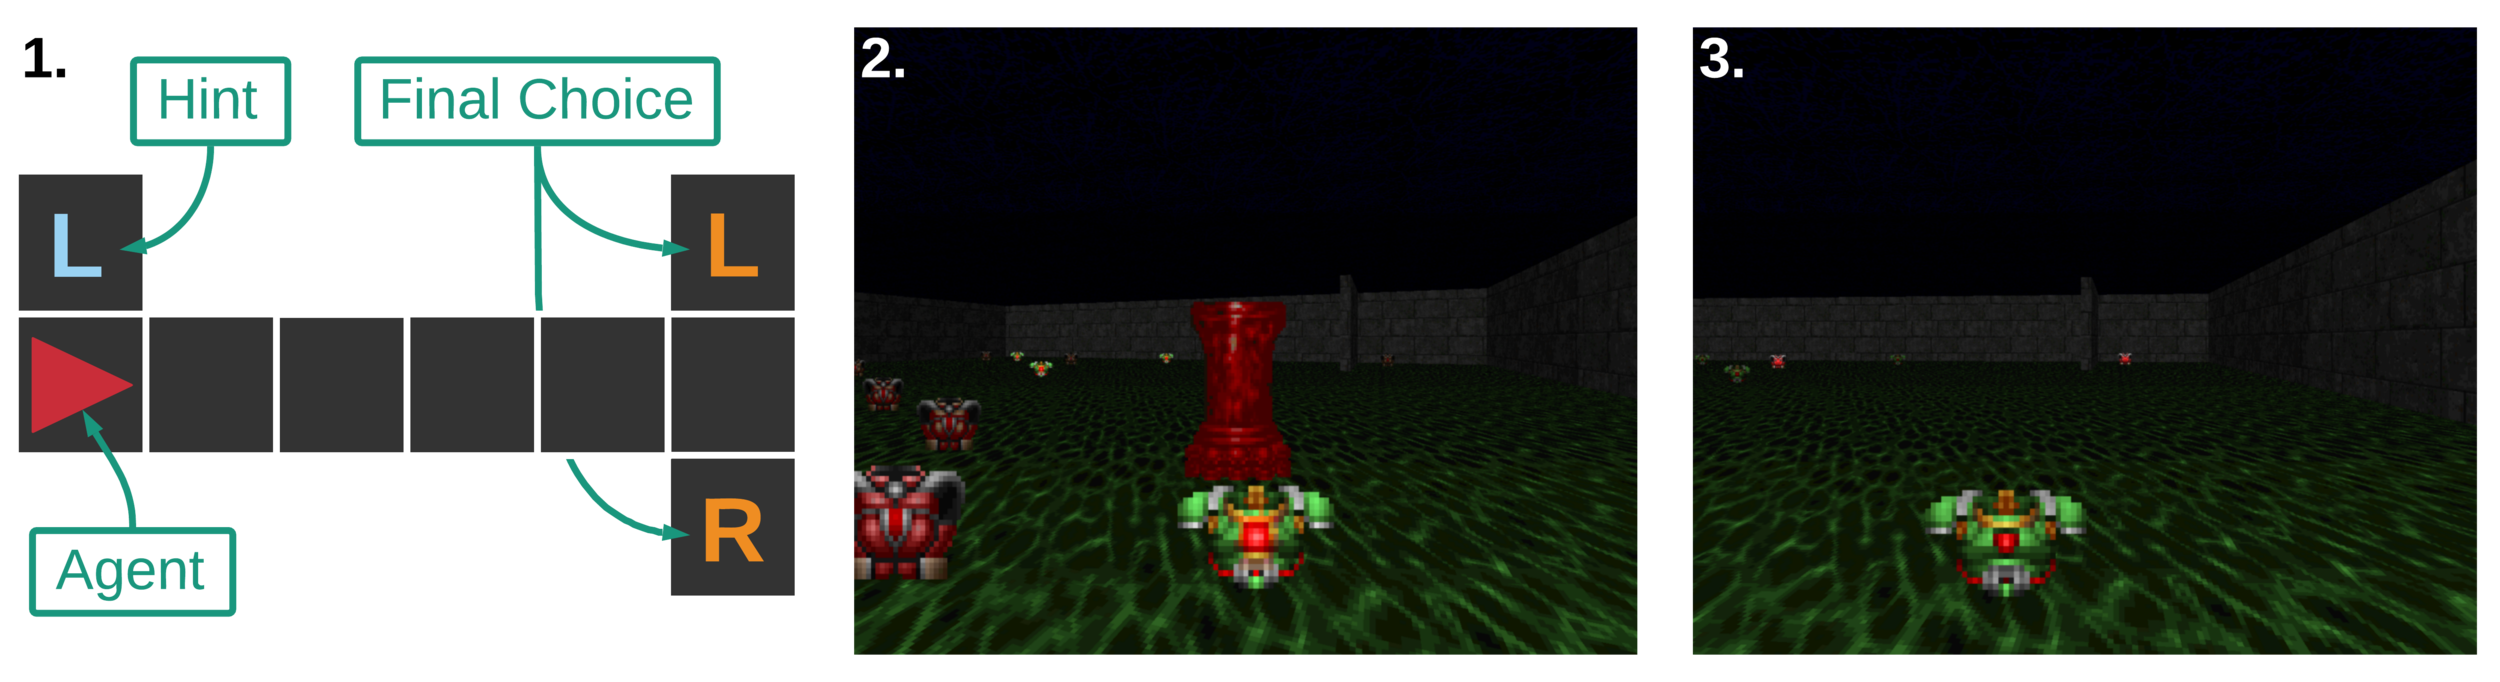
Noisy T-Maze Environment:
- Hard Task in terms of Memory
- Simple Task in every other aspect
Env Details:
- This version was proposed in AMRL paper
- Noisy Observations
- Determine the long-term dependency between hint at the start and reward at the end
- Learn to remember the hint, to achieve maximum reward:
- +4 for matching the hint, -3 otherwise
Experiments: Noisy T-Maze
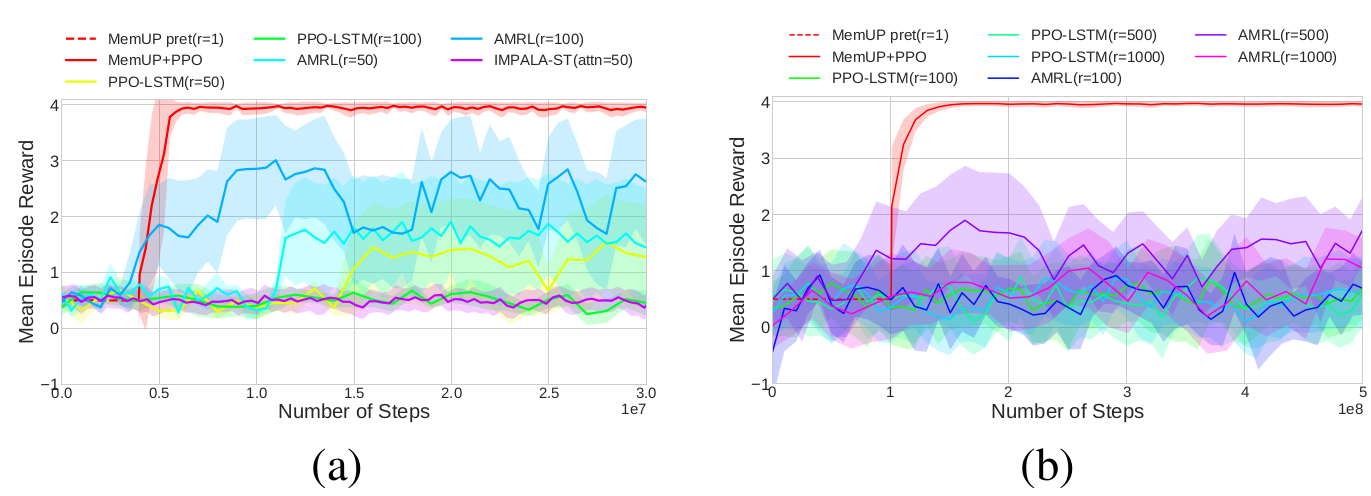
Noisy T-Maze-100
Noisy T-Maze-1000
- All algorithms process sequences shorter than the temporal dependency
- Only MemUp solves the problem consistently
Experiments: Vizdoom
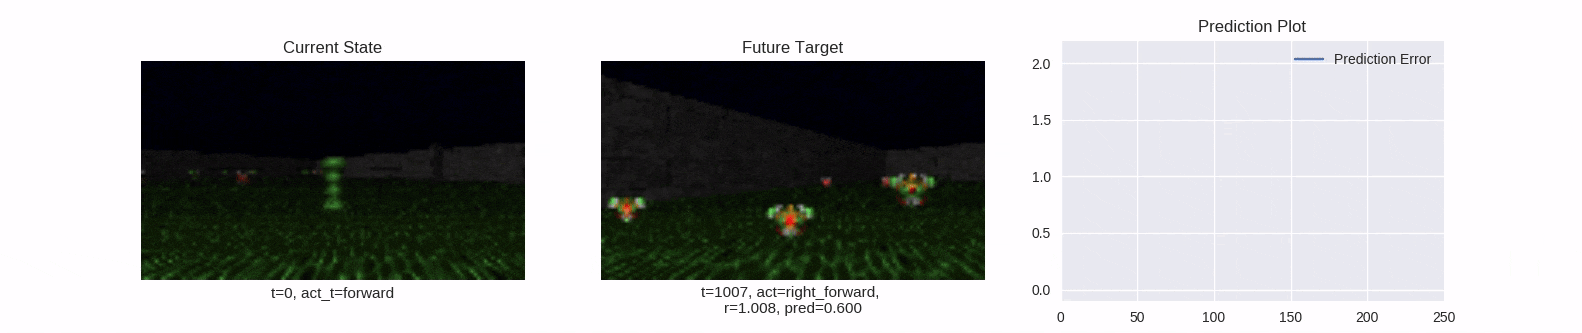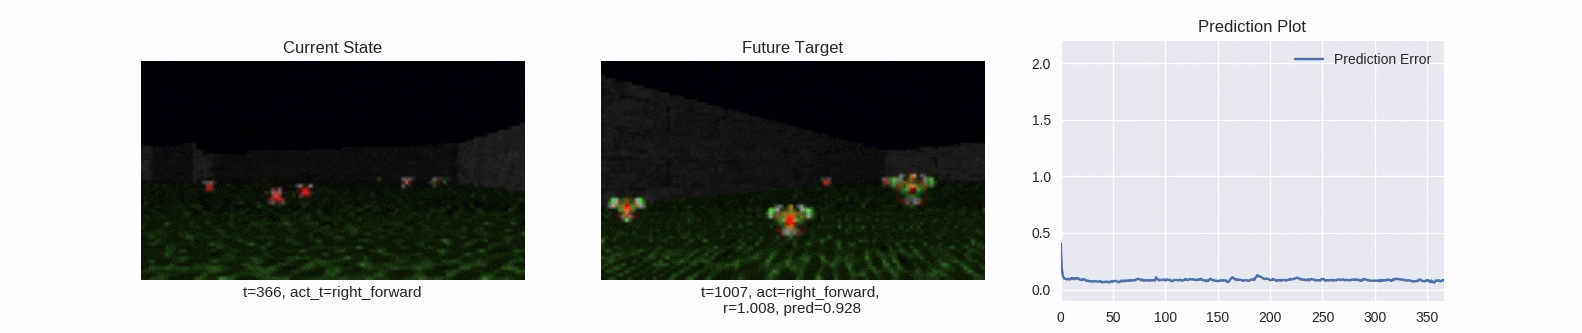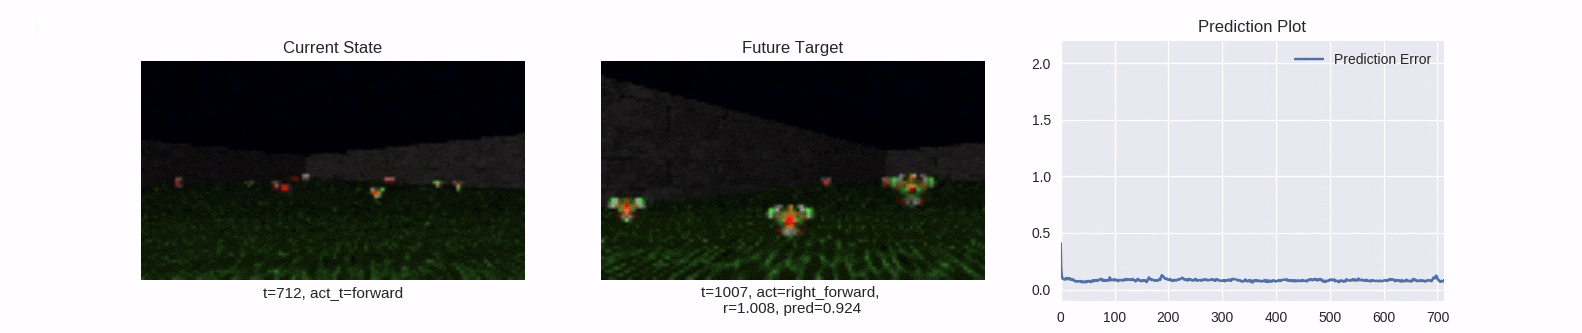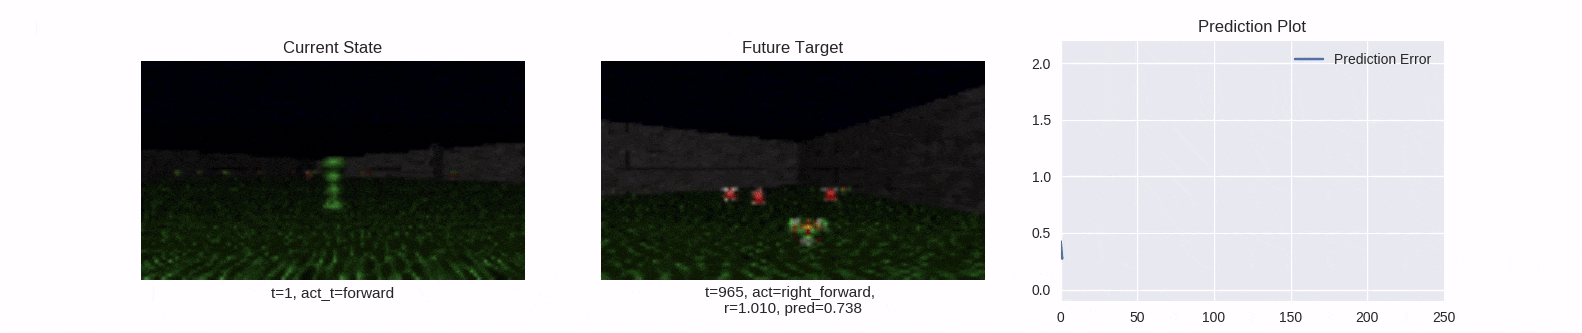
Details:
- Agent walks on acid (-4 health)
- +25 health for objects with a right color, otherwise -25 health
- The column hints the right color of objects
- The column disappears after 45 steps
- +1 reward for the right color, -1 otherwise
ViZDoom-two-colors:
- 3D environment
- Complex observation space
- ~100 steps long temporal dependency
- Proposed in Breeching et al (2019)
Experiments: Vizdoom
Uncertainty Detector Demonstration
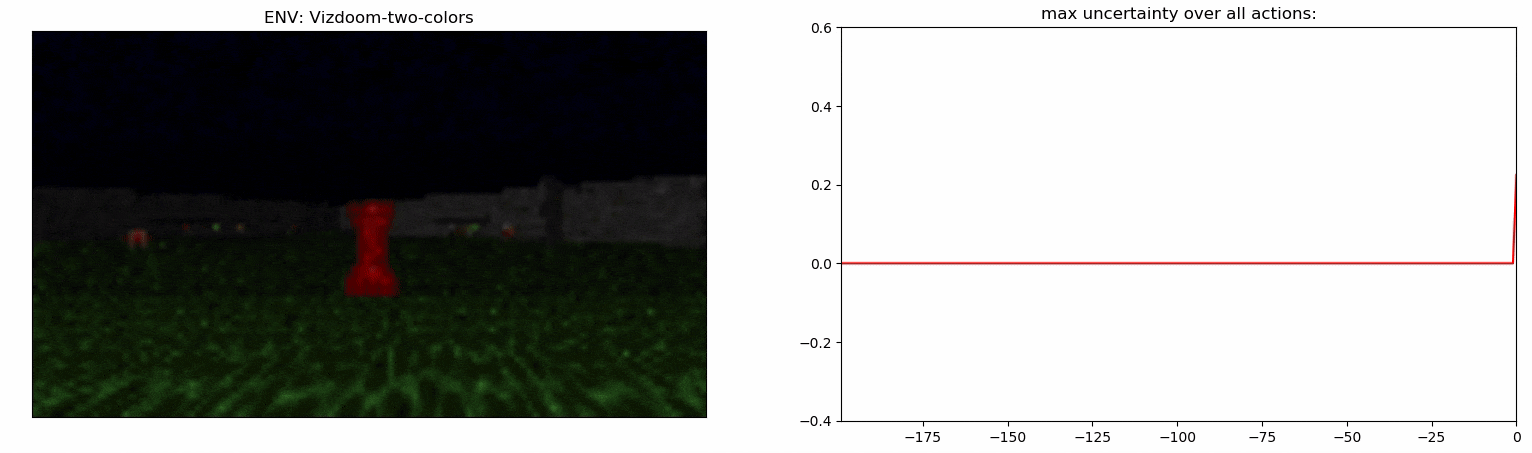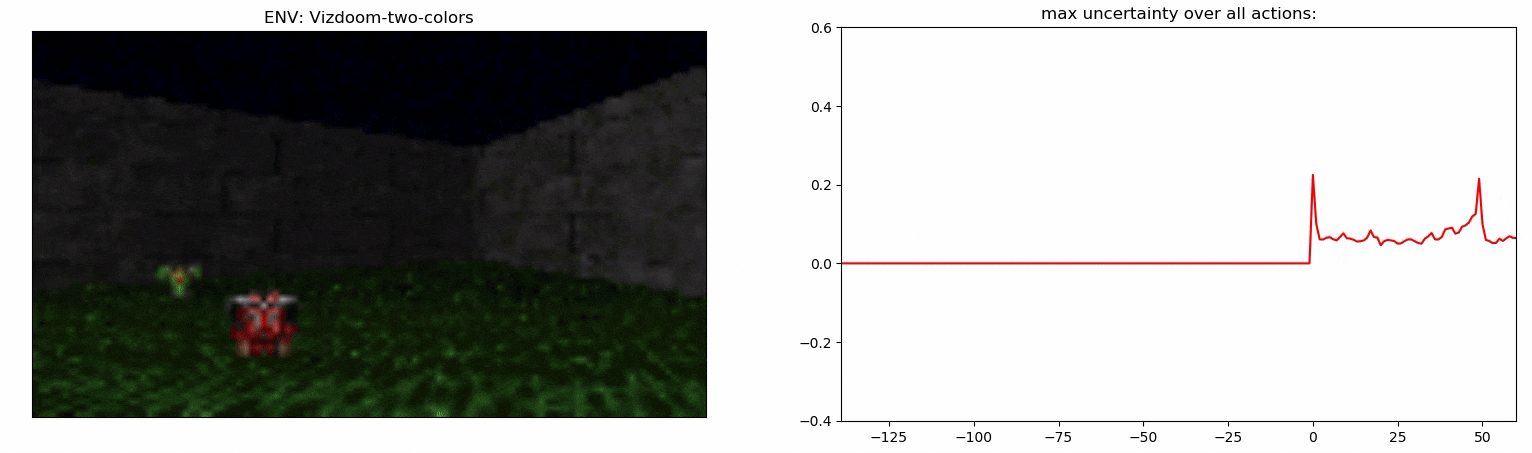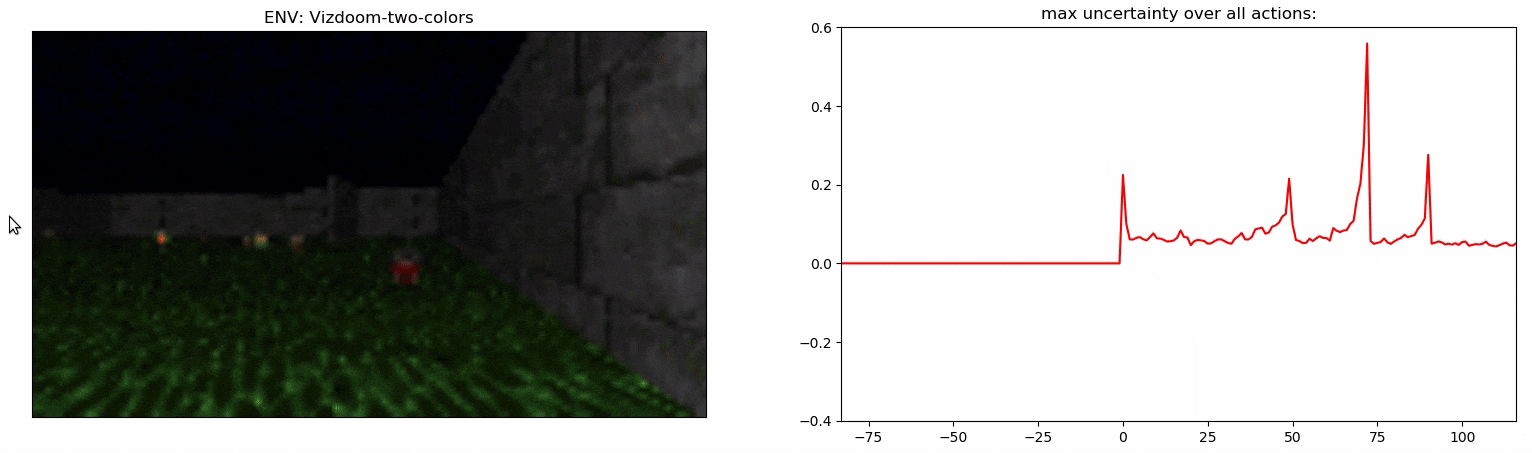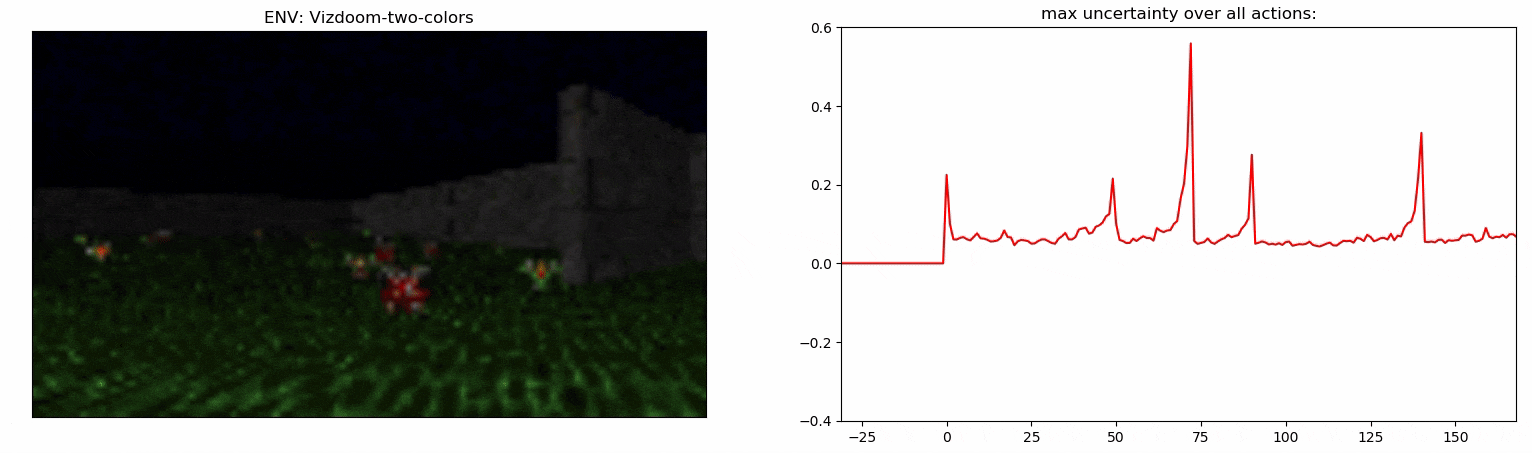
Experiments: Vizdoom
Results
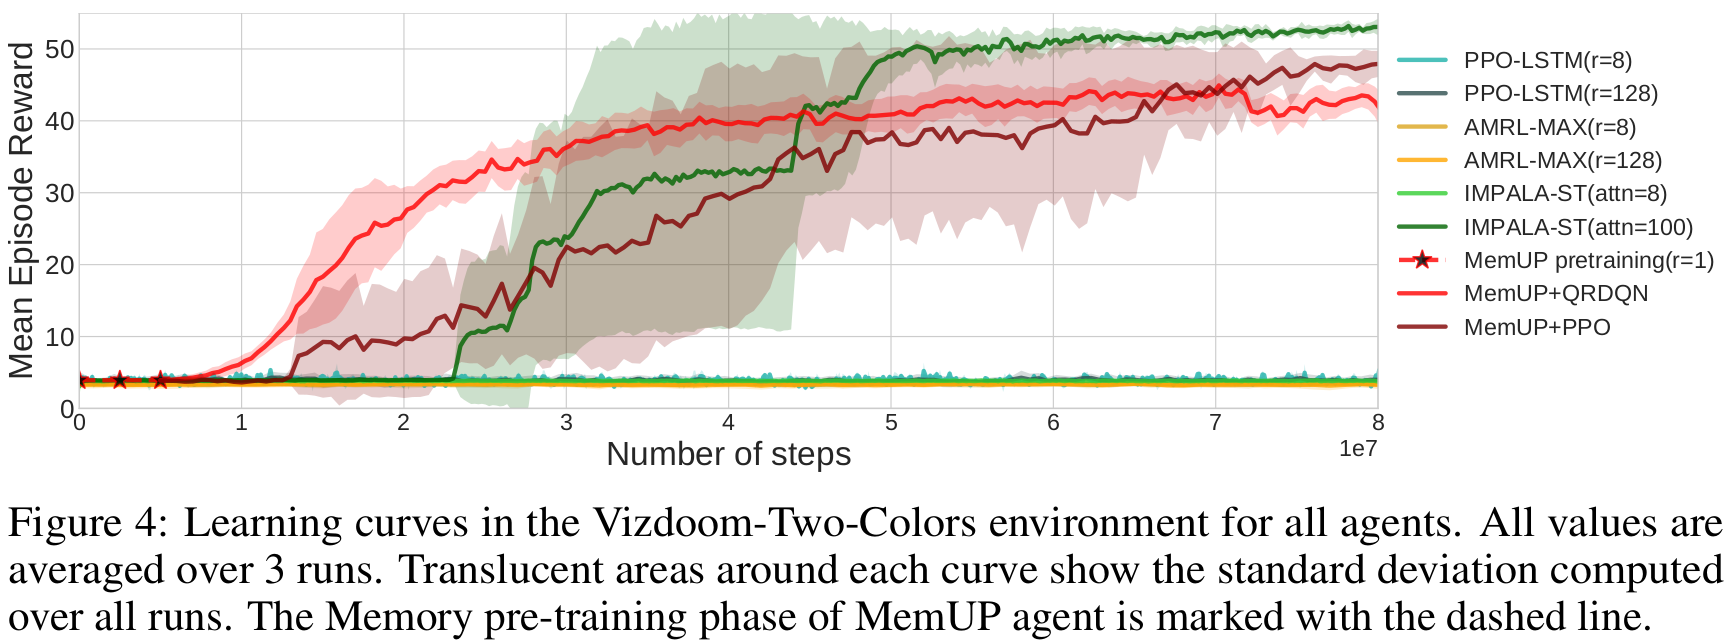
- MemUP solves Vizdoom-Two-Colors
Experiments: Vizdoom
Memory Demonstration
Experiments: Ablation
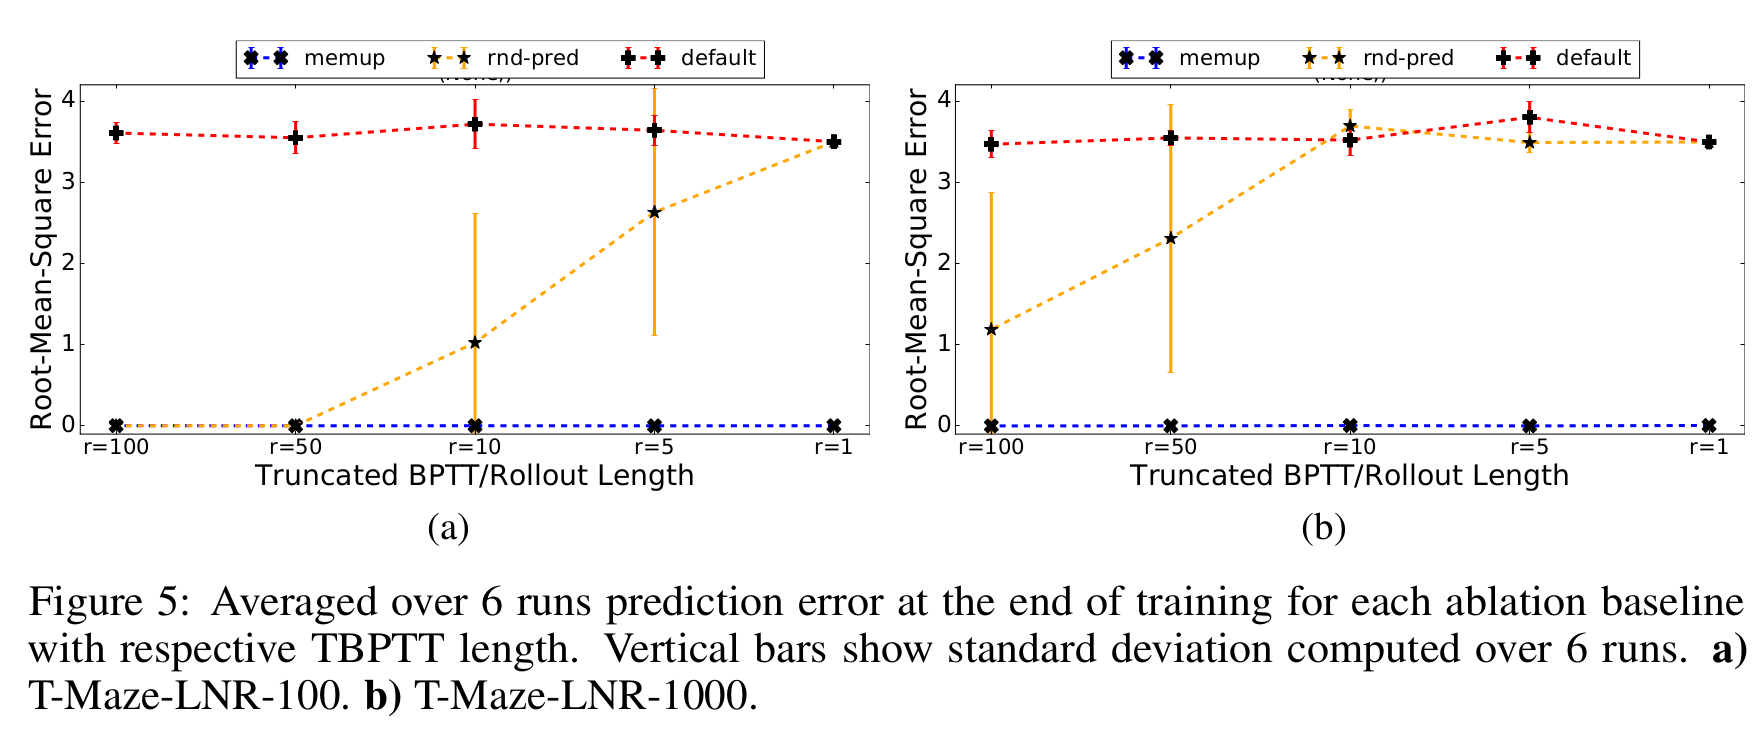
Ablation Baselines
Memory Baselines:
- MemUP - our proposed algorithm
- Rnd-Pred - Same as MemUP, but events for prediction are selected randomly and uniformly among all future timesteps.
- Default - Same as MemUP, but it is trained to predict return R t at each step t, as oposed to an arbitrarily distant future events as in MemUP and Rnd-Pred.
Experiment Setup:
- Noisy T-maze environment, but we ignore policy learning phase
- Baselines are compared in terms of their ability to predict \(f_t\)
- Separate test set of 100 episodes
Experiments: Ablation
Results
Thank you for your attention!
MemUP data Ёлка
By supergriver