Working Memory in RL
Artyom Sorokin
09 July 2022
Memory is Important
in many tasks, but we start from Reinforcement Learning...
Markov Decision Process
Basic Theoretical Results in Model-Free Reinforcement Learning are proved for Markov Decision Processes.
Markovian propery:
In other words: "The future is independent of the past given the present."
p(s_{t+1}, r_{t} | s_t, a_t, s_{t-1}, a_{t-1}, ..., s_{1}, a_{1}, s_{0}) = p( s_{t+1}, r_{t} | s_t, a_t )
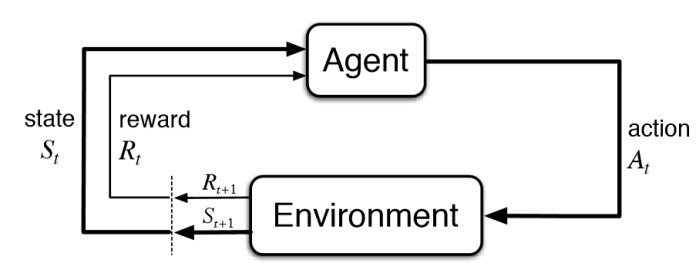
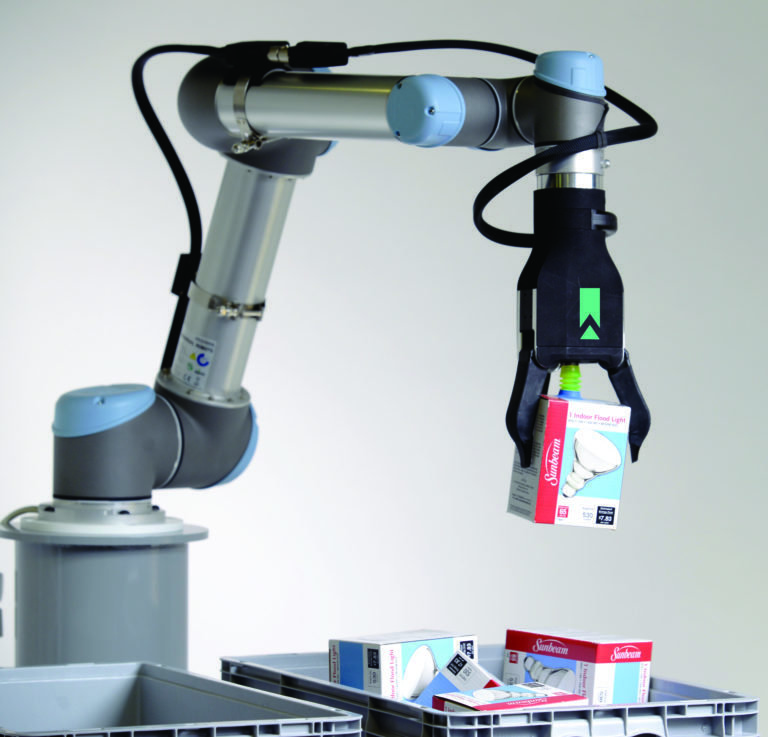
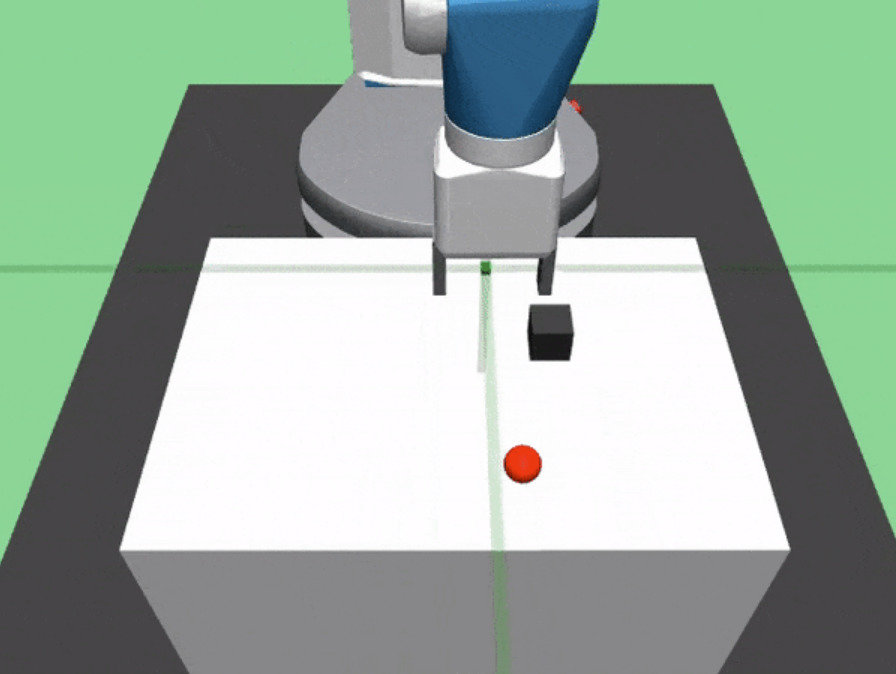
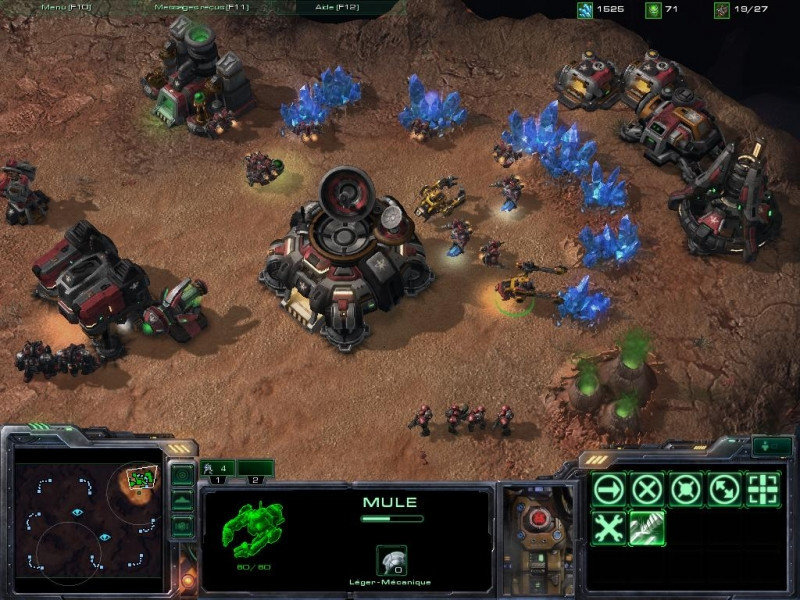
When does agent observe the state?
Partially Observable MDP
Definition
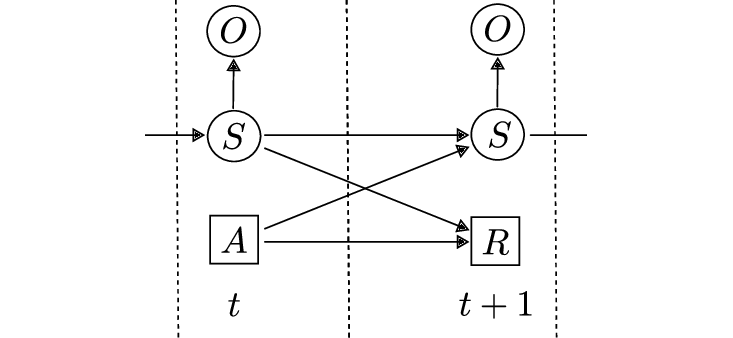
Graphical Model for POMDP:
POMDP is a 6-tuple \(<S,A,R,T,\Omega, O>\):
- \(S\) is a set of states
- \(A\) is a set of actions
- \(R: S \times A \to \mathbb{R}\) is a reward function
- \(T: S \times A \times S \to [0,1]\) is a transition function \(T(s,a,s\prime) = P(S_{t+1}=s\prime|S_t=s, A_t=a)\)
- \(O\) is a set of observations.
- \(\Omega\) is a set of \(|O|\) conditional probability distributions \(P(o|s)\)
Partially Observable MDP
Exact Solution
A proper belief state allows a POMDP to be formulated as a MDP over belief states (Astrom, 1965)
Belief State update:
General Idea:
Belief Update "Beilief" MDP Plan with Value Iteration Policy
b_0(s) = P(S_0=s)
b_{t+1}(s) = p(s|o_{t+1}, a_{t}, b_{t}) = \dfrac{p(s, o_{t+1}|a_t, b_t)}{p(o_{t+1}|a_t, b_t)}
\propto p(o_{t+1},| s, a_t, b_t)\, p(s | a_t, b_t)
= p(o_{t+1}| s) \sum_{s_i} p(s | a_t, s_i)\, b_t(s_i)
Problems:
- Need a model: \(p(o|s)\) and \(p(s'| a, s)\)
- Can compute exact belief update only for small/simple MDP
Huge sum or even integral over all states
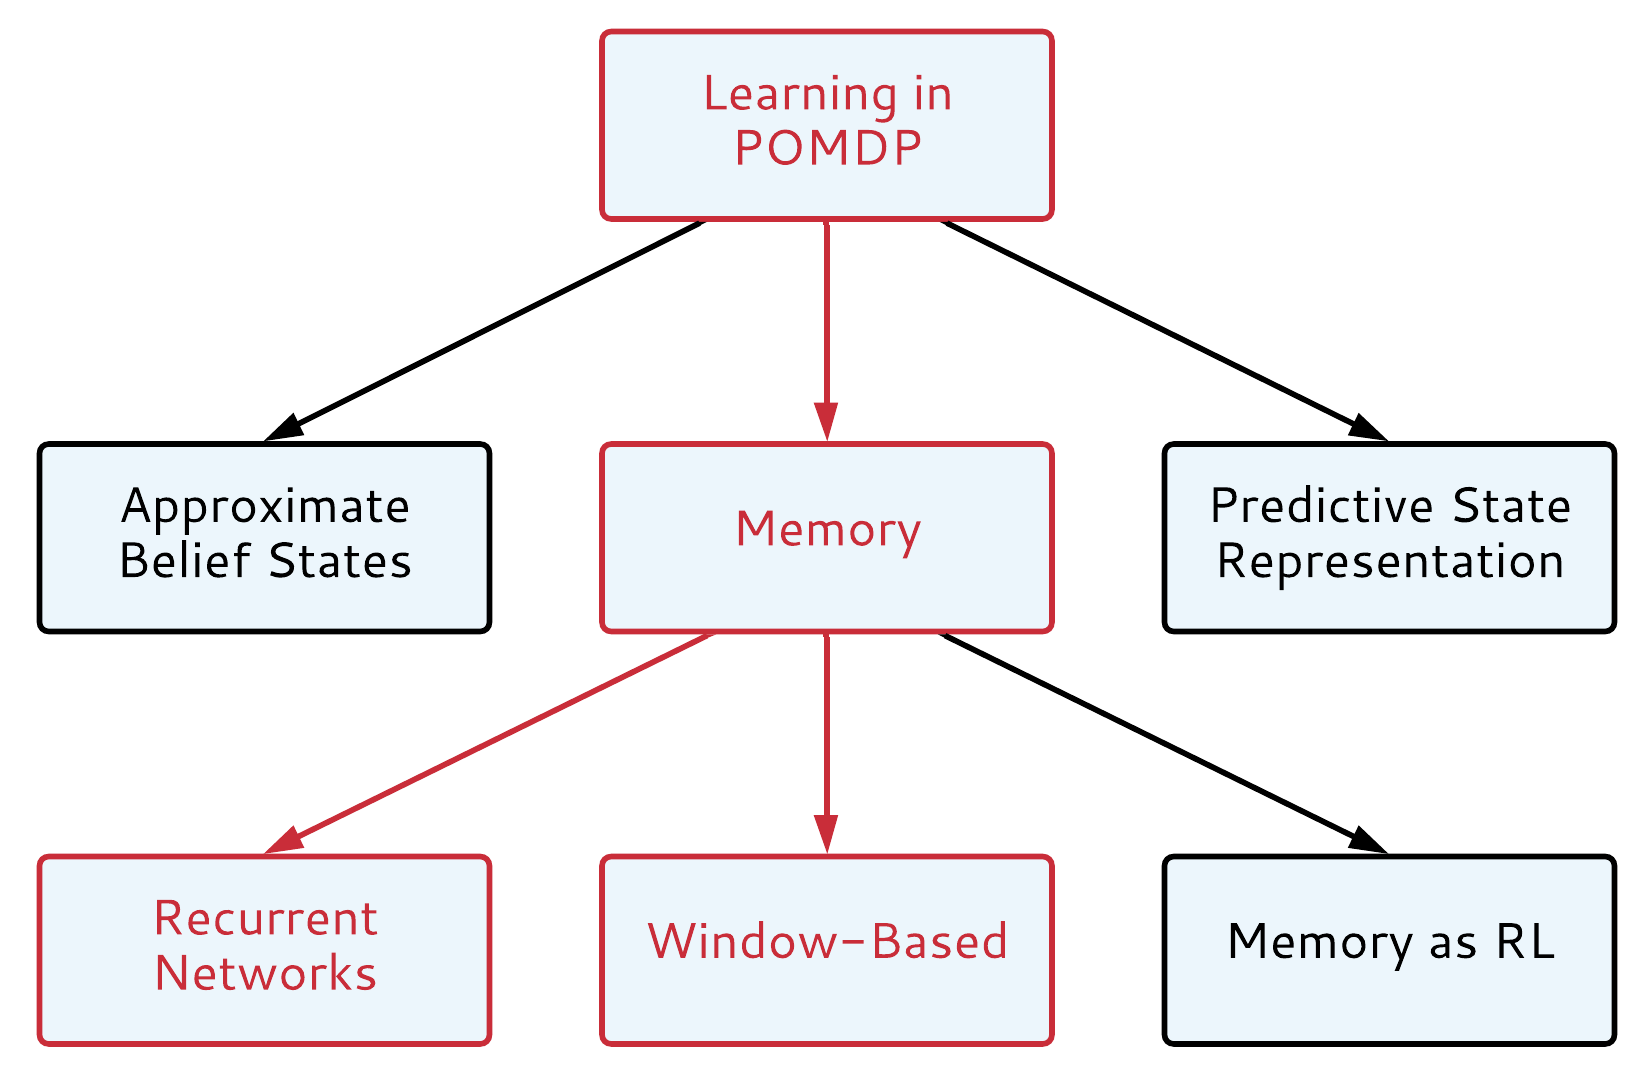
Learning in POMDP
Choose your fighter
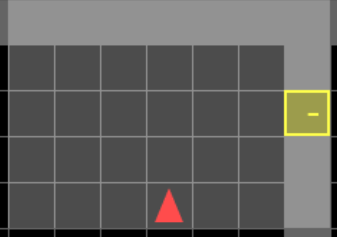
Why We Need Working Memory?
\(obs_{t=10}\)
\(obs_{t=12}\)
\(obs_{t=20}\)
\(act_{t=10}\)
\(act_{t=12}\)
\(act_{t=13}\)
We need this information
At this moment!
Memory
. . .
. . .
Recurrent Memory:
\(obs_{t=10}\)
\(obs_{t=12}\)
\(obs_{t=20}\)
\(act_{t=10}\)
\(act_{t=12}\)
\(act_{t=20}\)
\(h_{10}\)
. . .
. . .
\(h_9\)
\(h_{19}\)
. . .
. . .
. . .
Information
Gradients
Problem with RNNs:
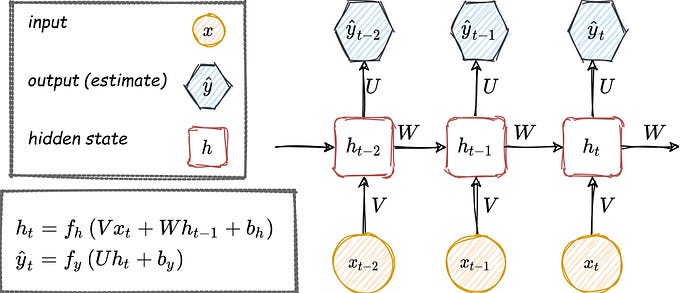
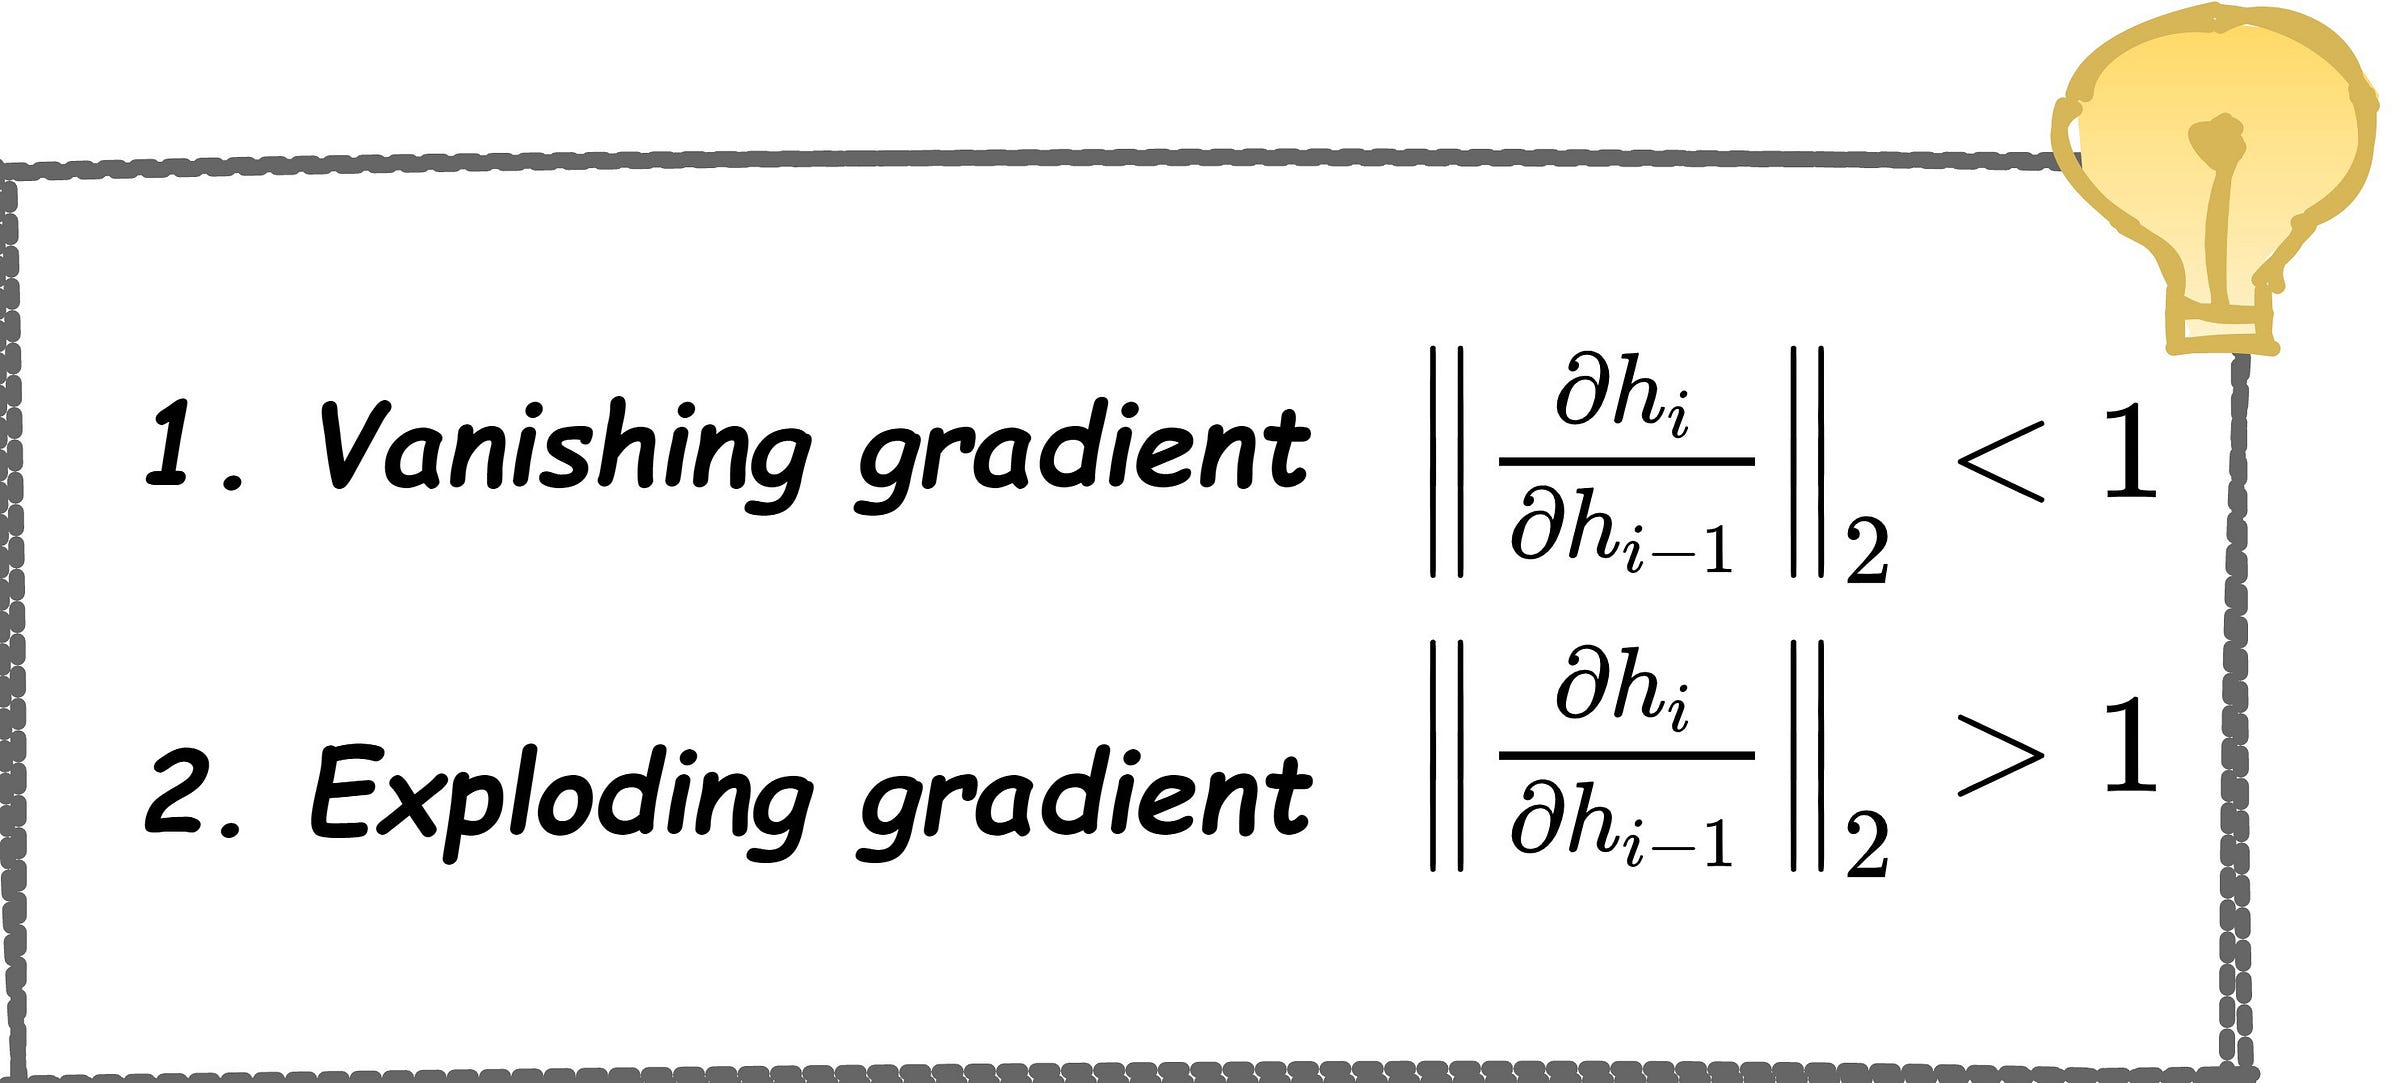
Solutions for Vanishing Gradients
Fight RNN problems by building more complex RNNs
Long-Short Term Memory: LSTM

Differential Neural Computer: DNC

Window Based Memory:
\(obs_{t=10}\)
\(obs_{t=12}\)
\(obs_{t=20}\)
\(act_{t=10}\)
\(act_{t=12}\)
\(act_{t=20}\)
. . .
. . .
Memory Window
Information
Gradients
Soft-Attention:
\(obs_{t=10}\)
\(obs_{t=12}\)
\(obs_{t=20}\)
. . .
. . .
\(e_{10}\)
\(e_{12}\)
\(a_{10}\)
\(e_{20}\)
Embeddings
Query
\times
\times
\times
\(a_{12}\)
Attention weight: \(a_t = {e_{t}}^T q/\sum_i {e_{i}}^T q \)
\(q\)
Soft-Attention:
\(obs_{t=10}\)
\(obs_{t=12}\)
\(obs_{t=20}\)
. . .
. . .
\(e_{10}\)
\(e_{12}\)
\(a_{10}\)
Embeddings
Query
\times
\times
\times
\(a_{12}\)
Context Vector \(c_{20} = \sum_t a_t e_t\)
Attention weight: \(a_t = {e_{t}}^T q/\sum_i {e_{i}}^T q \)
\(q\)
Transformer Basics: Self-Attention
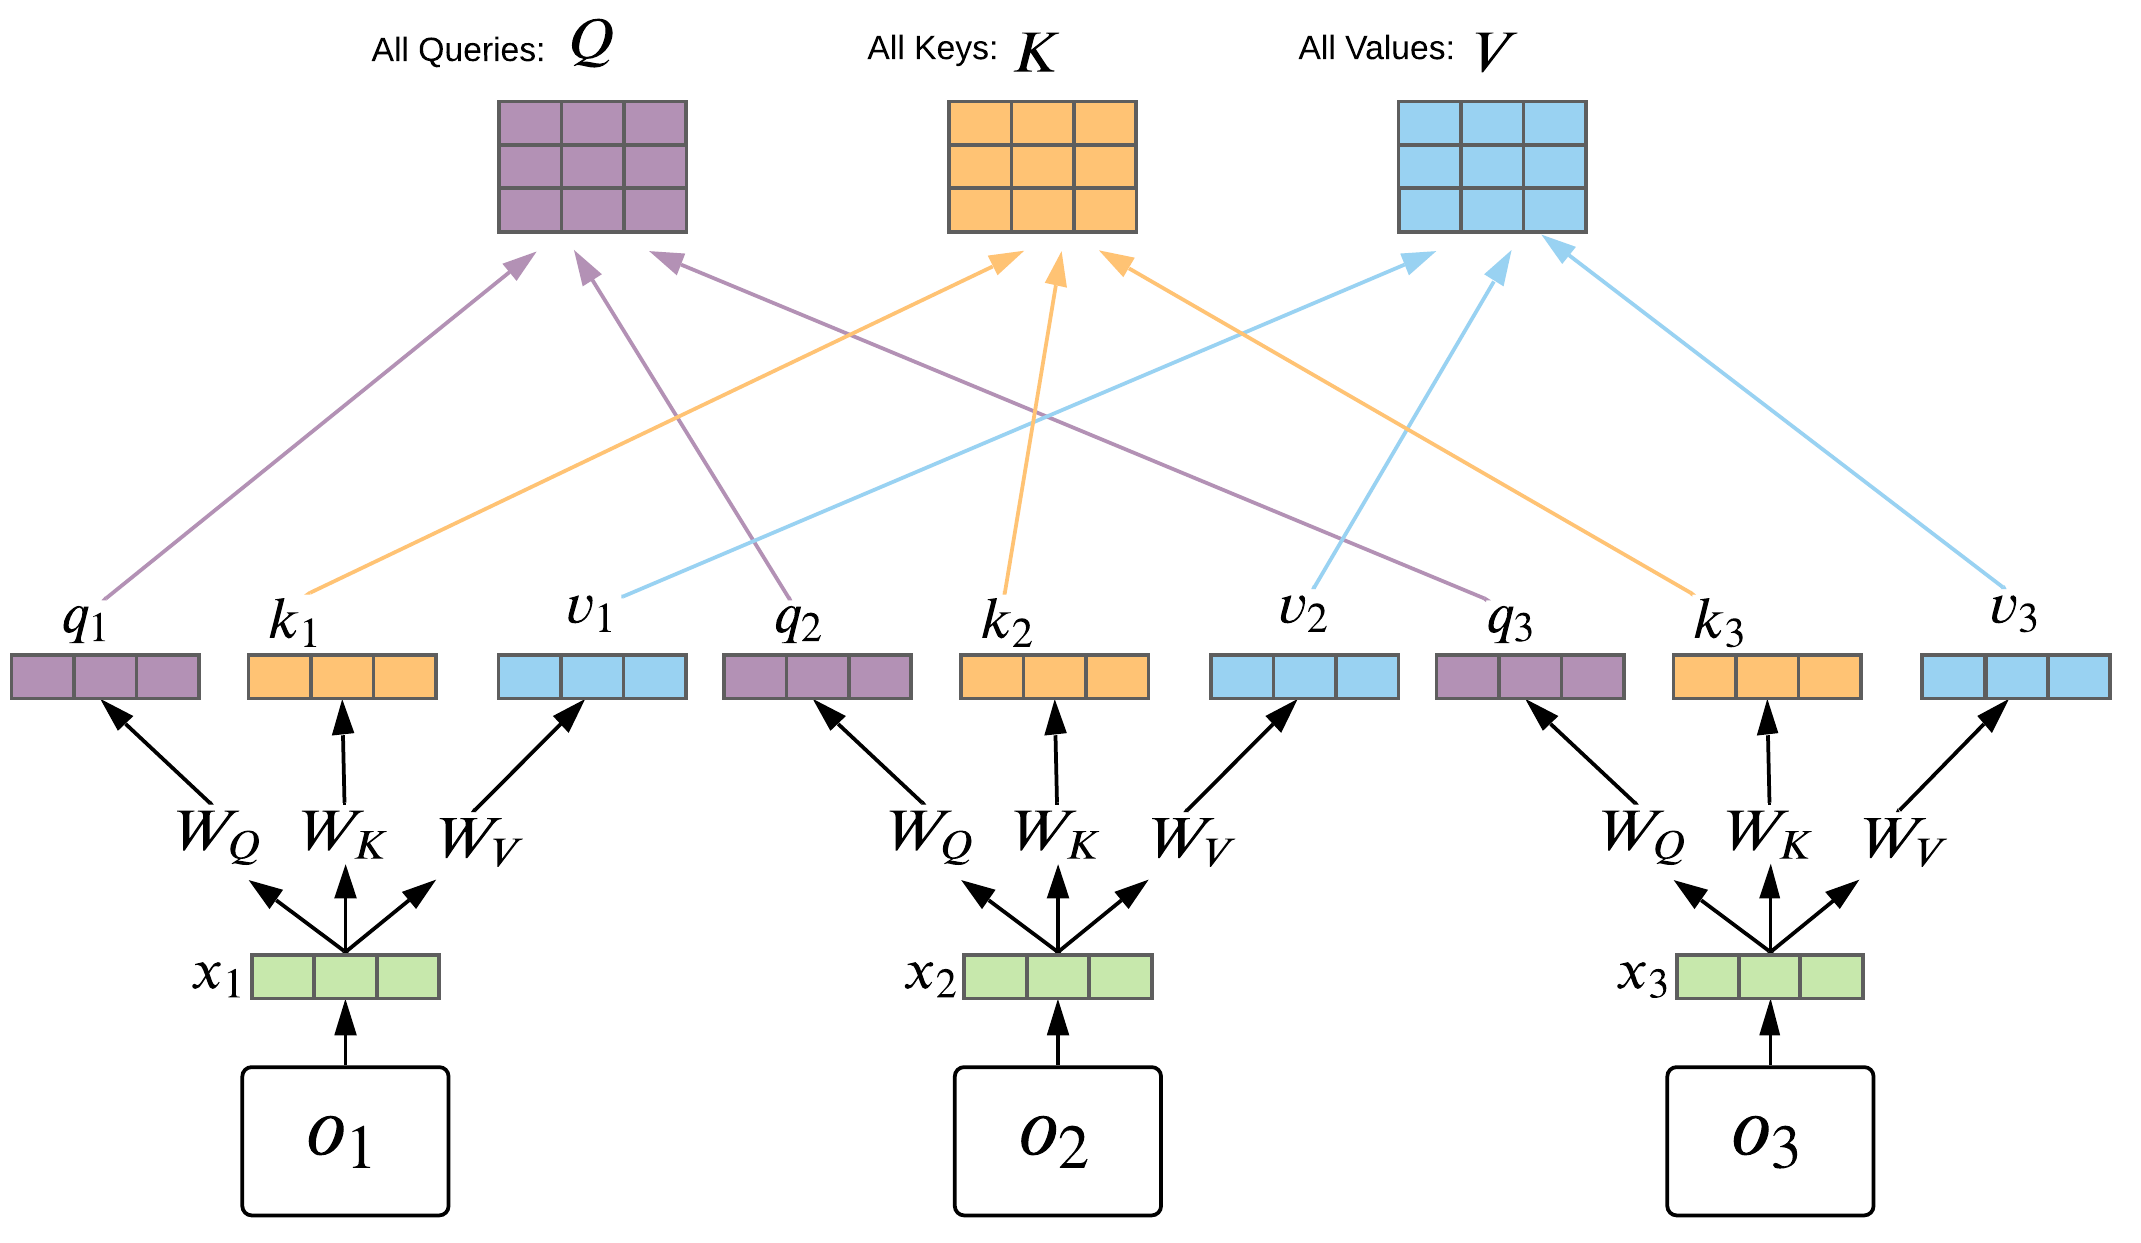
Transformer Basics: Self-Attention
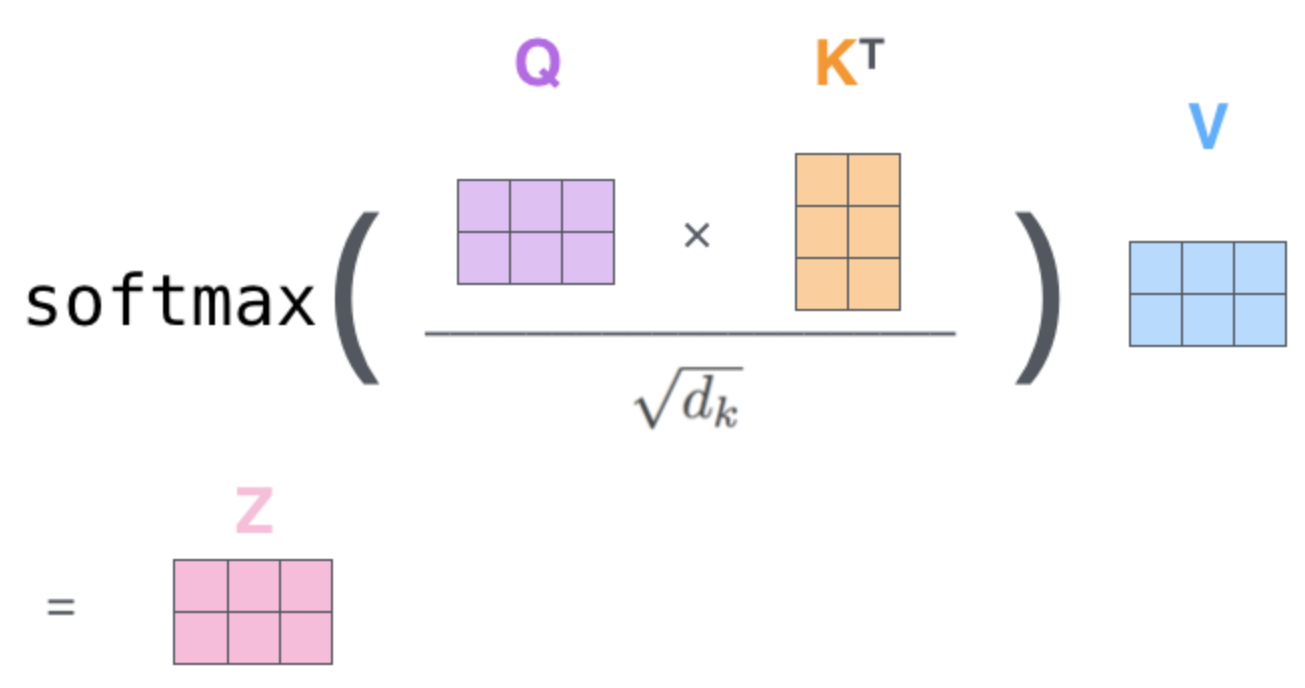
Self-Attention computation:
Each \(z_t\) contains relevant information about \(o_t\) collected over all steps in
Memory Window:
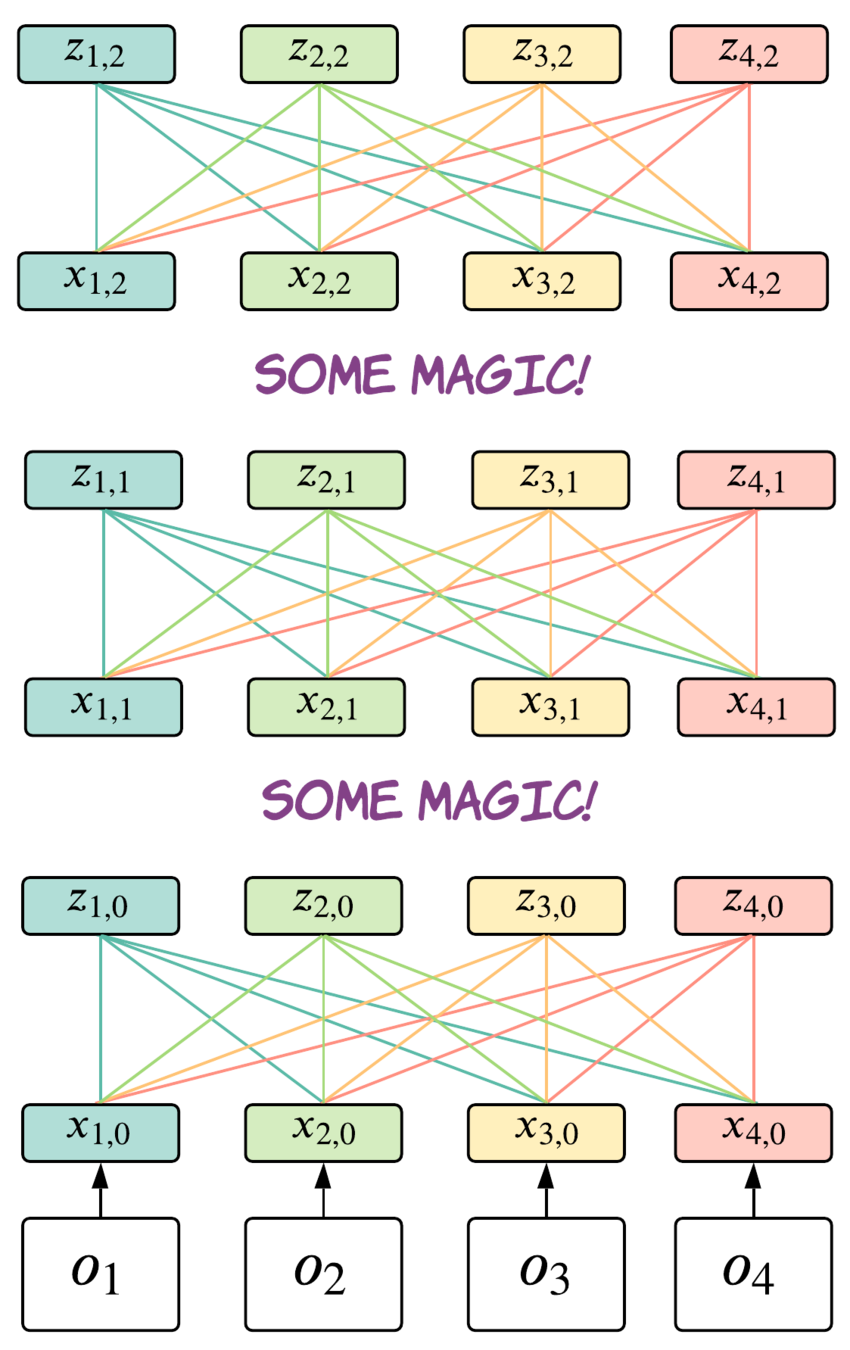
Full Transformer
This is how real Transformer looks:
Kind of...
This is how real Transformer looks:
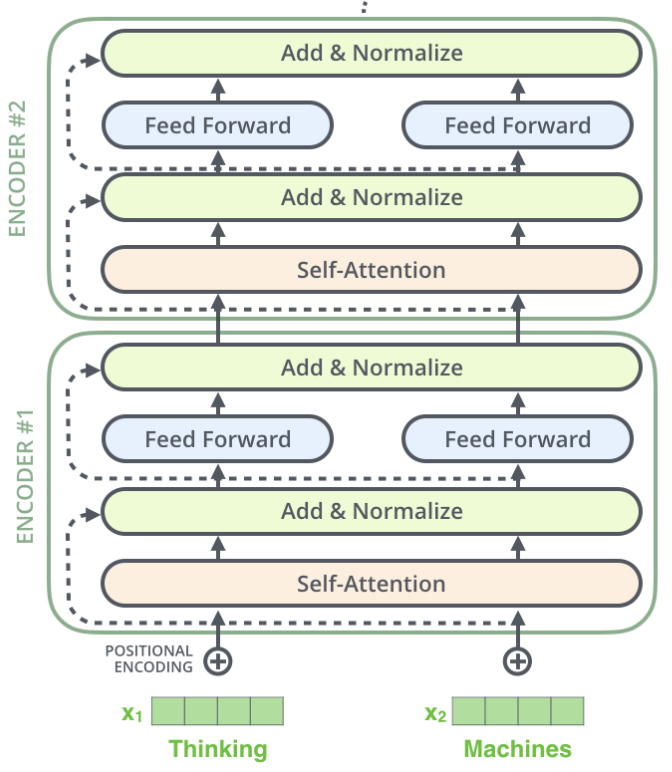
Transformer:
- All time-steps in a memory window attends to all other time-steps
- For each time-step you have: Query \(q_t\), Key \(k_t\), Value \(v_t\)
- Transformer has N attention heads!
- Transformer uses positional encoding to relate different time steps temporarily
- You repeat this process for several layers!
Transformer
Attention is All You Need!
Just add LSTM to everything
Off-Policy Learning (DRQN):
- Add LSTM before last 1-2 layers
- Sample sequences of steps from Experience Replay
On-Policy Learning (A3C/PPO):
- Add LSTM before last 1-2 layers
- Keep LSTM hidden state \(h_t\) between rollouts
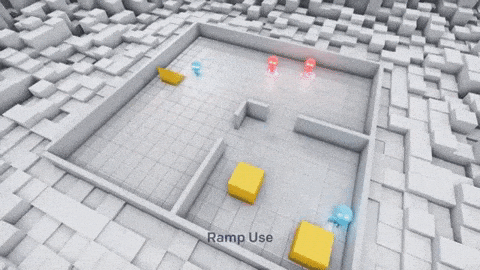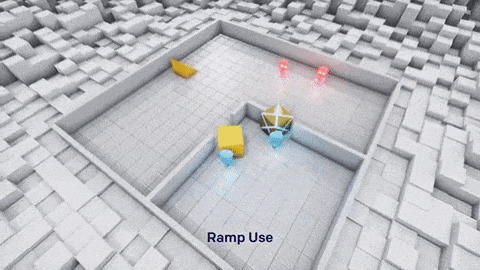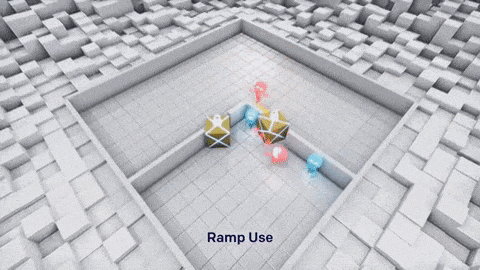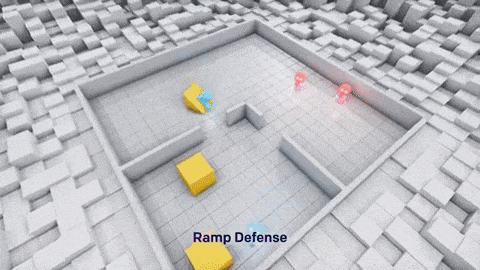
Asynchronous Methods for Deep Reinforcement Learning (Mnih et al, 2016) | DeepMind, ICML, 3113 citations
Deep Recurrent Q-Learning for Partially Observable MDPs
(Hausknecht et al, 2015) AAAI, 582 citations )
Just add LSTM to everything
Default choice for memory in big projects
"To deal with partial observability, the temporal sequence of observations is processed by a deep long short-term memory (LSTM) system"
AlphaStar Grandmaster level in StarCraft II using multi-agent reinforcement learning (Vinyalis et al, 2019) | DeepMind, Nature, 16 Citations
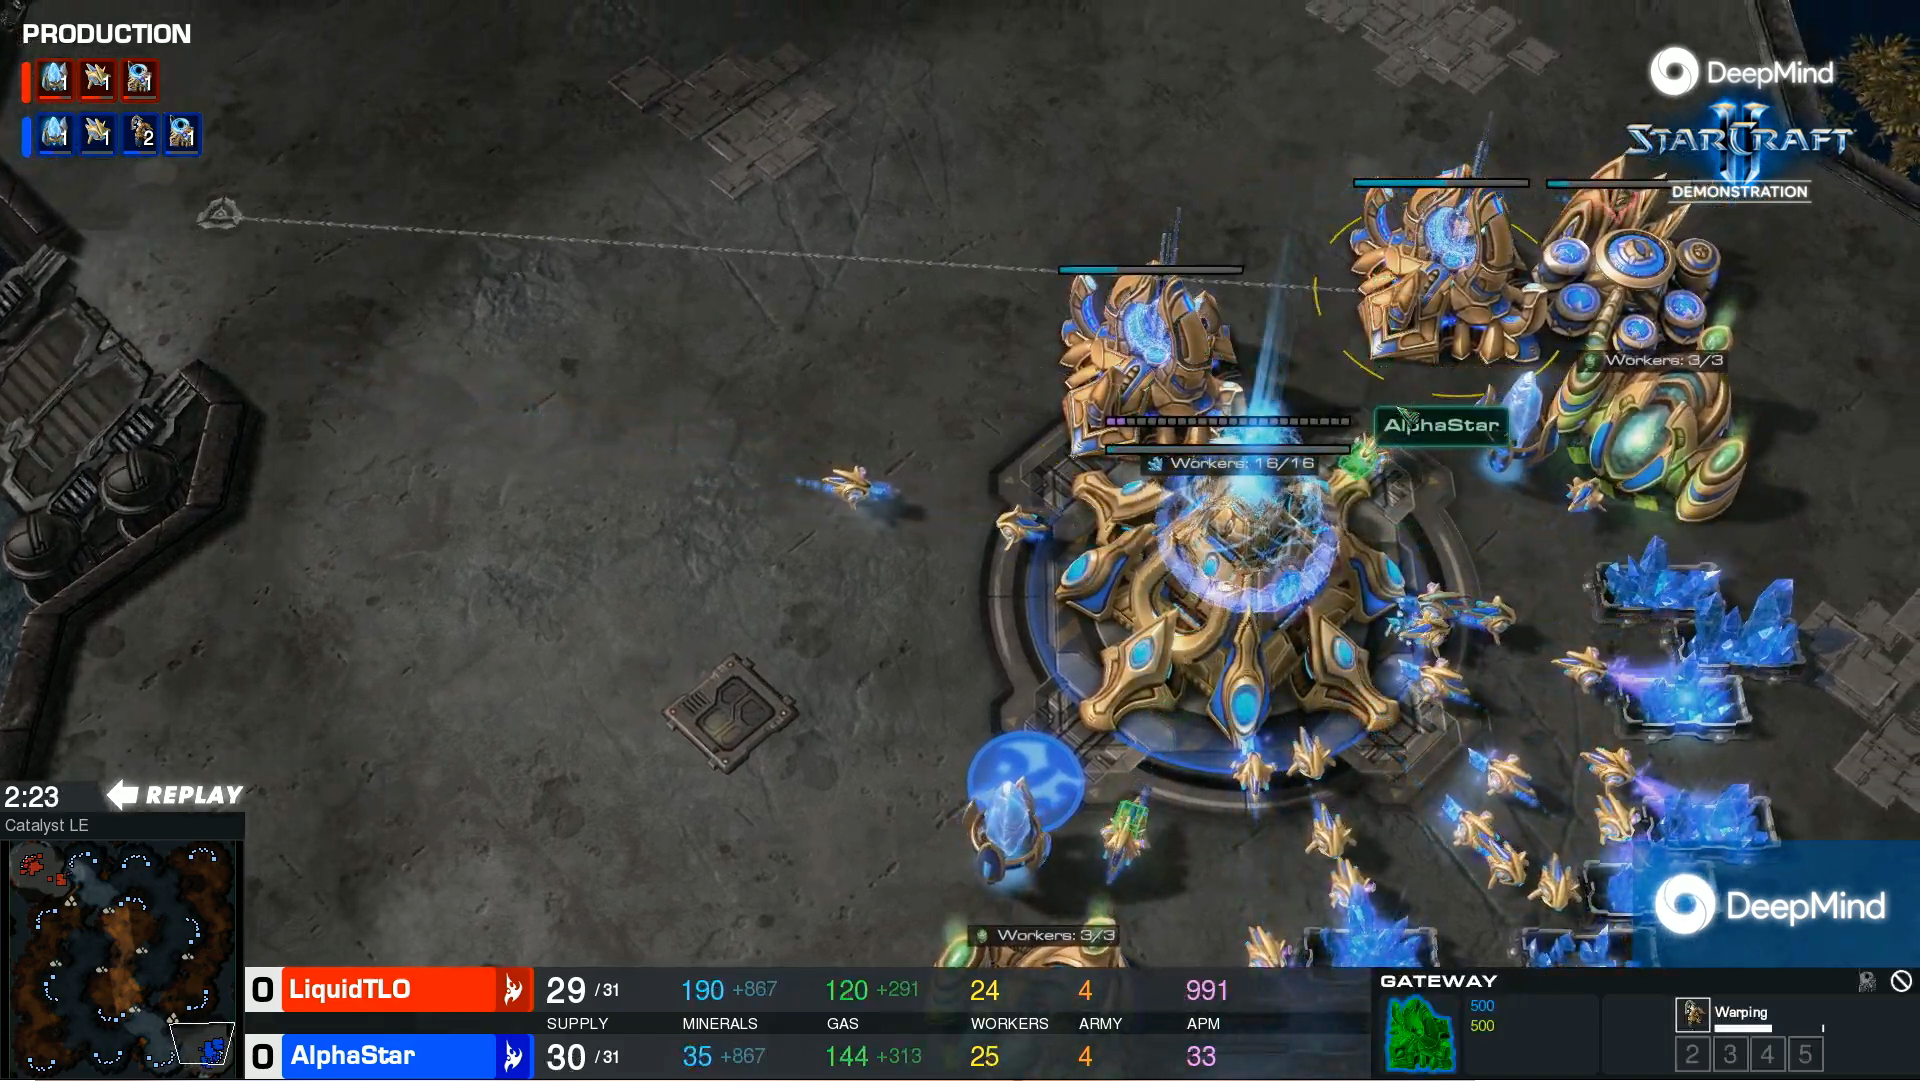
Just add LSTM to everything
Default choice for memory in big projects
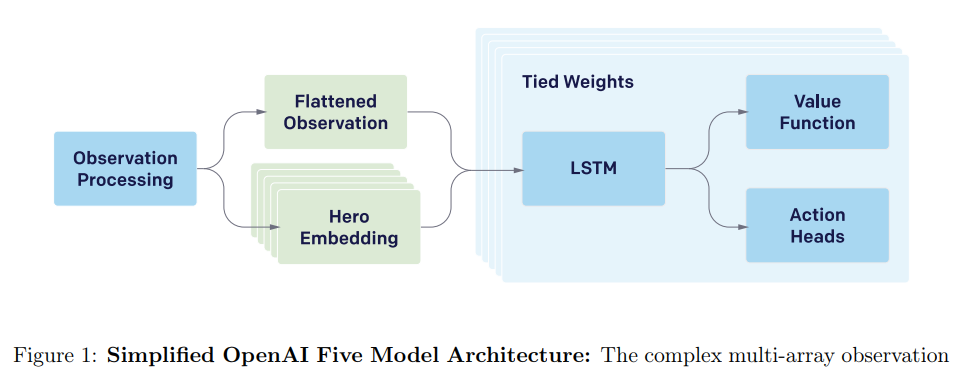
"The LSTM composes 84% of the model’s total parameter count."
Dota 2 with Large Scale Deep Reinforcement Learning (Berner et al, 2019) | OpenAI, 17 Citations
R2D2: We can do better
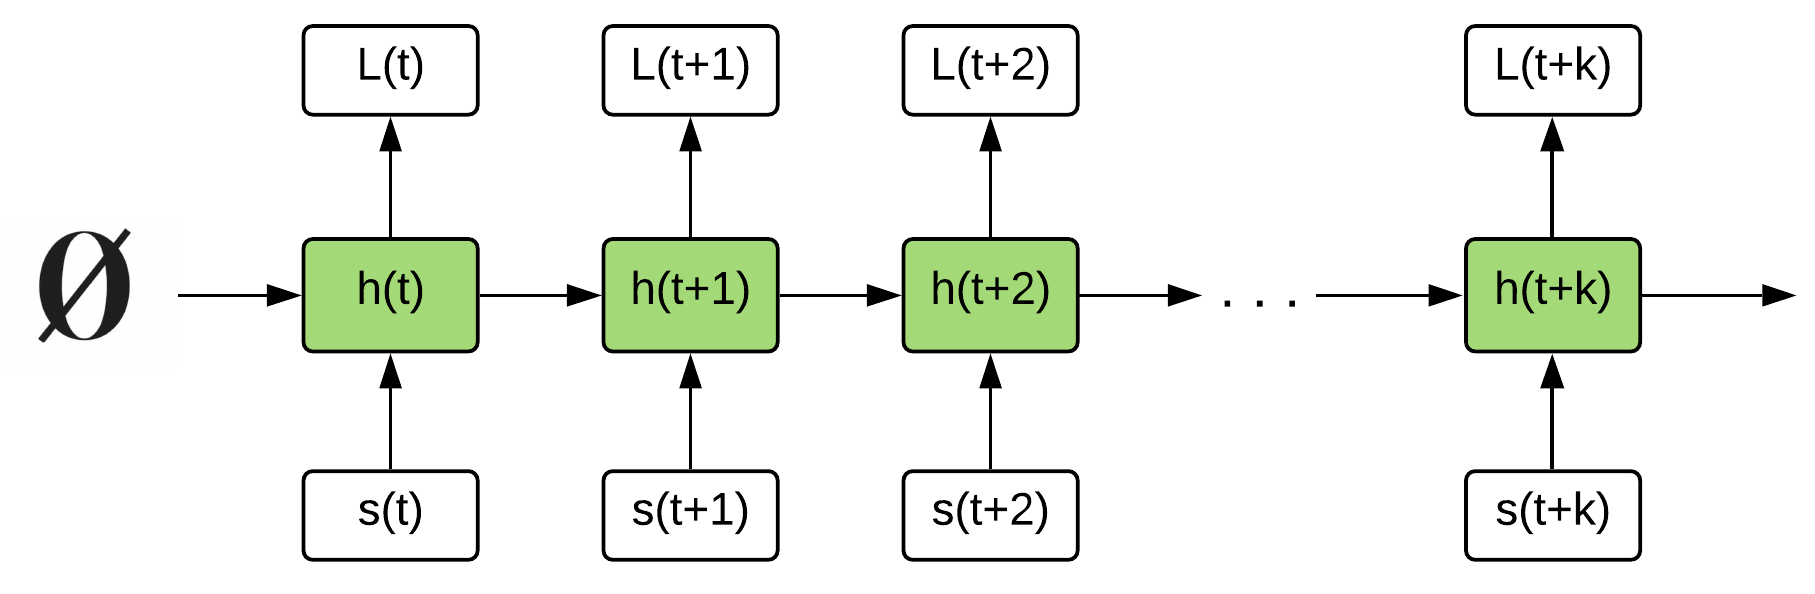
DRQN tests two sampling methods:
- Sample full episode sequences
- Problem: sample correlation in mini-batch is proportional to the sequence length
- Sample random sub-sequences of length k (10 steps in the paper)
- Problem: initial hidden state is zero at the start of a rollout
Recurrent Experience Replay in Distributed Reinforcement Learning (Kapturowski et al, 2019) | DeepMind, ICLR, 49 citations
R2D2: We can do better
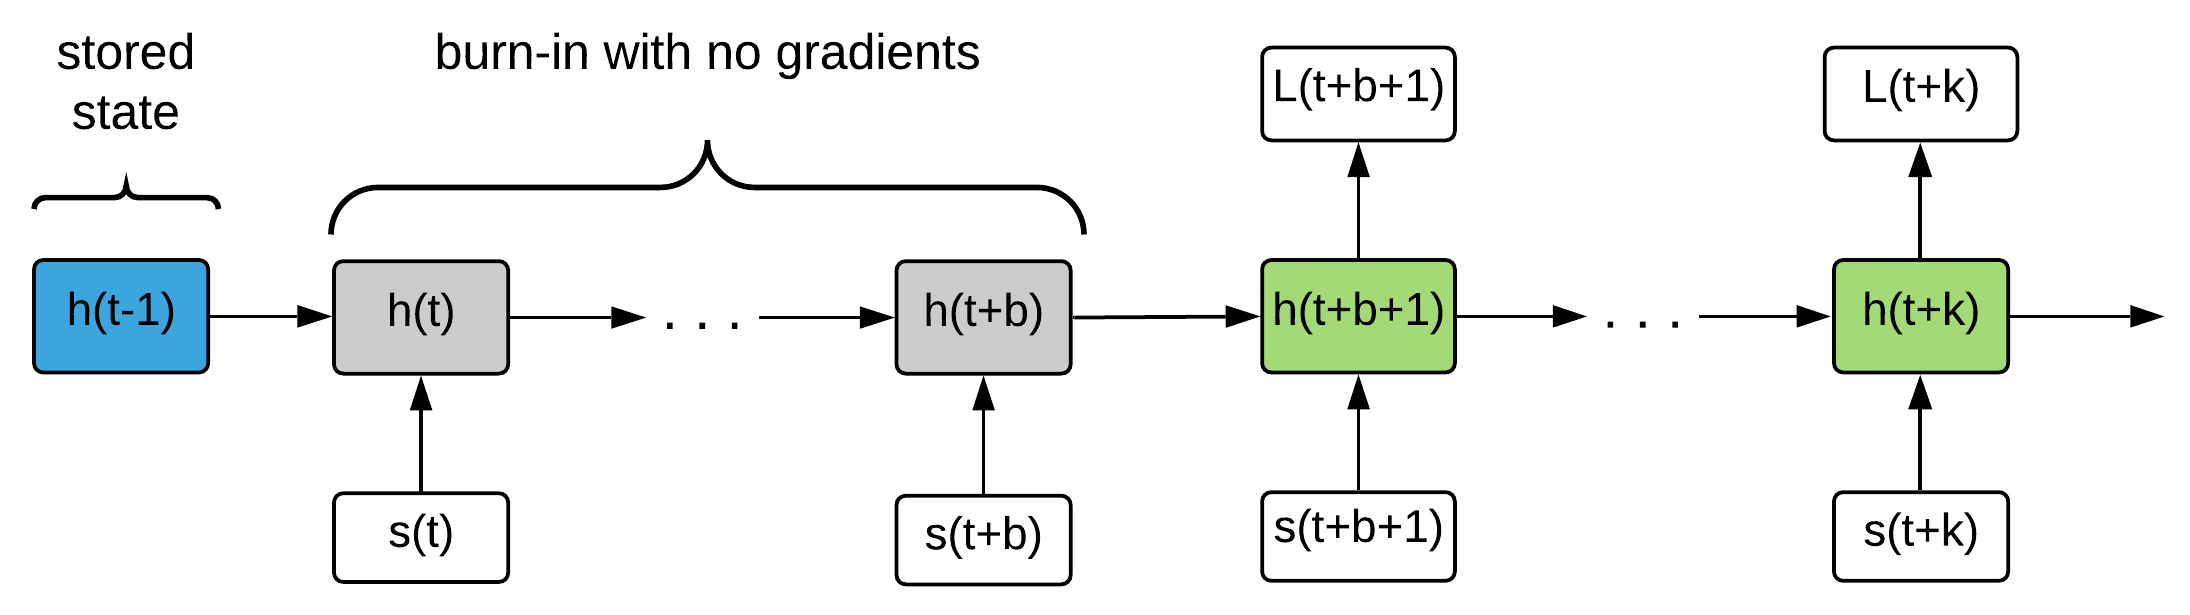
R2D2 is a DRQN build on top of Ape-X (Horgan et al, 2018) with addition of two heuristics:
- Stored state: Storing the recurrent state in replay and using it to initialize the network at training time
- Burn-in: Use a portion of the replay sequence only for unrolling the network and producing a start state, and update the network only on the remaining part of the sequence
Burn-in - 40 steps, full rollout - 80 steps
Recurrent Experience Replay in Distributed Reinforcement Learning (Kapturowski et al, 2019) | DeepMind, ICLR, 49 citations
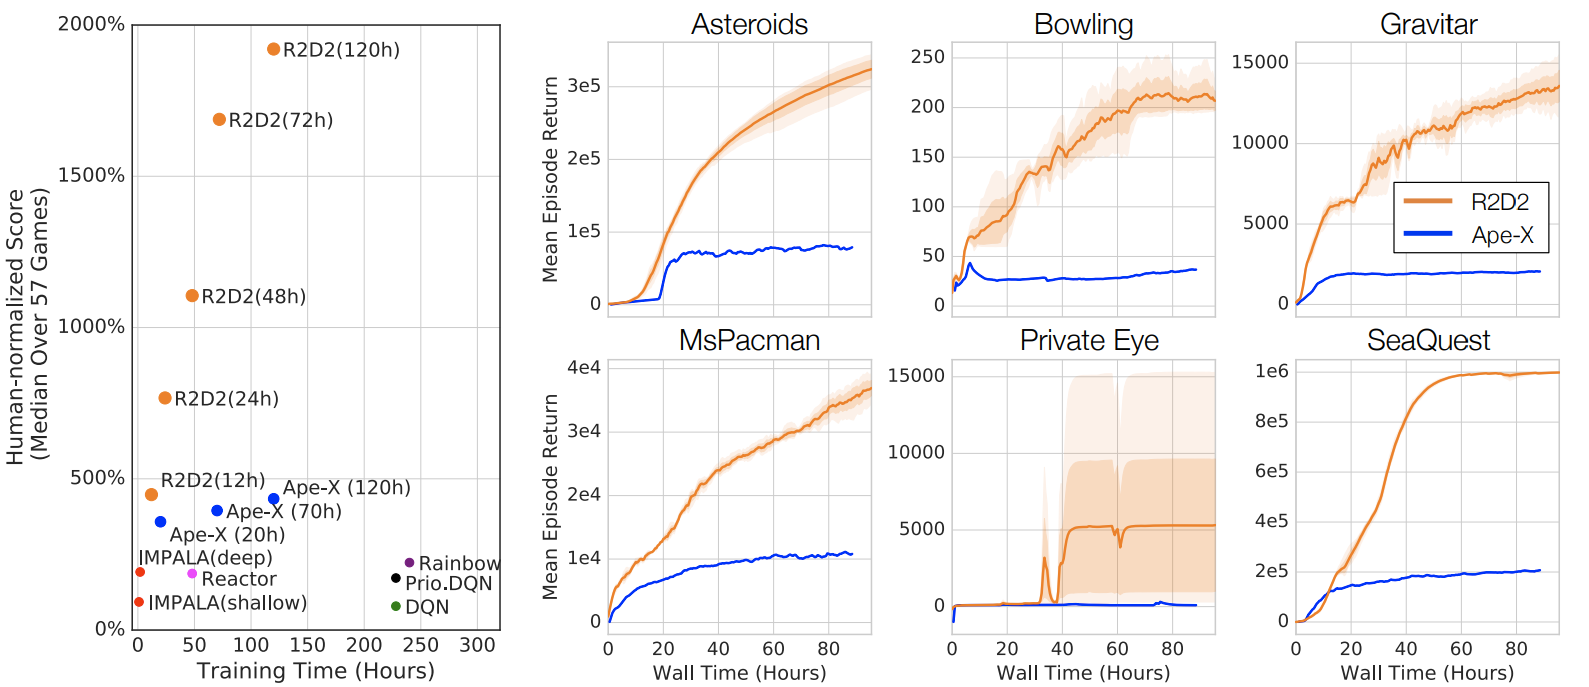
R2D2
Results: Atari-57
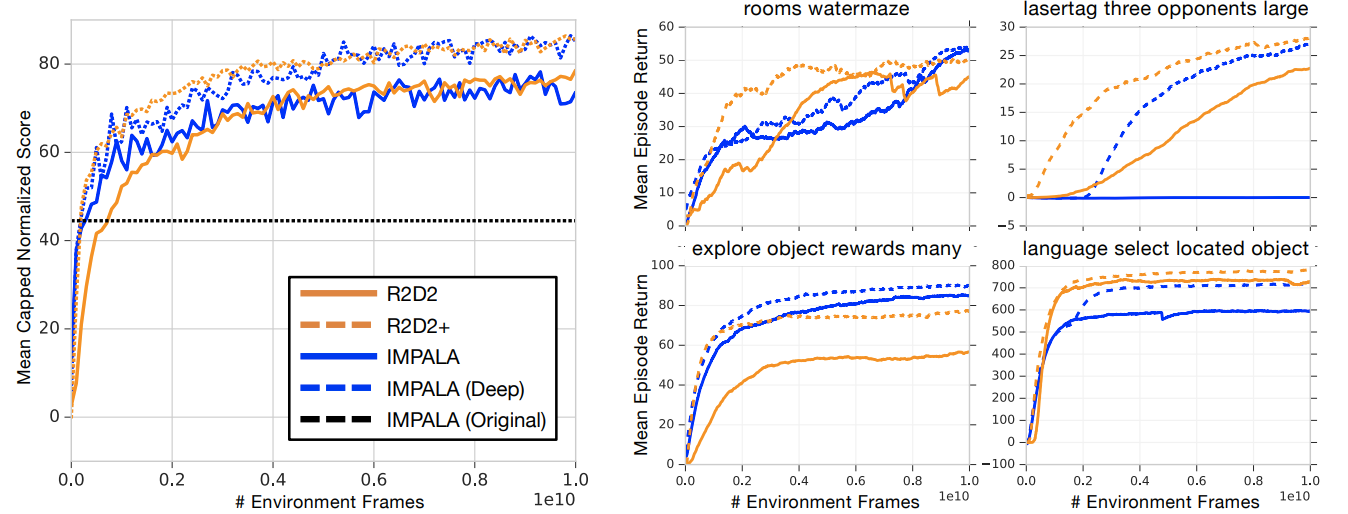
R2D2
Results: DMLab-30
Recurrent Experience Replay in Distributed Reinforcement Learning (Kapturowski et al, 2019) | DeepMind, ICLR, 49 citations
AMRL
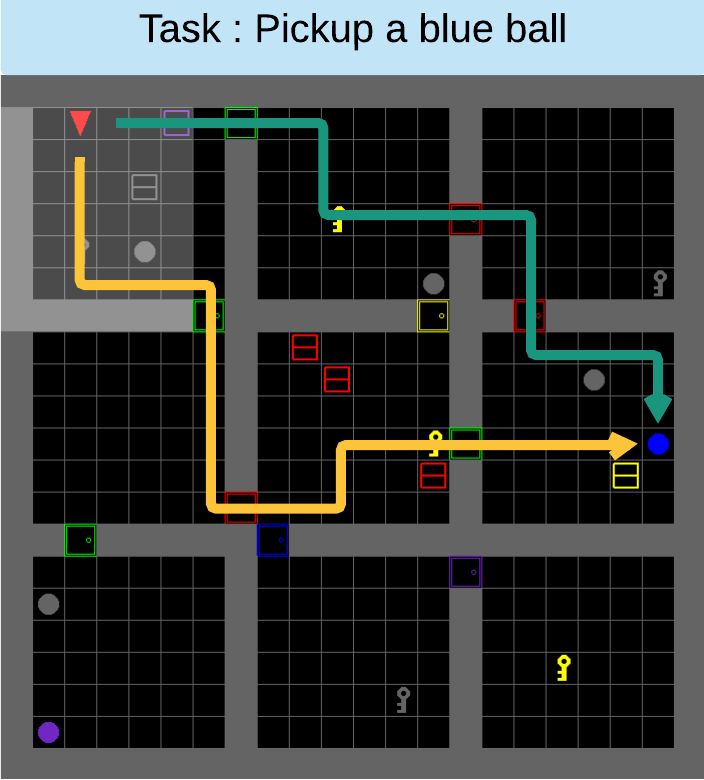
Motivation
Recurrent Neural Networks:
-
good at tracking order of observations
-
susceptible to noise in observations
-
bad at long-term dependencies
RL Tasks:
-
order often doesn't matter
-
high variability in observation sequences
-
long-term dependencies
AMRL: Aggregated Memory For Reinforcement Learning (2020) | MS Research, ICLR
AMRL:
Robust Aggregators
Add aggregators that ignore order of observations:


Agregators also act as residual skip connections across time.

Instead of true gradients a straight-through estimator(Bengio et al., 2013) is used.
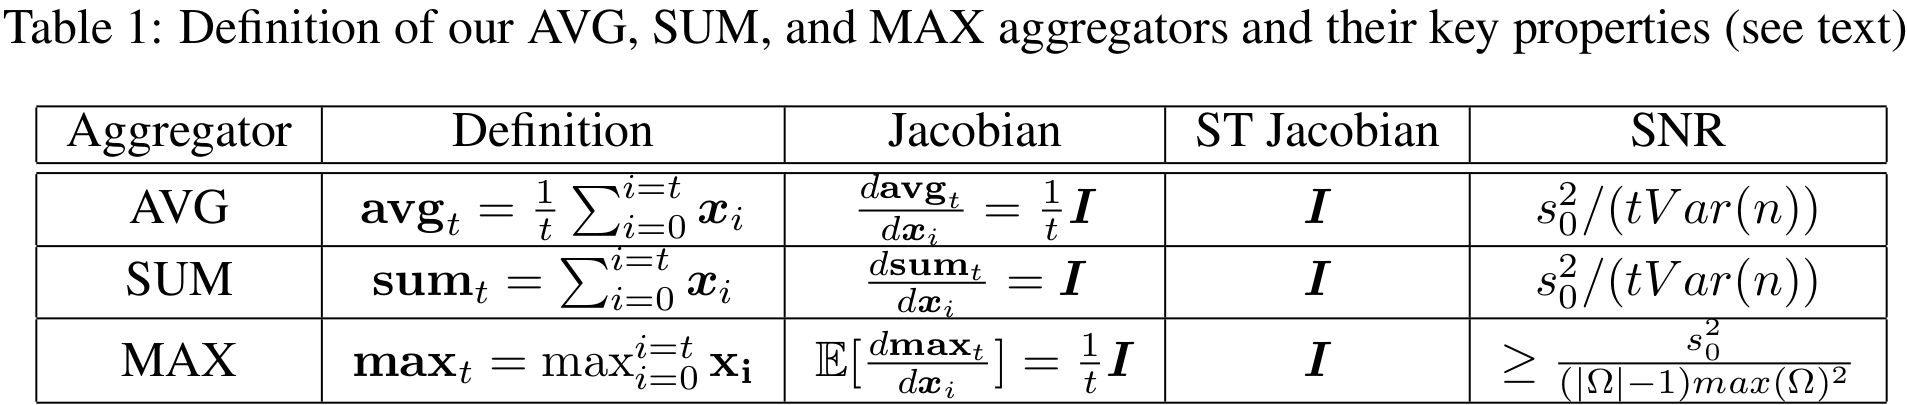
AMRL: Aggregated Memory For Reinforcement Learning (2020) | MS Research, ICLR
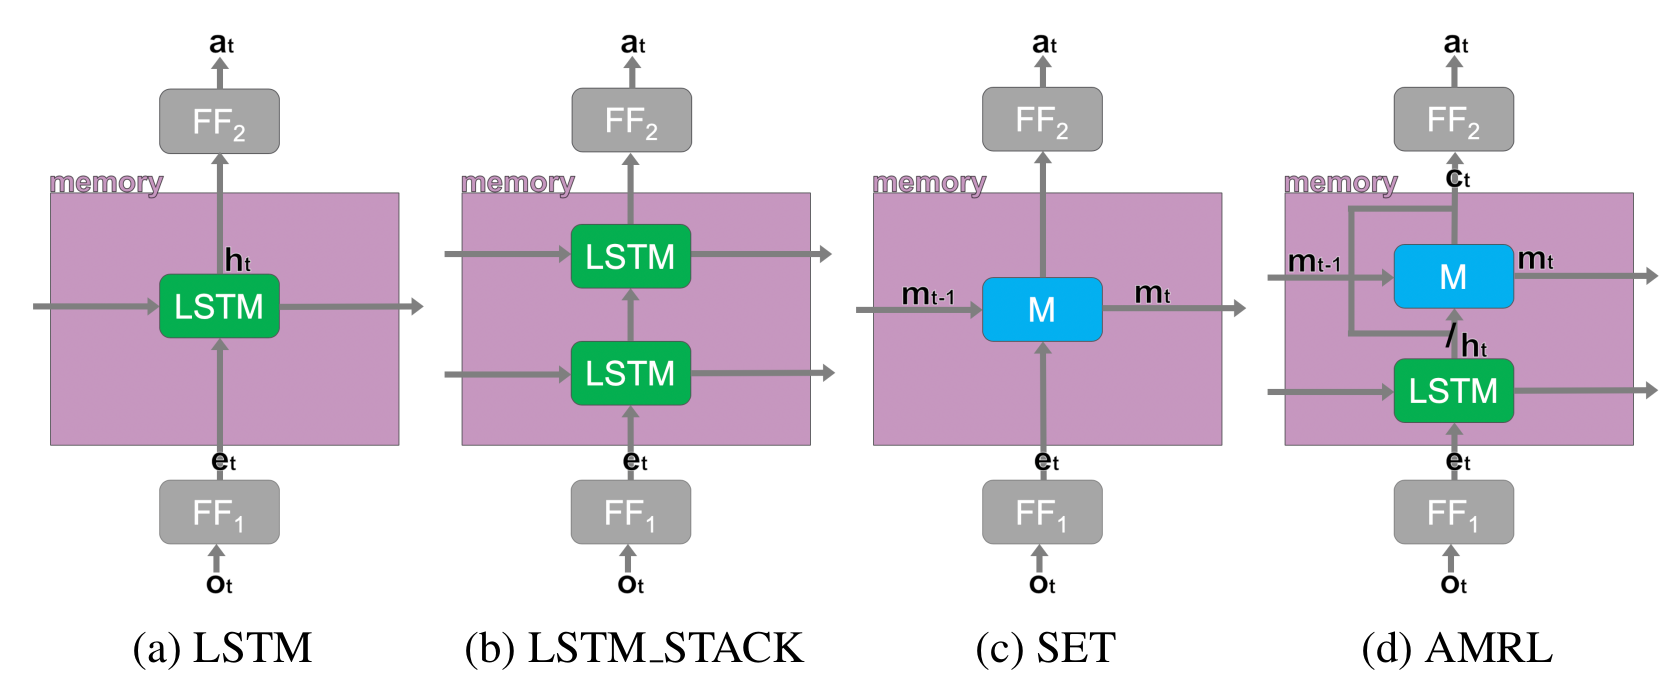
AMRL
Architecture and Baselines
AMRL: Aggregated Memory For Reinforcement Learning (2020) | MS Research, ICLR
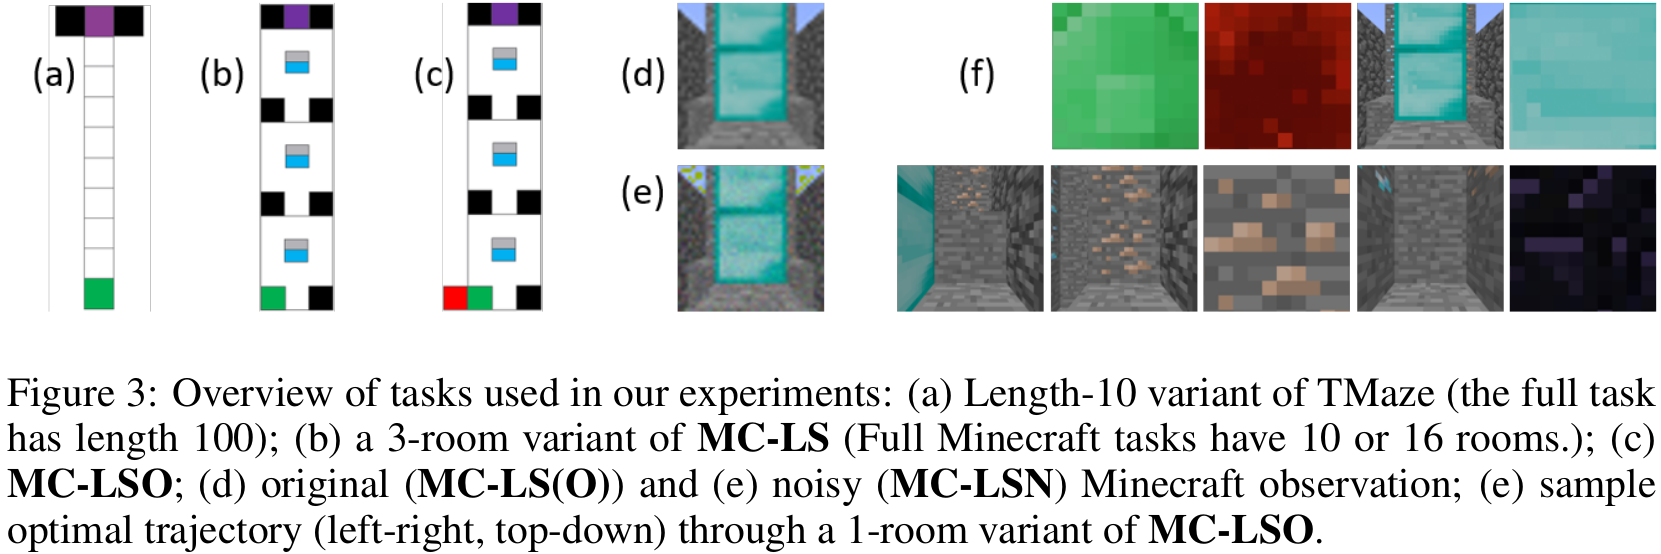
AMRL
Experiments
AMRL: Aggregated Memory For Reinforcement Learning (2020) | MS Research, ICLR
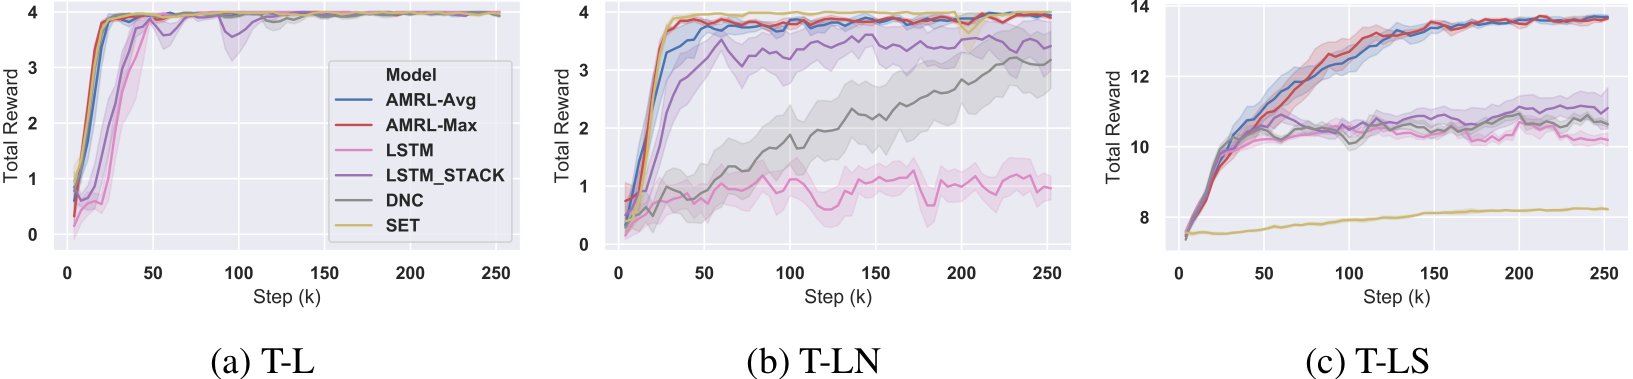
AMRL
Experiments
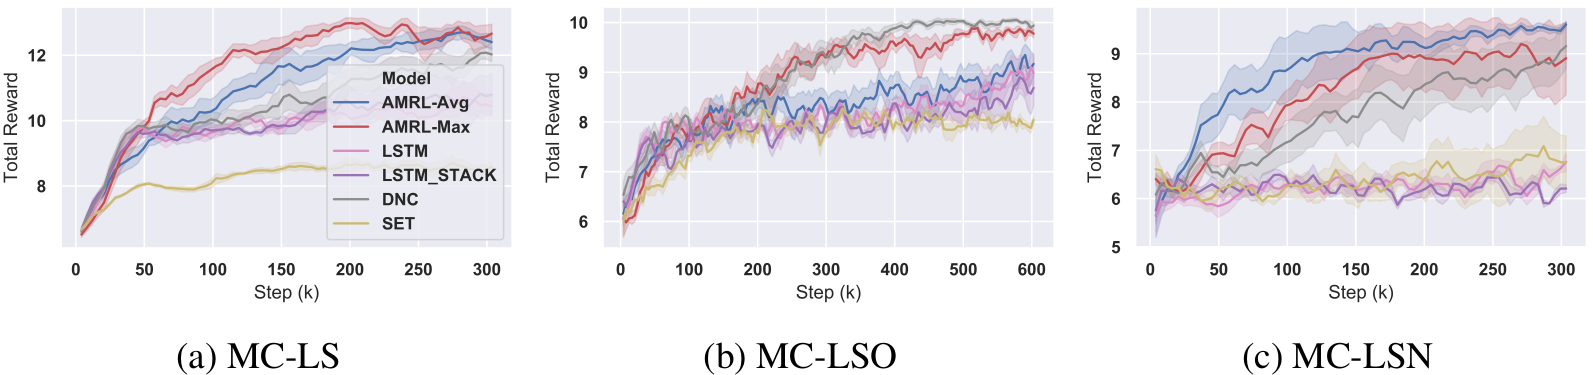
AMRL
Experiments
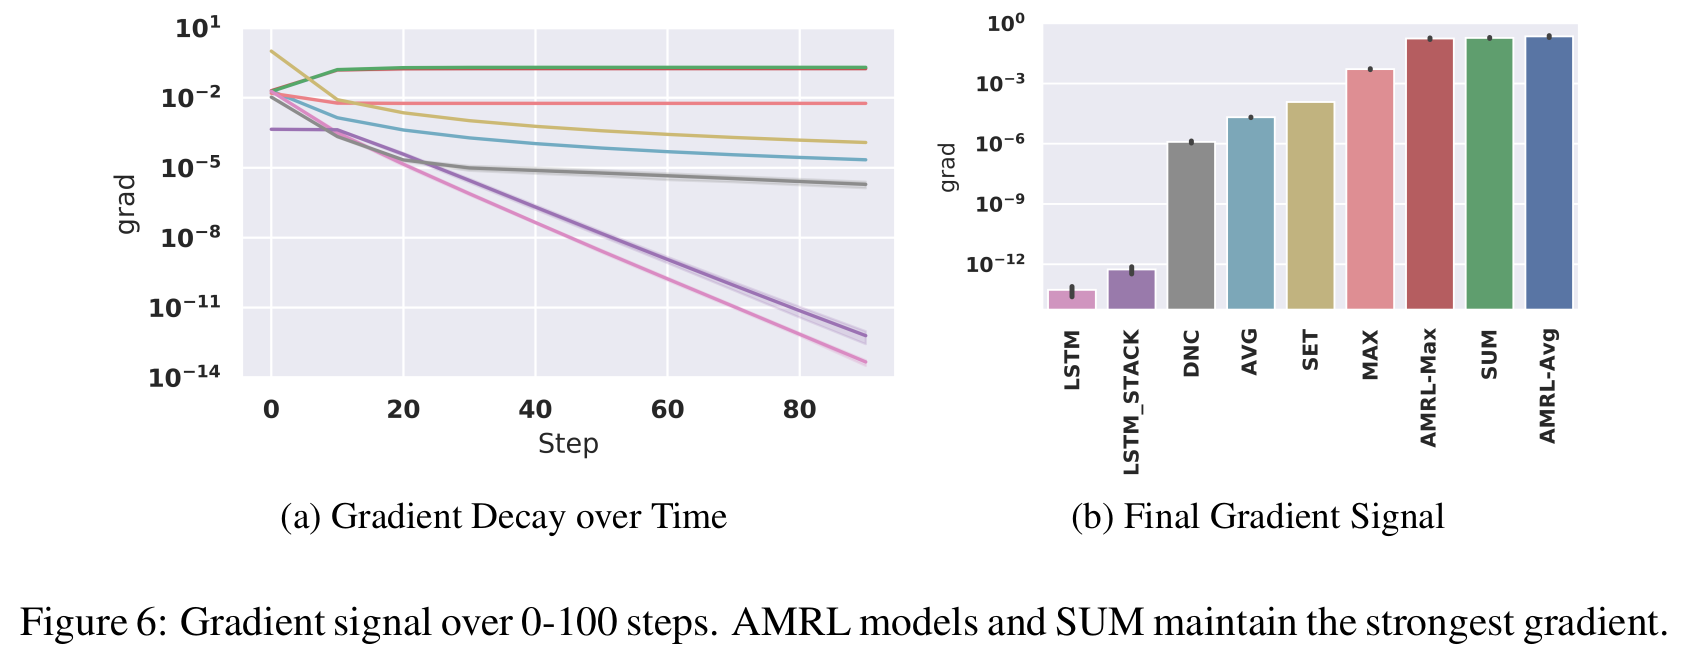
AMRL: Aggregated Memory For Reinforcement Learning (2020) | MS Research, ICLR
Are rewards enough to learn memory?
-
Learning only by optimizing future rewards
-
A3C/PPO + LSTM
- DRQN, R2D2
- AMRL
-
-
What if we know a little bit more?
- Neural Map (Parisotto et al, 2017)
- Working Memory Graphs(Loynd et al, 2020)
-
Learing with rich self-supervised sensory signals
- World Models (Ha et al, 2018)
- MERLIN (Wayne et al, 2018)
- PlaNet (Hafner et al, 2019)
- Dreamer (Hafner et al, 2020)
- Dreamer-v2 (Hafner et al, 2021)
MERLIN
Unsupervised Predictive Memory in a Goal-Directed Agent (2018)
MERLIN has two basic components:
-
Model-Based Predictor
-
a monstrous combination of VAE and Q-function estimator
-
uses simplified DNC under the hood
-
-
Policy
-
no gradients flow between policy and MBR
-
trained with Policy Gradients and GAE
-
MERLIN is trained on-policy in A3C-like manner:
- 192 parallel workers, 1 parameter server
- rollout length is 20-24 steps
VAE:

DNC:
MERLIN
Experiments
MERLIN is compared against two baselines: A3C-LSTM, A3C-DNC
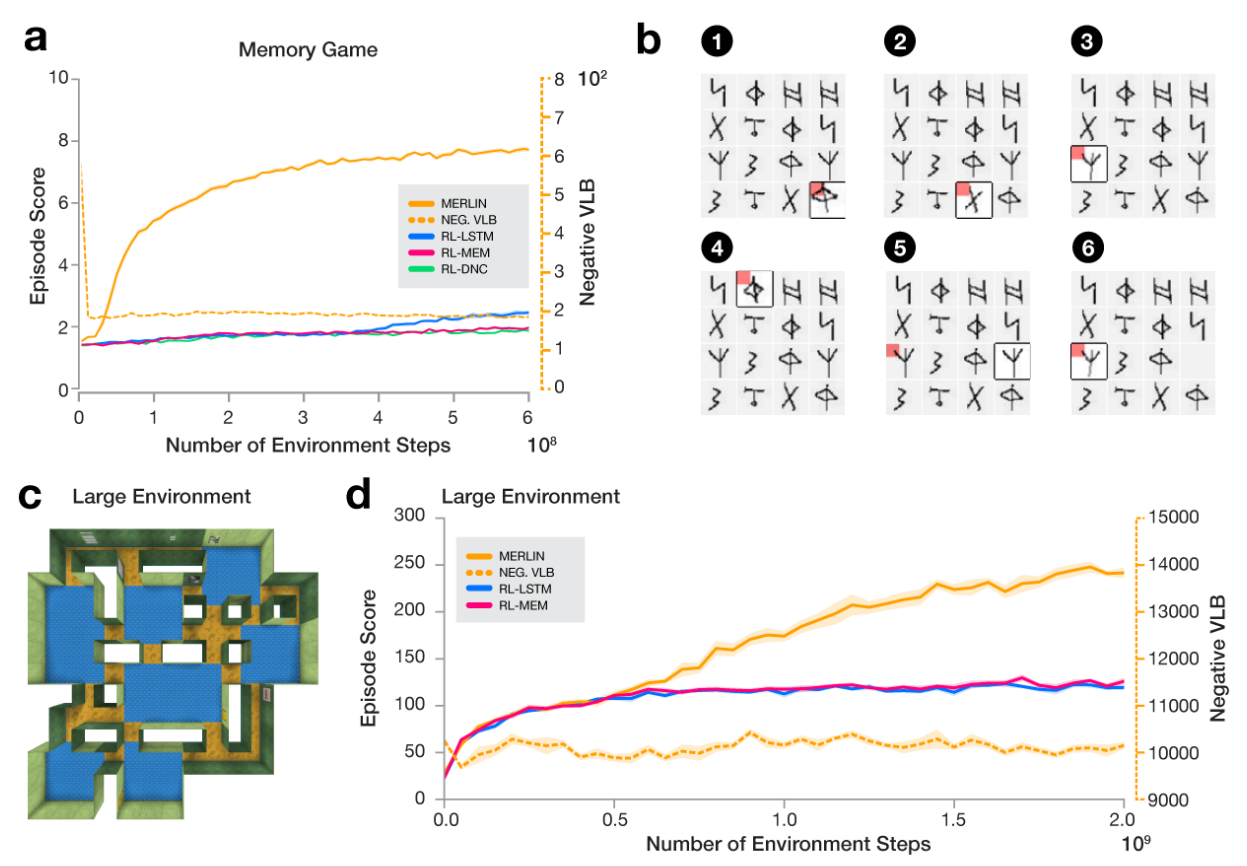
MERLIN
Experiments
Unsupervised Predictive Memory in a Goal-Directed Agent (2018)
Transformers as Memory in RL
Problem:
- Transformers are unstable when applied in RL setting
HINT: Casts an RL problem as a supervised Learning problem!
Solution:
- Do not use Transformers in RL!
Real Solution:
- Use Transformers in Offline-RL and Imitation Learning
Decision Transformer
Just treat RL as a sequence modeling problem
Solution:
- Do not use Transformers in RL!
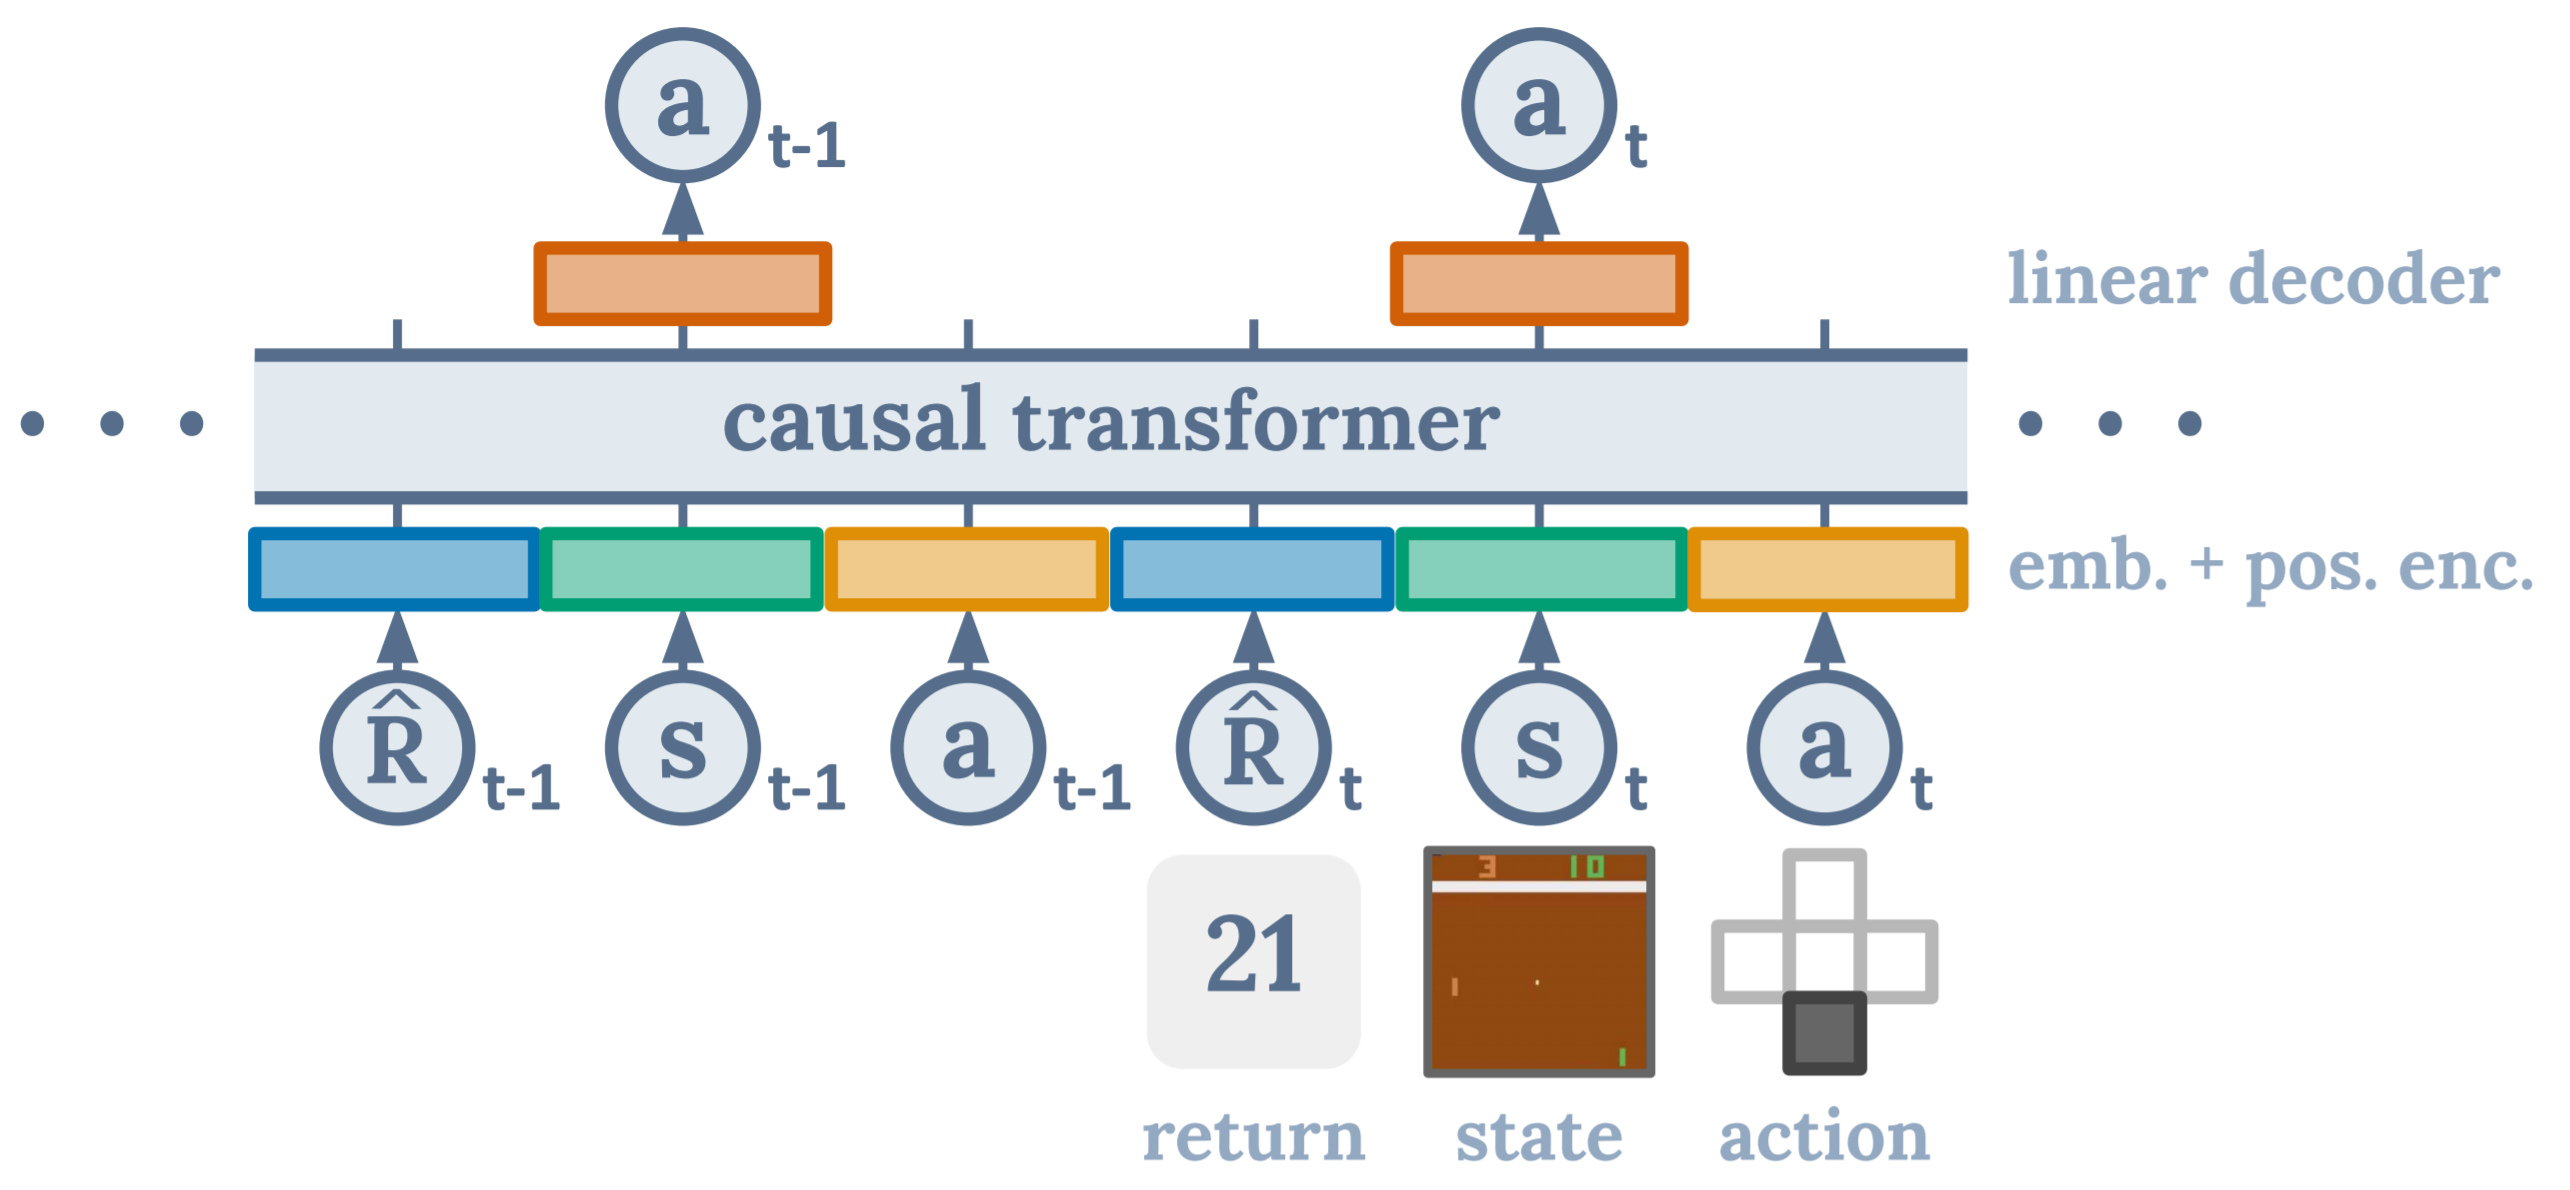
encode each step with three tokens
Reward-to-Go:
\(R_t=\sum^T_{i=t} r_i\)
Decision Transformer: Reinforcement Learning via Sequence Modeling (Chen et al. 2021) |NeurIPS 2021
Decision Transformer
Training Decision Transformer:
- Train as in usual sequence learning task
- Can use suboptimal trajectories
Inference with Decision Transformer:
- Use first Reward-to-go \(R_0\) as promt in regular Transformers
Solution:
- Do not use Transformers in RL!
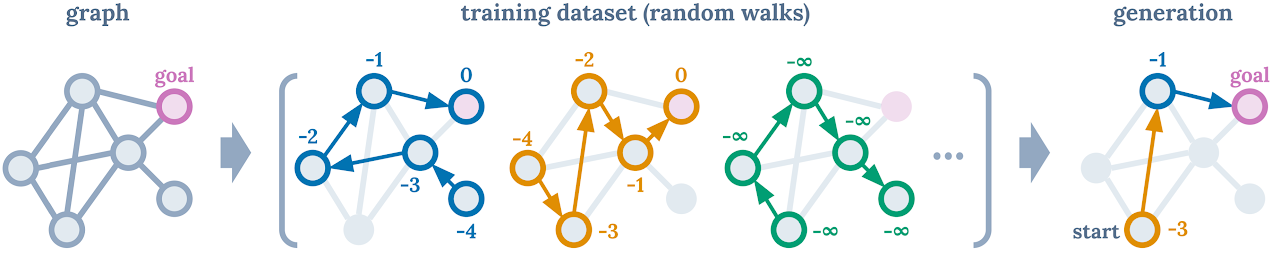
Decision Transformer: Reinforcement Learning via Sequence Modeling (Chen et al. 2021) |NeurIPS 2021
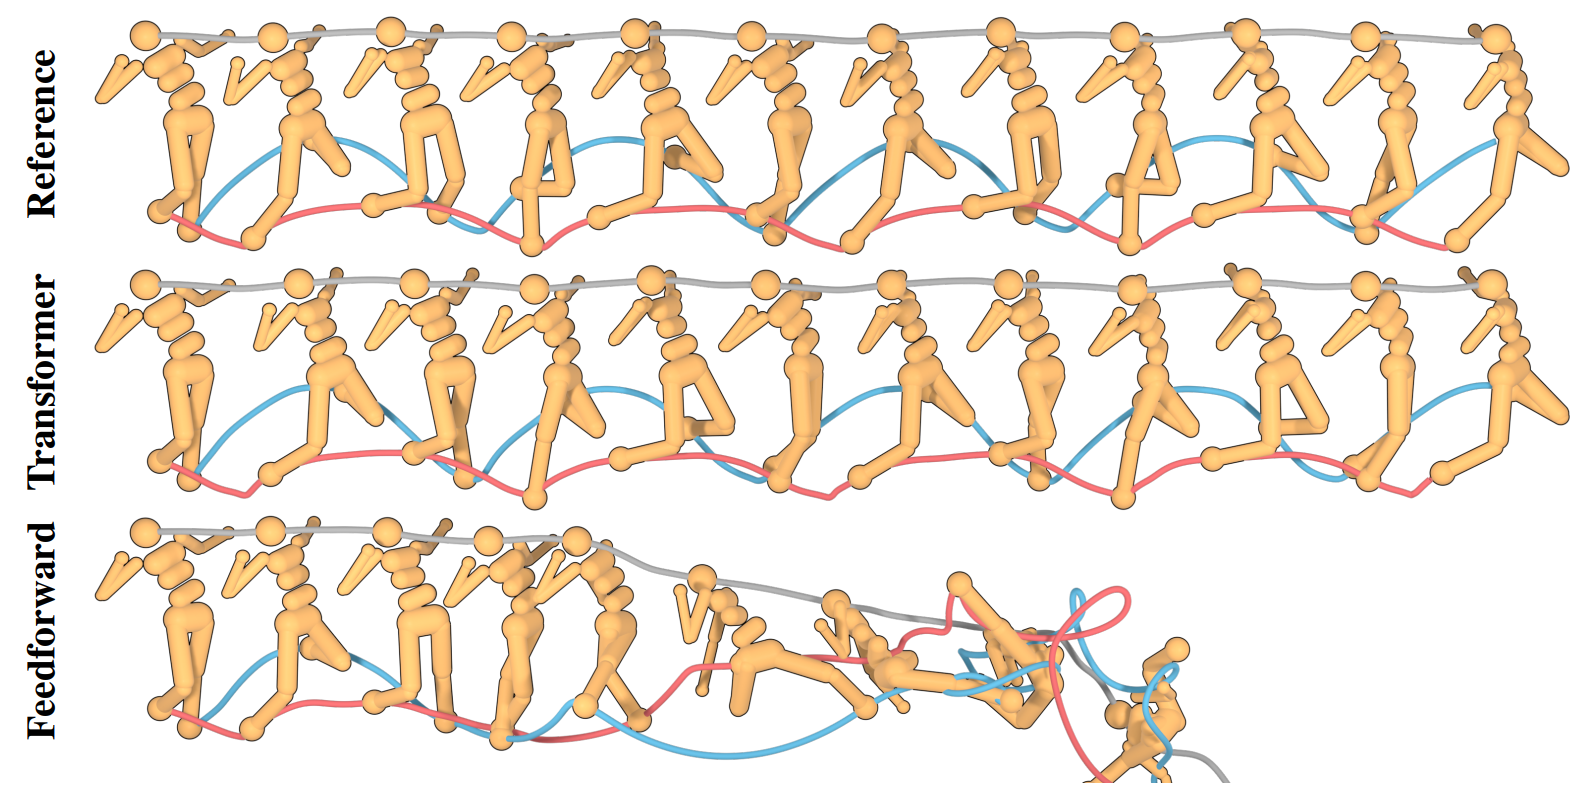
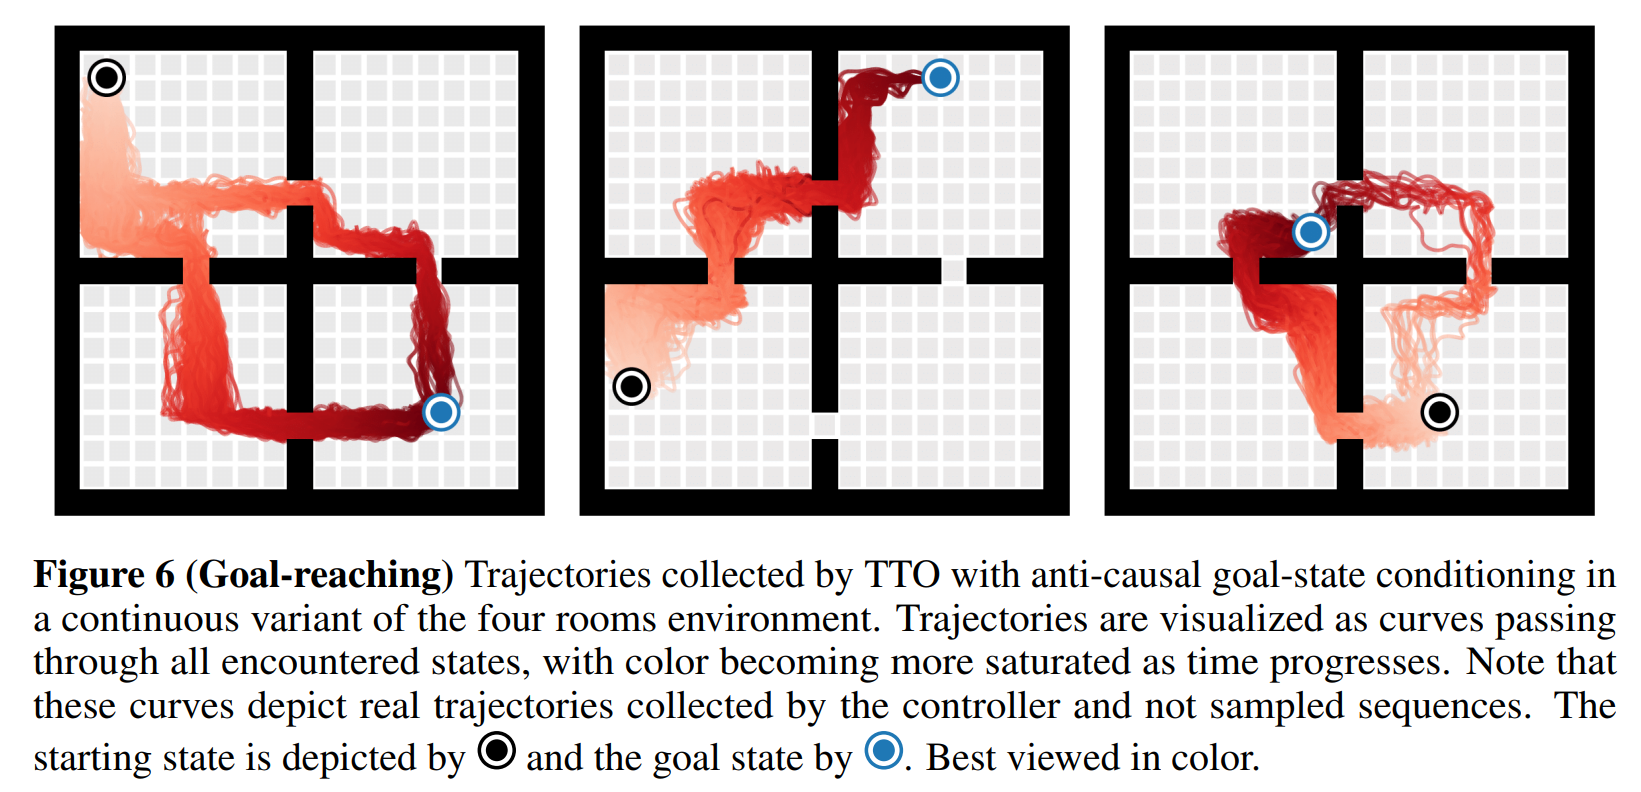
Trajectory Transformer
Differences with Decision Transformer:
- Each states and actions are split into many tokens
- Uses Beam Search to select actions (see 1.)
- Can learn goal-directed behaviour by using goal state as promt
Solution:
- Do not use Transformers in RL!
Offline Reinforcement Learning as One Big Sequence Modeling Problem (Janner et al. 2021) |NeurIPS 2021
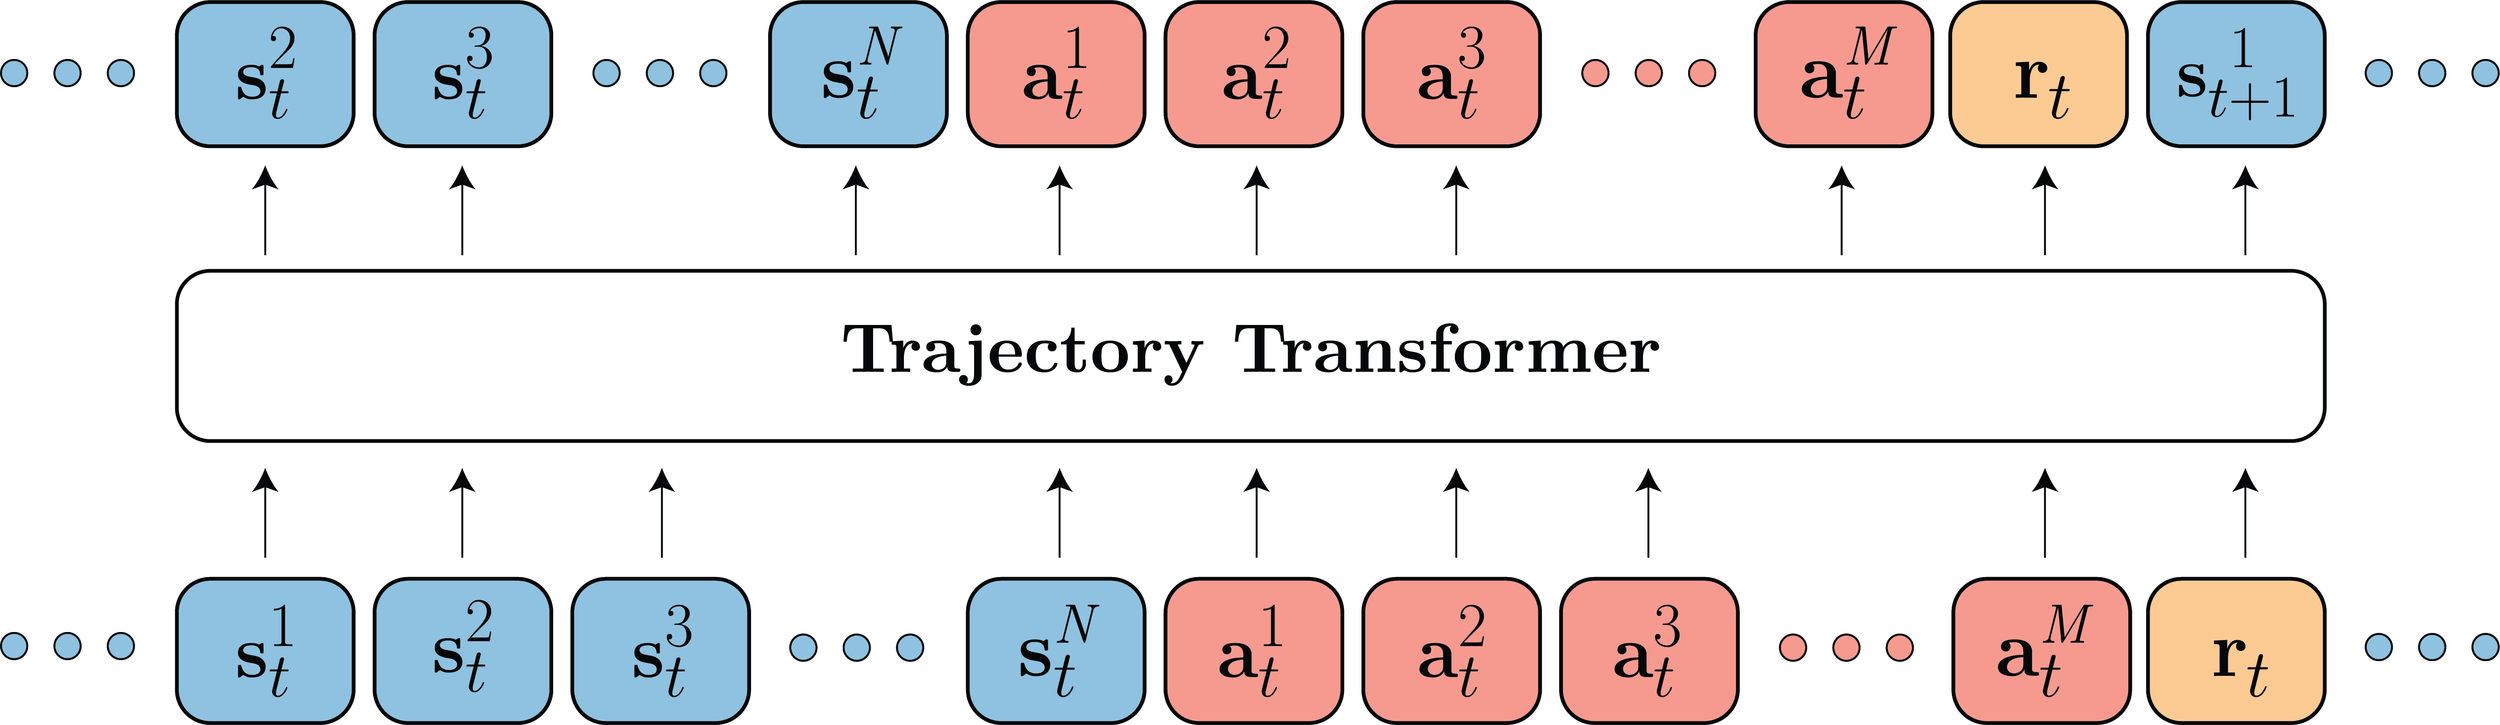
Append goal state here

Results
Decision Transformer:
Solution:
- Do not use Transformers in RL!
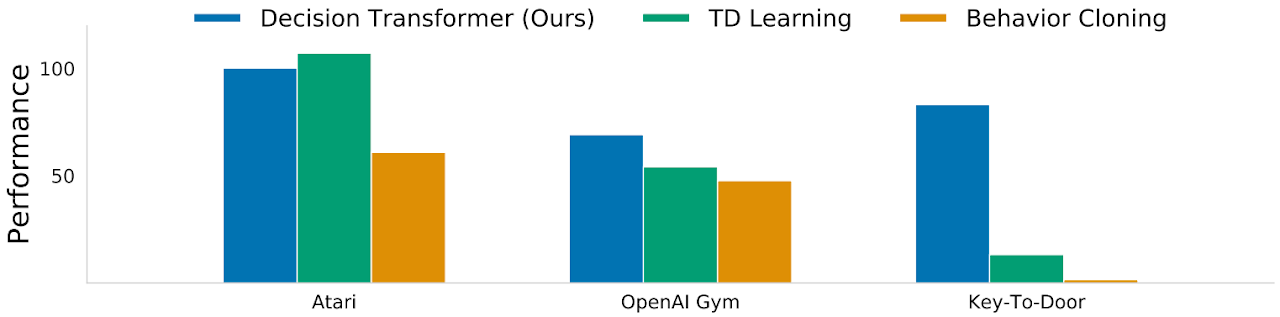
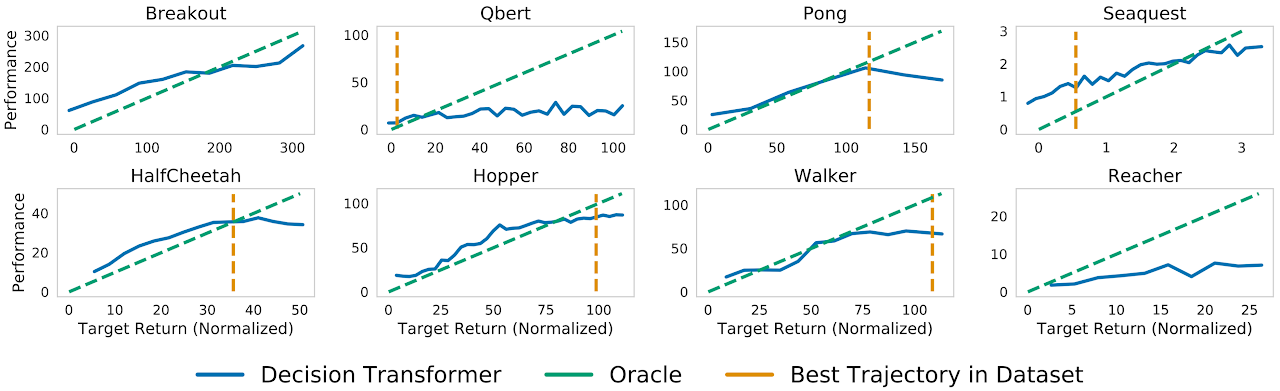
Results
Trajectory Transformer:
Solution:
- Do not use Transformers in RL!
Hindsight Information Matching
Trajectory Transformer and Decision Transformer learn to generate tragectories that match with some statistics about the future
Solution:
- Do not use Transformers in RL!
Generalized Decision Transformer:
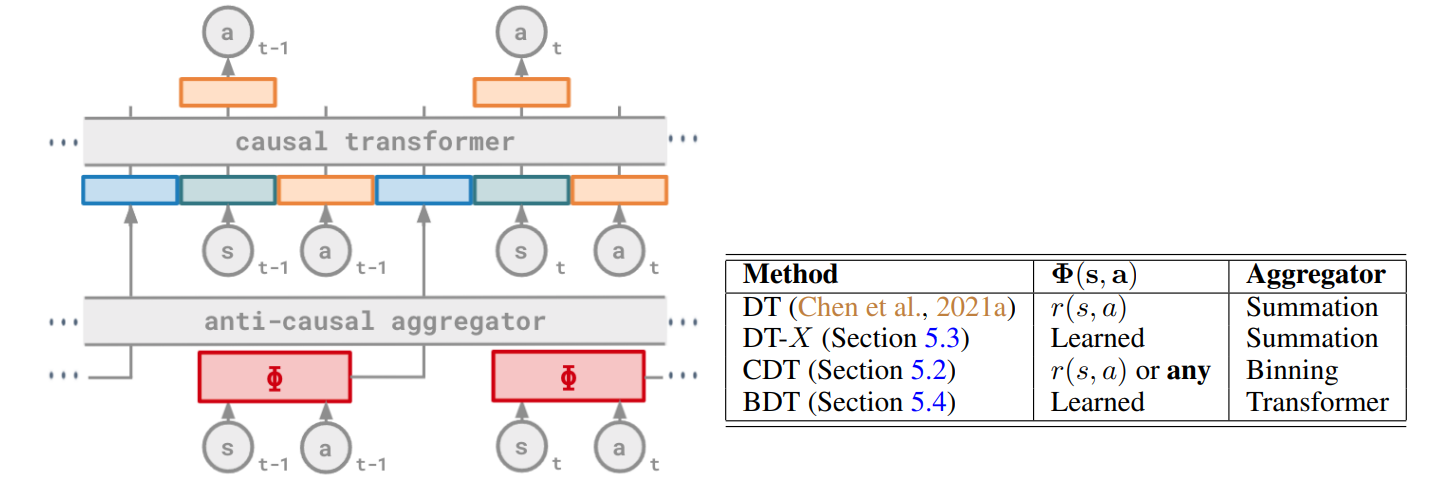
DT: \(r(s_t, a_t)\)
TT: \(s_t\)
DT: summation
TT: select last
Generalized Decision Transformer for offline Hindsight Information Matching (Furuta et al) | ICLR 2022
HIM: Unseen HalfCheetah Task
Future statisitcs: Discretized X-velocity
Solution:
- Do not use Transformers in RL!


Backflipping Dataset
Running Dataset
Results for combined distribution promt:

Generalized Decision Transformer for offline Hindsight Information Matching (Furuta et al) | ICLR 2022
HIM: Unseen HalfCheetah Task
Solution:
- Do not use Transformers in RL!
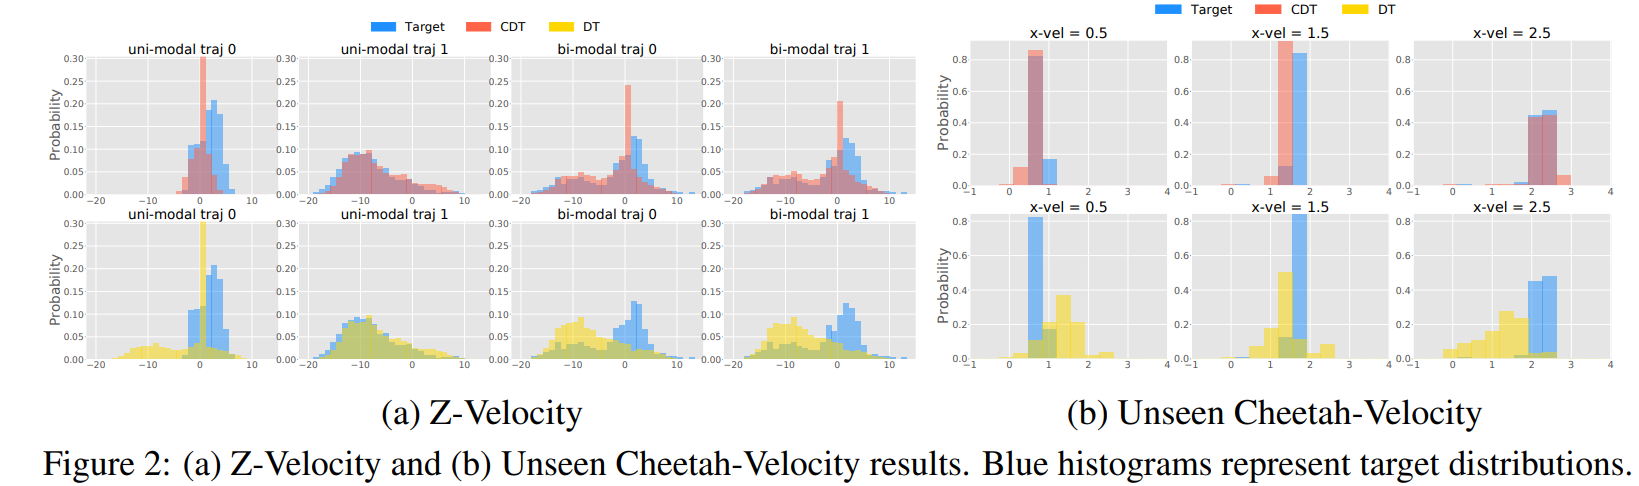
Generalized Decision Transformer for offline Hindsight Information Matching (Furuta et al) | ICLR 2022
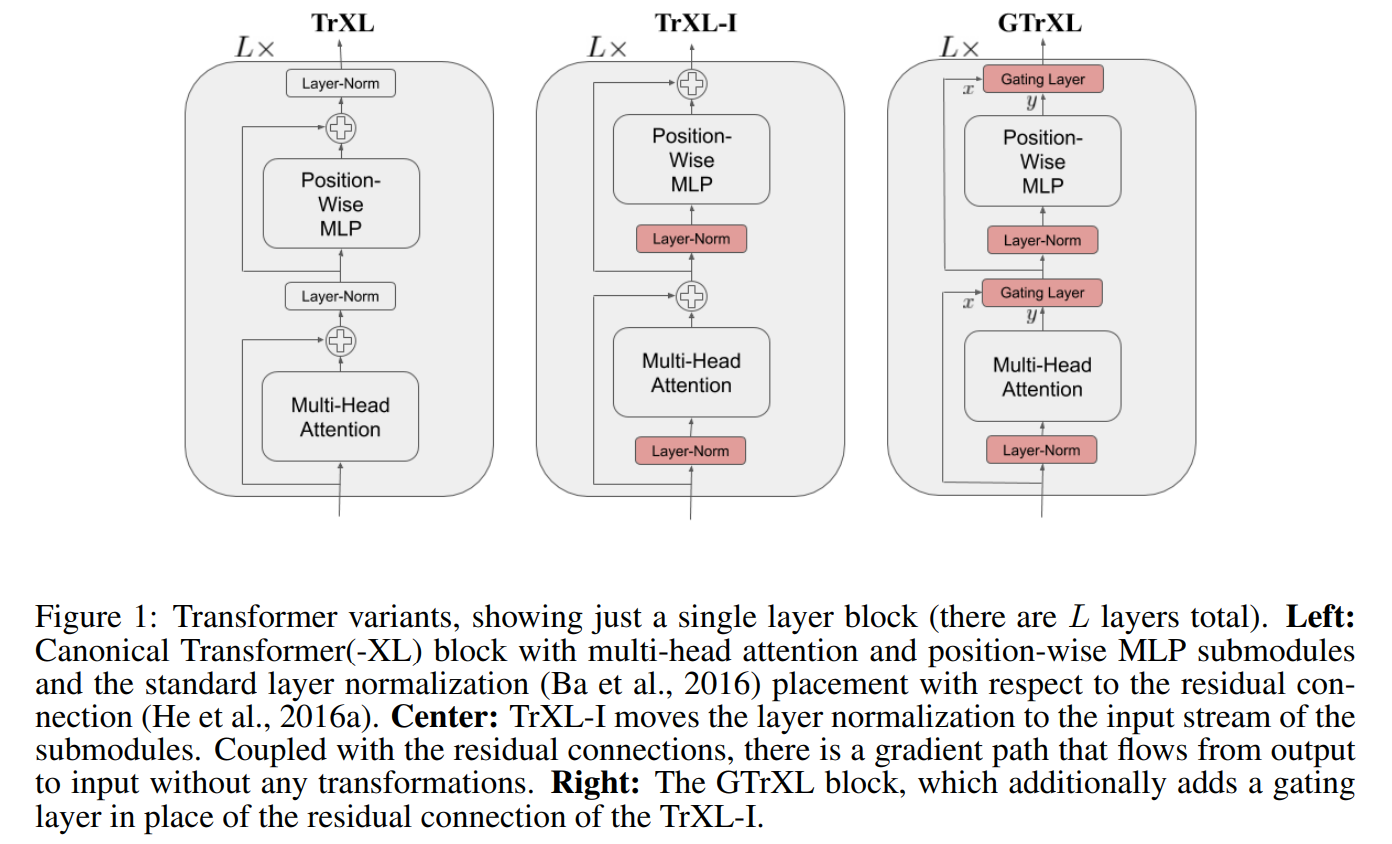
Stabilizing Transformers for RL
Stabilizing Transformers For Reinforcement Learning (Parisotto et al) | ICML 2020
Stabilizing Transformers for RL
Gating Layer
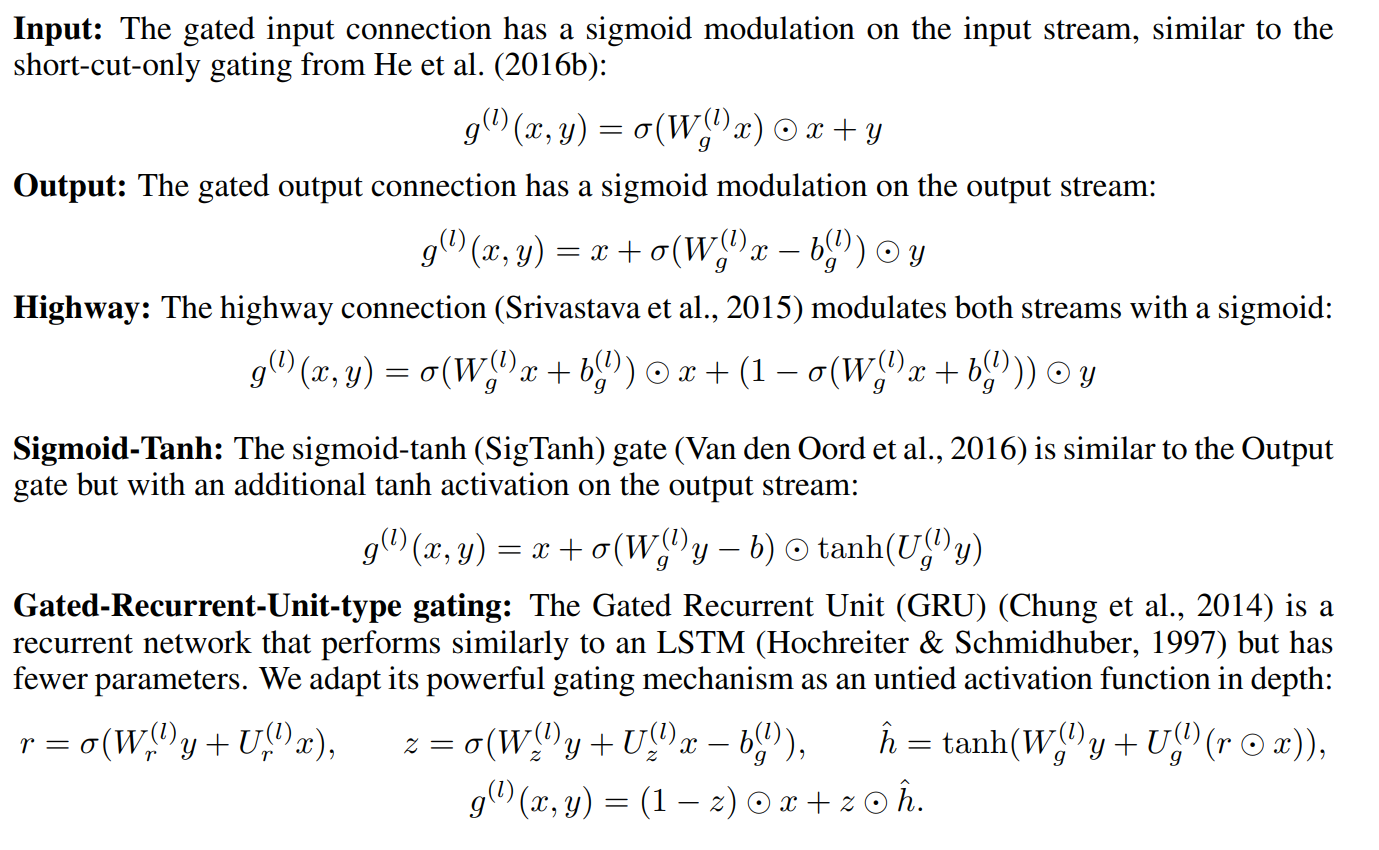
Stabilizing Transformers For Reinforcement Learning (Parisotto et al) | ICML 2020
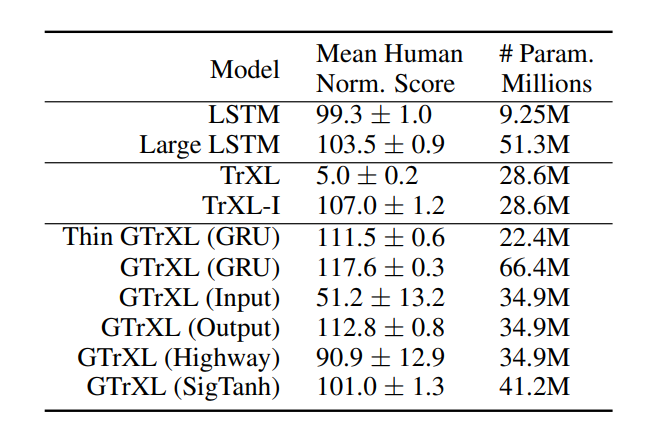
Stabilizing Transformers for RL
Experiments
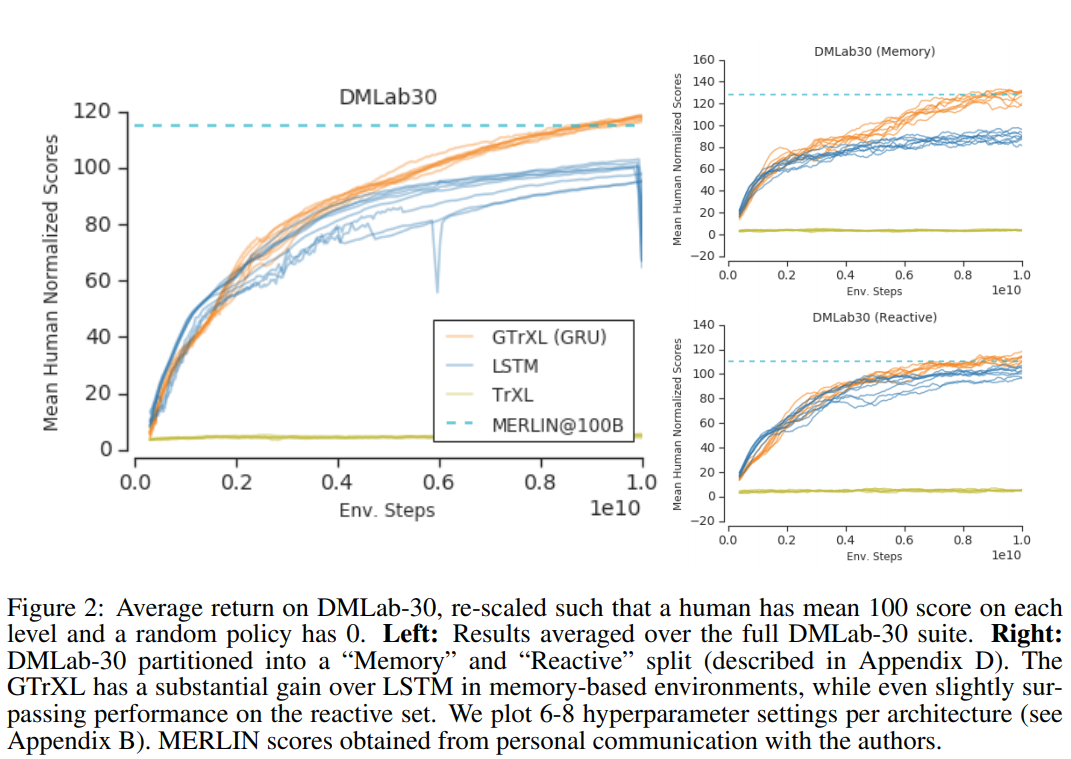
Stabilizing Transformers For Reinforcement Learning (Parisotto et al) | ICML 2020
Stabilizing Transformers for RL
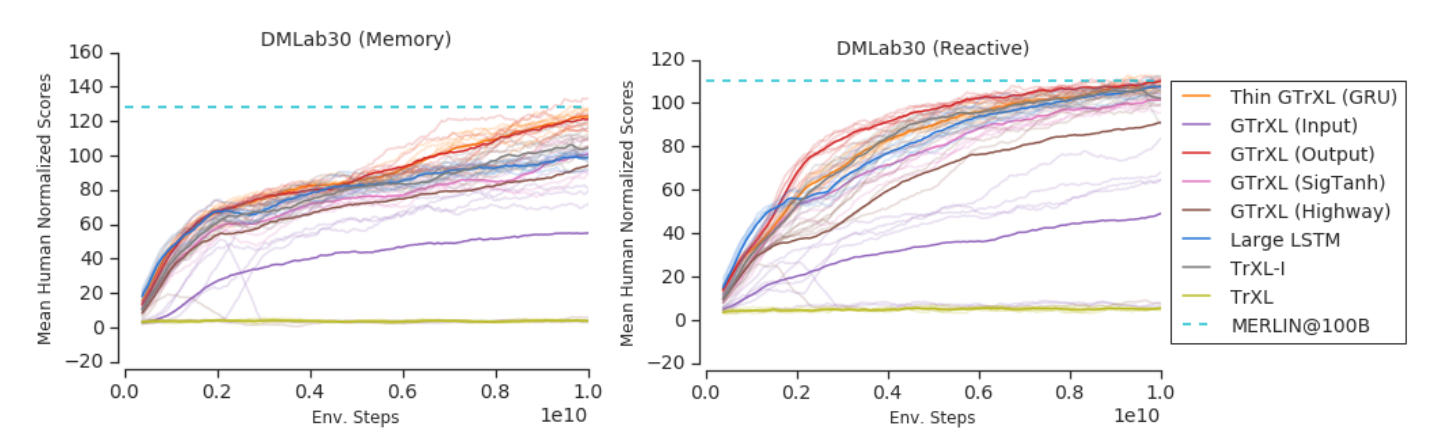
Ablation Study
Stabilizing Transformers For Reinforcement Learning (Parisotto et al) | ICML 2020
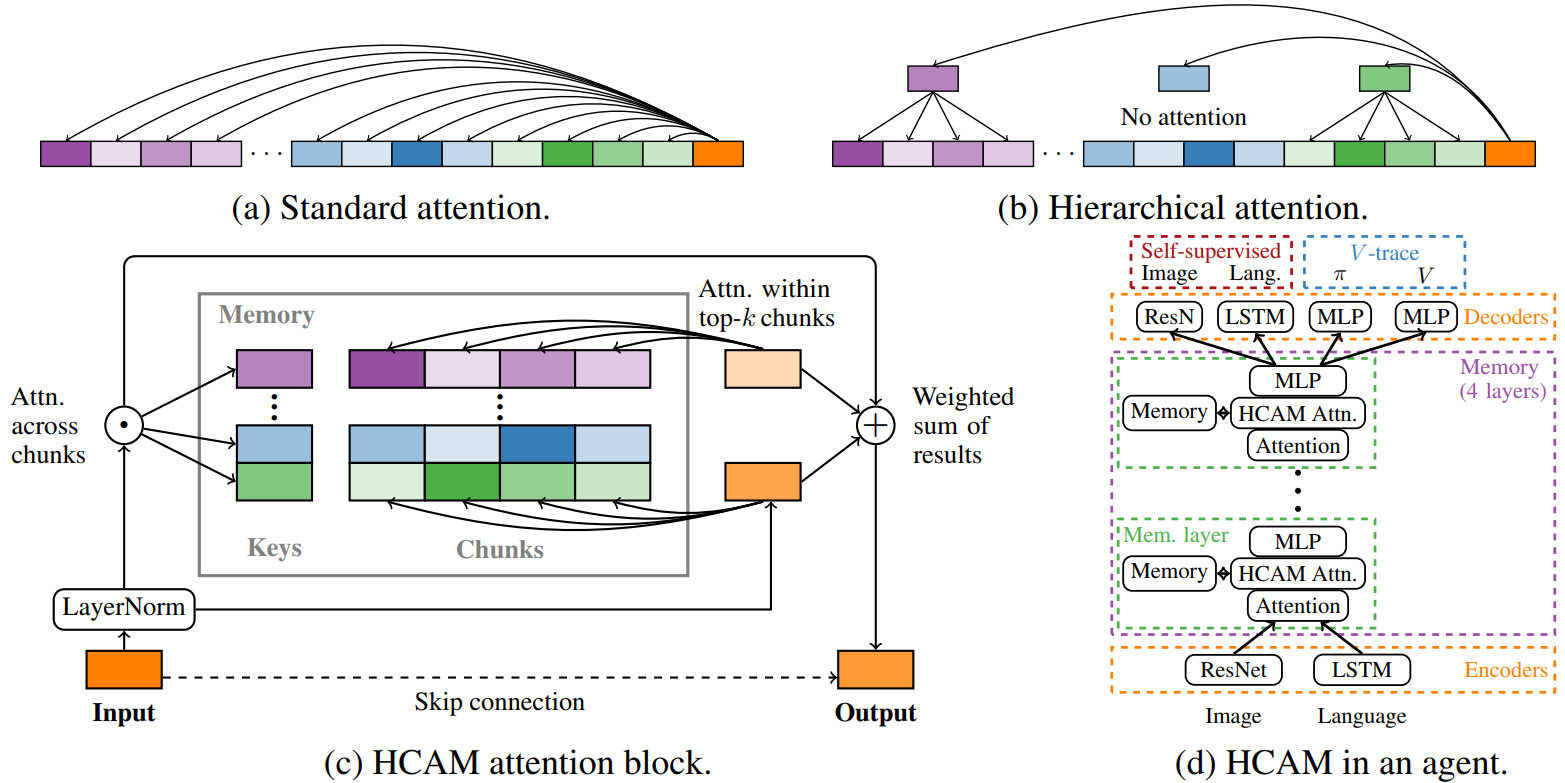
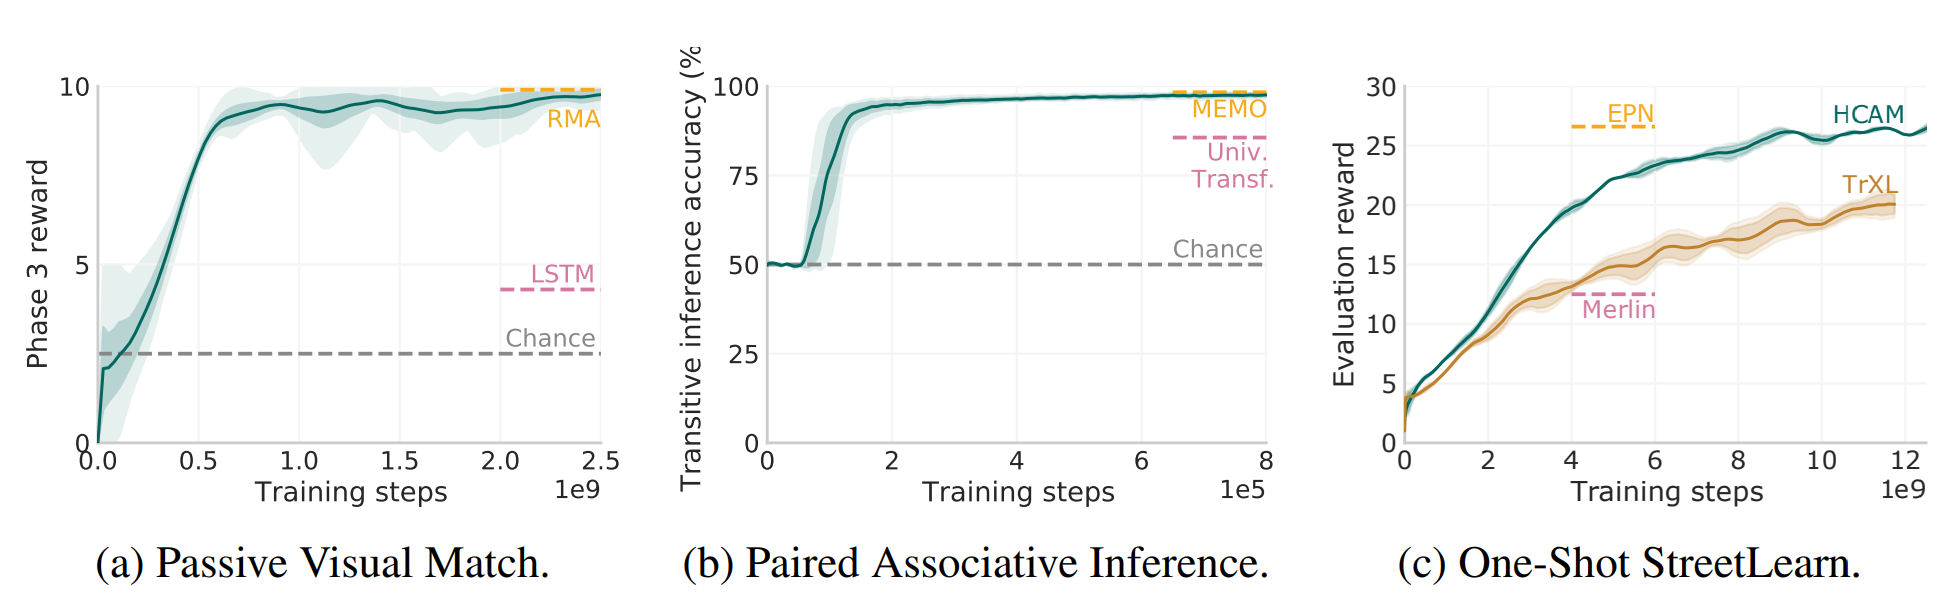
Hierarchical Chunk Attention Memory
HCAM
Towards mental time travel: a hierarchical memory for reinforcement learning agents (Lampinen et al) | NeurIPS 2021
Hierarchical Chunk Attention Memory
Results
Towards mental time travel: a hierarchical memory for reinforcement learning agents (Lampinen et al) | NeurIPS 2021
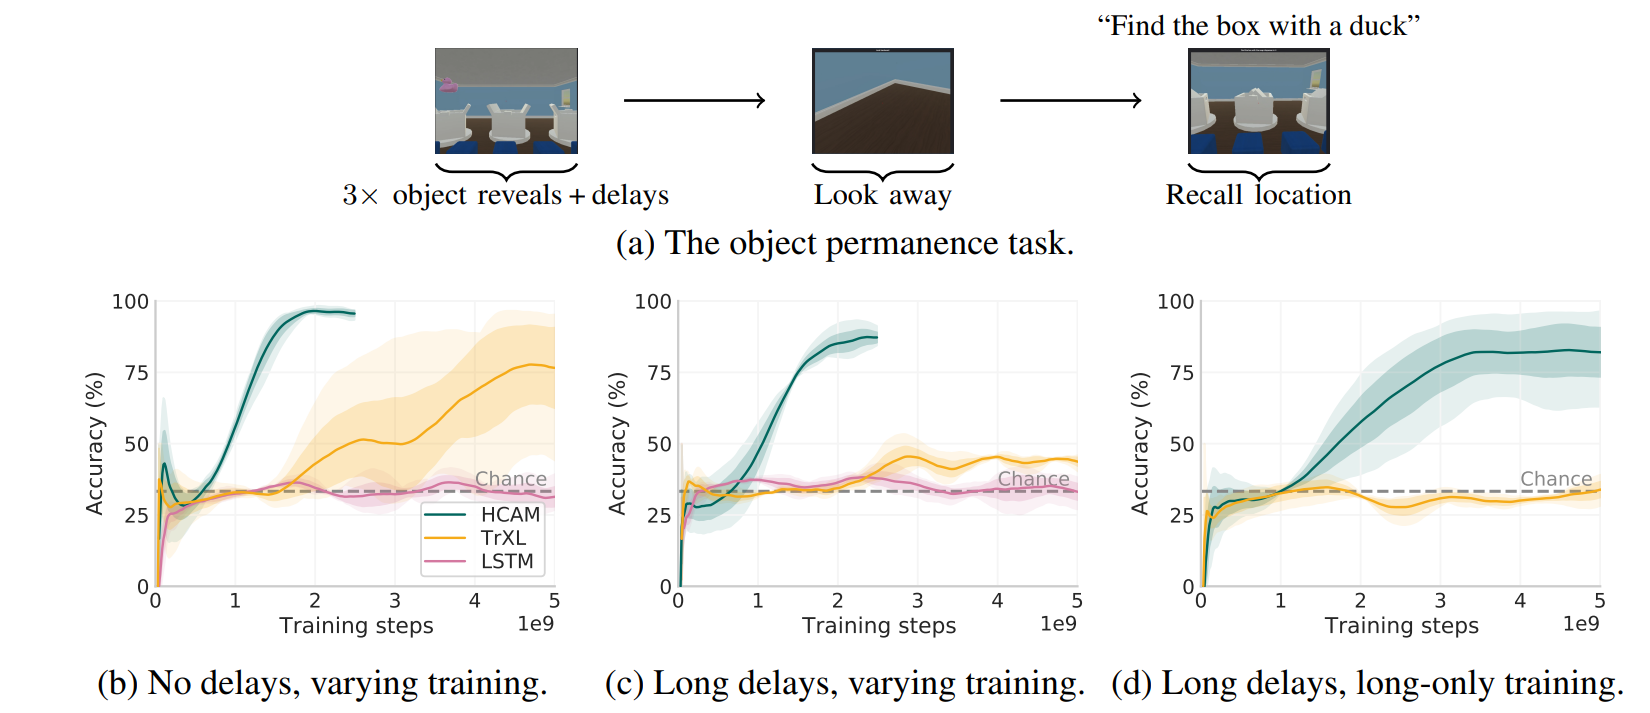
Long delay == 30 seconds
Hierarchical Chunk Attention Memory
Results
Towards mental time travel: a hierarchical memory for reinforcement learning agents (Lampinen et al) | NeurIPS 2021
Resume
Recurrent Memory
- LSTM, AMRL are simple to implement
- Still decent performance (in comparison to Transformers)
- Can easily plag and play any RNN model from SL papers
Transformer Memory
- Hard to implement and train in online RL
- Better results if works
- Good in offline RL
- Out of the box Multi-Task and Few-shot learning
Thank you for your attention!
Working memory in RL (Sirius)
By supergriver