It Could Be Worse: Lessons Learned In Distributed Systems Disasters
About Me
John Wittrock
Senior Software Engineer, Real Time Platform
@johnwittrock
jwittrock@appnexus.com
A Brief History of Time
Where are we, architecturally?
How did we get here?
...Do we like it here?
the work of many, many people
web page / SSP
Impbus
CM
Data
Providers
RTPP
Ext.
Bidders
AN
Bidder
Batches
Packrat
1
2
3
4
5
6
7
~120ms
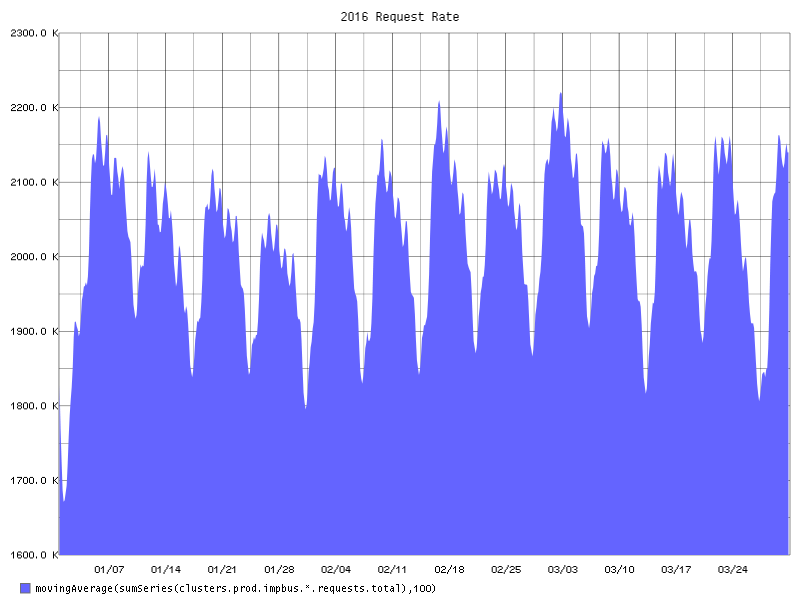
Scale
It's all in C.
Core concepts
Data distribution reliability
Traffic availability
Performance across networks
C strugglez
Workload
2009: Multiprocess apps, all using the same external port.
- no crosstalk between machines of the same application
- ...had some memory issues
Batches
Worker events
Batches
Worker events
Po
r
t
80
Workload
2013: Multithreaded, single writer
Batches / Control
Worker events
Po
r
t
80
Worker events
Process
Workload
2014: Multithreaded, single writer
Workload
2014: Multithreaded, single writer
Thread 12 (Thread 0x7ffff5ed0a50 (LWP 17893)):
#0  0x00000033126306f7 in kill () from /lib64/libc.so.6
#1  0x00007ffff6d5fa62 in mmap () from /usr/local/lib64/libgimli.so.0
#2  0x00007ffff6d5fa89 in mmap () from /usr/local/lib64/libgimli.so.0
#3  <signal handler called>
#4  0x0000000000474120 in find_index (tree=0x7ffcc43ffa60, key=0x7fffffffe648) at ../common/btree.c:77
#5  0x0000000000474907 in btree_delete (tree=0x7ffcc43ffa60, key=0x7fffffffe648) at ../common/btree.c:152
#6  0x00000000004783ea in remove_int_from_set (set=<value optimized out>, val=69) at ../common/int_set.c:131
#7  0x00000000005332ed in segment_bidder_access_remove (s=0x7fff961637b0, bidder_id=<value optimized out>) at ../common/cache/segment.c:244
#8  0x00007fffe3f9b43a in receive (src=<value optimized out>, buf=<value optimized out>, len=<value optimized out>, cookie=<value optimized out>) at member_data_access_segment.c:22
#9  _member_data_access_segment_parse (src=<value optimized out>, buf=<value optimized out>, len=<value optimized out>, cookie=<value optimized out>) at member_data_access_segment.c:10
#10 0x00000000004583fe in batch_process_object (src=0x7ffff56d1480, buffer=<value optimized out>, len=7206) at ../common/batches.c:1595
#11 batch_process (src=0x7ffff56d1480, buffer=<value optimized out>, len=7206) at ../common/batches.c:1795
#12 0x00000000004585d2 in batch_receive_chunk (req=0x7ffd950723e0, arg=0x7ffff56d1480) at ../common/batches.c:2048
#13 0x0000000000470386 in dp_read (fd=<value optimized out>, what=<value optimized out>, arg=0x7ffdcddf1800) at ../common/dnspool.c:1470
#14 0x00007ffff6b4a757 in event_process_active_single_queue (base=0x7ffff5448604, activeq=0x7ffff558d1b4, max_to_process=<value optimized out>, endtime=<value optimized out>) at event.c:1526
#15 0x00007ffff6b4af87 in event_process_active (base=0x7ffff5448604, flags=<value optimized out>) at event.c:1610
#16 event_base_loop (base=0x7ffff5448604, flags=<value optimized out>) at event.c:1833
#17 0x00000000005c2cd5 in main (argc=<value optimized out>, argv=<value optimized out>) at impbus_main.c:198
Workload
2014: Multithreaded, single writer
Workload
Validation Engines
On the batches boxes, run a copy of the prod app, verify that it's okay before you distribute wider.
VE
:)
Prod Apps
:)
:)
Workload
2016: Everything is great! Until you screw up.
Benefits and drawbacks to single-writer:
- data structures
- simple threading models
Really a decision made by necessity, but turned out well.
Workload
2016: Great! Until you screw up.
Two types of crashes:
- data distribution
- traffic
Workload
Data Distribution
- This low-frequency write workload allows us to be single writer
- But that single writer can bring down the world
- When that happens, how do we turn back time?
- max_ts - prevent distribution past a timestamp
Traffic
Traffic
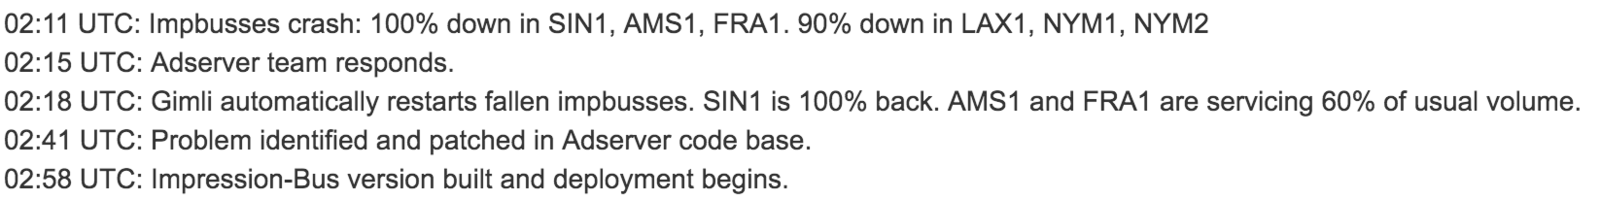
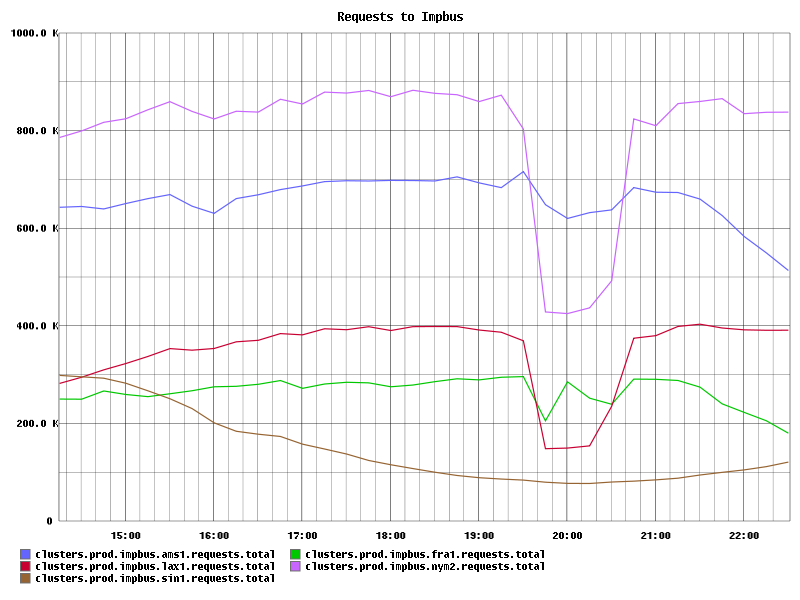
Bad traffic or bad code can machine-gun our boxes to death. Quickly.
Load balancers make the crashes fair, I guess....
Traffic
We can't turn back time like with max_ts
But how can we limit traffic crashes? Servers grouped by collection.
Can we turn off traffic quickly?
Feature switches and AN_HOOK
Traffic
core_me_maybe
Replace crashing with leaks!
But what happens when your system isn't actively destroying itself?
A distributed system is only as good as its performance in failure modes, because a distributed system is always failing.
With 6000 nodes, something is literally always broken.
We build our code to expect failure as normal operation.
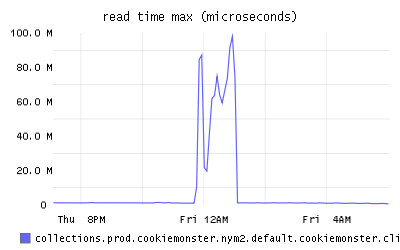
Load Conditions
We actually care more about consistency than peak performance.
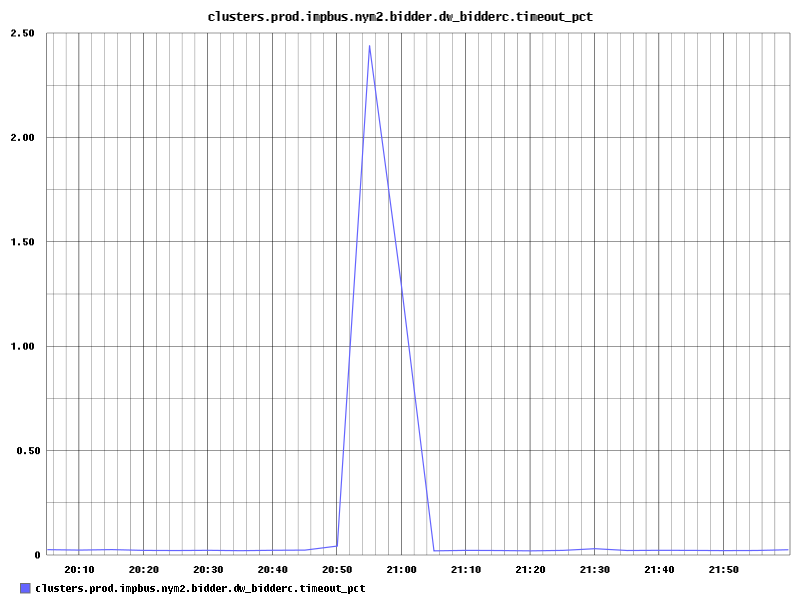
Some Things Only Happen Under Load
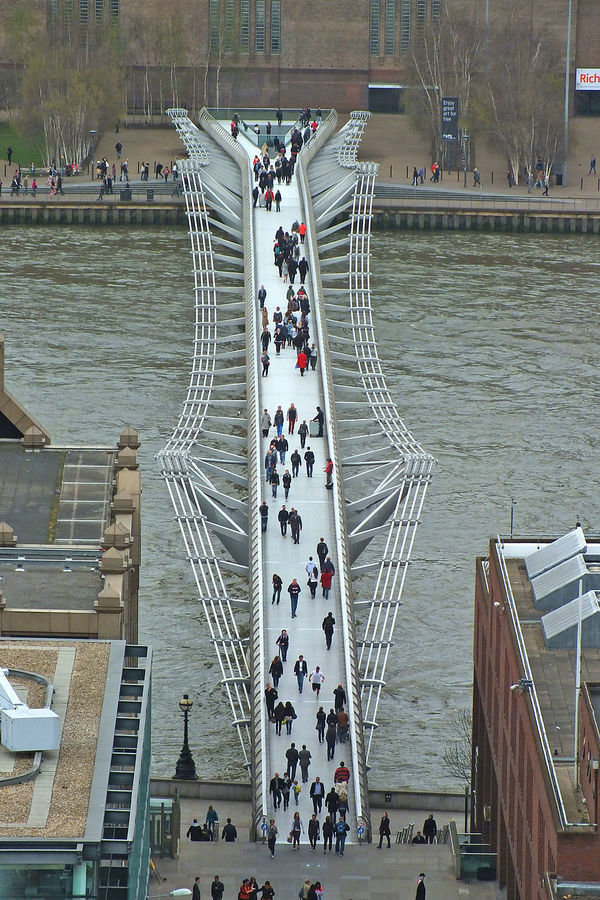
By Jan Kameníček - Own work, CC BY-SA 3.0 https://commons.wikimedia.org/w/index.php?curid=32543484
Overload Conditions
What happens when you've just slightly run out of capacity?
Overload Conditions
Network flow plays a huge role here - it's hard to detect transient perf degradation on a single node.
Network Flow
Router
Shard 1
p = 99.9%
Losing a single shard dependency can bring down the whole shard.
p = 60%
Backing
provider
This gets worse and worse as you add more layers, especially as you add queues.
Network Flow
Router
Required
Source 1
10ms
5ms
Backing
provider
Required
Source 2
65ms
55ms
Backing
provider
If you require sources to respond before you act, you'll start to use your entire timeout period - errors amplify themselves.
total: 75ms
:(
Network Flow
In this case, a single node's bad performance can bring down the performance of the whole cluster, and cause cascading issues.
Answer? Might be more sharding.
Network Flow
Sources of Jitter
Reads vs. writes
Expensive members
Network Flow
Okay, how the hell do you understand behavior like this?
Samples per quantile: 3047
Quantile 0: 1.000000 to 1.000000
Quantile 1: 1.000000 to 1.000000
Quantile 2: 1.000000 to 1.000000
Quantile 3: 1.000000 to 1.000000
Quantile 4: 1.000000 to 1.000000
Quantile 5: 1.000000 to 2.000000
Quantile 6: 2.000000 to 7.000000
Quantile 7: 7.000000 to 18.000000
Quantile 8: 18.000000 to 54.000000
Quantile 9: 54.000000 to 155.000000
Quantile 10: 155.000000 to 372.000000
Quantile 11: 372.000000 to 745.000000
Quantile 12: 745.000000 to 1282.000000
Quantile 13: 1282.000000 to 2024.000000
Quantile 14: 2025.000000 to 2871.000000
Quantile 15: 2871.000000 to 3781.000000
Quantile 16: 3781.000000 to 4674.000000
Quantile 17: 4675.000000 to 5702.000000
Quantile 18: 5703.000000 to 6945.000000
Quantile 19: 6945.000000 to 14510.000000
C Strugglez
Paul:"buffer[i] = (void*)((uintptr_t)buffer[i] | (1UL << 34));" is a code crime.
Maxime Henrion: >_<
Andrew Wong: (void*) makes it work anywhere
Maxime Henrion: it's magic!
Maxime Henrion: doesn't compile? add more void * casts.
Andrew Wong: that or switch the */& logic everywhere
Andrew Wong: All the combinations!
C Strugglez
The usual:
- Leaks
- Corruption
- Lack of a standard library
C Strugglez
We can fix the leaks! (by understanding our workload)
Corruption is harder, but good tooling is the most important.
- the 34th bit
C Strugglez
Paul: The tale of the 34th bit is closed.
    We CAS "snapshot & ~(1ULL << current->id)" over deallocated campaigns.
Mike Wright: ???
C Strugglez
Event 1:

- Frees memory, but not timer


- Timer fires,
  clears waiting bit of current thread

- Happens to be 34th bit
Event 2:


- Uses the same memory region for pointer


- Dereferences pointer...
C Strugglez
Paul: budget wakeup for long-deallocated campaigns.
Paul: an_array buffer takes its place.
    we basically spinlock on in_pacing_sleep by clearing out the thread's bit.
mcen: you guys should be popping bottles in the office
The Lessons
0. Understand your workload
1. Partition your workload and specialize
2. Keep network flow graphs flat
3. Use every possible feature of your environment to your advantage
4. Find a way to replicate prod, even if it means testing in prod
Questions?
itcouldbeworse
By jwittrock