OpenMP
Parallel Algorithms
David Mayerich
Scalable Tissue Imaging and Modeling (STIM) Laboratory
Department of Electrical and Computer Engineering
Cullen College of Engineering
University of Houston
David Mayerich
STIM Laboratory, University of Houston

OpenMP
-
Open Multi-Processing
-
Multi-threaded shared-memory
-
C/C++ (1998) and Fortran (1997)
-
Current Version: 6.0 (2024)
-
Primarily consists of preprocessor directives:
David Mayerich
STIM Laboratory, University of Houston
CMake Setup
project(mp_project)
#...
find_package(OpenMP)
#...
add_executable(mp_exe mp_exe.cpp)
if(OpenMP_CXX_FOUND)
    target_link_libraries(mp_exe
			PUBLIC OpenMP::OpenMP_CXX
	)
endif()
#...
OpenMP comes with your compiler, so you won't get it on vcpkg
#pragma omp construct
{
  // code affected by this construct
}
#pragma omp parallel
{
  // code to parallelize
}
num_threads(4)
OpenMP Basics
-
OpenMP uses preprocessor directives to assign work
-
Create a basic "Hello World!" application that outputs an integer
David Mayerich
STIM Laboratory, University of Houston
#include <stdio.h>

int main(int argc, char** argv) {
  int id = 0;
  printf("Hello From %d\n", ID);
}
OpenMP Basics
-
OpenMP uses preprocessor directives to assign work
-
Create a basic "Hello World!" application that outputs an integer
-
#pragma omp parallel
launch threads to do work inside the block-
How many threads?
-
Specified by the
OMP_NUM_THREADSenvironment variable:
export OMP_NUM_THREADS=4
-
David Mayerich
STIM Laboratory, University of Houston
#include <stdio.h>

int main(int argc, char** argv) {
  #pragma omp parallel
  {
  	int id = 0;
  	printf("Hello From %d\n", id);
  }
}
OpenMP Basics
-
OpenMP uses preprocessor directives to assign work
-
Create a basic "Hello World!" application that outputs an integer
-
#pragma omp parallel
launch threads to do work inside the block-
How many threads?
-
Specified by the
OMP_NUM_THREADSenvironment variable:
export OMP_NUM_THREADS=4
-
David Mayerich
STIM Laboratory, University of Houston
#include <stdio.h>
#include <omp.h>

int main(int argc, char** argv) {
  omp_set_num_threads(10);
  #pragma omp parallel
  {
  	int id = 0;
  	printf("Hello From %d\n", id);
  }
}
OpenMP Basics
-
OpenMP uses preprocessor directives to assign work
-
Create a basic "Hello World!" application that outputs an integer
-
#pragma omp parallel
launch threads to do work inside the block-
How many threads?
-
Specified by the
OMP_NUM_THREADSAPI or environment variable:
export OMP_NUM_THREADS=4
-
-
omp_get_thread_num()
retrieve an index for the current thread
David Mayerich
STIM Laboratory, University of Houston
#include <stdio.h>
#include <omp.h>

int main(int argc, char** argv) {
  omp_set_num_threads(10);
  #pragma omp parallel
  {
  	int id = omp_get_thread_num();
  	printf("Hello From %d\n", ID);
  }
}
OpenMP Basics
-
OpenMP uses preprocessor directives to assign work
-
Create a basic "Hello World!" application that outputs an integer
-
#pragma omp parallel
launch threads to do work inside the block-
How many threads?
-
Specified by the
OMP_NUM_THREADSAPI or environment variable:
export OMP_NUM_THREADS=4
-
-
omp_get_thread_num()
retrieve an index for the current thread
David Mayerich
STIM Laboratory, University of Houston
#include <stdio.h>
#include <omp.h>

int main(int argc, char** argv) {
  omp_set_num_threads(10);
  #pragma omp parallel
  {
  	int id = omp_get_thread_num();
  	printf("Hello %d ", ID);
    printf("from %d\n", ID);
  }
}
Demo
Calculate \(\pi\) with a Riemann Sum
David Mayerich
STIM Laboratory, University of Houston
\int_0^1 \frac{4}{1+x^2}dx=\pi
// set the number of steps
static long N = BIG_NUM;
double step;
int main(int argc, char** argv) {
  // step size (smaller -> accurate)
  step = 1.0/N;
  // integral becomes a summation
  double sum = 0.0;
  for(int i=0; i<N; i++) {
    // calculate the integrand
    x = (i + 0.5) * step;
    sum += 4.0 / (1.0 + x * x);
  }
  // approximate integral (pi)
  pi = step * sum;
}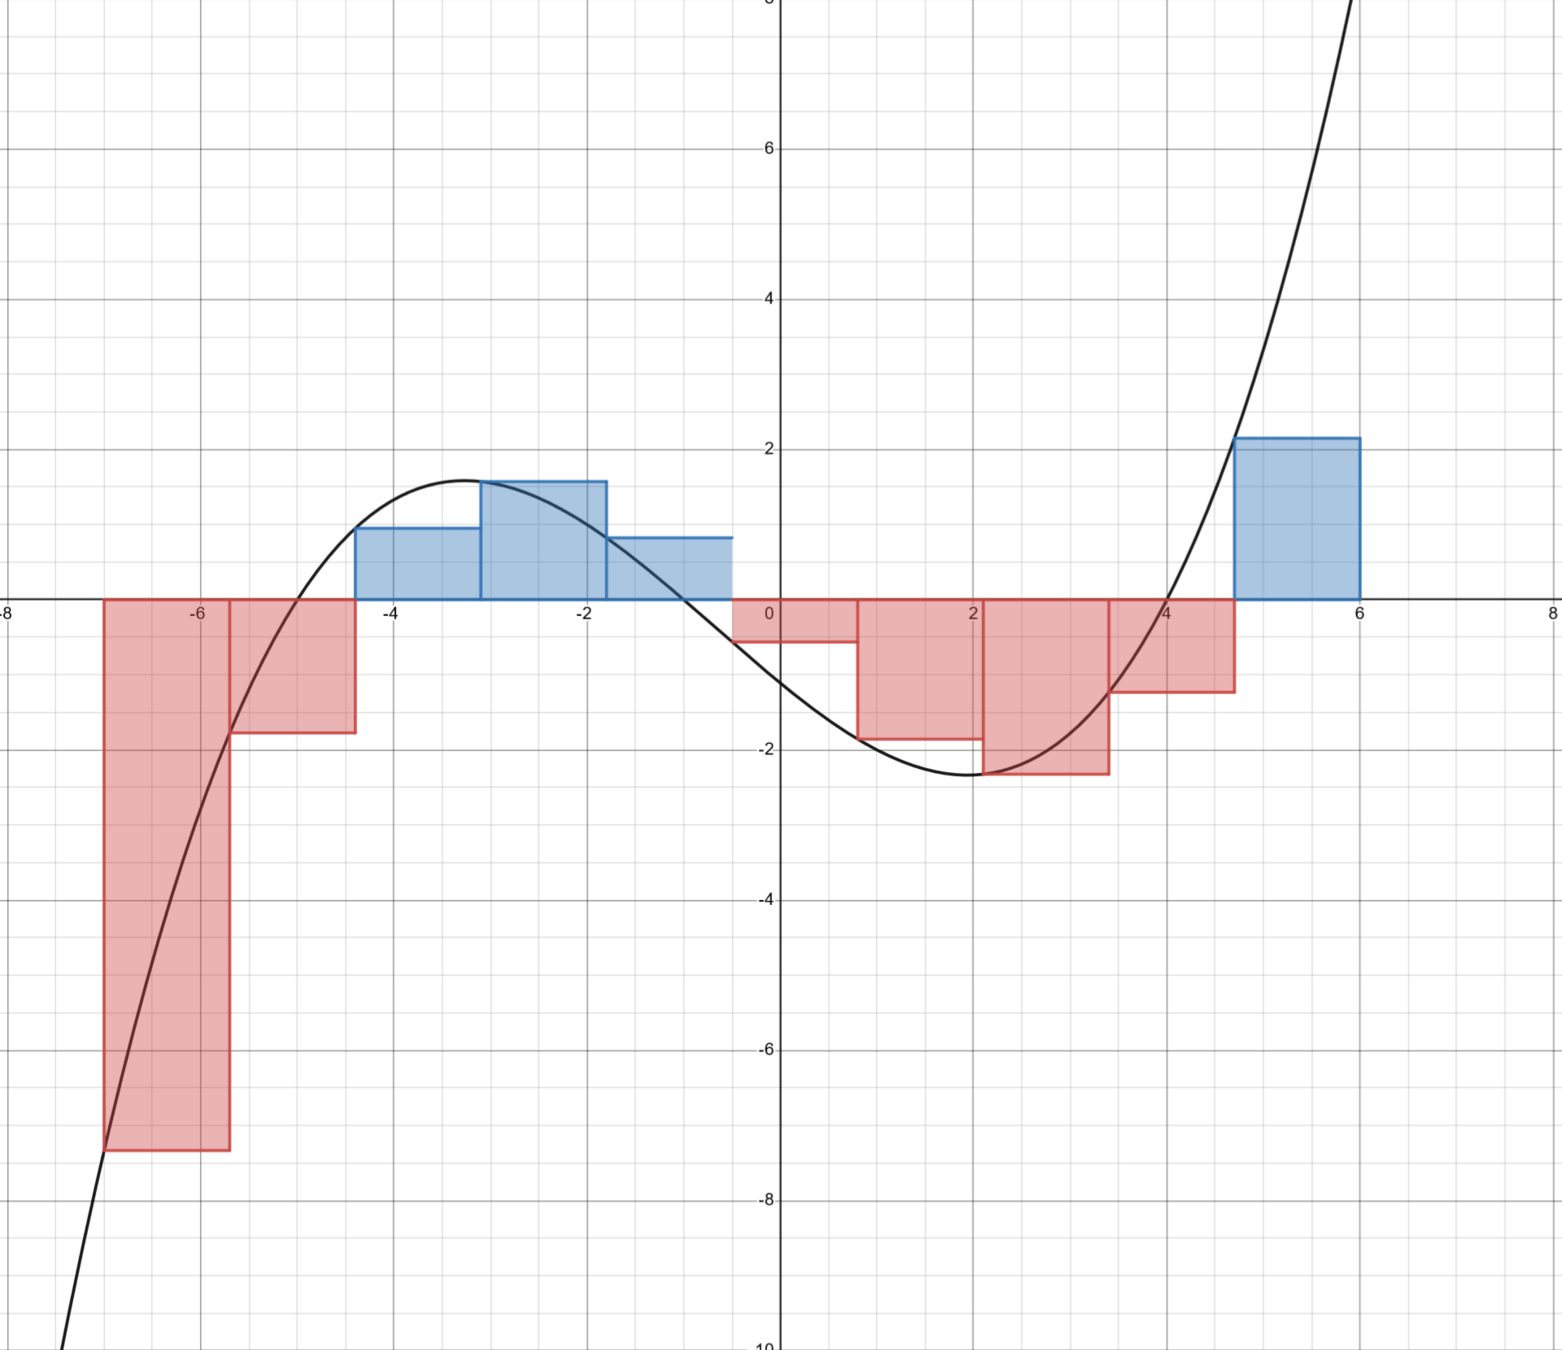
\(N=10\)
\(\Delta_x=1.44\)
\(\pi=3.14243\)
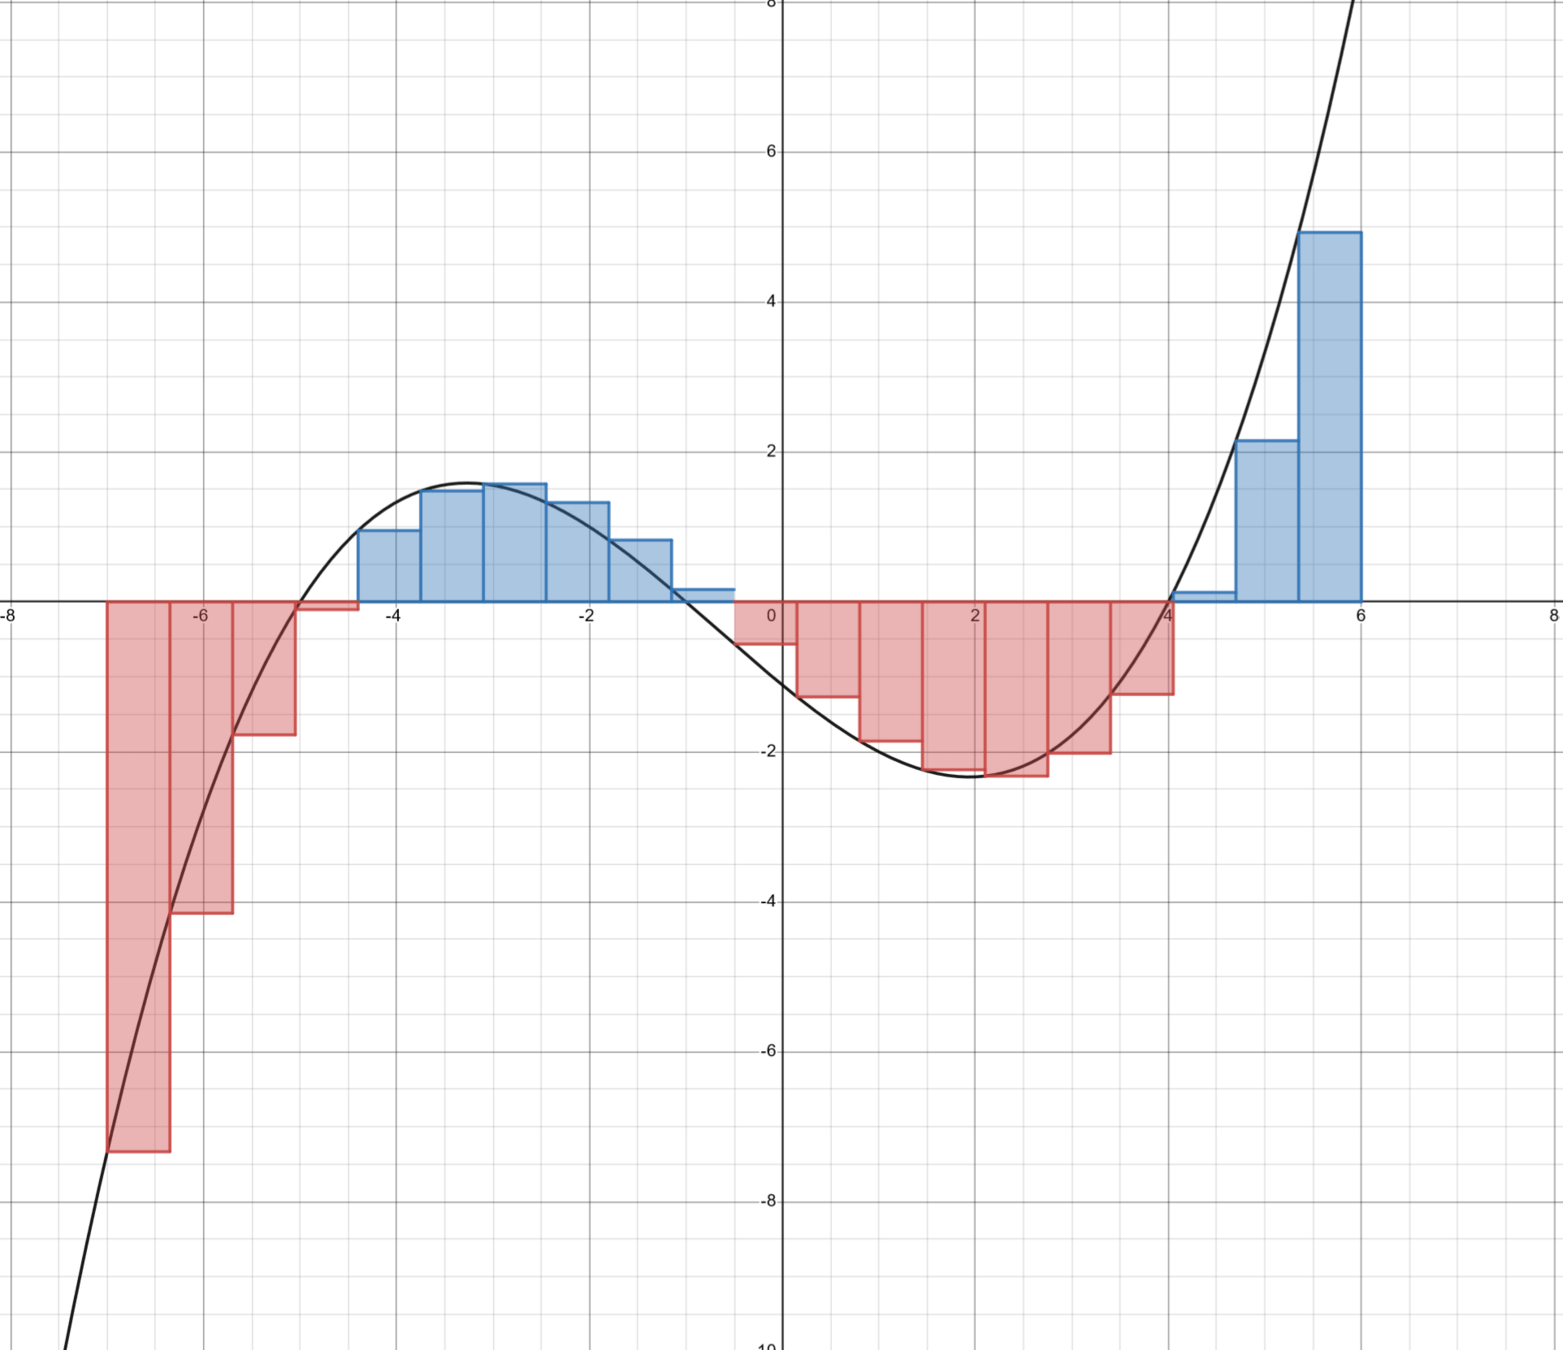
\(N=20\)
\(\Delta_x=0.684\)
\(\pi=3.14180\)
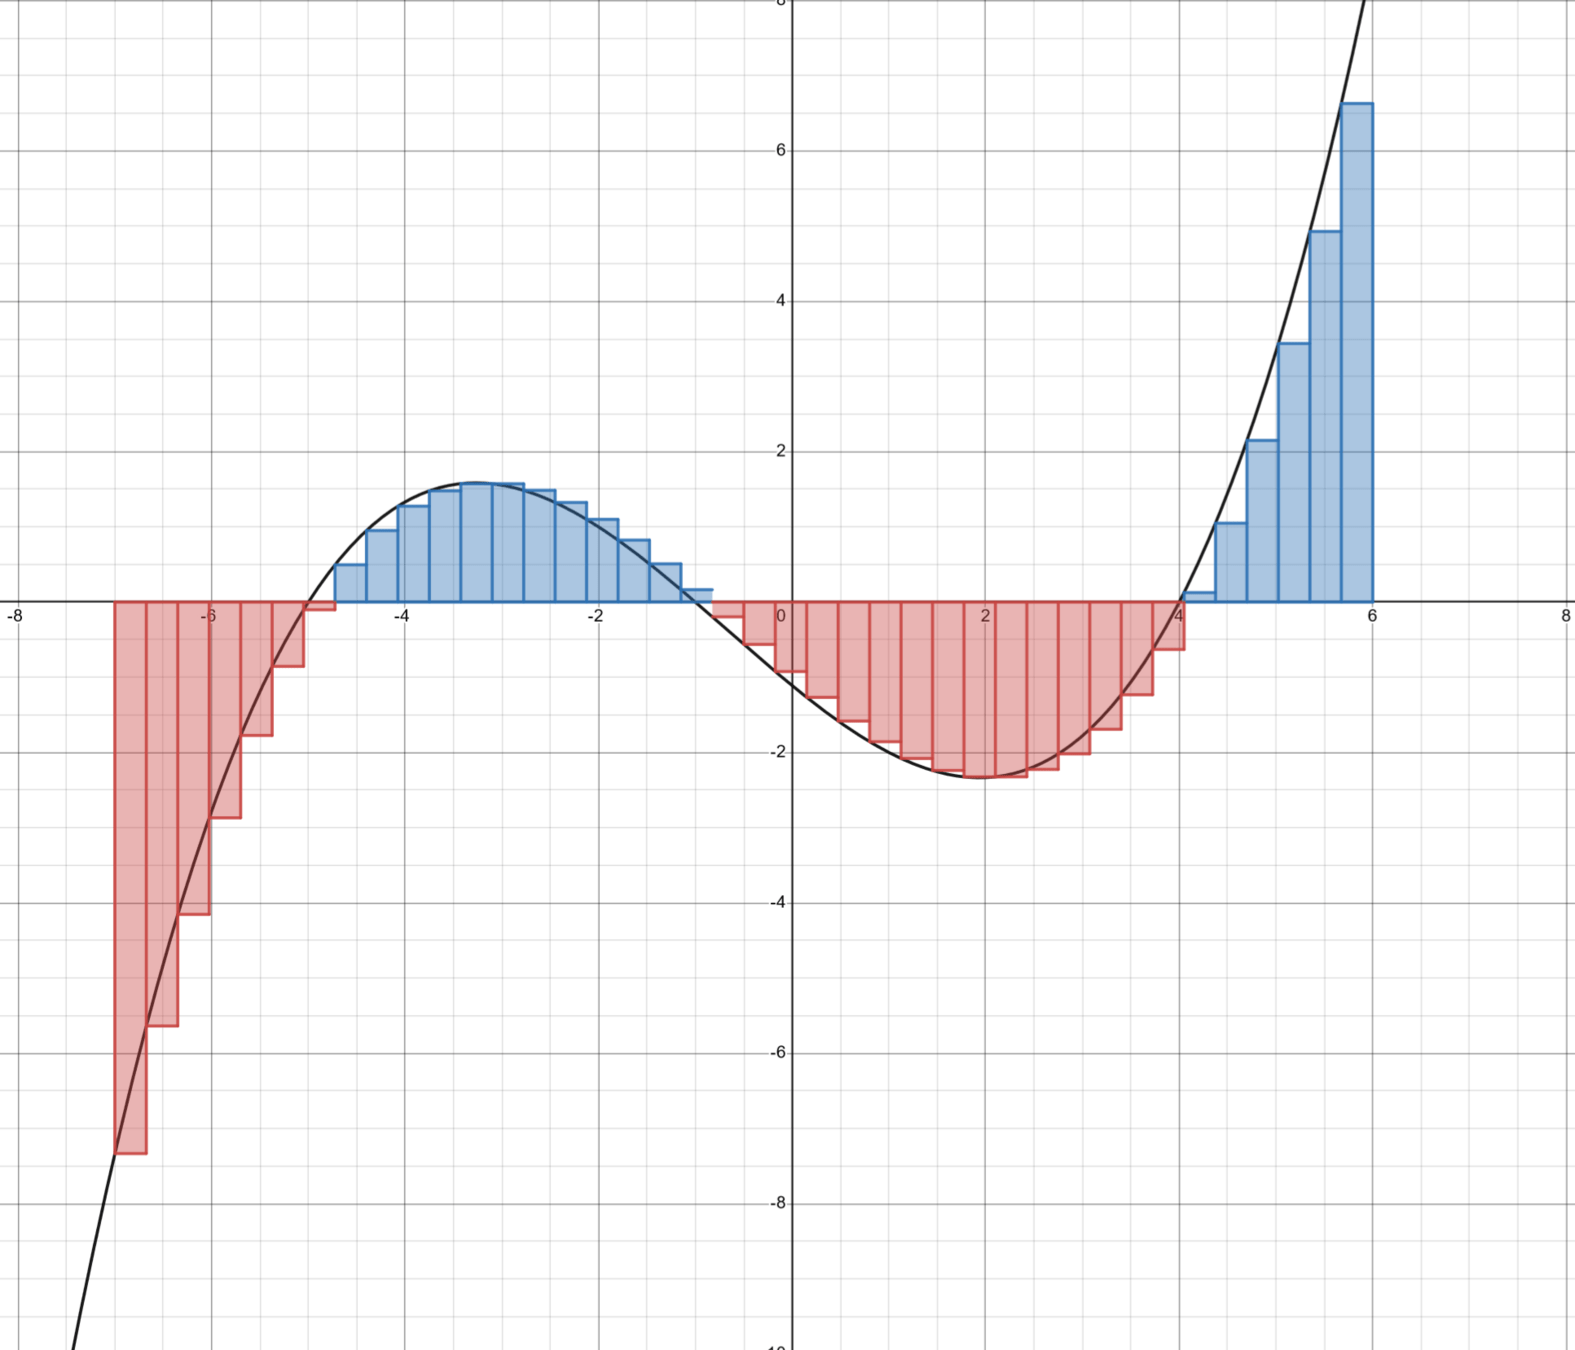
\(N=40\)
\(\Delta_x=0.333\)
\(\pi=3.14164\)
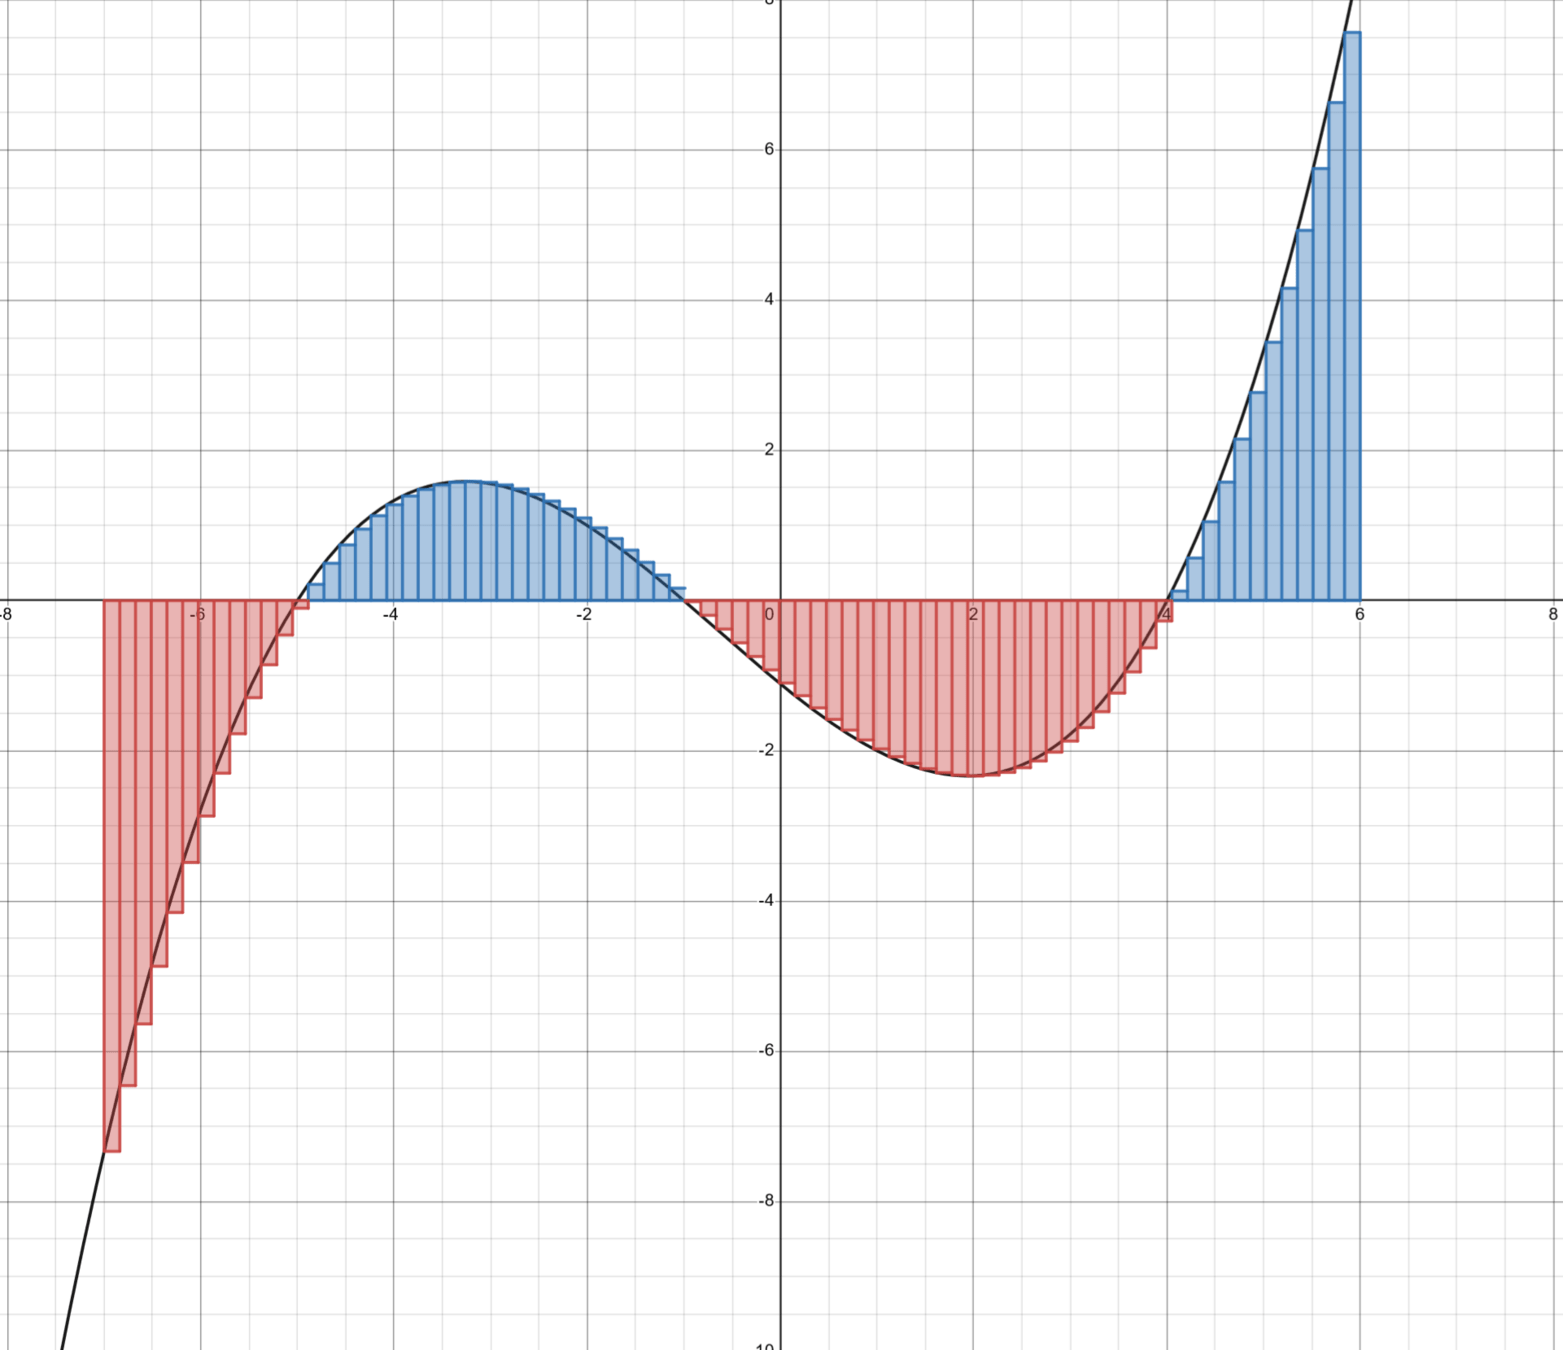
\(N=80\)
\(\Delta_x=0.165\)
\(\pi=3.14161\)
Solution Using std::threads
David Mayerich
STIM Laboratory, University of Houston
#include <thread>
using namespace std;

void pi_sum(unsigned ti, /* ... */);

unsigned n = BIG_NUM;
unsigned nt = NUM_THREADS;
double step;
int main(int argc, char** argv) {
  double sum = 0.0;
  double t_sum = new double[nt];
  thread* t = new thread[nt];
  for(unsigned ti=0; i<nt; ti++)
    t[ti] = thread(pi_sum, ti, /*...*/);
  for(unsigned ti=0; ti<nt; ti++) {
    t[ti].join();
    sum += t_sum[ti];
  }
  pi = step * sum;
}
// set the number of steps
static long N = BIG_NUM;
double step;
int main(int argc, char** argv) {
// step size (smaller -> accurate)
step = 1.0/N;
// integral becomes a summation
double sum = 0.0;
for(int i=0; i<N; i++) {
// calculate the integrand
x = (i + 0.5) * step;
sum += 4.0 / (1.0 + x * x);
}
// approximate integral (pi)
pi = step * sum;
}serial C++
parallel with std::threads
implement thread
avoid races
launch threads
synchronize
Work Distribution Patterns
Round Robin (Cyclic)
- Given \(N\) threads:
-
\(t_0\) accesses:
[0]->[N]->[2*N] -
\(t_1\) accesses:
[1]->[N+1]->[2*N+1] -
\(\cdots\)
-
David Mayerich
STIM Laboratory, University of Houston
Block (Contiguous)
-
Given \(N\) threads:
-
\(t_0\) accesses:
[0]->[1]->[2] -
\(t_1\) accesses:
[N+0]->[N+1]->[N+2] -
\(\cdots\)
-
\(t_0\)
\(t_1\)
\(t_2\)
\(t_3\)
\(t_0\)
\(t_1\)
A0
A4
A8
AC
B0
B4
B8
BC
D0
D4
D8
DC
E0
E4
E8
EC
F0
F4
F8
Work Distribution Patterns
Round Robin (Cyclic)
- Given \(N\) threads:
-
\(t_0\) accesses:
[0]->[N]->[2*N] -
\(t_1\) accesses:
[1]->[N+1]->[2*N+1] -
\(\cdots\)
-
David Mayerich
STIM Laboratory, University of Houston
Block (Contiguous)
-
Given \(N\) threads:
-
\(t_0\) accesses:
[0]->[1]->[2] -
\(t_1\) accesses:
[N+0]->[N+1]->[N+2] -
\(\cdots\)
-
A0
A4
A8
AC
B0
B4
B8
BC
D0
D4
D8
DC
E0
E4
E8
EC
F0
F4
F8
\(t_0\)
\(t_1\)
\(t_2\)
\(t_3\)
\(t_0\)
\(t_1\)
Trade-Offs: Memory
David Mayerich
STIM Laboratory, University of Houston
Round Robin (Cyclic)
- Can mess up spatial locality
- threads may be out-of-sync
- may be on different processors
Block (Contiguous)
-
Local accesses within a thread will be cached
same cache?
maybe...
A0
A4
A8
AC
B0
B4
B8
BC
D0
D4
D8
DC
E0
E4
E8
EC
F0
F4
F8
cached on \(t_0\)'s processor
cached on \(t_3\)'s processor
\(t_0\)
\(t_1\)
\(t_2\)
\(t_3\)
\(t_0\)
\(t_1\)
\(t_0\) fetches cached with \(t_0\)'s processor
Trade-Offs: Work
David Mayerich
STIM Laboratory, University of Houston
Round Robin (Cyclic)
- More likely to distribute work evenly
Block (Contiguous)
-
If effort is distributed unevenly, individual threads are easily overloaded
# calculations
\(t_0\)
\(t_1\)
\(t_2\)
\(t_3\)
\(t_0\)
\(t_1\)
\(t_2\)
\(t_3\)
\(t_0\)
\(t_1\)
\(t_2\)
\(t_3\)
\(t_0\)
\(t_1\)
\(t_2\)
Scheduling Guidelines
David Mayerich
STIM Laboratory, University of Houston
Round Robin (Cyclic)
- Load balancing: usually better at distributing work between threads
Block (Contiguous)
-
Load balancing: worse (on average) at distributing work
-
Memory access: doesn't guarantee locality
-
Memory access: local fetches will be cached with the thread
-
Architectures: CPUs with uneven work, GPUs (coalescing)
-
Architectures: CPUs with uniform work
Which do you think will win?
(I'll do RR, you do blocked)
Round-Robin Distribution
David Mayerich
STIM Laboratory, University of Houston
\(t_0\)
id=0
\(t_2\)
id=2
\(t_1\)
id=1
\(t_3\)
id=3
void pi_sum(unsigned ti, unsigned nt,
unsigned N, double* sum) {
// step size has to be passed or
// calculated here
double step = 1.0 / N;
// sum must be initialized to zero
*sum = 0.0;
// enter a round-robin FOR loop
for(int i=ti; i<N; i+=nt) {
double x = (i + 0.5) * step;
*sum += 4.0 / (1.0 + x * x);
}
}Round-Robin Distribution
David Mayerich
STIM Laboratory, University of Houston
\(t_0\)
id=0
\(t_2\)
id=2
\(t_1\)
id=1
\(t_3\)
id=3
void pi_sum(unsigned ti, unsigned nt,
unsigned N, double* sum) {
// step size has to be passed or
// calculated here
double step = 1.0 / N;
// sum must be initialized to zero
*sum = 0.0;
// enter a round-robin FOR loop
for(int i=ti; i<N; i+=nt) {
double x = (i + 0.5) * step;
*sum += 4.0 / (1.0 + x * x);
}
}OpenMP Round-Robin Implementation
David Mayerich
STIM Laboratory, University of Houston
// set the number of steps
static long N = BIG_NUM;
double step;
int main(int argc, char** argv) {
  // step size (smaller -> accurate)
  step = 1.0/N;
  // integral becomes a summation
  double sum = 0.0;
  for(int i=0; i<N; i++) {
    // calculate the integrand
    x = (i + 0.5) * step;
    sum += 4.0 / (1.0 + x * x);
  }
  // approximate integral (pi)
  pi = step * sum;
}
serial C++
static long N = BIG_NUM;
#define T 4
void main() {
  double sum[T];
  omp_set_num_threads(T);
  {...}
  double pi = 0;
  for(int i=0; i<T; i++)
    pi += sum[i] * step;
}
parallel with OpenMP
implement thread
#pragma omp parallel
{
  int id = omp_get_thread_num();
  int nt = omp_get_num_threads();
  if(id == 0) nthreads = nt;
  sum[id] = 0;
  for(int i=id; i<N; i+=nt) {
    double x = (i + 0.5) * step;
    sum[id] += 4.0 / (1.0 + x * x);
  }
}
OpenMP Round-Robin Implementation
David Mayerich
STIM Laboratory, University of Houston
static long N = BIG_NUM;
#define T 4
void main() {
  double sum[T];
  omp_set_num_threads(T);
  {...}
  double pi = 0;
  for(int i=0; i<T; i++)
    pi += sum[i] * step;
}
parallel with OpenMP
implement thread
#pragma omp parallel
{
  int id = omp_get_thread_num();
  int nt = omp_get_num_threads();
  if(id == 0) nthreads = nt;
  sum[id] = 0;
  for(int i=id; i<N; i+=nt) {
    double x = (i + 0.5) * step;
    sum[id] += 4.0 / (1.0 + x * x);
  }
}
#include <thread>
using namespace std;
void pi_sum(unsigned ti, /* ... */);
unsigned n = BIG_NUM;
unsigned nt = NUM_THREADS;
double step;
int main(int argc, char** argv) {
double sum = 0.0;
double t_sum = new double[nt];
thread* t = new thread[nt];
for(unsigned ti=0; i<nt; ti++)
t[ti] = thread(pi_sum, ti, /*...*/);
for(unsigned ti=0; ti<nt; ti++) {
t[ti].join();
sum += t_sum[ti];
}
pi = step * sum;
}void pi_sum(unsigned ti, unsigned nt,
unsigned N, double* sum) {
// step size has to be passed or
// calculated here
double step = 1.0 / N;
// sum must be initialized to zero
*sum = 0.0;
// enter a round-robin FOR loop
for(int i=ti; i<N; i+=nt) {
double x = (i + 0.5) * step;
*sum += 4.0 / (1.0 + x * x);
}
}parallel with std::threads
implicit barrier
Control Execution: single
-
Use
omp singleto specify a line of code that only one thread will execute -
Any thread can execute it (but there's an implicit barrier afterwards)
David Mayerich
STIM Laboratory, University of Houston
#pragma omp parallel
{
  int id = omp_get_thread_num();
  int nt = omp_get_num_threads();
  if(id == 0) nthreads = nt;
  sum[id] = 0;
  for(int i=id; i<N; i+=nt) {
    double x = (i + 0.5) * step;
    sum[id] += 4.0 / (1.0 + x * x);
  }
}
int nt;
#pragma omp parallel
{
int id = omp_get_thread_num();
#pragma omp single
nt = omp_get_num_threads();
if(id == 0) nthreads = nt;
sum[id] = 0;
for(int i=id; i<N; i+=nt) {
double x = (i + 0.5) * step;
sum[id] += 4.0 / (1.0 + x * x);
}
}Control Execution: barrier
-
Placing an
omp barrierin anomp parallelblock makes all threads wait
David Mayerich
STIM Laboratory, University of Houston
int* data = new int[N];
int nthreads;

#pragma omp parallel
{
  int id = omp_get_thread_num();
  #pragma omp single
  nthreads = omp_get_num_threads();

  each thread writes to an index
  data[id] = id * 10;

  // wait for all threads to finish writing
  #pragma omp barrier

  // each thread reads from its neighbor
  int neighbor = (id + 1) % nthreads;
  printf("Thread %d read data[%d] = %d\n", id, neighbor, data[neighbor]);
}
launches a bunch of threads
only one executes this line
they all wait here for their friends
Control Execution: critical and atomic
David Mayerich
STIM Laboratory, University of Houston
int total = 0;

#pragma omp parallel
{
  int id = omp_get_thread_num();
  int my_result = (id + 1) * 100;

  #pragma omp critical
  {
    total += my_result;
    printf("Thread %d added %d", id, my_result);
    printf(", total is now %d\n", total);
  }
}
printf("Final total = %d\n", total);
int total = 0;
#pragma omp parallel
{
int id = omp_get_thread_num();
int my_result = (id + 1) * 100;
#pragma omp atomic
total += my_result;
}
printf("Final total = %d\n", total);-
Atomics simplify this for memory writes
-
A critical region only allows one thread in at a time
launches a bunch of threads
only one may enter
only one may write
Summary
Basic Concepts
-
OpenMP implements shared-memory parallelism
-
Preprocessor directives (with some API functions)
-
The number of threads can be set by the environment variable:
OMP_NUM_THREADS
or the API function:
omp_set_num_threads(10);
David Mayerich
STIM Laboratory, University of Houston
Preprocessor Directives
-
omp parallel- launch threads that all execute this block of code-
omp_get_thread_num()returns an id for each thread
-
-
omp single- only one thread executes this block of code -
omp critical- only one thread executes this block of code at a time -
omp atomic- only one thread is allowed to write at a time
D.4 OpenMP
By STIM Laboratory