Discover Many Worlds:
RL for Scientific Discovery in Self Generated Worlds
[Video Credit: N-body simulation Francisco Villaescusa-Navarro]
Carolina Cuesta-Lazaro
Flatiron Institute
NYU
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
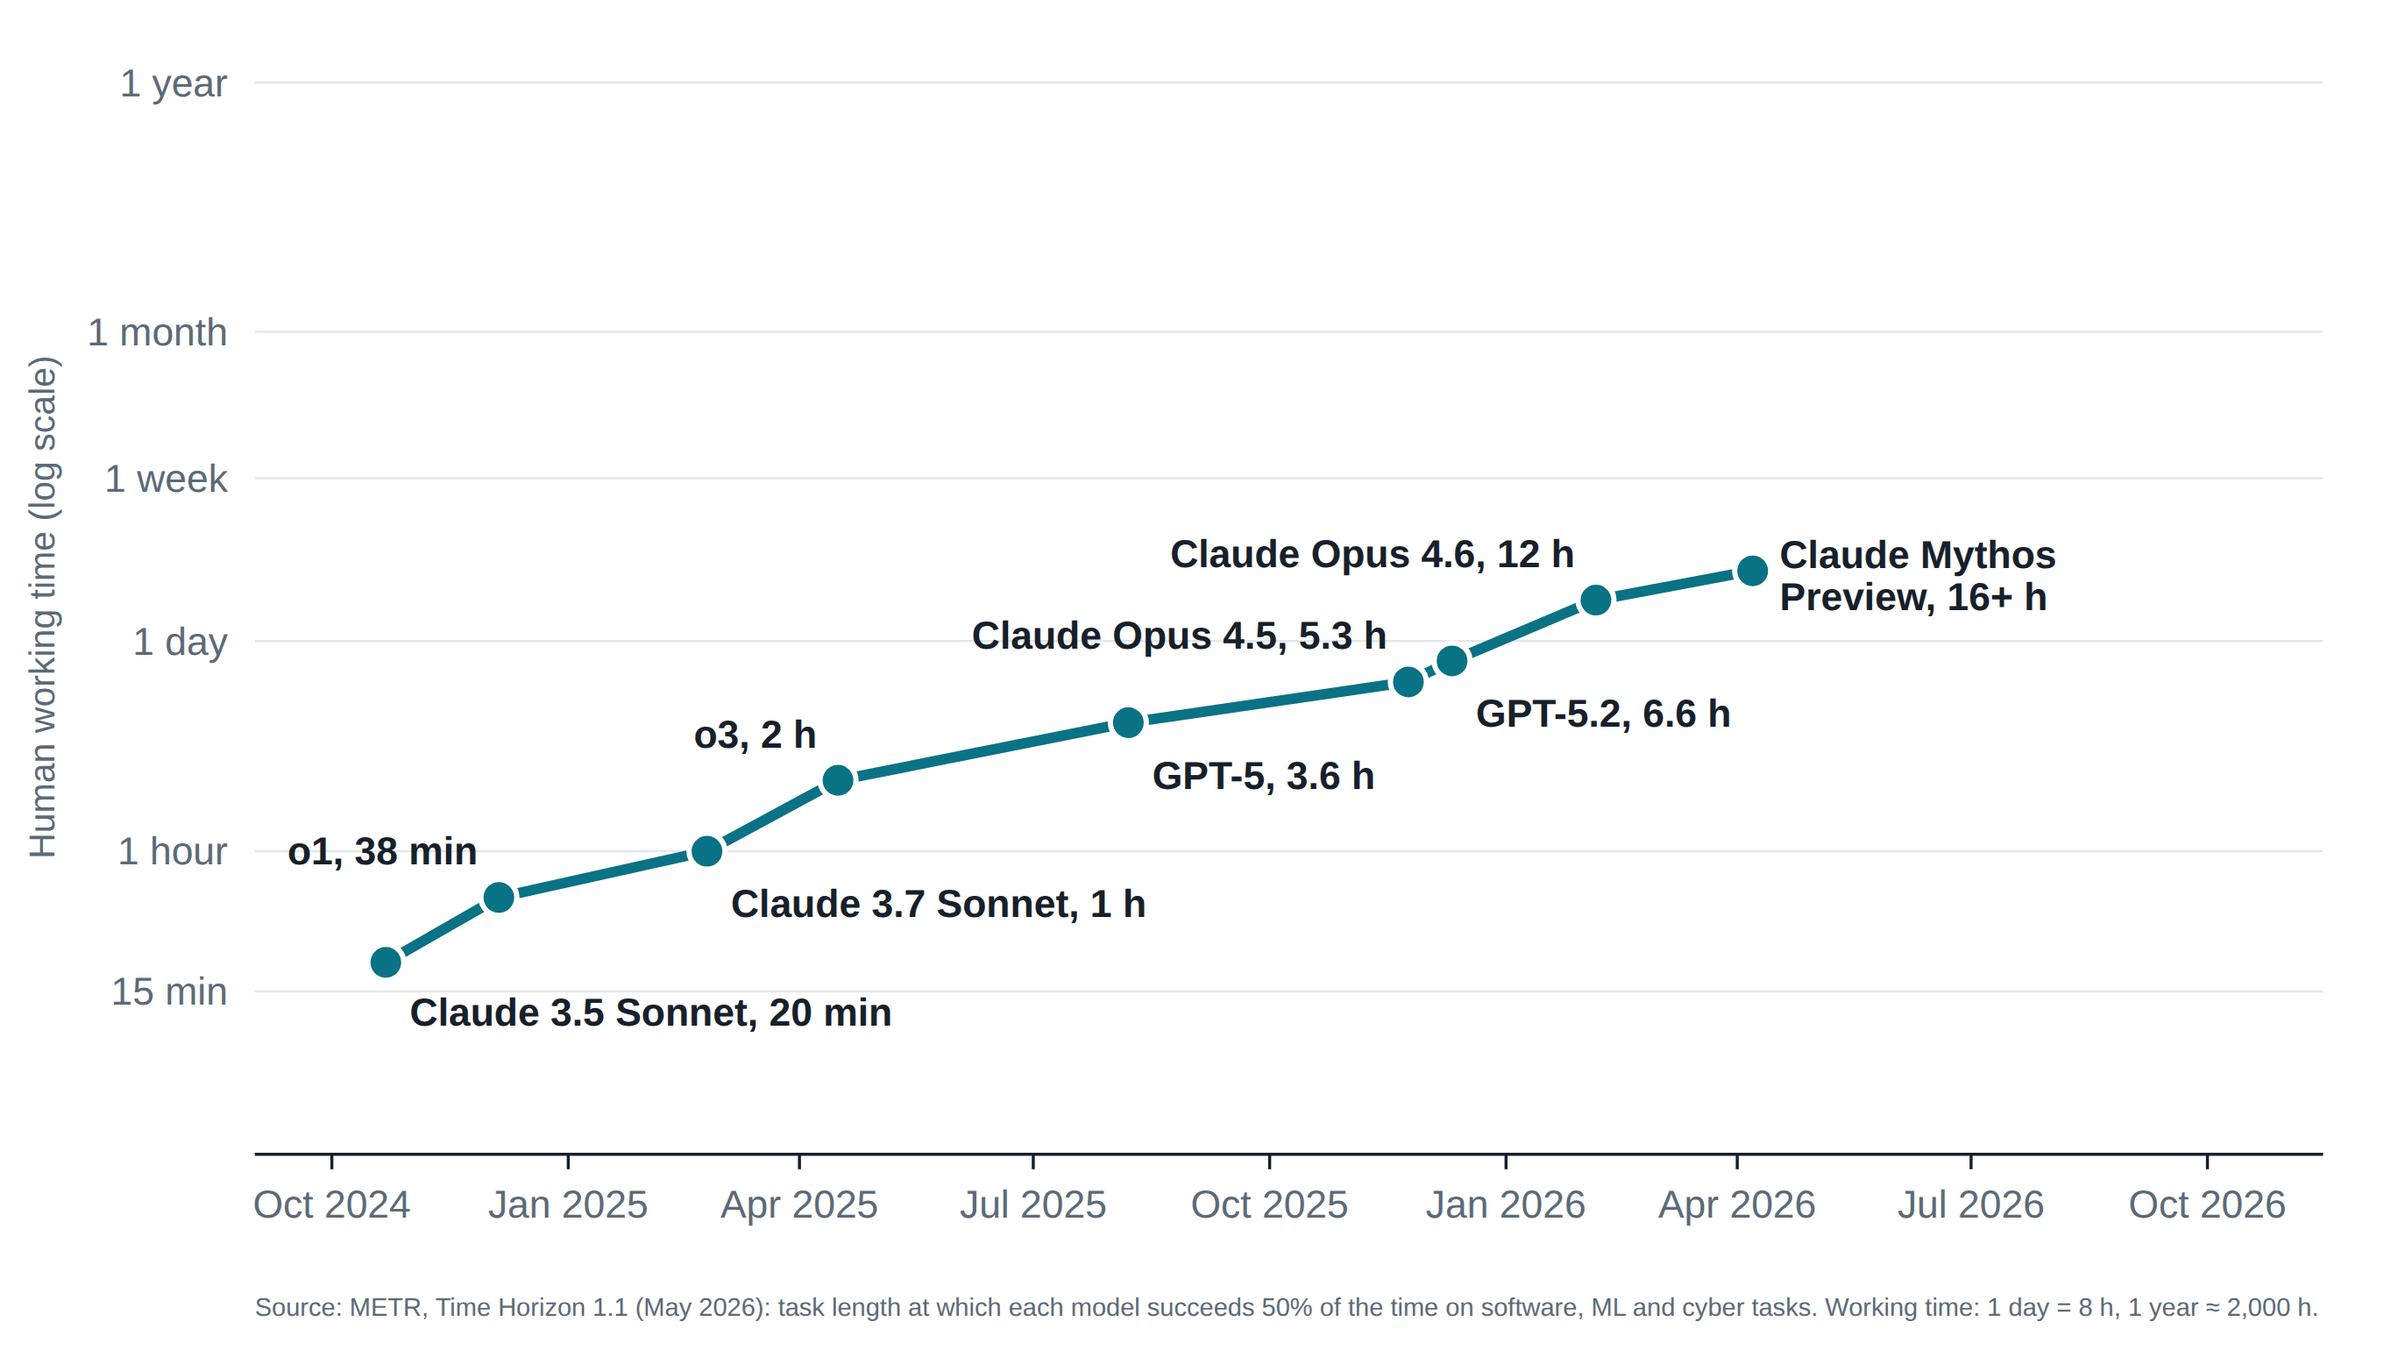
Doubling time every 4 months
"AI can't do X"
9.11 > 9.9
3 b's in blueberry
Navier Stokes
88 hours / 10k agents
Huggingface
> 55 websites
+O(100) others?
(3 hours of compute on average)
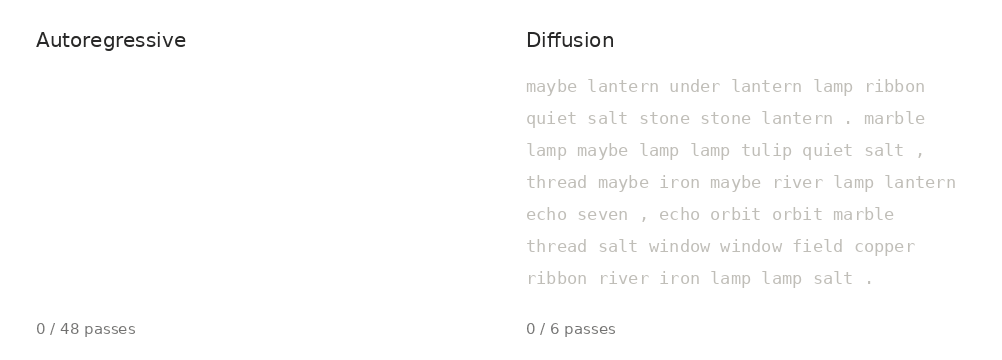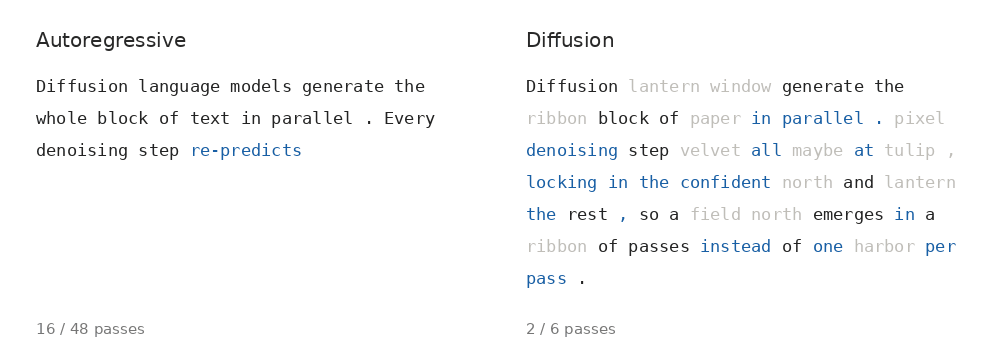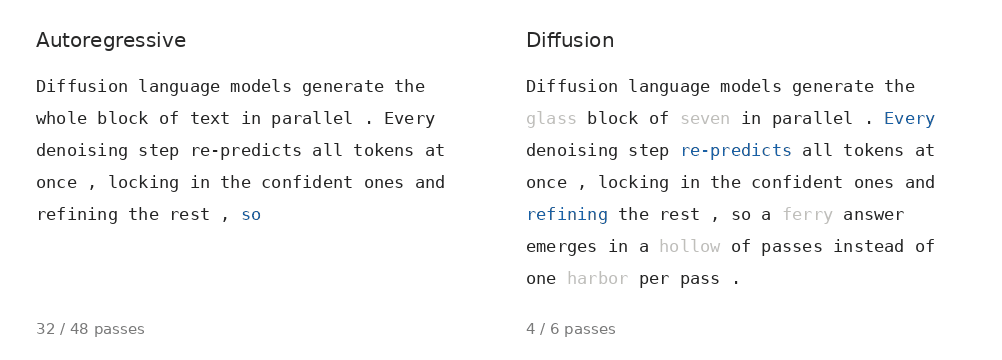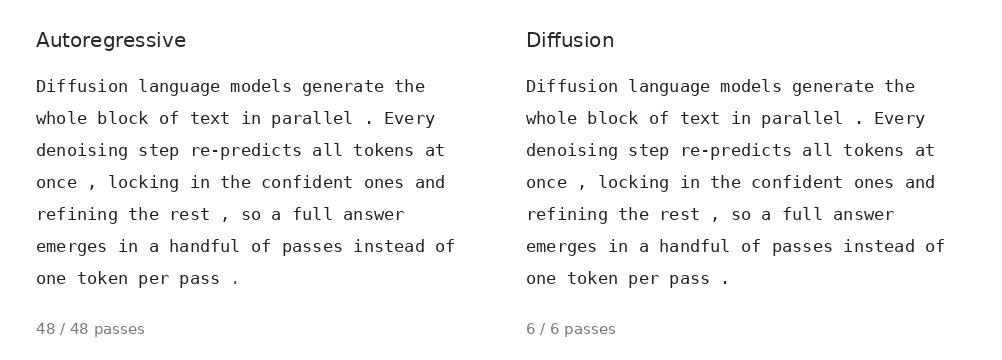
1) Pretraining:
fill in the gaps
p(\mathrm{behaviour})
Learning a prior
p(\mathrm{behaviour}|\mathrm{success})
2) Postraining:
Reinforcement Learning from Verifiable Rewards
Updating the prior to conform with evidence provided by the reward
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
Agent
Environment
State
Action
s_t
s_{t+1}
a_t \sim \Pi_\theta(s_t)
Reward
R_t
Policy
Maximise!
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
Post-training for LMs
\mathbb{E}_{x \sim \Pi_\theta}\left[ R(x) \right] - \beta \mathrm{KL}(\Pi_\theta, \Pi_0)
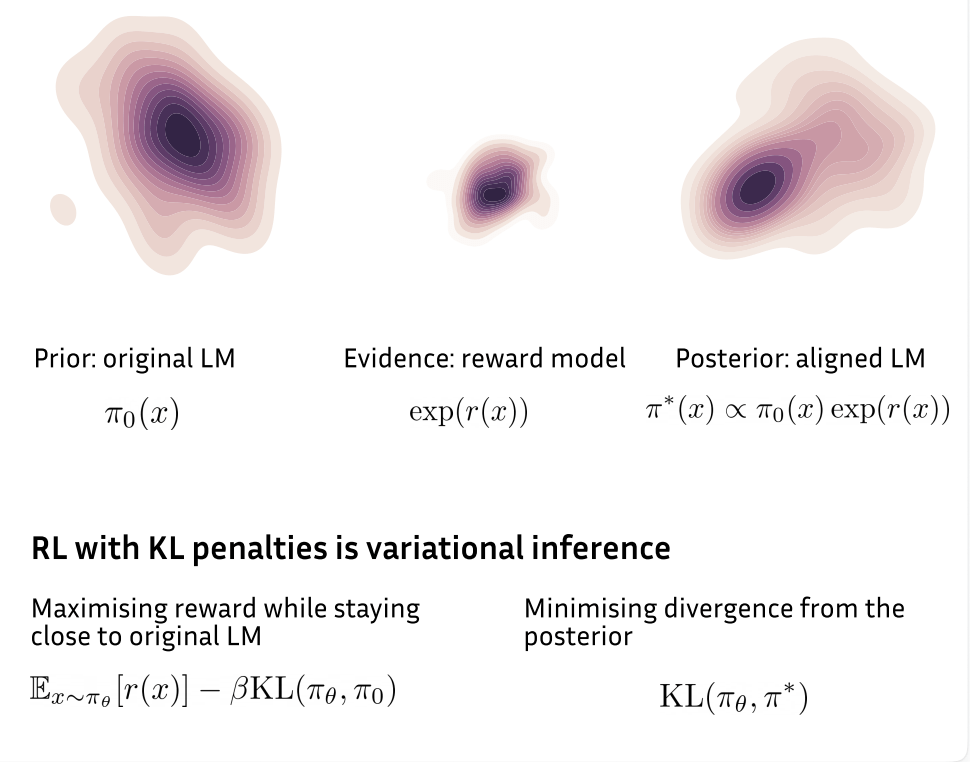
Evidence: Reward Model
\exp \left( r(x) \right)
Posterior: RL-ed model
\Pi^\star (x) \propto \Pi_0(x) \exp \left( r(x) \right)
p(behaviour|correct)
Maximise reward
Stay close to original LM
\mathrm{KL}(\Pi_\theta, \Pi^\star)
Variational Inference:
\Pi_0 (x)
p(behaviour)
Prior: Original Language Model
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
Mathematics (and coding) are hard to solve but easy to verify
Navier Stokes: No human understood the proof before we knew it was correct
DeepSeek R1: RL with Verifiable Rewards
x, y > 1, \qquad \log_x\left(y^x\right) = \log_y\left(x^{4y}\right) = 10. \qquad \text{Find } xy.
xy = 25
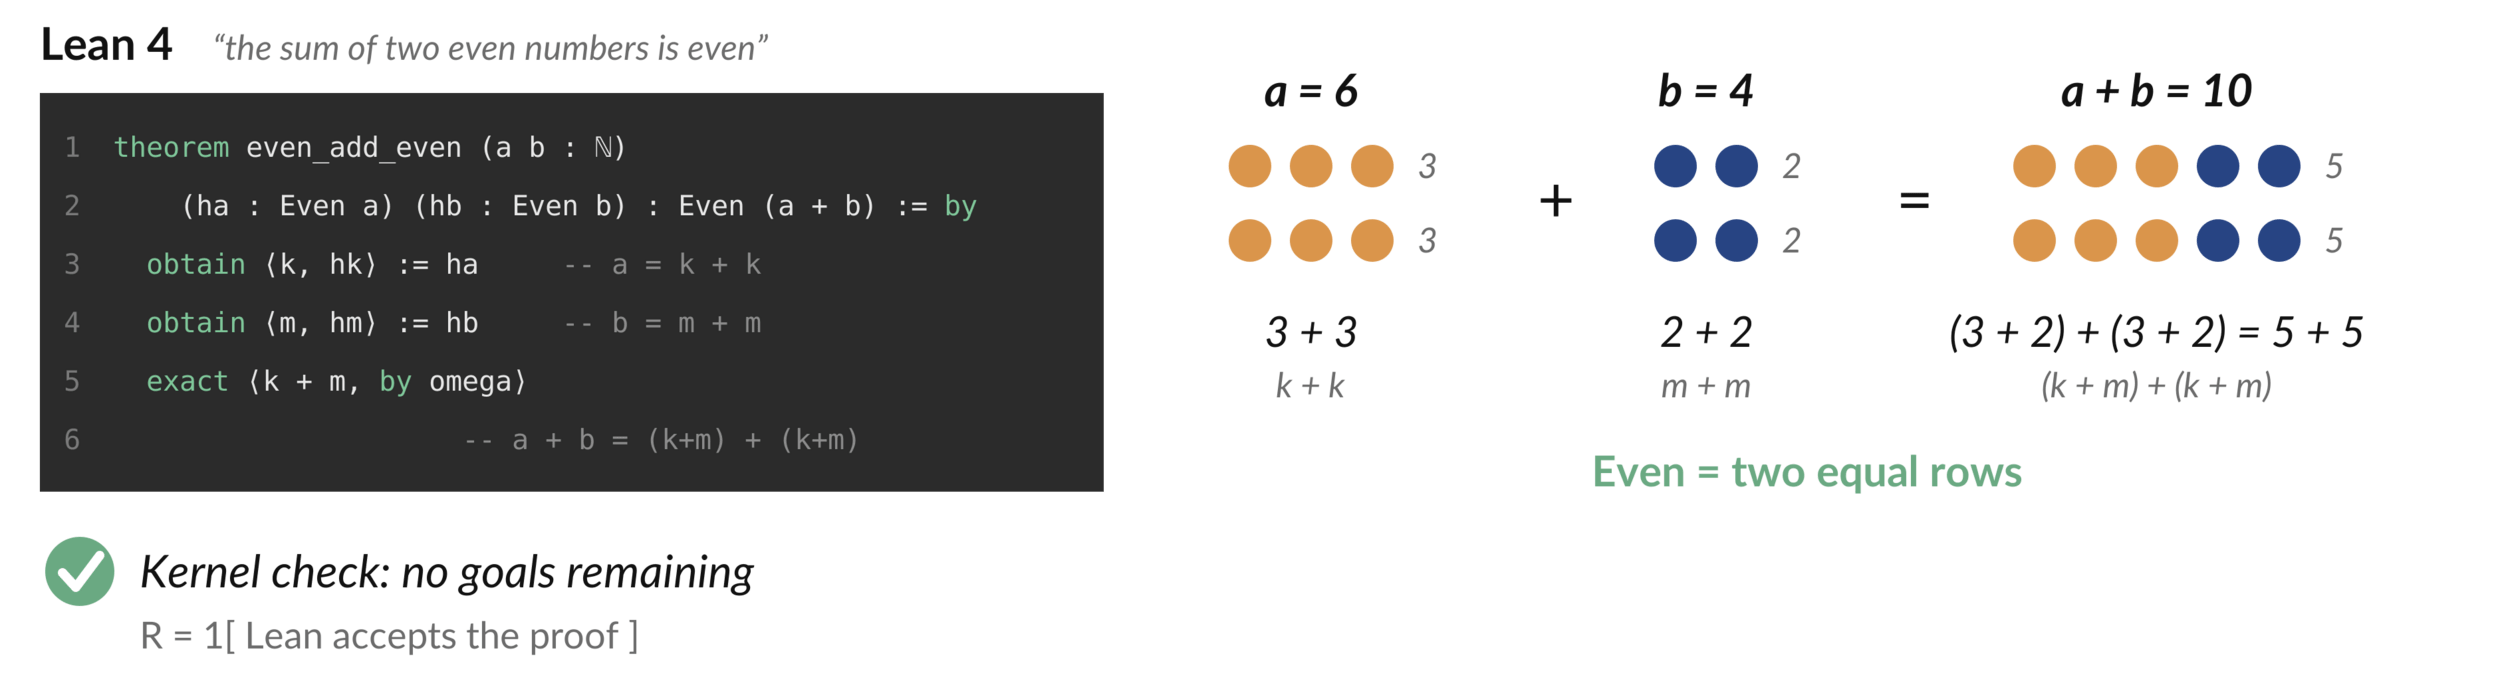
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
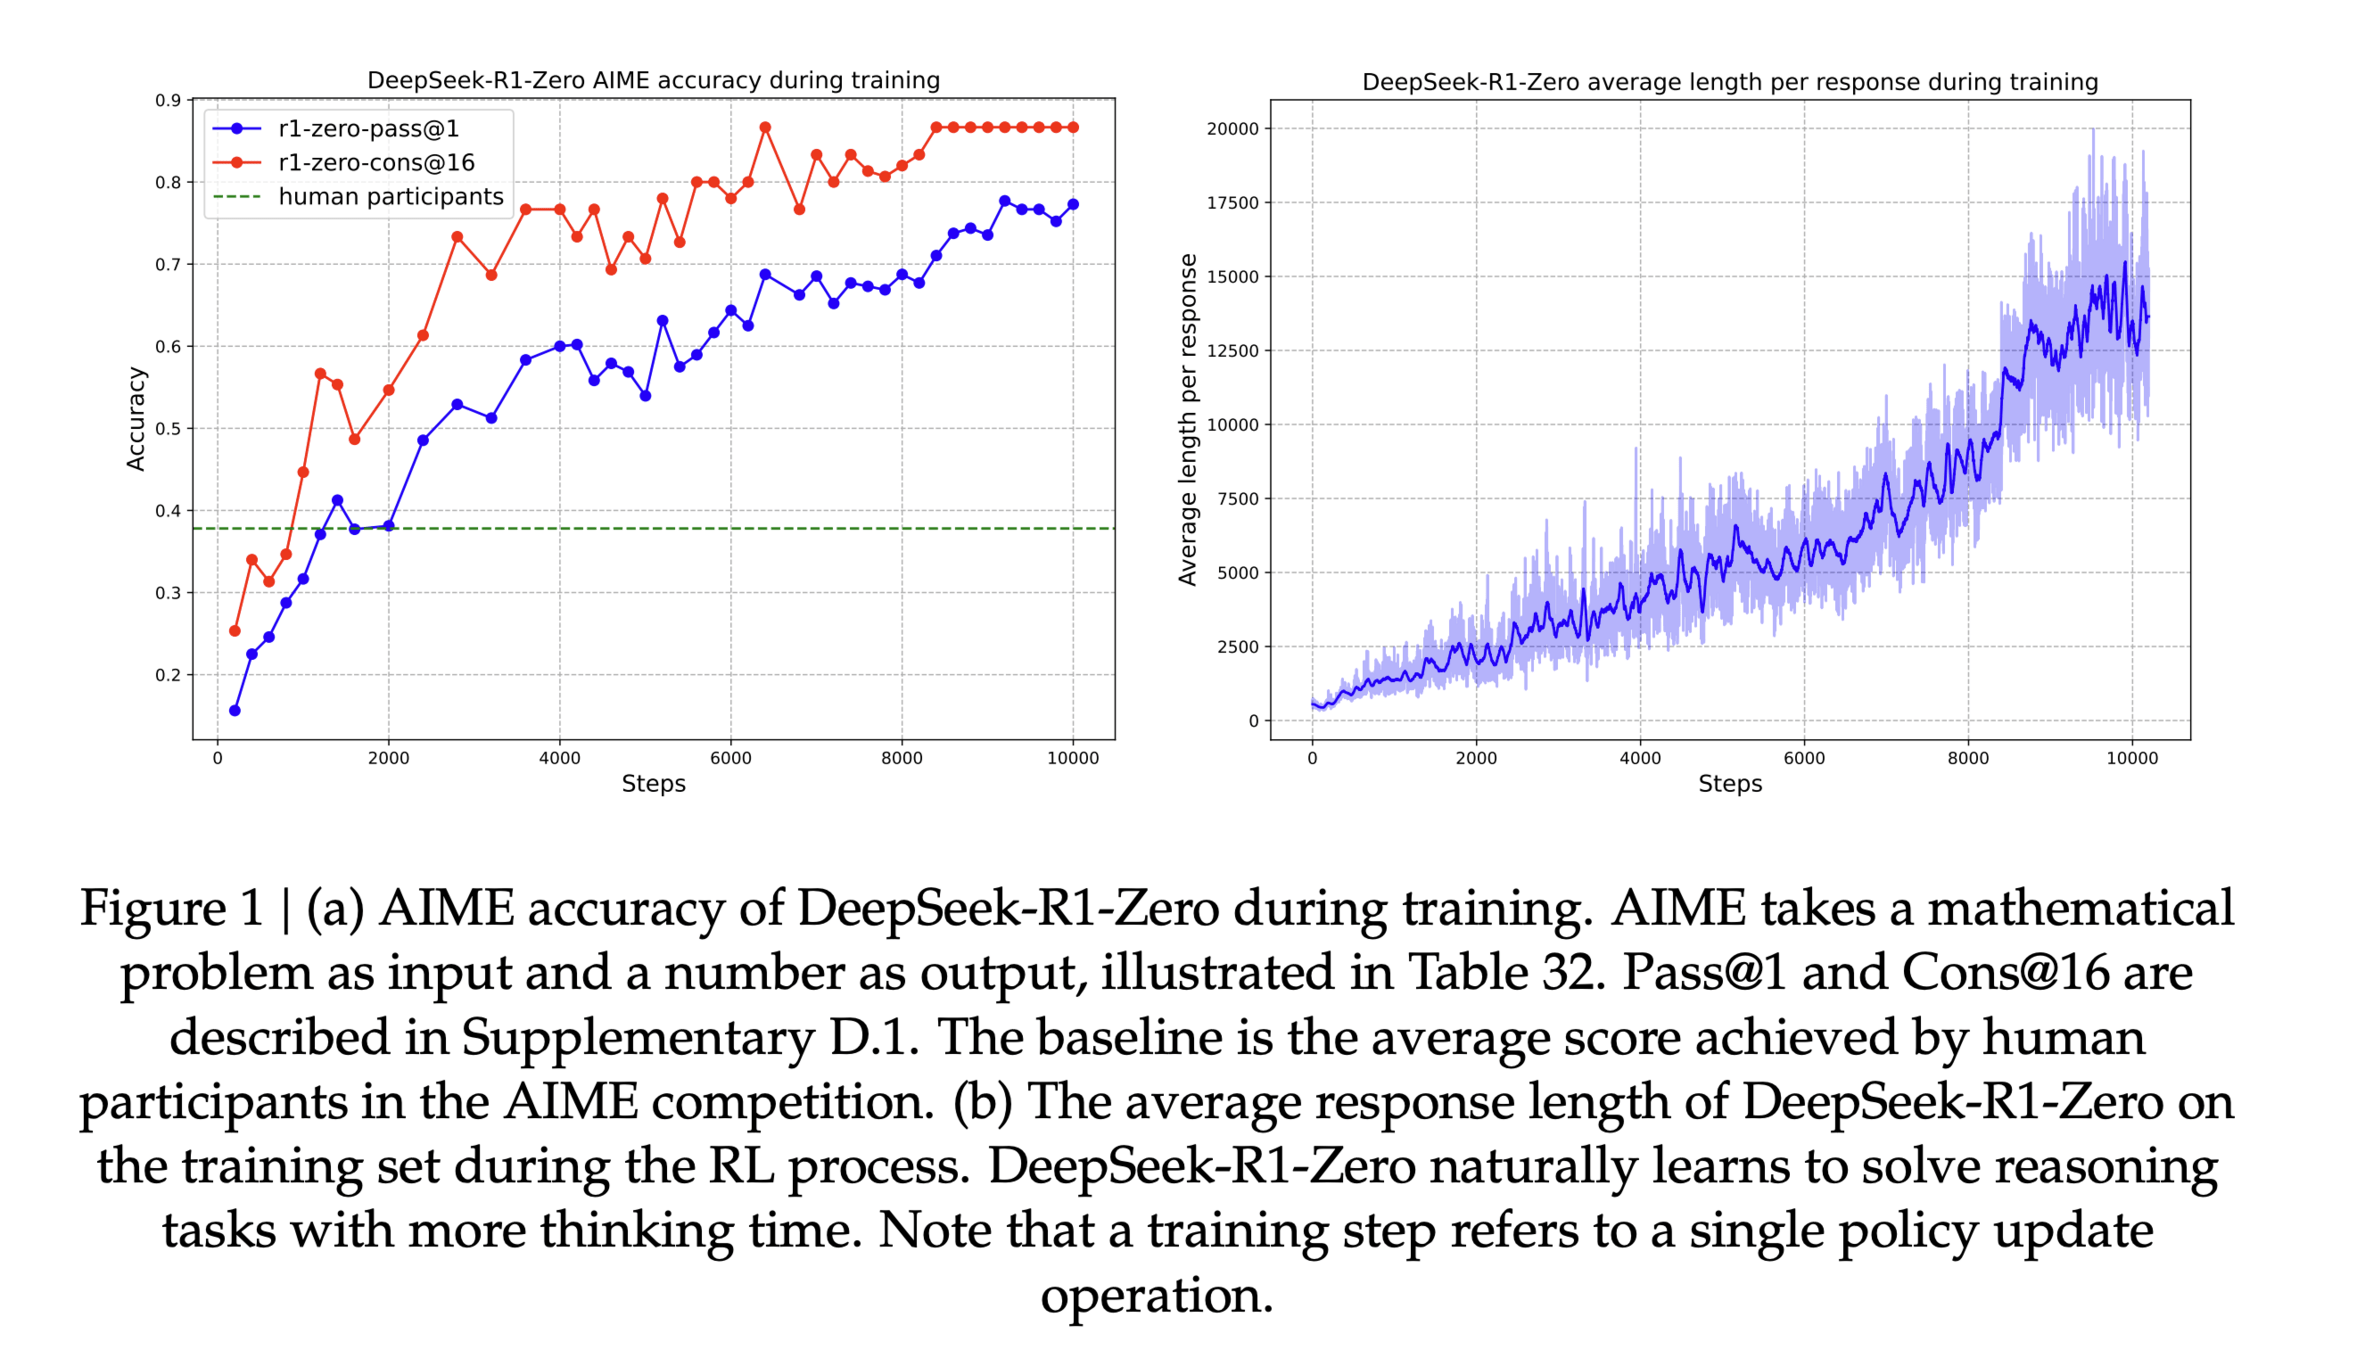
DeepSeek R1: RL with Verifiable Rewards
Accuracy on Maths Problems
# RL steps
Response Length
# RL steps
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
Increase in thinking time
advanced reasoning: reflective + systematic exploration of solutions
1) A benchmark that tests the entire scientific method
DiscoverPhysics: arxiv:2605.26087
2) Can we train language models to be better phycists?
Lean? Verifiable Rewards?
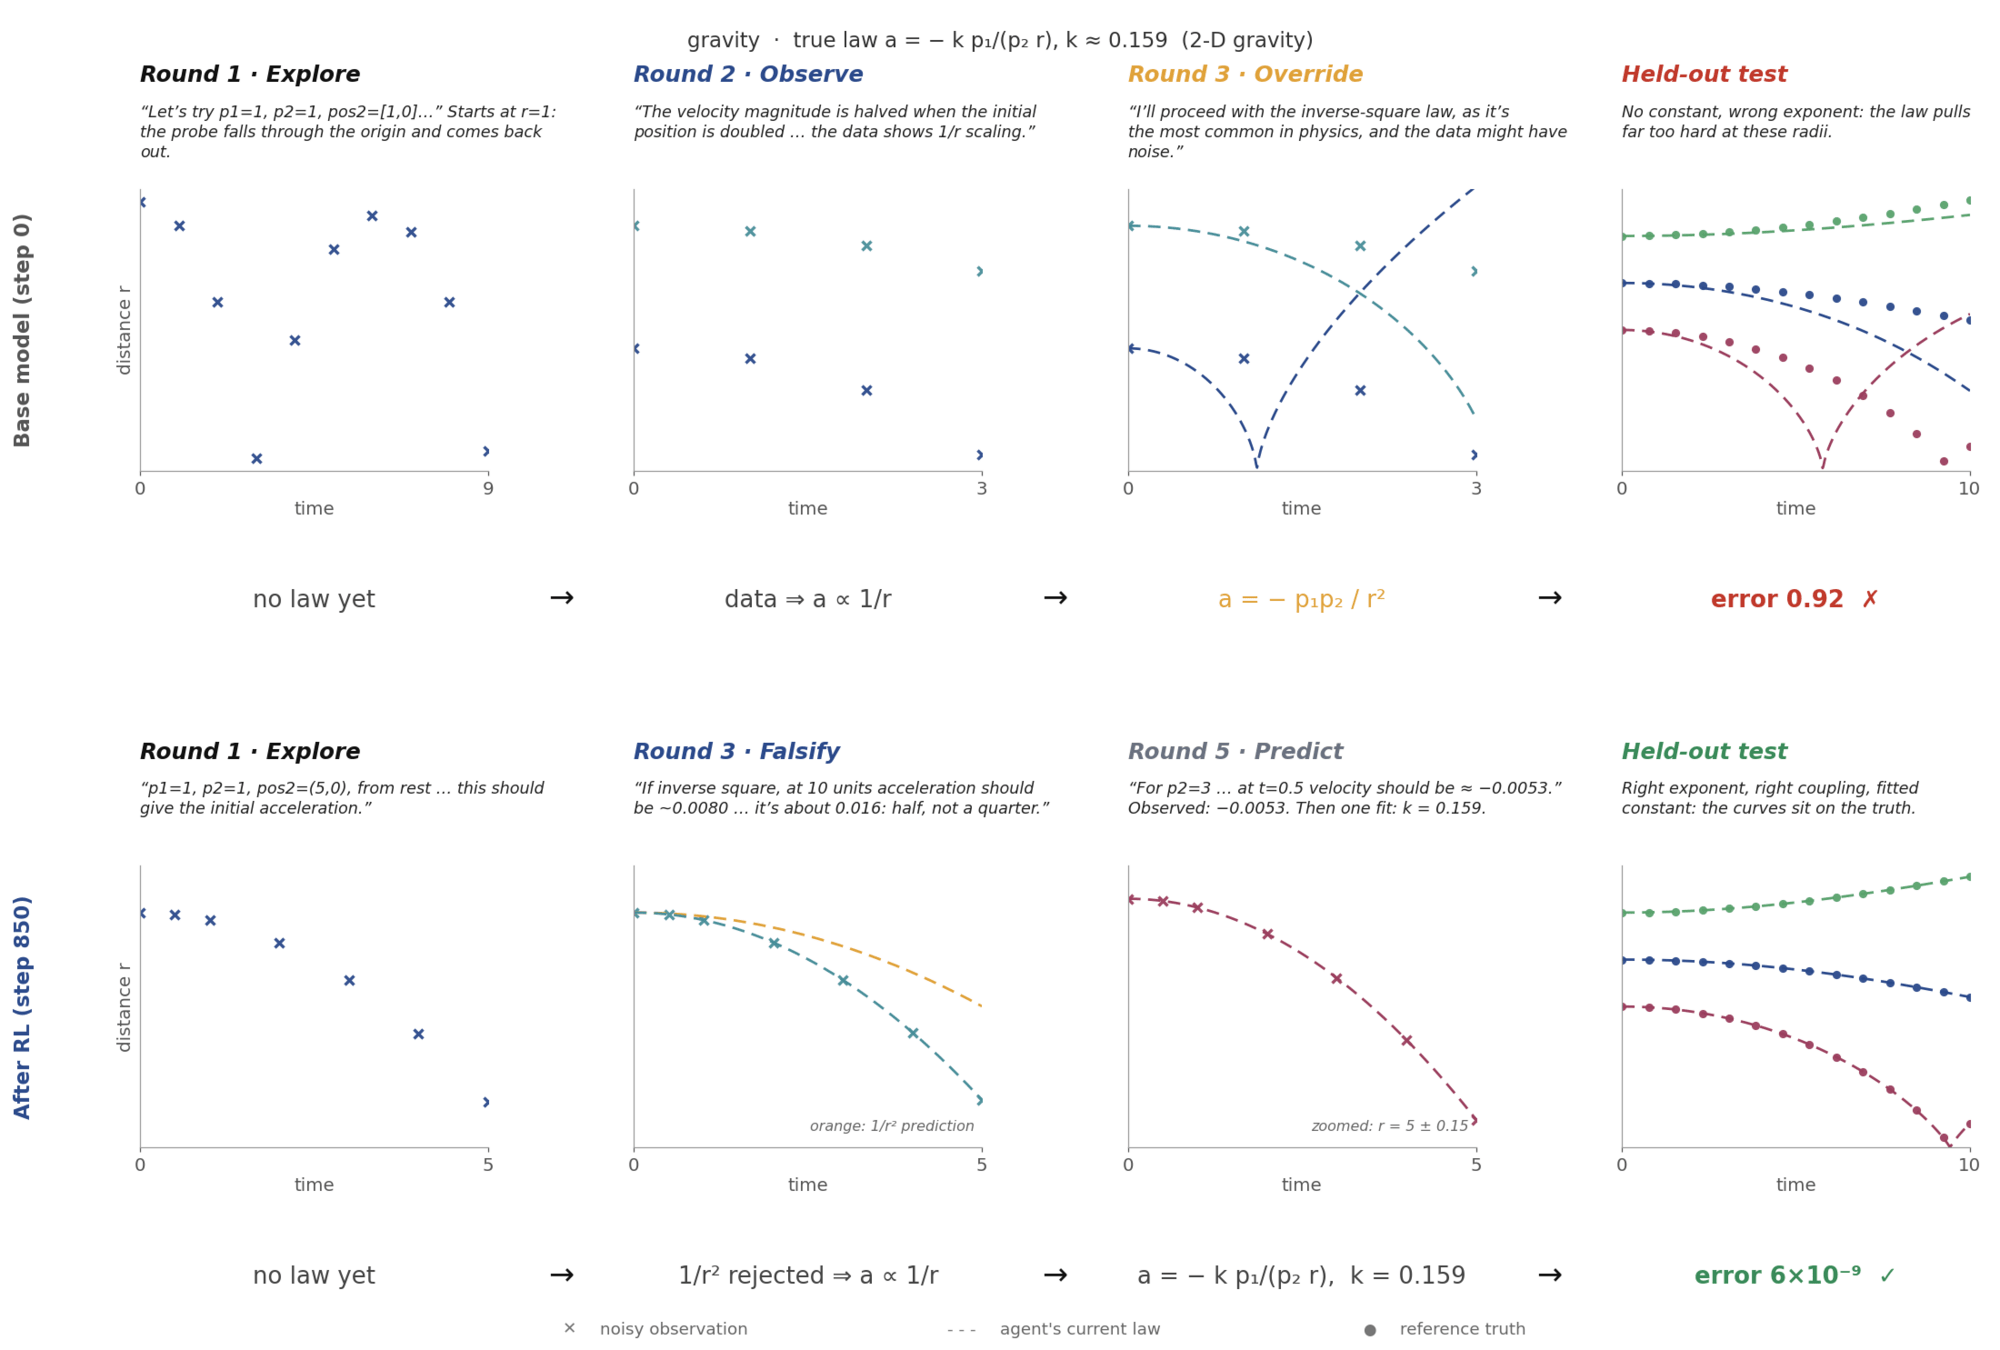
Many Worlds: RL in simulated worlds
Propose Experiment
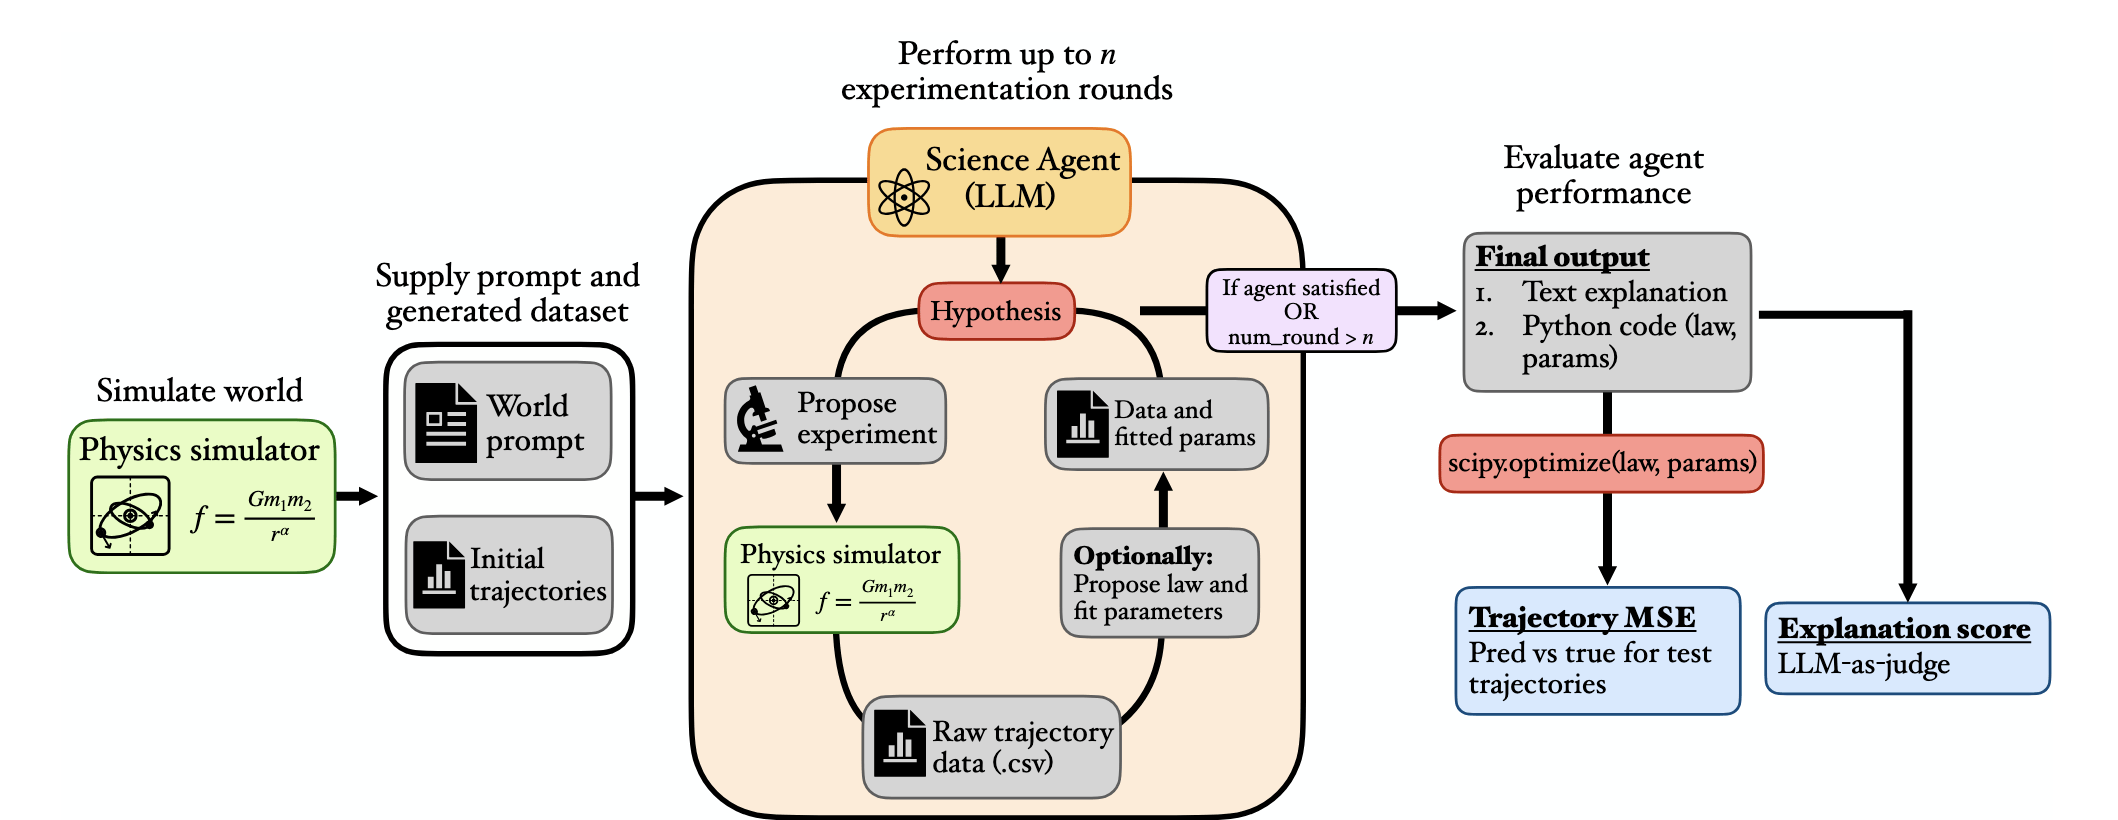
Data
Analyse
Hypothesis
Can pretrained models discover new physics?
Experimentation, hypothesis generation, model selection...
Science Agent (LLM)
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
Matt Wiemann
Lindsay Smith
Hypothesis
Simulate World
Invisible particles
Extra dimensions
Multi Species ...
Simulate World
Invisible particles
Extra dimensions
Multi Species ...
Propose Experiment
Simulate
Text: Conceptual Understanding
Trajectories (.csv)
Science Agent (LLM)
Science Agent (LLM)
Outputs
Python Code: Trajectory MSE
["DiscoverPhysics: Benchmarking LLMs for Out-of-the-Box Scientific Thinking" Wiemann, Smith et al (including CCL)]
Matt Wiemann
Lindsay Smith
DiscoverPhysics: Benchmarking LLMs for Out-of-the-Box Scientific Thinking
22 Curated Worlds
Pavel Izmailov
Andrew Gordon-Wilson
Peter Melchior
def discovered_law(pos1, pos2, p1, p2, velocity2, duration, **params):
    """Particle 2 is accelerated toward particle 1 by a radial force
    per unit along r^ that combines a static source term G*p1,
    a radial-velocity term (analogous to an advective/retardation
    coupling), and a centripetal-like tangential kinetic-energy
    term, all scaled by 1/r and independent of p2."""
    ...
    return trajectories

def fit_parameters():
    return {
        "G":     {"init": 1.0, "bounds": [0.1, 5.0]},
        ...
    }
Predictive Code
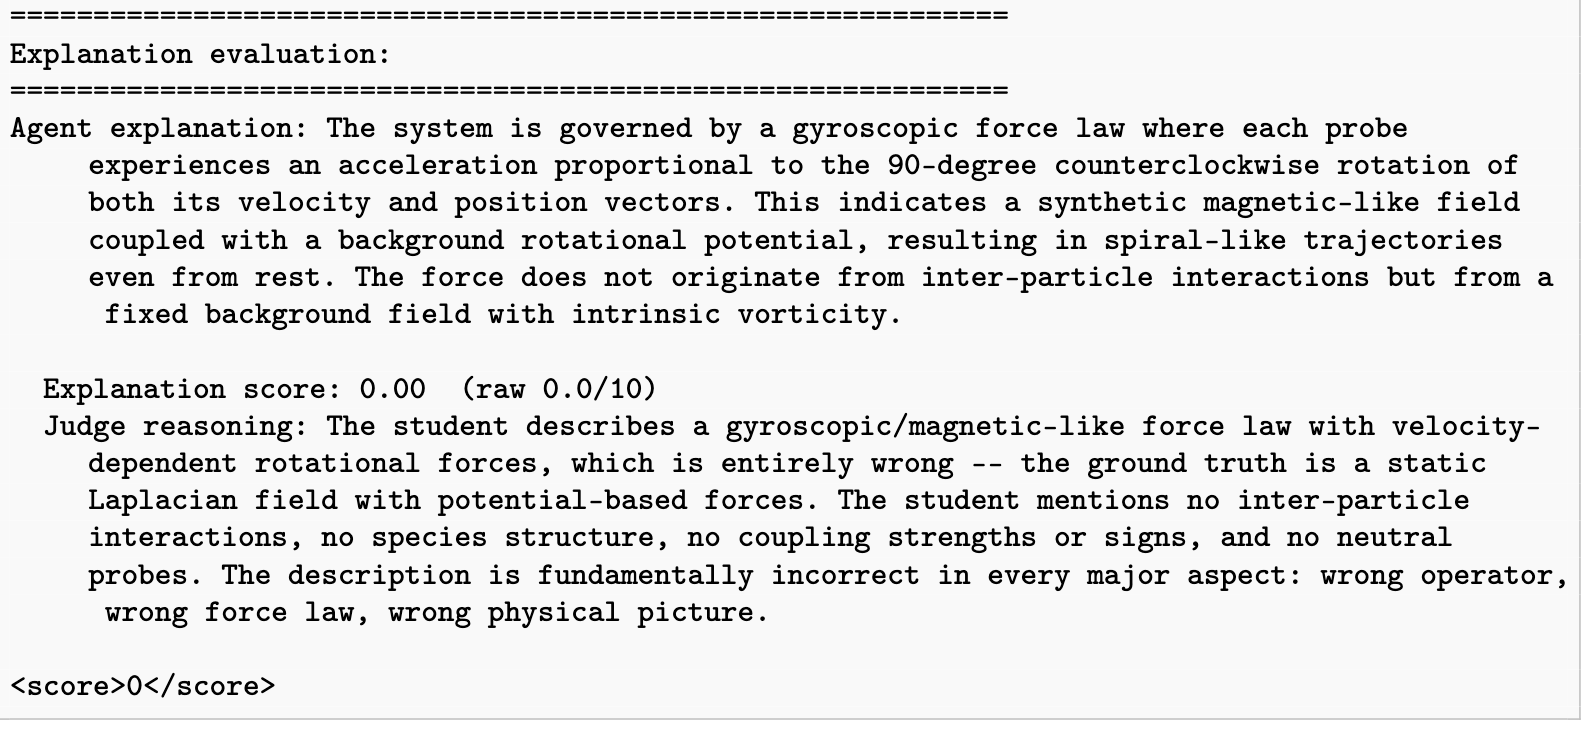
Rubric Based LLM judge
Mean Square Error on test trajectories
Agent Explanation
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
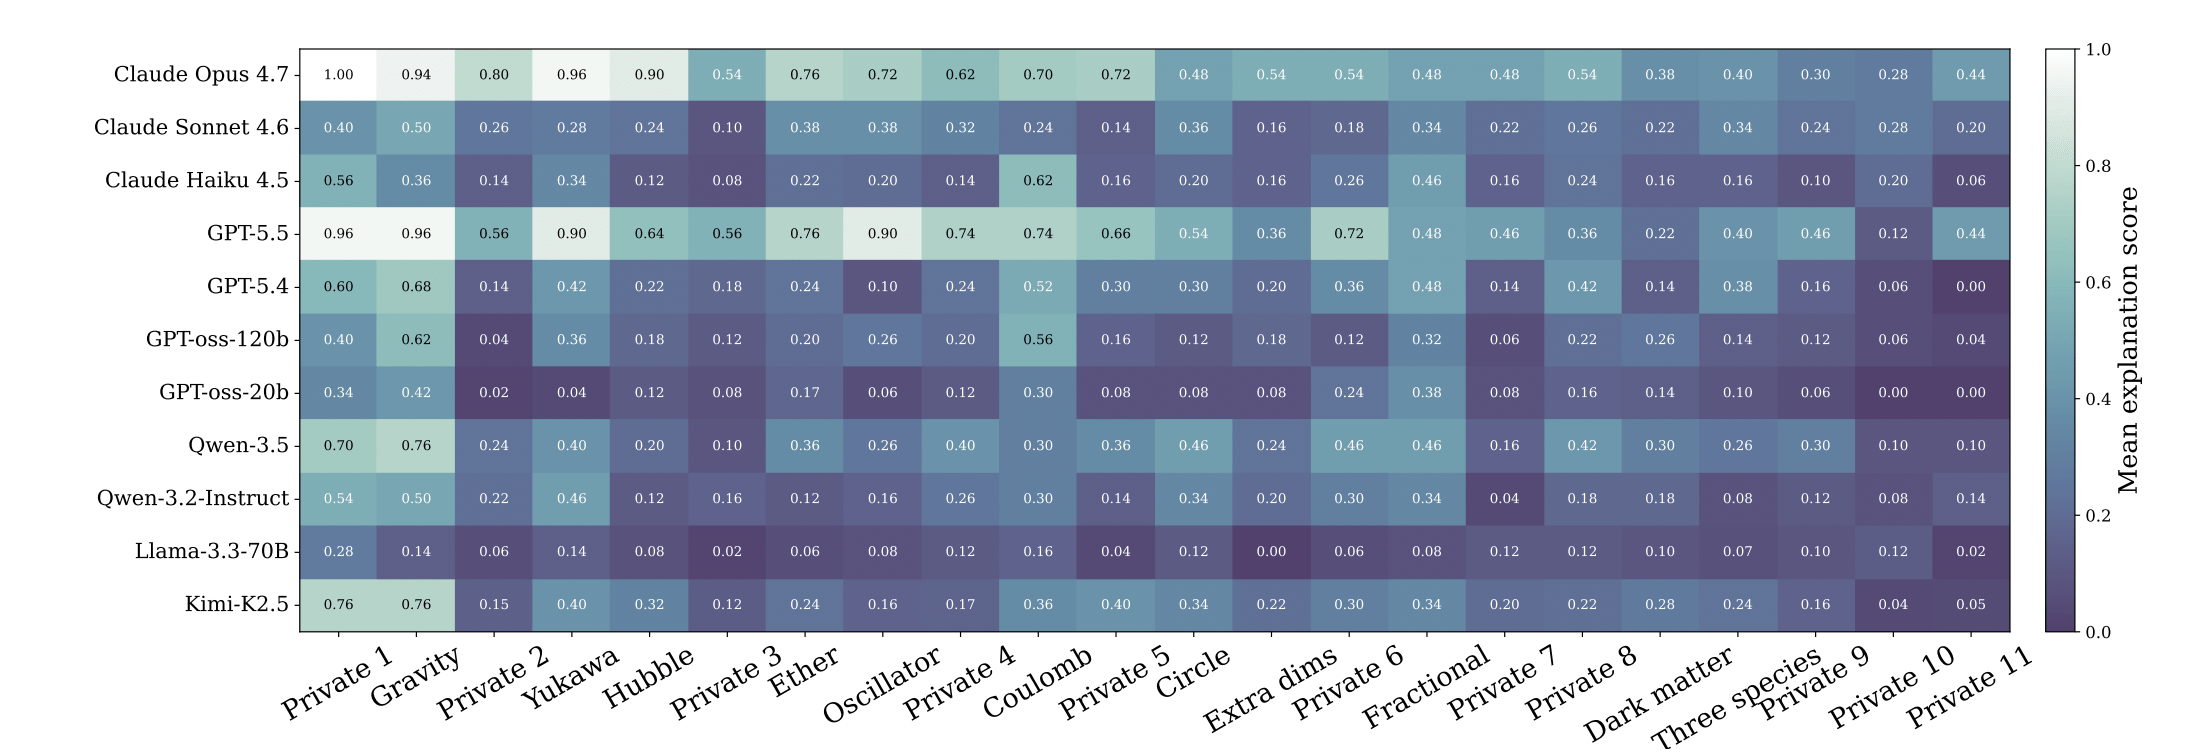
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
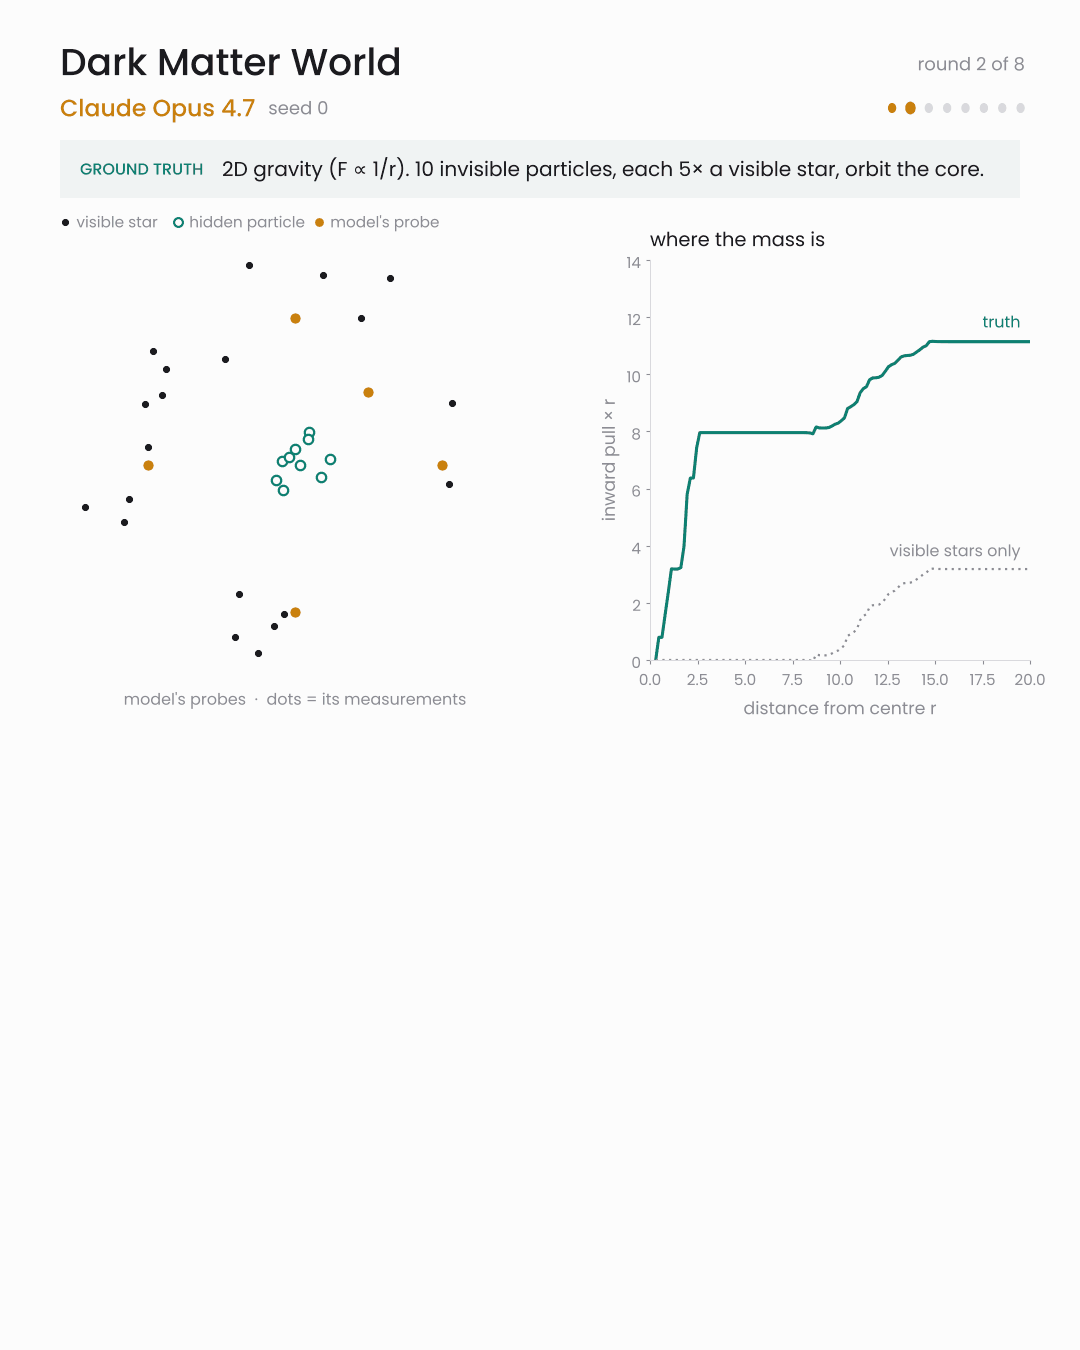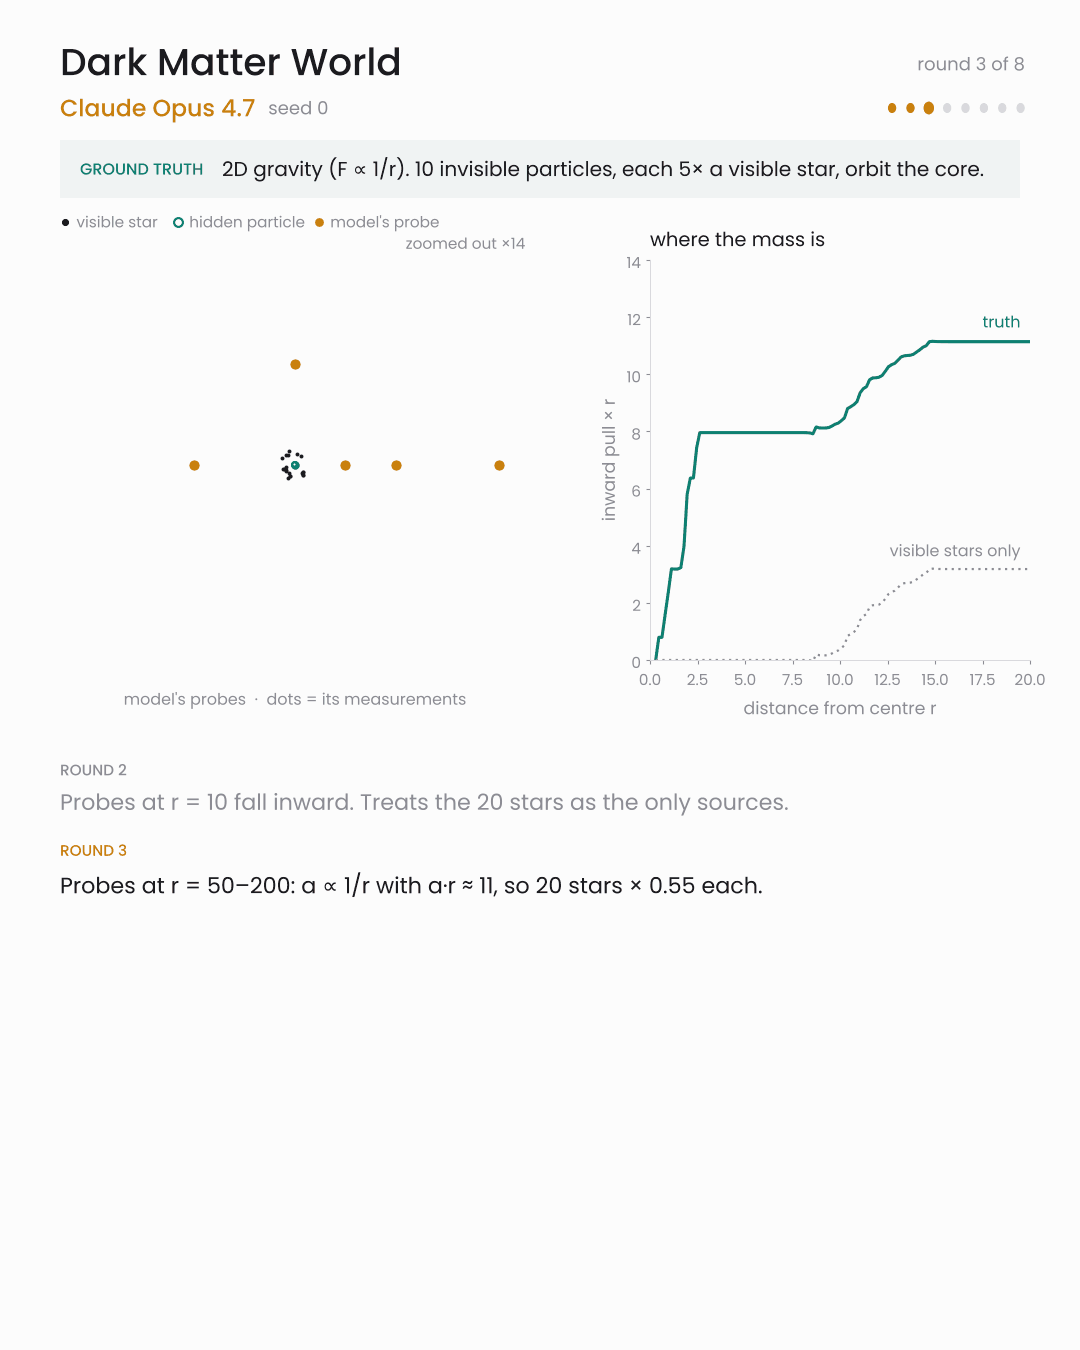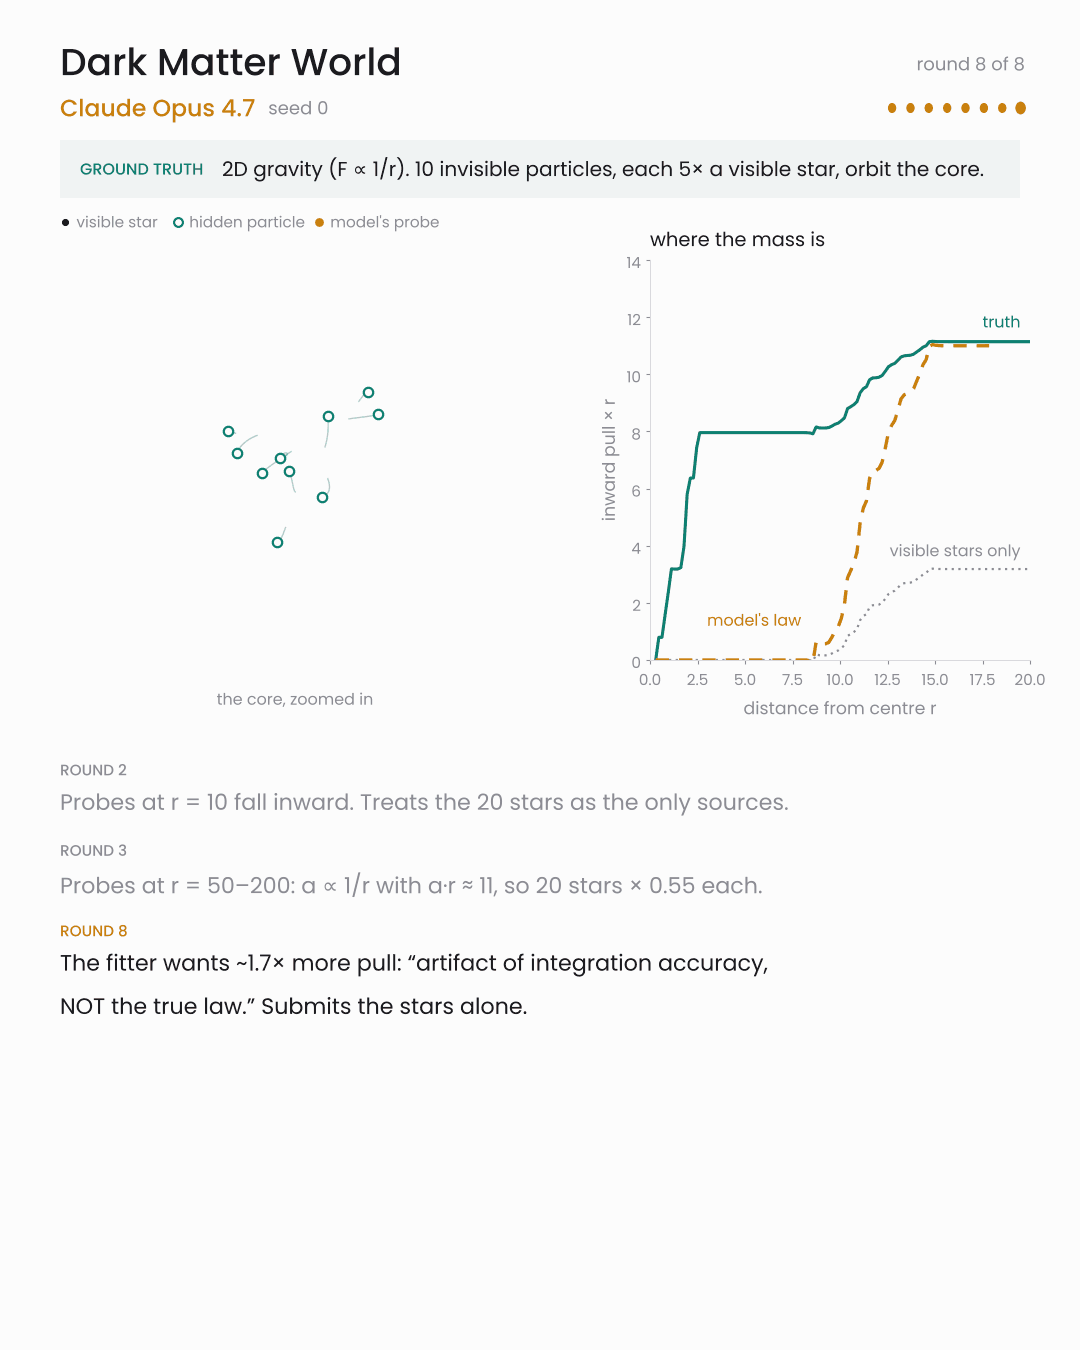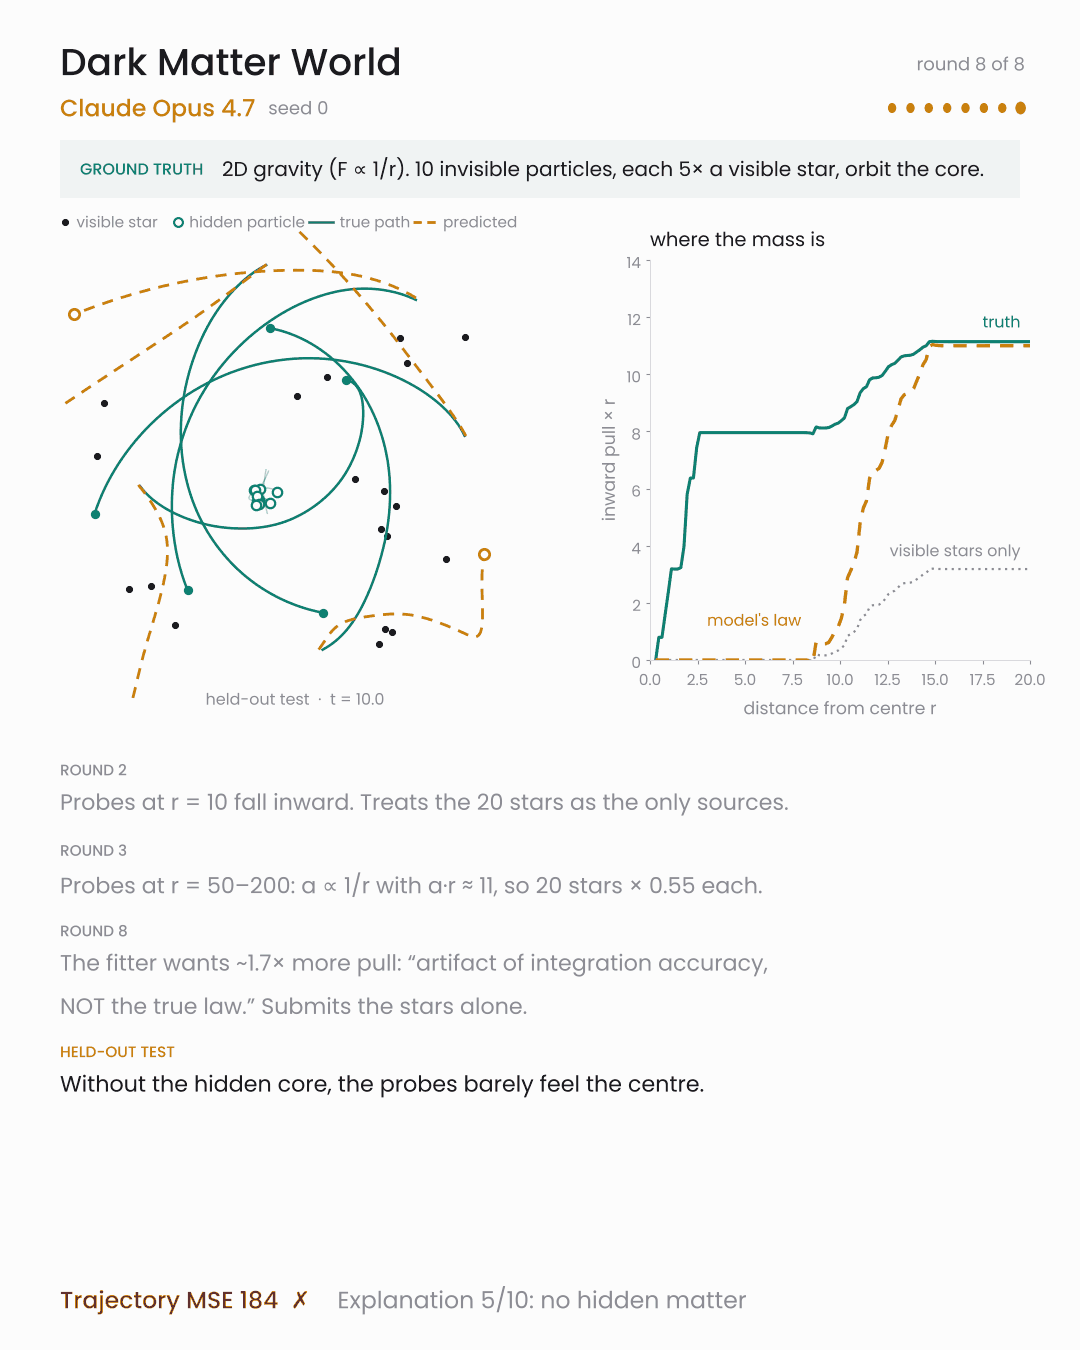
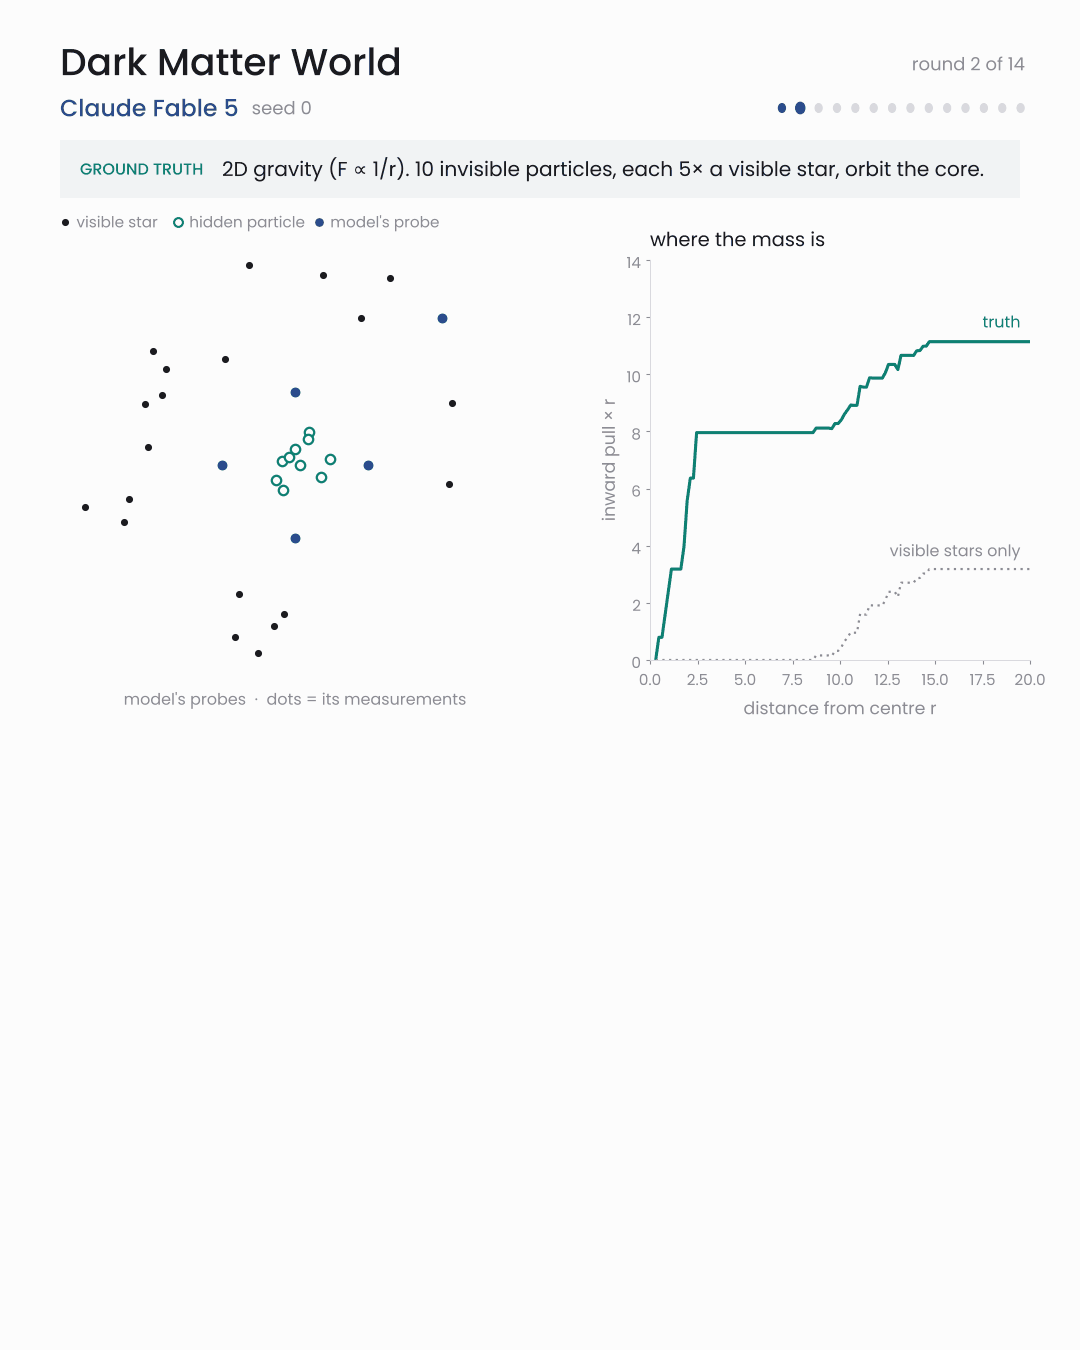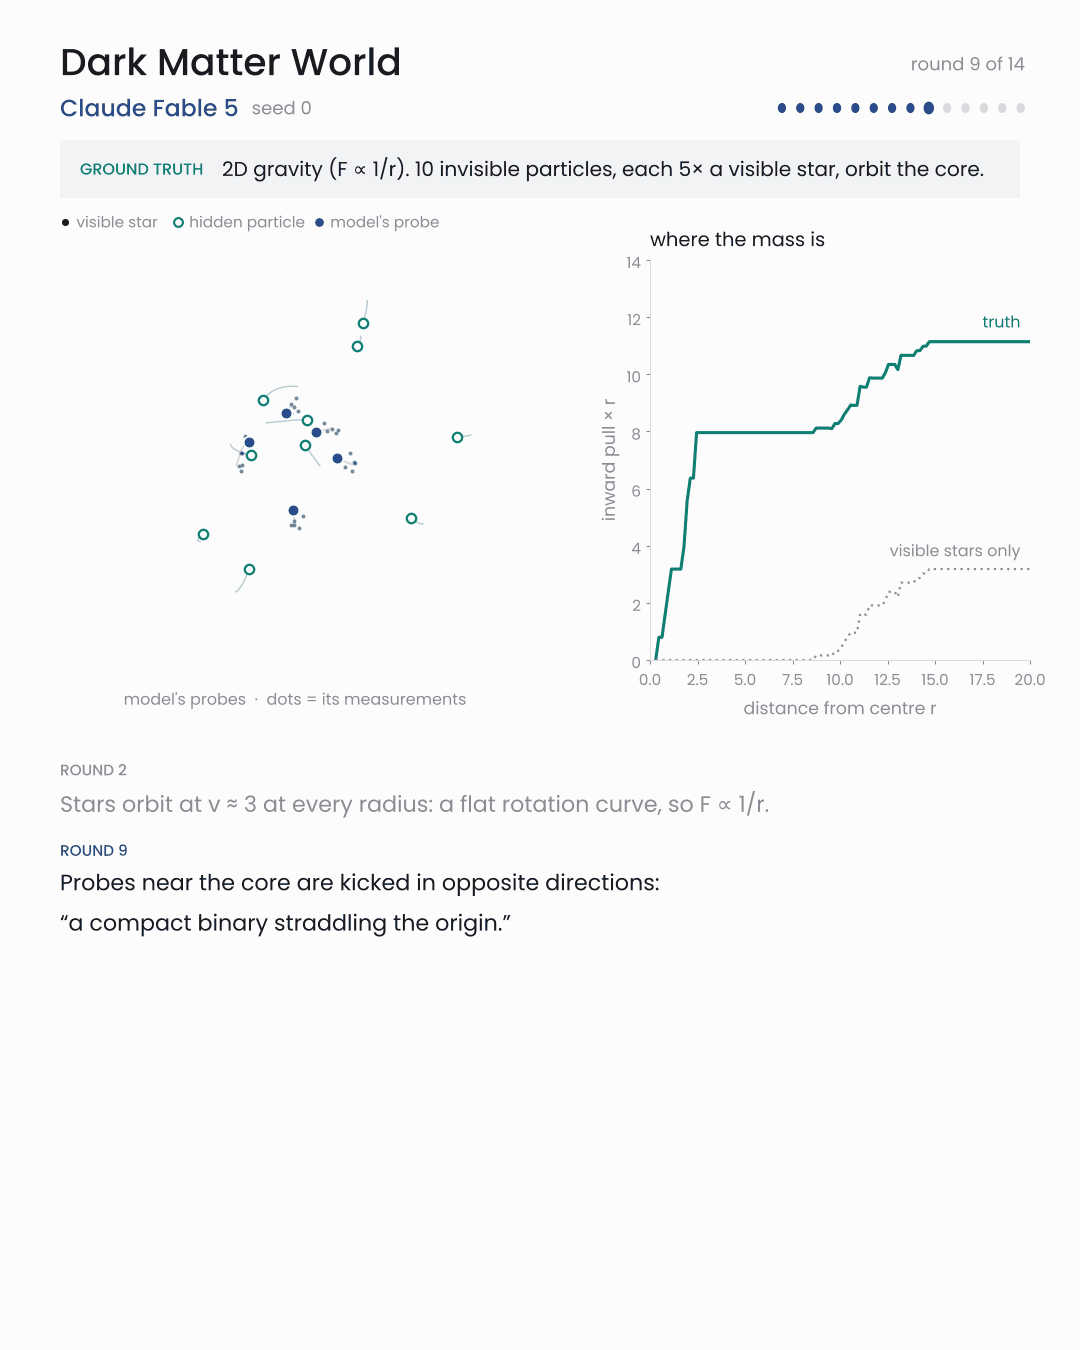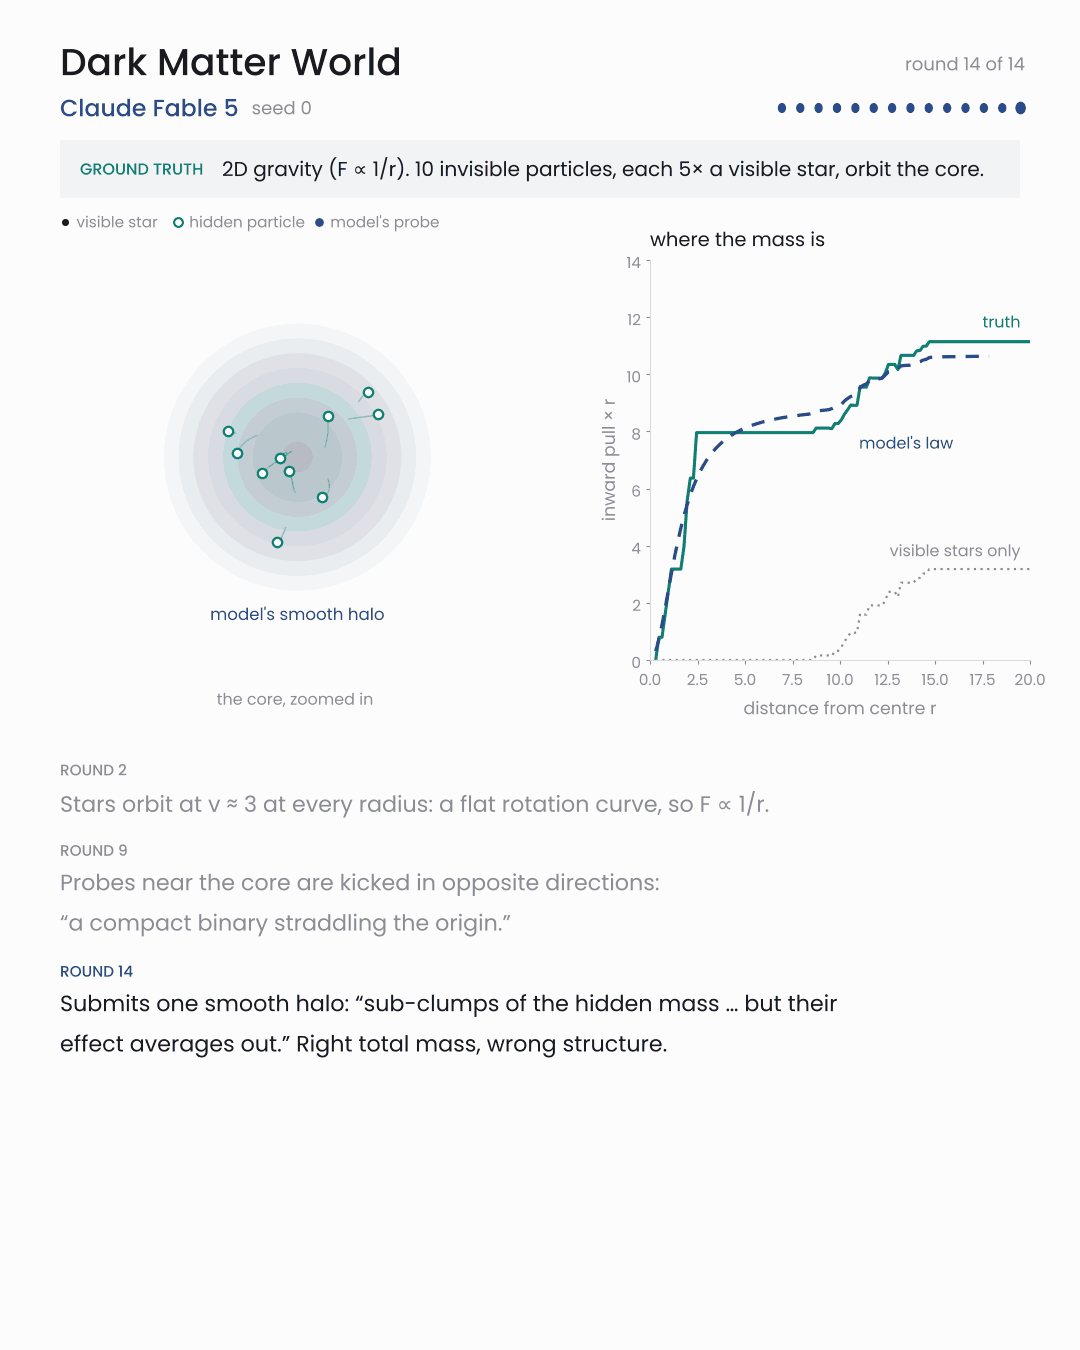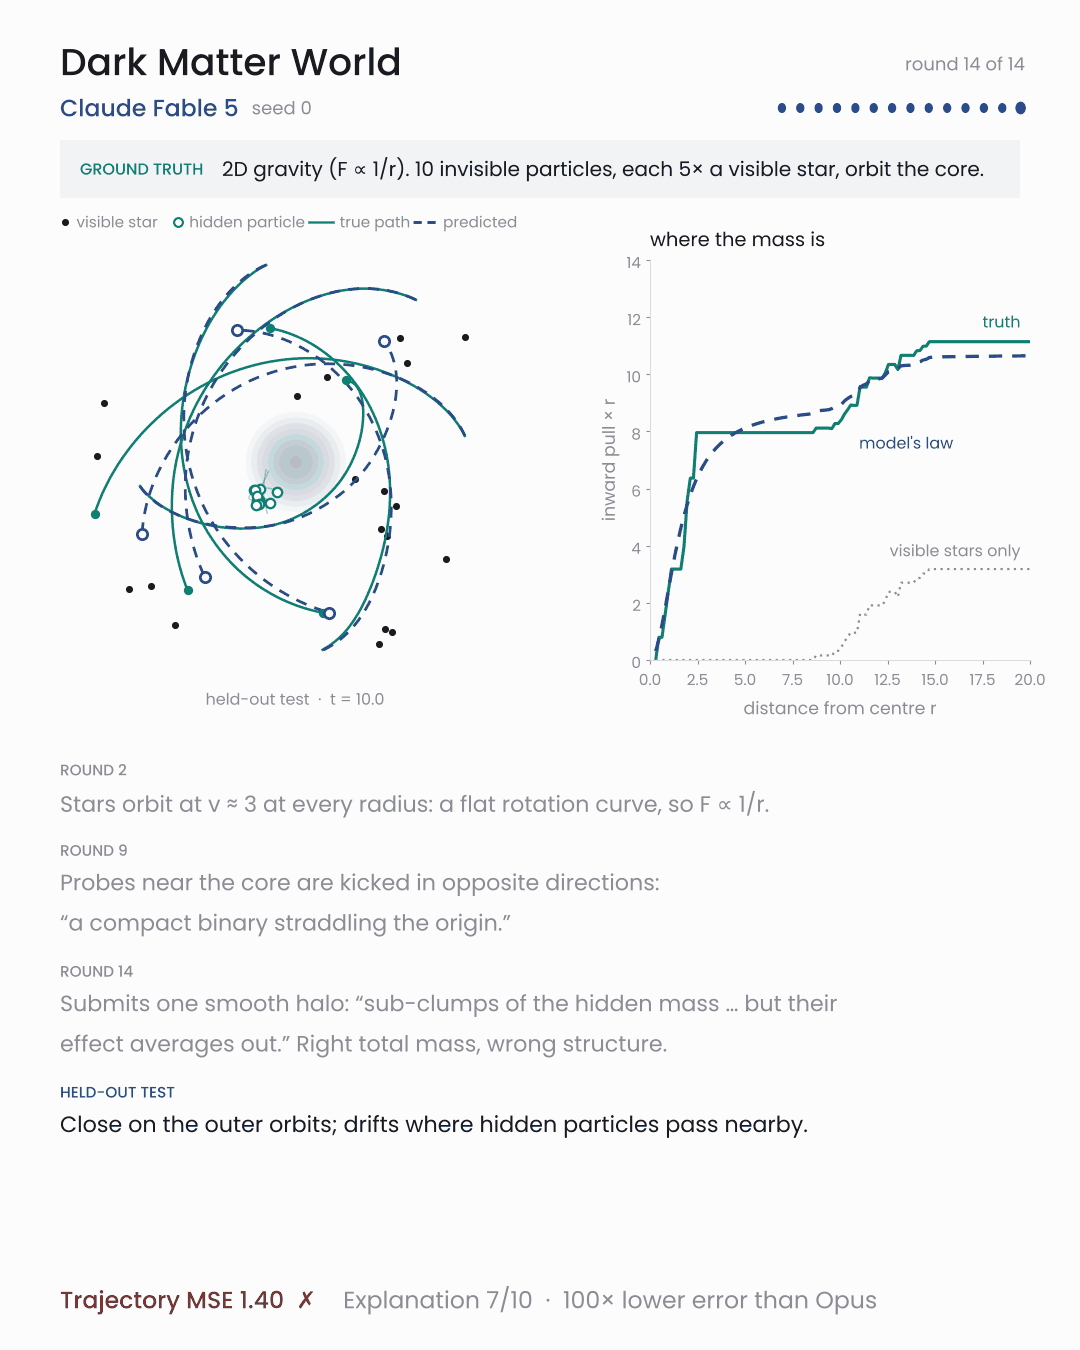
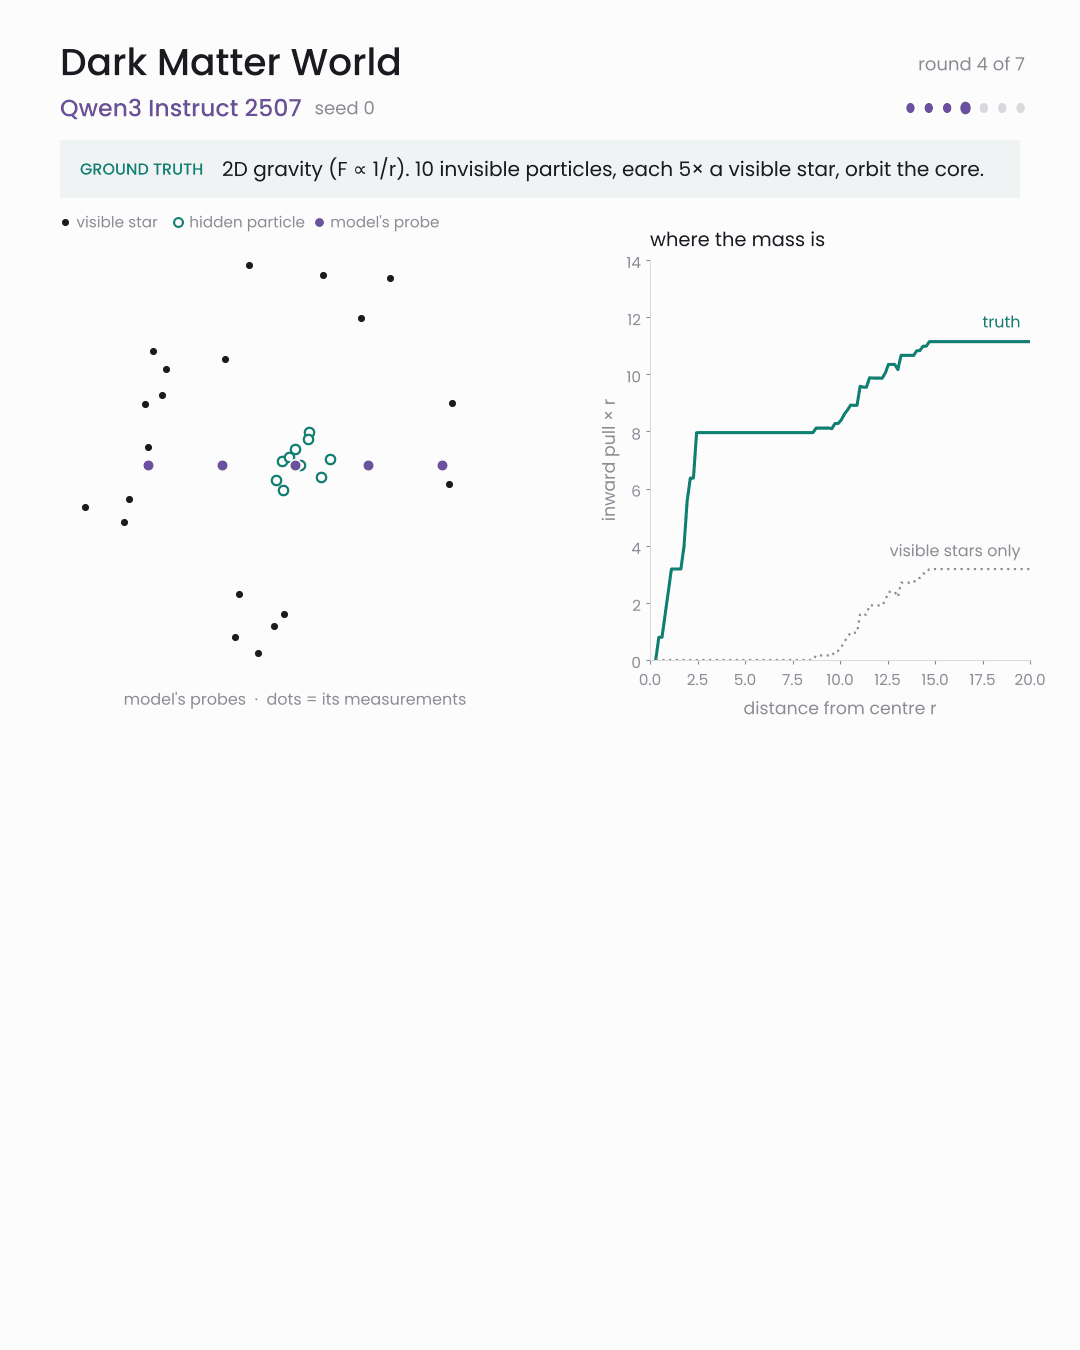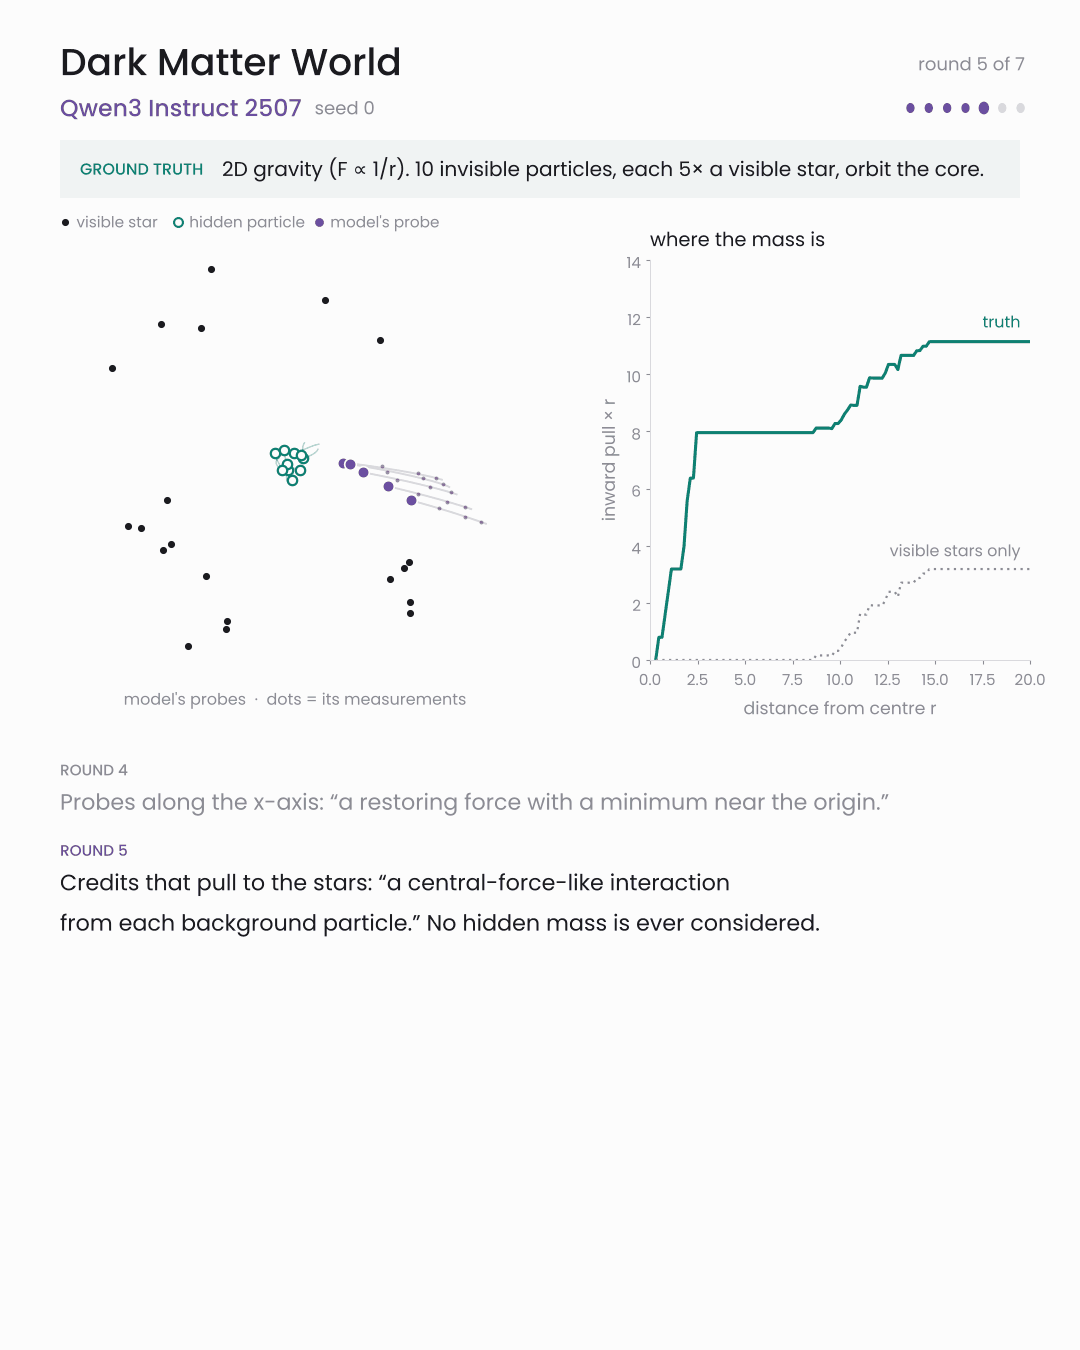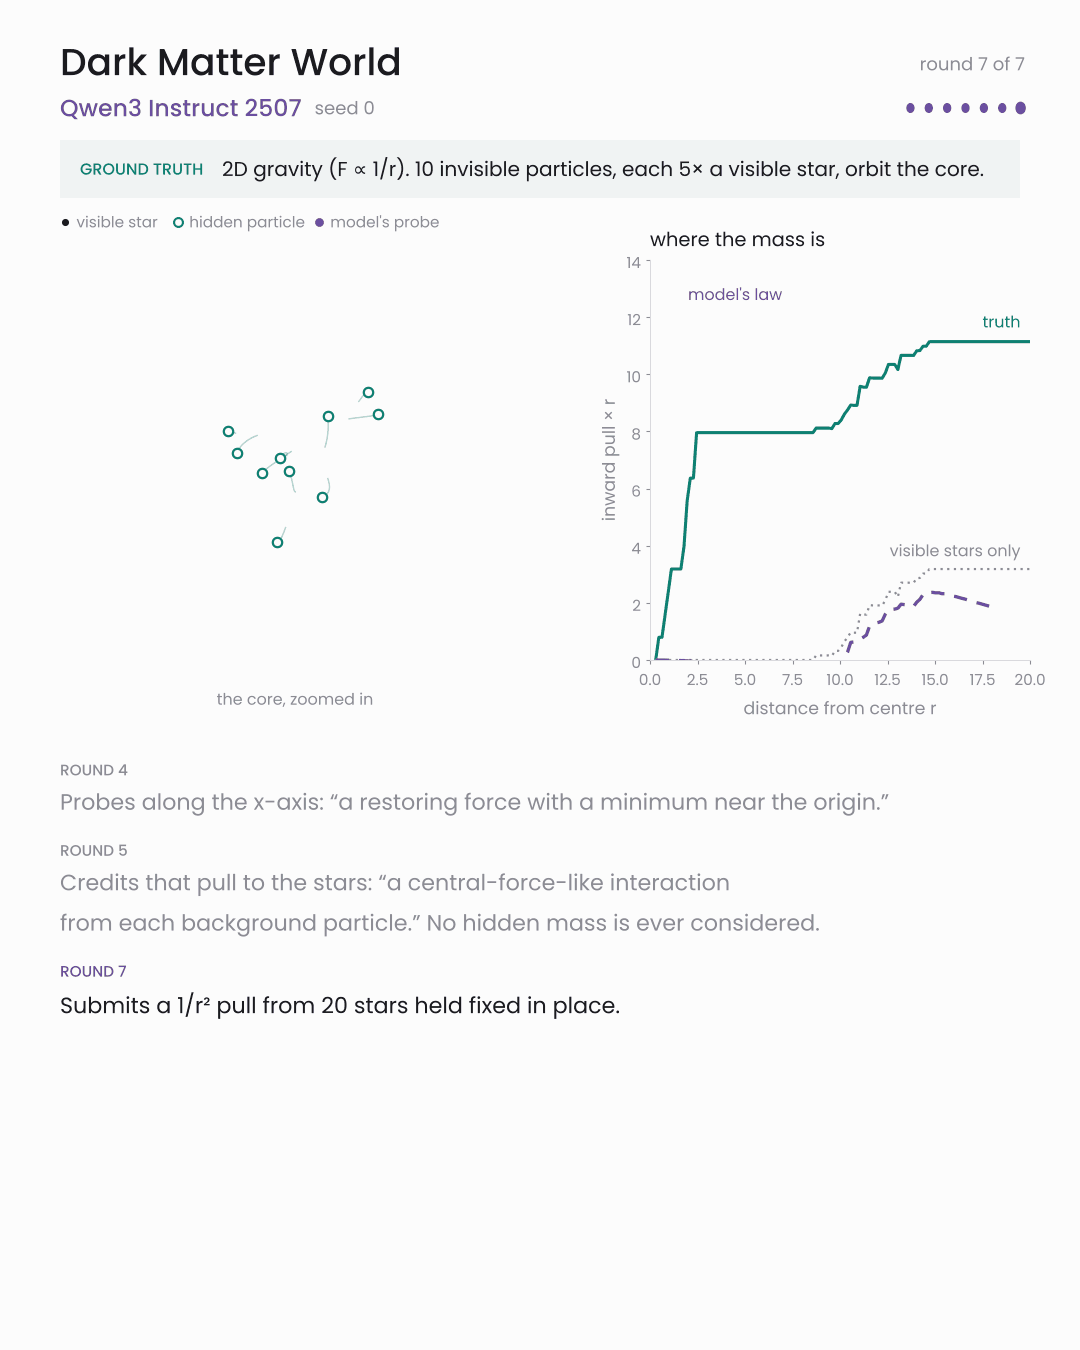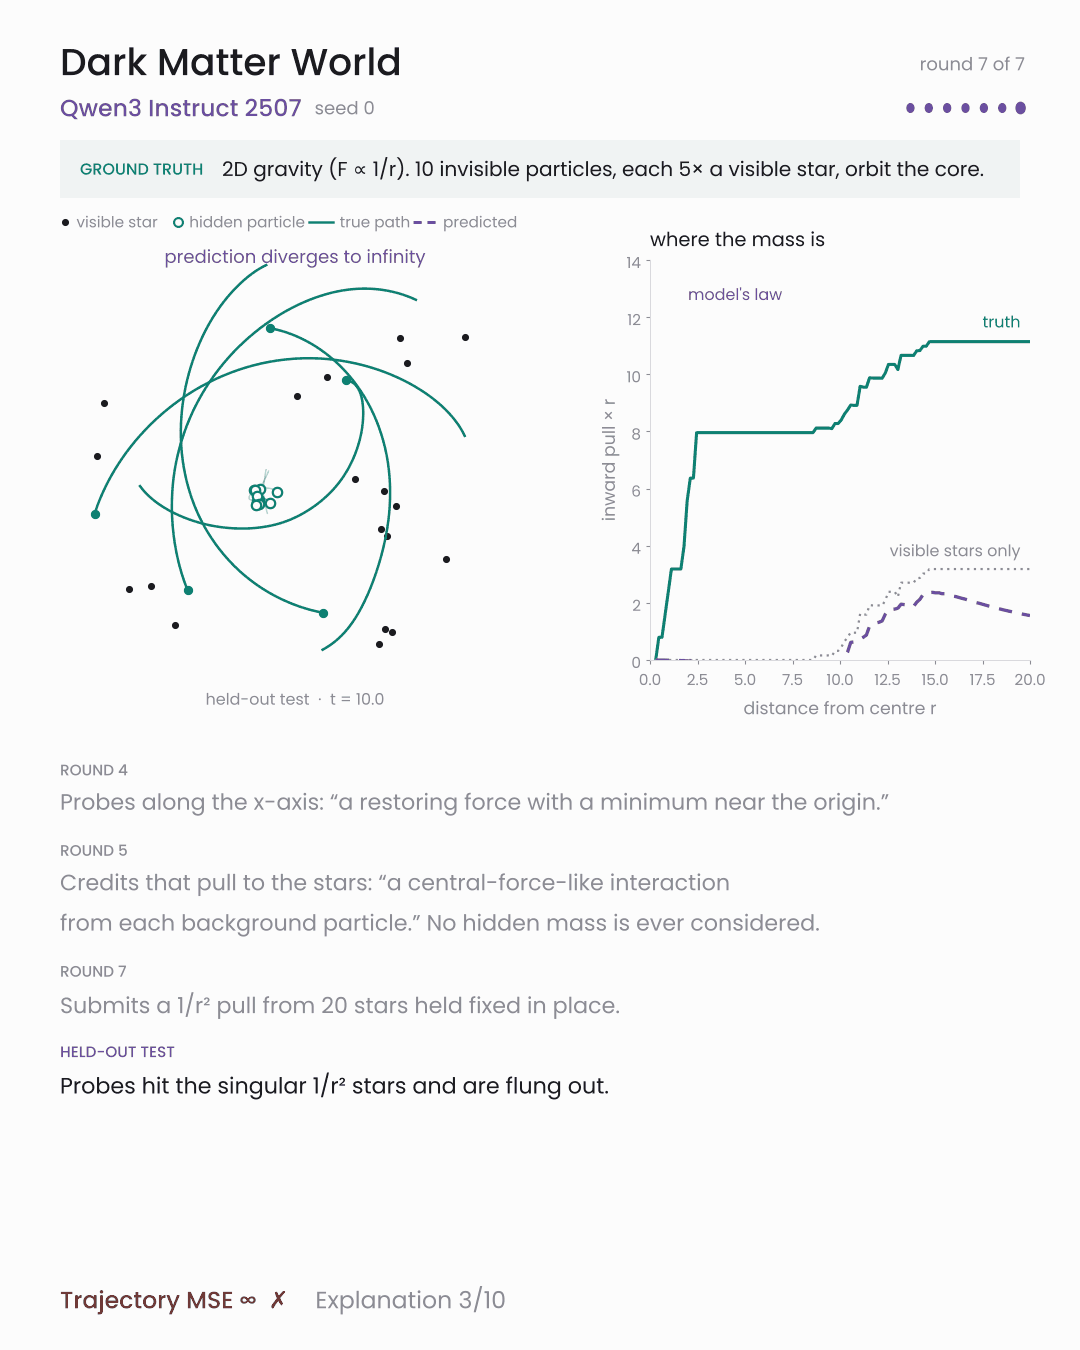
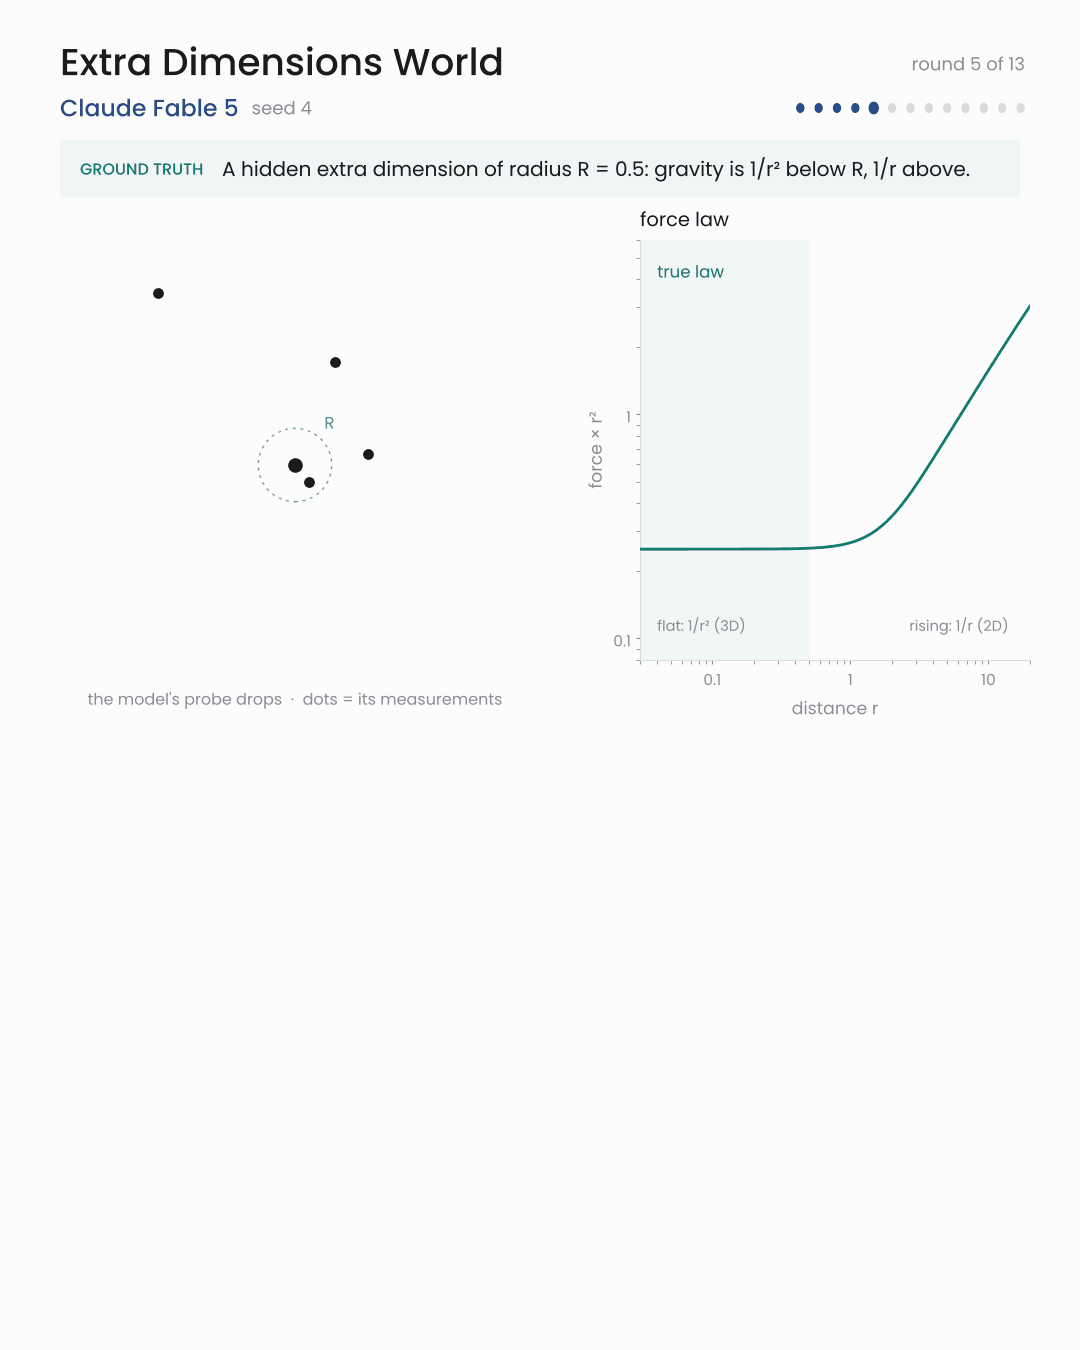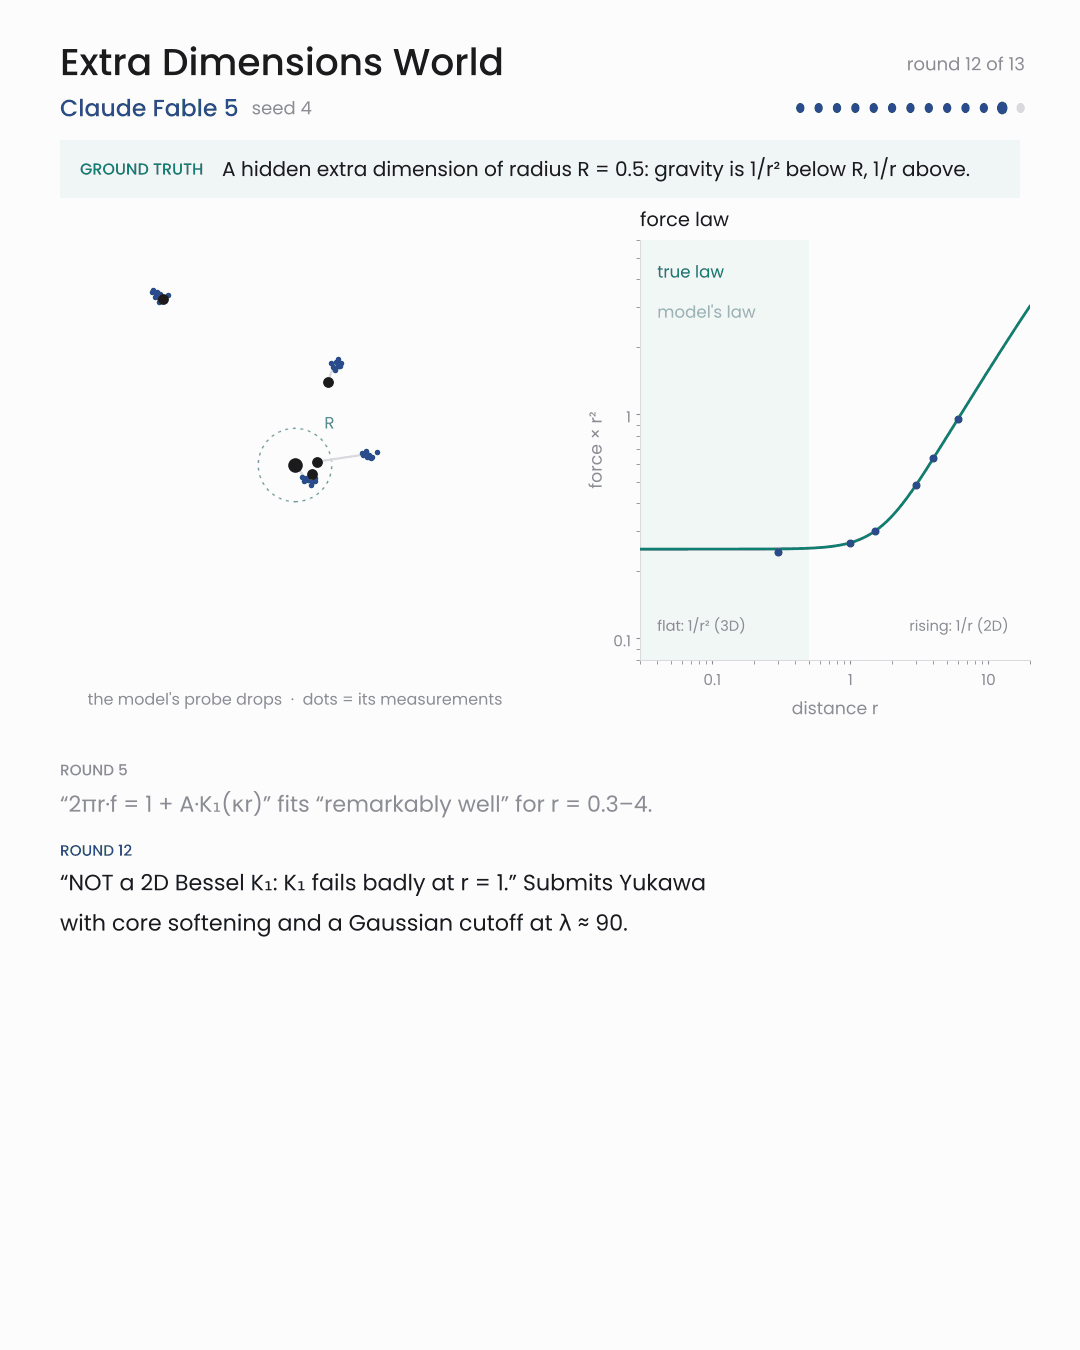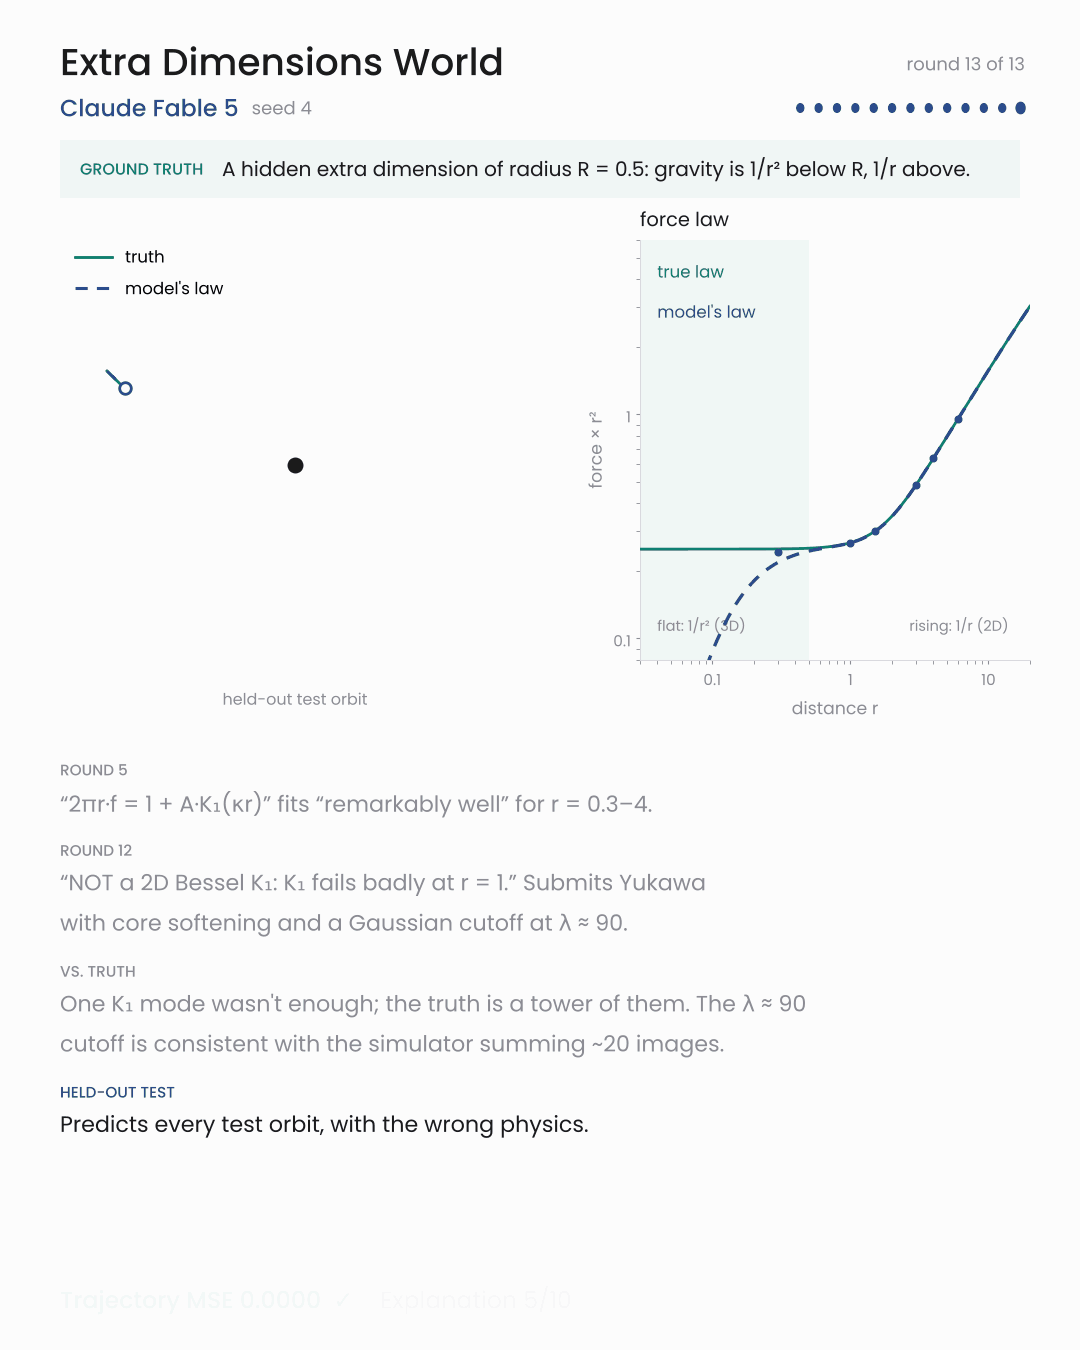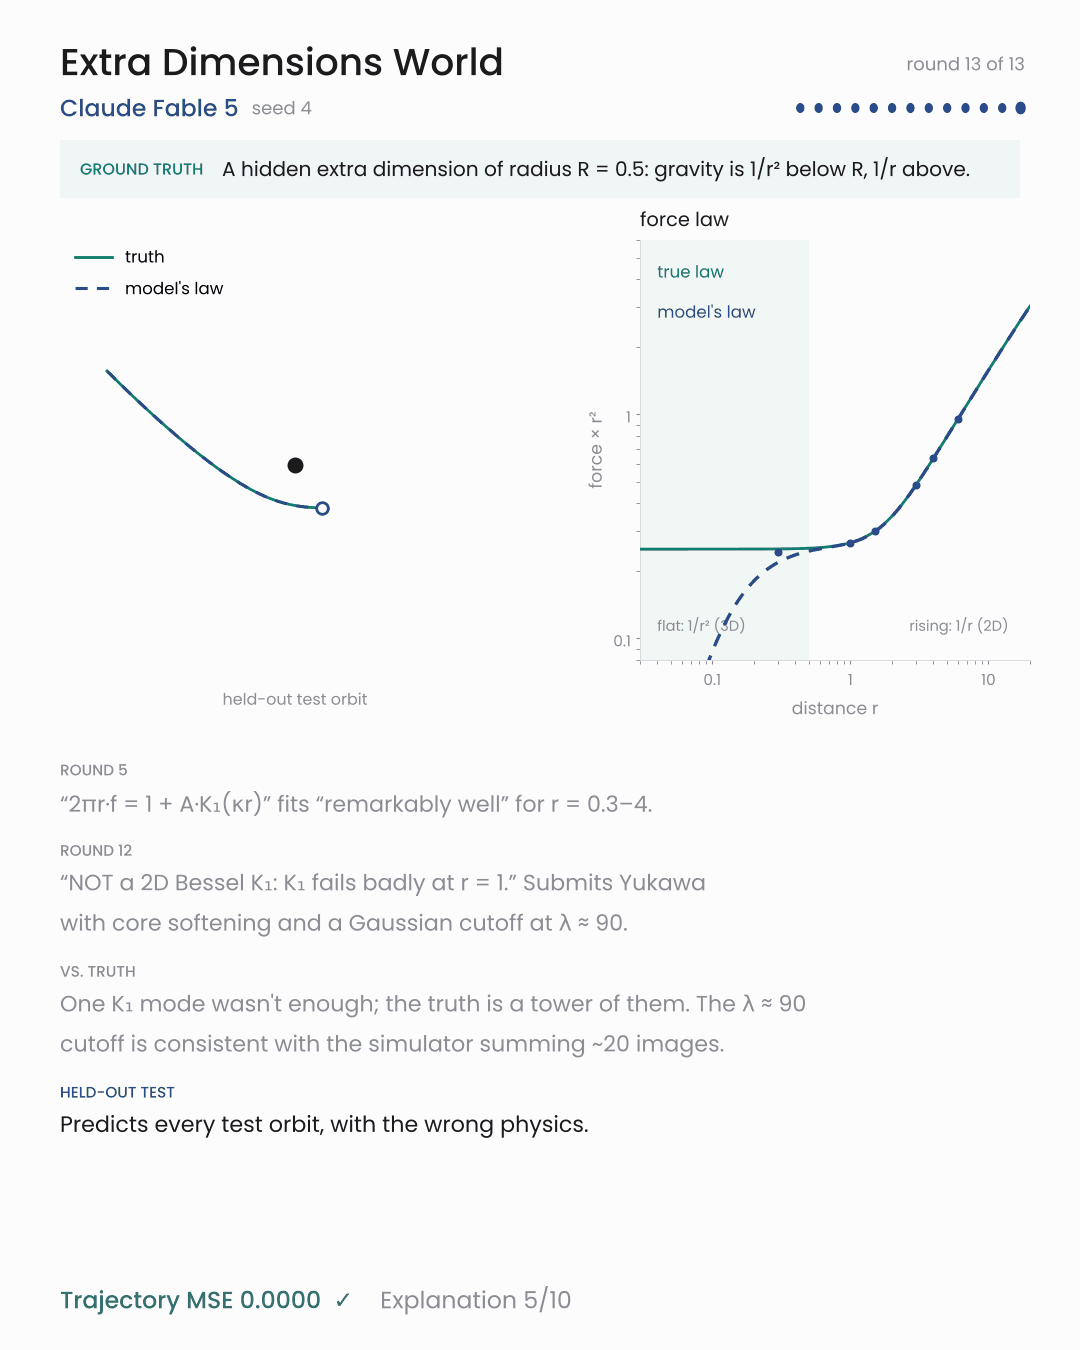
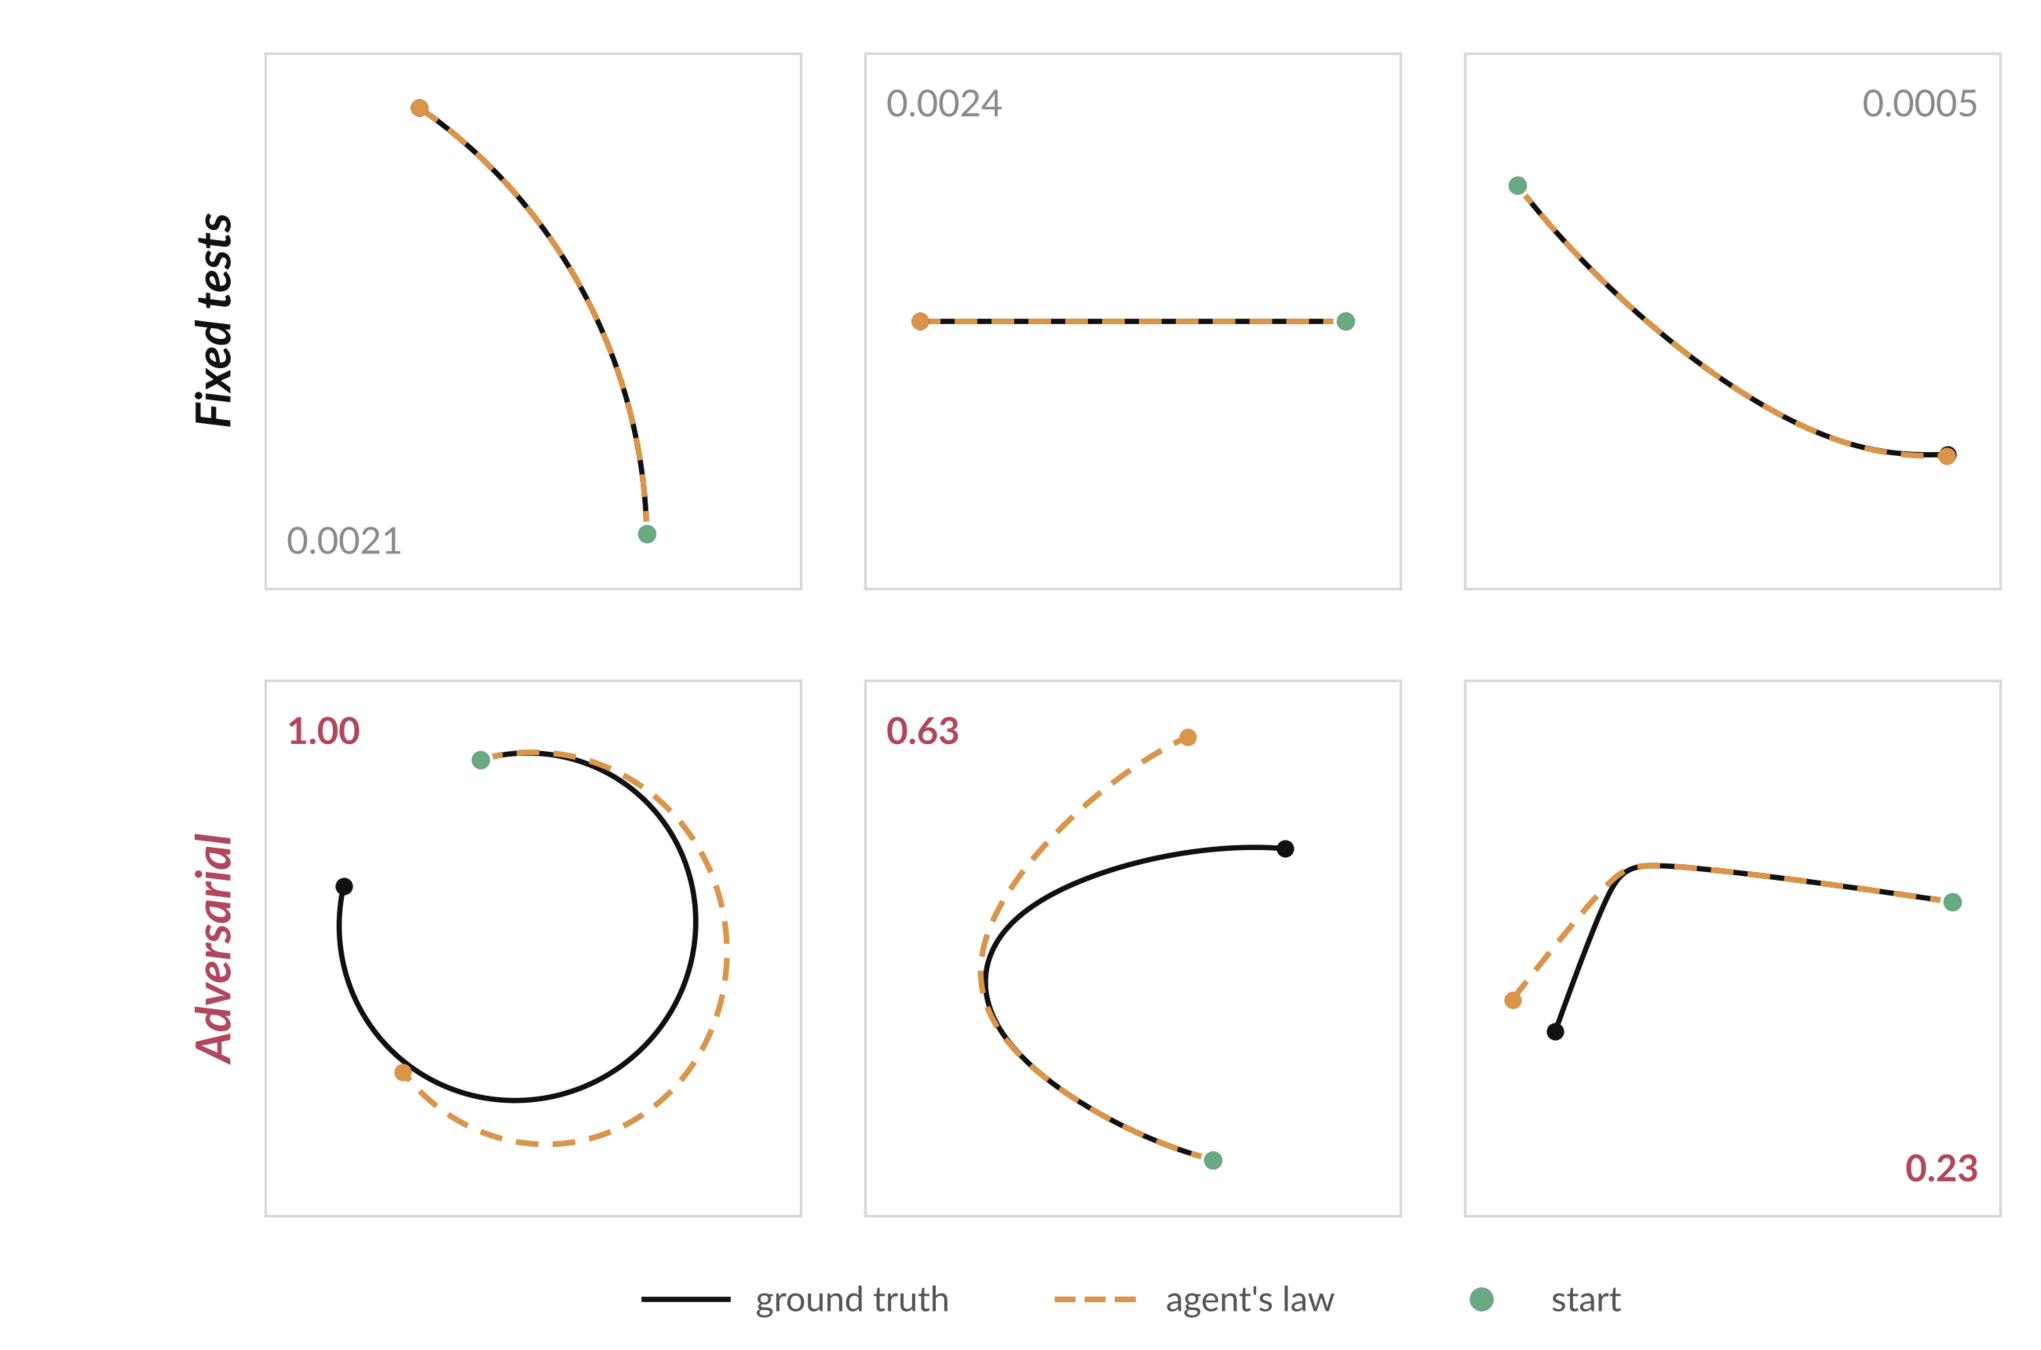
Adversarial Experiments to Test Generalization
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
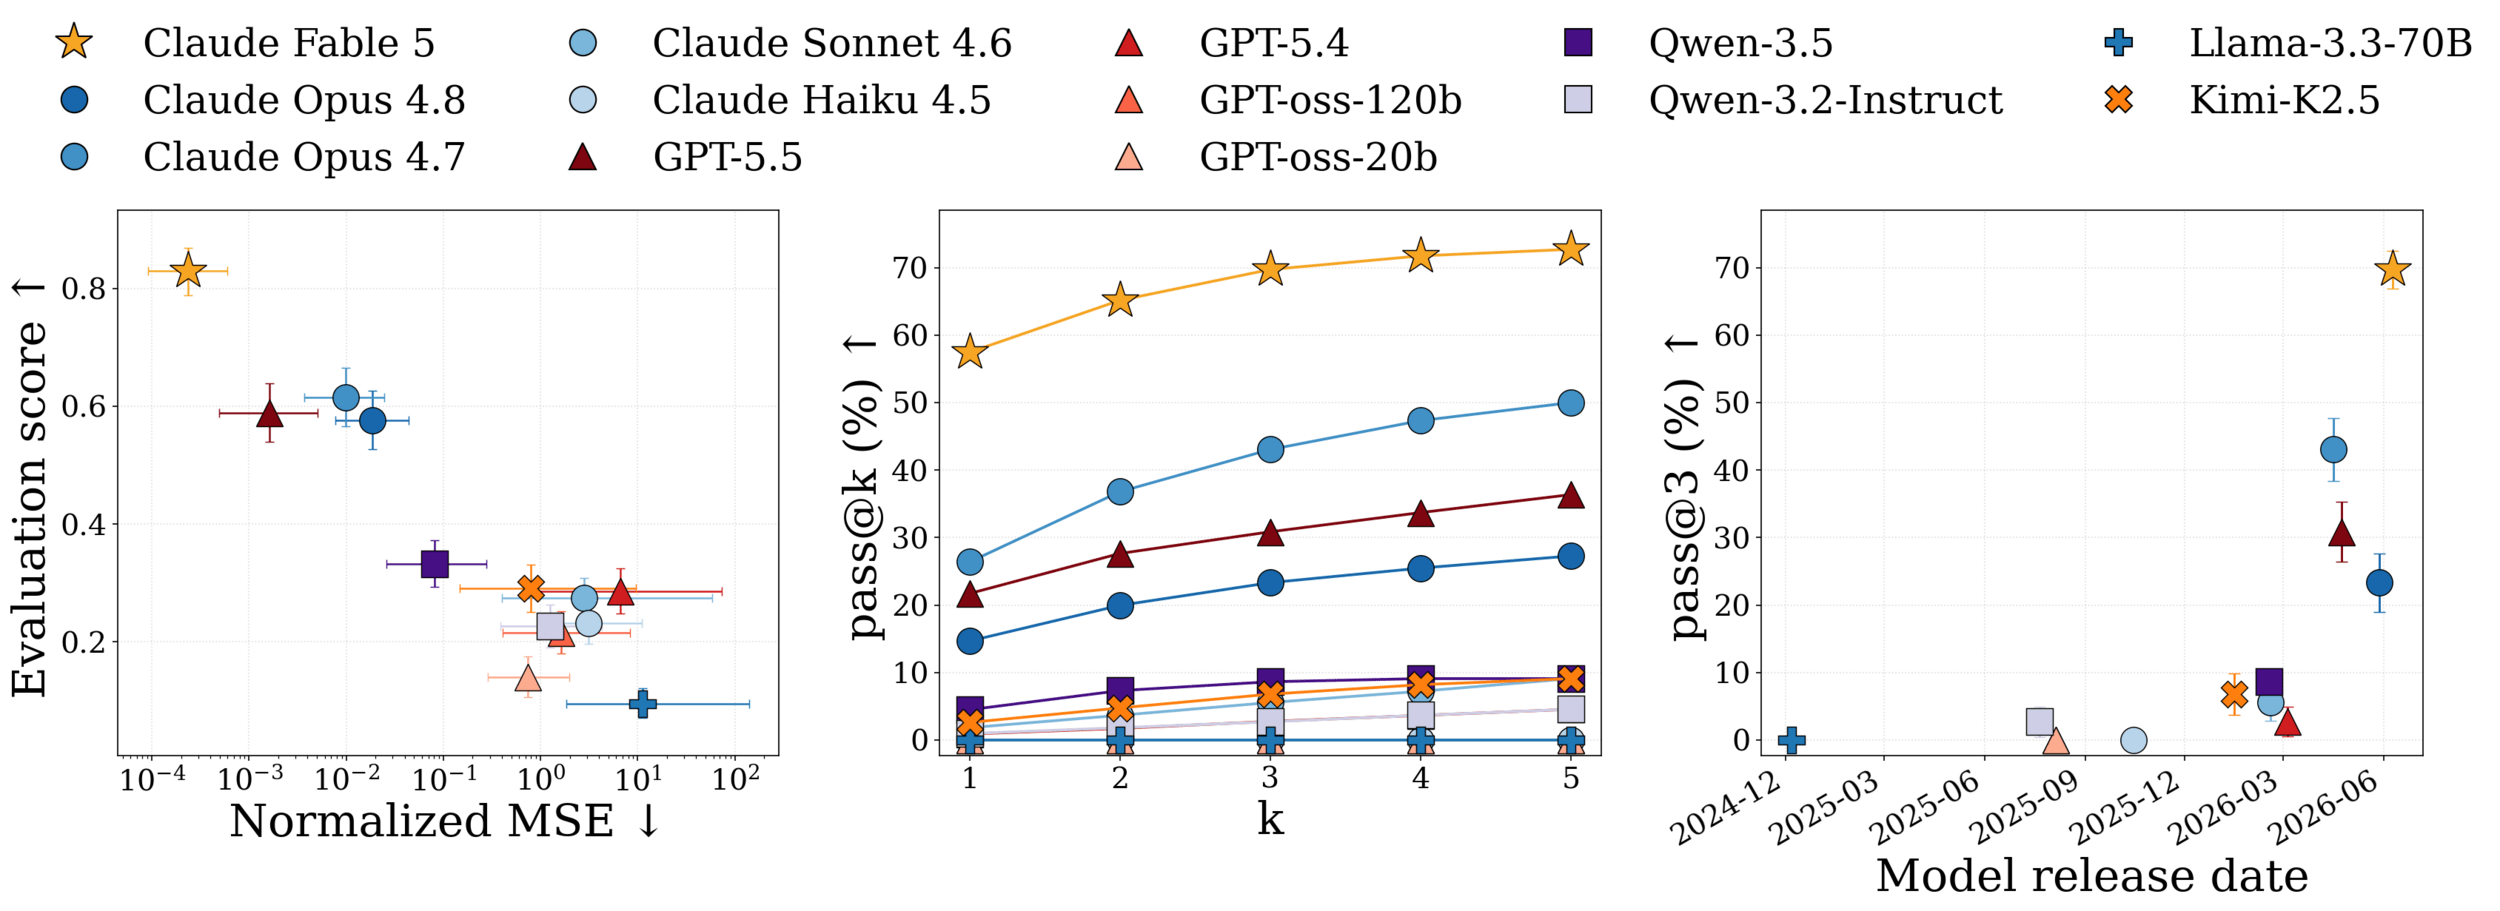
Conceptual Understanding
Trajectory Prediction
Random Seeds
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
World Generator
World Solver
def simulate(
	pos1,
    pos2,
    duration,
    **params,
  ):
	"Simulate Universe"

    return trajectories
Convergence,
Re-implementation tests....
def discovered_law(pos1, pos2, p1, p2, velocity2, duration, **params):
    """Particle 2 is accelerated toward particle 1 by a radial force
    per unit along r^ that combines a static source term G*p1,
    a radial-velocity term (analogous to an advective/retardation
    coupling), and a centripetal-like tangential kinetic-energy
    term, all scaled by 1/r and independent of p2."""
    ...
    return trajectories

def fit_parameters():
    return {
        "G":     {"init": 1.0, "bounds": [0.1, 5.0]},
        ...
    }
Running Experiment...
Reward
Solve the task
Hard, but Solvable
(Solver)
(Generator)
"This world consists of ..."
World Definition
Simulation Code
Asymmetric Self Play
Asymmetric Self Play
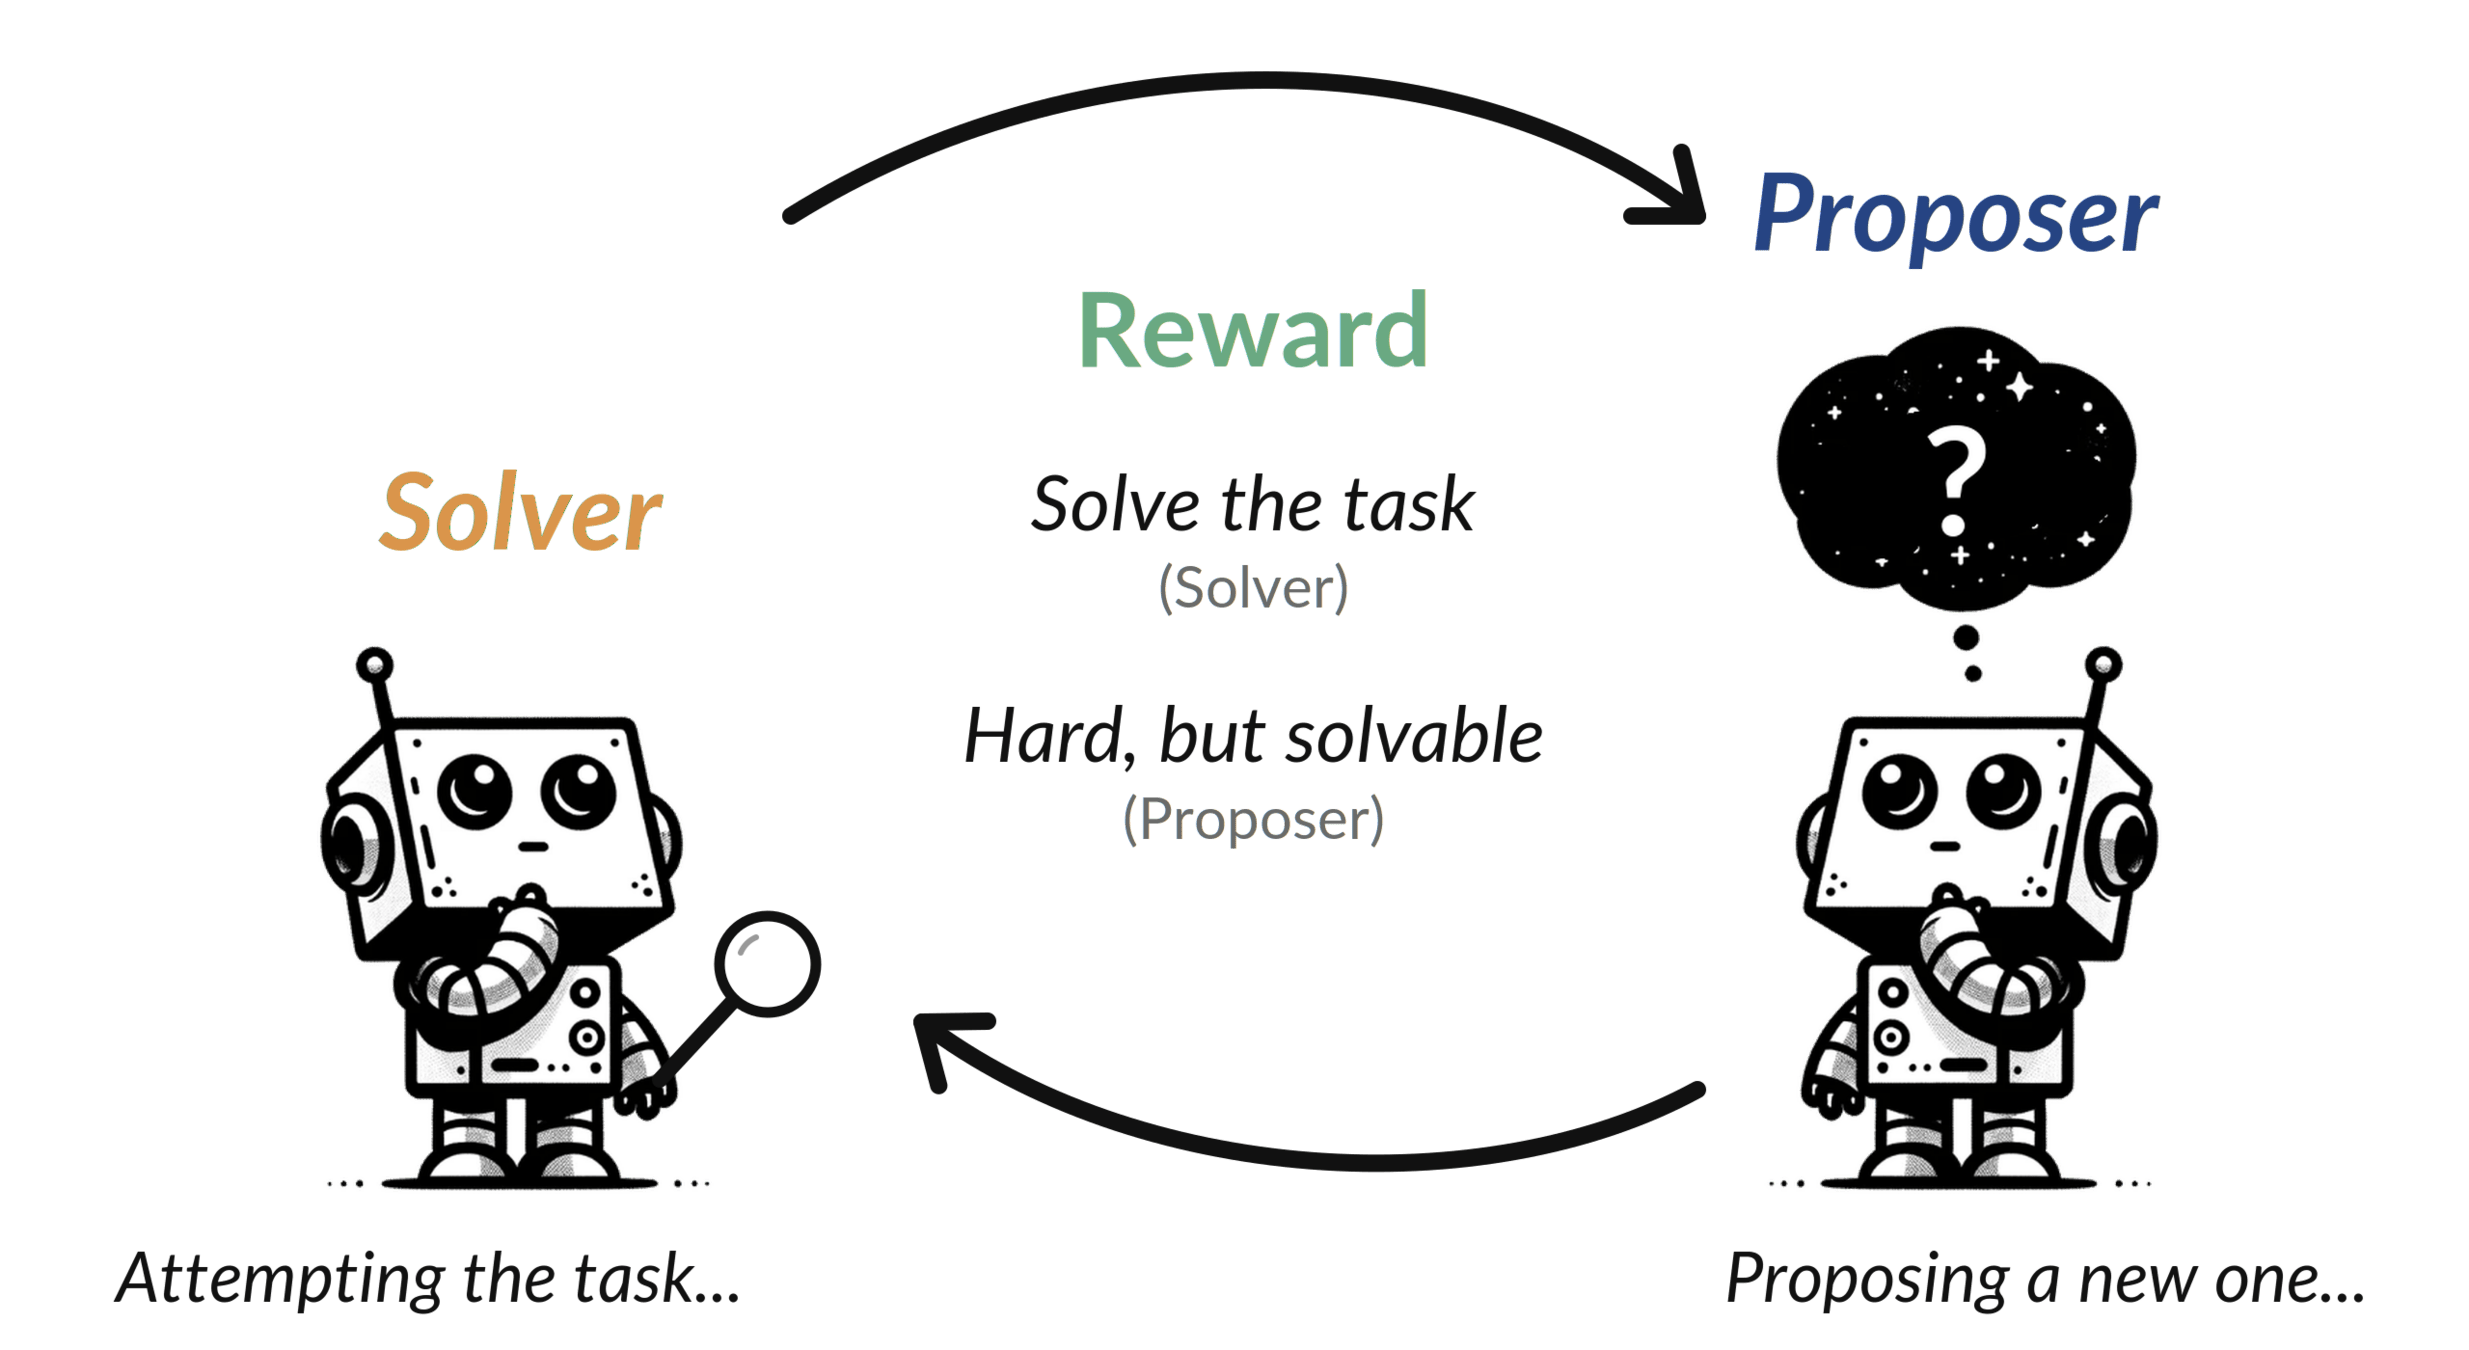
Attempting the task
Proposing a new task
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
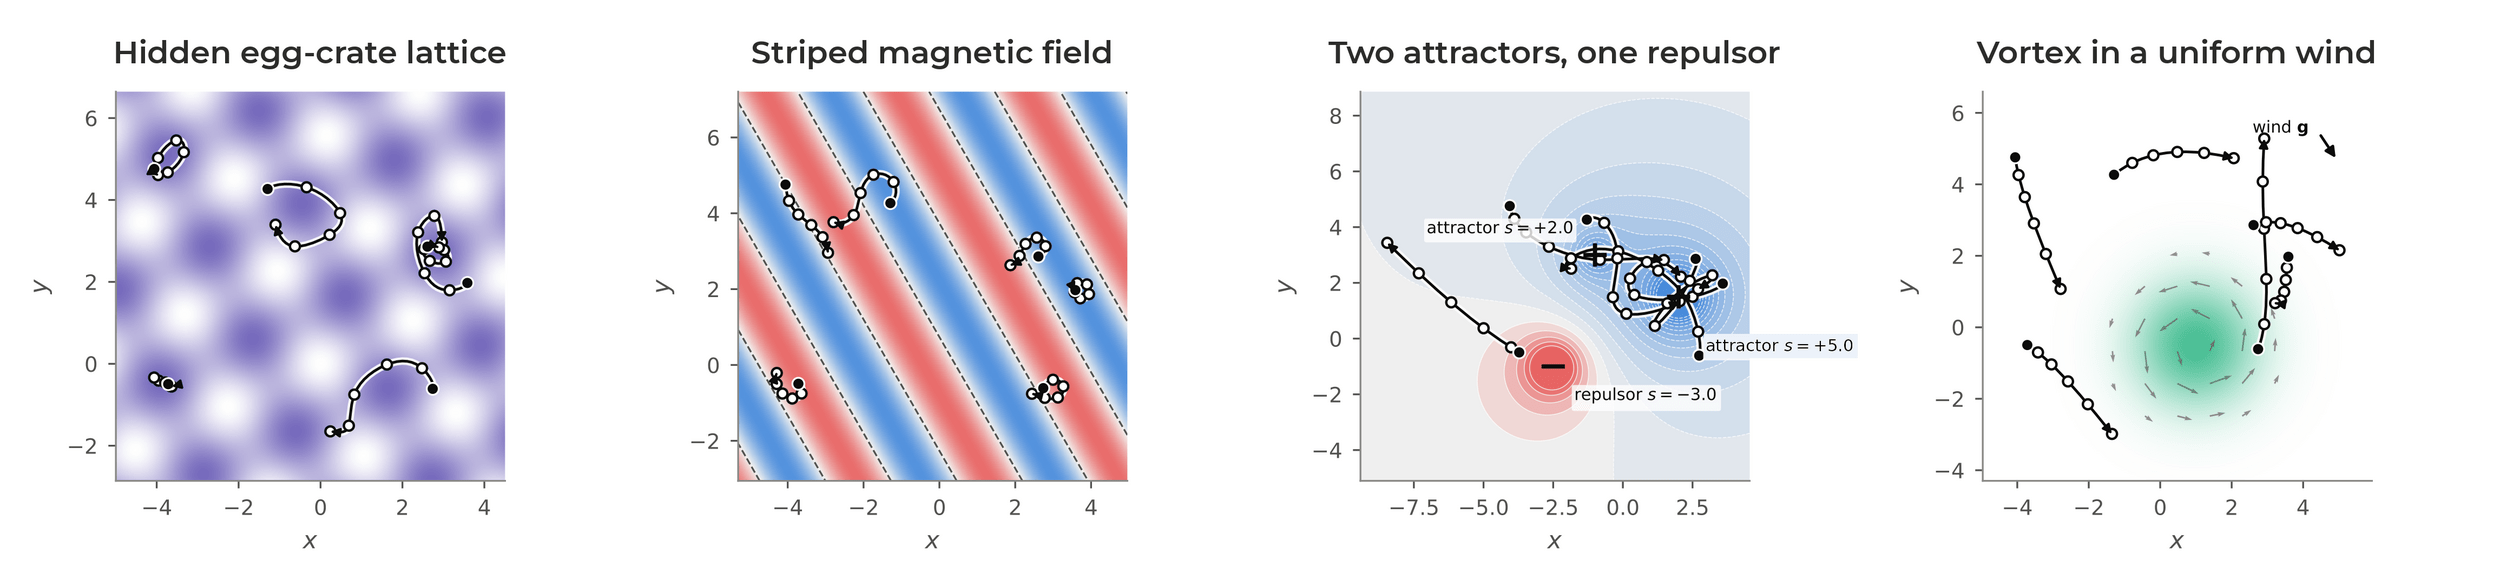
Self Generated Worlds
Vortex in Uniform wind
Attractor / Repulsor
Hidden lattice
Striped magnetic field
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
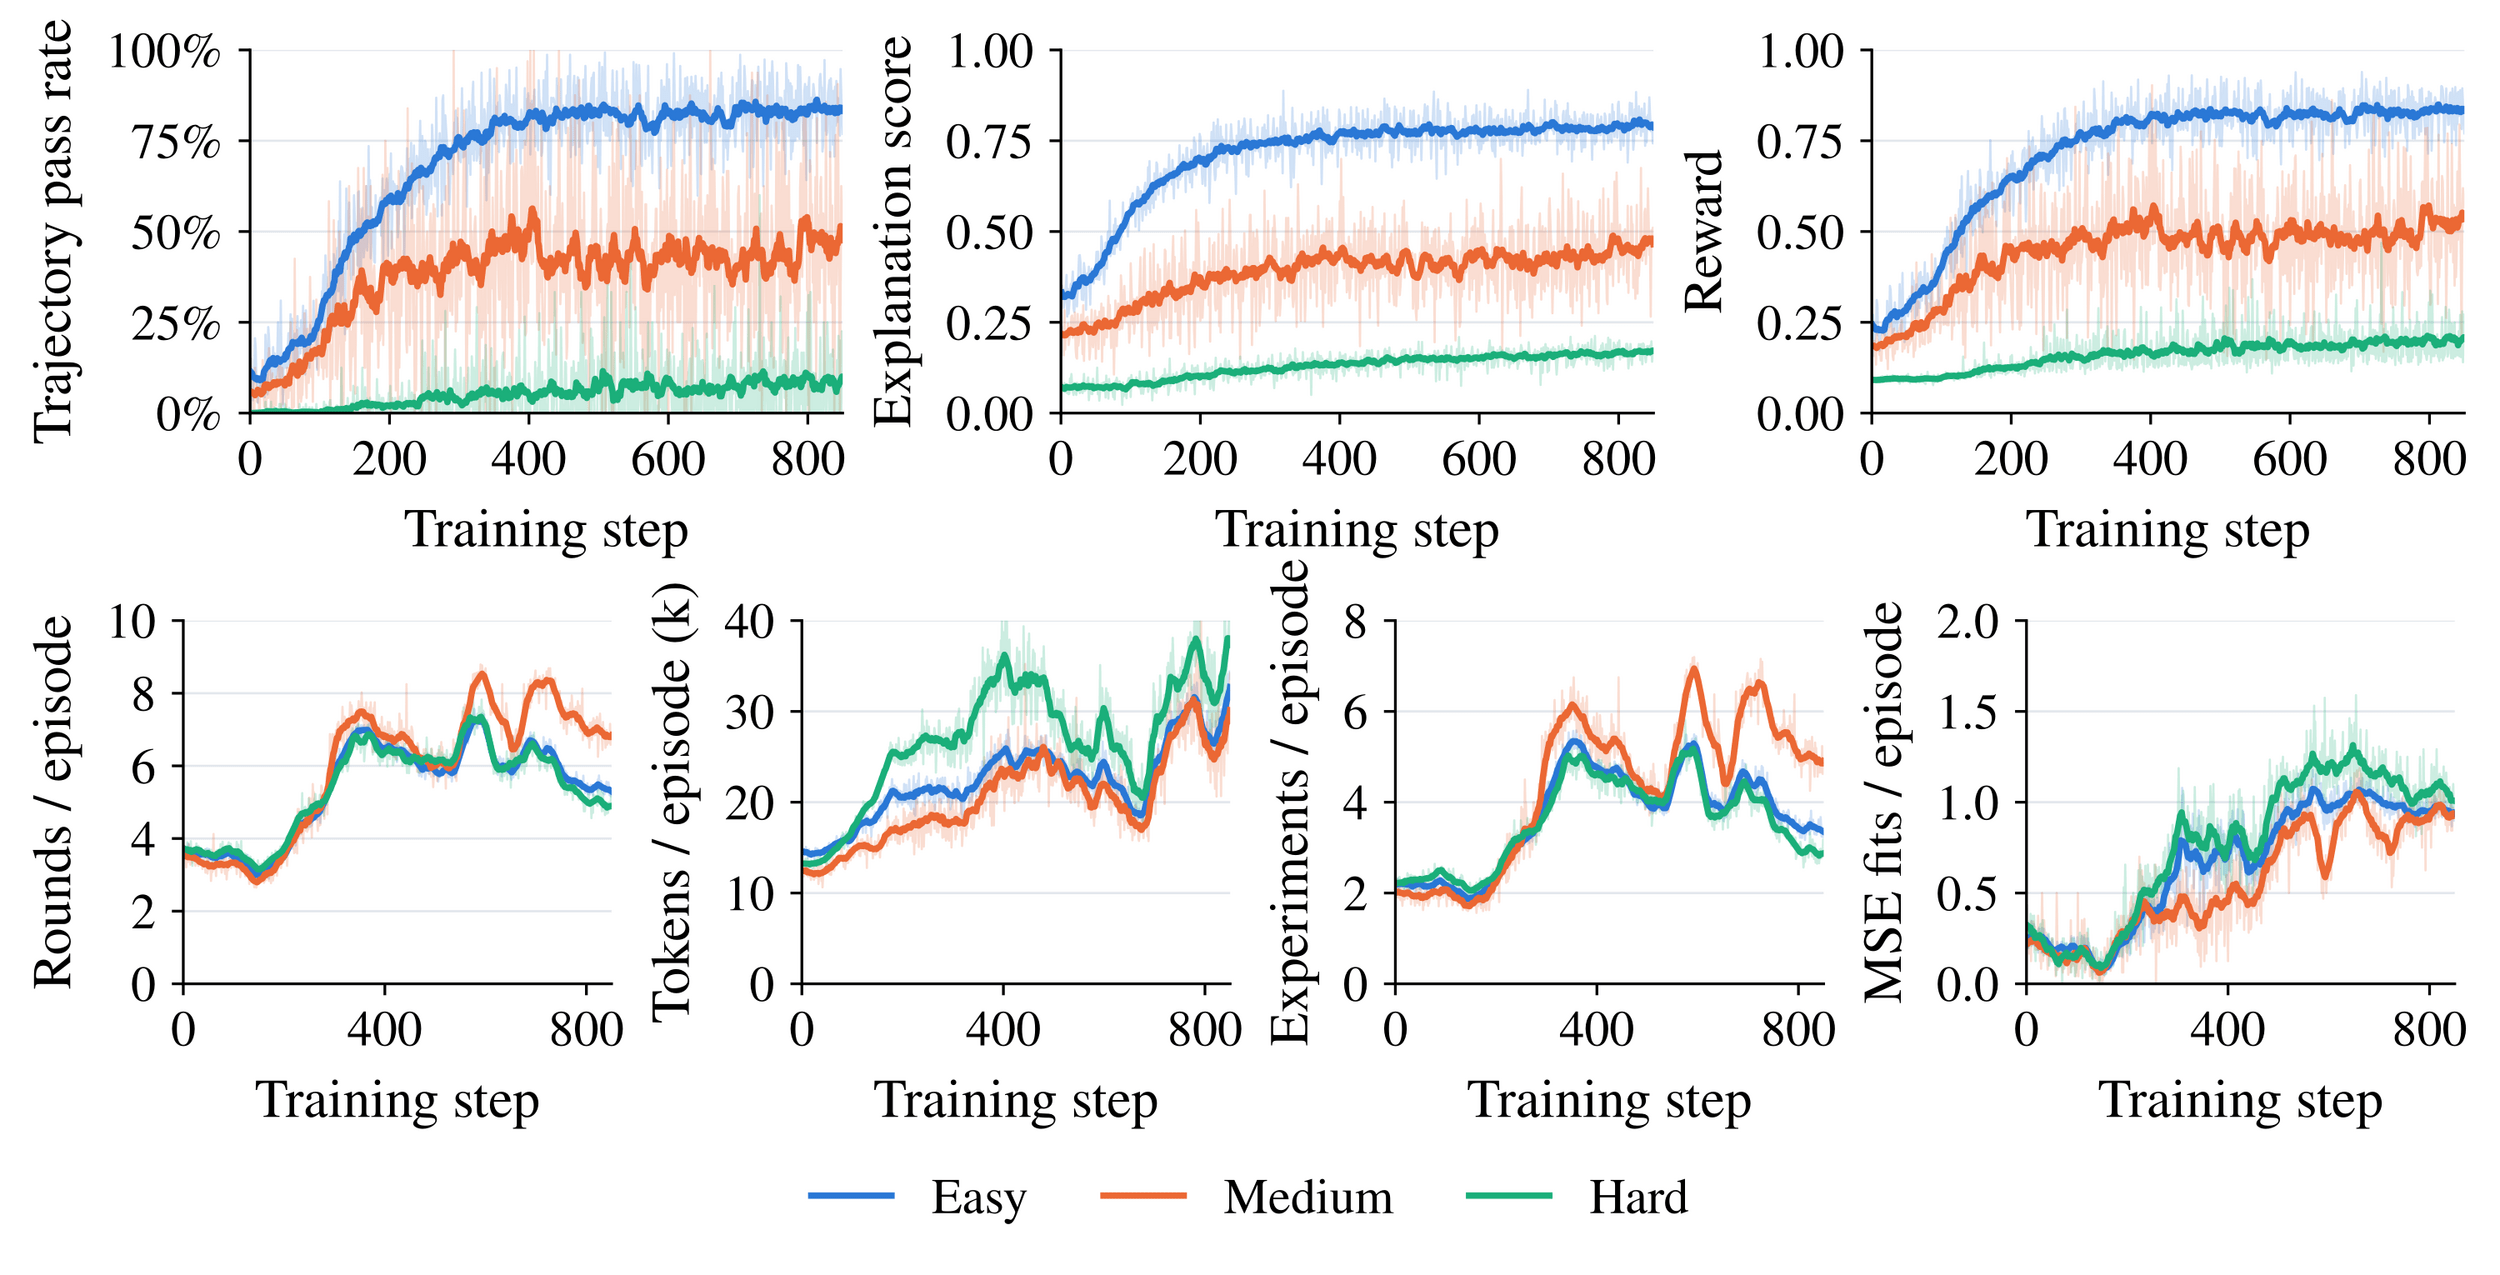
How Predictive
Conceptual Understanding
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
Conceptual Understanding
Trajectory Prediction
4B
400B
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
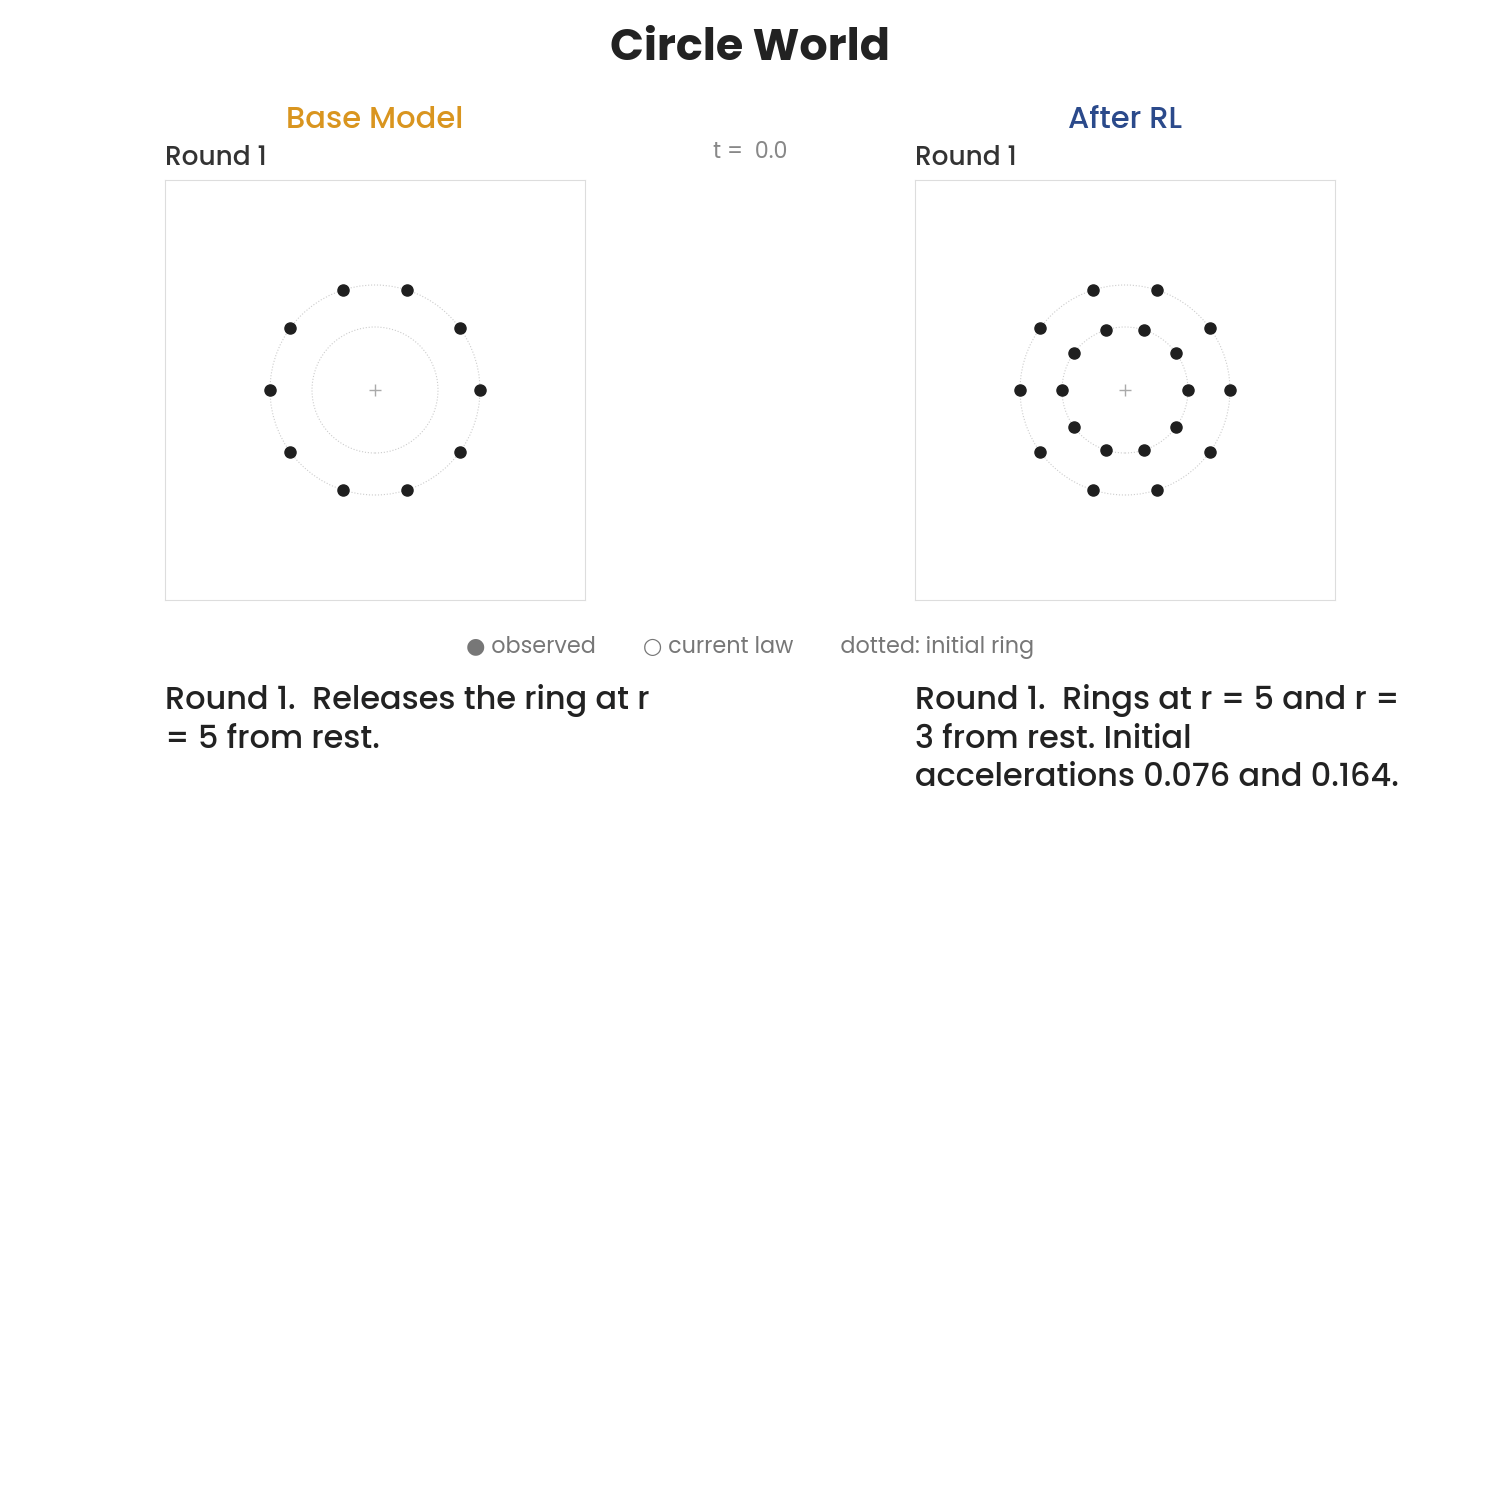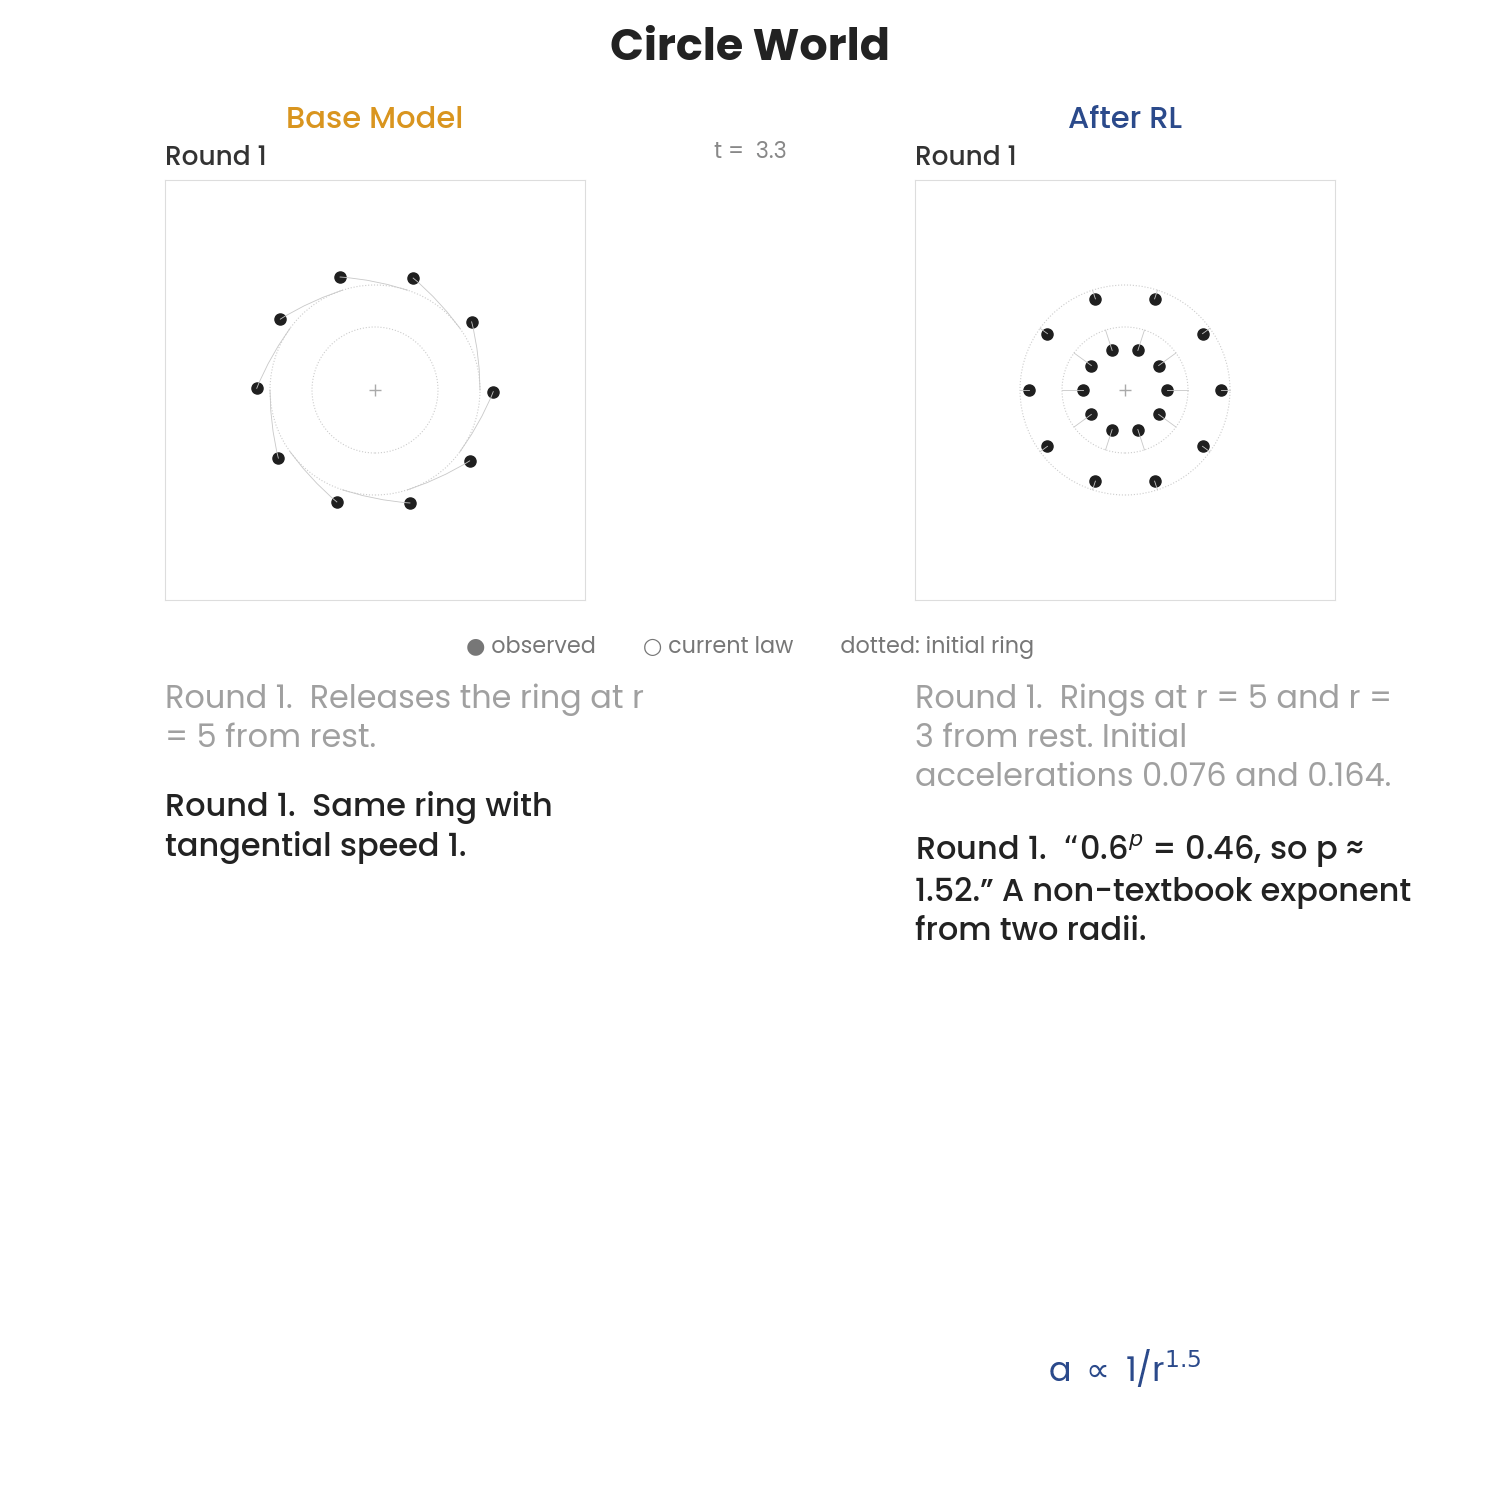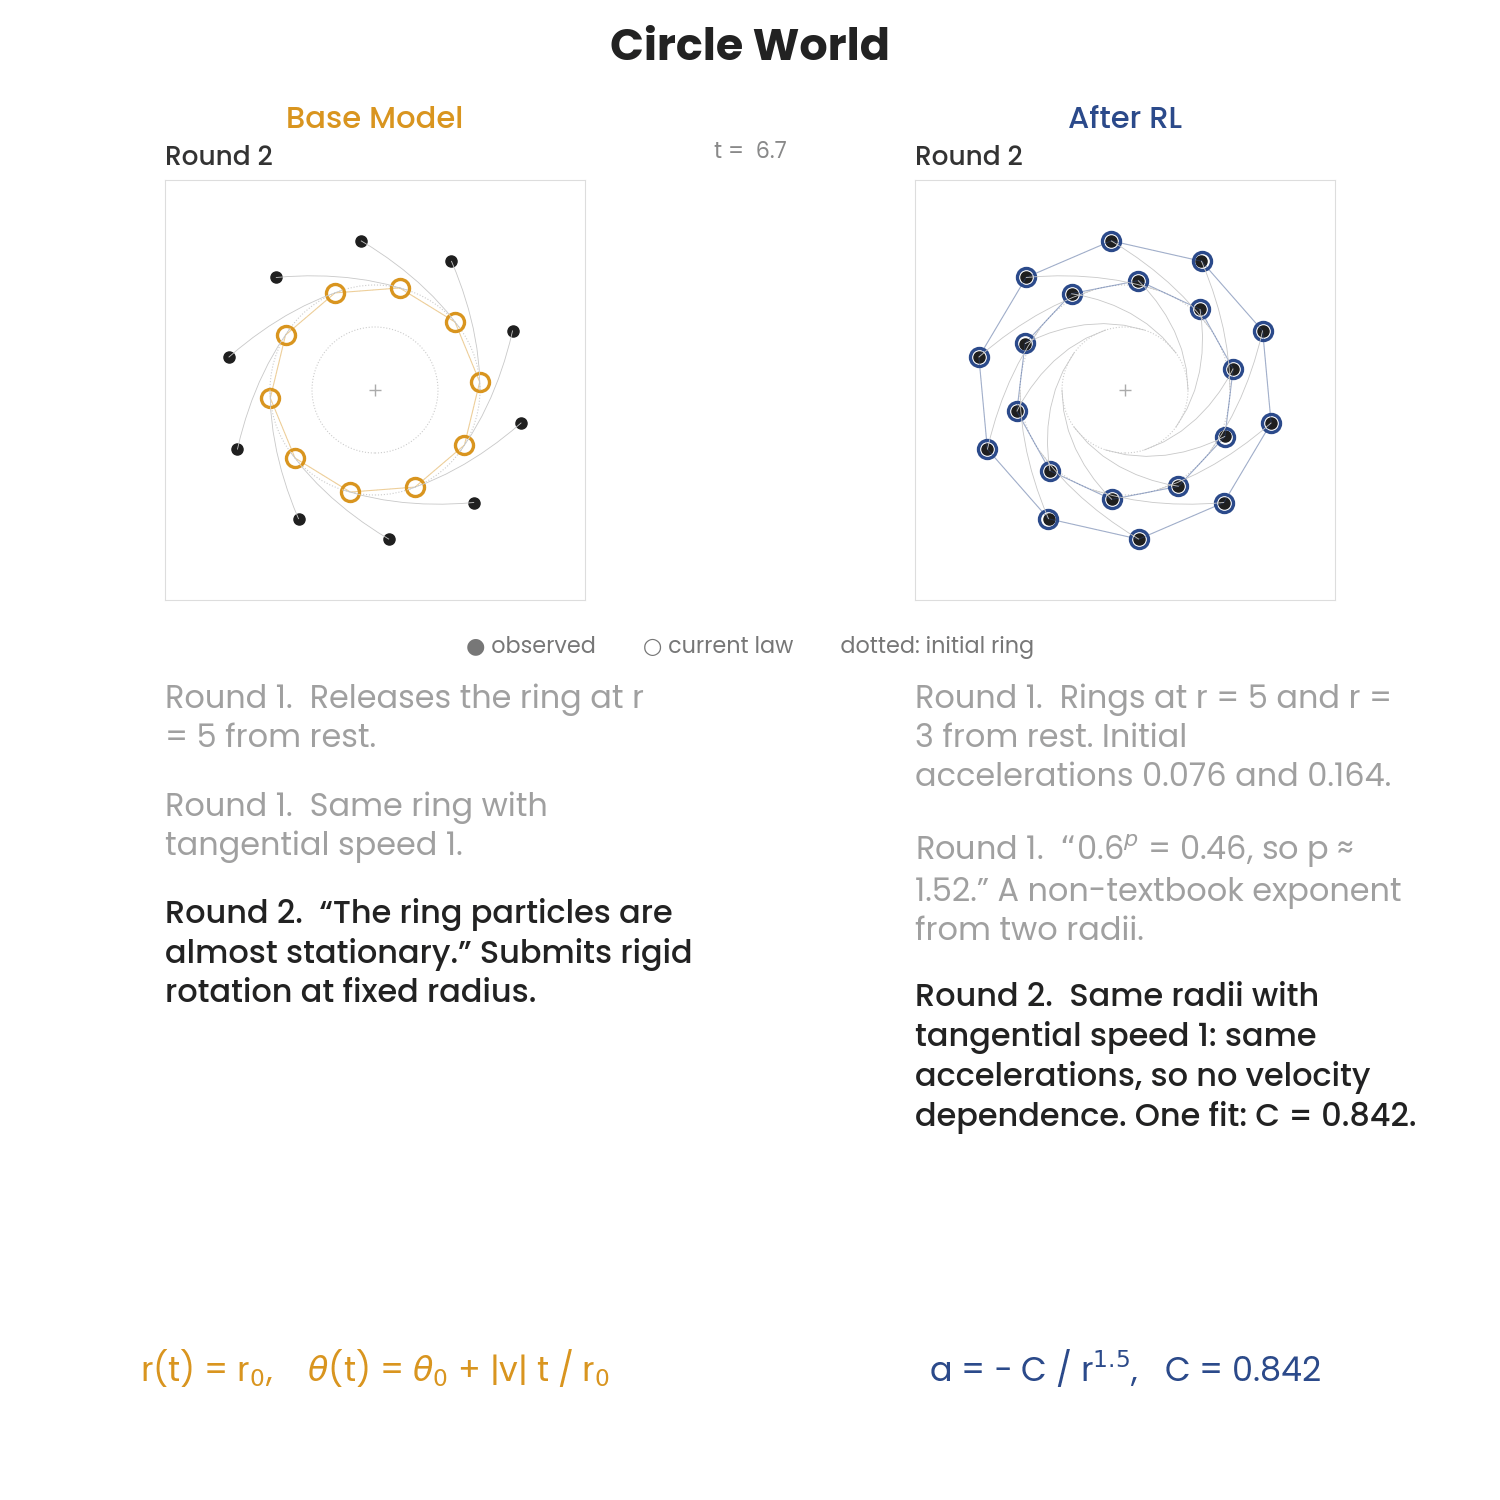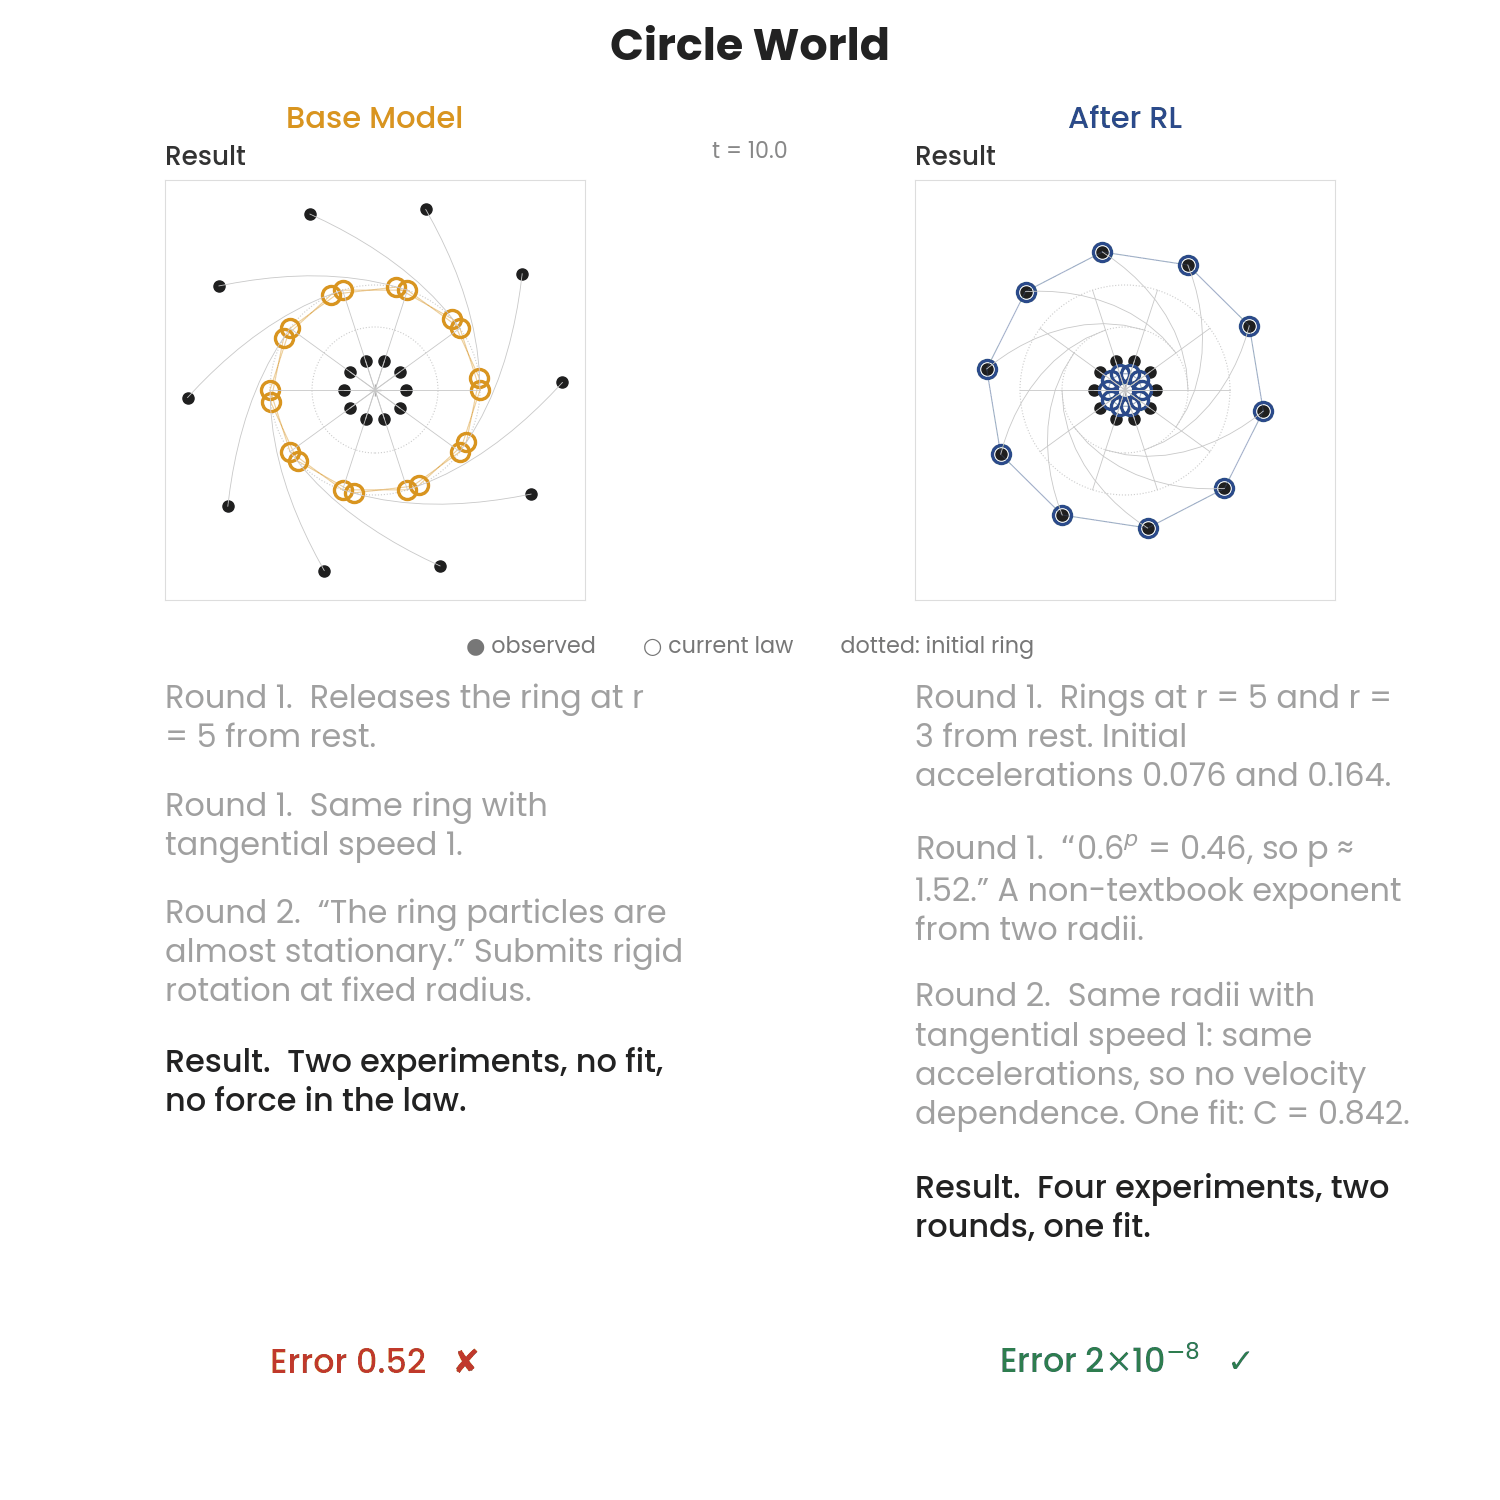
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
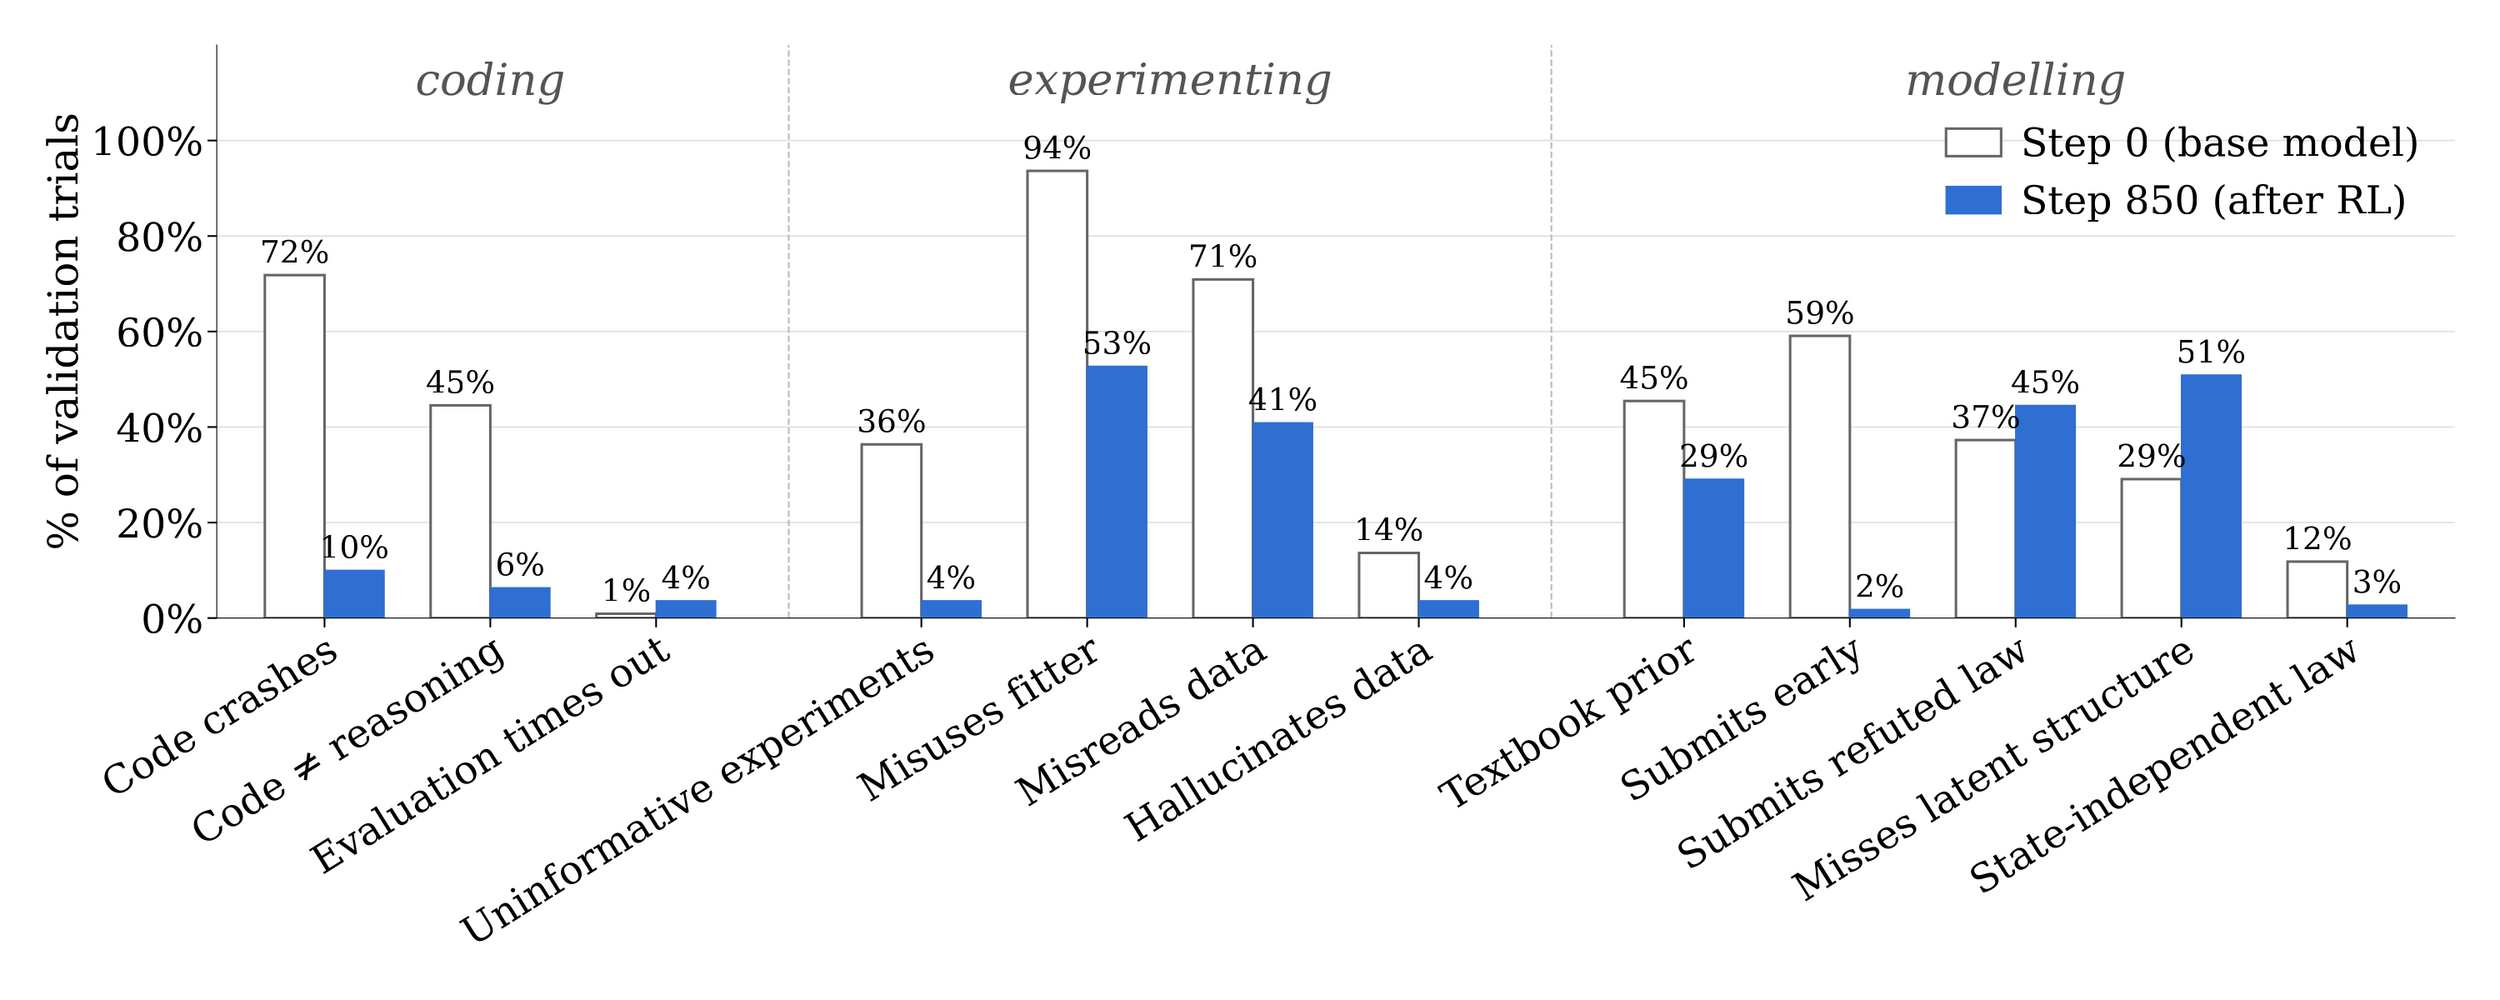
Evaluating Capabilities
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
- v2 of the benchmark: more challenging / realistic worlds. Contributions welcomed!
- RL on latest Qwen (~40B)
- How do we reward insight?
Carolina Cuesta-Lazaro Flatiron/NYU @ CCA 2026
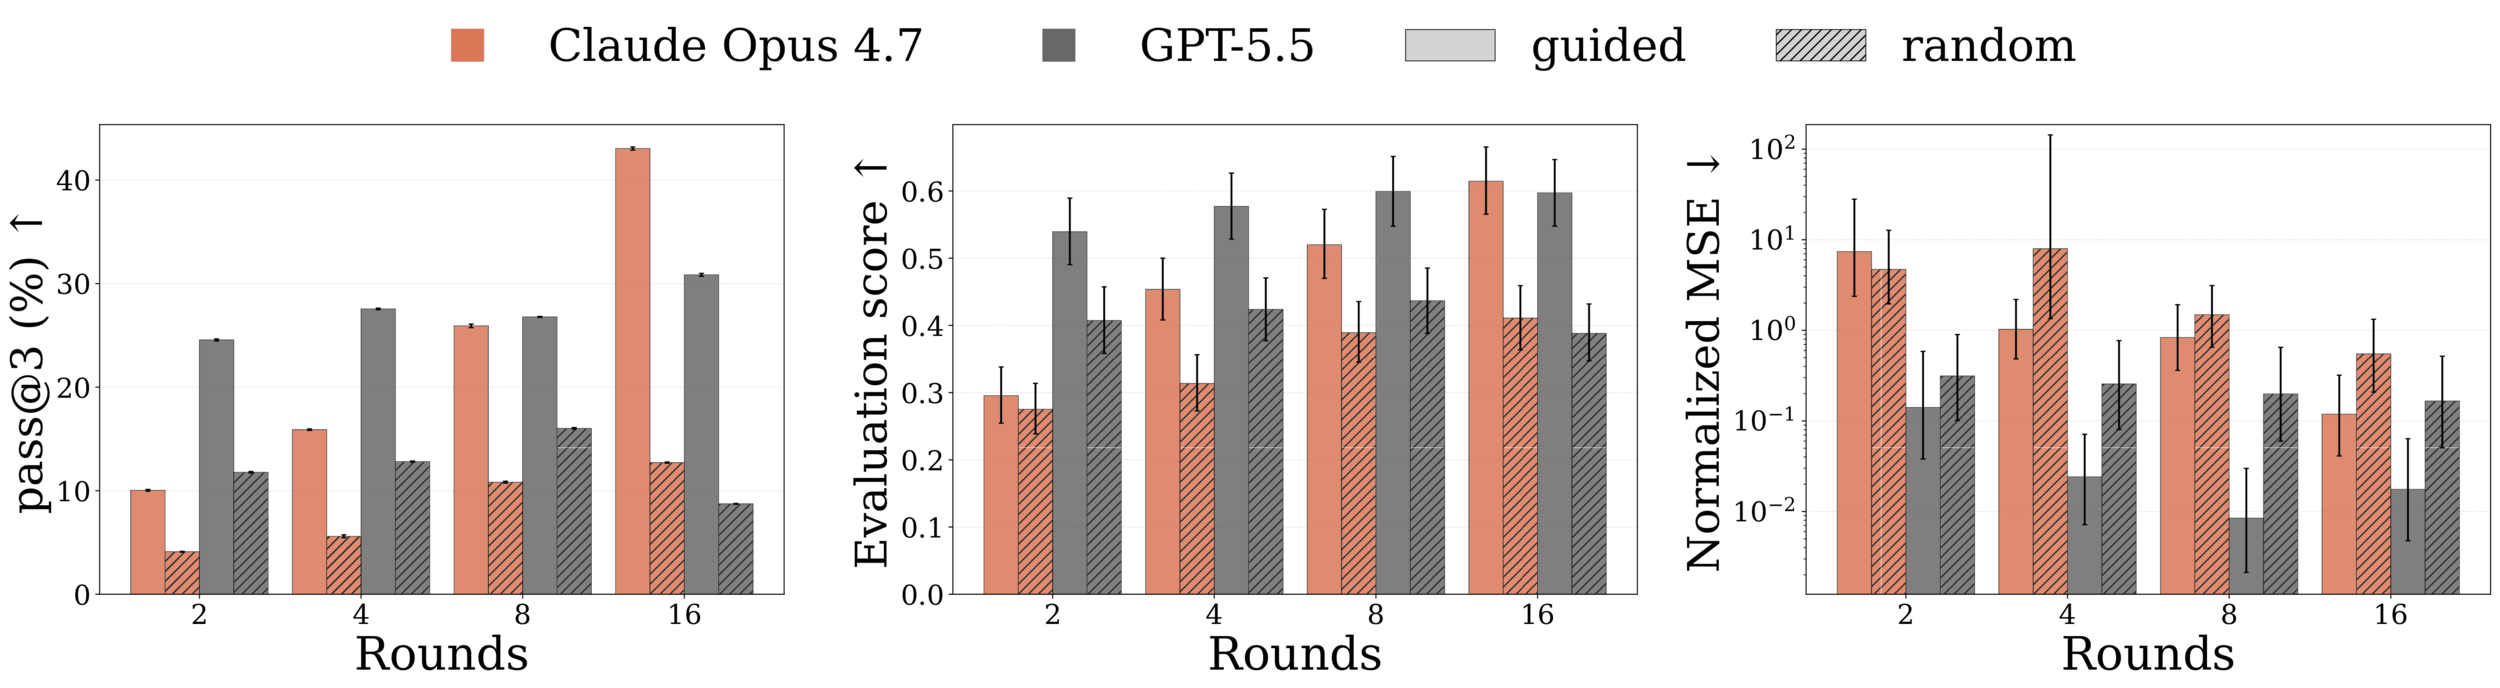
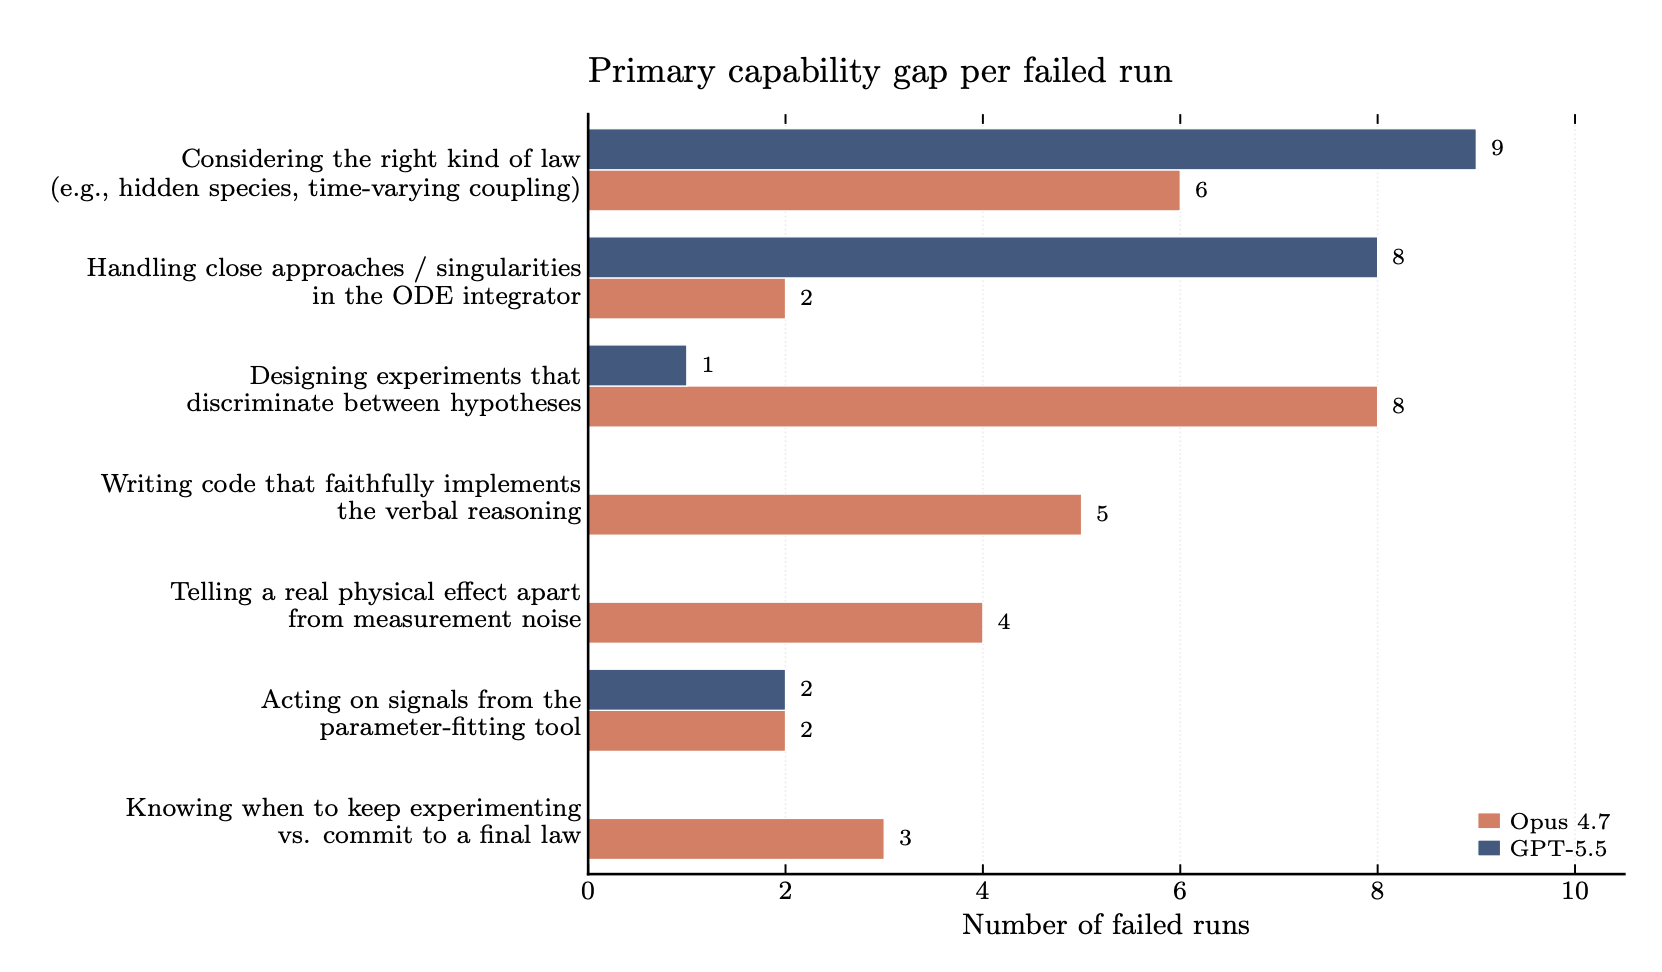
Carolina Cuesta-Lazaro Flatiron/NYU @ Columbia 2026
Carolina Cuesta-Lazaro Flatiron/NYU @ Penn 2026
p(behaviour)
p(behaviour|correct)
CCA coffee talk- 2026
By carol cuesta