ML for Scientists: L14
Carol(ina) Cuesta-Lazaro
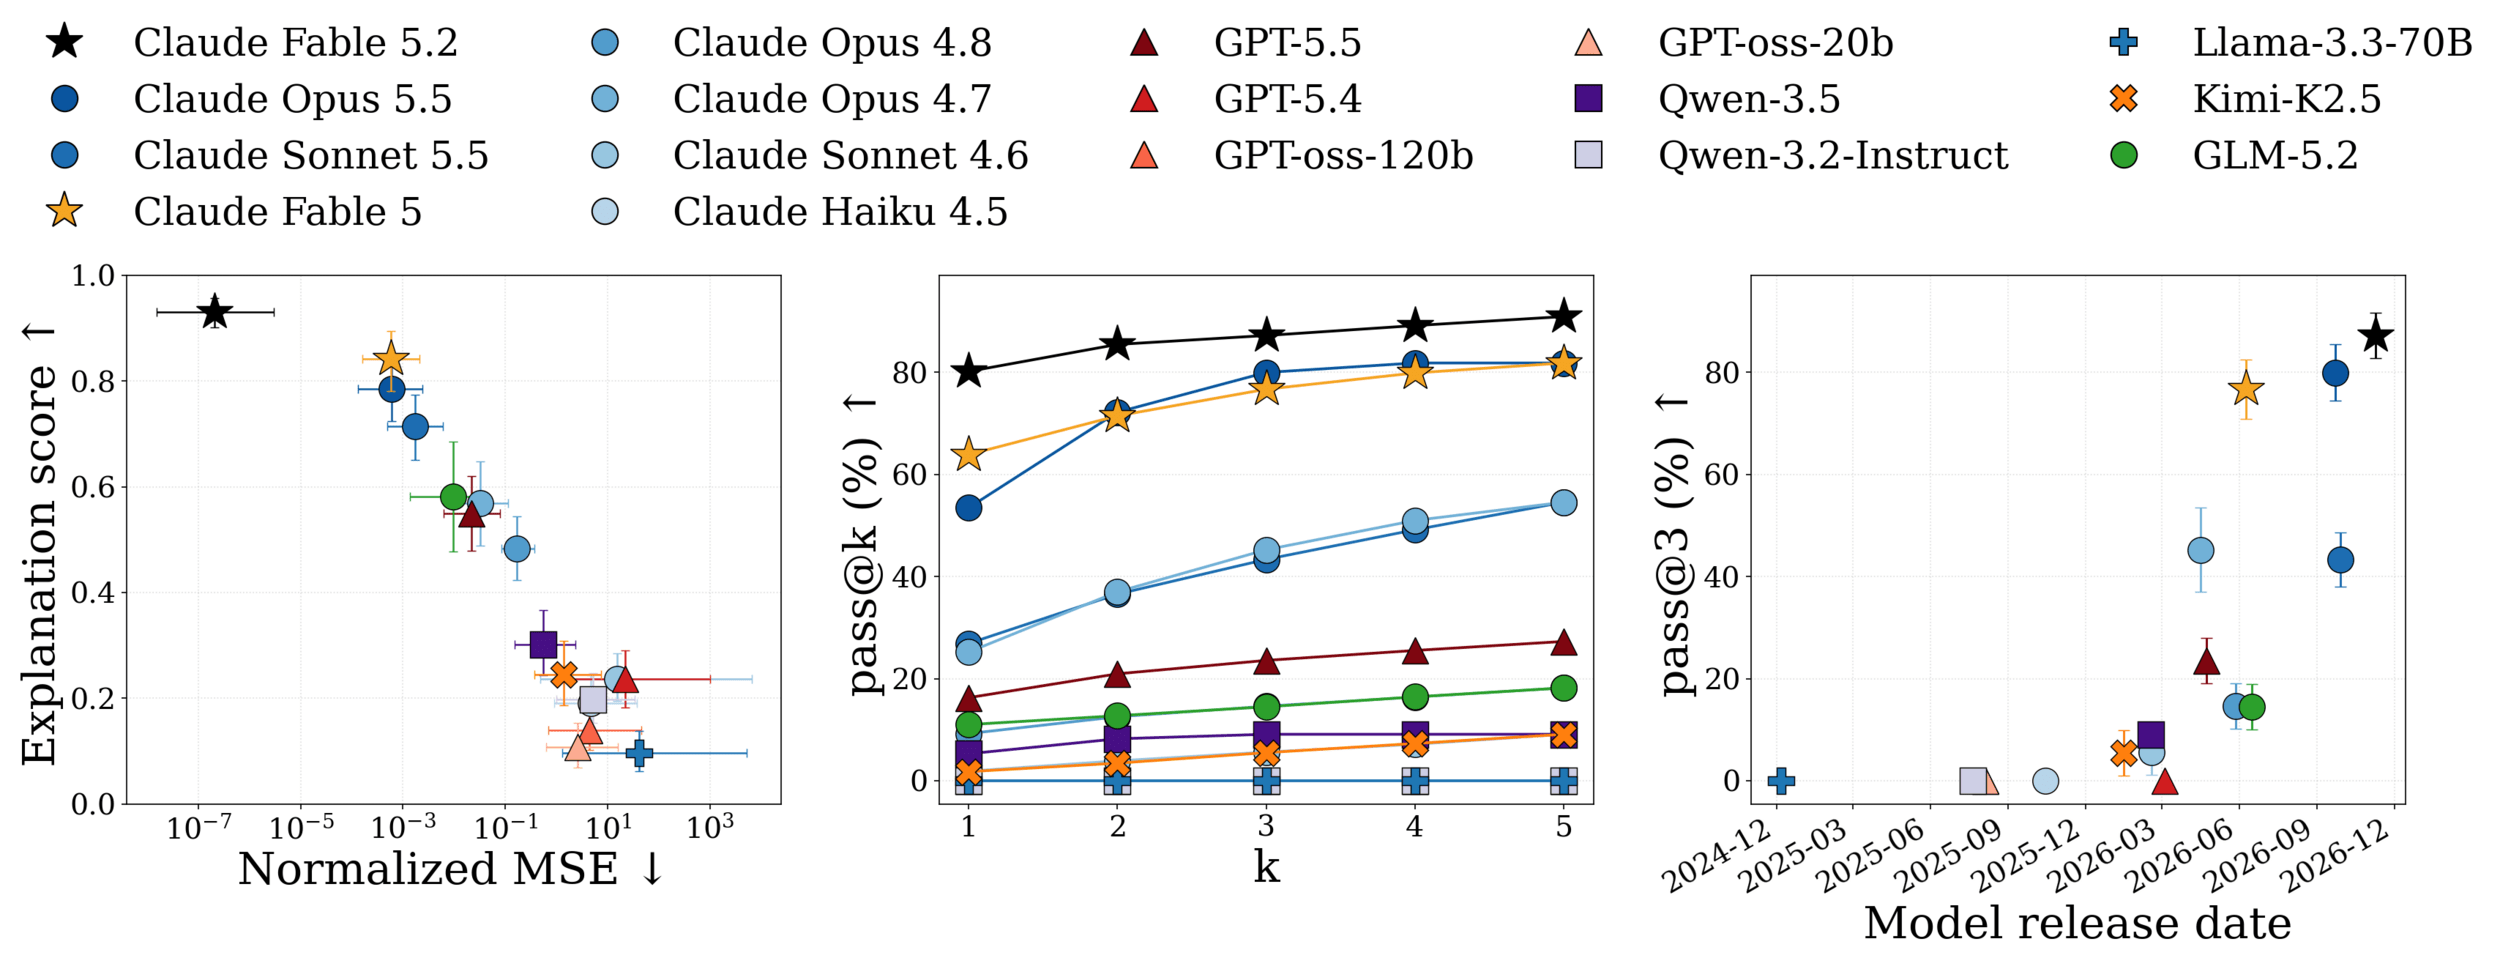
https://tinyurl.com/moneyplot
https://meet.google.com/sqh-ttyp-rqt
Do we actually need Density Estimation?
Just use binary classifiers!

x, \theta \sim p(x,\theta)
x, \theta \sim p(x)p(\theta)
y = 1
y = 0
\theta
x
Binary cross-entropy
Sample from simulator
Mix-up
Likelihood-to-evidence ratio
r(x,\theta) = \frac{p(x\mid \theta)}{p(x)}
Likelihood-to-evidence ratio
p(x,\theta|y) = p(x,\theta) \, \, \mathrm{if} \, \, y=1
p(x,\theta|y) = p(x)p(\theta) \, \, \mathrm{if} \, \, y=0
p(y=1 \mid x,\theta) = \frac{p(x,\theta|y=1)p(y)}{p(x,\theta)}
\left(p(x,\theta \mid y=0) + p(x,\theta \mid y=1) \right)p(y)
p(y=1 \mid x,\theta) = \frac{p(x,\theta)}{p(x)p(\theta) + p(x,\theta)}
= \frac{p(x,\theta)}{p(x)p(\theta)}
= \frac{r(x,\theta)}{r(x,\theta) + 1}
NLE
No implicit prior
Not amortized
Goodness-of-fit
Scaling with dimensionality of x
p(x|\theta)
NPE
p(\theta|x)
NRE
\frac{p(x|\theta)}{p(x)}
Amortized
Scales well to high dimensional x
Implicit marginalization
\mathcal{L}(\phi) \approx -\frac{1}{N} \sum_{i=1}^N \log q_\phi(\theta_i \mid x_i)
\mathcal{L}(\phi) \approx -\frac{1}{N} \sum_{i=1}^N \log q_\phi(x_i \mid \theta_i )
No need variational distribution
No implicit prior
Implicit marginalization
Approximately normalised
\begin{split}
L &= - \frac{1}{N} \sum_{i=1}^N \left[ y_i \log(p_i) \right. \\
&\left. + (1 - y_i) \log(1 - p_i) \right]
\end{split}
Not amortized
Implicit marginalization
Goodness-of-fit?
Robustness?
Fixed prior


How good is your posterior?
Test log likelihood
["Benchmarking simulation-based inference"
Lueckmann et al
arXiv:2101.04653]
\mathbb{E}_{p(x,\theta)} \log \hat{p}(\theta \mid x)
Posterior predictive checks

Observed
Re-simulated posterior samples
Classifier 2 Sample Test (C2ST)

\mathrm{R} \sim p(\theta|x)
\mathrm{F} \sim \hat{p}(\theta|x)
Real or Fake?
Benchmarking SBI
["Benchmarking simulation-based inference"
Lueckmann et al
arXiv:2101.04653]

Classifier 2 Sample Test (C2ST)
["A Trust Crisis In Simulation-Based Inference? Your Posterior Approximations Can Be Unfaithful"
Hermans et al
arXiv:2110.06581]

Much better than overconfident!
Coverage: assessing uncertainties
\int_\Theta \hat{p}(\theta \mid x = x_0) d\theta = 1 - \alpha
["A Trust Crisis In Simulation-Based Inference? Your Posterior Approximations Can Be Unfaithful"
Hermans et al
arXiv:2110.06581]
Credible region (CR)
Not unique
High Posterior Density region (HPD)
Smallest "volume"

True value in CR with
1 - \alpha
probability

\theta^*
\mathcal{H}
Empirical Coverage Probability (ECP)
\mathrm{ECP} = \mathbb{E}_{p(x,\theta)} \left[ \mathbb{1} \left[ \theta \in \mathcal{H}_{\hat{p}(\theta|x)}(1-\alpha)\right] \right]

["Investigating the Impact of Model Misspecification in Neural Simulation-based Inference"
Cannon et al arXiv:2209.01845 ]
Underconfident
Overconfident
Calibrated doesn't mean informative!
Always look at information gain too
\mathrm{ECP} = \mathbb{E}_{p(x,\theta)} \left[ \mathbb{1} \left[ \theta \in \mathcal{H}(\hat{p}, \alpha) \right] \right]
= \mathbb{E}_{p(\theta)} \left[ \mathbb{1} \left[ \theta \in \mathcal{H}(\hat{p}, \alpha) \right] \right]
\hat{p}(\theta \mid x) = p(\theta)
= \int_{\mathcal{H}(\hat{p}),\alpha} d\theta p(\theta)
\mathbb{E}_{p(x,\theta)} \left[ \log \hat{p}(\theta \mid x) - \log p(\theta) \right]
= 1 - \alpha
["A Trust Crisis In Simulation-Based Inference? Your Posterior Approximations Can Be Unfaithful"
Hermans et al
arXiv:2110.06581]

["Calibrating Neural Simulation-Based Inference with Differentiable Coverage Probability"
Falkiewicz et al
arXiv:2310.13402]
["A Trust Crisis In Simulation-Based Inference? Your Posterior Approximations Can Be Unfaithful"
Hermans et al
arXiv:2110.06581]
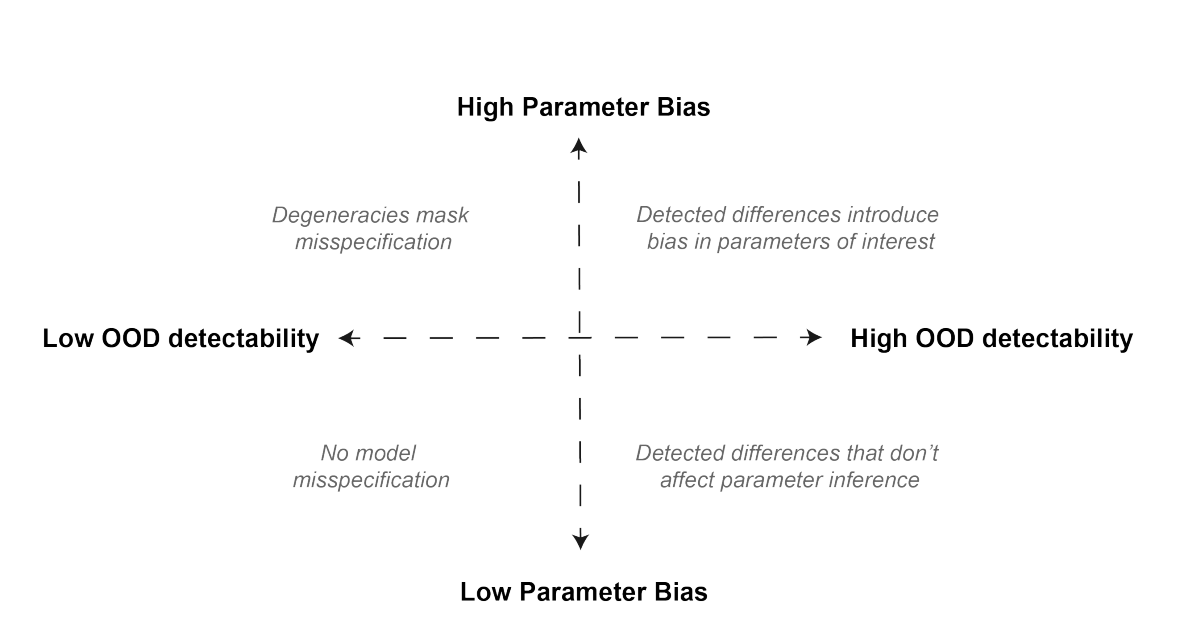
Model mispecification

["Investigating the Impact of Model Misspecification in Neural Simulation-based Inference"
Cannon et al arXiv:2209.01845]
More misspecified
Sequential SBI
["Benchmarking simulation-based inference"
Lueckmann et al
arXiv:2101.04653]

[Image credit: https://www.mackelab.org/delfi/]Sequential SBI
Real life scaling: Gravitational lensing
["A Strong Gravitational Lens Is Worth a Thousand Dark Matter Halos: Inference on Small-Scale Structure Using Sequential Methods"
Wagner-Carena et al arXiv:2404.14487]


Generative Priors: Plug and Play
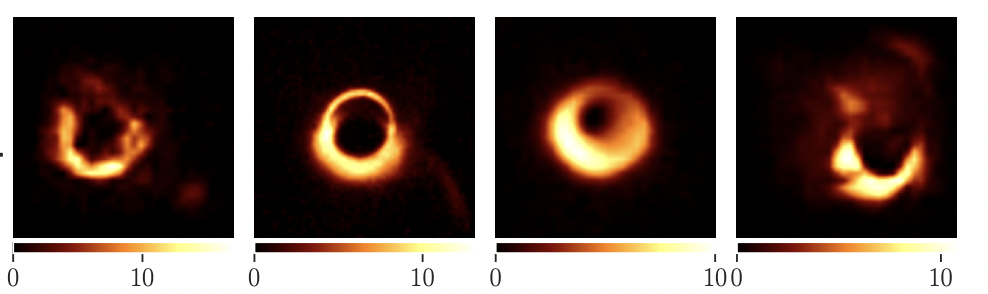
EHT posterior samples with different priors
["Event-horizon-scale Imaging of M87* under Different Assumptions via Deep Generative Image Priors" Feng et al]
CIFAR-10
GRMHD
RIAF
CelebA
(Sims)
(Sims)
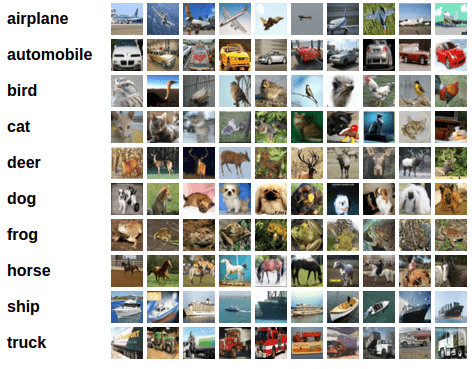
(LR Natural Images)
(Human Faces)
\log p(x|y) = \log p(y|x) + \log p(x) + \mathrm{constant}
Prior
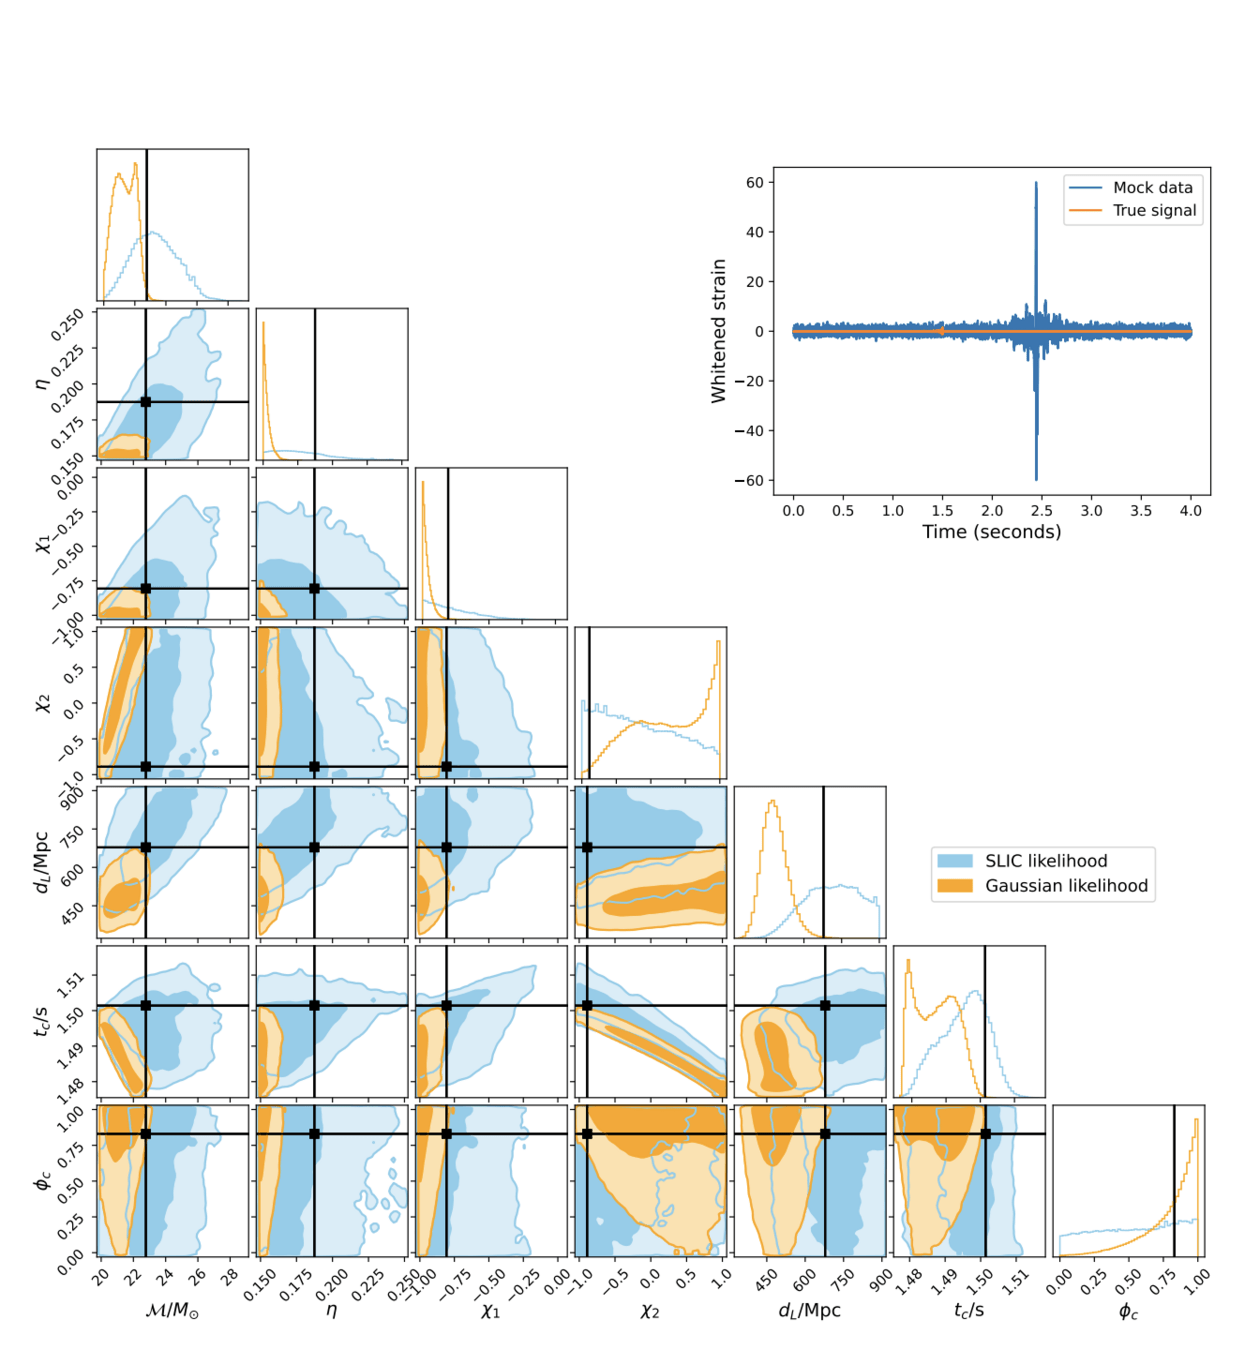
Learned Noise Models
Money plot - Nov 18th -> Discuss in class Nov 19th
ML For Scientists: L14
By carol cuesta