How Can AI Help Us Understand the Universe?
Justine Zeghal
Mila, Université de Montréal
Cosmology From Home 2026, Online
Cosmological Inference
Cosmological Inference
Goal: Get the value of the cosmological parameters
p(\theta \mid x_0)
with the uncertainty!
x_0
\Omega_c,\: \Omega_b,\:\Omega_\Lambda,\: h_0, \: n_s, \sigma_8,\: w_0
\theta
\theta
\underbrace{p(\theta|x=x_0)}_{\text{posterior}}
\underbrace{p(\theta)}_{\text{prior}}
\underbrace{p(x = x_0|\theta)}_{\text{likelihood}}
\propto
Bayes theorem:
\underbrace{p(x = x_0|\theta)}_{\text{likelihood}}
To study the nature of Dark Energy
Cosmological Inference
x_0
p(\theta \mid x_0)
\theta
Cosmological Inference
x_0
p(\theta \mid x_0)
\theta
The power spectrum is near gaussian so we have an approximation of the likelihood
\mathcal{N}(t(x_0), \sigma) \approx p(x_0\mid\theta)

t_0 :=
Cosmological Inference
The power spectrum is near gaussian so we have an approximation of the likelihood
\mathcal{N}(t(x_0), \sigma) \approx p(x_0\mid\theta)
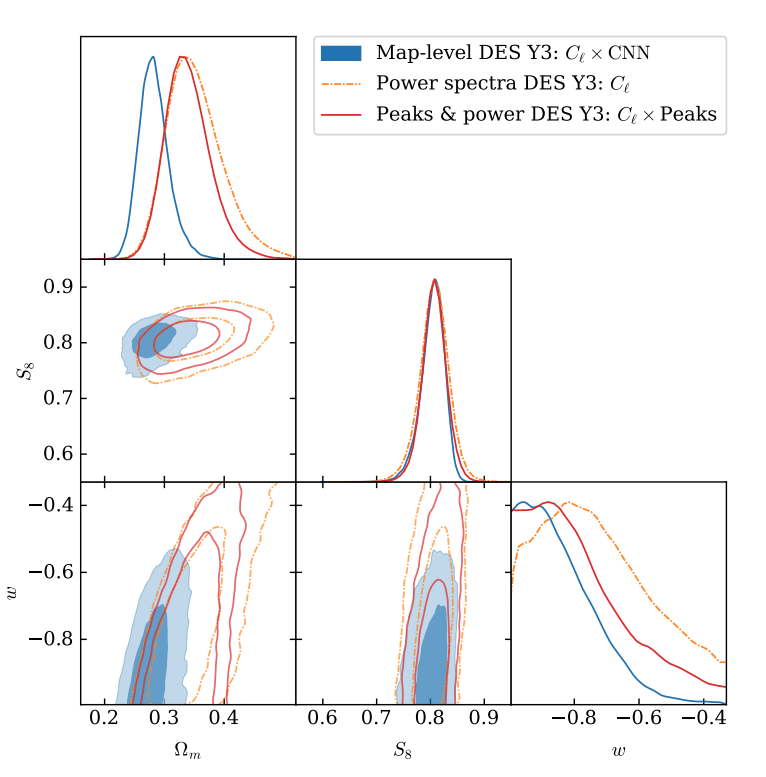
DES Y3 WL Results (with SBI).
The power spectrum is not a sufficient statistics for non gaussian field
t_0 :=
Cosmological Inference
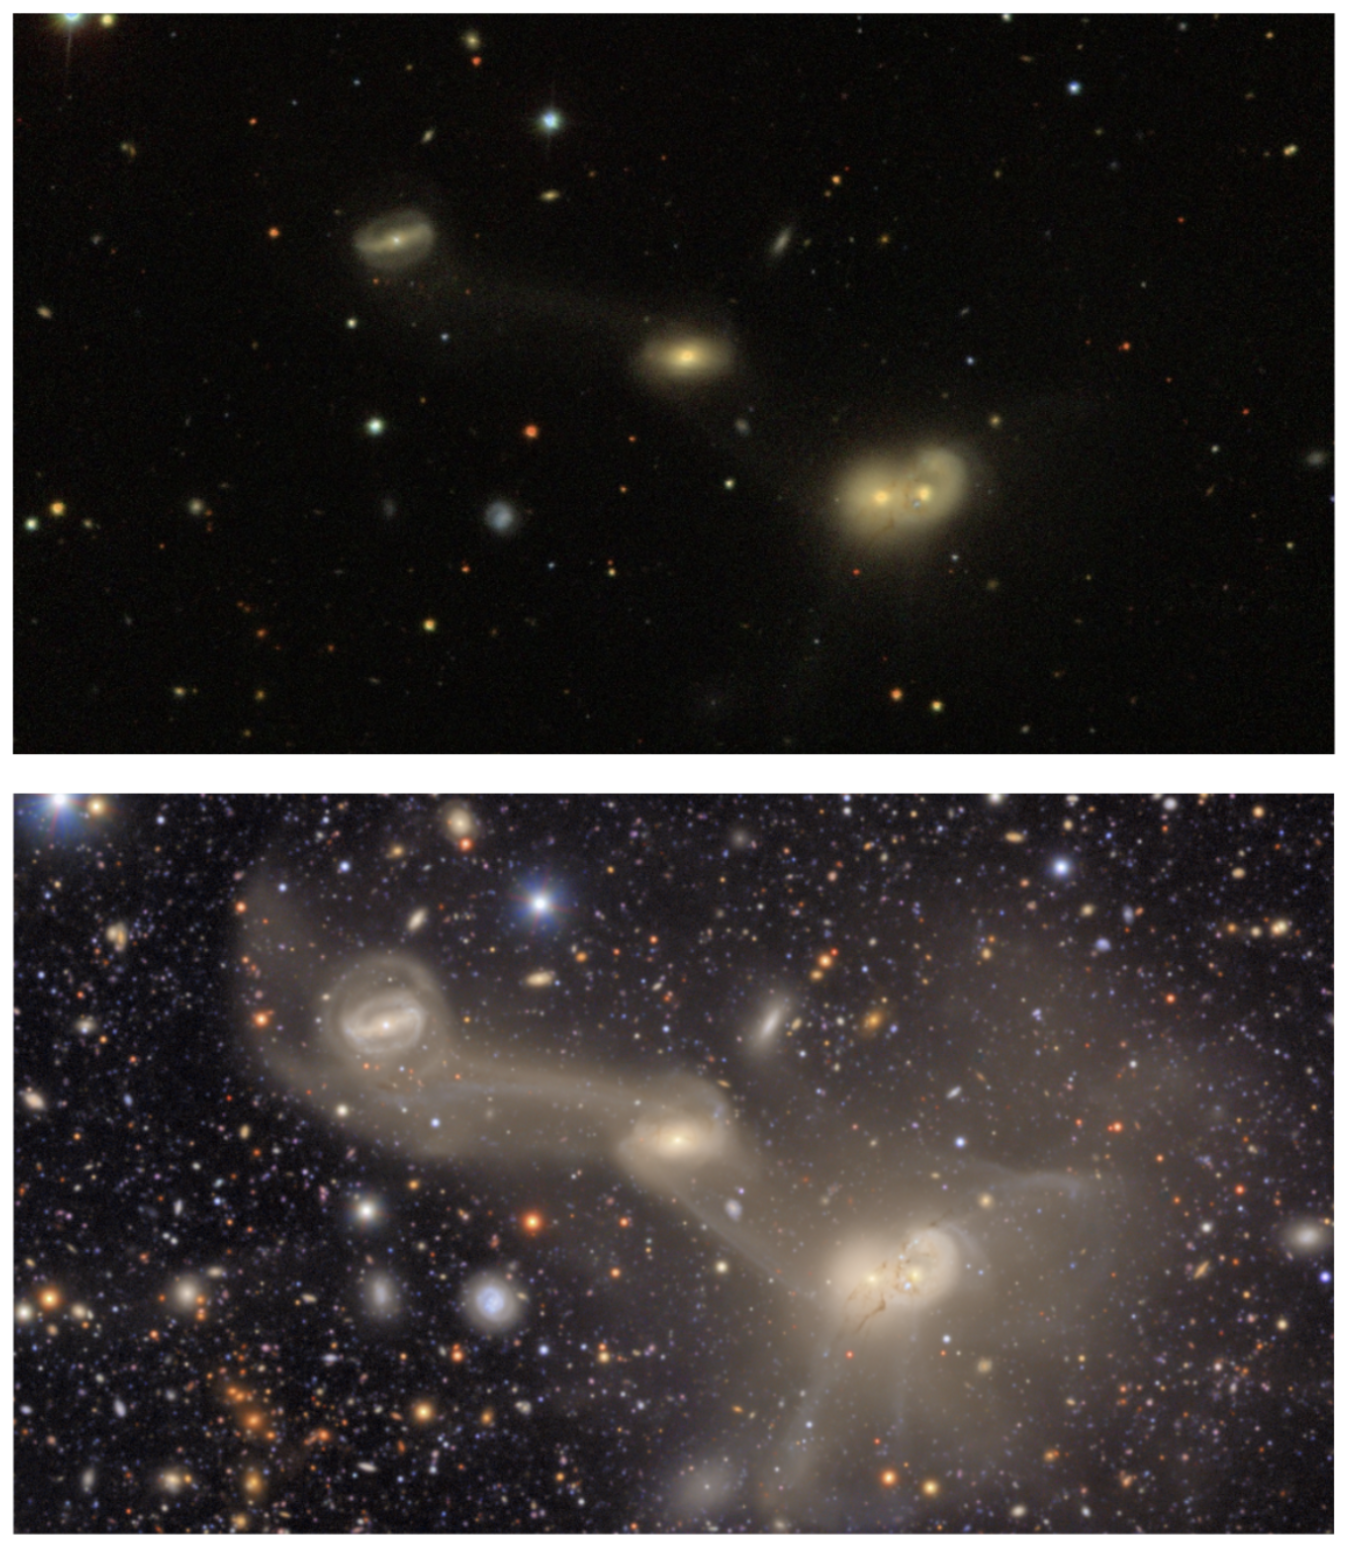
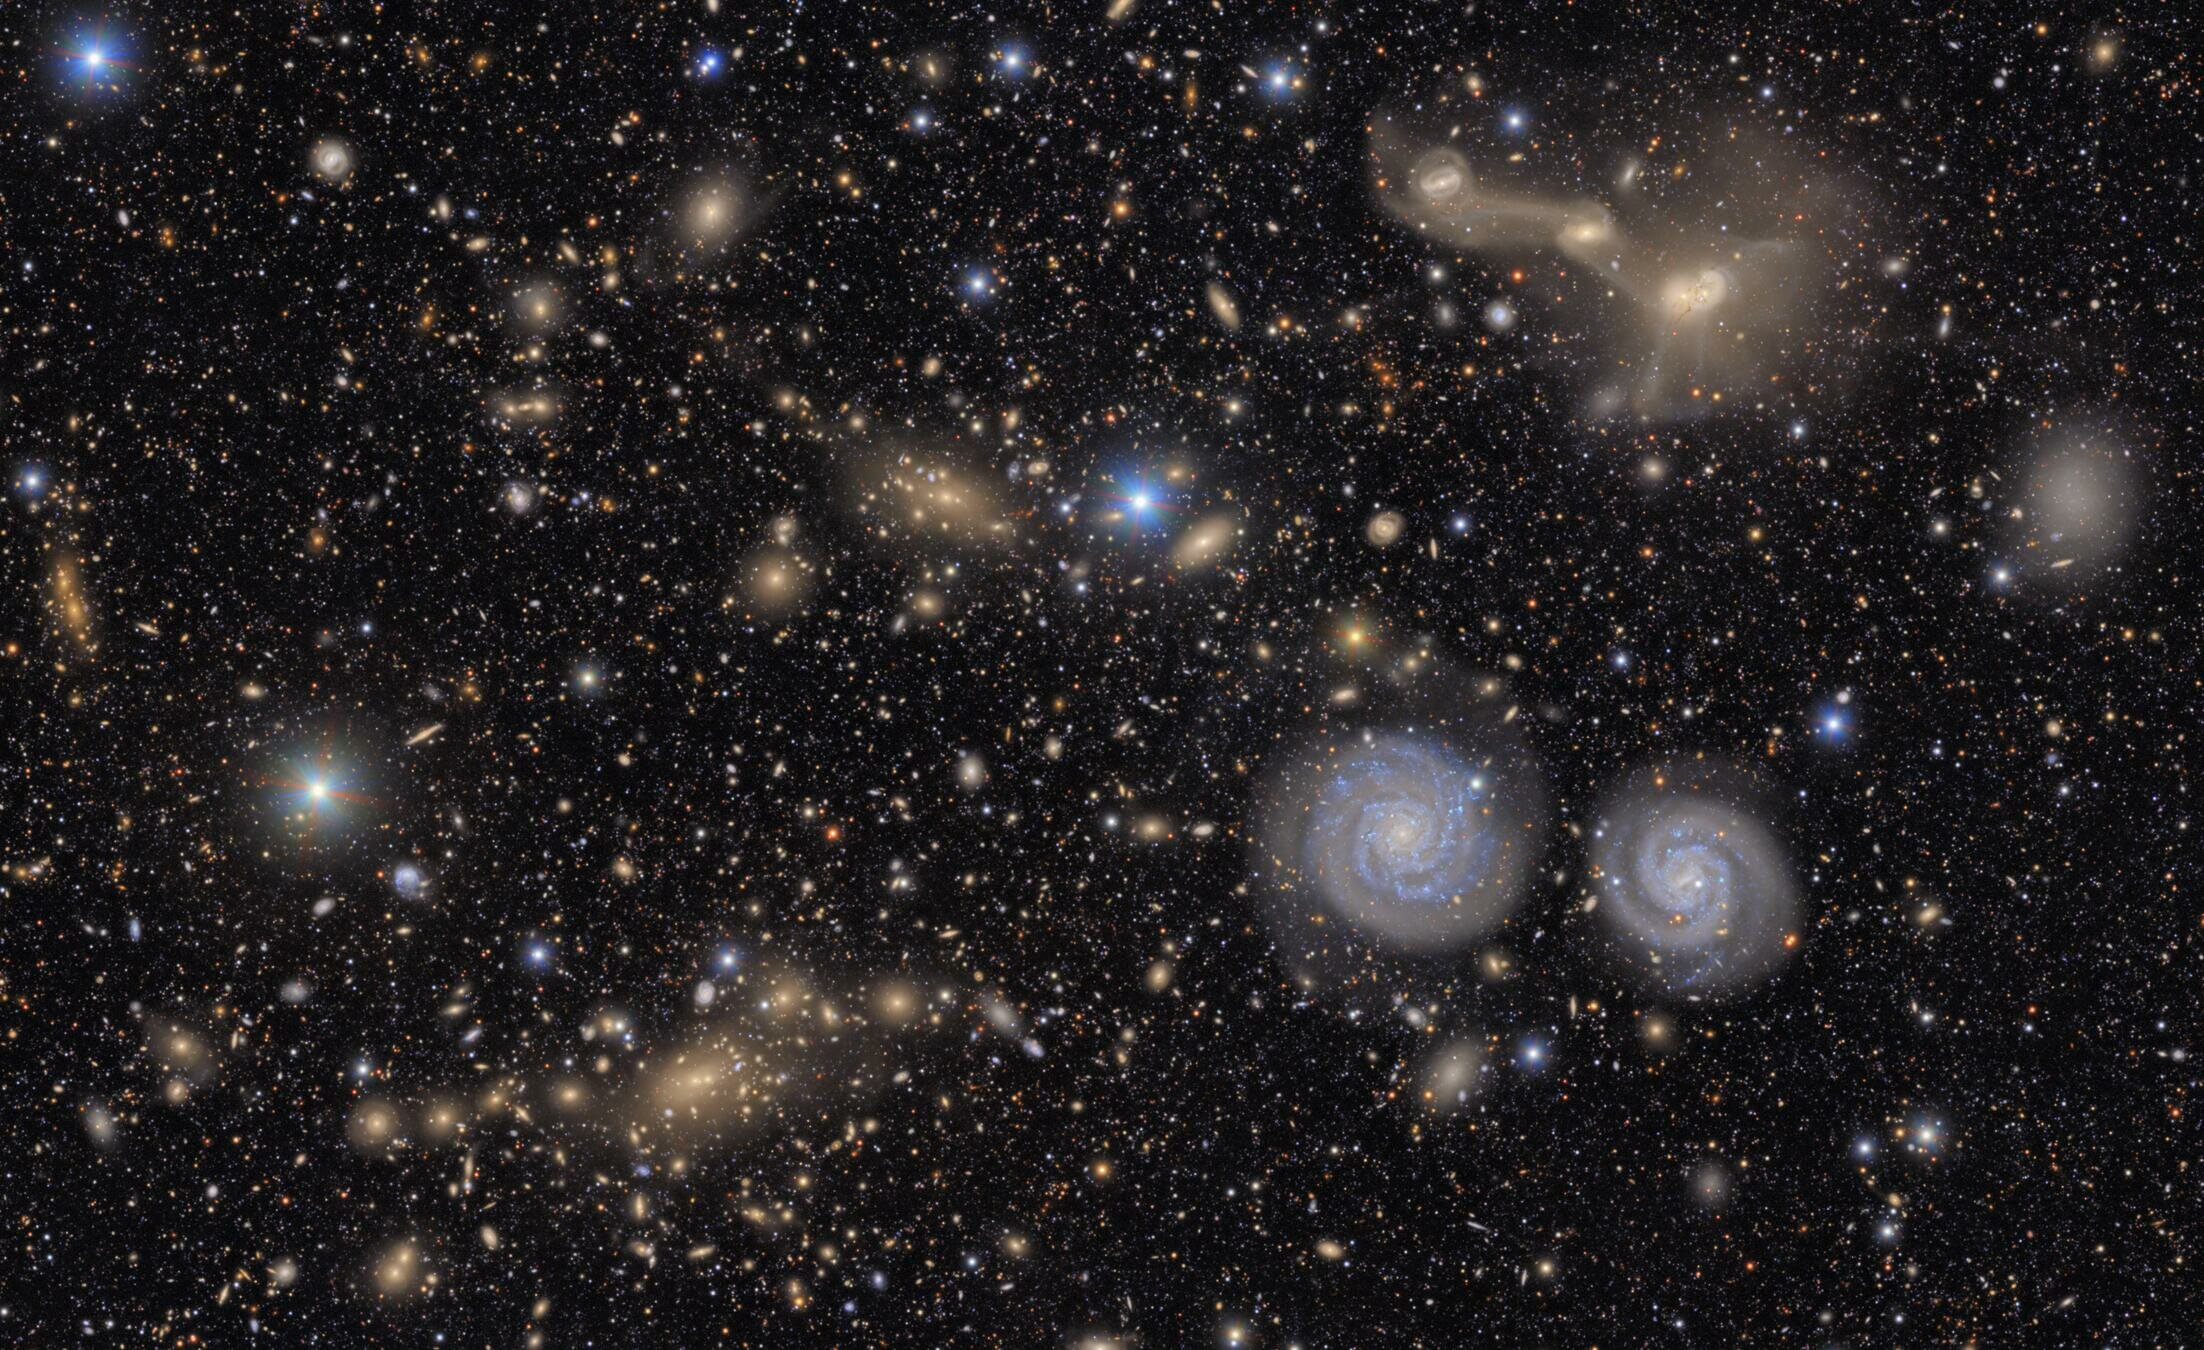
Stage III
Stage IV
Portion of the Virgo cluster, zoom on RSCG 55
Portion of the Virgo cluster, zoom on RSCG 55
Access to new non gaussian small scales. We don't want to lose this new information!
Field-Level Inference
Field-Level Inference
Field-Level Inference
\theta
x
f
z_1
z_2
Simulator
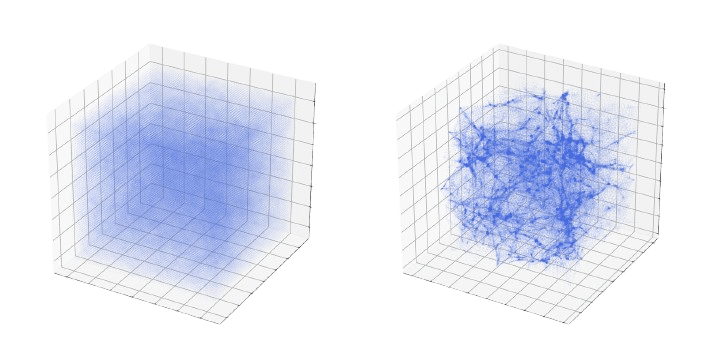
z
x
Initial conditions
Large Scale Structure
\theta
Prediction
Inference
p(x| \theta, z)
Explicit inference
p(\theta, z \: | \: x) \propto
p(z\:|\:\theta) p(\theta)
Needs an explicit simulator to sample the joint posterior through MCMC:
p(x| \theta, z)
p(\theta, z \: | \: x) \propto
Implicit inference
(\theta_i, x_i)_{i=1...N}
We use simulations to
learn
p(\theta \mid x)
Instead of relying on an analytical model to describe the phenomenon, we can simulate it.
Two ways of performing inference from simulations:
Field-Level Inference
Because we work at the map level, considering all cosmological information, we call this inference:
Field-level inference / Pixel-level inference / Full-field inference
Most precise inference!
Explicit inference
p(\theta, z \: | \: x) \propto
p(z\:|\:\theta) p(\theta)
Needs an explicit simulator to sample the joint posterior through MCMC:
p(x| \theta, z)
p(\theta, z \: | \: x) \propto
Implicit inference
(\theta_i, x_i)_{i=1...N}
We use simulations to
learn
p(\theta \mid x)
Instead of relying on an analytical model to describe the phenomenon, we can simulate it.
Two ways of performing inference from simulations:
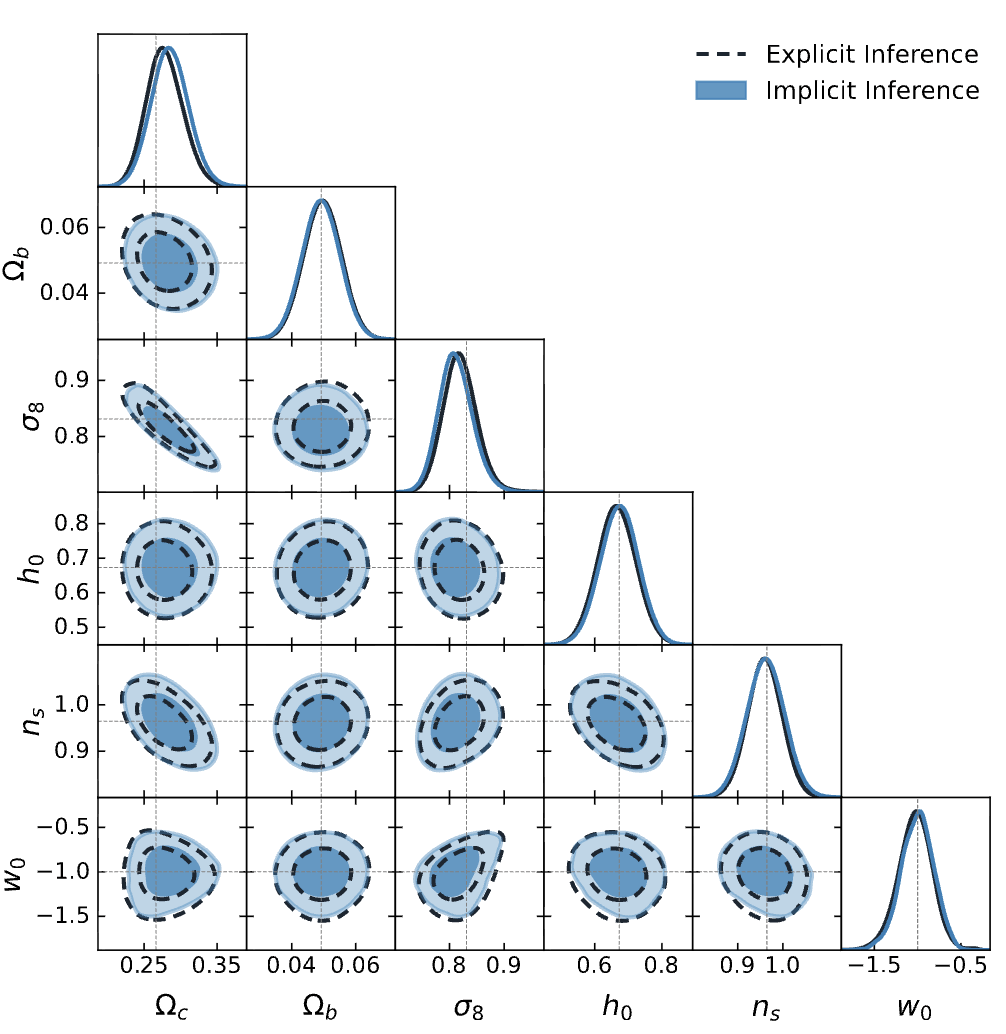
Implicit Inference
Implicit Inference
From the dataset we can learn:
(\theta_i, x_i)_{i=1...N}
p(x\mid\theta)
- the marginal likelihood
p(\theta \mid x)
- the posterior
r(x, \theta) = \frac{p(\theta \mid x)}{p(\theta)}
- the likelihood to evidence ratio
Since the goal of implicit inference is to approximate a distribution, it has greatly benefited from the advent of generative models.
Implicit Inference
Definition:
A generative model is a machine learning model designed to create new data that is similar to its training data .
x
x \sim p(x)
Different kinds of generative models:
- Generative Adversarial Networks (GANs)
- Variational Autoencoders (VAEs)
- Flow Models (Normalizing Flows, Flow Matching, Diffusion Models, Stochastic Interpolants)
- etc.
p_0
p_t
p_1
f_2
f^{-1}_2
f_1
f^{-1}_1
Implicit Inference
f_1
p_0
p_1
p_t
Implicit Inference
f_1
p_0
p_1
p_t
Implicit Inference
f_1
f_2
p_0
p_1
p_t
Implicit Inference
f_1
f_2
f^{-1}_2
p_0
p_1
p_t
Implicit Inference
f_1
f_2
f^{-1}_2
f^{-1}_1
p_0
p_1
p_t
Implicit Inference
f_1
f_2
f^{-1}_2
f^{-1}_1
p_0
p_1
p_t
Implicit Inference
f_1
f_2
f^{-1}_2
f^{-1}_1
p_0
p_1
p_t
\log p_0(f^{-1}(x))
+ \log
\displaystyle\left\lvert det \frac{\partial f^{-1}(x)}{\partial x}\right\rvert
Change of Variable Formula:
\log p_1(x)
=
f^{-1} = f_1^{-1} \circ ... \circ f_{k-1}^{-1} \circ f_k^{-1}
Should be easy to compute
Where is the NN?
Implicit Inference
Where is the NN?
For instance, for affine transformation (RealNVP, Dinh et al. 2017):
\begin{array}{ll}
x_{1:d} &= z_{1:d}\\
x_{d+1:D} &= z_{d+1:D} \odot \exp (s(z_{1:d})) + t(z_{1:d})
\end{array}
\\
NN
It is such a specific function.. Why?
Easy to inverse
Easy to compute the determinant of the Jacobian
\frac{\partial f^{-1}(x)}{\partial x} =
\begin{bmatrix}
\mathbb{I} & 0 \\
\frac{\partial g^{-1}(x_{1:d}, x_{d+1:D})}{\partial x^{1:d}} & \frac{\partial g^{-1}(x_{1:d},x_{d+1:D})}{\partial x_{d+1:D}}
\end{bmatrix}
=g(x_{1:d}, x_{d+1:D})
= \frac{\partial g^{-1}(x_{1:d},x_{d+1:D})}{\partial x_{d+1:D}} = \text{diag }(\exp(s(x_{1:d})))
Implicit Inference
Credit: François Lanusse
We need a tool to compare distributions:
the Kullback-Leiber Divergence
How to train the NNs?
Implicit Inference
\begin{array}{ll}
D_{KL}(\color{#479af7}{p_x(x)}\color{black}{||}\color{#479af7}{p_x^{\phi}(x)}\color{black}{)} &= \mathbb{E}_{p_x(x)}\Big[ \log\left(\frac{p_x(x)}{p_x^{\phi}(x)}\right) \Big] \\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
Implicit Inference
\begin{array}{ll}
D_{KL}(\color{#479af7}{p_x(x)}\color{black}{||}\color{#479af7}{p_x^{\phi}(x)}\color{black}{)} &= \mathbb{E}_{p_x(x)}\Big[ \log\left(\frac{p_x(x)}{p_x^{\phi}(x)}\right) \Big] \\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\phi
We want to minimize the Kullback-Leiber Divergence wrt
Implicit Inference
\begin{array}{ll}
D_{KL}(\color{#479af7}{p_x(x)}\color{black}{||}\color{#479af7}{p_x^{\phi}(x)}\color{black}{)} &= \mathbb{E}_{p_x(x)}\Big[ \log\left(\frac{p_x(x)}{p_x^{\phi}(x)}\right) \Big] \\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\phi
We want to minimize the Kullback-Leiber Divergence wrt
Implicit Inference
\begin{array}{ll}
D_{KL}(\color{#479af7}{p_x(x)}\color{black}{||}\color{#479af7}{p_x^{\phi}(x)}\color{black}{)} &= \mathbb{E}_{p_x(x)}\Big[ \log\left(\frac{p_x(x)}{p_x^{\phi}(x)}\right) \Big] \\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
= \text{constant}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\phi
We want to minimize the Kullback-Leiber Divergence wrt
Implicit Inference
\begin{array}{ll}
D_{KL}(\color{#479af7}{p_x(x)}\color{black}{||}\color{#479af7}{p_x^{\phi}(x)}\color{black}{)} &= \mathbb{E}_{p_x(x)}\Big[ \log\left(\frac{p_x(x)}{p_x^{\phi}(x)}\right) \Big] \\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
= \mathbb{E}_{p_x(x)}\left[ \log\left(p_x(x)\right) \right]
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
- \mathbb{E}_{p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
= \text{constant}
Simulations only!
Change of variable formula
\begin{array}{ll}
\implies Loss = - \mathbb{E}_{x \sim p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
\implies Loss = - \mathbb{E}_{x \sim p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\phi
We want to minimize the Kullback-Leiber Divergence wrt
Implicit Inference
\begin{array}{ll}
\implies Loss = - \mathbb{E}_{x \sim p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
\implies Loss = - \mathbb{E}_{x \sim p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
\implies Loss = - \mathbb{E}_{x \sim p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
Implicit Inference
\begin{array}{ll}
Loss = - \mathbb{E}_{x, \theta \sim p(x, \theta)}\left[ \log\left(p^{\phi}(x \mid \theta)\right) \right]\\
\end{array}
\begin{array}{ll}
\implies Loss = - \mathbb{E}_{x \sim p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
\implies Loss = - \mathbb{E}_{x \sim p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
\begin{array}{ll}
\implies Loss = - \mathbb{E}_{x \sim p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
Likelihood approximation (e.g. Papamakarios et al., 2019)
\begin{array}{ll}
\implies Loss = - \mathbb{E}_{x \sim p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
Implicit Inference
\begin{array}{ll}
Loss = - \mathbb{E}_{x, \theta \sim p(x, \theta)}\left[ \log\left(p^{\phi}(x \mid \theta)\right) \right]\\
\end{array}
Likelihood approximation (e.g. Papamakarios et al., 2019)
\begin{array}{ll}
Loss = - \mathbb{E}_{x, \theta \sim p(x, \theta)}\left[ \log\left(p^{\phi}(\theta \mid x)\right) \right]\\
\end{array}
Posterior approximation (e.g. Papamakarios et al., 2016)
\begin{array}{ll}
\implies Loss = - \mathbb{E}_{x \sim p_x(x)}\left[ \log\left(p_x^{\phi}(x)\right) \right]\\
\end{array}
Implicit Inference
Implicit Inference
https://simulation-based-inference.org/by Kyle Cranmer and Jason Lo
Implicit Inference
E.g. of results on Data
Reminder: Implicit Inference enables approximating the posterior when the likelihood is unknown but implicitly encoded in simulations.
Summary statistics are not always Gaussian distributed.
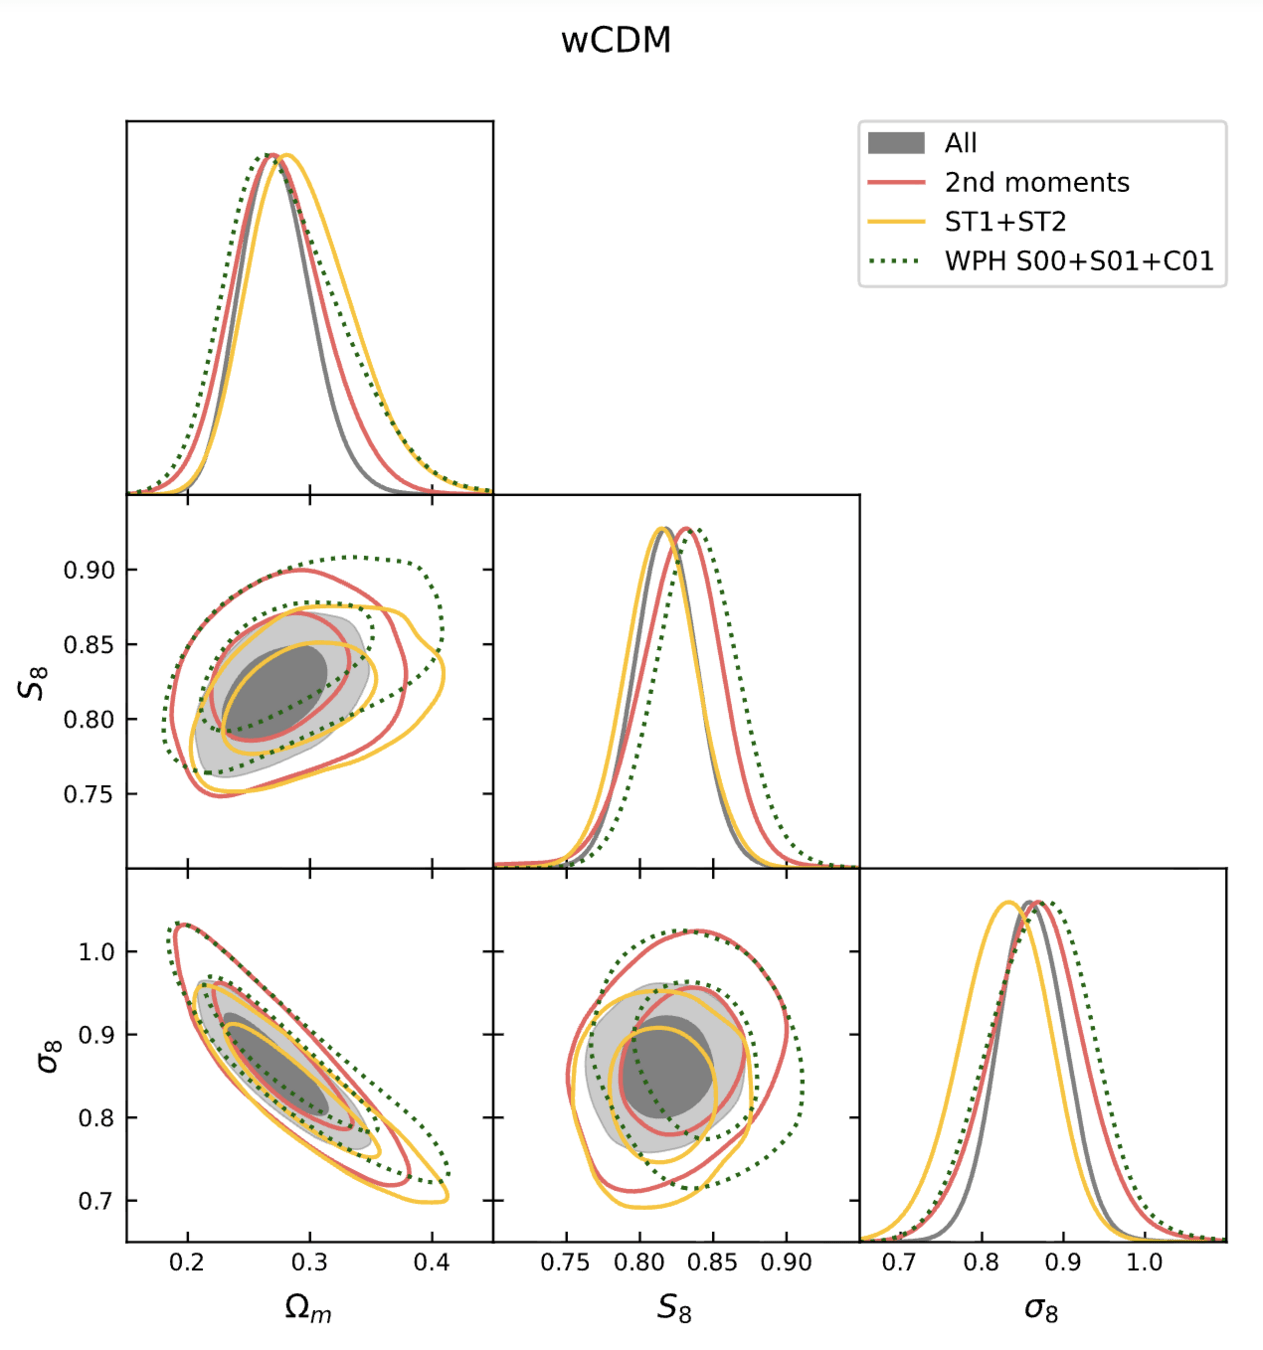
wavelet phase harmonic
scattering transform coefficients
Computing the covariance matrix of a combination of summary statistics is challenging.
Adding more summary statistics tightens the constraints
Implicit Inference
E.g. of results on Data
NN-based summaries from the maps + Cl
Implicit Inference
E.g. of results on Data
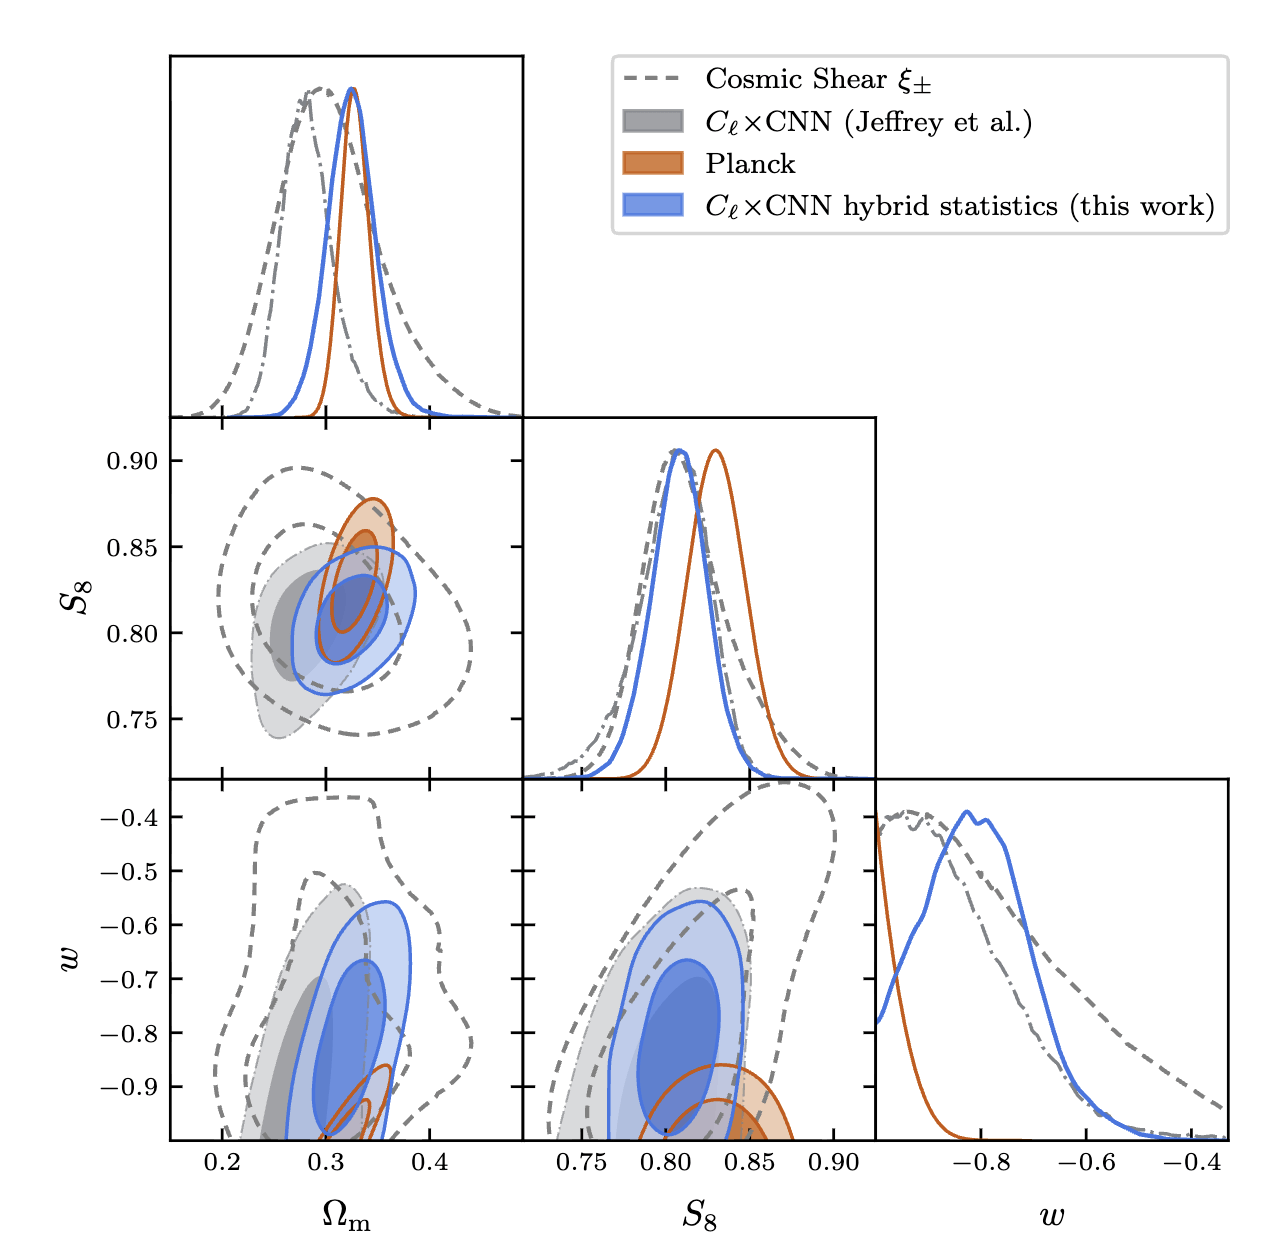
Different NN-based summaries from the maps + Cl
Robust FLI with Implicit Inference
We've seen that implicit inference is usually combined with summary statistics. Why?
p(x \mid \theta)
- NLE needs to learn
- NLE needs to learn
p(\theta \mid x)
- NPE needs to learn
Classical NFs are not good in high dimensions
How to build summaries that can extract all the information?
t := f(x)
x
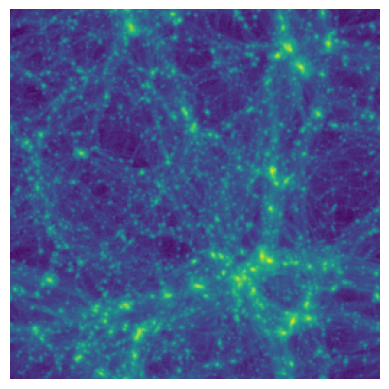
The NF needs to learn the distribution for each AND the complex relation between and
x
x
\theta
Robust FLI with Implicit Inference
Indeed, we saw in previous slides that the summaries have an impact on the constraining power
I(\theta,t)
H(\theta)
H(t)
H(\theta|t)
H(t|\theta)
I(\theta,t) = H(t) - H(t|\theta)
p(\theta \: | \: x) = p(\theta \: | \: f(x))
\Leftrightarrow I(\theta, x) = I(\theta, f(x))
Sufficient Statistic:
Mutual information
t := f(x)
x
Robust FLI with Implicit Inference
p(\theta \: | \: x) = p(\theta \: | \: f(x))
\Leftrightarrow I(\theta, x) = I(\theta, f(x))
Sufficient Statistic:
Mutual information
t := f(x)
x

Only a matter of the loss function we use!
Robust FLI with Implicit Inference
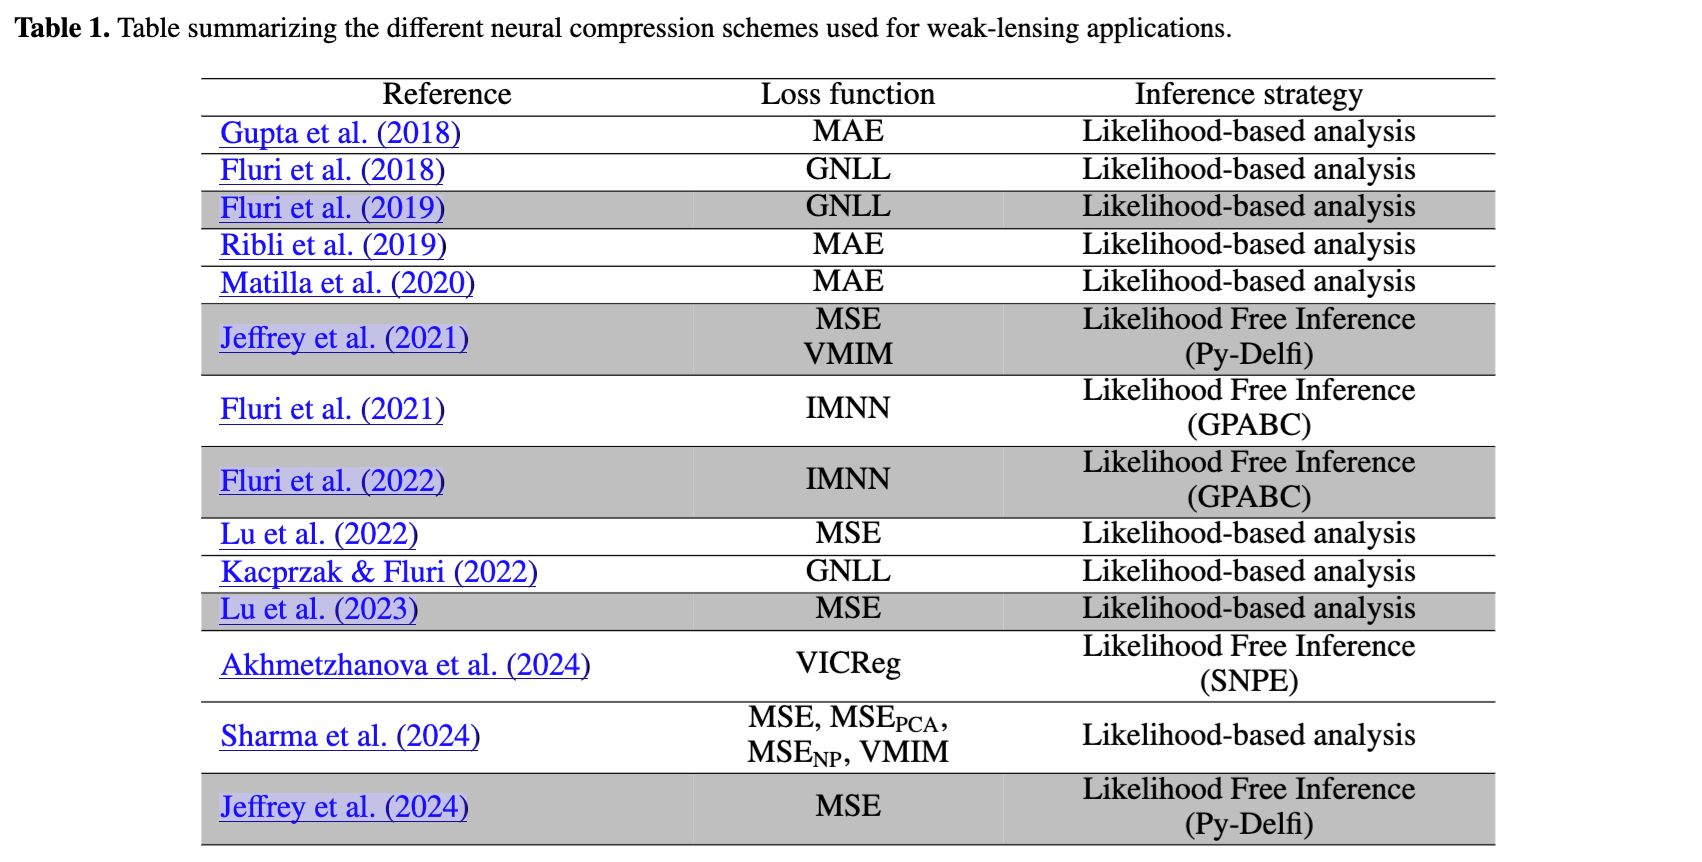
Regression Losses
Information-based Losses
p(\theta \mid x_0)
p(\theta \mid x_1)
p(\theta \mid t = t_0= t_1 =....=t_N)
I(\theta, x) = I(\theta, f(x))
\mathcal{L}_{\text{MIM}} =\underset{f}{\text{ max }} I(\theta, f(x))
→ Build sufficient statistics by definition.
Mean Squared Error (MSE) loss:
\mathcal{L}_{\text{MSE}} = \mathbb{E}_{p(x,\theta)} \left[\parallel \theta - f_\varphi(x) \parallel ^2 \right]
→ Approximate the mean of the posterior.
p(\theta \: | \: x) = p(\theta \: | \: f(x))
\Leftrightarrow I(\theta, x) = I(\theta, f(x))
Sufficient Statistic:
Robust FLI with Implicit Inference
= \underset{f}{\text{ min }} - \mathbb{E}_{p(x,f(x))}\left[\log p(\theta |f(x)\right]
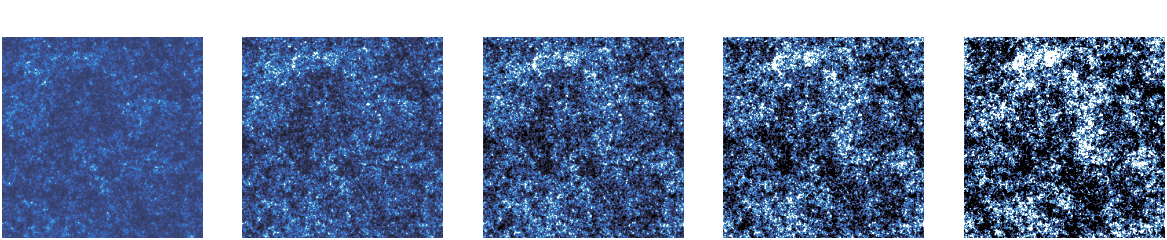
t = f_{\varphi}(x)
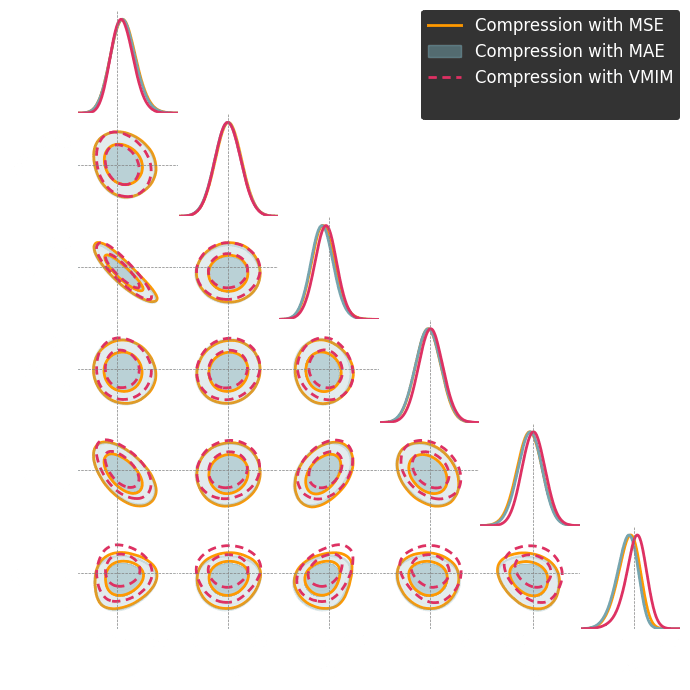
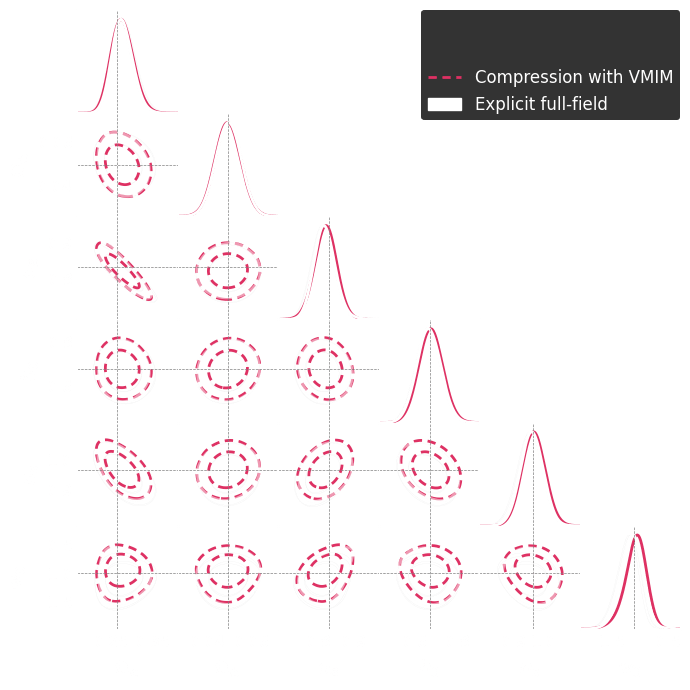
Robust FLI with Implicit Inference
Joint Inference with Implicit Inference
Joint Inference with Implicit Inference
Implicit Inference can be extended to the joint posterior of initial conditions. For this, we need generative models that scale to high dimension.
Flow Matching / Stochastic Interpolants / Diffusion Models (Albergo et al. (2025))
p_0
p_1
p_t
We need to learn a continuous transformation solution of the ODE
f_t
\frac{d x}{dt} = \color{#479af7}{v}\color{black}{(x, t)}
velocity field
More flexible!
Joint Inference with Implicit Inference
\frac{d x}{dt} = \color{#479af7}{v}\color{black}{(x, t)}
We need to learn a continuous transformation solution of the ODE
f_t
Joint Inference with Implicit Inference
\frac{d x}{dt} = \color{#479af7}{v}\color{black}{(x, t)}
Credit: Gagneux et al. 2025
We need to learn a continuous transformation solution of the ODE
f_t
Joint Inference with Implicit Inference
\frac{d x}{dt} = \color{#479af7}{v}\color{black}{(x, t)}
We need to learn a continuous transformation solution of the ODE
f_t
Too difficult to train under the NLL, as we need to solve the ODE for each simulation:
- \mathbb{E}_{x \sim p_x(x)}\left[\log p_1(x)\right] = - \mathbb{E}_{x \sim p_x(x)}\left[\log p_0(f^{-1}(x)) + \log
\displaystyle\left\lvert det \frac{\partial f^{-1}(x)}{\partial x}\right\rvert \right]
Joint Inference with Implicit Inference
\frac{d x}{dt} = \color{#479af7}{v}\color{black}{(x, t)}
We need to learn a continuous transformation solution of the ODE
f_t
\mathcal{L}_{FM} = \mathbb{E}_{p(t)q(x_0,x_1)p_t(x_t\mid x_0,x_1)} \Big[ \| \color{#b6008e}{v_\varphi} \color{black}{(x_t,t)- v(x_t) \|^2 \Big]}
This is the NN!
Lipman et al. (2023)
Joint Inference with Implicit Inference
\frac{d x}{dt} = \color{#479af7}{v}\color{black}{(x, t)}
We need to learn a continuous transformation solution of the ODE
f_t
\mathcal{L}_{FM} = \mathbb{E}_{p(t)q(x_0,x_1)p_t(x_t\mid x_0,x_1)} \Big[ \| \color{#b6008e}{v_\varphi} \color{black}{(x_t,t)- v(x_t|x_0,x_1) \|^2 \Big]}
This is the NN!
Lipman et al. (2023)
Joint Inference with Implicit Inference
\frac{d x}{dt} = \color{#479af7}{v}\color{black}{(x, t)}
We need to learn a continuous transformation solution of the ODE
f_t
p(x_t\mid x_0,x_1) = \mathcal{N}((1-t)x_1 + t x_0, \sigma)
v(x_t| x_0,x_1) = x_1 - x_0
with:
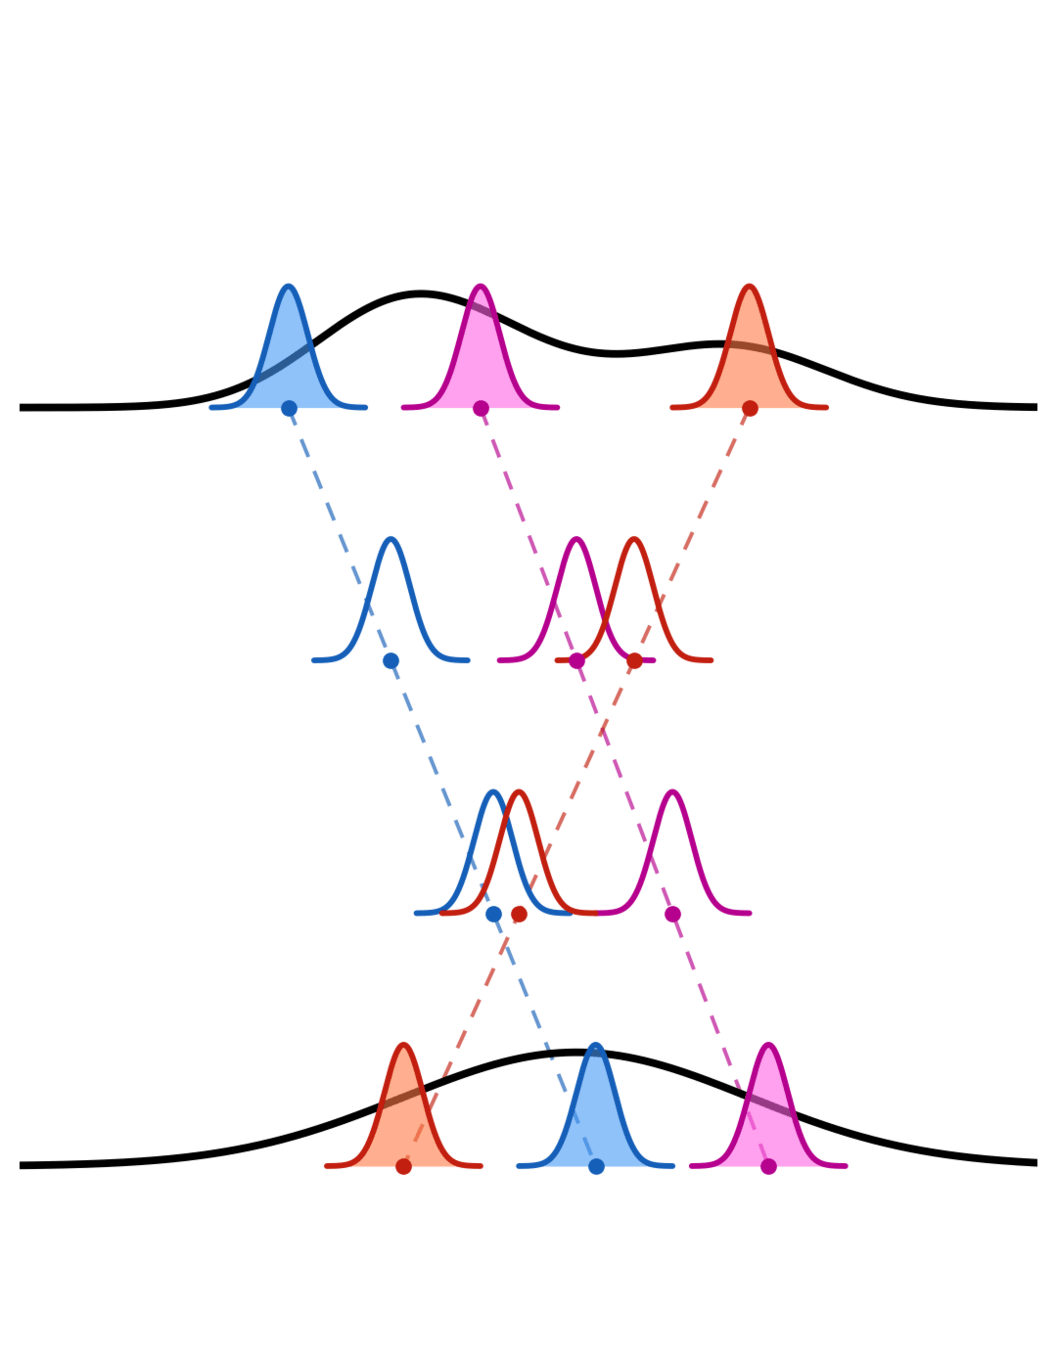
Tong et al. 2023
\mathcal{L}_{FM} = \mathbb{E}_{p(t)q(x_0,x_1)p_t(x_t\mid x_0,x_1)} \Big[ \| \color{#b6008e}{v_\varphi} \color{black}{(x_t,t)- v(x_t|x_0,x_1) \|^2 \Big]}
Joint Inference with Implicit Inference
dx = [f(x,t)-g^2(t)\color{#b6008e}{\nabla_x \log p_t(x)}\color{black}{]dt +g(t)dw}
\nabla_x \log p_t(x)
v(x,t)
dx= [\color{#479af7}{v(x, t)}\color{black}{]dt}
\mathcal{L}_{SM} = \lambda_t\mathbb{E}_{p(t)p(x_0)p(x_t \mid x_0)} \Big[ \| \color{#b6008e}{s_\varphi} \color{black}{(x_t,t)- \nabla_{x_t} \log p(x_t\mid x_0) \|^2 \Big]}
\mathcal{L}_{FM} = \mathbb{E}_{p(t)q(x_0,x_1)p_t(x_t\mid x_0,x_1)} \Big[ \| \color{#479af7}{v_\varphi} \color{black}{(x_t,t)- v(x_t|x_0,x_1) \|^2 \Big]}
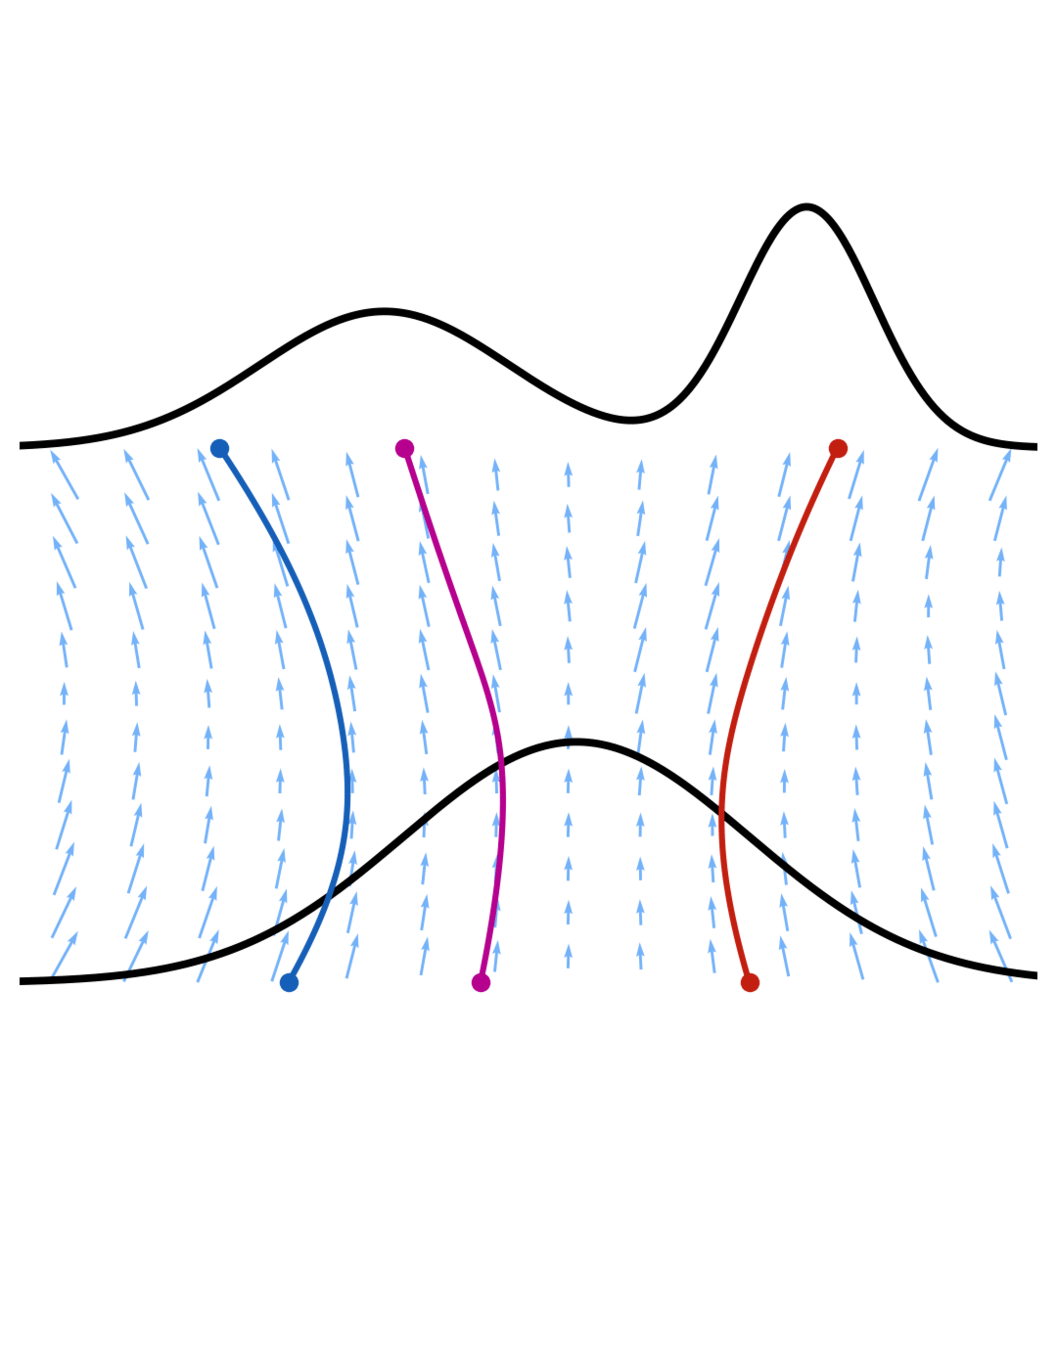
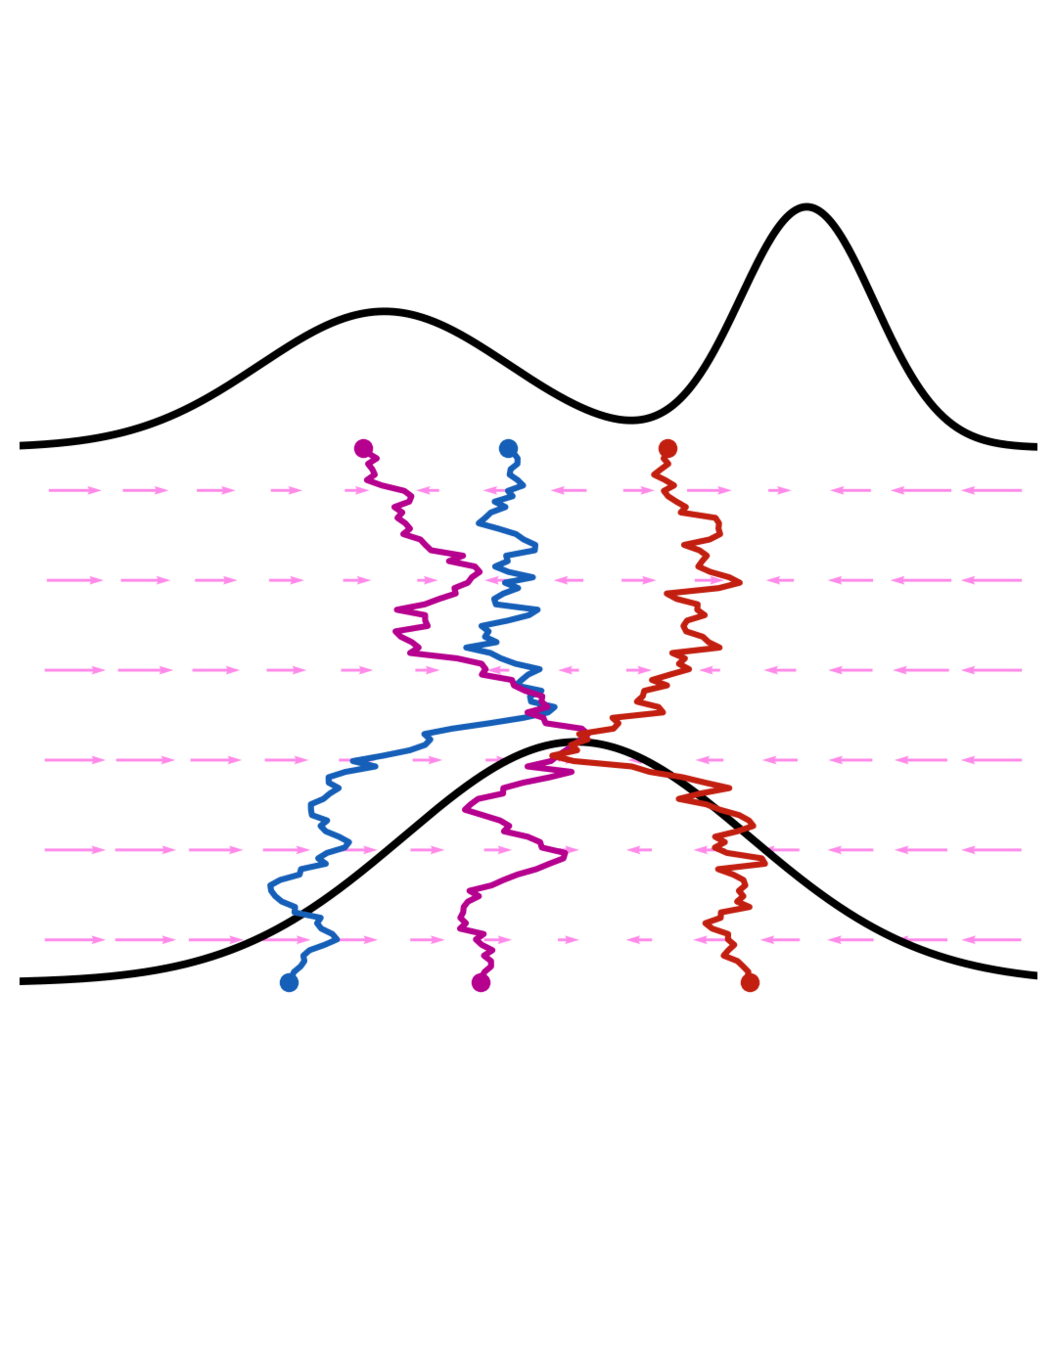
Flow Matching, Diffusion Models and Stochastic Interpolants are the same generative framework (Albergo et al. (2025)):
For instance:
Joint Inference with Implicit Inference
p(\delta_{\text{ICs}}, \theta \mid x) = p(\delta_{\text{ICs}} \mid x) p(\theta \mid \delta_{\text{ICs}}, x)
Normalizing Flow
Stochastic Interpolant
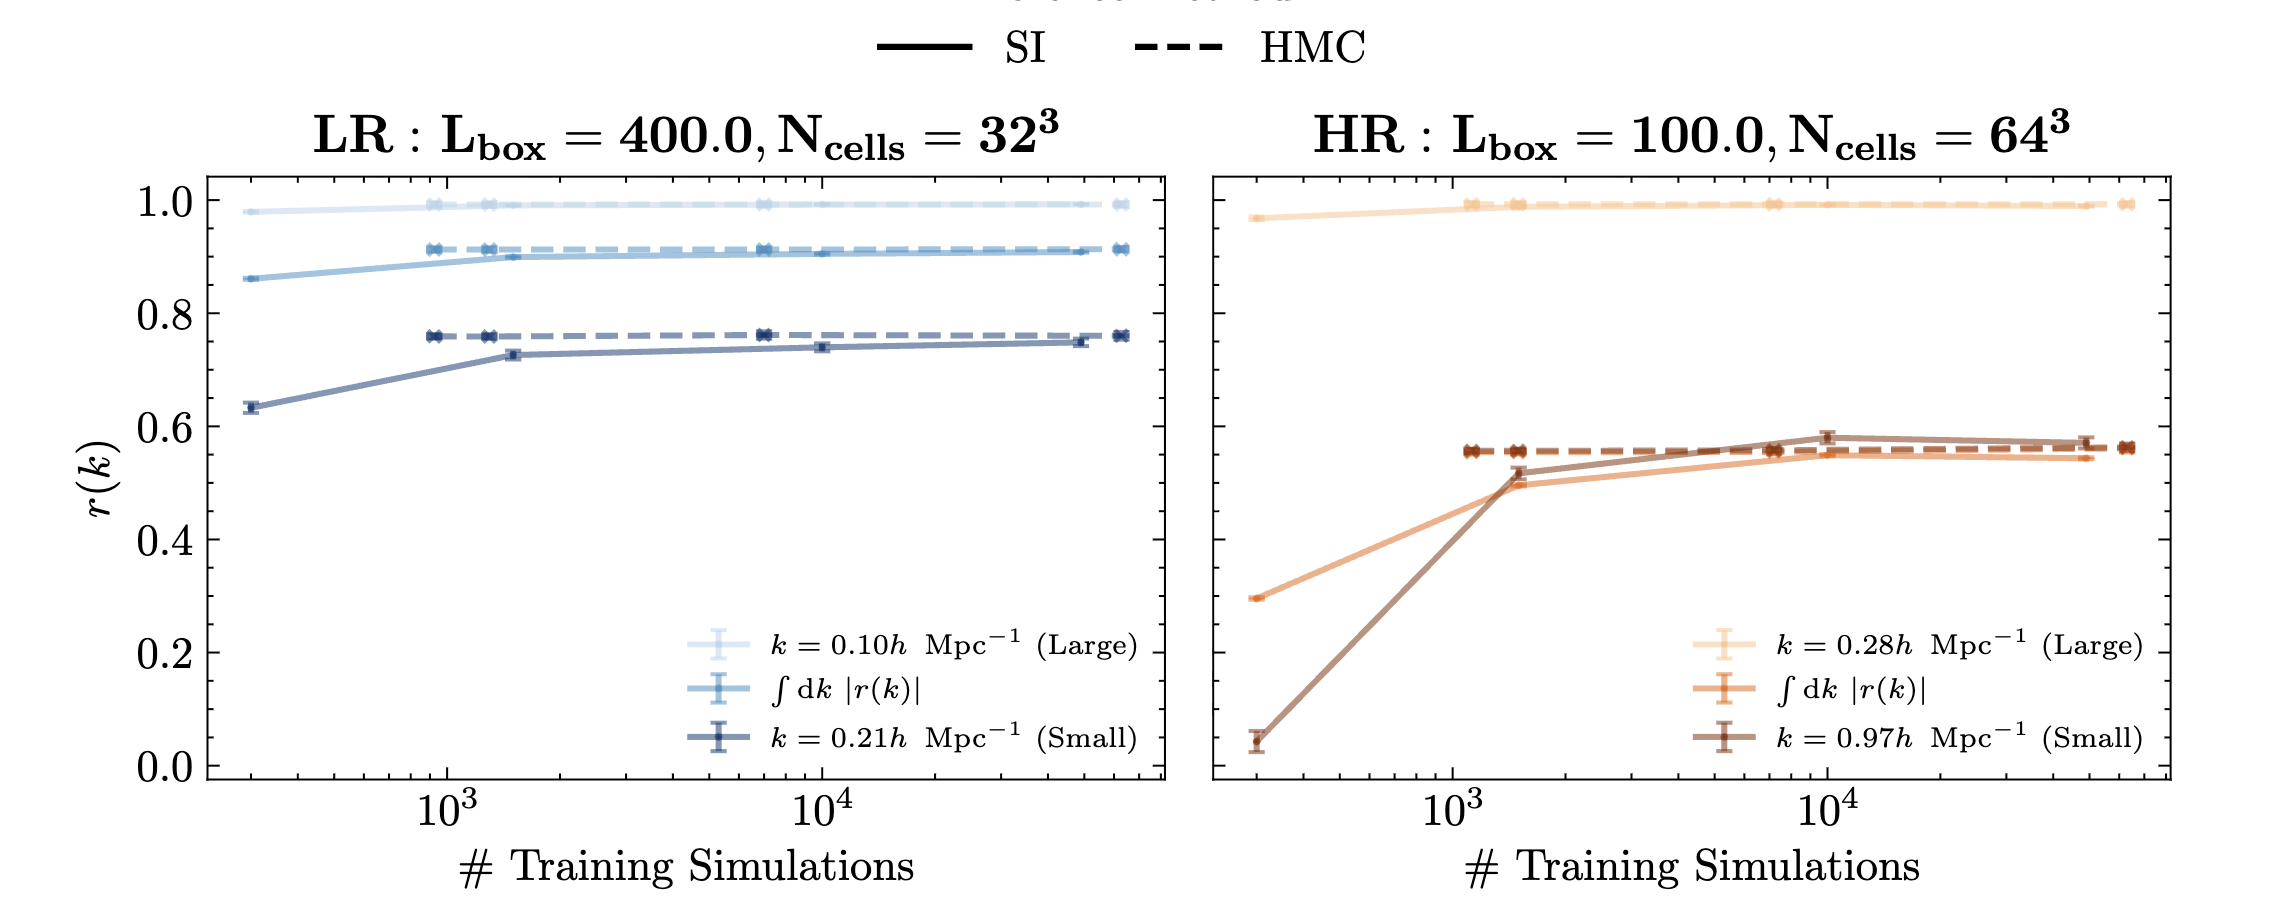
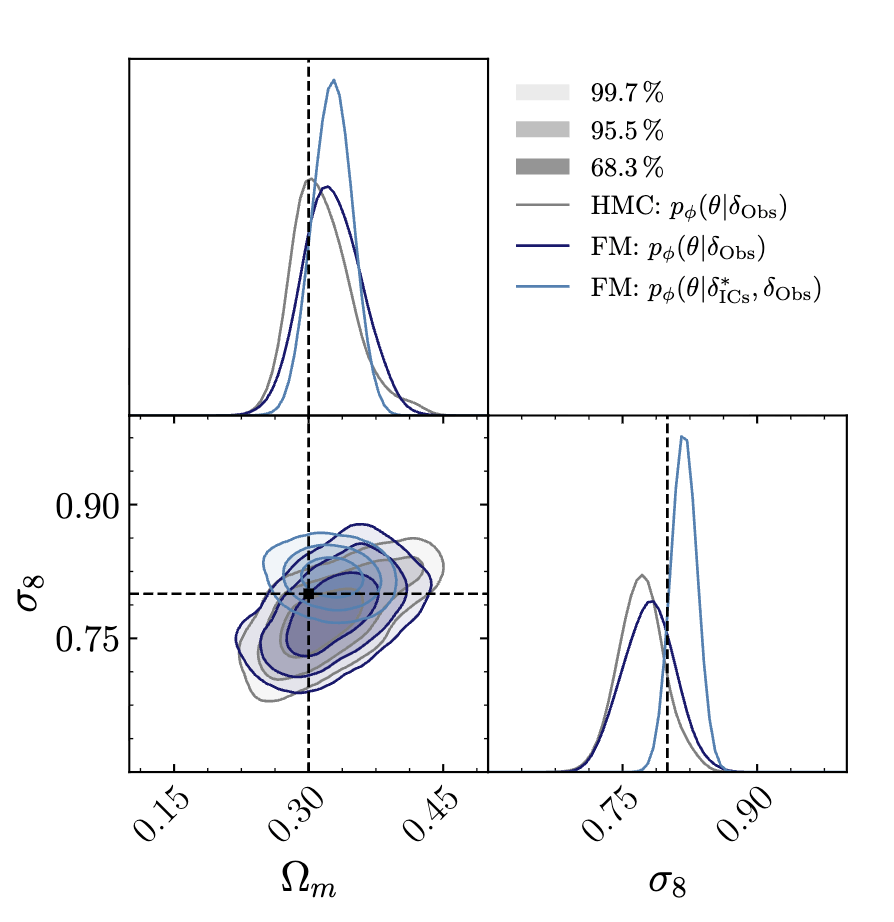
For instance:
Joint Inference with Implicit Inference
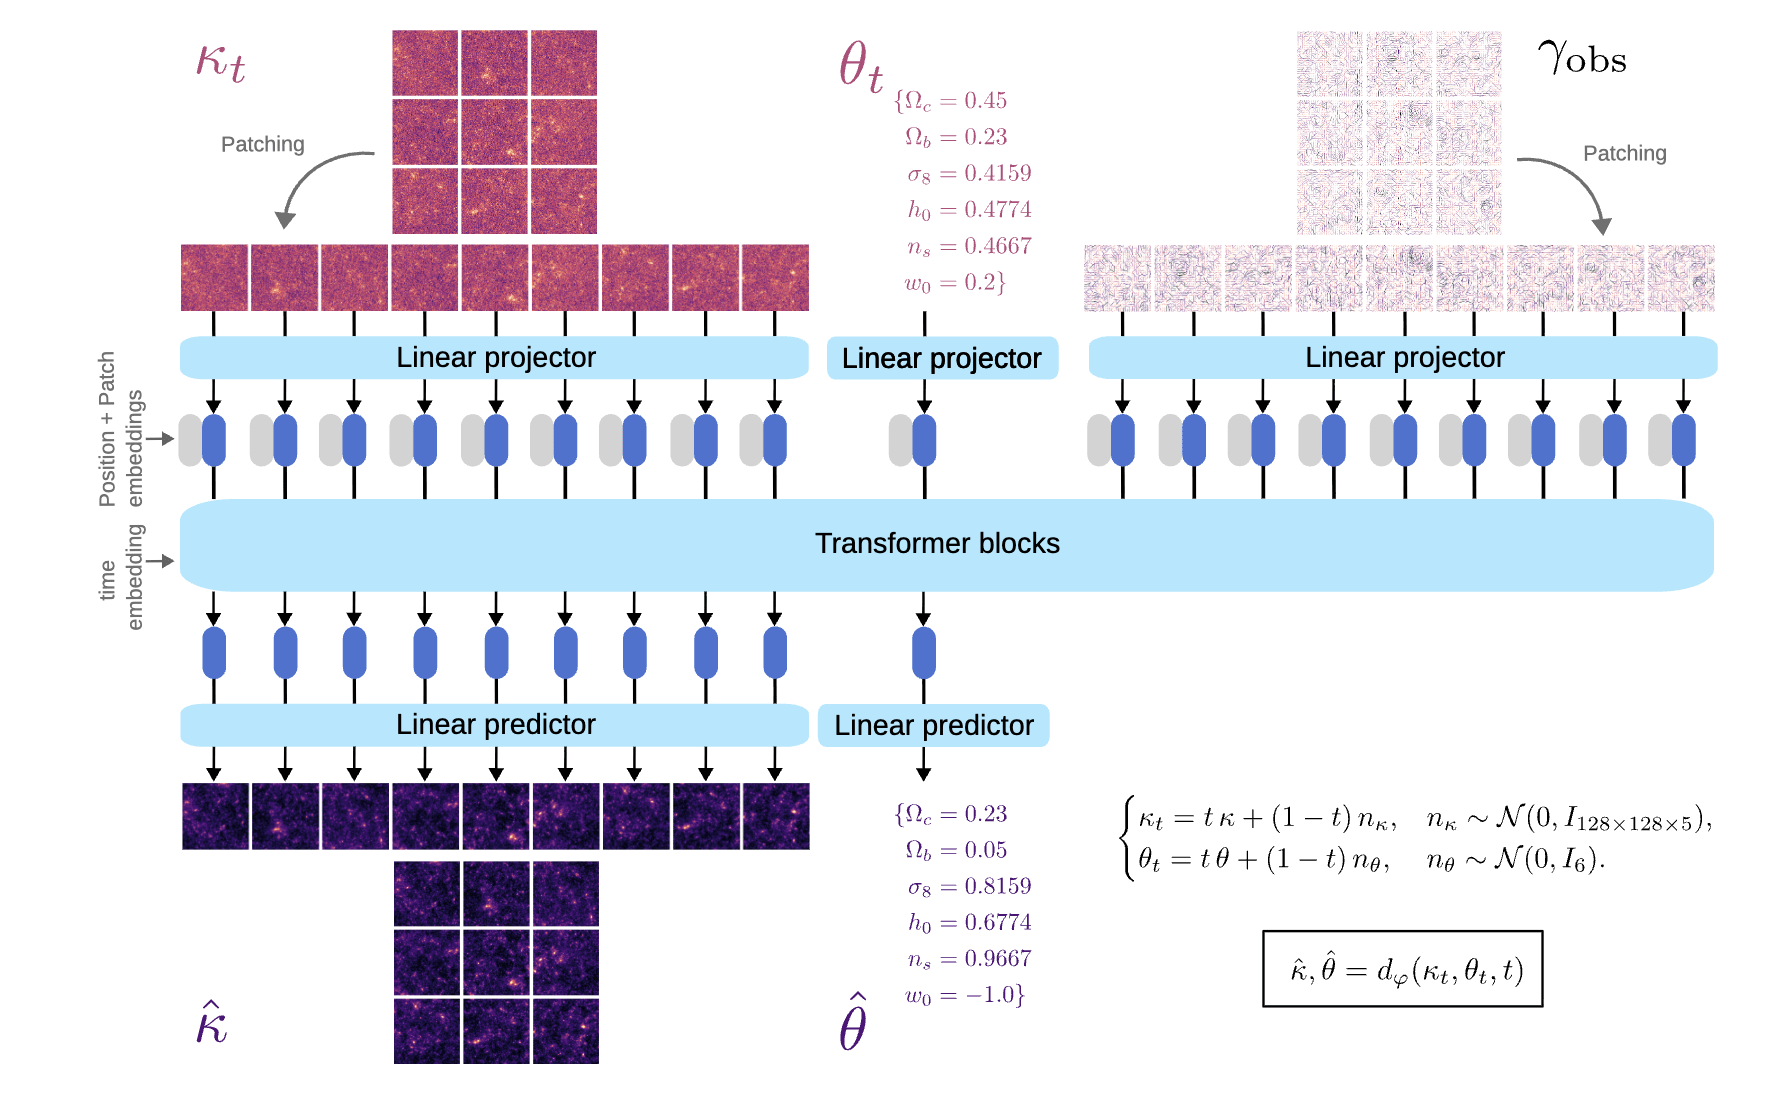
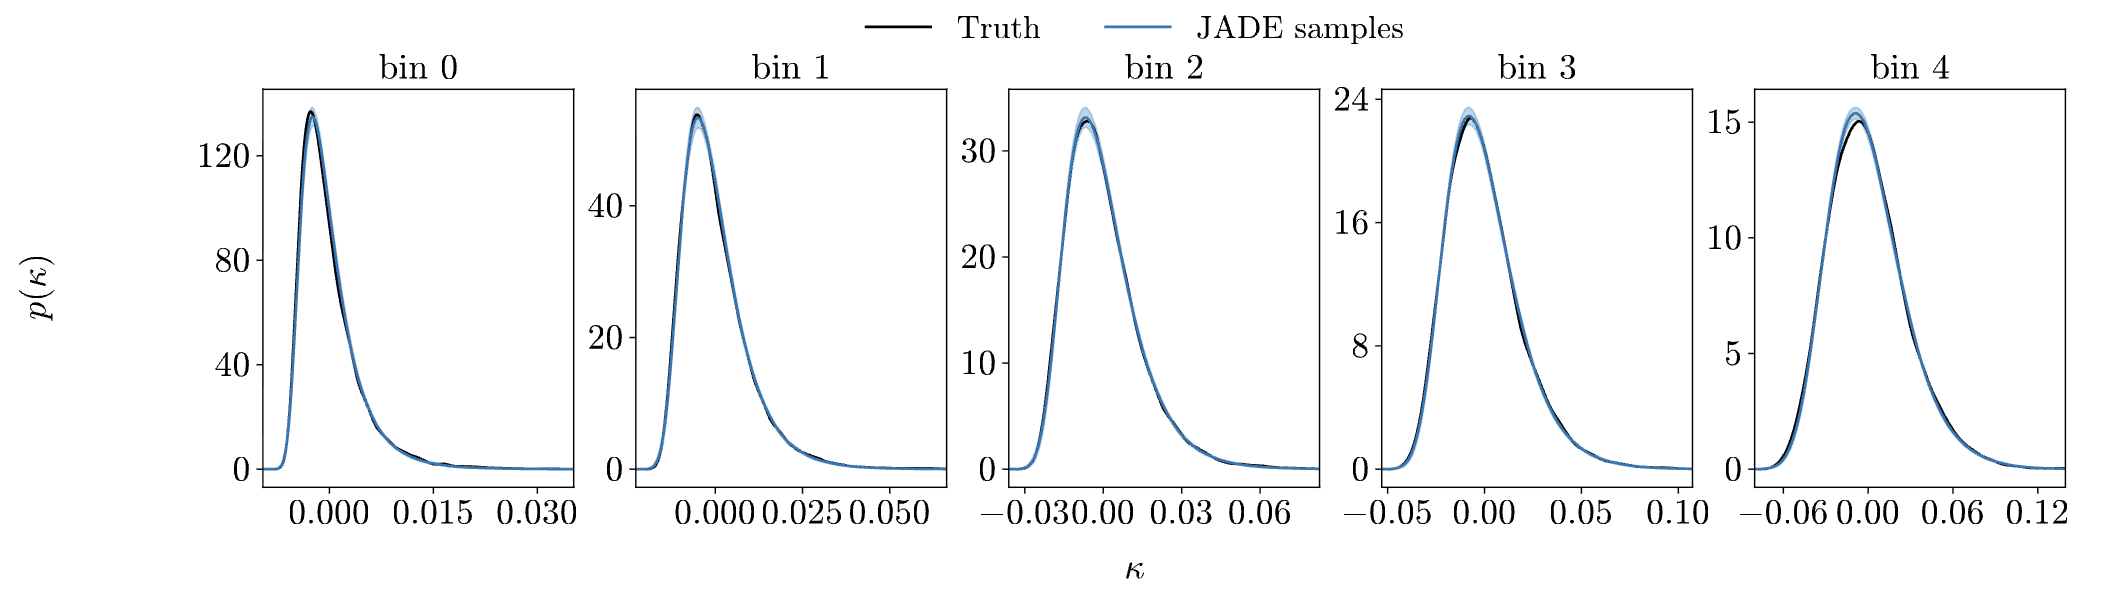
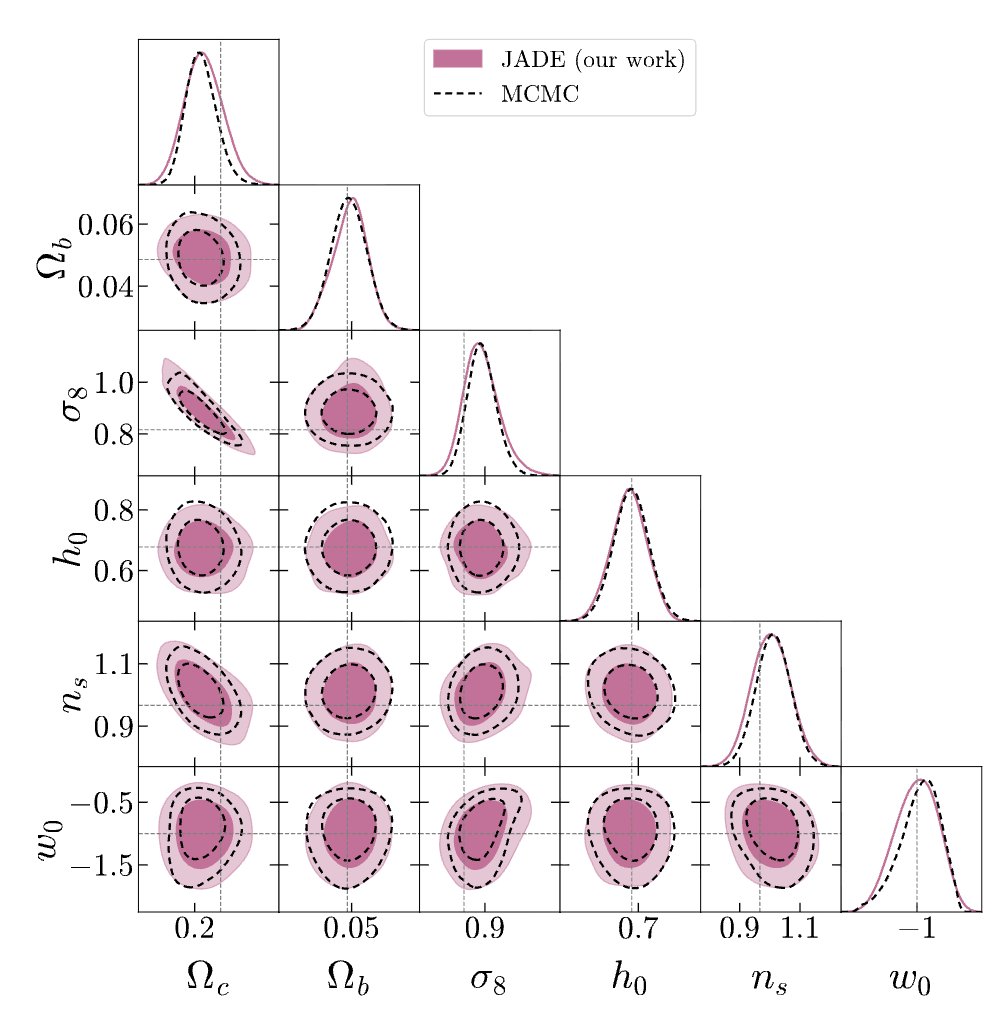
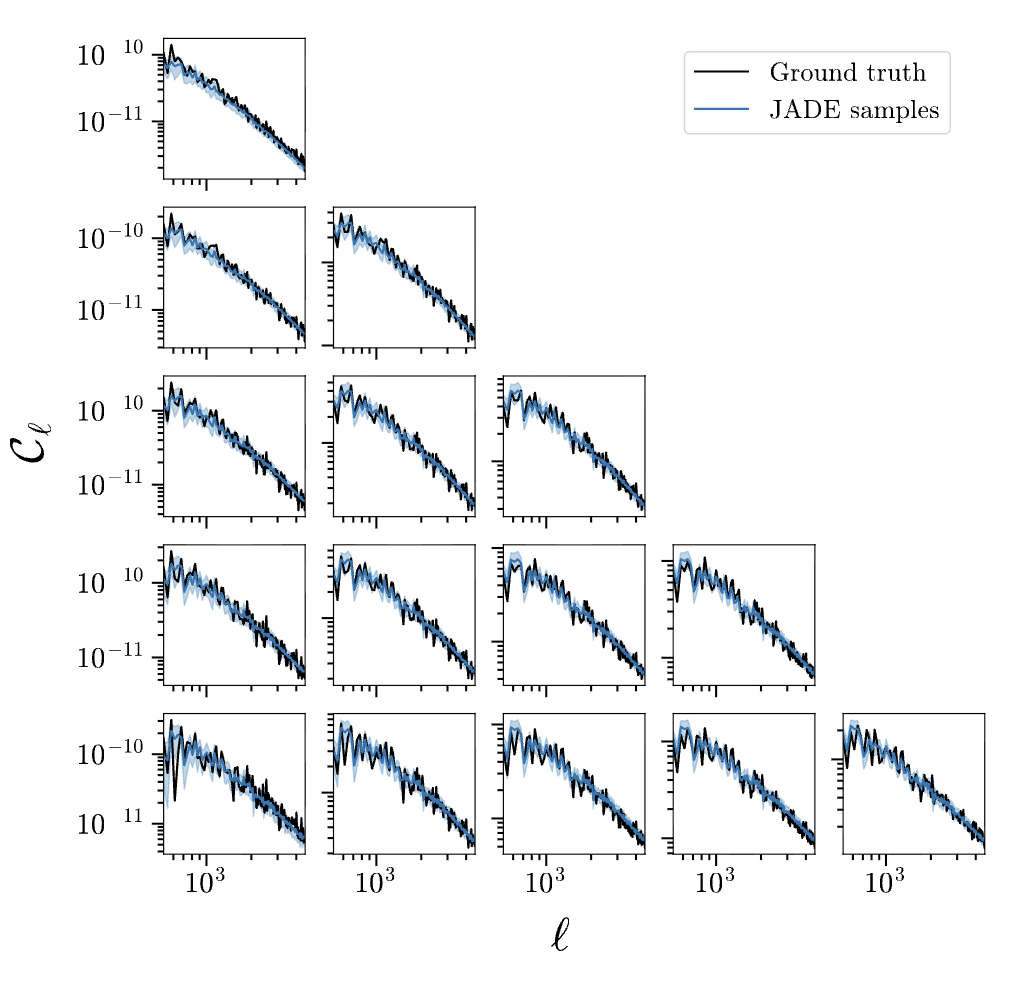
Directly learn the joint with Flow Matching
p(\delta_{\text{ICs}}, \theta \mid x)
We need an architecture that can work with multimodal data.
Inference Validation
Inference Validation
\hat{p}(y\mid x)
\hat{p}(y\mid x)
p(y\mid x)
Underconfident
p(y\mid x)
Biased
\hat{p}(y\mid x)
p(y\mid x)
Overconfident
ICML Spotlight ✨
Inference Validation
ICML Spotlight ✨
\hat{p}(y\mid x)
p(y \mid x)
.
Theorem:
Two distributions are equal if their probability measures are the same over all measurable sets.
6 pink samples
5 blue samples
✅
6 pink samples
5 blue samples
✅
Inference Validation
ICML Spotlight ✨
\hat{p}(y\mid x)
p(y \mid x)
.
Theorem:
Two distributions are equal if their probability measures are the same over all measurable sets.
6 pink samples
5 blue samples
✅
6 pink samples
5 blue samples
✅
6 pink samples
✅
6 pink samples
7 blue samples
✅
Inference Validation
ICML Spotlight ✨
\hat{p}(y\mid x)
p(y \mid x)
.
Theorem:
Two distributions are equal if their probability measures are the same over all measurable sets.
6 pink samples
5 blue samples
✅
6 pink samples
5 blue samples
✅
6 pink samples
✅
6 pink samples
7 blue samples
✅
✅
8 pink samples
7 blue samples
✅
Inference Validation
ICML Spotlight ✨
\hat{p}(y\mid x)
p(y \mid x)
Theorem:
Two distributions are equal if their probability measures are the same over all measurable sets.
6 pink samples
5 blue samples
✅
6 pink samples
5 blue samples
✅
6 pink samples
✅
6 pink samples
7 blue samples
✅
✅
8 pink samples
7 blue samples
✅
.
Inference Validation
ICML Spotlight ✨
\hat{p}(y\mid x)
p(y \mid x)
.
Bayesian approach: what is the probability that the true sample lies inside or outside the region given than n samples from the proposed one are inside?
p(k\mid n)
Theorem:
\text{If } \hat{p}(y \mid x) = p(y \mid x) \text{ then }\: p(k \mid n) \sim Beta(2,1)
Lemma:
\text{If } \hat{p}(y \mid x) = p(y \mid x) \text{ then }
\mu_{Mira} = \mathbb{E}_{p(k,n)}\left[p(k \mid n)\right] = 2/3
= \frac{n+1}{N+2}1_{(k=1)}+ \frac{N-n+1}{N+2}1_{(k=0)}
Inference Validation
ICML Spotlight ✨
- Sample-based
- Can work with few samples
- Works in high dimension
- Does not rely on training a model
- Detect miscalibration even when other scores fail
- It is a scalar value
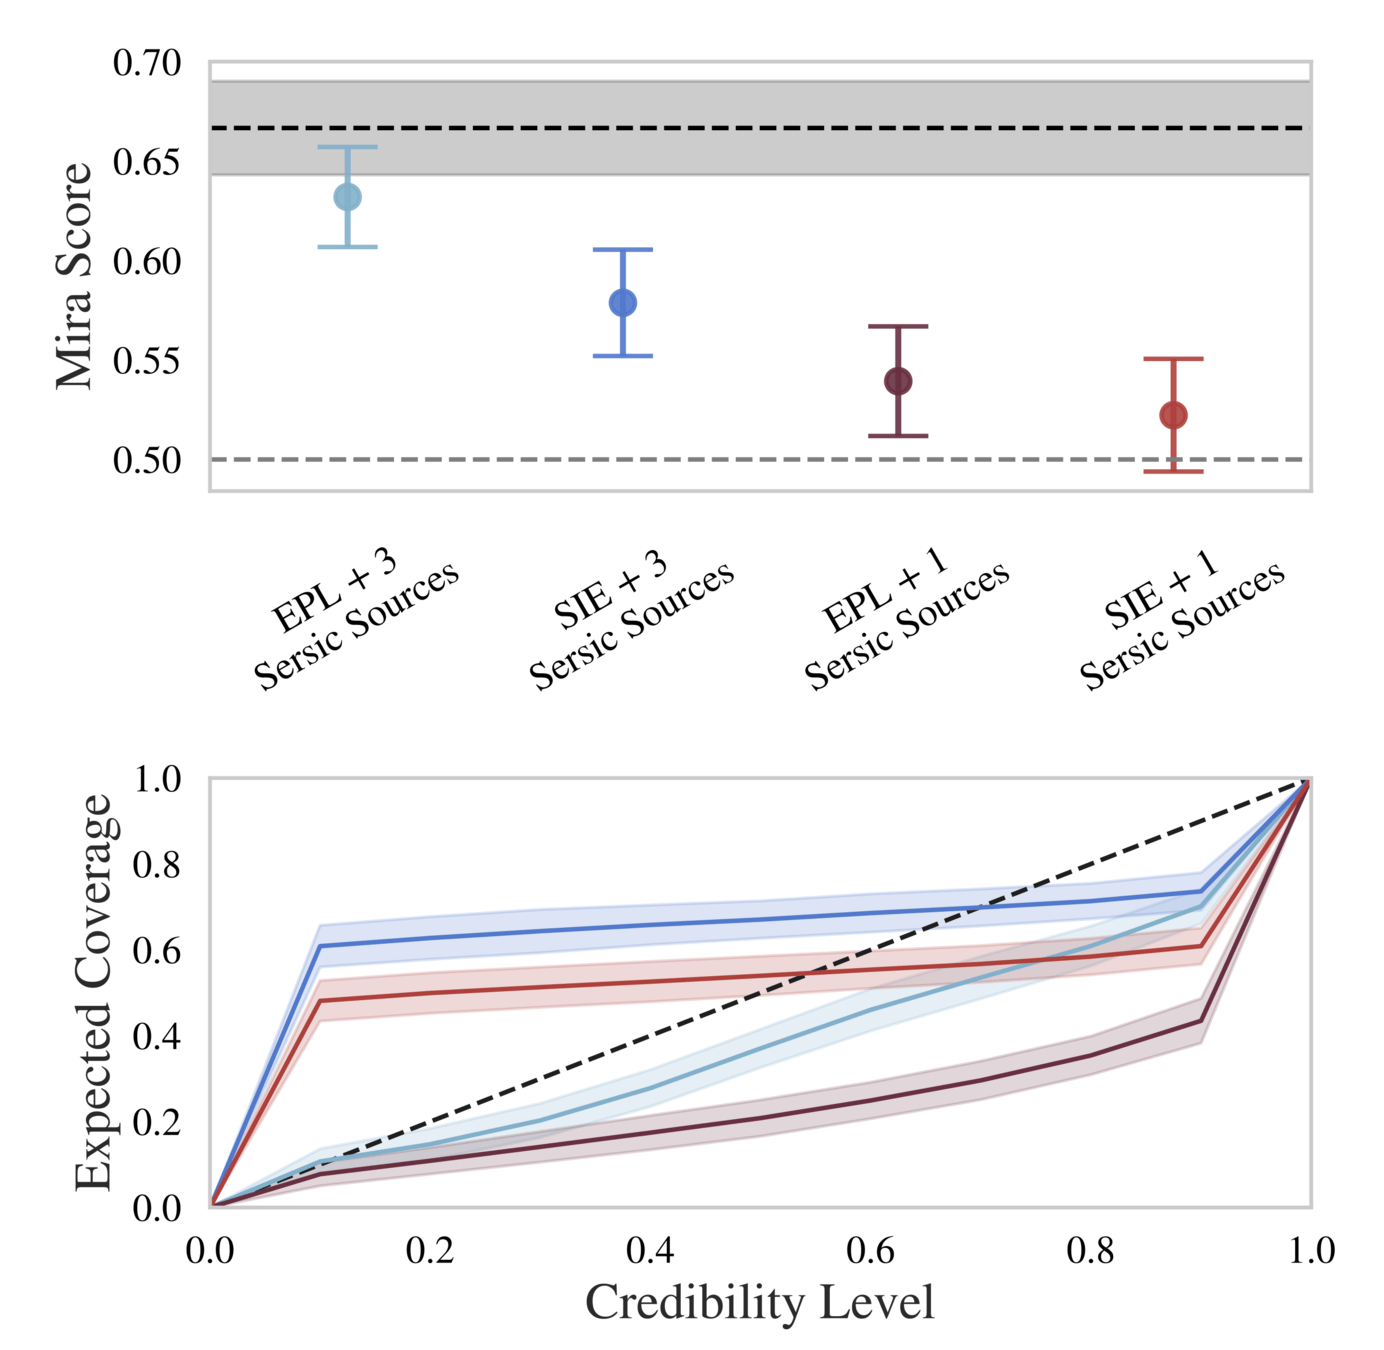
Which posterior is the best?
MIRA (Mass In Random Area)
A Score for Conditional Distribution Accuracy and Model Comparison
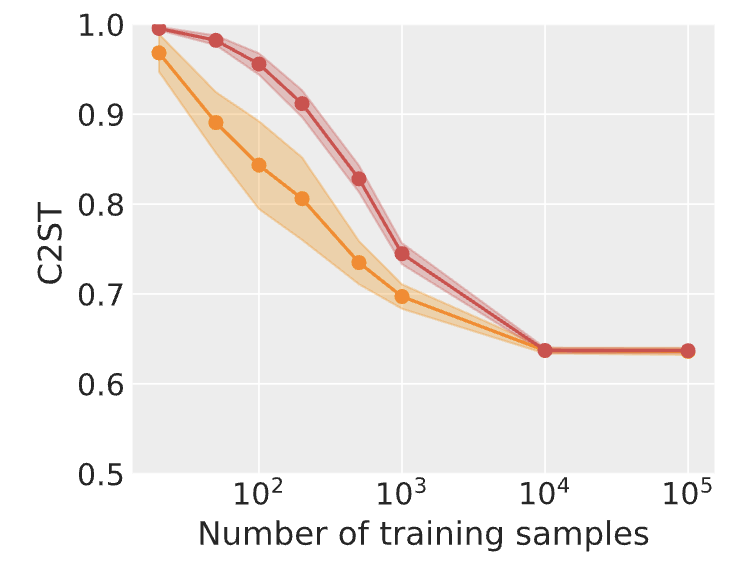
Dealing with Expensive Simulations
Dealing with Expensive Simulations
Simulation-Based Inference methods rely exclusively on simulations
Simulations have to be the most realistic
Very costly
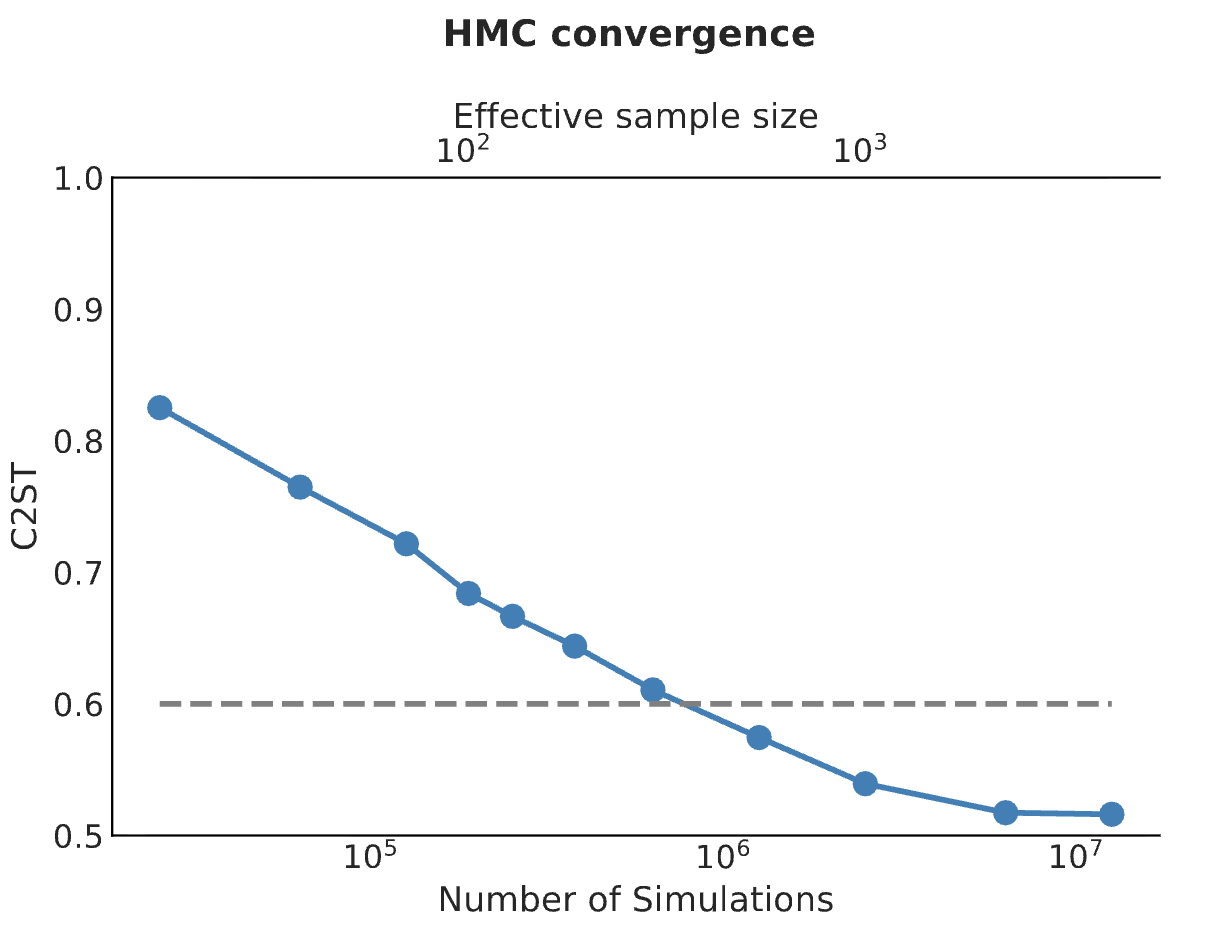
Explicit Inference
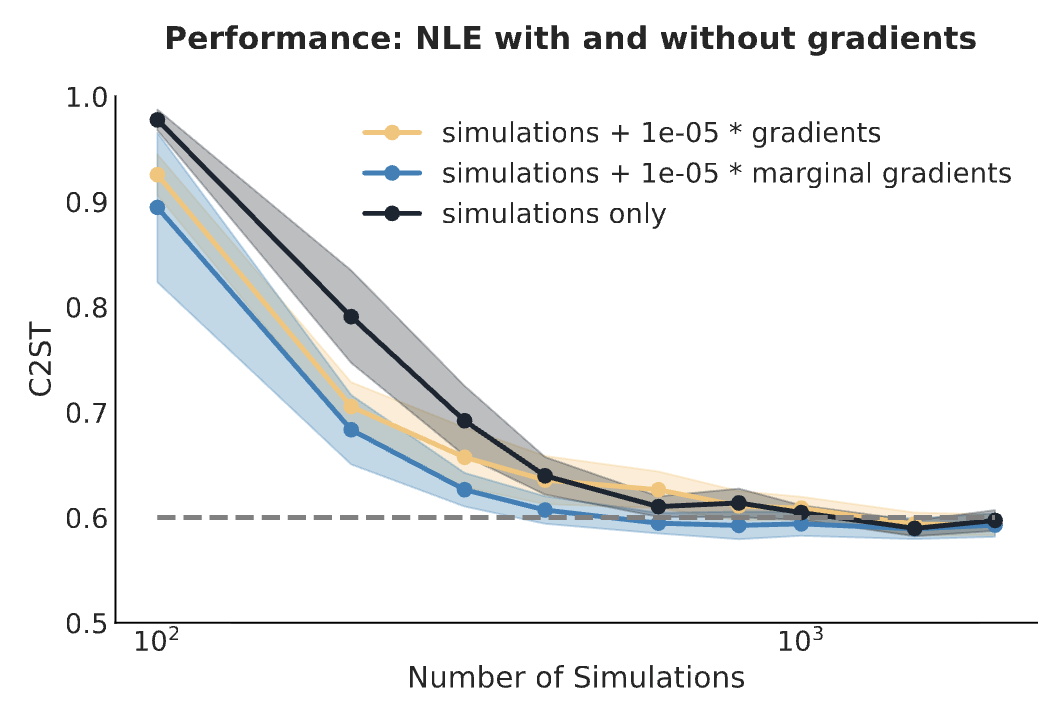
Implicit Inference
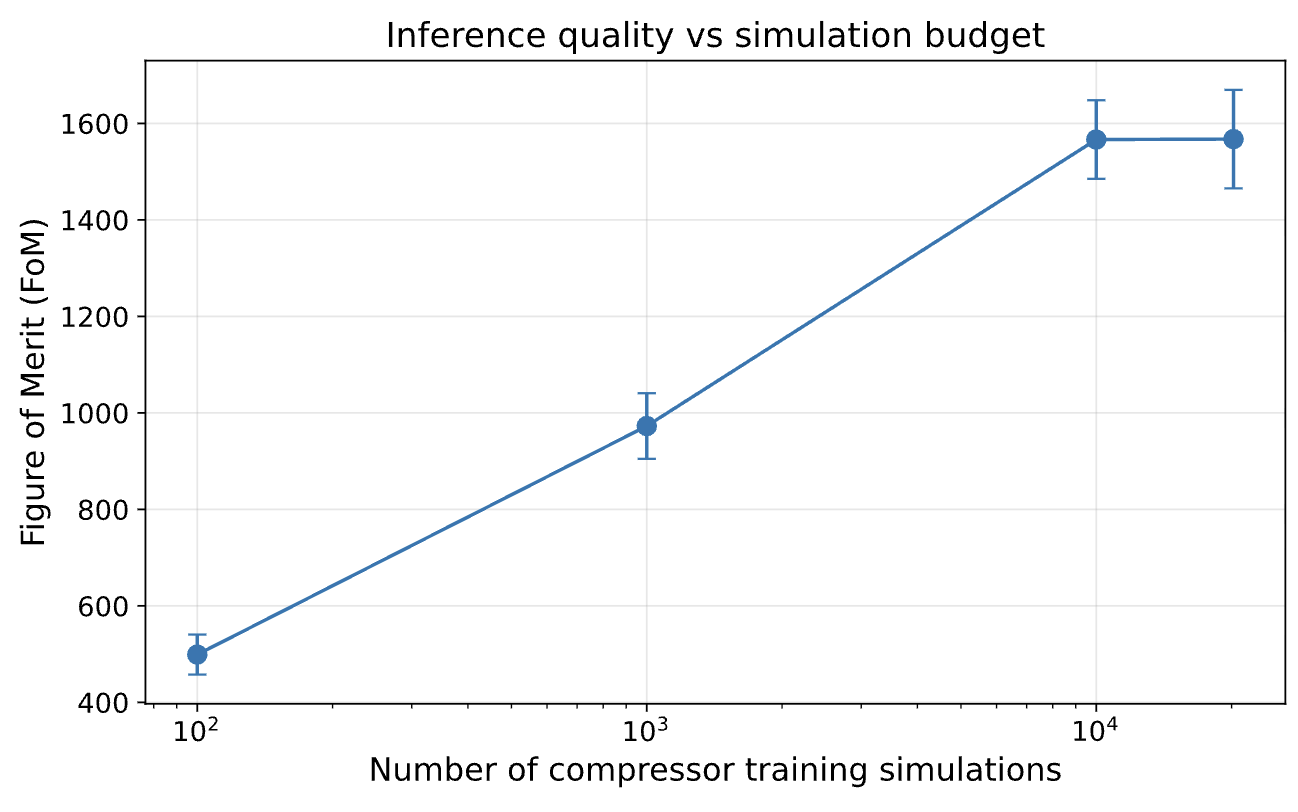
Compression
Preliminary results!
Dealing with Expensive Simulations
Implicit Inference methods with fewer simulations
Sequential methods
p(\theta)
We can sample simulations only where we need!
p(\theta \mid x=x_0)
Prior
Evaluate
Posterior
Observation
Posterior Estimator
Simulator
Neural Posterior Estimation
Sequential
Proposal
Need to re weight for SNPE! See Greenberg et al. (2019)
Dealing with Expensive Simulations
Implicit Inference methods with fewer simulations
Gradient-based methods
?
❌
✅
+ \: \lambda \: \displaystyle \mathbb{E}\left[ \parallel \nabla_{\theta} \log p^{\phi}(\theta |x) - \nabla_{\theta} \log p(\theta, z |x)\parallel_2^2 \right]
\begin{array}{ll}
Loss = - \mathbb{E}_{x, \theta \sim p_x(x, \theta)}\left[ \log\left(p_x^{\phi}(\theta \mid x)\right) \right]\\
\end{array}
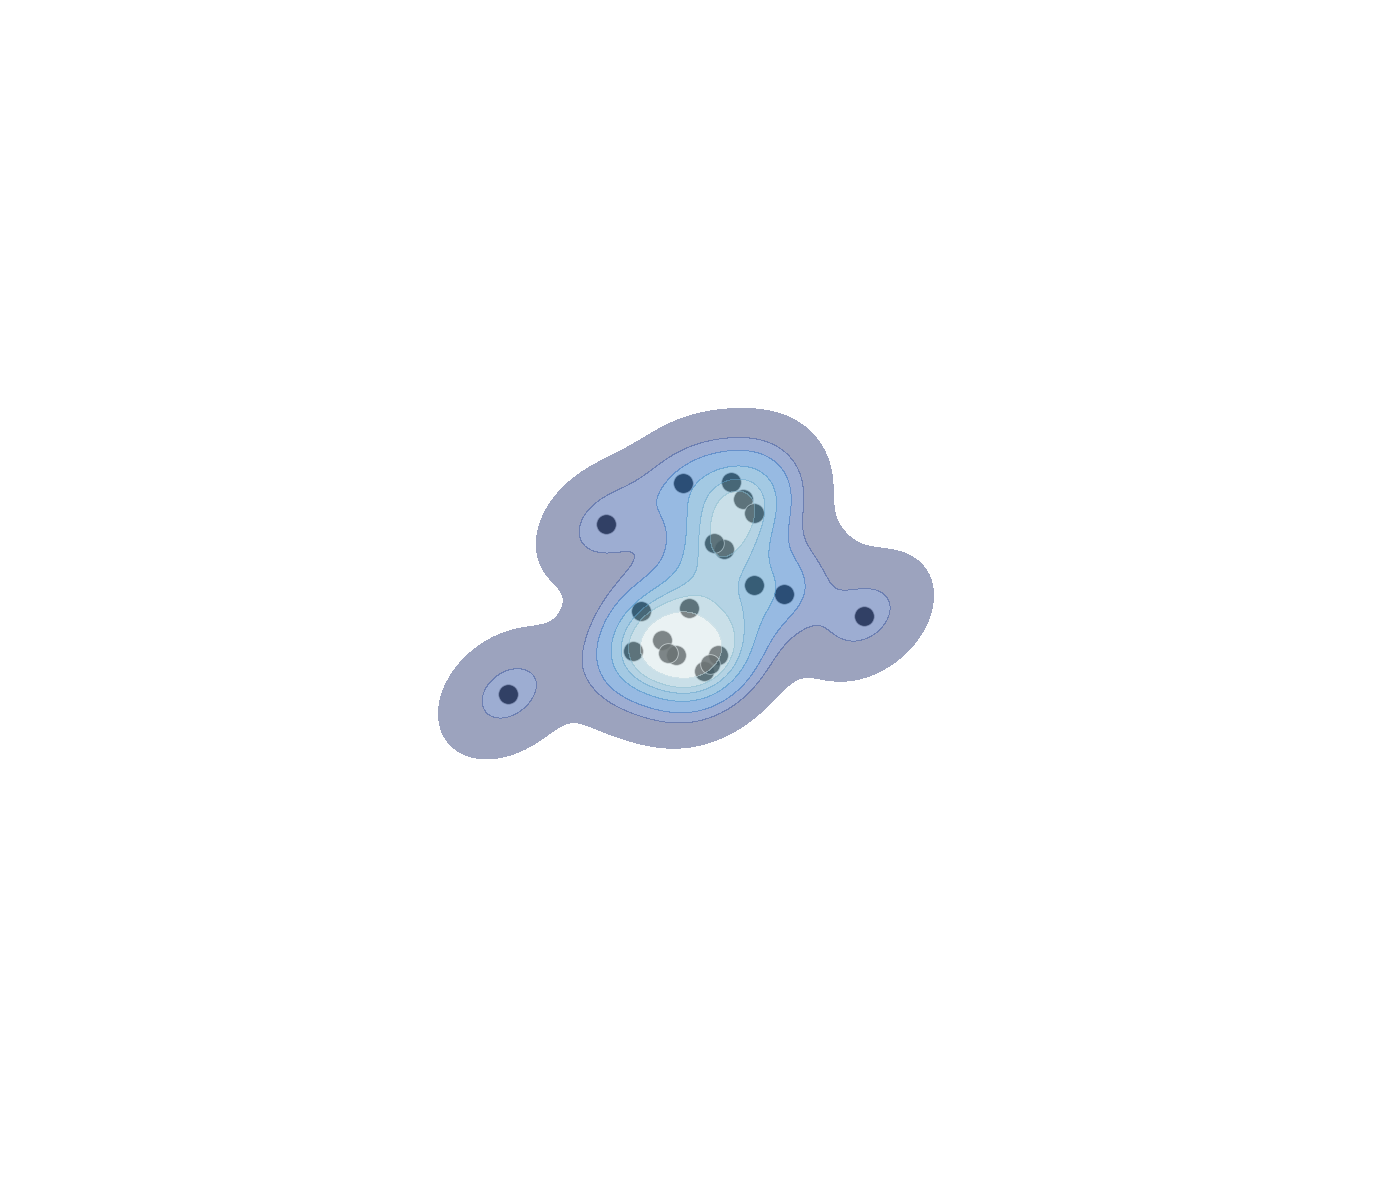
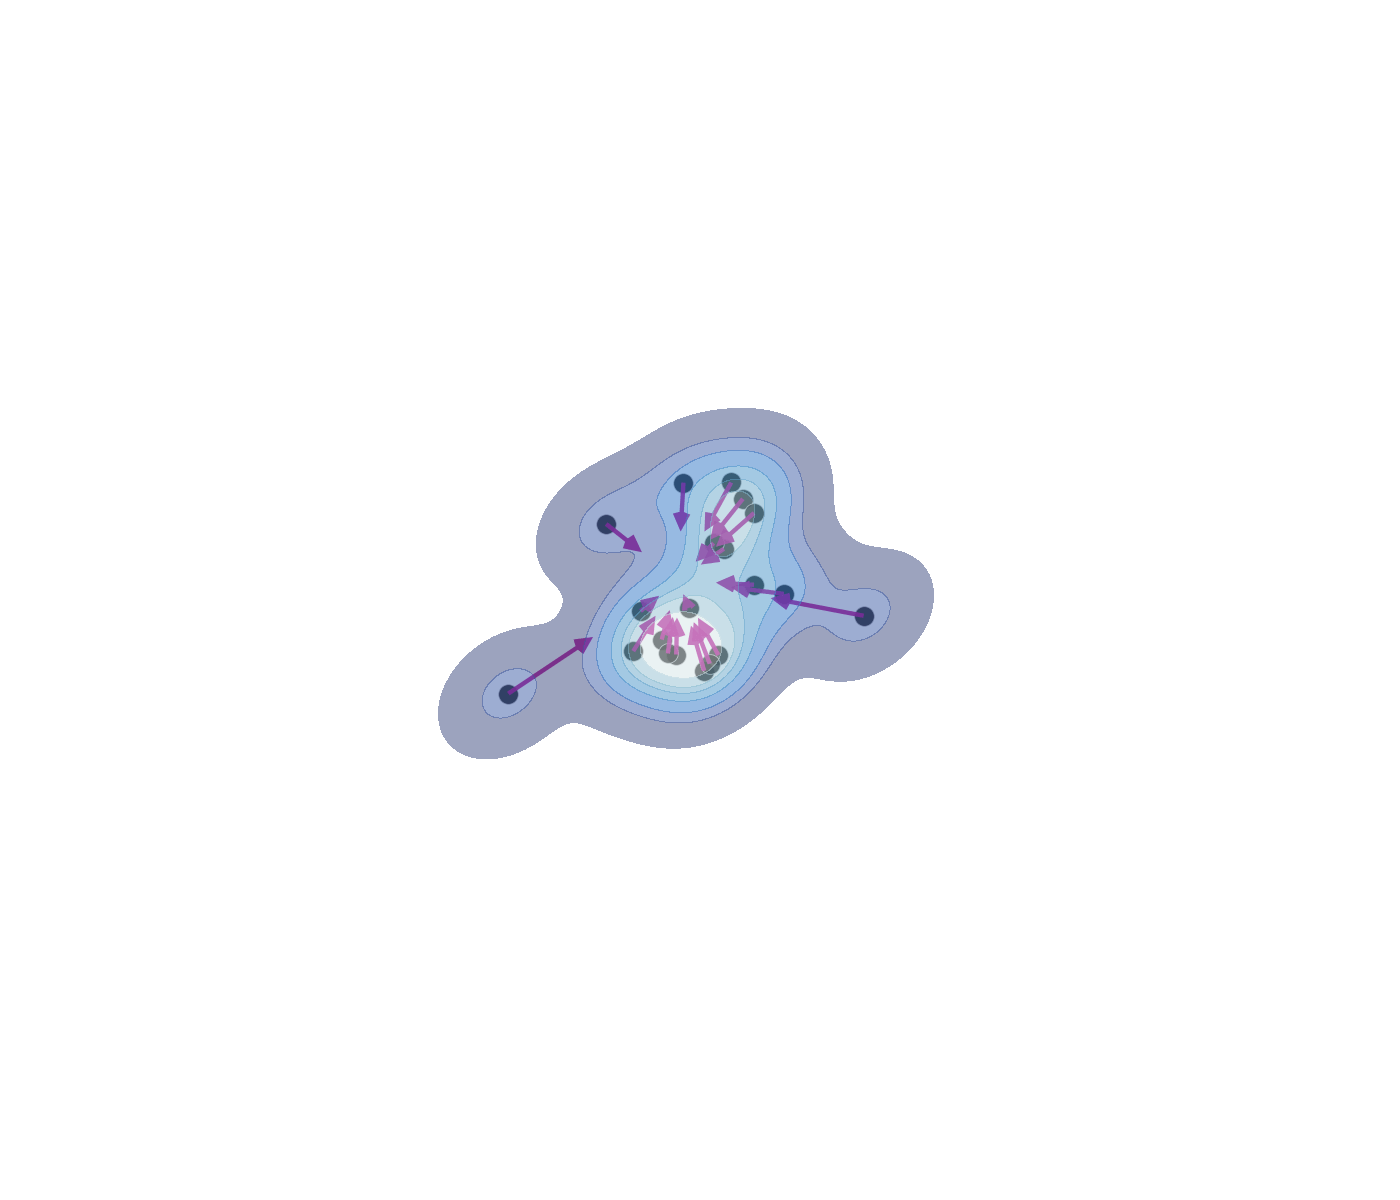
For instance for NPE:
Brehmer et al. (2018), Zeghal et al. (2022)
Dealing with Expensive Simulations
Implicit Inference methods with fewer simulations
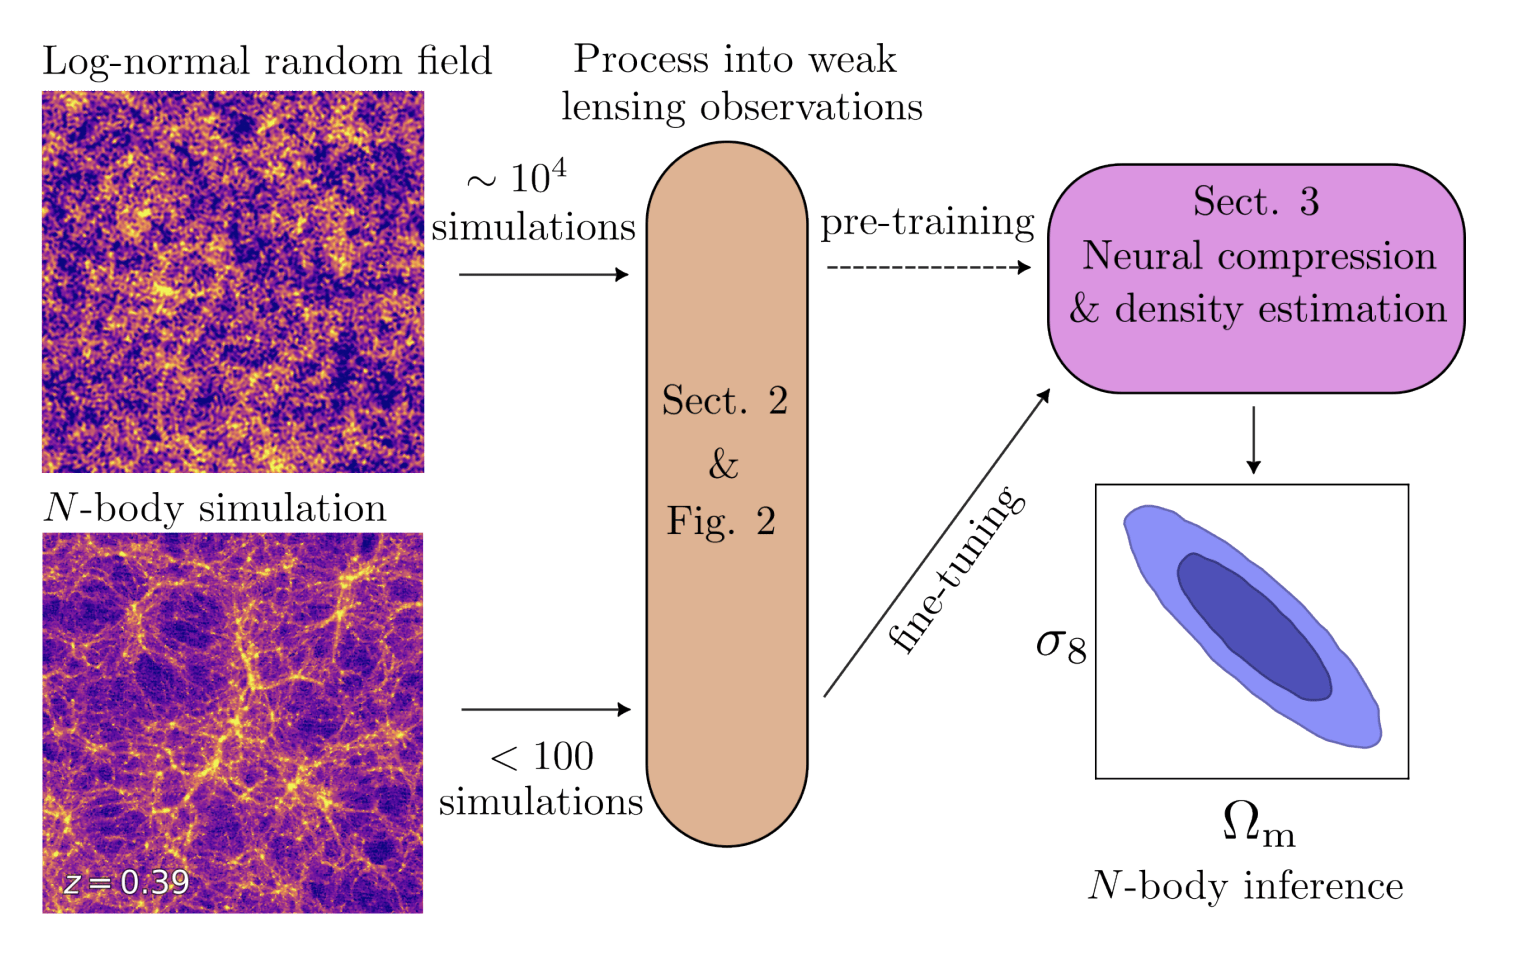
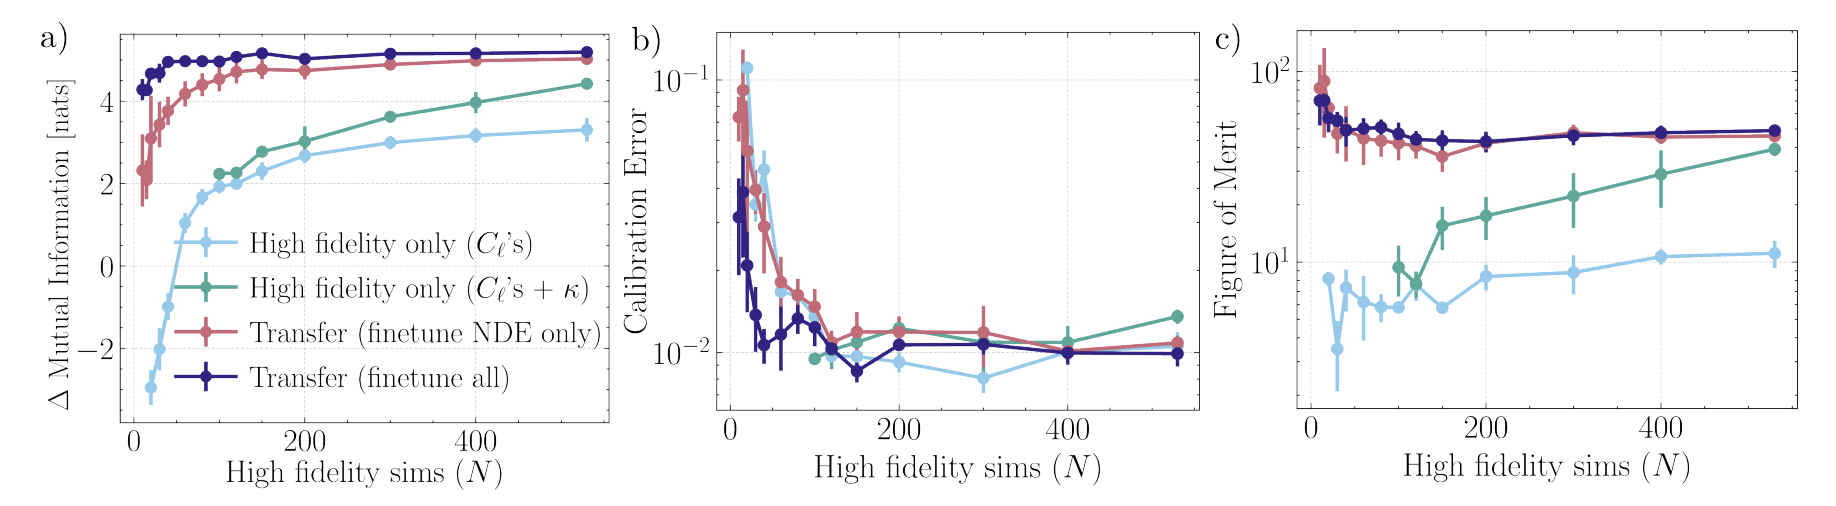
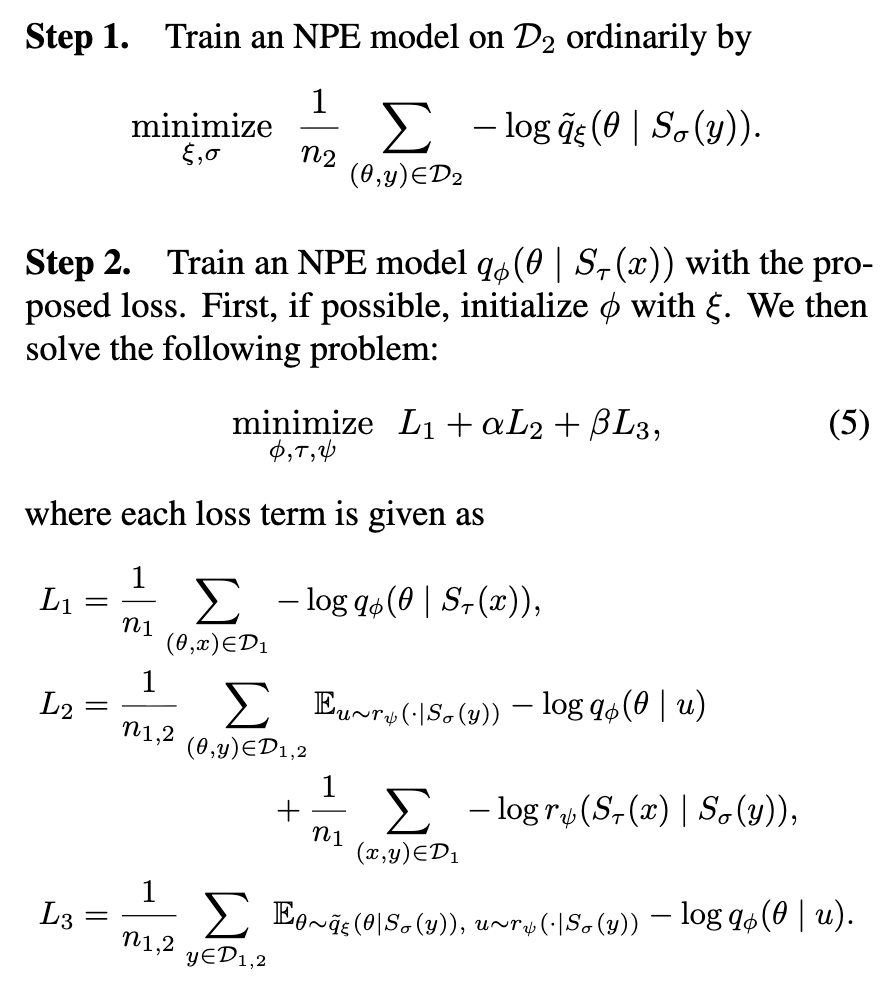
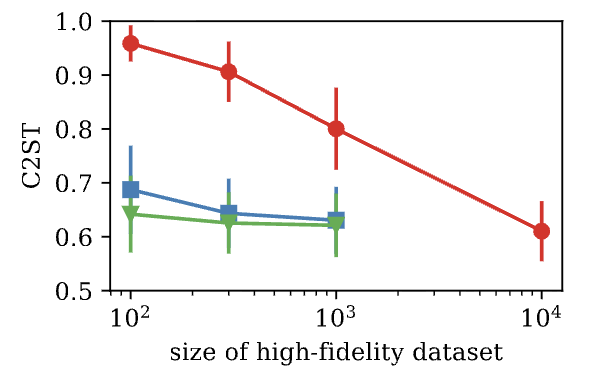
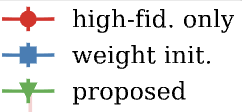
Multi Fidelity methods
For instance:
Dealing with Expensive Simulations
Emulating Simulations
For instance, we can learn the mapping between a cheap and a realistic simulation
Easier than learning the transformation from ICs
Easier than learning the transformation from ICs
Easier than learning the transformation from ICs
→ e.g. log-normal, LPT, PM
| O(ms) runtime | ✅ |
| differentiable | ✅ |
| realistic | ❌ |
Fast simulations
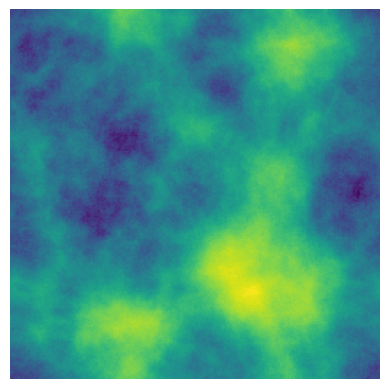
→ e.g. full nbody, hydro
Costly simulations
| O(ms) runtime | ❌ |
| differentiable | ❌ |
| realistic | ✅ |
f_\varphi
Trained under MSE
Dealing with Expensive Simulations
Emulating Simulations
\mathbb{E}_{p(x_1,x_0)} \Big[ \| \color{#b6008e}{f_\varphi} \color{black}{(x_0)- x_1 \|^2 \Big]}
p(x_1\mid x_0)
\color{#b6008e}{f_\varphi}^* \color{black}{(x_0)}
minimized by
\color{#b6008e}{f_\varphi}^* \color{black}{(x_0)=\mathbb{E}_{p(x_1\mid x_0)} [x_1] }
p(x_1 \mid x_0)
which is fine if, for instance , is a dirac
p(x_1 \mid x_0)
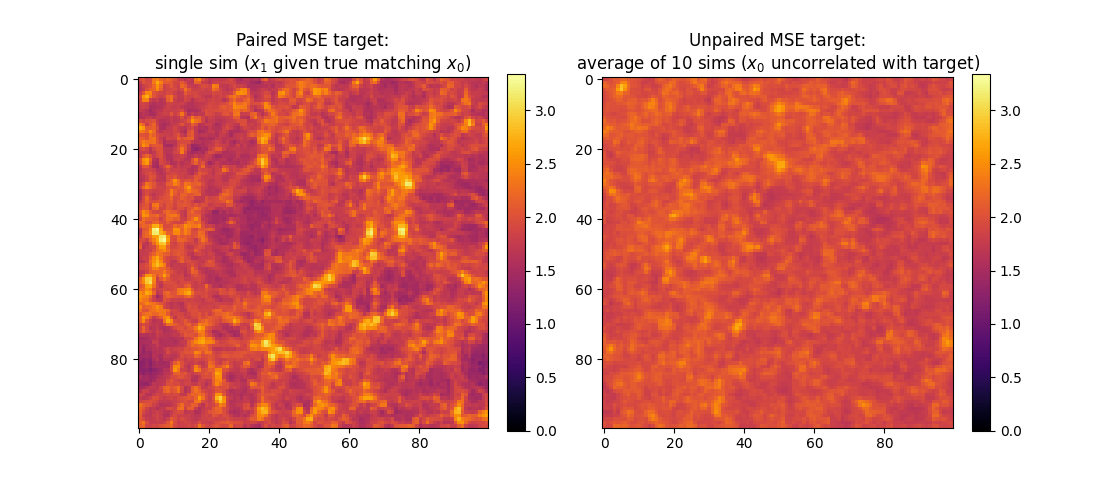
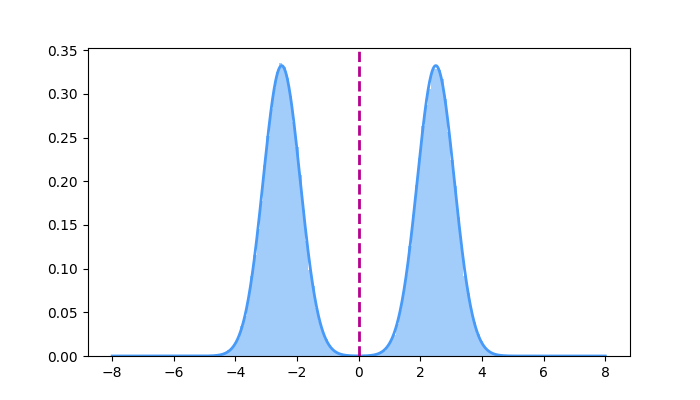
p(x_1\mid x_0)
when is not a dirac we can use generative models to get probable samples
x_1 \sim p(x_1)
Dealing with Expensive Simulations
Emulating Simulations
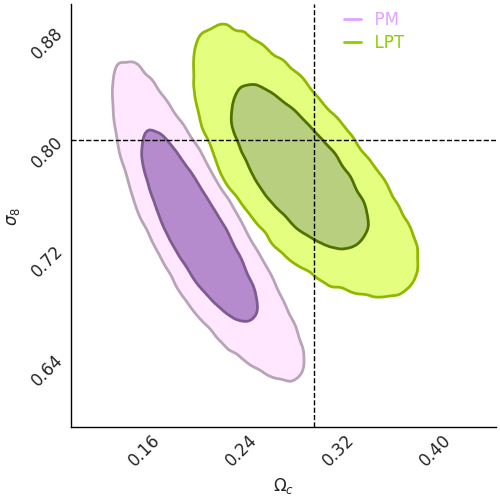
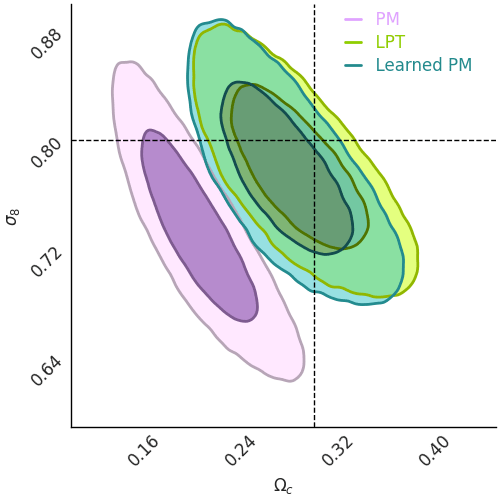
For instance, in Zeghal et al. (2025) we aim to approximate
p(x_1\mid \theta)
from unpaired simulations
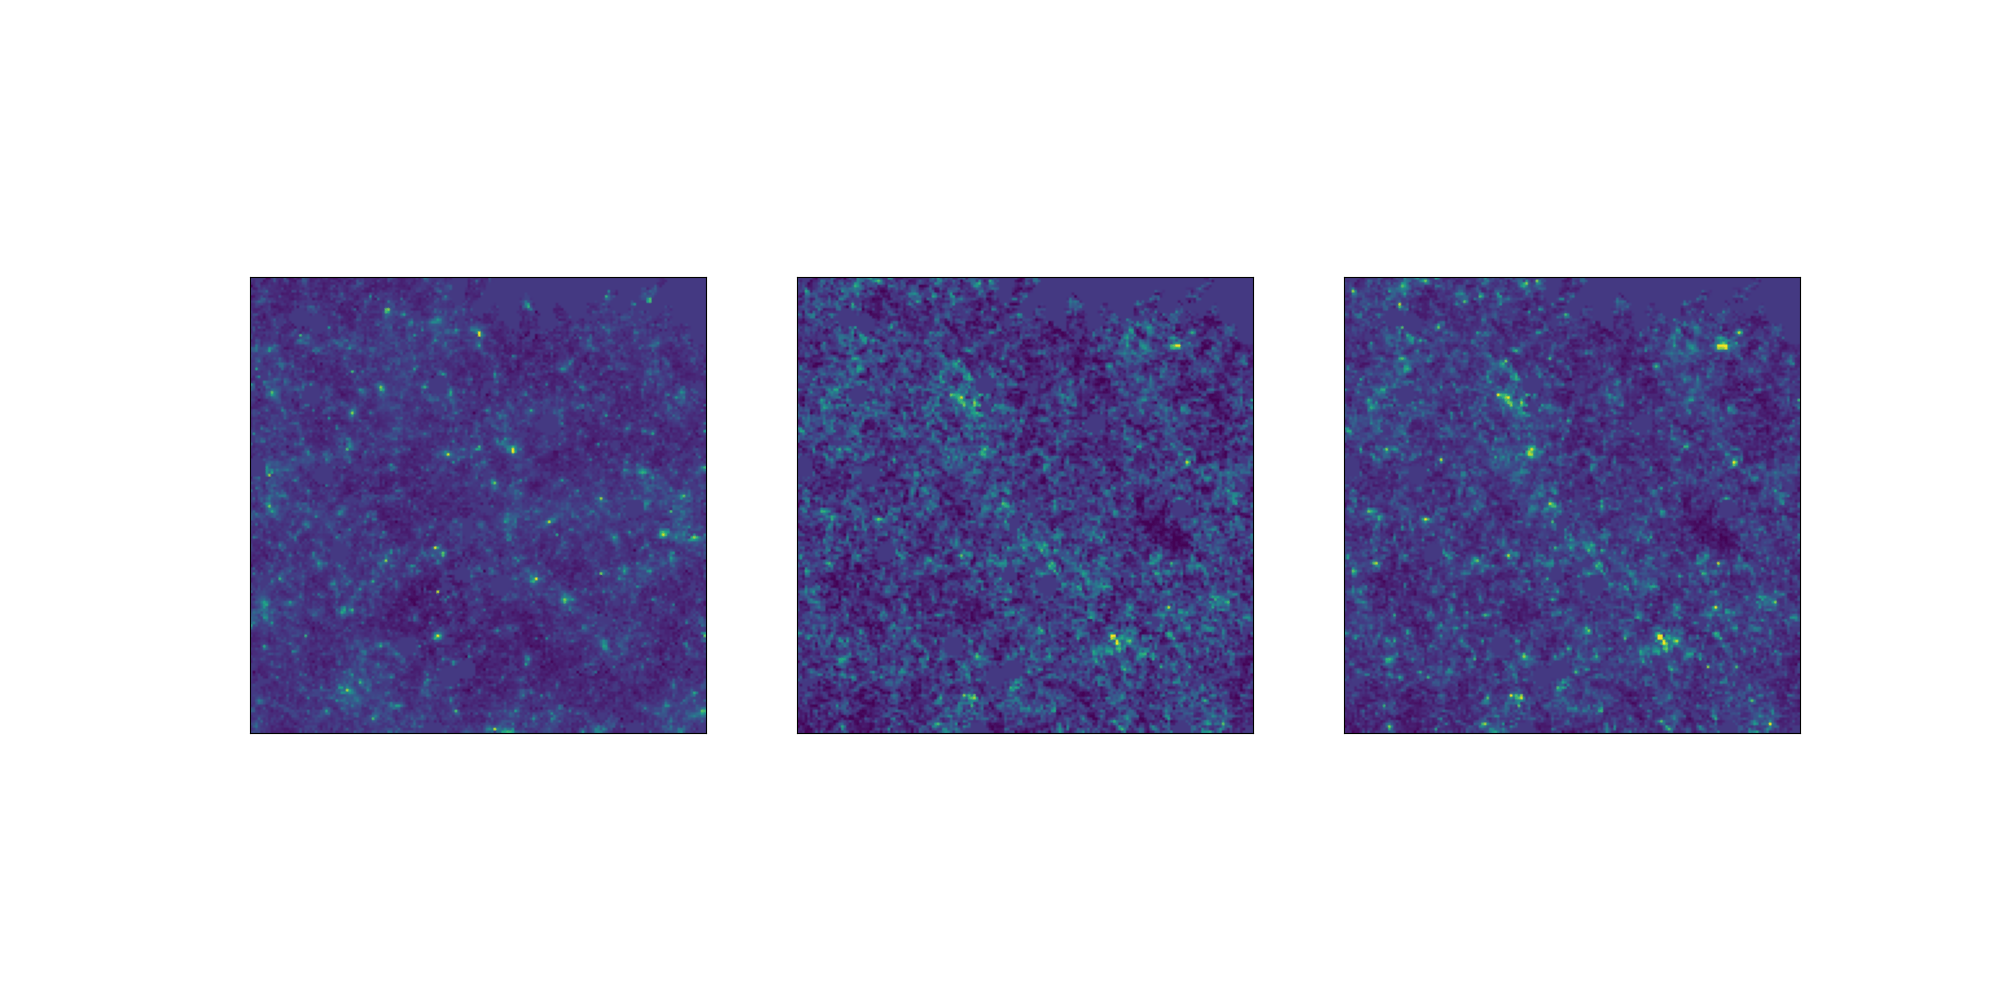
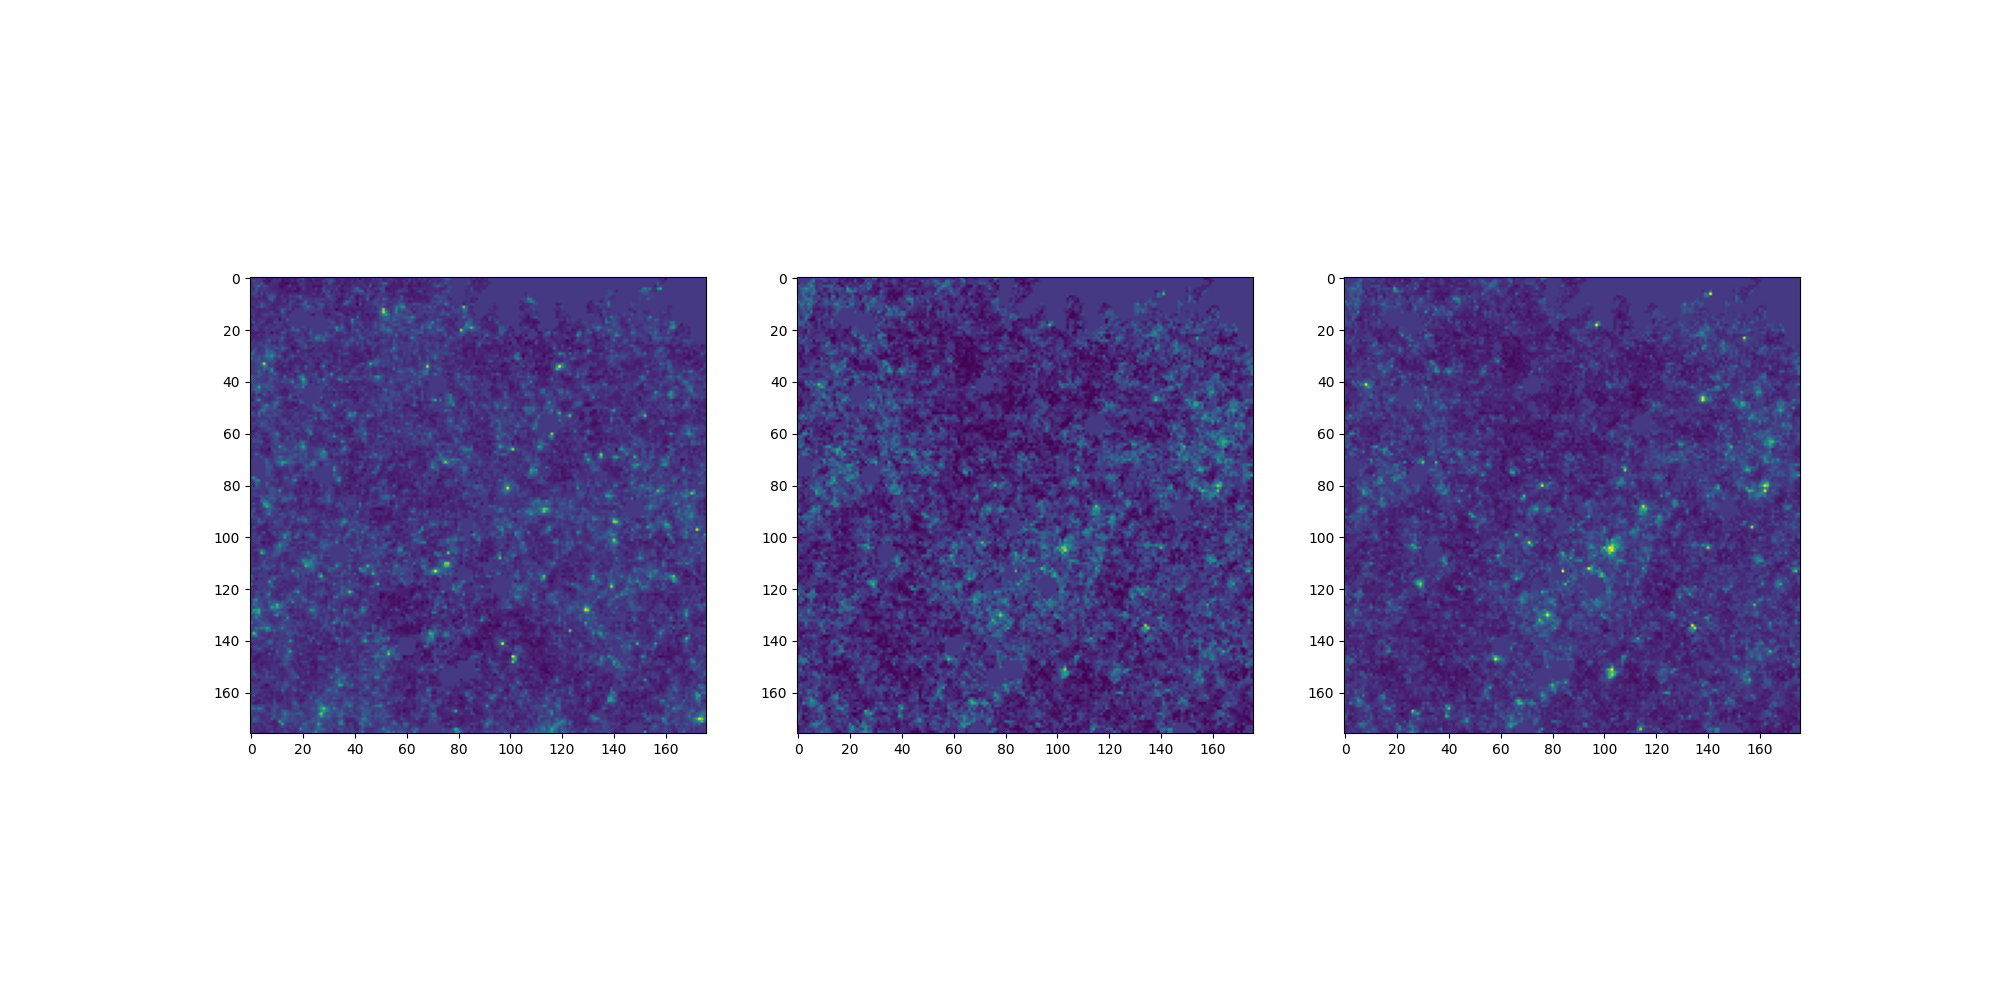
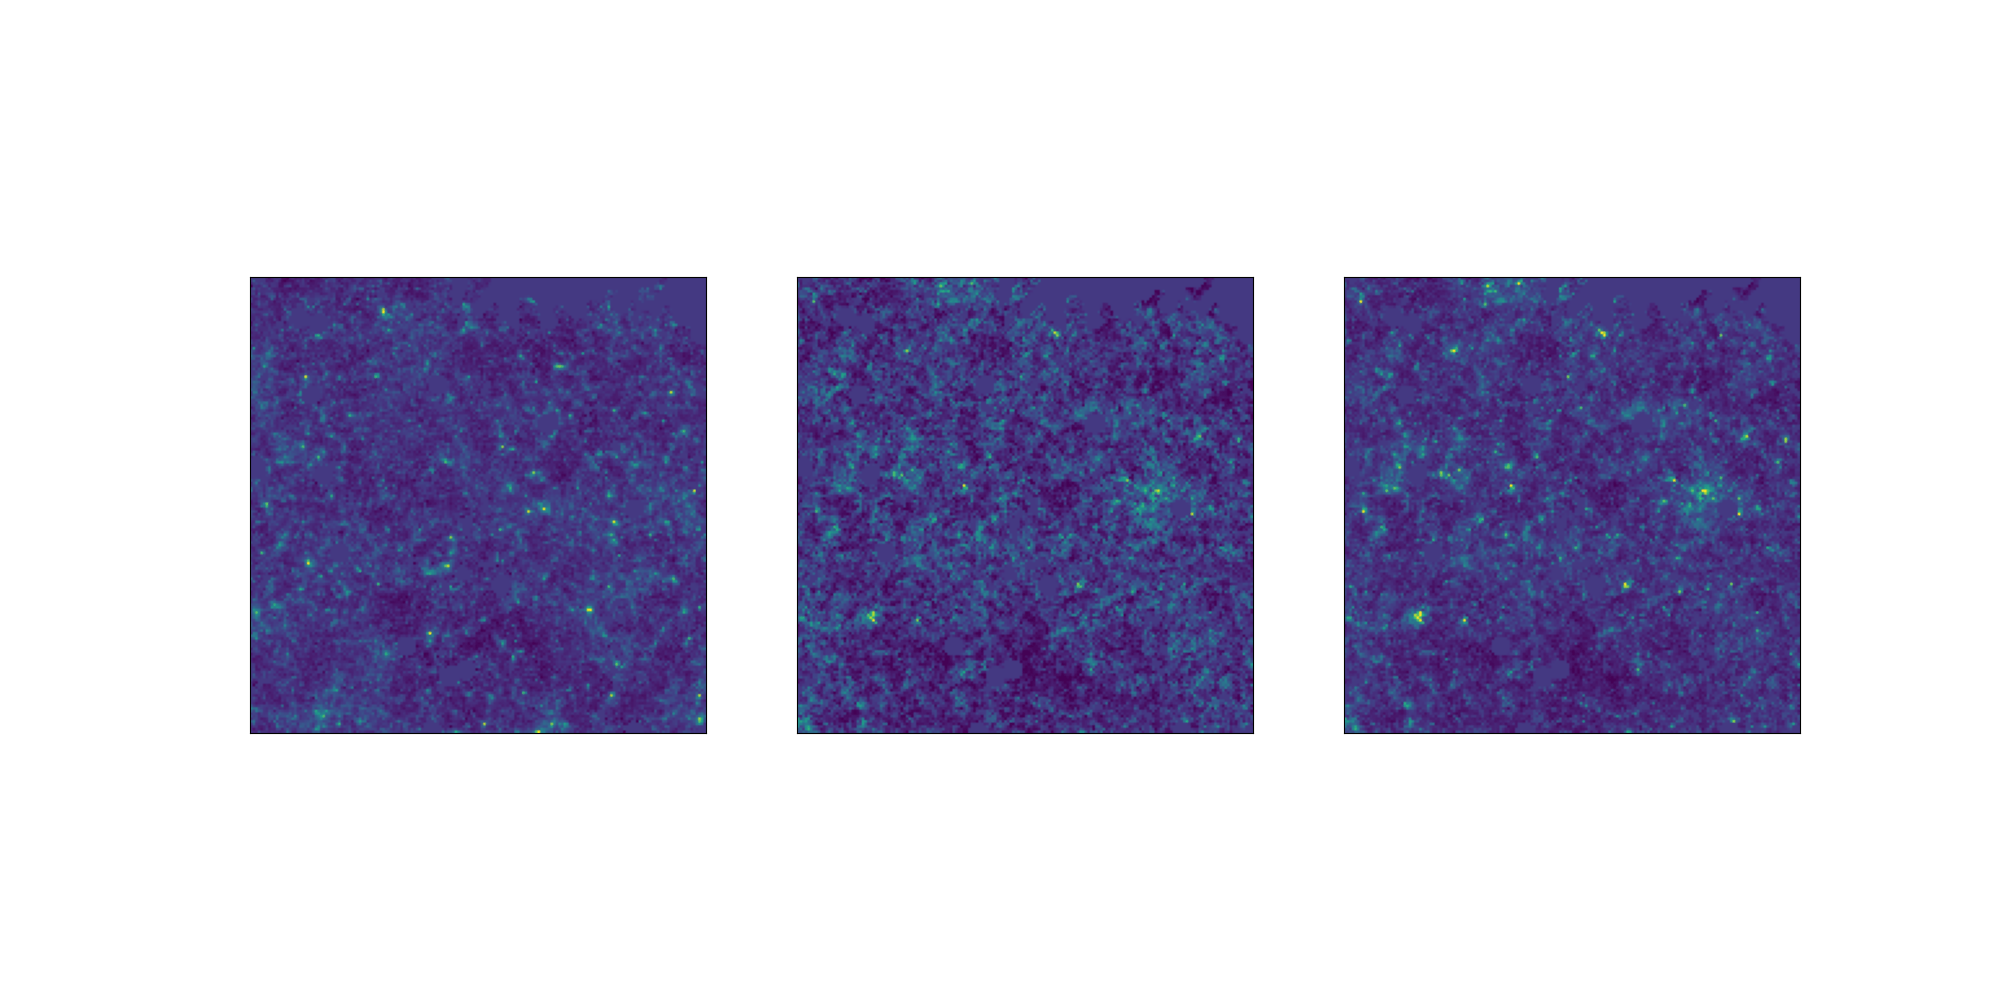
Dataset 1
Optimal Transport Plan
\pi(x_0, x_1)
Dataset 2
is not a dirac so we use Flow Matching
p(x_1 \mid x_0, \theta)
to train with fewer simulations, we employ OT to find the minimal transformation
x^A_0
x^B_0
x^C_0
\theta^A
\theta^B
\theta^C
\theta^C
\theta^A
\theta^B
x^C_1
x^A_1
x^B_1
Dealing with Expensive Simulations
Emulating Simulations
Dealing with Expensive Simulations
Emulating Simulations
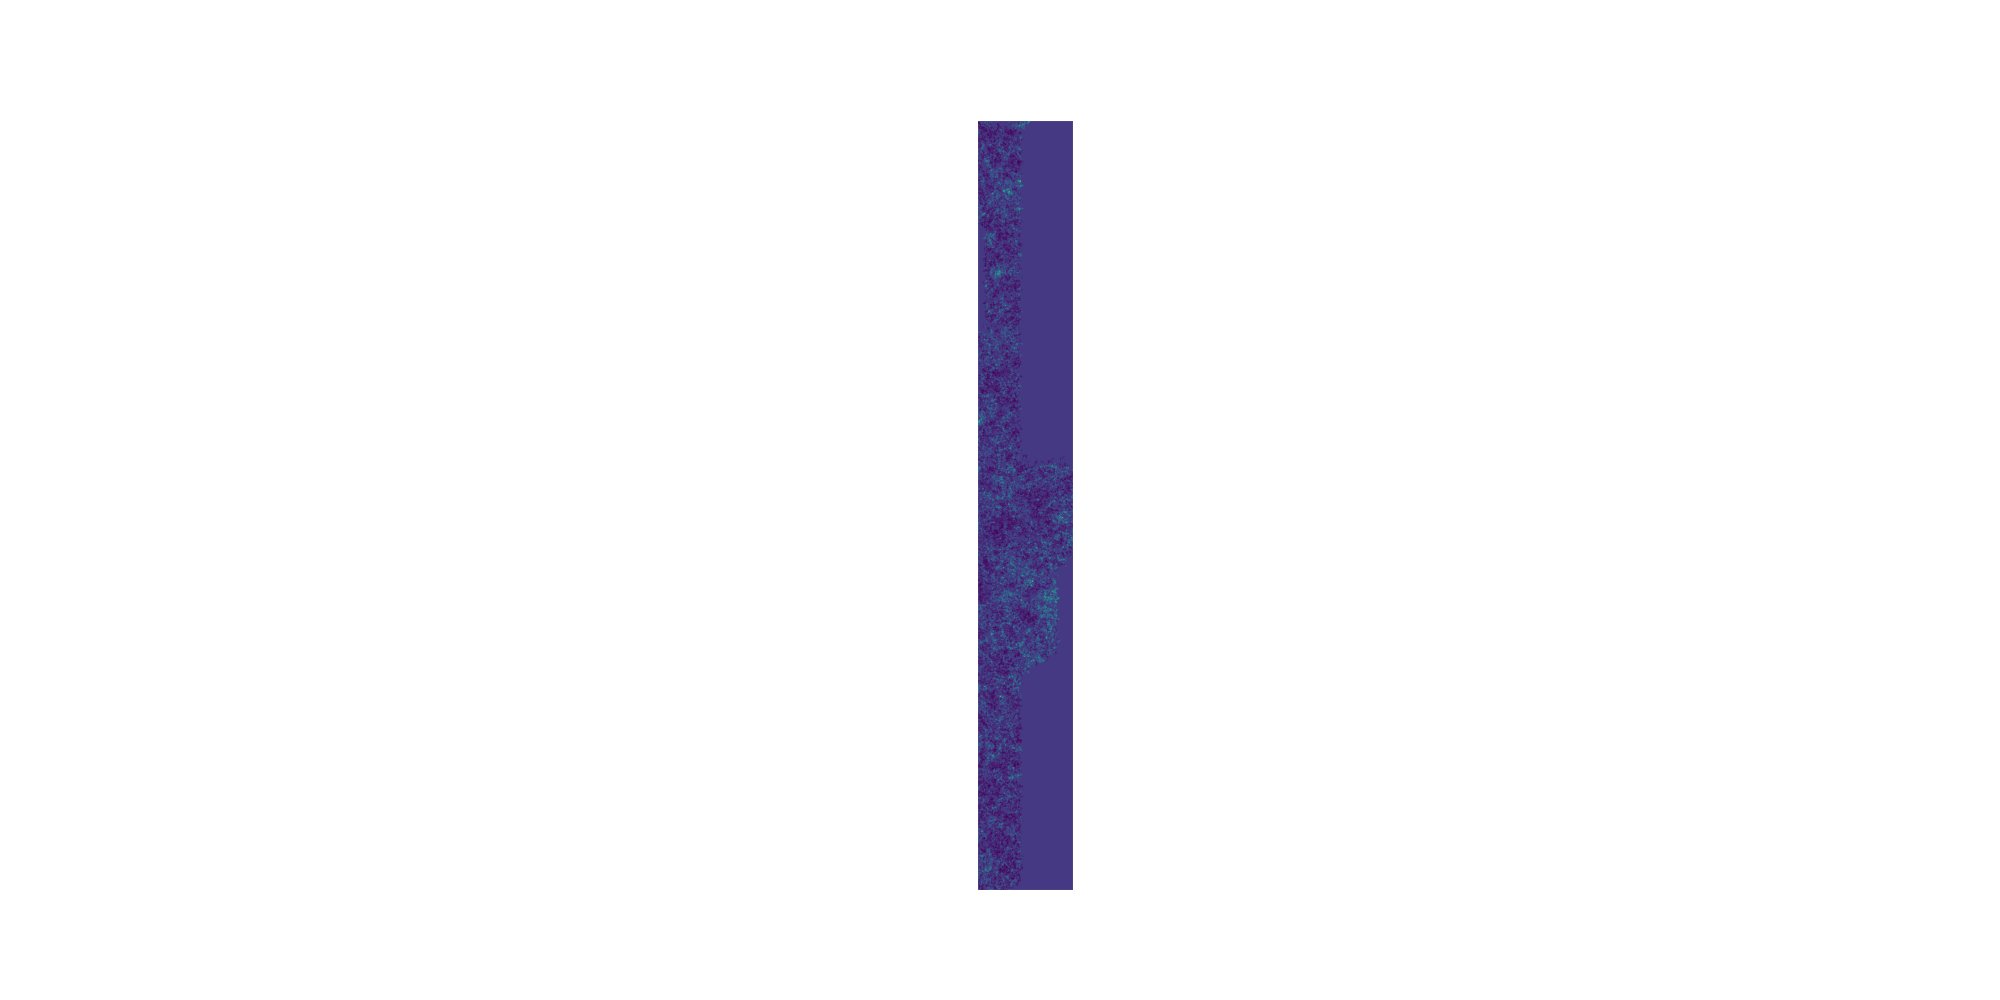
LogNormal
Emulated
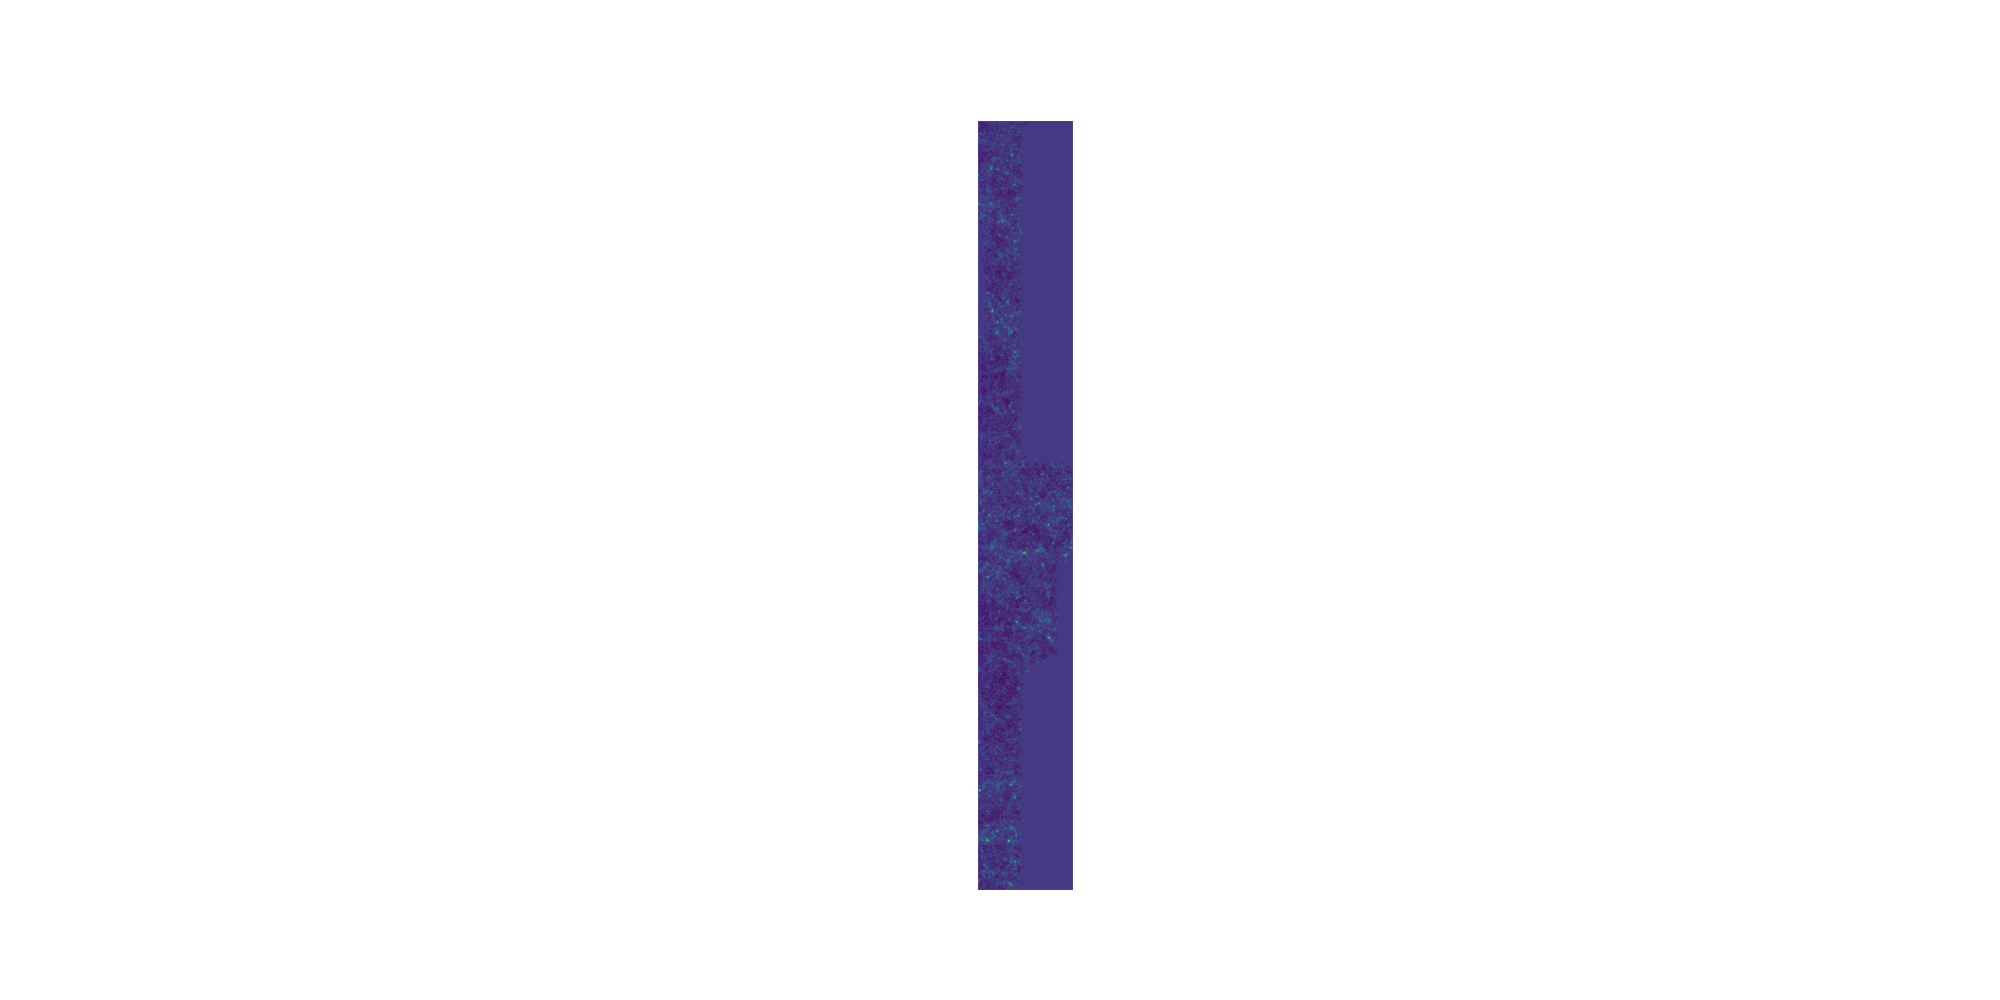
Challenge simulation
VS
🥳
ML is already reshaping the way we analyze data
Thank you for your attention!
Cosmology From Home 2026
By Justine Zgh