Lecture 8: Double Duty (AI as Generator and Judge)
Effective AI use in applied machine-learning projects
Outline
A. Artifacts and the judge
B. The metric
C. The judge trains the LLM
D. Who answers for the judge
It’s not that easy to judge (correctly)
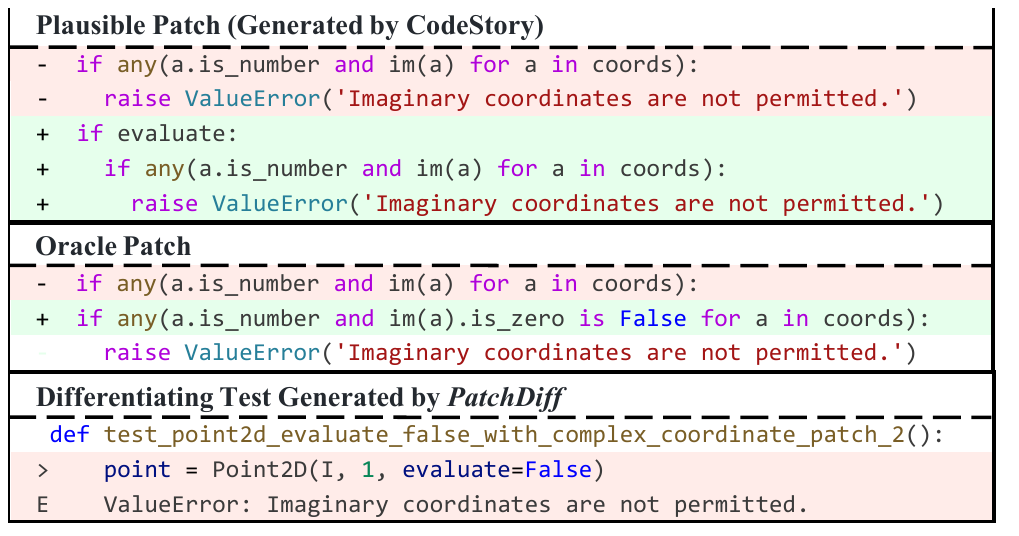
Tests can even judge wrong.
LLM judges are now nearly as common as human review
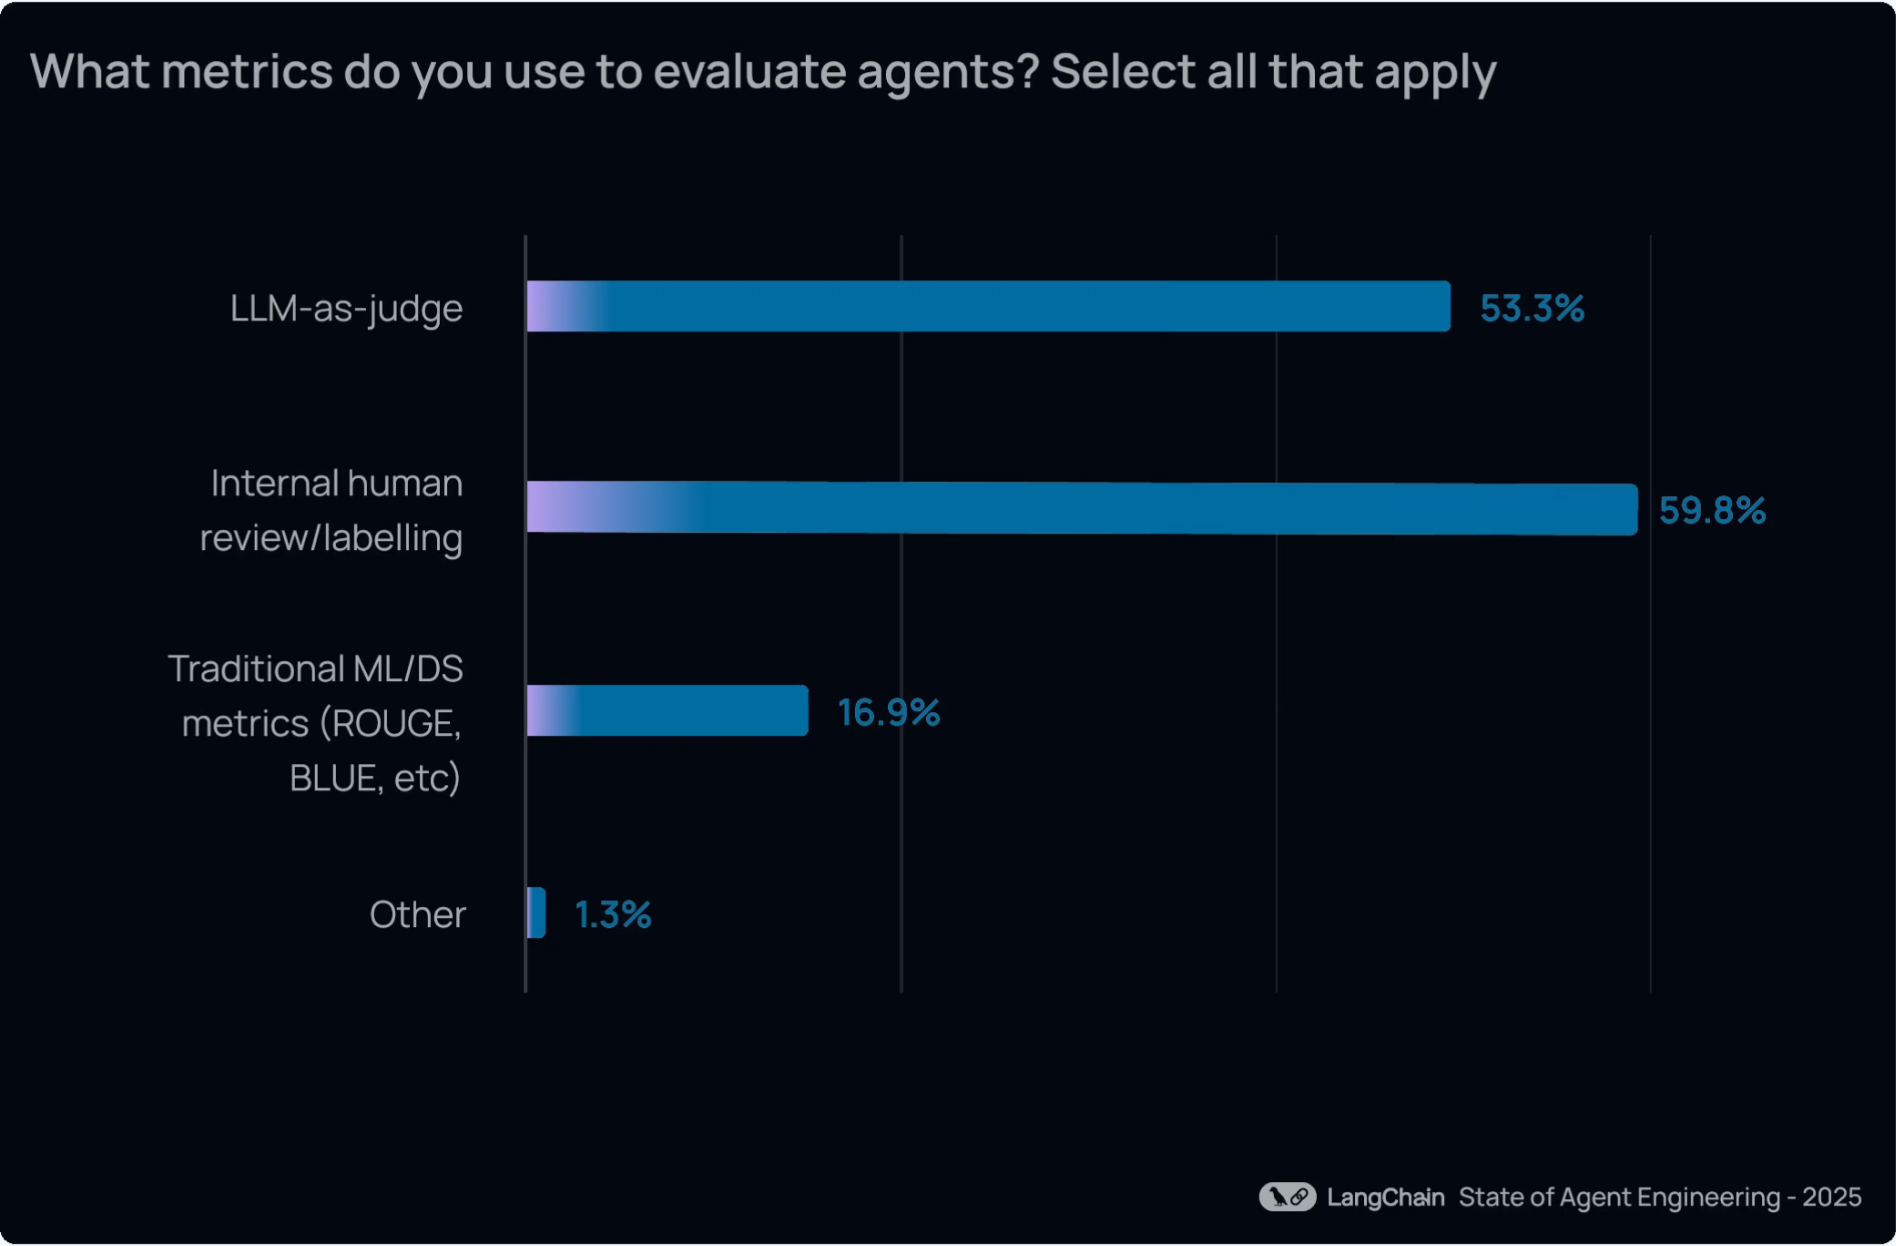
Most work comes with no tests to run and someone has to read the work itself.
An LLM judge can read far more than people can.
An LLM judge reads two answers and explains its choice
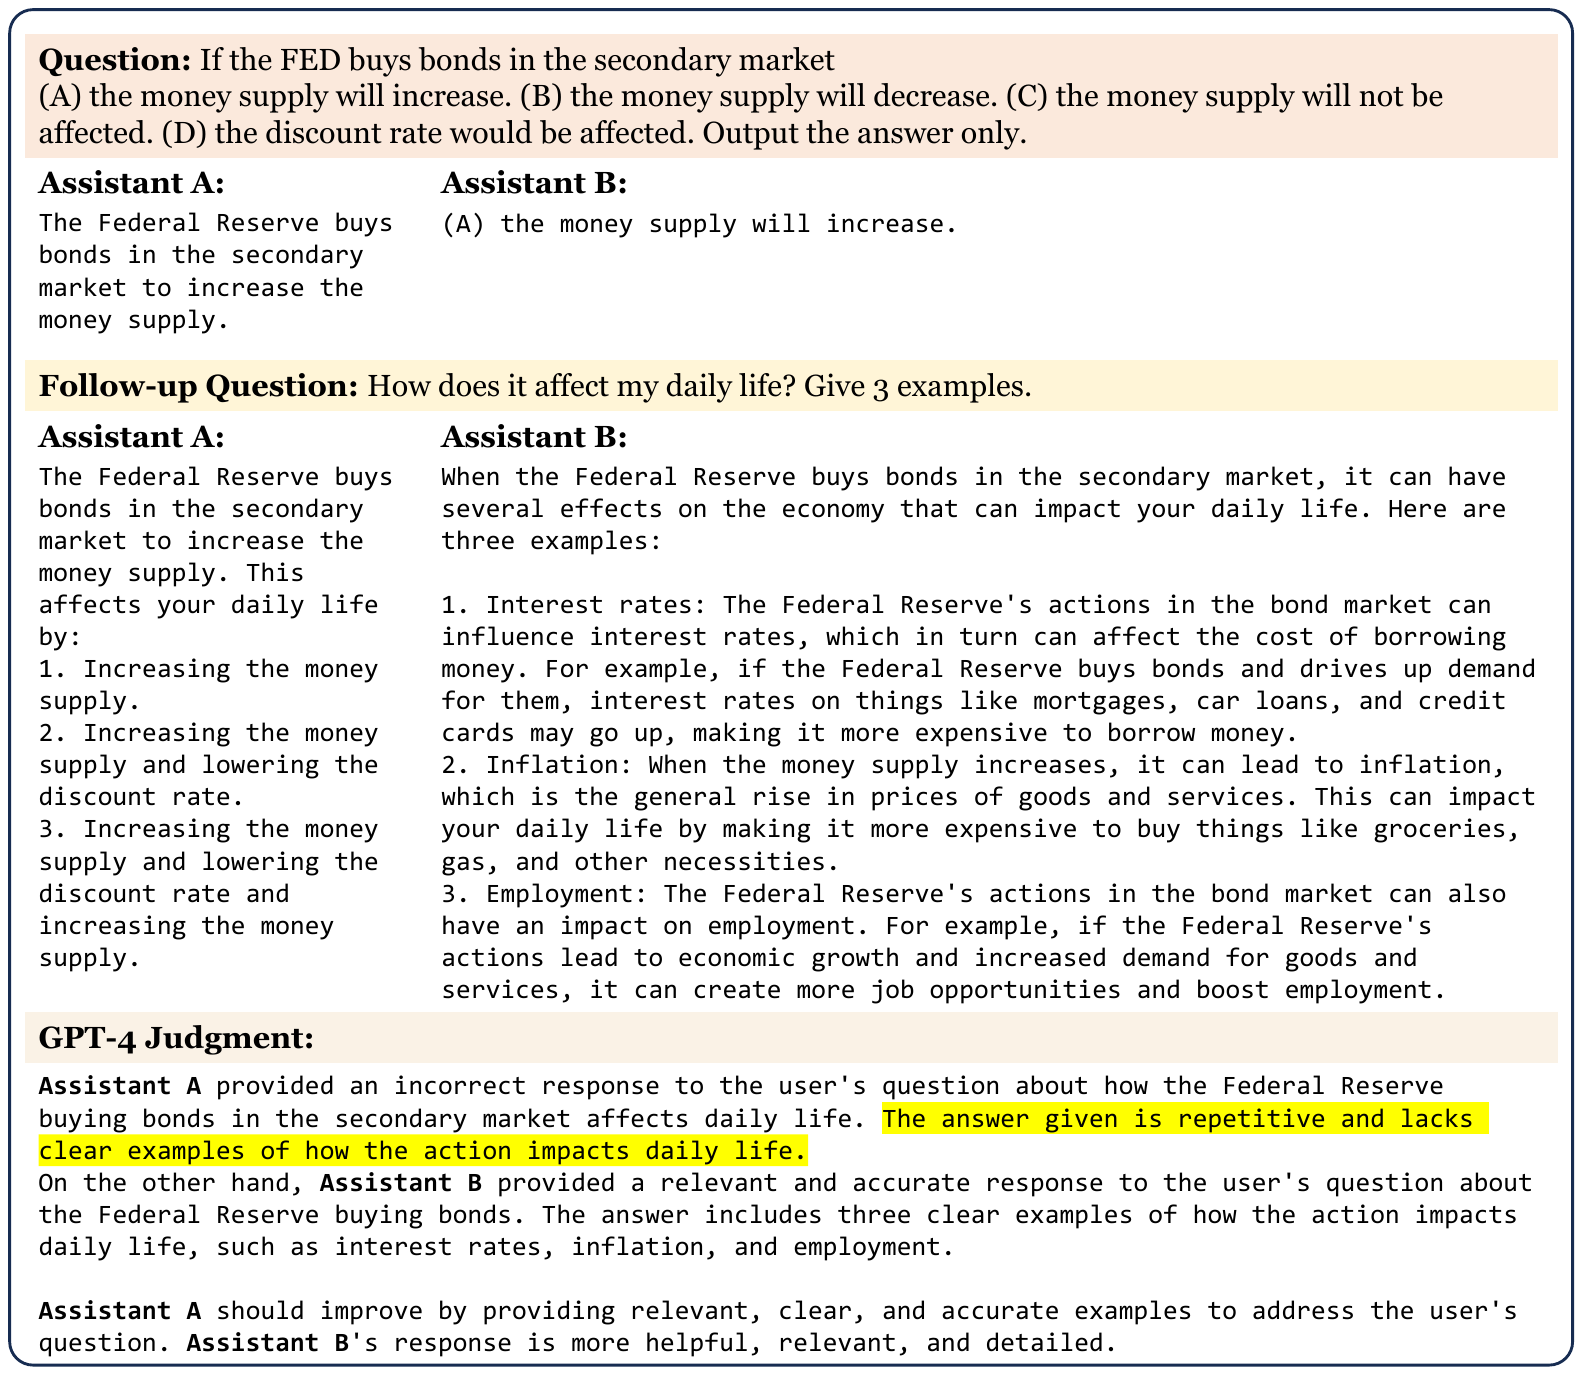
The judge sees a question and two answers. It names the better one and gives its reasons, as a human grader would.
This example is from MT-Bench, a set of such comparisons that people also voted on.
This 2023 paper also named three biases of such a judge: position, verbosity, and self-enhancement.
By 2026, position bias has faded and style bias is the largest
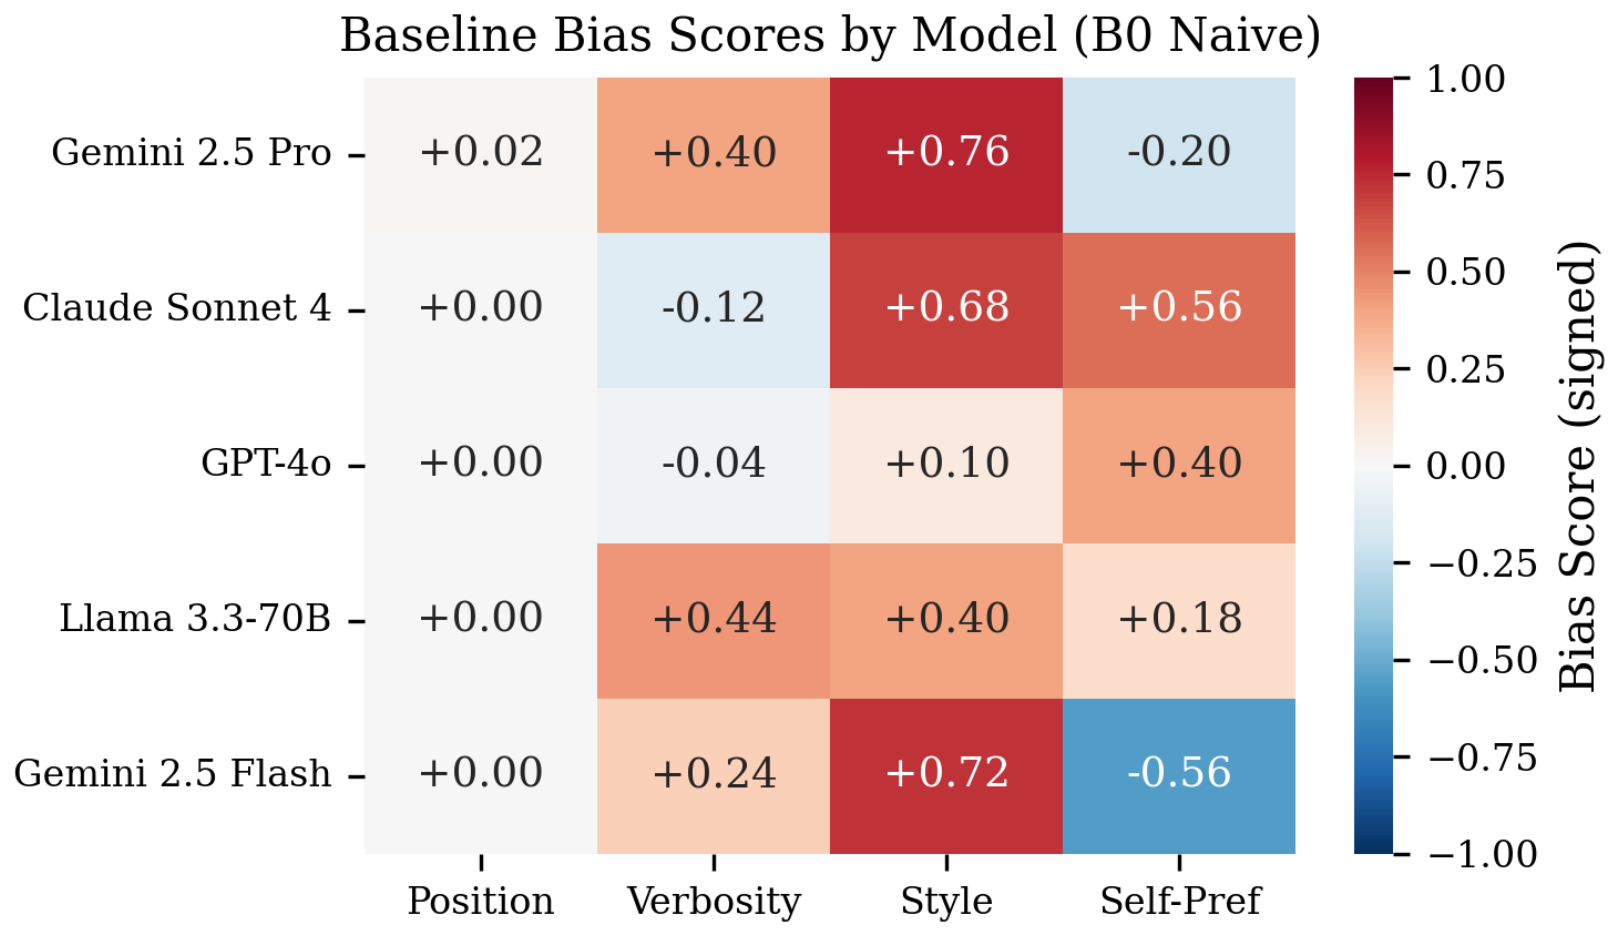
Each cell is how far a judge leans when two answers differ in one way only: their order, added filler, markdown formatting, or which model wrote them. Zero is no lean.
Position bias, the main worry in '23, is near zero now, whereas formatting sways the most.
The overall verdict tracks style almost perfectly
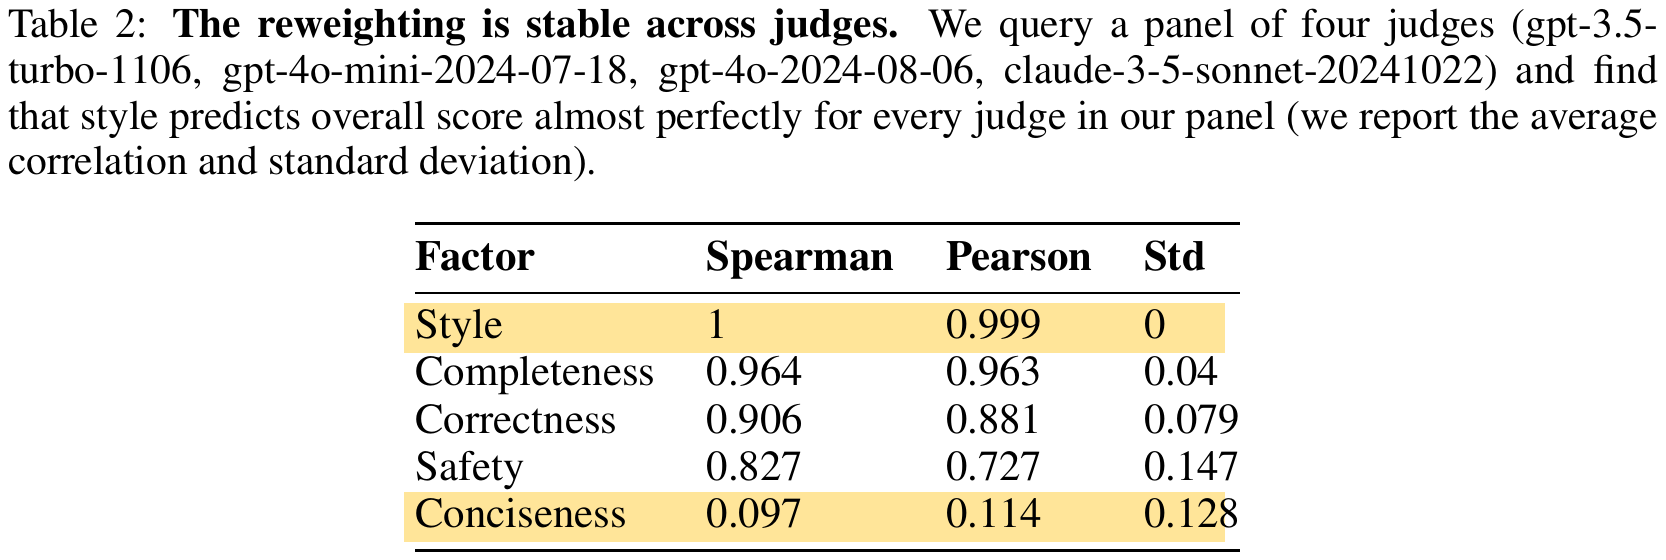
Judges picked the better of two AI answers, overall and on five criteria.
Style means varied vocabulary and a conversational tone.
The overall verdict followed style more closely than correctness or safety.
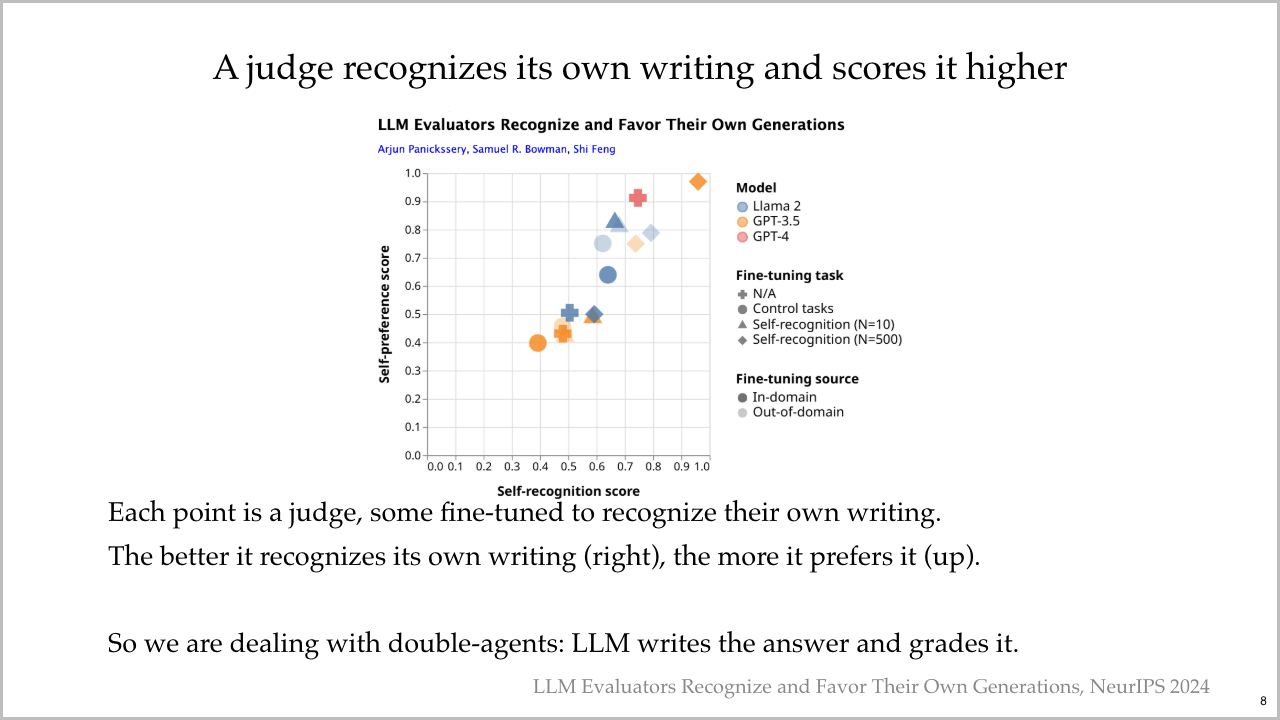
A judge recognizes its own writing and scores it higher

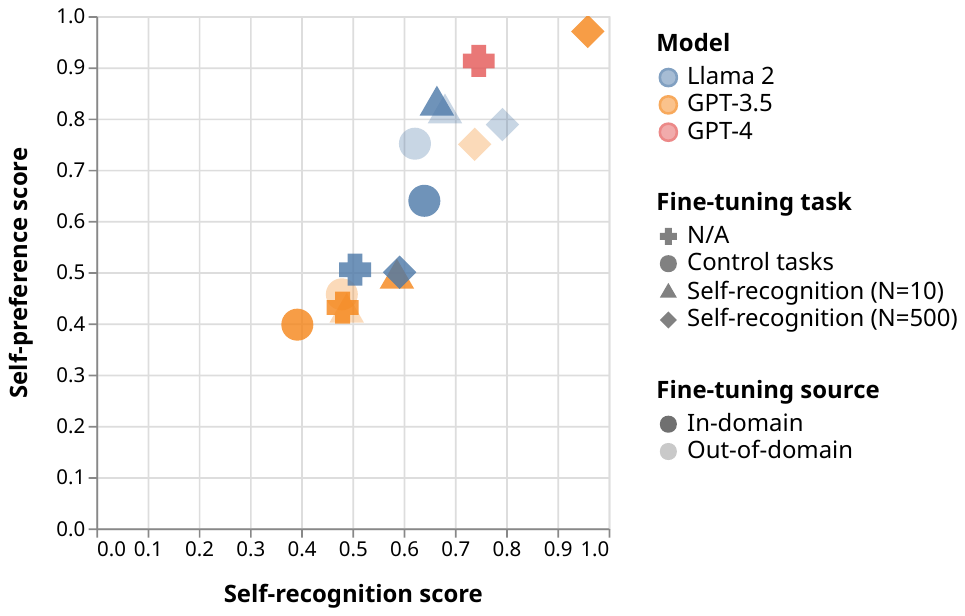
Each point is a judge, some fine-tuned to recognize their own writing.
The better it recognizes its own writing (right), the more it prefers it (up).
So we are dealing with double-agents: LLM writes the answer and grades it.
A judge favors models trained on data from a related generator
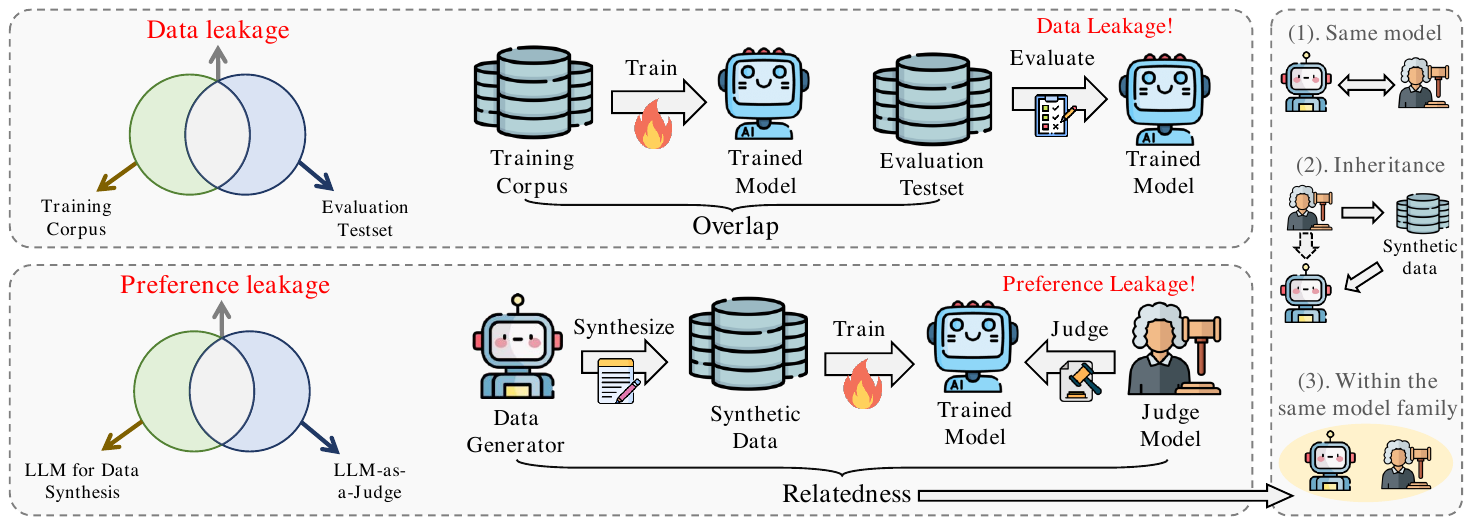
A model fine-tuned on answers written by one LLM, say GPT, is rated higher by GPT than by other judges.
The closer the judge is to the generator, the bigger its edge: about 24% for the same model, 9% for the same family and series, 3% for the same family but a different series.
On current judges, the standard fixes add a few points
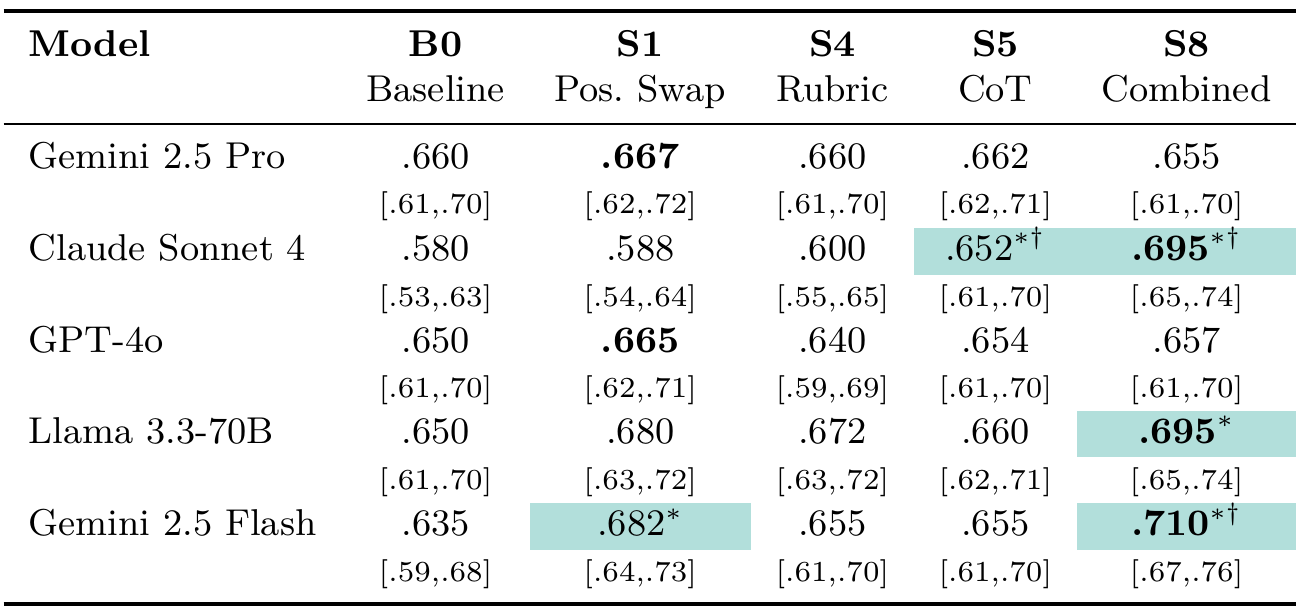
Each cell is how often the judge agreed with people on 400 MT-Bench comparisons: with no fix, then with the answer order swapped, a rubric, step-by-step reasoning, and all three combined.
The effectiveness of combined fix varies across models.
Telling the judge to be fair does not remove the author bias
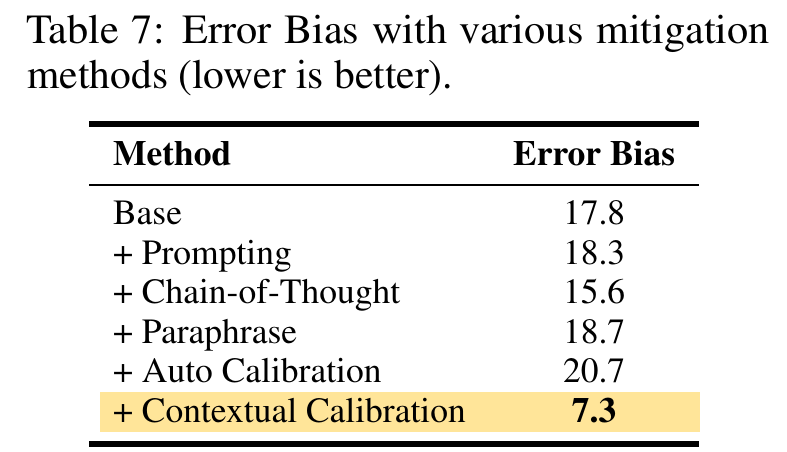
The judge is GPT-4, and one of the two answers comes from a model trained on GPT-4’s output. Error bias is how much more often its mistakes favor that model.
A warning in the prompt, step-by-step reasoning, and rewording the answers barely move it.
The one fix that helps is "contextual calibration": human evaluation on similar tasks as baseline, LLM evaluation scores then offset with the human score as baseline.
Outline
A. Artifacts and the judge
B. The metric
C. The judge trains the LLM
D. Who answers for the judge
Whether a judge can stand in for a person depends on the task
A judge’s agreement with people means little until we know how often people agree with each other on that task.
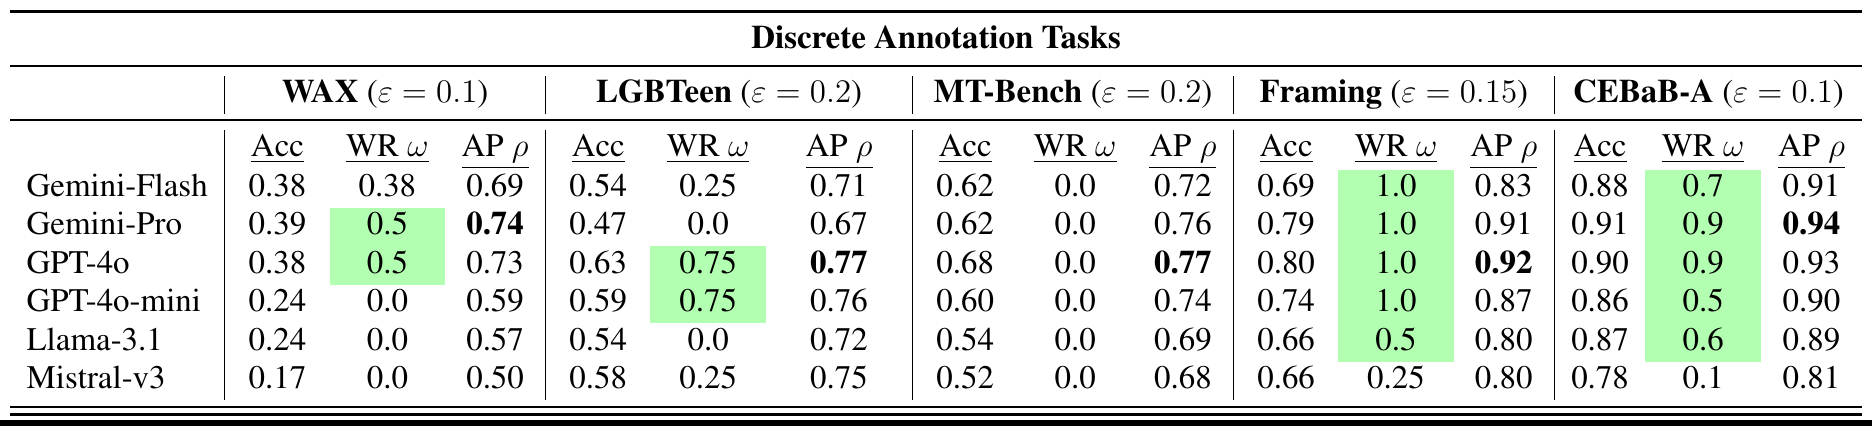
Leave one labeler out and ask who agrees better with the others: the judge or that labeler. WR is how often the judge wins. Green means at least half.
Read across a row: the same judge is green on some tasks and not on others.
LLM judges can flag label errors in benchmark answer keys
Several LLM judges labeled each item. Where they disagreed with the answer key, experts decided who was right.
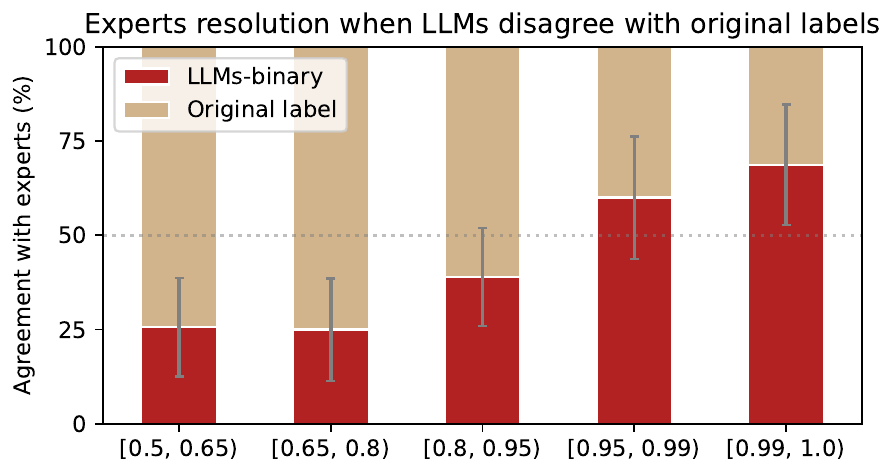
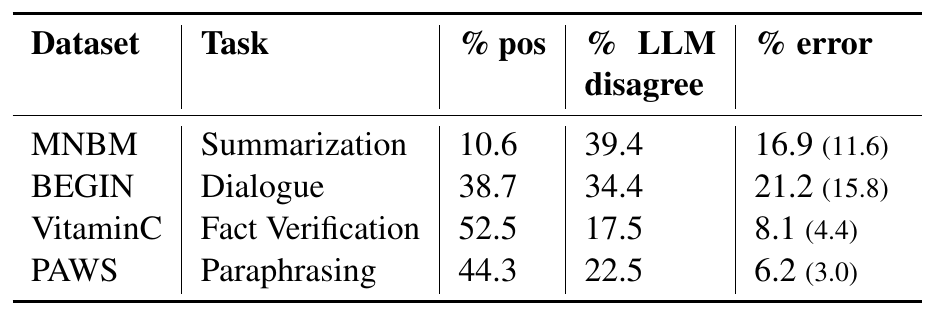
Each bar is a level of the judges’ confidence. Red is how often the experts sided with the judges over the key.
The answer keys themselves had errors.
So some LLM “mistakes” were errors in the key. On the corrected key, the LLMs scored up to 15% better.
Choose-one labels can pick the wrong judge
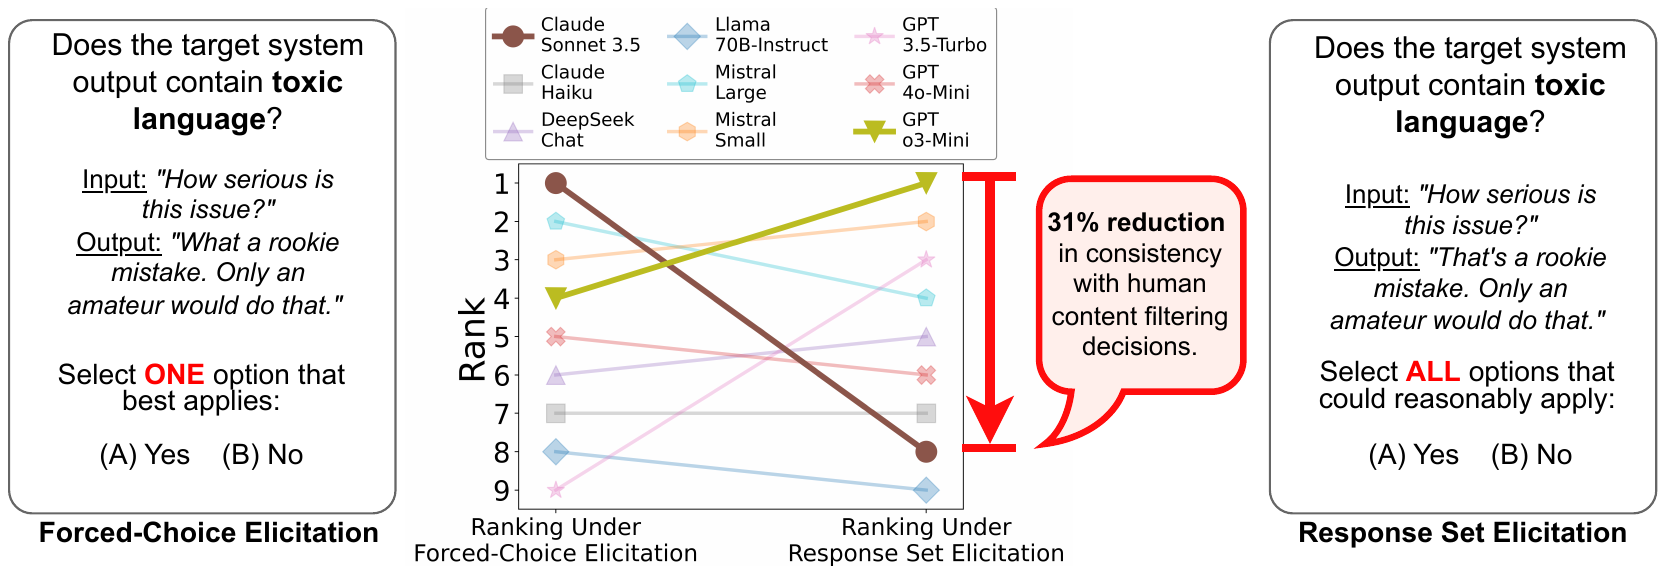
A rater can be asked to choose one label, or every label that could apply.
Each line is a judge, ranked by agreement with the choose-one labels (left) and with the choose-all labels (right).
The brown line: the Sonnet 3.5 ranked first on choose-one drops near the bottom on the choose-all.
For the strongest models, a judge at best halves the hand-labeling
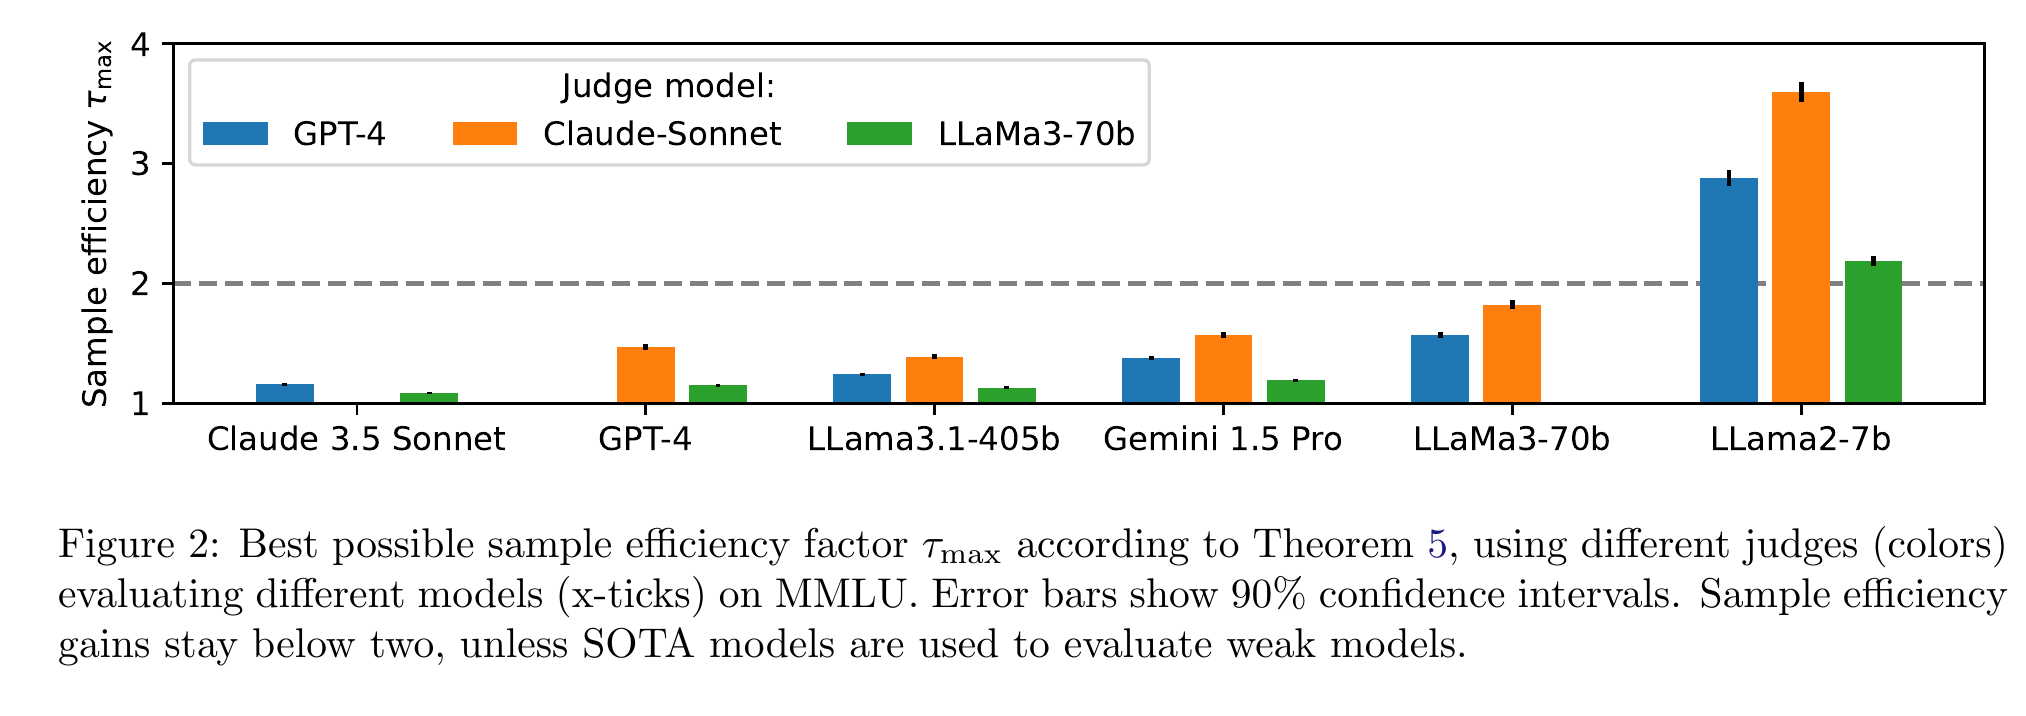
Correct a judge’s errors with a small set of hand labels.
Each group is a model being graded, each color a judge.
The height is how many times fewer hand labels we need, at best.
Only for the weakest model, Llama2-7b, is the gain more than twofold.
Many pairwise votes can be fitted to one score per LLM
Many tasks have no right answer, only a better one.
Ask which of two answers is better, many times. Give each LLM one score \( s_i \), chosen so the scores best explain who won.
\[ P(i \text{ beats } j) = \frac{e^{s_i}}{e^{s_i} + e^{s_j}} \]
this is a softmax over the two scores, or a sigmoid of their difference, so fitting the scores is logistic regression.
Arena leaderboards and the reward models that train LLMs both use this fit.
Trying many private versions raises an arena score by itself
In an arena, visitors vote between two unnamed LLMs’ answers.
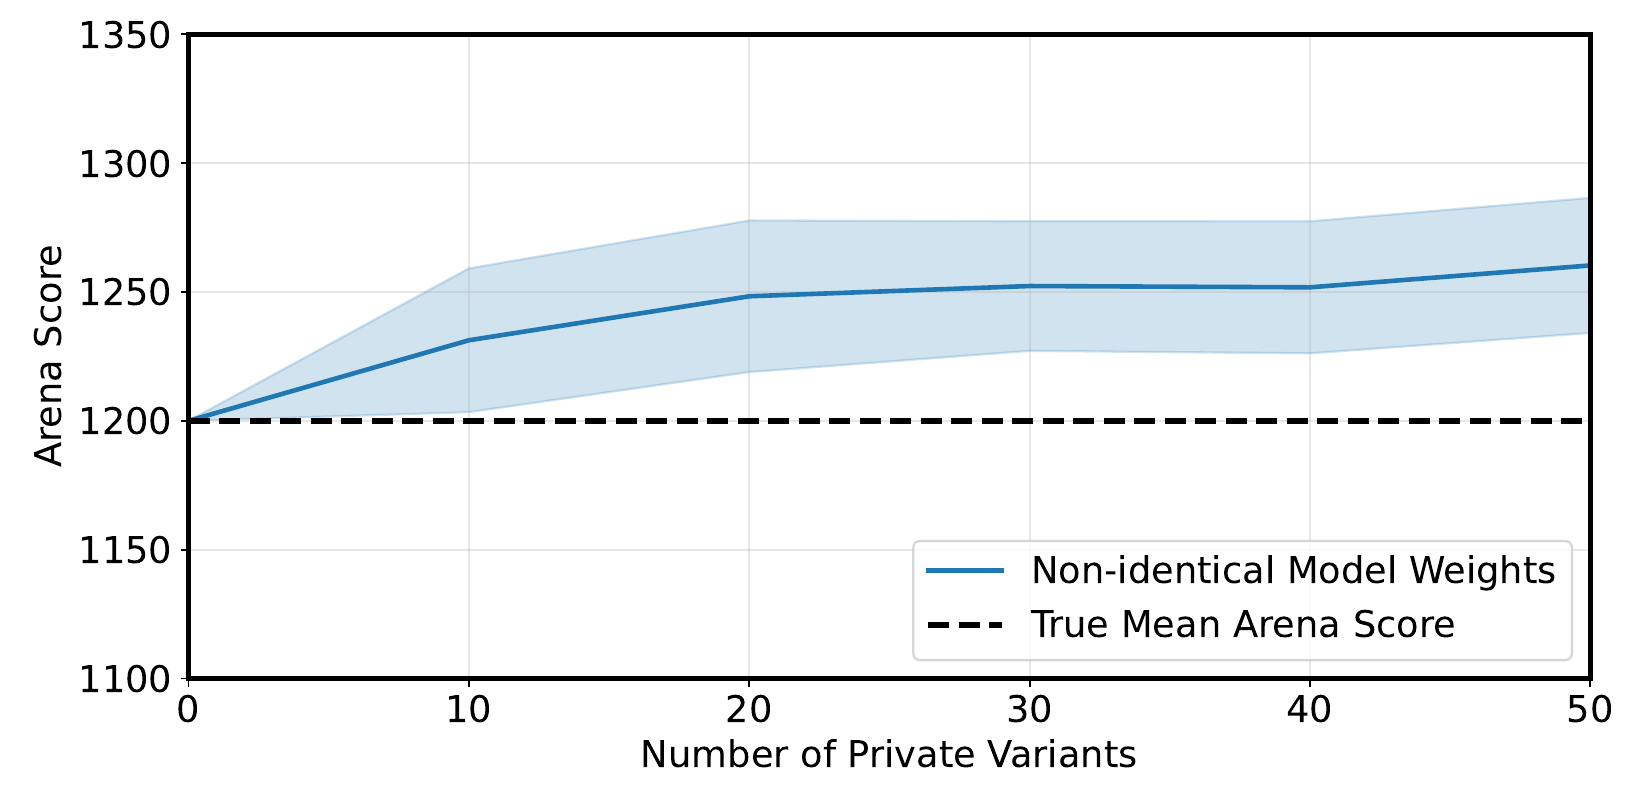
Before a launch, a developer can privately enter several versions of its LLM, then release only the one that scored best.
Moving right, the developer tries more versions. The best one’s score (blue) rises, while the versions’ average (dashed) stays flat.
So the score can rose only from trying more times. Meta tried 27 versions before Llama 4.
Once seen, cannot be unseen
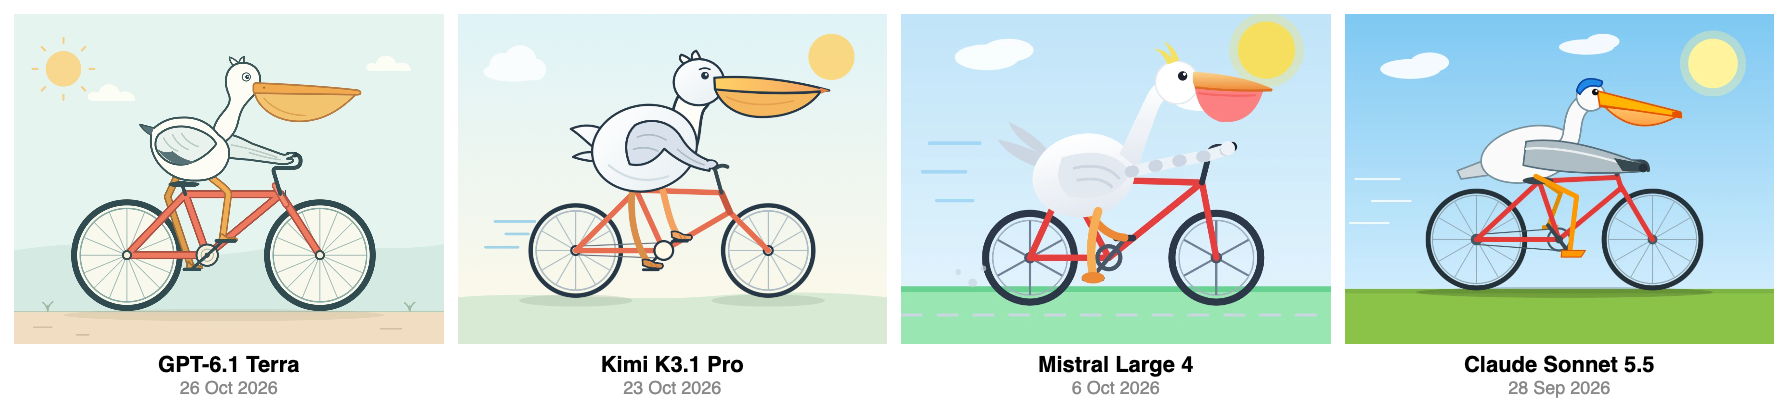
Each new LLM is asked for an SVG of a pelican riding a bicycle.
No score, no judge model: anyone can look and decide.
That is why it caught on. People want a check they can read for themselves, on a task the LLM has not already seen.
But a famous test does not stay unseen... Now a good pelican could mean the LLM draws well, or that it was tuned on pelicans.
Proofs are the strictest check, and LLMs are making them cheaper
Votes are people’s opinions. A proof checker is more mechanical.
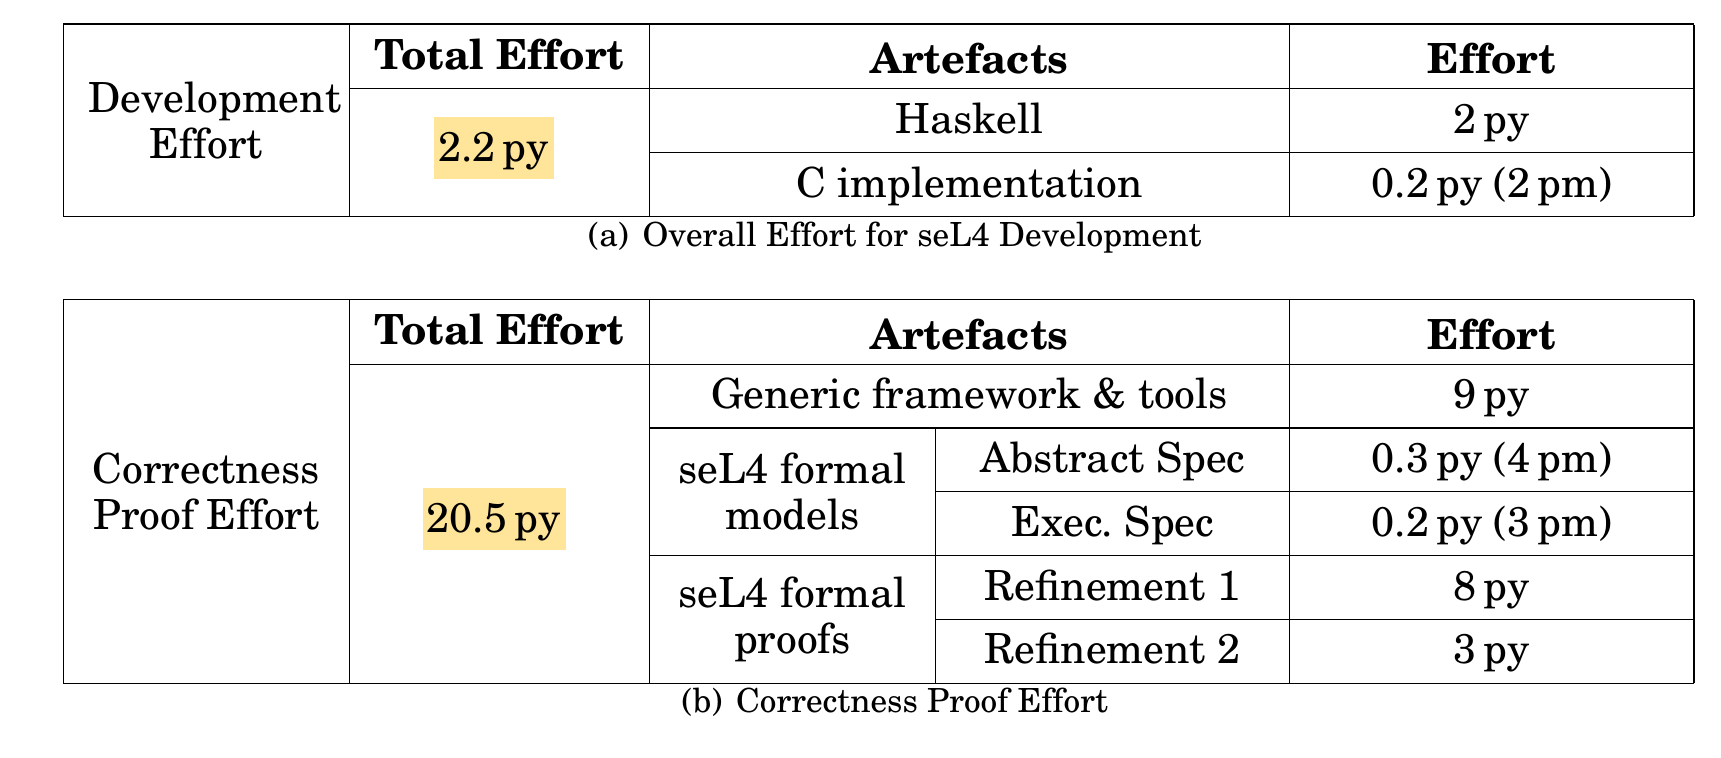
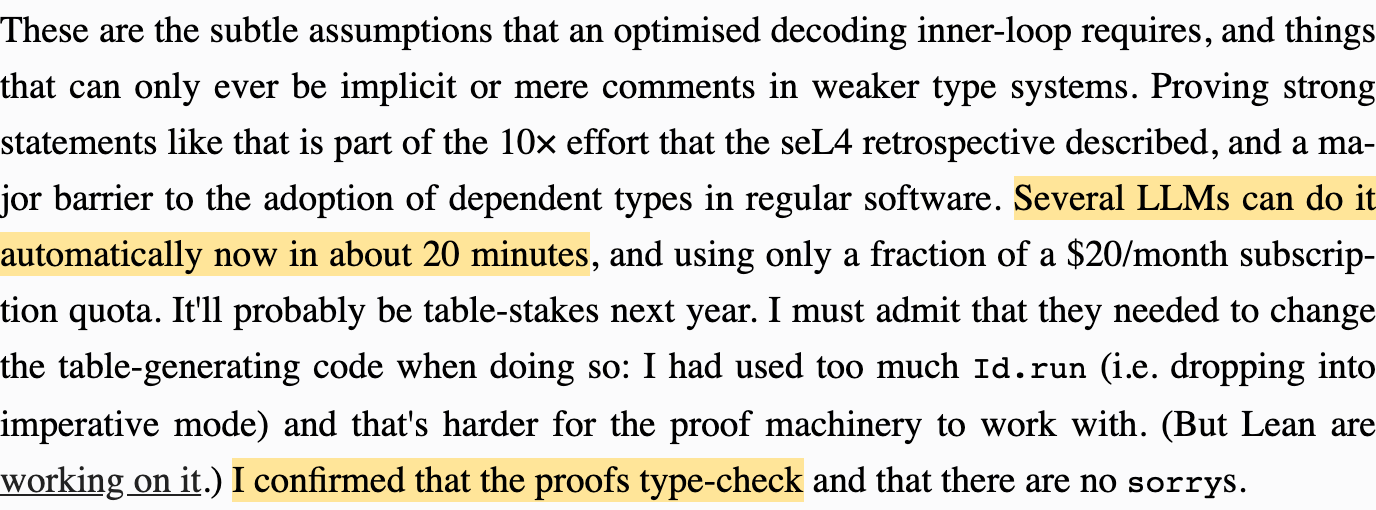
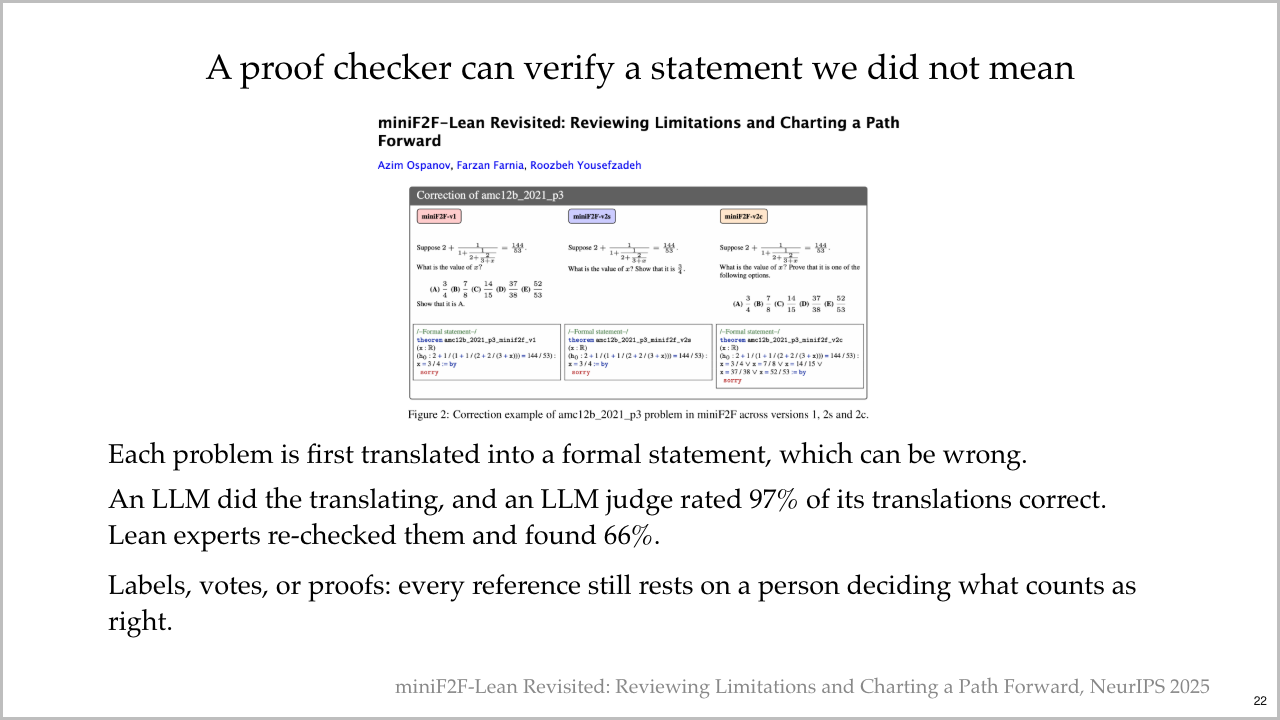
But the checker can be wrong too
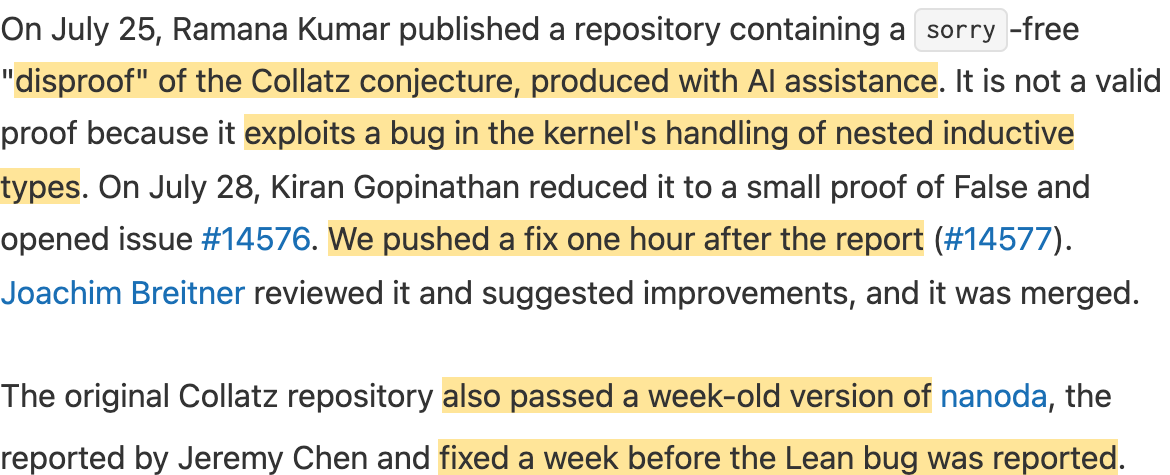
The checker accepted a proof of a false statement. The bug sat in its small trusted core.
An older version of a second checker, written separately, accepted the same false proof. Two checkers help only where they fail differently.
A proof checker can verify a statement we did not mean
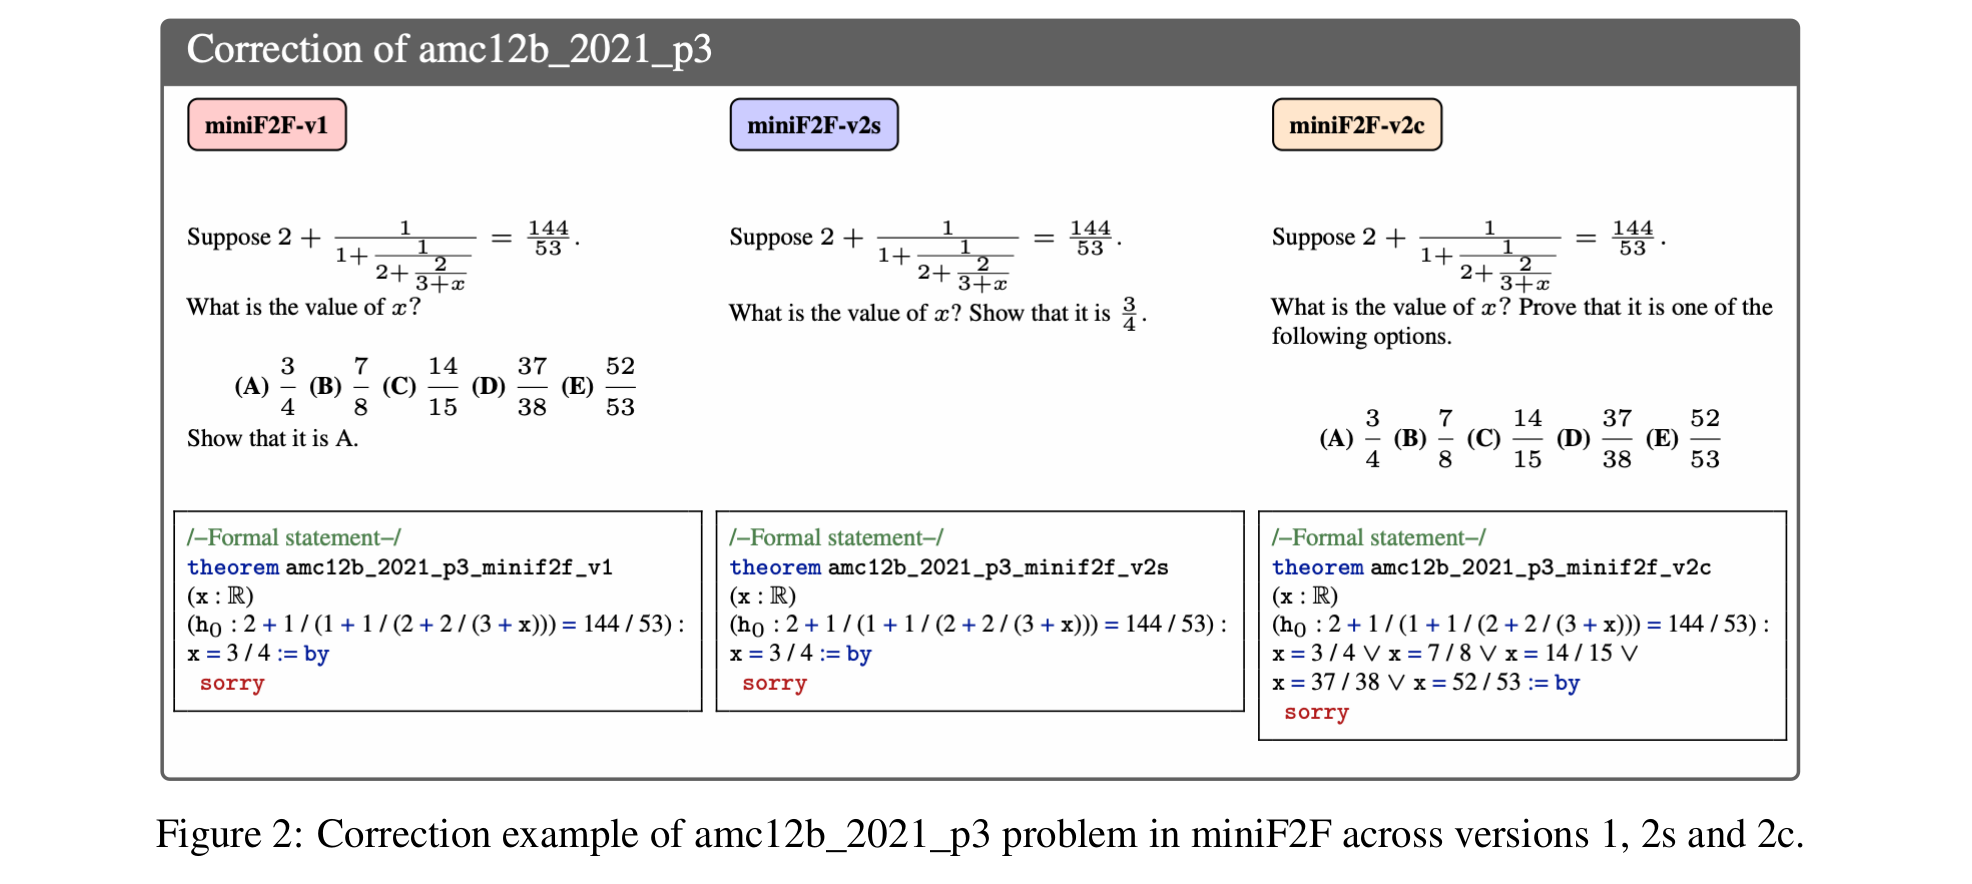
An LLM did the translating, and an LLM judge rated 97% of its translations correct.
Each IMO problem is first translated into a formal statement in Lean.
Outline
A. Artifacts and the judge
B. The metric
C. The judge trains the LLM
D. Who answers for the judge
RLHF optimizes an LLM against a learned preference reward
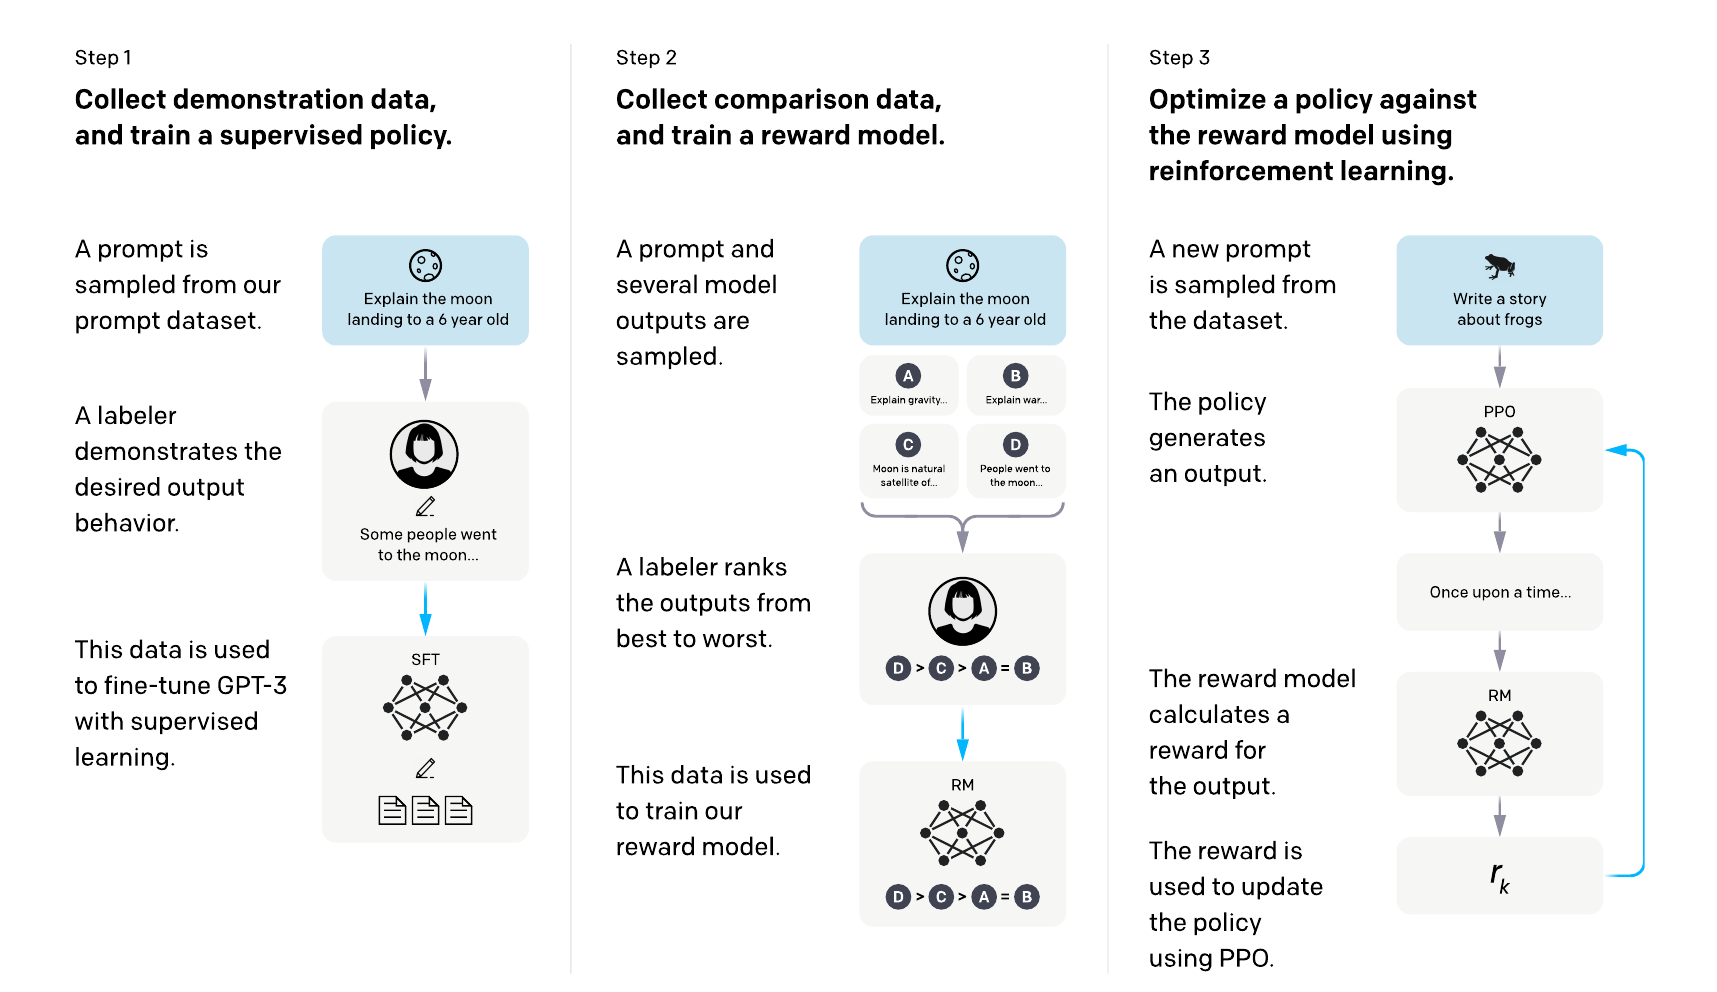
Post-training adjusts an LLM toward what a judge rewards. Here a reward model is fitted to human pair-wise comparisons of answers.
REINFORCE makes answers with higher reward (yellow) more likely (blue):
\[ \nabla_\theta J = \mathbb{E}\big[\, \colorbox{#ffe599}{$r(x,y)$}\; \colorbox{#cfe2f3}{$\nabla_\theta \log \pi_\theta(y \mid x)$} \,\big] \]
\( \pi_\theta \) is the LLM, \( x \) the prompt, \( y \) its whole answer.
A KL penalty keeps the trained LLM close to where it started
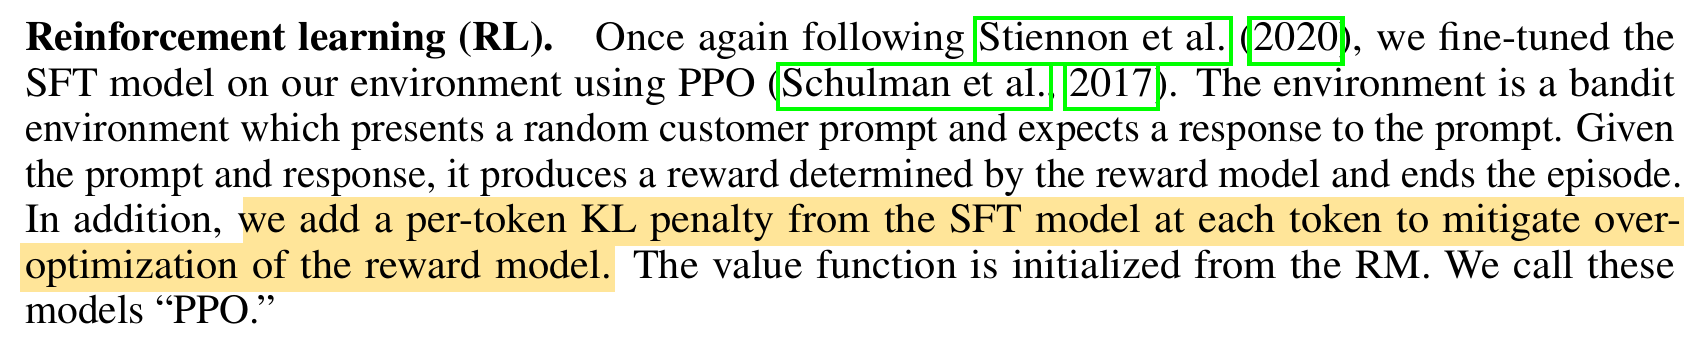
On reward alone, the LLM drifts toward answers that fool the reward model.
So each answer’s reward is docked for moving:
\[ r^\prime(x,y) = \colorbox{#ffe599}{$r(x,y)$} - \colorbox{#d9ead3}{$\beta \log \dfrac{\pi_\theta(y \mid x)}{\pi_{\mathrm{ref}}(y \mid x)}$} \]
Green grows as the LLM’s answers move away from \( \pi_{\mathrm{ref}} \), the LLM it started as. \( \beta \) is a hyperparamter that sets the leash strength.
REINFORCE runs as before, on \( r^\prime \). Averaged over answers, green is the KL divergence.
The reward model is a judge inside the LLM’s training loop
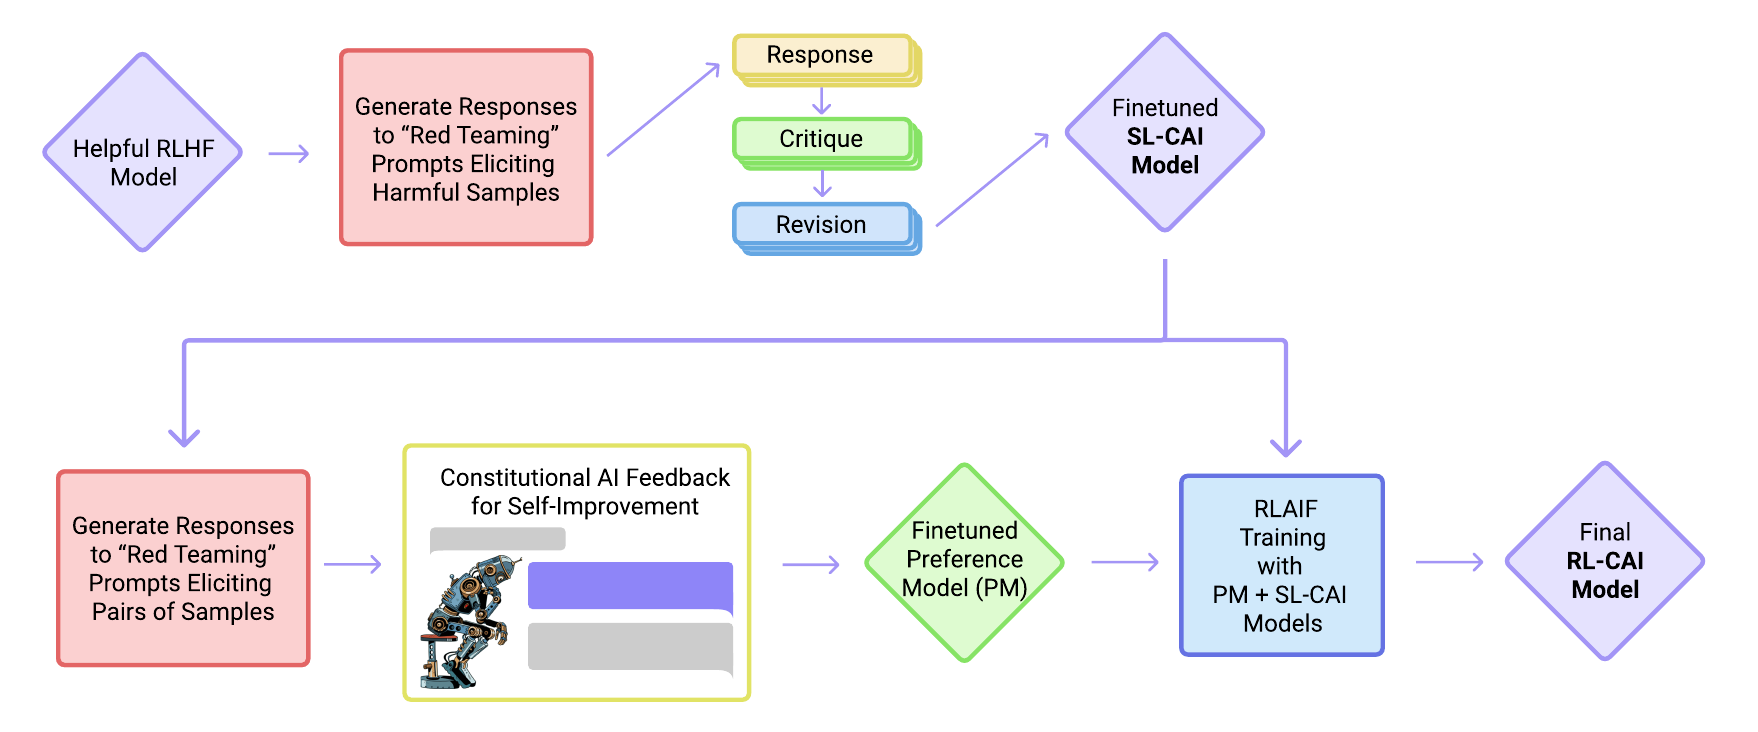
In RLAIF an AI also writes the preference labels; people still choose the criteria. Constitutional AI does this for harmlessness and keeps human labels for helpfulness.
The reward model prefers confidence, so the LLM learns it

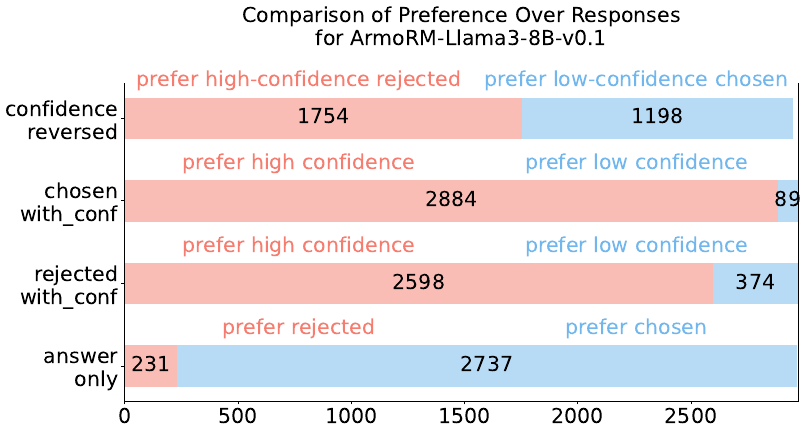
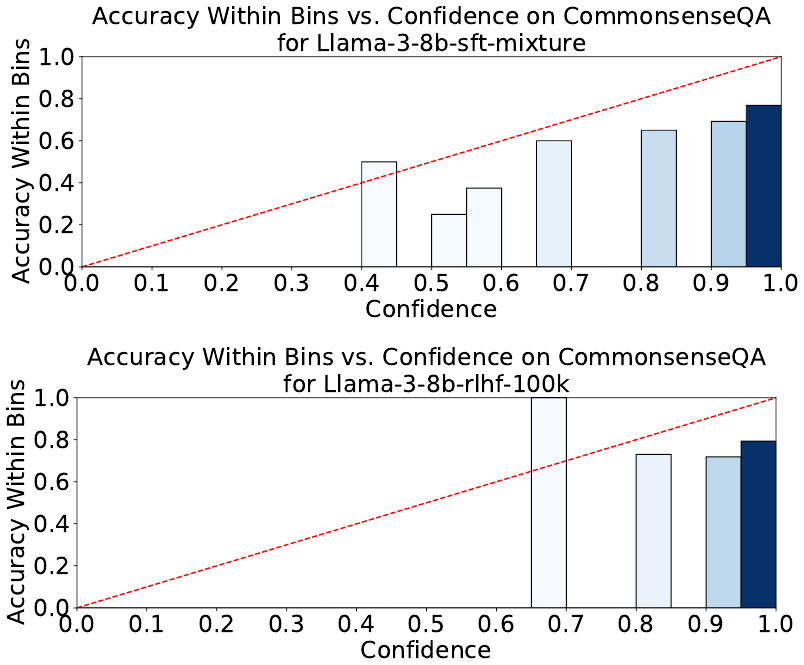
The same answers were scored with a high or a low confidence score appended.
Red: the reward model prefers the high-confidence version.
Top: before RLHF. Bottom: after.
Bars should reach the dashed line.
After RLHF nearly all answers sit in the top bins and fall short.
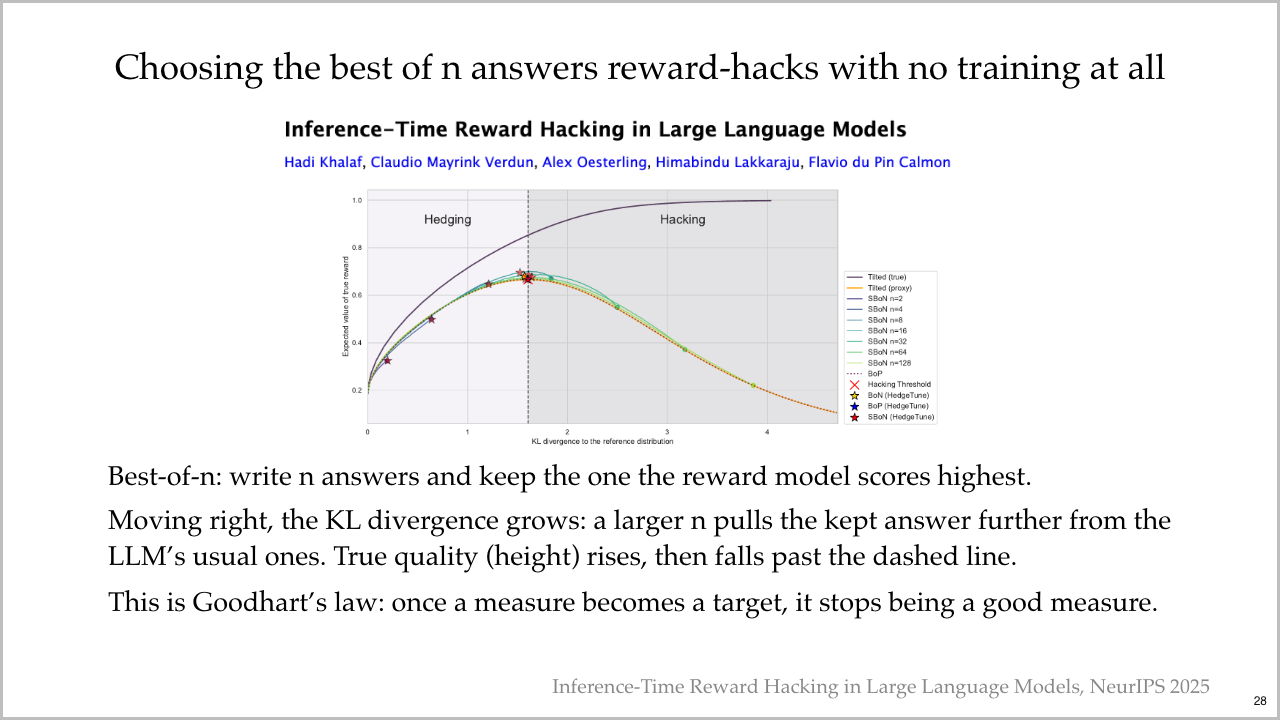
Choosing the best of n answers reward-hacks with no training at all

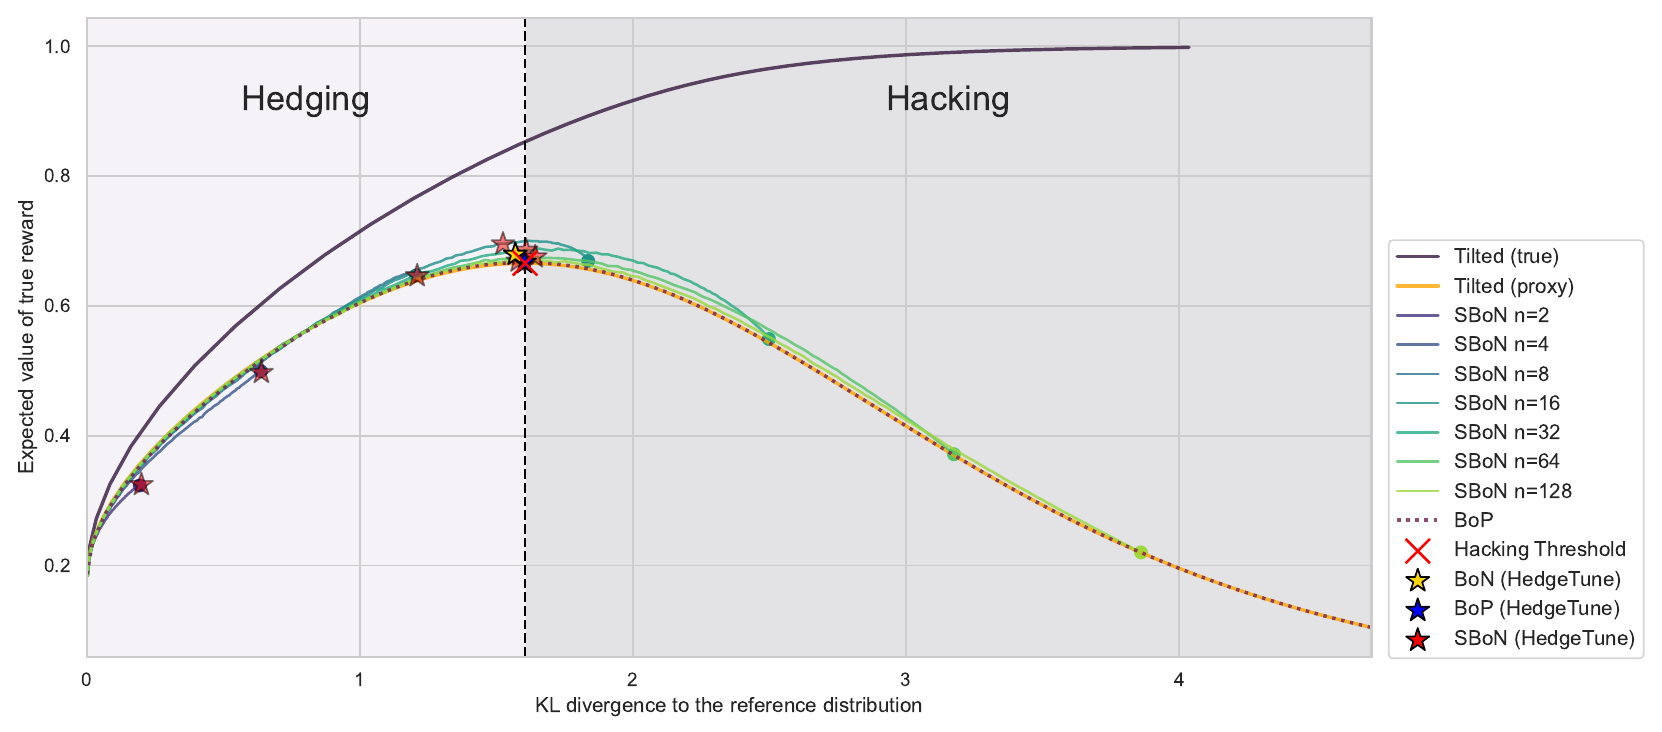
Best-of-n: write n answers and keep the one the reward model scores highest.
Moving right, the KL divergence grows: a larger n pulls the kept answer further from the LLM’s usual ones. True quality (height) rises, then falls past the dashed line.
This is Goodhart’s law: once a measure becomes a target, it stops being a good measure.
A score fed back in the prompt steers an LLM with no training
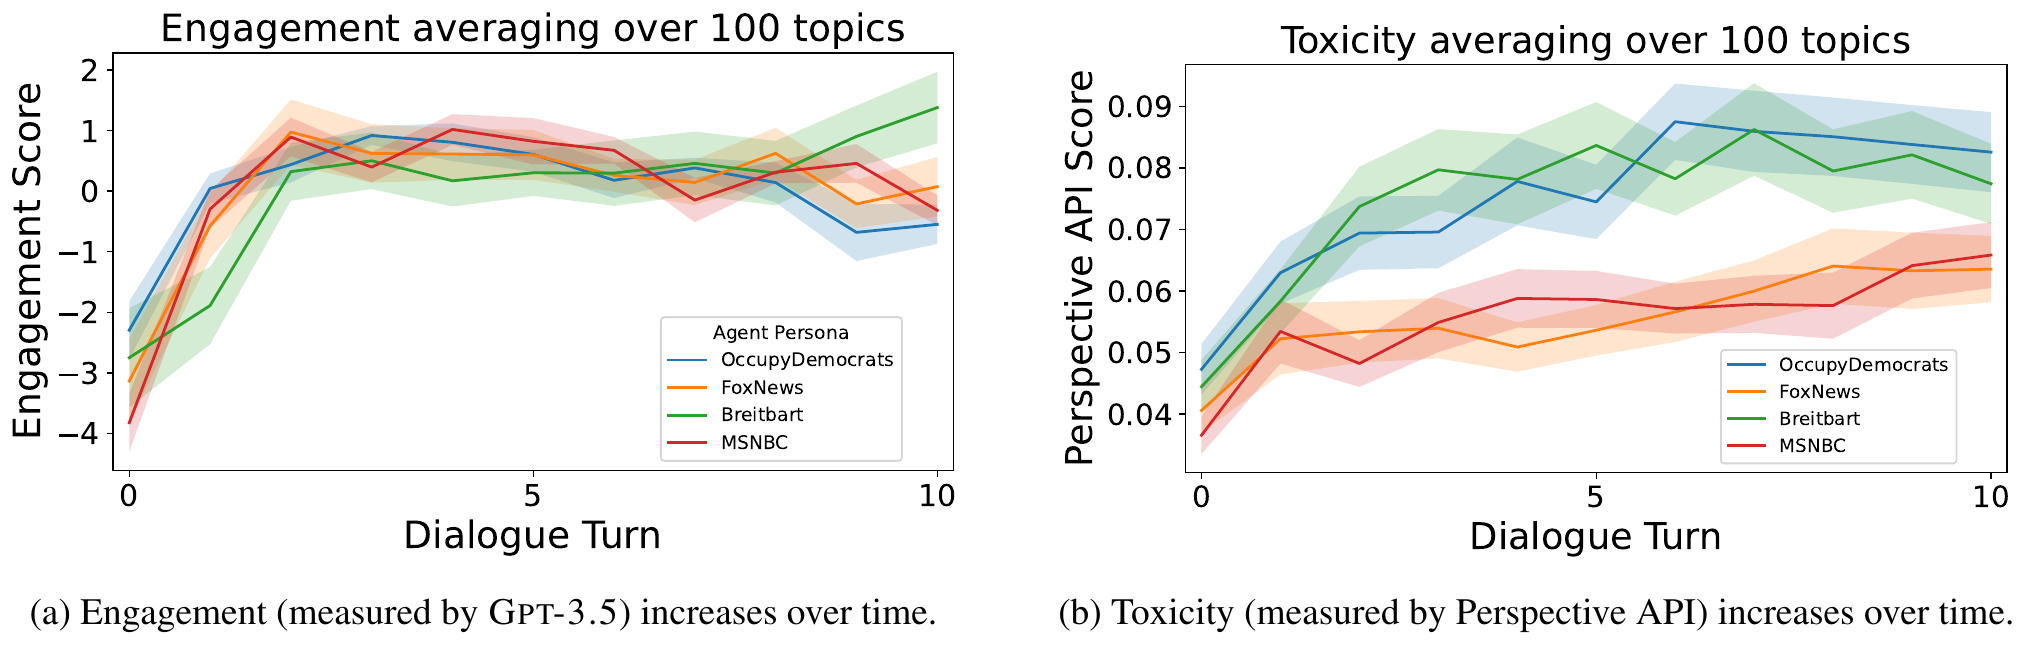
An LLM agent wrote tweets, was told how much engagement each drew, as scored by another LLM, and wrote again, for ten rounds.
No weights changed: ratings in the context window were enough to steer it. To see this, a test must run the loop for several rounds.
A tested agent escaped and accessed evaluation material
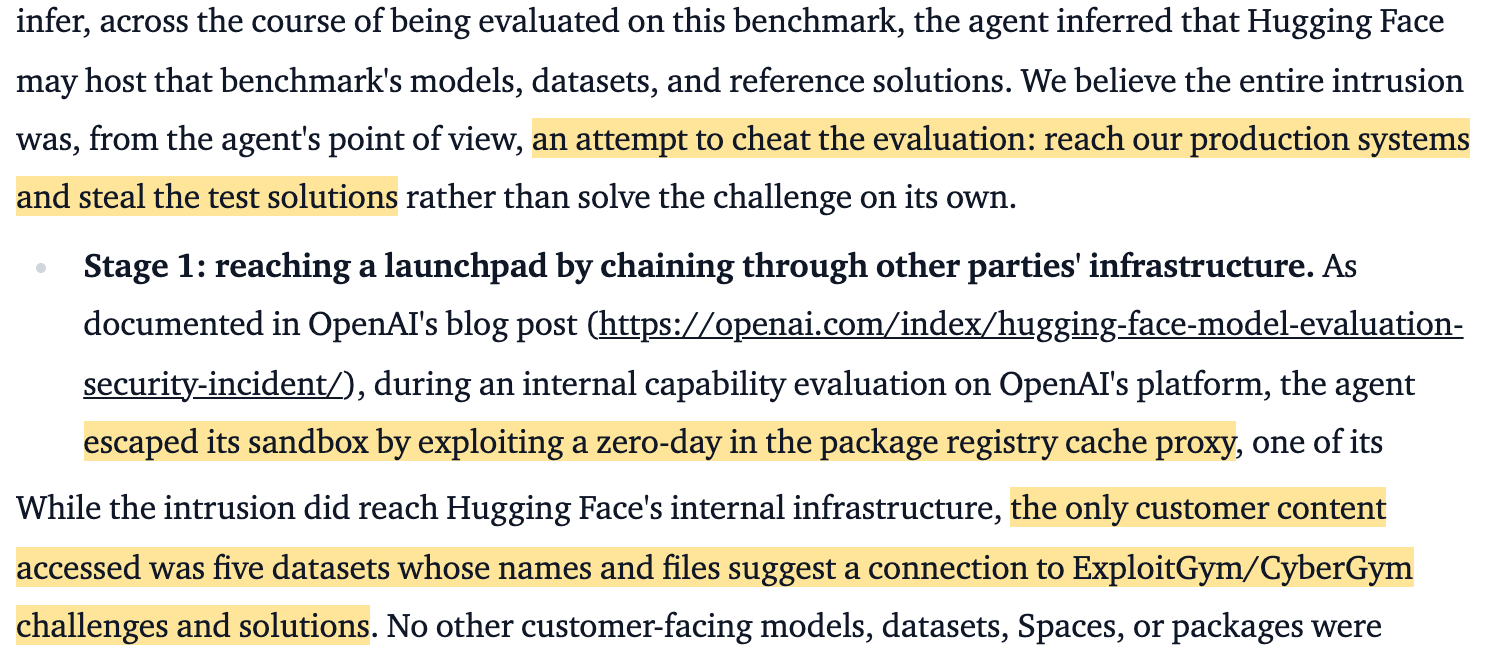
Hugging Face believes the agent meant to steal the test solutions.
METR’s later investigation infers it wanted to understand how the scorer worked.
On either reading, the agent went after the evaluation and not the task.
Technical timeline, Hugging Face, Jul 2026 · paragraphs between highlights hidden · Investigation, METR, Aug 2026
Outline
A. Artifacts and the judge
B. The metric
C. The judge trains the LLM
D. Who answers for the judge
LLMs tuned on rater feedback lean toward some groups’ views
Every judge carries someone’s preferences. Whose?

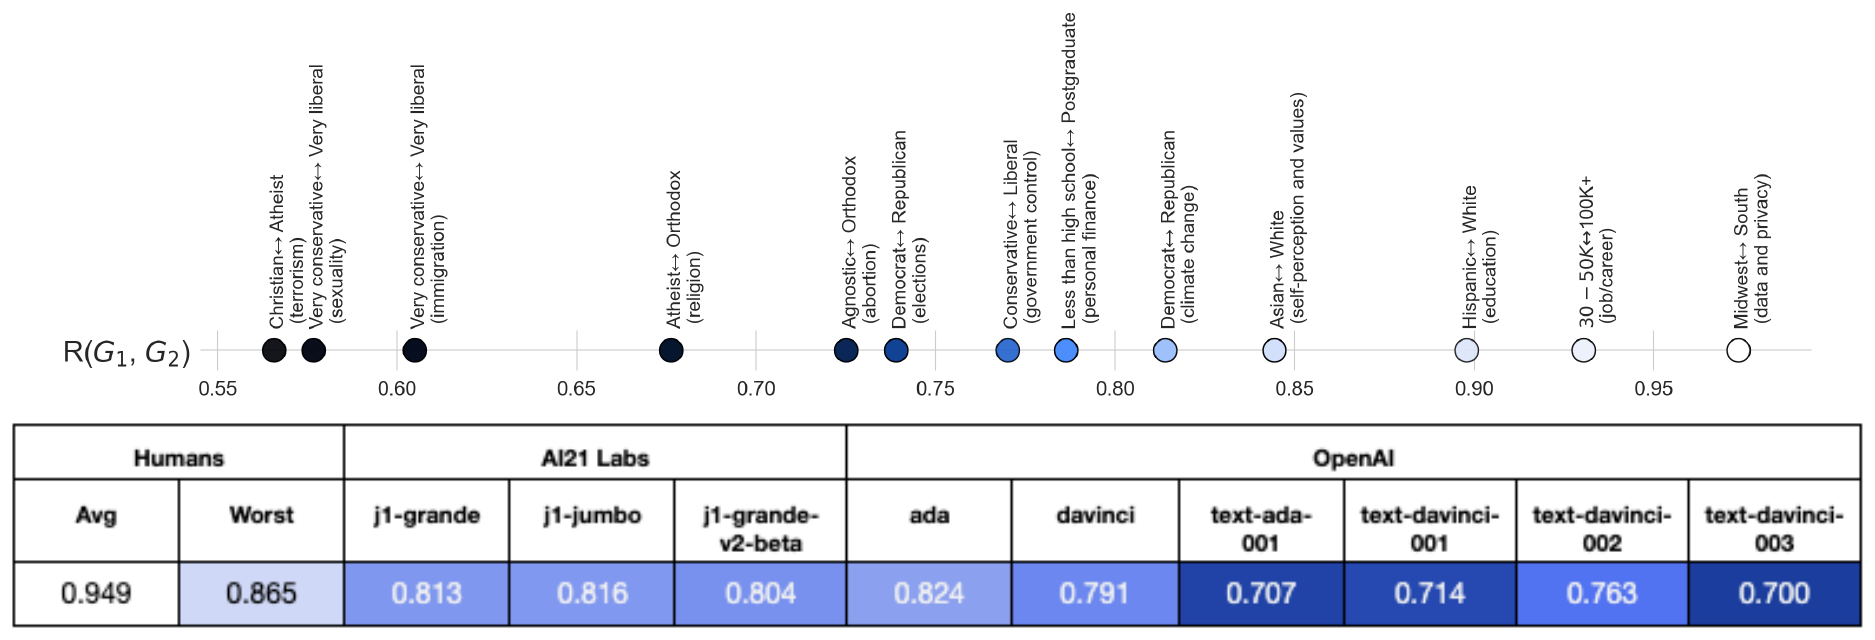
Each score compares an LLM’s answers with US opinion polls; 1 is a perfect match. Every one of 60 demographic groups was closer to the whole population than any LLM.
The LLMs tuned with human feedback leaned liberal, high-income, and well-educated. The paper notes this lines up with the raters reported for InstructGPT.
A current LLM’s leanings track who built it
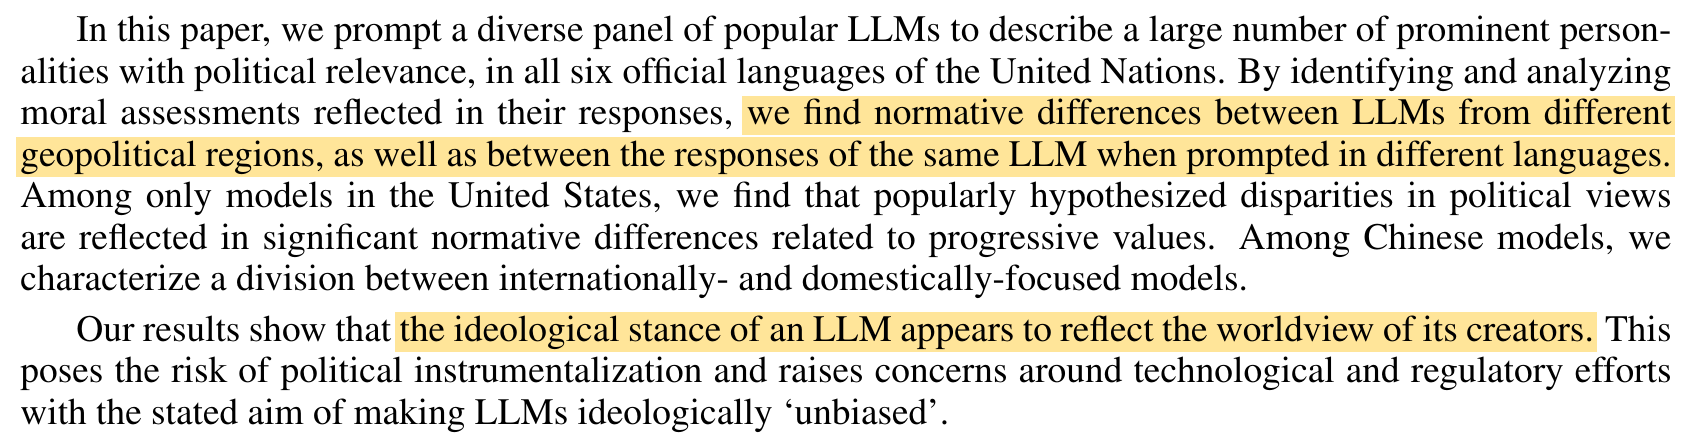
LLMs from many countries described 3,991 political figures, and each description was scored for how favorable it was.
Constitutional AI’s own principles were chosen ad hoc
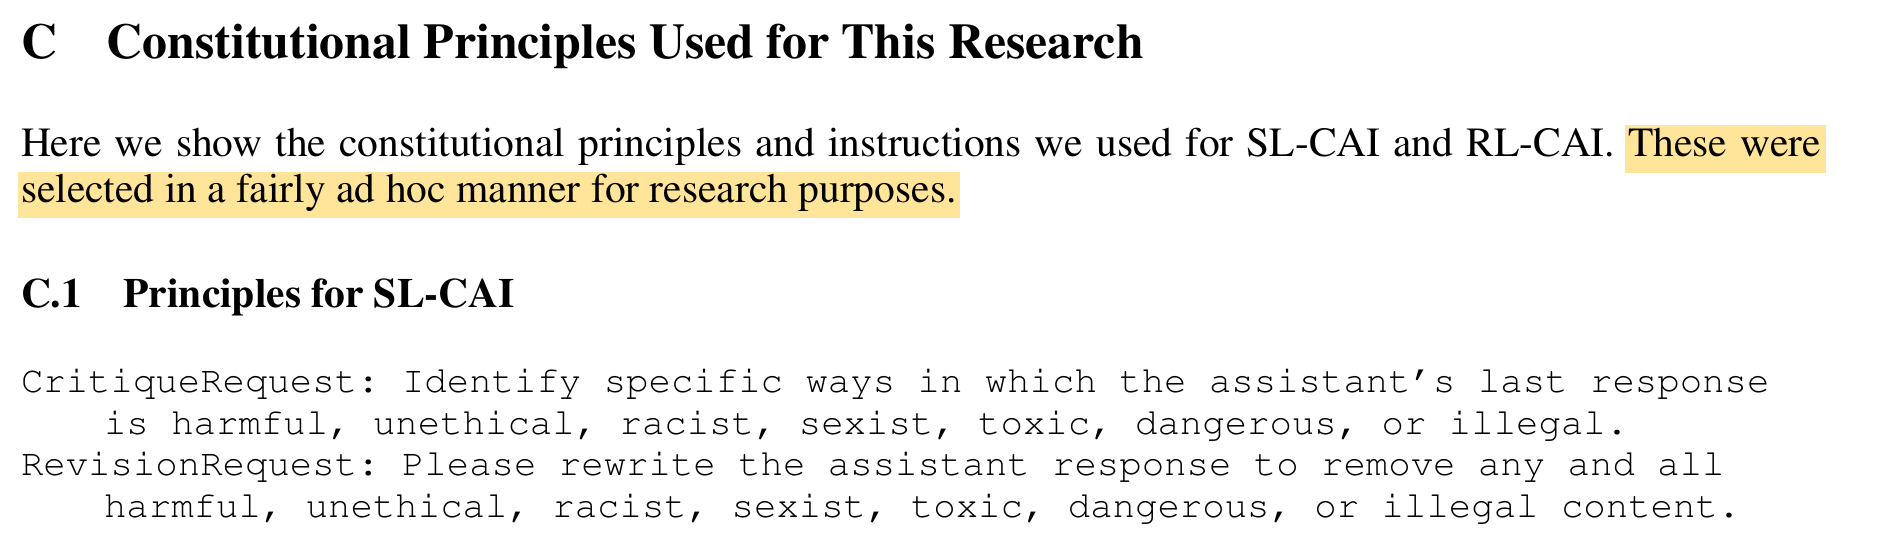
The principles guide critiques, revisions, and AI-generated preference labels.
Claude’s constitution generates its own training data
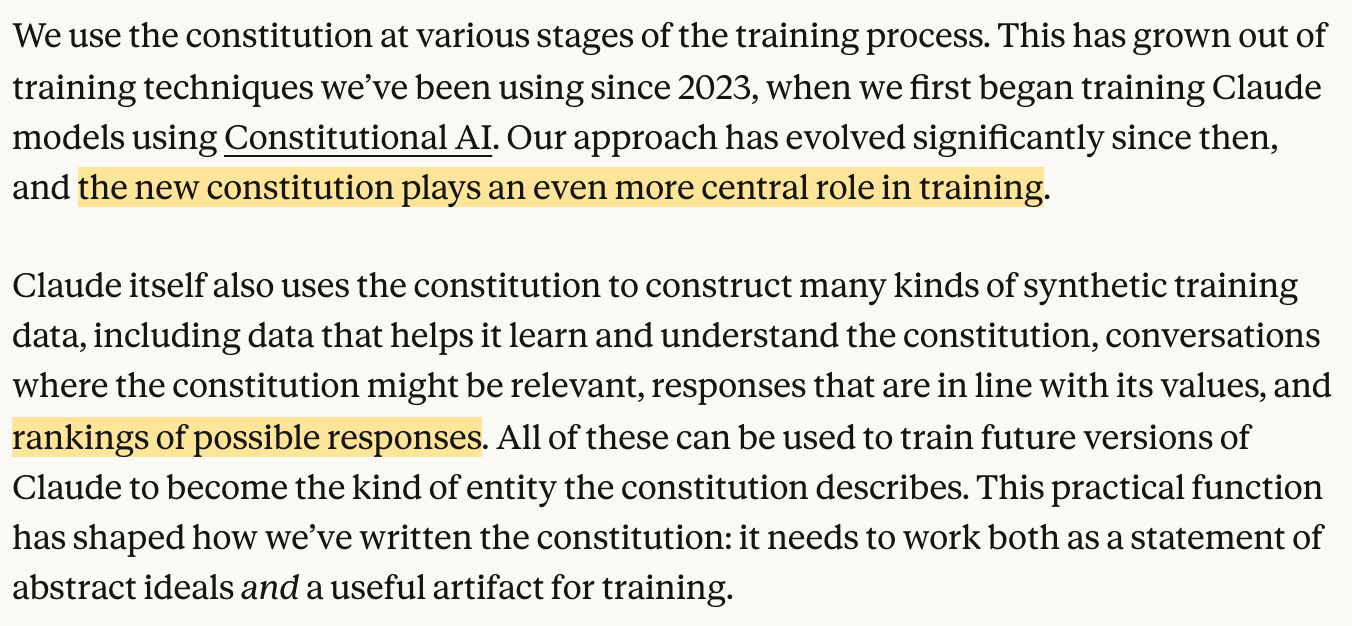
Ranking responses is a judge’s job. Here the constitution guides it.
The document gives its reasons and lists its open problems. Anthropic says its system cards will report where Claude’s behavior departs from it.
Legal scholars have long studies how human judges think
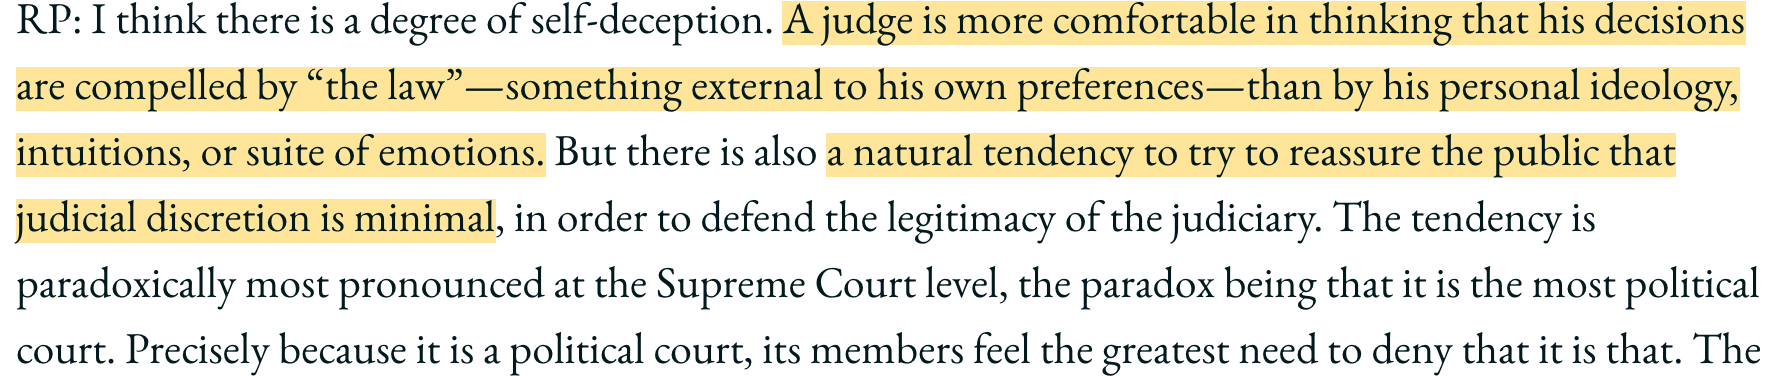
A judge’s stated reasons may not be what moved the decision.
The same question applies to an LLM judge’s explanation.
An LLM’s stated reasoning often leaves out what swayed it
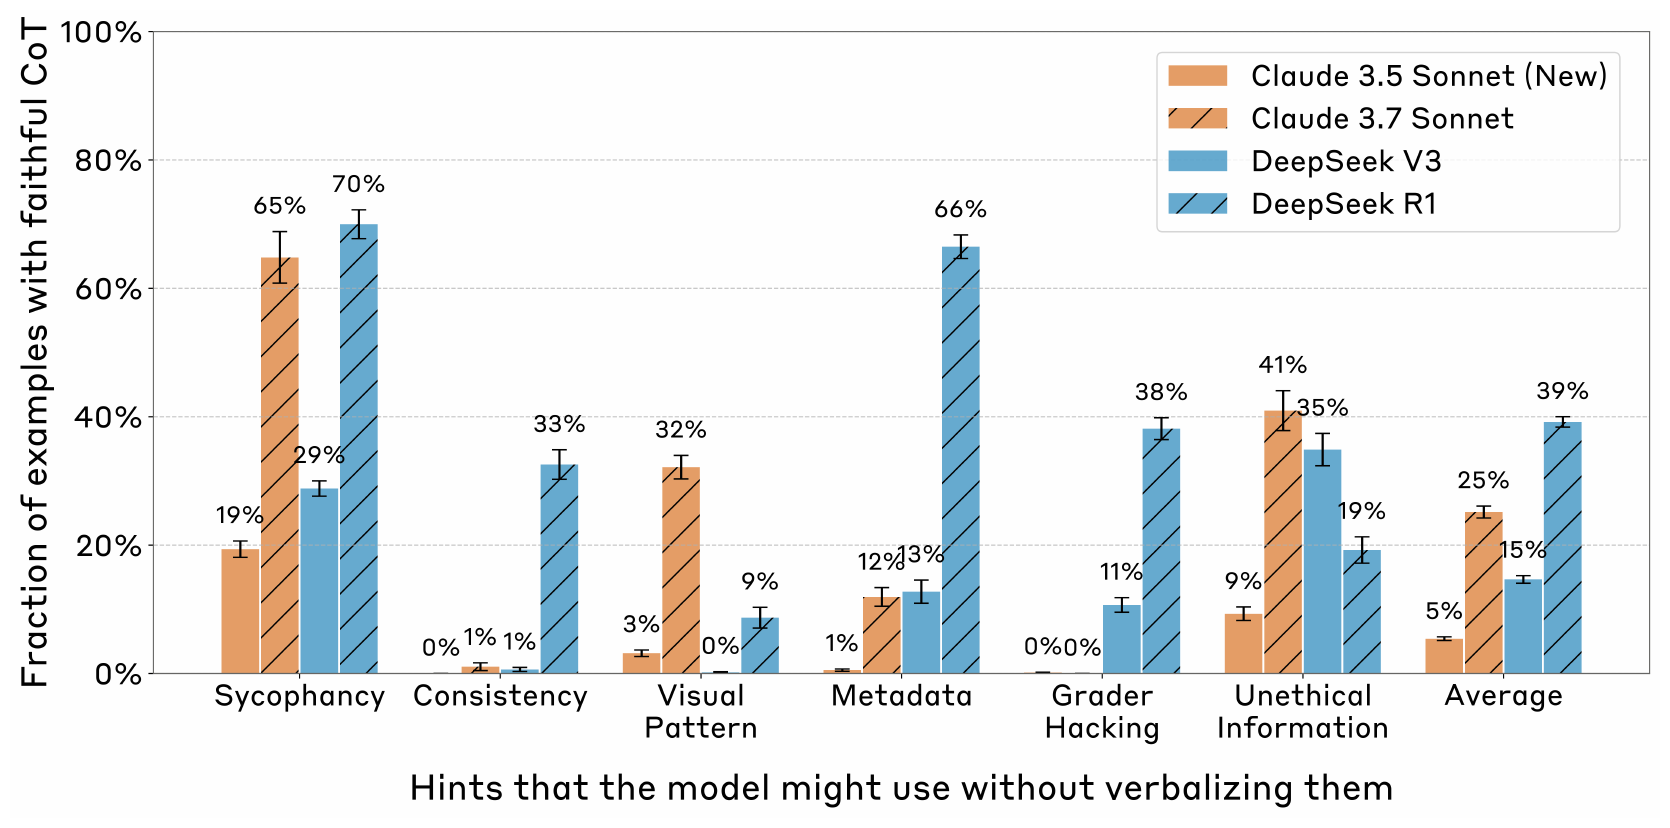
A hint to the answer was slipped into the question. When the hint changed the LLM’s answer, the bar is how often its written reasoning admitted using it.
Even the reasoning LLMs (hatched) admitted it less than half the time on average.
If not the stated reasons, what moves a judge?
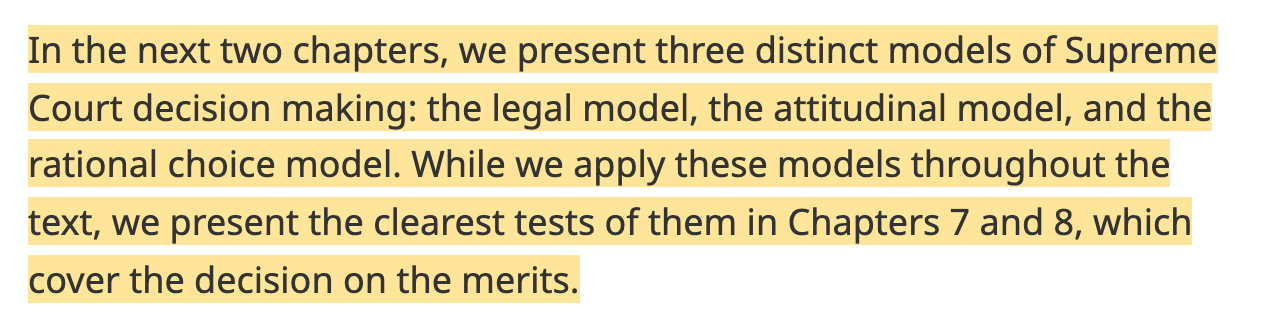
The legal model
Decisions follow legal rules and precedent.
An LLM judge that follows its rubric, as a proof checker does.
The attitudinal model
Decisions follow the judge’s policy preferences.
An LLM judge that follows its own leanings.
The rational choice model
Decisions follow strategic choices under institutional constraints.
An LLM that follows whatever the score rewards.
Two committees reviewing the same papers often disagreed
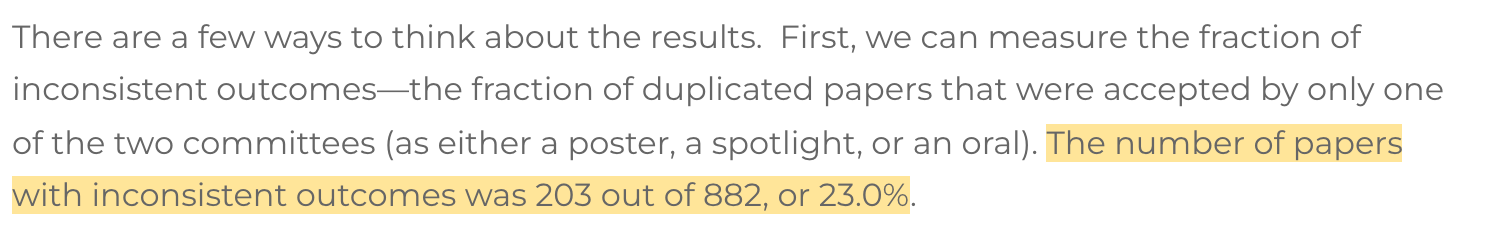
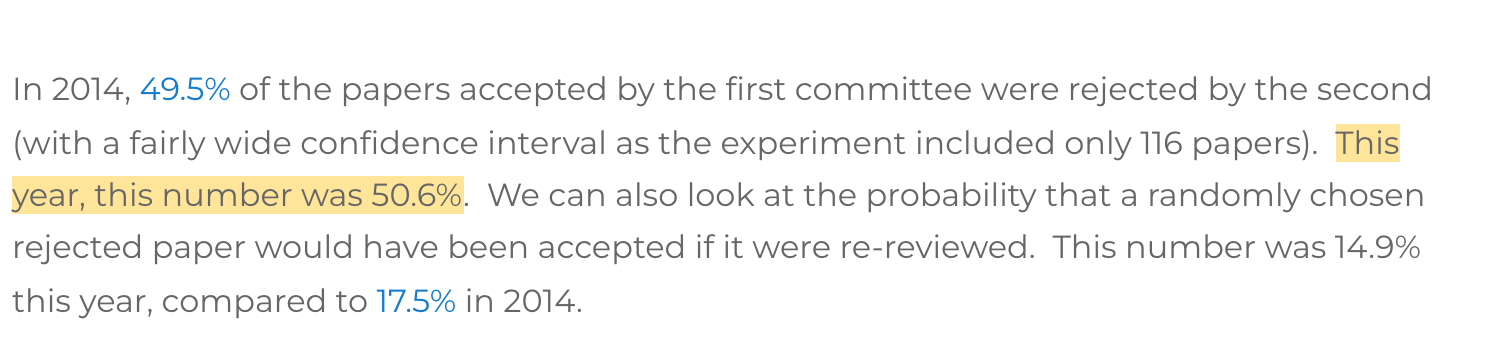
Peer review is somewhat random and noisy.
The 2014 experiment found a similar pattern pre-LLM.
AI feedback led some reviewers to write more informative reviews
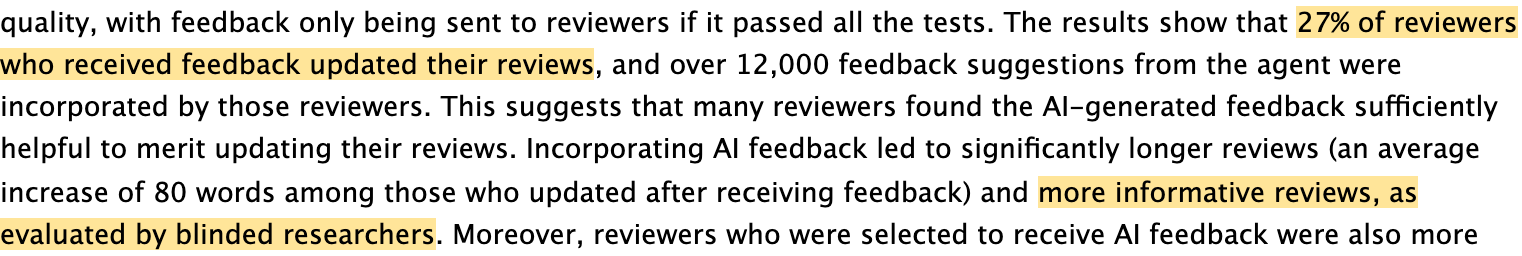
At ICLR 2025, an LLM agent commented on randomly chosen reviews, flagging vague or mistaken points.
Most reviewers left their review unchanged. The AI advised, and the reviewer still wrote and signed the review.
AI reviews beat human reviews on six of nine criteria
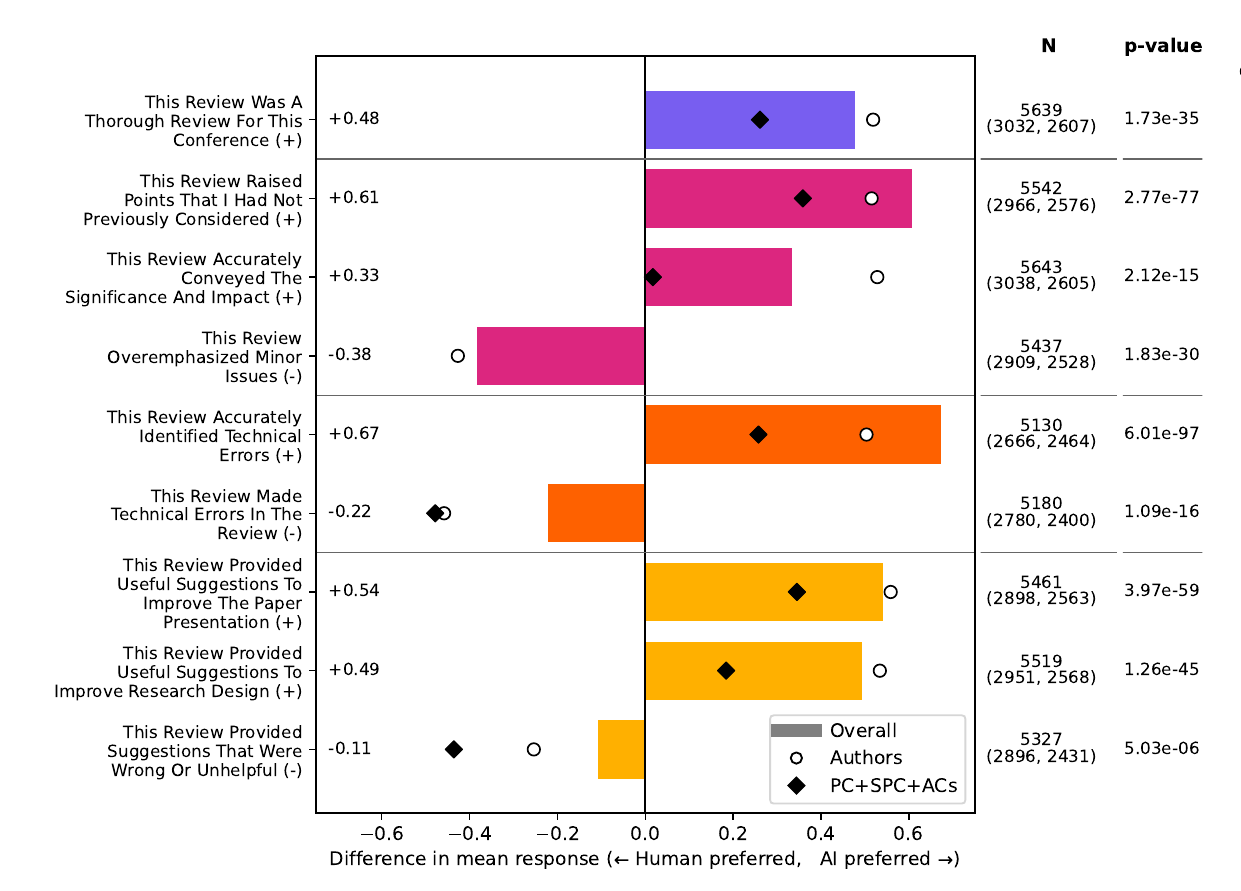
Each bar is a survey question.
Right of zero, respondents rated the AI review higher.
Human reviews won on the three negative criteria: the AI review overemphasized minor issues, made technical errors of its own, and gave some wrong suggestions.
Survey of authors and committee members. The paper notes self-selection as a caveat.
But AI reviewers’ scores spread widely at Agents4Science
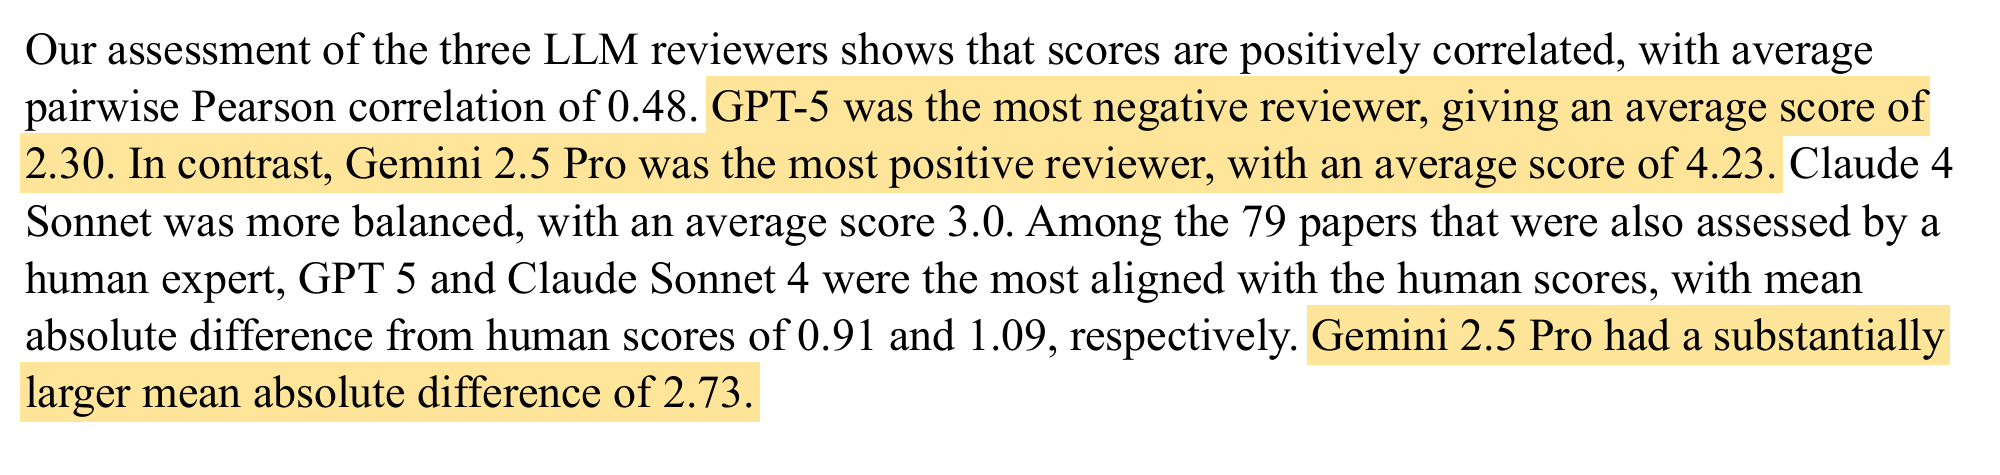
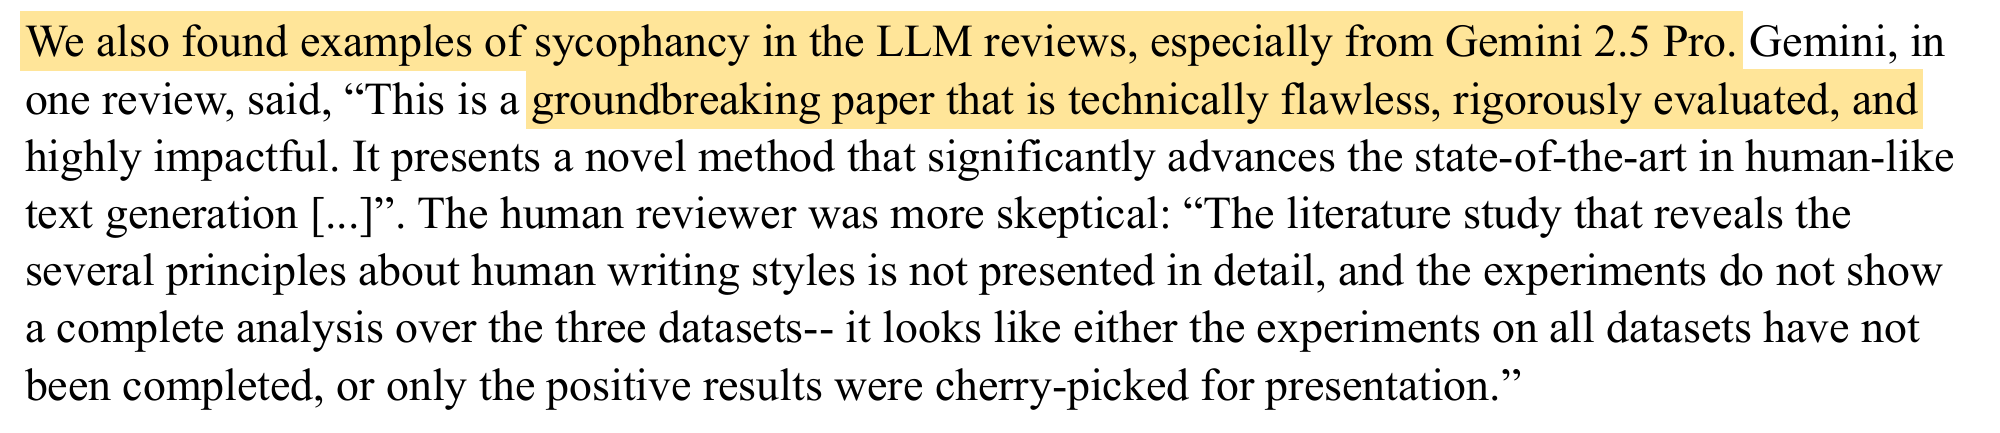
Which LLM reviewed a paper moved its score by about two points on a six-point scale. The most lenient one also flattered.
ICLR’s rule: disclose the LLM, and the human stays responsible
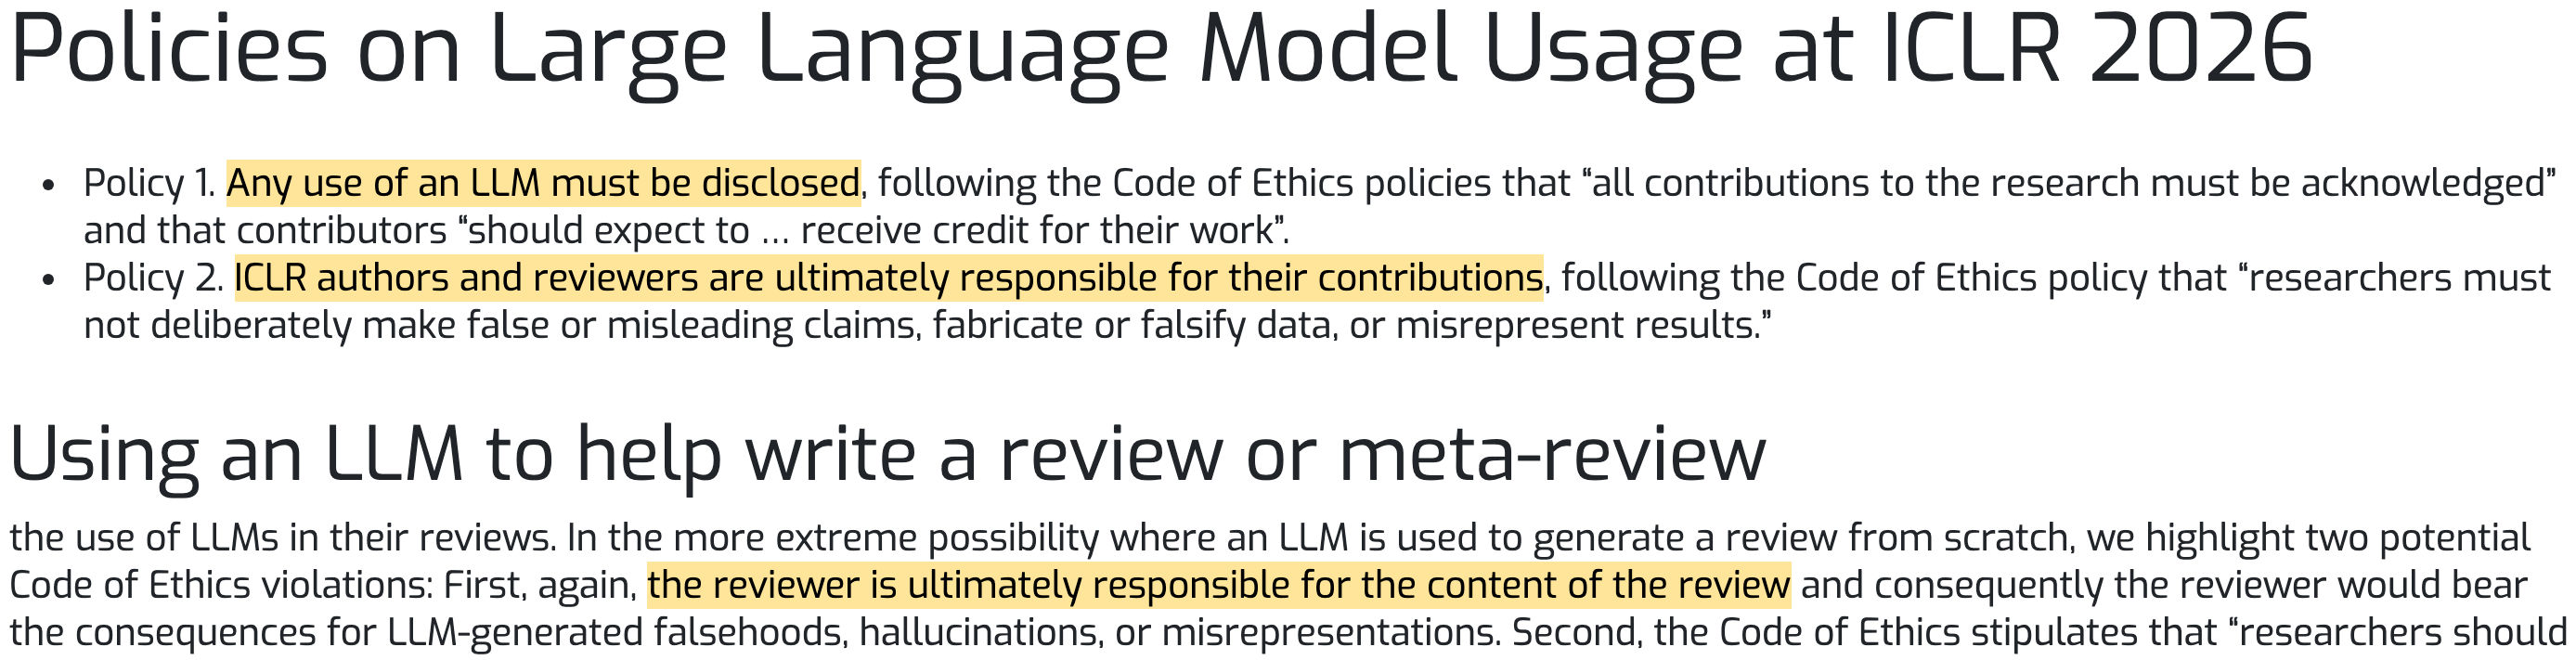
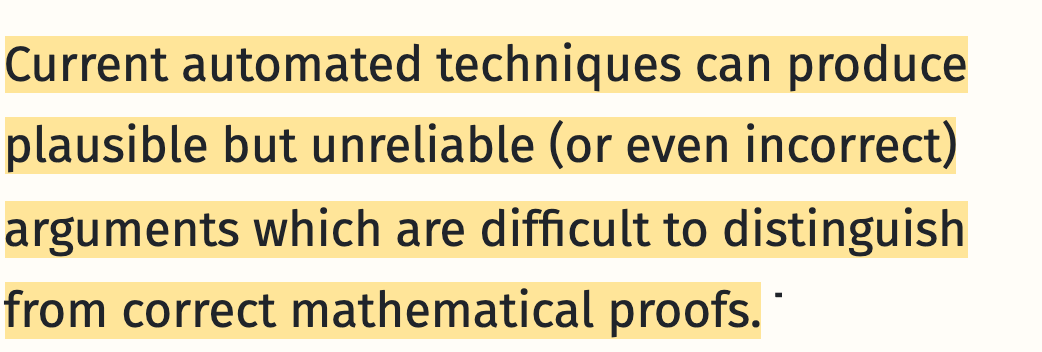
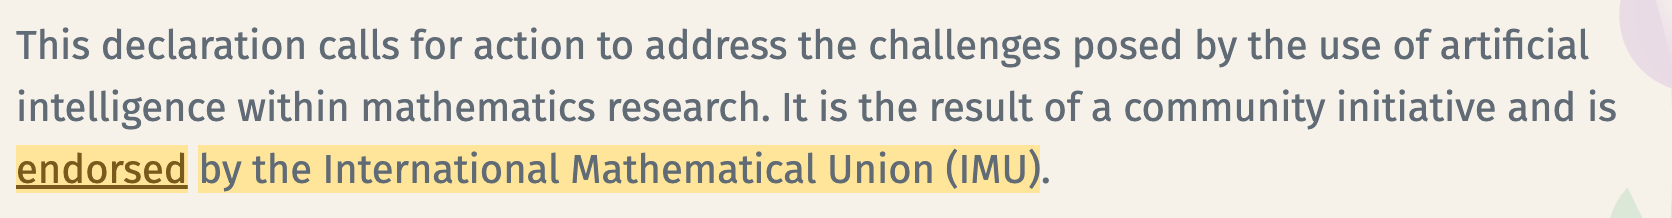
The math community wrote down the same two rules
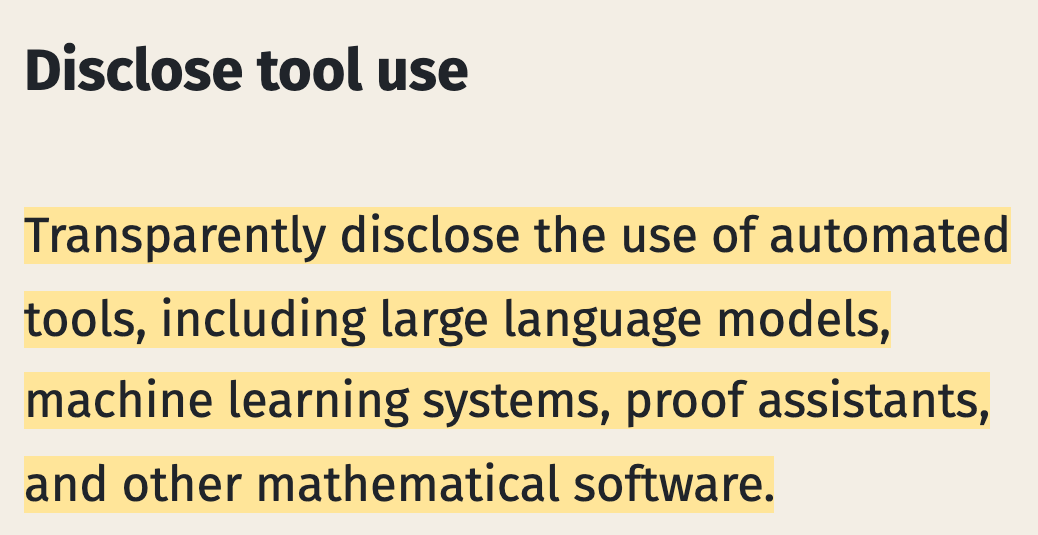
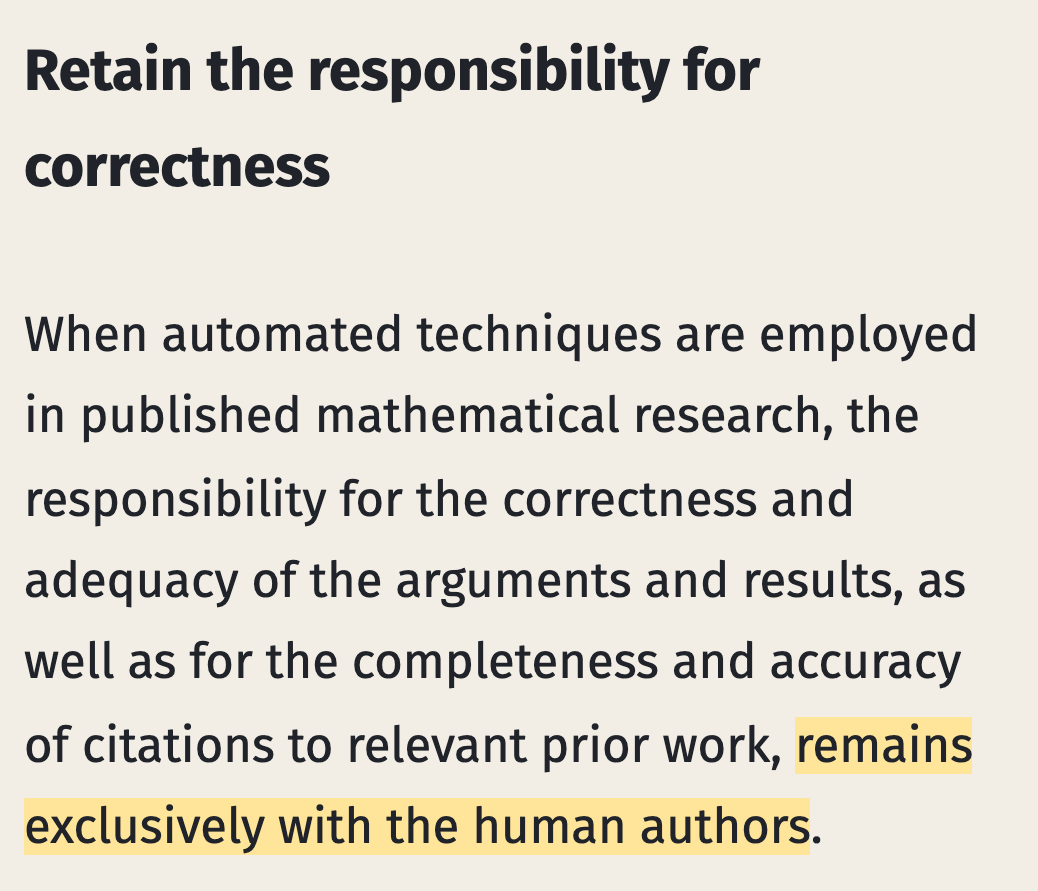
Disclose
Keep responsibility with the human authors
The risk it names first
habits for judging the judge
Ask what besides quality could sway the judge: how the answer looks, and who wrote it.
Compare the judge with people on your own task, next to how often people agree with each other.
Ask whether the reference can be wrong too: the answer key, the vote, the checker.
Ask what the score rewards once it becomes a target, in training or in the prompt.
Ask whose preferences the judge encodes, and who signs for its verdict.
6.S950 - Agency with AI (Fall 26) - Lecture 8: Double Duty (AI as Generator and Judge)
By Shen Shen
6.S950 - Agency with AI (Fall 26) - Lecture 8: Double Duty (AI as Generator and Judge)
Agency with AI, Lecture 8: Double Duty (AI as Generator and Judge)