Lecture 10: Markov Decision Processes
Intro to Machine Learning
Toddler demo, Russ Tedrake thesis, 2004
Outline
-
Markov Decision Processes Definition
-
Policy Evaluation
-
Policy Optimization
-
Markov Decision Processes Definition
-
Policy Evaluation
-
Policy Optimization
like computing the loss: the weights are given, we score them
like training: we search for good weights
like computing the loss: the weights are given, we score them
like training: we search for good weights
- (state, action) results in a transition \(\mathrm{T}\) into a next state:
-
Normally, we get to the “intended” state;
-
E.g., in state (7), action “↑” gets to state (4)
-
-
If an action would take Mario off the grid, he stays put;
-
E.g., in state (9), “→” gets back to state (9)
-
-
In state (6), action “↑” leads to two possibilities:
-
20% chance to (2)
-
80% chance to (3)
-
-
80\%
20\%
Running example: Mario in a grid-world
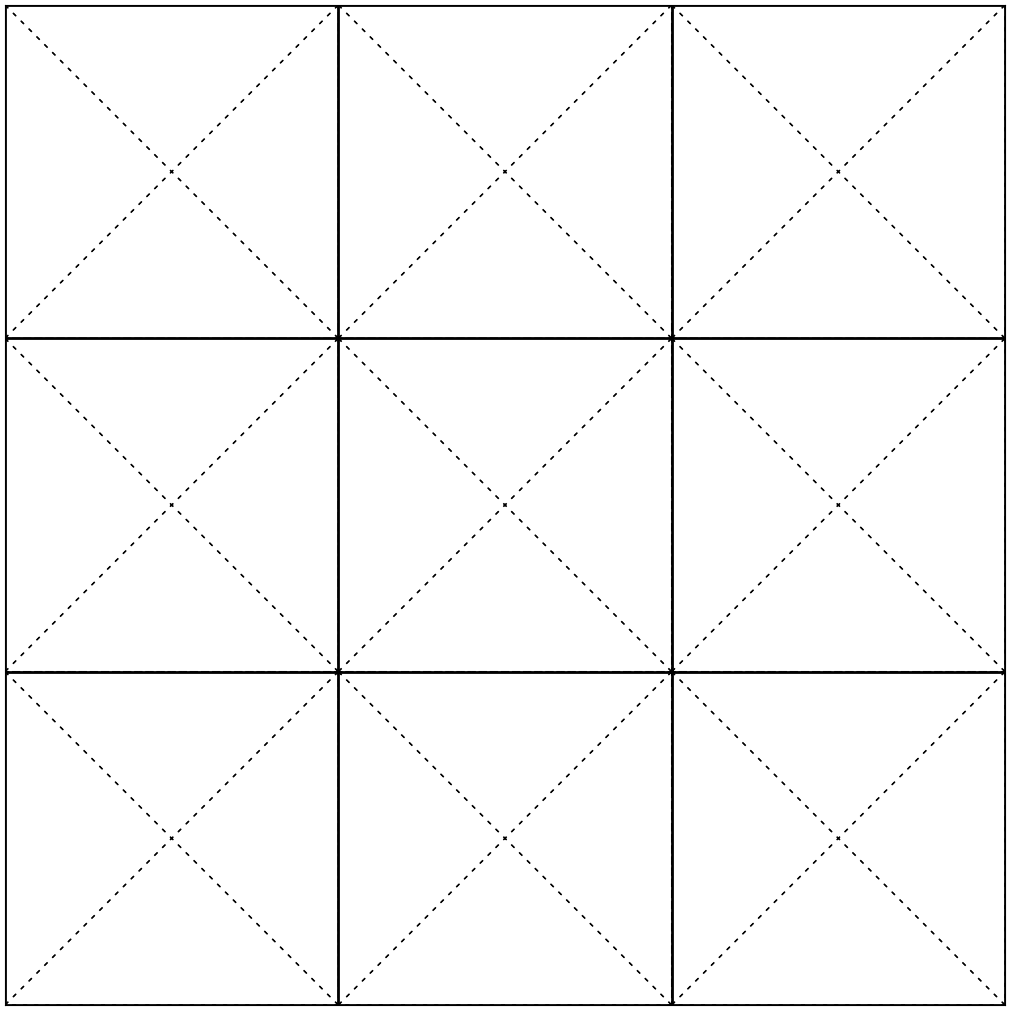
- 9 possible states \(s\)
- 4 possible actions \(a\): {Up ↑, Down ↓, Left ←, Right →}
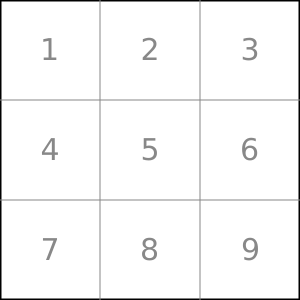
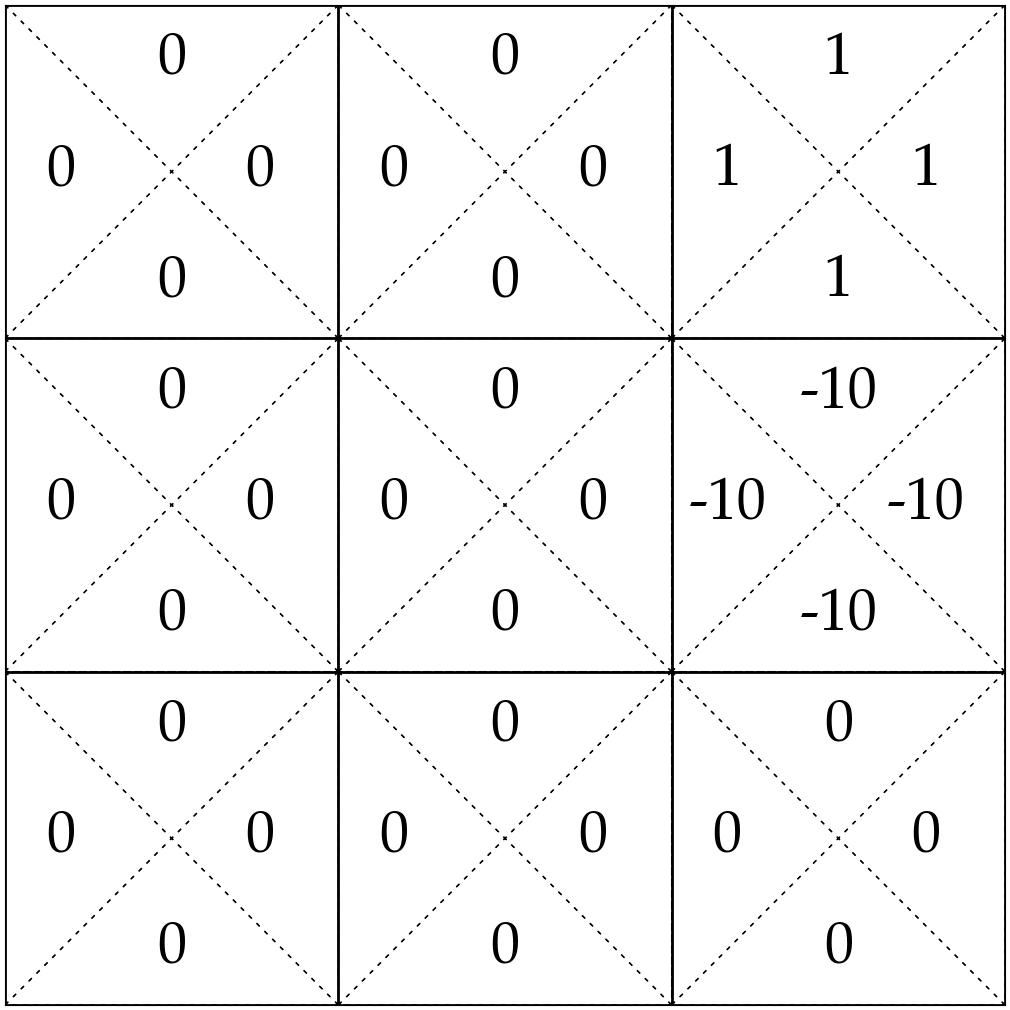
1
1
1
1
-10
-10
-10
-10
reward of (3, \(\downarrow\))
reward of \((3,\uparrow\))
reward of \((6, \downarrow\))
reward of \((6,\rightarrow\))
- Mario gets a reward for each action he takes:
- any action taken in state 3 gives reward 1
- any action taken in state 6 gives reward \(-10\)
- any other (state, action) pair gives reward 0
- discount factor \(\gamma = 0.9\): a reward counts for less the later Mario receives it.
Mario in a grid-world, cont'd
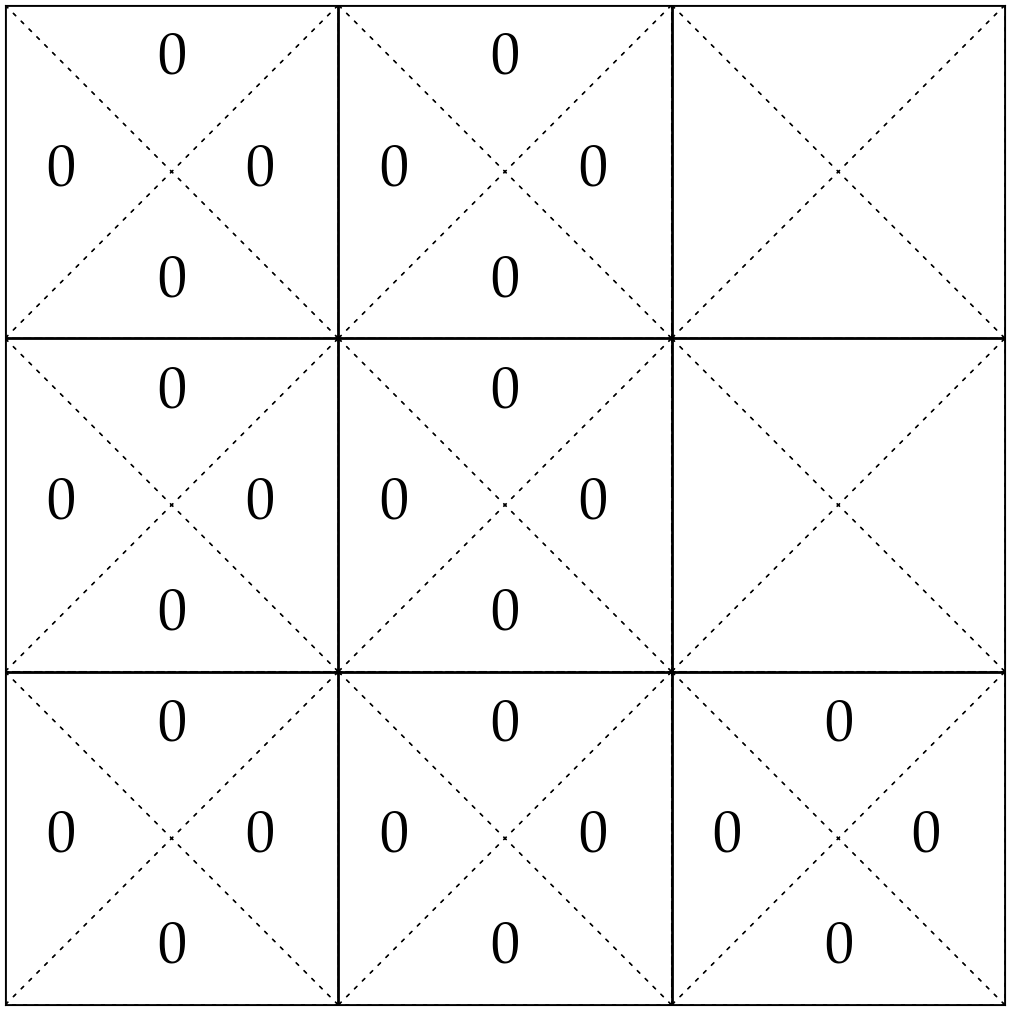
The reward is for taking the action, not for arriving.
e.g. moving up from state 6 earns a reward of \(-10\), regardless of whether we end in state 2 or 3
e.g. the reward 1 from \((3, \leftarrow)\) is worth \(1,\ 0.9,\ 0.9^2, \dots\) at time steps 0, 1, 2, …
- \(\mathcal{S}\) : state space, contains all possible states \(s\).
- \(\mathcal{A}\) : action space, contains all possible actions \(a\).
- \(\mathrm{T}\left(s, a, s^{\prime}\right)\) : the probability of transition from state \(s\) to \(s^{\prime}\) when action \(a\) is taken.
Markov Decision Process (MDP)
80\%
20\%
\(\mathrm{T}\left(7, \uparrow, 4\right) = 1\)
\(\mathrm{T}\left(9, \rightarrow, 9\right) = 1\)
\(\mathrm{T}\left(6, \uparrow, 3\right) = 0.8\)
\(\mathrm{T}\left(6, \uparrow, 2\right) = 0.2\)
In 6.390,
- \(\mathcal{S}\) and \(\mathcal{A}\) are small discrete sets, unless otherwise specified.
- \(s^{\prime}\) and \(a^{\prime}\) are shorthand for the next-timestep state and action.
- \(\mathcal{S}\) : state space, contains all possible states \(s\).
- \(\mathcal{A}\) : action space, contains all possible actions \(a\).
- \(\mathrm{T}\left(s, a, s^{\prime}\right)\) : the probability of transition from state \(s\) to \(s^{\prime}\) when action \(a\) is taken.
- \(\mathrm{R}(s, a)\) : the reward received for taking action \(a\) in state \(s\).
Markov Decision Process (MDP)
reward of \((3,\uparrow\))
reward of \((6,\rightarrow\))
\(\mathrm{R}\left(3, \uparrow \right) = 1\)
\(\mathrm{R}\left(6, \rightarrow \right) = -10\)
In 6.390,
- \(\mathcal{S}\) and \(\mathcal{A}\) are small discrete sets, unless otherwise specified.
- \(s^{\prime}\) and \(a^{\prime}\) are shorthand for the next-timestep state and action.
- \(\mathrm{R}(s, a)\) is deterministic and bounded.
- \(\mathcal{S}\) : state space, contains all possible states \(s\).
- \(\mathcal{A}\) : action space, contains all possible actions \(a\).
- \(\mathrm{T}\left(s, a, s^{\prime}\right)\) : the probability of transition from state \(s\) to \(s^{\prime}\) when action \(a\) is taken.
- \(\mathrm{R}(s, a)\) : the reward received for taking action \(a\) in state \(s\).
- \(\gamma \in [0,1]\): discount factor, a scalar.
- \(\pi{(s)}\) : policy, takes in a state and returns an action.
The goal of an MDP is to find a good policy.
Markov Decision Process (MDP)
In 6.390,
- \(\mathcal{S}\) and \(\mathcal{A}\) are small discrete sets, unless otherwise specified.
- \(s^{\prime}\) and \(a^{\prime}\) are shorthand for the next-timestep state and action.
- \(\mathrm{R}(s, a)\) is deterministic and bounded.
- \(\pi(s)\) is deterministic.
Policy \(\pi(s)\)
Transition \(\mathrm{T}\left(s, a, s^{\prime}\right)\)
Reward \(\mathrm{R}(s, a)\)
time
a trajectory (also called an experience or rollout) of horizon \(h\)
\(\quad \tau=\left(s_0, a_0, r_0, s_1, a_1, r_1, \ldots, s_{h-1}, a_{h-1}, r_{h-1}\right)\)
\underbrace{\hspace{4.2cm}}
initial state
all depend on \(\pi\)
\dots
s_2
s_3
s_4
s_5
a_2
a_3
a_4
r_2
r_3
r_4
s_0
s_1
a_0
a_1
r_0
r_1
s_{h-2}
a_{h-2}
r_{h-2}
s_{h-1}
a_{h-1}
r_{h-1}
\(0\)
\(h\)
\(1\)
\(h-1\)
\(2\)
\(h-2\)
\(3\)
\(h-3\)
\(4\)
\(h-4\)
\(5\)
\(h-5\)
\(h-2\)
\(2\)
\(h-1\)
\(1\)
clock \(t\)
remaining horizon
Outline
-
Markov Decision Processes Definition
-
Policy Evaluation
-
State value functions: \(\mathrm{V}^{\pi}\)
-
Bellman recursions and Bellman equations
-
-
Policy Optimization
Starting in state \(s\), how good is it to follow a given policy \(\pi\) for \(h\) time steps?
One idea:
But if we start at \(s = 6\) and follow the “always-up” policy:
??
-10
\uparrow
6
👈
80\%
20\%
states and one special transition:
rewards:
trajectory:
\mathrm{R}(s_0, \pi(s_0)) \;+\; \gamma \mathrm{R}(s_1, \pi(s_1)) \;+\; \dots \;+\; \gamma^{h-1}\mathrm{R}(s_{h-1}, \pi(s_{h-1}))
s_0 = s
,
\mathbb{E}\Big[
\Big]
Value functions
- A value is an expected sum of discounted rewards
- \(\mathrm{V}_h^\pi(s)\): starting from state \(s\), following \(\pi\) for \(h\) time steps
- expected: averaged over the random transitions
- Value is long-term; reward is immediate (one-time)
- Convention: with no steps left, every value is 0
\mathrm{R}(s_0, \pi(s_0)) \;+\; \gamma \mathrm{R}(s_1, \pi(s_1)) \;+\; \dots \;+\; \gamma^{h-1}\mathrm{R}(s_{h-1}, \pi(s_{h-1}))
=\mathbb{E}\left[\sum_{t=0}^{h-1} \gamma^t \mathrm{R}\left(s_t, \pi\left(s_t\right)\right) \mid s_0=s\right]
\mathrm{V}_h^\pi(s):=
(eq. 1️⃣)
Outside 6.390, the expectation can also be over random rewards and random policies.
s_0 = s
\Big|
\( h\) terms
evaluate \(\mathrm{V}_h^\pi(s)\) under the “always-up” policy
states and
one special transition:
rewards
- \(\pi(s) = ``\uparrow",\ \forall s\)
- \(\gamma = 0.9\)
80\%
20\%
\underbrace{\hspace{4.6cm}}
\mathrm{V}_h^\uparrow(s) = \mathbb{E}\Big[\mathrm{R}(s, \uparrow)+\gamma \mathrm{R}(s_1, \uparrow) + \dots + \gamma^{h-1}\mathrm{R}(s_{h-1}, \uparrow)\Big]
\mathrm{V}^{\uparrow}_0(s) = 0
0
0
0
0
0
0
0
horizon \(h\) = 0: no steps left
0
0
0
0
0
0
1
-10
horizon \(h\) = 1: receive the rewards
\mathrm{V}^{\uparrow}_1(s) = \mathrm{R}(s, \uparrow)
0
0
0
0
0
\mathrm{R}(1, \uparrow) + \gamma \mathrm{R}(1, \uparrow)
0
\mathrm{R}(2, \uparrow) + \gamma \mathrm{R}(2, \uparrow)
1.9
\mathrm{R}(3, \uparrow) + \gamma \mathrm{R}(3, \uparrow)
0
\mathrm{R}(4, \uparrow) + \gamma \mathrm{R}(1, \uparrow)
= 1 + 0.9 \times (1) \Rightarrow 1.9
\mathrm{R}(5, \uparrow) + \gamma \mathrm{R}(2, \uparrow)
horizon \(h = 2\)
states and
one special transition:
rewards
- \(\pi(s) = ``\uparrow",\ \forall s\)
- \(\gamma = 0.9\)
80\%
20\%
\mathrm{V}^{\uparrow}_2(s) = \mathbb{E}\Big[\mathrm{R}(s, \uparrow)+\gamma \mathrm{R}(s_1, \uparrow)\Big]
\( 2\) terms
\underbrace{\hspace{2cm}}
-9
0
0
-9.28
\mathrm{R}(6, \uparrow) + \gamma [.2 \mathrm{R}(2, \uparrow) + .8 \mathrm{R}(3, \uparrow)]
\mathrm{R}(8, \uparrow) + \gamma \mathrm{R}(5, \uparrow)
\mathrm{R}(7, \uparrow) + \gamma \mathrm{R}(4, \uparrow)
\mathrm{R}(9, \uparrow) + \gamma \mathrm{R}(6, \uparrow)
= -10 + .9 \times (.2 \times 0 + .8 \times 1)
\Rightarrow -9.28
= 0 + 0.9 \times (-10) \Rightarrow -9
action \(\uparrow\)
\mathrm{R}(6, \uparrow)
20\%
80\%
action \(\uparrow\)
\mathrm{R}(2, \uparrow)
\gamma
action \(\uparrow\)
\mathrm{R}(3, \uparrow)
\gamma
horizon \(h = 2\)
states and
one special transition:
rewards
- \(\pi(s) = ``\uparrow",\ \forall s\)
- \(\gamma = 0.9\)
80\%
20\%
0
0
0
1.9
0
\( 2\) terms
\underbrace{\hspace{2cm}}
\mathrm{V}^{\uparrow}_2(s) = \mathbb{E}\Big[\mathrm{R}(s, \uparrow)+\gamma \mathrm{R}(s_1, \uparrow)\Big]
\mathrm{V}^{\uparrow}_3(6)
action \(\uparrow\)
action \(\uparrow\)
action \(\uparrow\)
action \(\uparrow\)
action \(\uparrow\)
20\%
80\%
80\%
\mathrm{R}(6, \uparrow)
\gamma \mathrm{R}(2, \uparrow)
20\%
+
+
\gamma \mathrm{R}(2, \uparrow)
\gamma^2 \mathrm{R}(2, \uparrow)
\gamma \mathrm{R}(3, \uparrow)
\mathrm{R}(6, \uparrow)
\gamma^2\mathrm{R}(3, \uparrow)
\gamma^2 \mathrm{R}(2, \uparrow)
\gamma \mathrm{R}(3, \uparrow)
20\%
+
80\%
\gamma^2\mathrm{R}(3, \uparrow)
+
=
states and
one special transition:
rewards
- \(\pi(s) = ``\uparrow",\ \forall s\)
- \(\gamma = 0.9\)
80\%
20\%
\mathrm{R}(6, \uparrow)
\gamma \mathrm{R}(2, \uparrow)
20\%
+
+
\gamma^2 \mathrm{R}(2, \uparrow)
\gamma \mathrm{R}(3, \uparrow)
80\%
+
\gamma^2\mathrm{R}(3, \uparrow)
=
+
[
]
]
[
=
+
\left[\mathrm{R}(3, \uparrow) + \gamma \mathrm{R}(3, \uparrow)\right]
\gamma
+
80\%
\mathrm{R}(6, \uparrow)
\left[\mathrm{R}(2, \uparrow) + \gamma \mathrm{R}(2, \uparrow)\right]
\gamma
20\%
=
80\%
\gamma
20\%
+
\mathrm{V}^{\uparrow}_2(2)
\gamma
+
\mathrm{R}(6, \uparrow)
\mathrm{V}^{\uparrow}_2(3)
horizon \(h = 3\)
\( 3\) terms
\underbrace{\hspace{3.5cm}}
\mathrm{V}^{\uparrow}_3(s) = \mathbb{E}\Big[\mathrm{R}(s, \uparrow)+\gamma \mathrm{R}(s_1, \uparrow)+\gamma^2 \mathrm{R}(s_2, \uparrow)\Big]
\mathrm{V}_h^\pi(s)=\mathrm{R}\left(s, \pi(s)\right)+\gamma \sum_{s^{\prime}} \mathrm{T}\left(s, \pi(s), s^{\prime}\right) \mathrm{V}_{h-1}^\pi\left(s^{\prime}\right)
the immediate reward for taking the policy-prescribed action \(\pi(s)\) in state \(s\).
horizon-\(h\) value in state \(s\): the expected sum of discounted rewards, starting in state \(s\) and following policy \(\pi\) for \(h\) steps.
\mathrm{V}^{\uparrow}_3(6)
=
80\%
\gamma
20\%
+
\mathrm{V}^{\uparrow}_2(2)
\gamma
+
\mathrm{R}(6, \uparrow)
\mathrm{V}^{\uparrow}_2(3)
\((h-1)\) horizon future value at a next state \(s^{\prime}\)
sum of future values weighted by the probability of reaching that next state \(s^{\prime}\)
discounted by \(\gamma\)
(eq. 2️⃣)
\mathrm{V}_h^\pi(s)=\mathrm{R}\left(s, \pi(s)\right)+\gamma \sum_{s^{\prime}} \mathrm{T}\left(s, \pi(s), s^{\prime}\right) \mathrm{V}_{h-1}^\pi\left(s^{\prime}\right)
Bellman Recursion (eq. 2️⃣)
= 0 + 0.9\times[-10]
\mathrm{V}^{\uparrow}_{2}(9) = \mathrm{R}(9, \uparrow) + \gamma [\mathrm{V}^{\uparrow}_{1}(6)]
= -9
states and
one special transition:
rewards
- \(\pi(s) = ``\uparrow",\ \forall s\)
- \(\gamma = 0.9\)
80\%
20\%
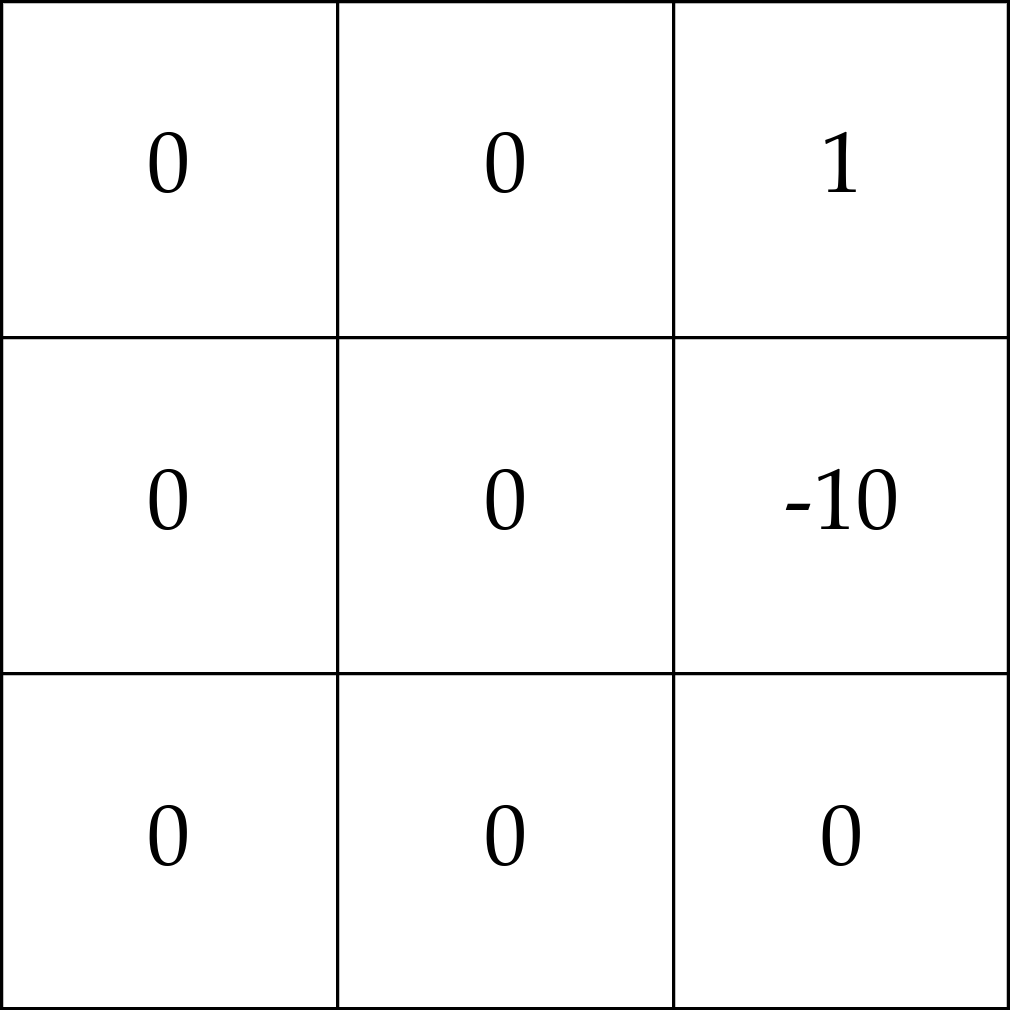
\mathrm{V}^{\uparrow}_1(s) = \mathrm{R}(s,\uparrow)
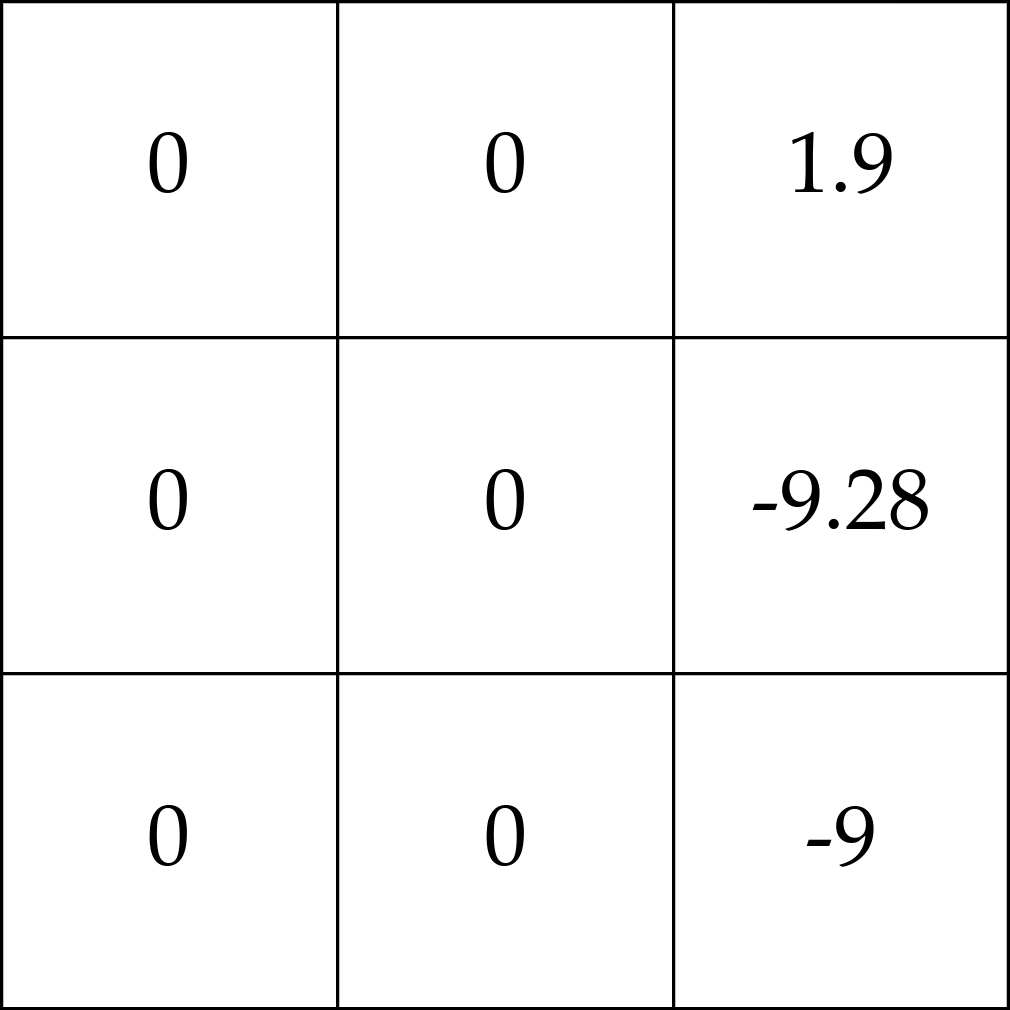
\mathrm{V}^{\uparrow}_2(s)
\mathrm{V}_h^\pi(s)=\mathrm{R}\left(s, \pi(s)\right)+\gamma \sum_{s^{\prime}} \mathrm{T}\left(s, \pi(s), s^{\prime}\right) \mathrm{V}_{h-1}^\pi\left(s^{\prime}\right)
= -10 +.9[.2\times0+.8\times1.9]
\mathrm{V}^{\uparrow}_{3}(6) = \mathrm{R}(6, \uparrow) + \gamma [.2 \times \mathrm{V}^{\uparrow}_{2}(2) + .8\times \mathrm{V}^{\uparrow}_{2}(3)]
= -8.632
states and
one special transition:
rewards
- \(\pi(s) = ``\uparrow",\ \forall s\)
- \(\gamma = 0.9\)
80\%
20\%
\mathrm{V}^{\uparrow}_1(s) = \mathrm{R}(s,\uparrow)
\mathrm{V}^{\uparrow}_2(s)
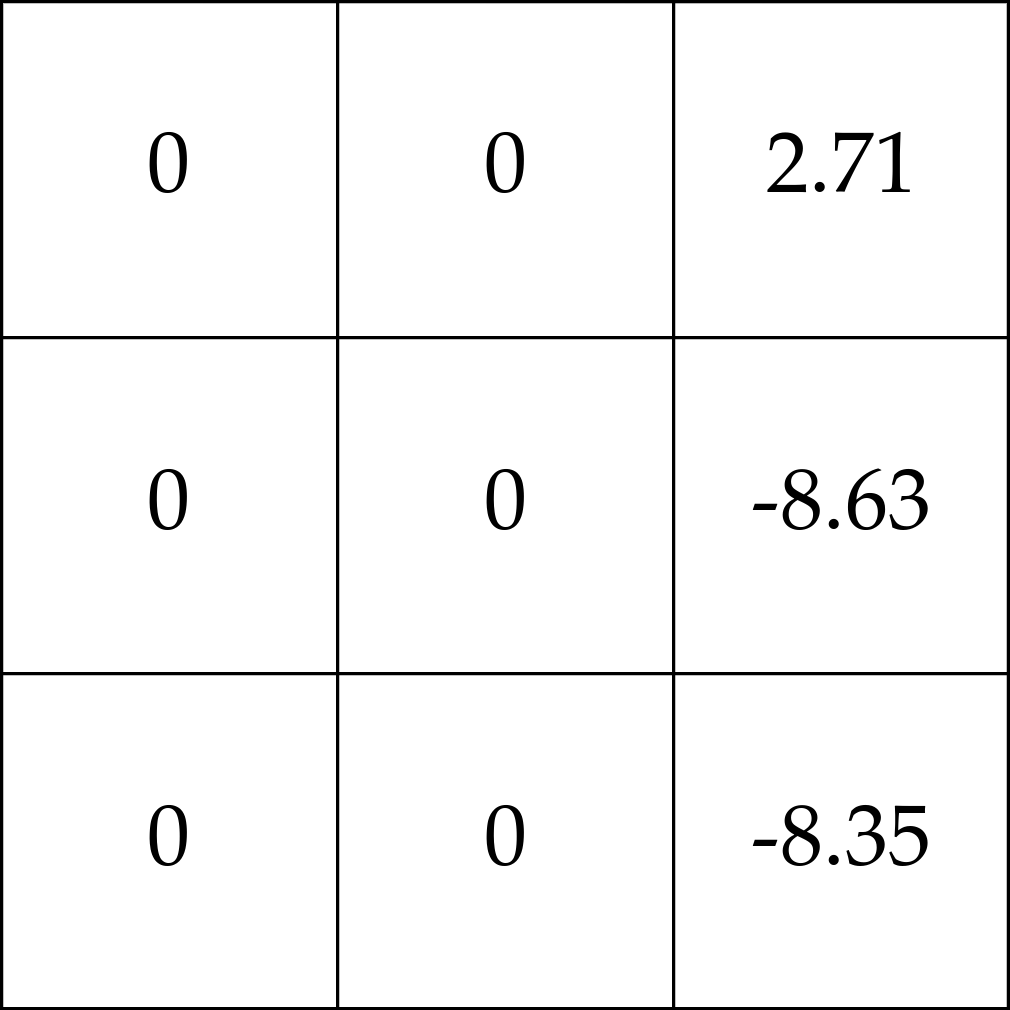
\mathrm{V}^{\uparrow}_3(s)
Bellman Recursion (eq. 2️⃣)
Check-in:
to fill one entry of the \(\mathrm{V}_3\) table, which tables do we need?
Just \(\mathrm{V}_2\) and \(\mathrm{R}\).
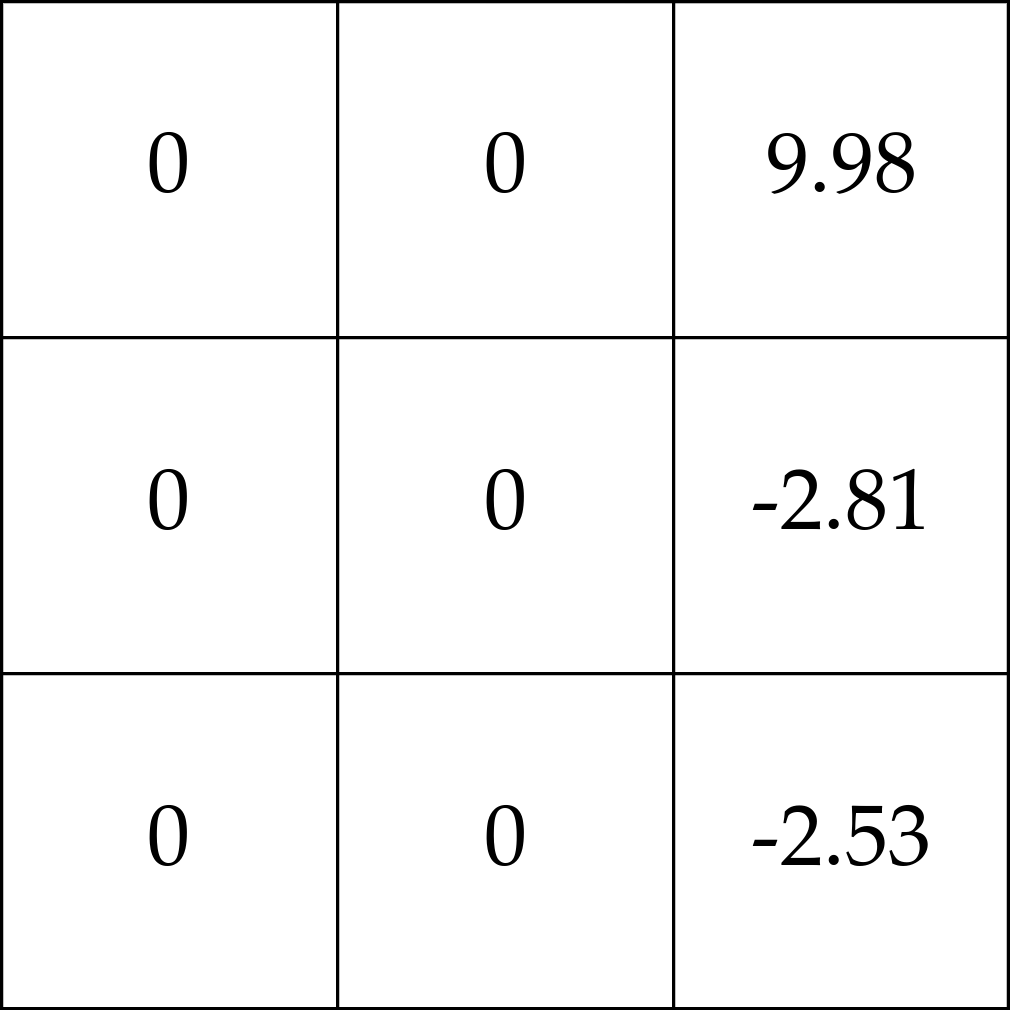
\mathrm{V}^{\uparrow}_{60}(s)
\mathrm{V}^{\uparrow}_{61}(s)
states and
one special transition:
rewards
- \(\pi(s) = ``\uparrow",\ \forall s\)
- \(\gamma = 0.9\)
80\%
20\%
\mathrm{V}_h^\pi(s)=\mathrm{R}\left(s, \pi(s)\right)+\gamma \sum_{s^{\prime}} \mathrm{T}\left(s, \pi(s), s^{\prime}\right) \mathrm{V}_{h-1}^\pi\left(s^{\prime}\right)
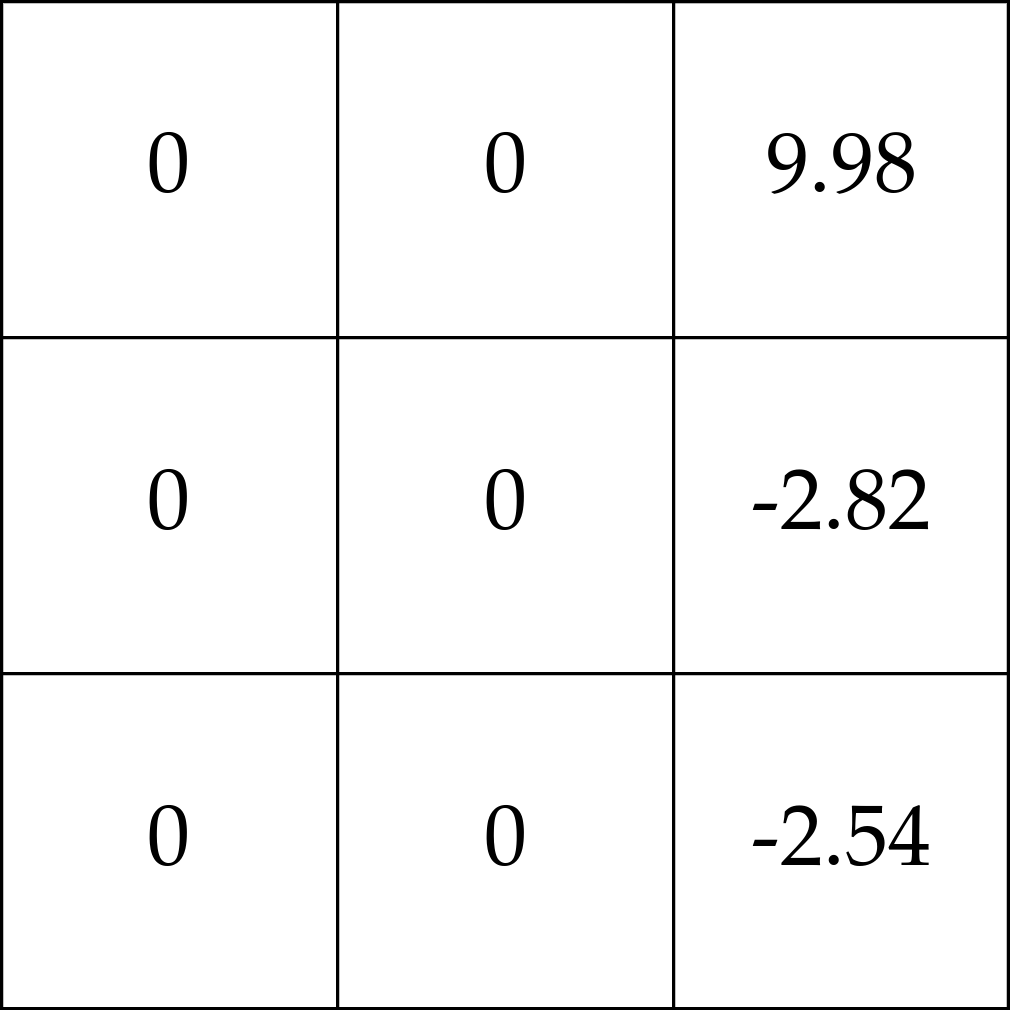
\mathrm{V}^{\uparrow}_{59}(s)
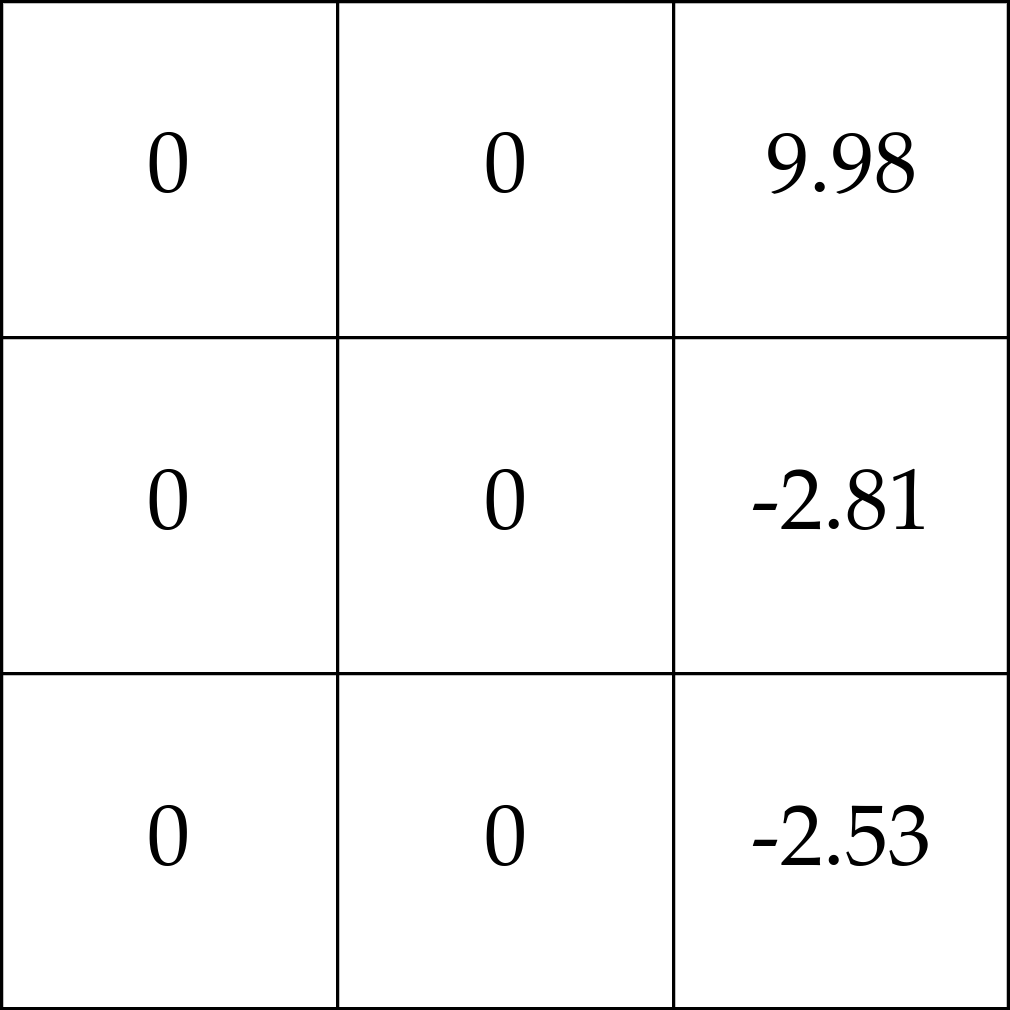
= -10 +.9[.2\times0+.8\times9.98]
\mathrm{V}^{\uparrow}_{61}(6) = \mathrm{R}(6, \uparrow) + \gamma [.2 \times \mathrm{V}^{\uparrow}_{60}(2) + .8\times \mathrm{V}^{\uparrow}_{60}(3)]
= -2.8144
\dots
Bellman Recursion (eq. 2️⃣)
\mathrm{V}^{\uparrow}_{60}(s)
\mathrm{V}^{\uparrow}_{61}(s)
states and
one special transition:
rewards
- \(\pi(s) = ``\uparrow",\ \forall s\)
- \(\gamma = 0.9\)
80\%
20\%
\dots
\mathrm{V}^{\uparrow}_{\infty}(s)
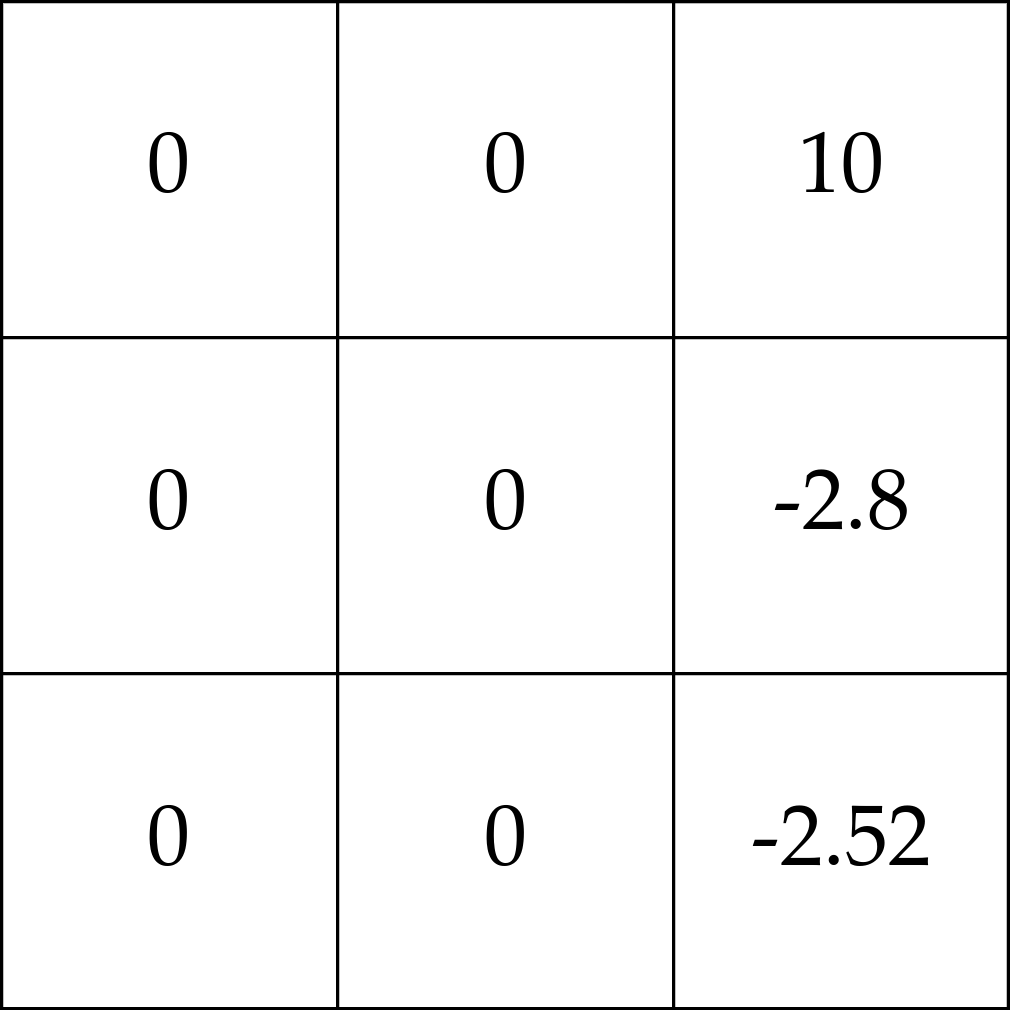
- As we extend the horizon, each new table differs less from the last
- because longer-term rewards are heavily discounted
- so, as \(h \to \infty,\) the value functions stop changing
- convergence can be seen, e.g., via \(\mathrm{V}^{\uparrow}_{\infty}(3)=1+.9+.9^2+.9^3 + \dots =10\)
Value functions converge as \(h \to \infty\)
Typically, \(\gamma < 1\) to ensure \(\mathrm{V}_{\infty}\) is finite.
Recursion (finite \(h\)) 2️⃣
As horizon \(h \to \infty,\) the Bellman recursion becomes the Bellman equation
Equation \((h\to \infty)\) 3️⃣
\mathrm{V}^\pi_{\infty}(s)= \mathrm{R}(s, \pi(s))+ \gamma \sum_{s^{\prime}} \mathrm{T}\left(s, \pi(s), s^{\prime}\right) \mathrm{V}^\pi_{\infty}\left(s^{\prime}\right)
\mathrm{V}_h^\pi(s)=\mathrm{R}\left(s, \pi(s)\right)+\gamma \sum_{s^{\prime}} \mathrm{T}\left(s, \pi(s), s^{\prime}\right) \mathrm{V}_{h-1}^\pi\left(s^{\prime}\right)
A system of \(|\mathcal{S}|\) self-consistent linear equations, one for each state
two different tables: \(\mathrm{V}_h\) is filled in from \(\mathrm{V}_{h-1}\)
the same table on both sides
Bellman Equation (eq. 3️⃣)
\mathrm{V}^\pi_{\infty}(s)= \mathrm{R}(s, \pi(s))+ \gamma \sum_{s^{\prime}} \mathrm{T}\left(s, \pi(s), s^{\prime}\right) \mathrm{V}^\pi_{\infty}\left(s^{\prime}\right)
states and
one special transition:
rewards
- \(\pi(s) = ``\uparrow",\ \forall s\)
- \(\gamma = 0.9\)
80\%
20\%
\mathrm{V}^{\uparrow}_{\infty}(s)
\mathrm{V}^{\uparrow}_{\infty}(3) = \mathrm{R}(3, \uparrow) + \gamma [\mathrm{V}^{\uparrow}_{\infty}(3)]
= 1 + .9 \times 10 \Rightarrow 10
\mathrm{V}^{\uparrow}_{\infty}(9) = \mathrm{R}(9, \uparrow) + \gamma [\mathrm{V}^{\uparrow}_{\infty}(6)]
= 0 + .9 \times [-2.8] \Rightarrow -2.52
finite horizon: Bellman recursion
infinite horizon: Bellman equation
\mathrm{V}^\pi_{\infty}(s)= \mathrm{R}(s, \pi(s))+ \gamma \sum_{s^{\prime}} \mathrm{T}\left(s, \pi(s), s^{\prime}\right) \mathrm{V}^\pi_{\infty}\left(s^{\prime}\right)
\mathrm{V}_{h}^\pi(s)= \mathrm{R}(s, \pi(s))+ \gamma \sum_{s^{\prime}} \mathrm{T}\left(s, \pi(s), s^{\prime}\right) \mathrm{V}_{h-1}^\pi\left(s^{\prime}\right)
\pi(s)
\mathrm{V}^{\pi}_{h}(s)
Policy Evaluation
Quick summary
By definition:
Or, by recursion:
\mathrm{V}_h^\pi(s):=\mathbb{E}\left[\sum_{t=0}^{h-1} \gamma^t \mathrm{R}\left(s_t, \pi\left(s_t\right)\right) \mid s_0=s\right]
1️⃣
2️⃣
3️⃣
\(\mathrm{V}^{\pi}_h(s)\): the value of state \(s\), under policy \(\pi\), with \(h\) steps to go
Outline
-
Markov Decision Processes Definition
-
Policy Evaluation
-
Policy Optimization
-
Optimal policies \(\pi^*\)
-
Optimal state-action value functions: \(\mathrm{Q}^*\)
-
Value iteration
-
For a given horizon \(h\), an optimal policy \(\pi^*_h\) is one such that:
\(\mathrm{V}^*_h(s) = \mathrm{V}^{\pi^*_h}_h(s) \ge \mathrm{V}^{\pi}_h(s)\) for every state \(s\) and every policy \(\pi\)
Optimal policy \(\pi^*\)
- How do we get the \(\mathrm{V}^*\) table?
- Even with the \(\mathrm{V}^*\) table in hand, it’s not obvious how to act optimally.
\(\mathrm{V}^{\uparrow}_{\infty}(s)\)
\(\mathrm{V}^{*}_{\infty}(s)\)
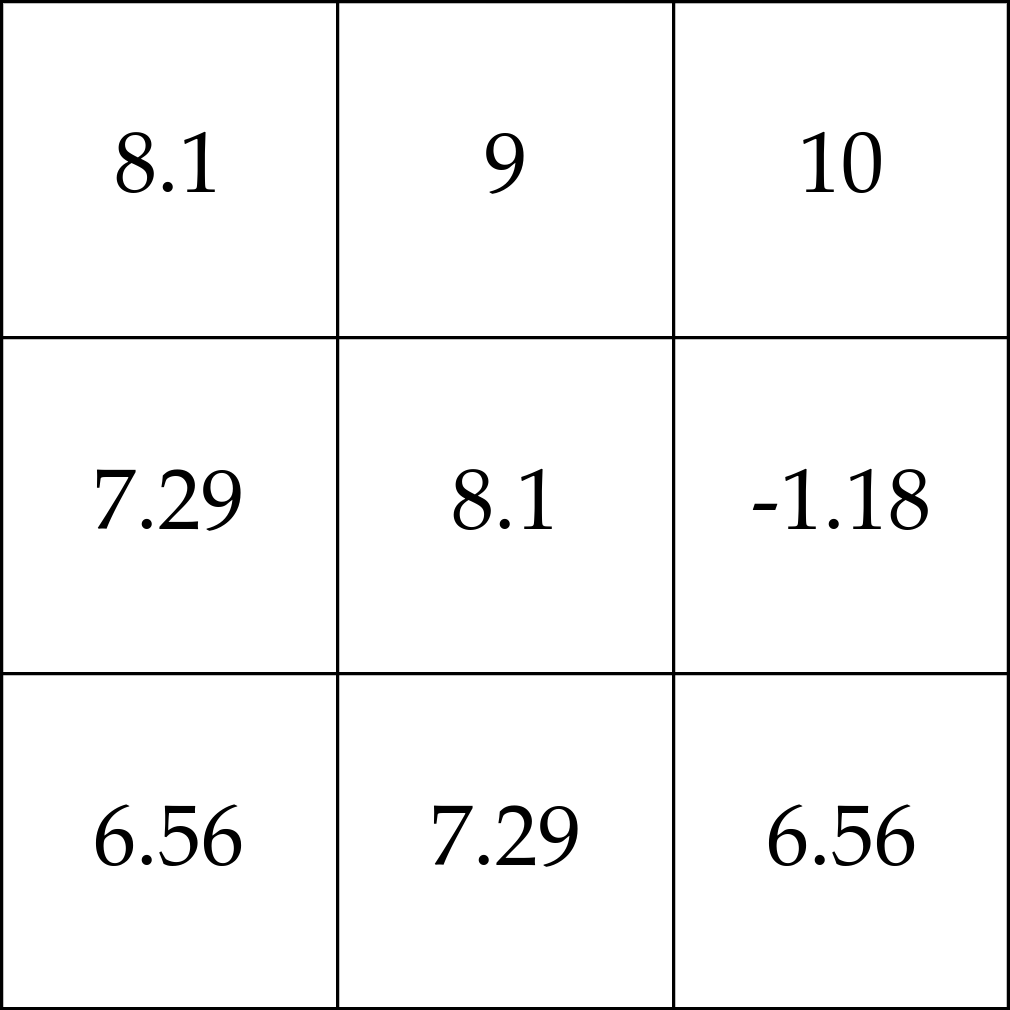
\(\ge\)
in every
state
For example, for Mario:
acting optimally, horizon \(h = 1\)
states and
one special transition:
rewards
- no policy given,
we choose \(a\) - \(\gamma = 0.9\)
80\%
20\%
\(\mathrm{V}^*_1(s)\)
0
0
1
0
0
-10
0
0
0
?
from 3
\(a_0 = \,{\uparrow}\)
\(a_0 = \,{\leftarrow}\)
\(a_0 = \,{\downarrow}\)
\(a_0 = \,{\rightarrow}\)
reward
\(r_0 = 1\)
\(r_0 = 1\)
\(r_0 = 1\)
\(r_0 = 1\)
\mathrm{V}^*_1(3) = \hspace{0.3em}\max\hspace{0.3em} = 1
- With one step left, only the reward now matters.
- So \(\mathrm{V}^*_1(s) = \hspace{0.3em}\max_a\hspace{0.25em}\mathrm{R}(s, a)\), in every state.
acting optimally, horizon \(h = 2\)
states and
one special transition:
rewards
- no policy given,
we choose \(a\) - \(\gamma = 0.9\)
80\%
20\%
\(\mathrm{V}^*_1(s)\)
\(\mathrm{V}^*_2(s)\)
0
0
1
0
0
-10
0
0
0
0
0.9
1.9
0
0
-9.28
0
0
0
from 3
\(a_0 = \,{\uparrow}\)
\(a_0 = \,{\leftarrow}\)
\(a_0 = \,{\downarrow}\)
\(a_0 = \,{\rightarrow}\)
reward
\(r_0 = 1\)
\(r_0 = 1\)
\(r_0 = 1\)
\(r_0 = 1\)
lands in
\(s_1 = 3\)
\(s_1 = 2\)
\(s_1 = 6\)
\(s_1 = 3\)
\(r_0 + 0.9\,\mathrm{V}^*_1(s_1)\)
\(1 + 0.9 \cdot \mathrm{V}^*_1(3) = 1.9\)
\(1 + 0.9 \cdot \mathrm{V}^*_1(2) = 1\)
\(1 + 0.9 \cdot \mathrm{V}^*_1(6) = -8\)
\(1 + 0.9 \cdot \mathrm{V}^*_1(3) = 1.9\)
\mathrm{V}^*_2(3) = \hspace{0.3em}\max\hspace{0.3em} = 1.9
- The first action decides not only rewards but also future starting state.
- From any future start, how to act optimally for the remaining step?
?
- That’s exactly encoded in \(\mathrm{V}^*_1(s')\)!
\(\mathrm{V}_h^*(s) = \max_{a} \big[\mathrm{R}(s, a) + \gamma \sum_{s'} \mathrm{T}(s, a, s') \mathrm{V}_{h-1}^*(s') \big]\)
Policy \(\pi(s)\)
Transition \(\mathrm{T}\left(s, a, s^{\prime}\right)\)
Reward \(\mathrm{R}(s, a)\)
time
\dots
s_2
s_3
s_4
s_5
a_2
a_3
a_4
r_2
r_3
r_4
s_0
s_1
a_0
a_1
r_0
r_1
s_{h-2}
a_{h-2}
r_{h-2}
s_{h-1}
a_{h-1}
r_{h-1}
\underbrace{\hspace{6.8cm}}
\underbrace{\hspace{7.8cm}}
act optimally for \(h\) steps: \(\mathrm{V}_h^*(s)\)
then act optimally for the remaining \((h-1)\) steps: \(\mathrm{V}_{h-1}^*(s')\)
(new, eq. 4️⃣, for an optimal policy)
(recall, eq. 2️⃣, for any policy)
\mathrm{V}_h^\pi(s)=\mathrm{R}\left(s, \pi(s)\right)+\gamma \sum_{s^{\prime}} \mathrm{T}\left(s, \pi(s), s^{\prime}\right) \mathrm{V}_{h-1}^\pi\left(s^{\prime}\right)
a first action \(a\),
chosen with the future in mind
\(s_1 = s'\)
- starting in state \(s\)
- take action \(a\), for one step
- act optimally thereafter for the remaining \((h-1)\) steps
\(\mathrm{Q}^*_h(s, a)\), the optimal state-action value function, i.e. the value for:
(eq. 5️⃣)
(eq. 4️⃣)
\(\mathrm{V}_h^*(s) = \max_{a} \big[\mathrm{R}(s, a) + \gamma \sum_{s'} \mathrm{T}(s, a, s') \mathrm{V}_{h-1}^*(s') \big]\)
\(= \max_{a} \kern0.38em \mathrm{Q}^*_h(s, a)\)
\(\mathrm{Q}^*_h(s, a) = \mathrm{R}(s, a) + \gamma \sum_{s'} \mathrm{T}(s, a, s') \max_{a'} \mathrm{Q}^*_{h-1}(s', a')\)
From eq. 4 to eq. 5:
\(\begin{aligned} \mathrm{Q}^*_h(s, a) &= \mathrm{R}(s, a) + \gamma \sum\nolimits_{s'} \mathrm{T}(s, a, s')\, \mathrm{V}_{h-1}^*(s') && \text{(the two green boxes in eq. 4 are equal)} \\ &= \mathrm{R}(s, a) + \gamma \sum\nolimits_{s'} \mathrm{T}(s, a, s') \max\nolimits_{a'} \mathrm{Q}^*_{h-1}(s', a') && \text{(eq. 4 at horizon } h-1 \text{: } \mathrm{V}_{h-1}^*(s') = \max\nolimits_{a'} \mathrm{Q}^*_{h-1}(s', a') \text{)} \end{aligned}\)
\(\mathrm{Q}^*_0\) and \(\mathrm{Q}^*_1\)
states and
one special transition:
rewards
- no policy given,
we choose \(a\) - \(\gamma = 0.9\)
80\%
20\%
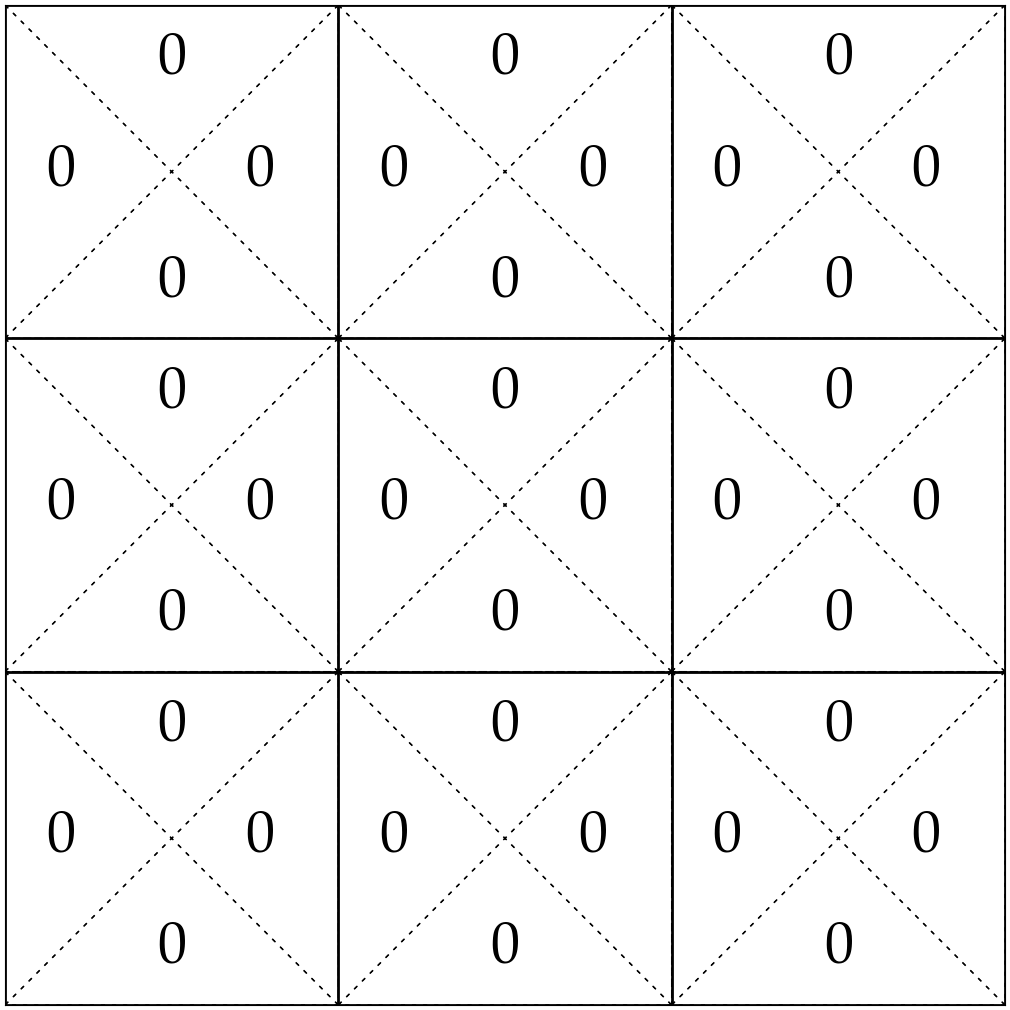
\mathrm{Q}^*_0(s, a)
\mathrm{Q}^*_1(s, a)
=\mathrm{R}(s, a)
eq. 5️⃣ with \(h = 1\):
\(\mathrm{Q}^*_1(s,a)\)
\(= \mathrm{R}(s,a)\) \(+\ \gamma \sum_{s^{\prime}} \mathrm{T}(s,a,s^{\prime}) \max_{a^{\prime}} \mathrm{Q}^*_0(s^{\prime},a^{\prime})\)
\(= \mathrm{R}(s,a)\) since \(\mathrm{Q}^*_0\) is all zeros
\(\mathrm{Q}^*_h(s, a)\): the value for
starting in state \(s\),
take action \(a\), for one step
act optimally thereafter for the remaining \((h-1)\) steps
by convention: with no
steps left, every value is 0
building \(\mathrm{Q}^*_2\): the entry \((3, \downarrow)\)
states and
one special transition:
rewards
- no policy given,
we choose \(a\) - \(\gamma = 0.9\)
80\%
20\%
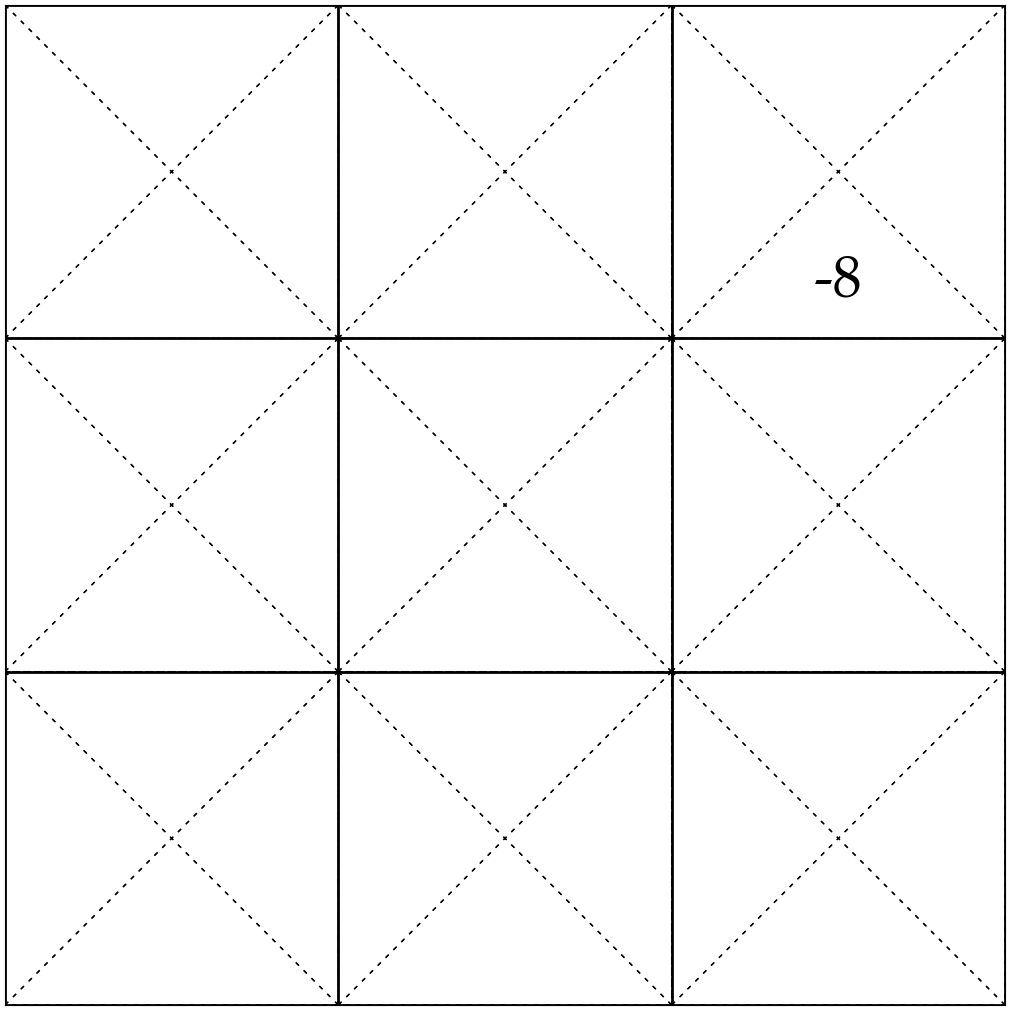
\mathrm{Q}^*_2(s, a)
\mathrm{Q}^*_1(s, a)
receive \(\mathrm{R}(3,\downarrow)\)
then act optimally from \(s' = 6\)
get \(\max_{a'} \mathrm{Q}^*_1(6, a')\)
\(\mathrm{Q}_2^*(3, \downarrow) = \mathrm{R}(3,\downarrow) + \gamma \max _{a^{\prime}} \mathrm{Q}_{1}^*\left(6, a^{\prime}\right)\)
\( = 1 + .9\times -10\)
\( = -8\)
?
building \(\mathrm{Q}^*_2\): the entry \((6, \uparrow)\)
states and
one special transition:
rewards
- no policy given,
we choose \(a\) - \(\gamma = 0.9\)
80\%
20\%
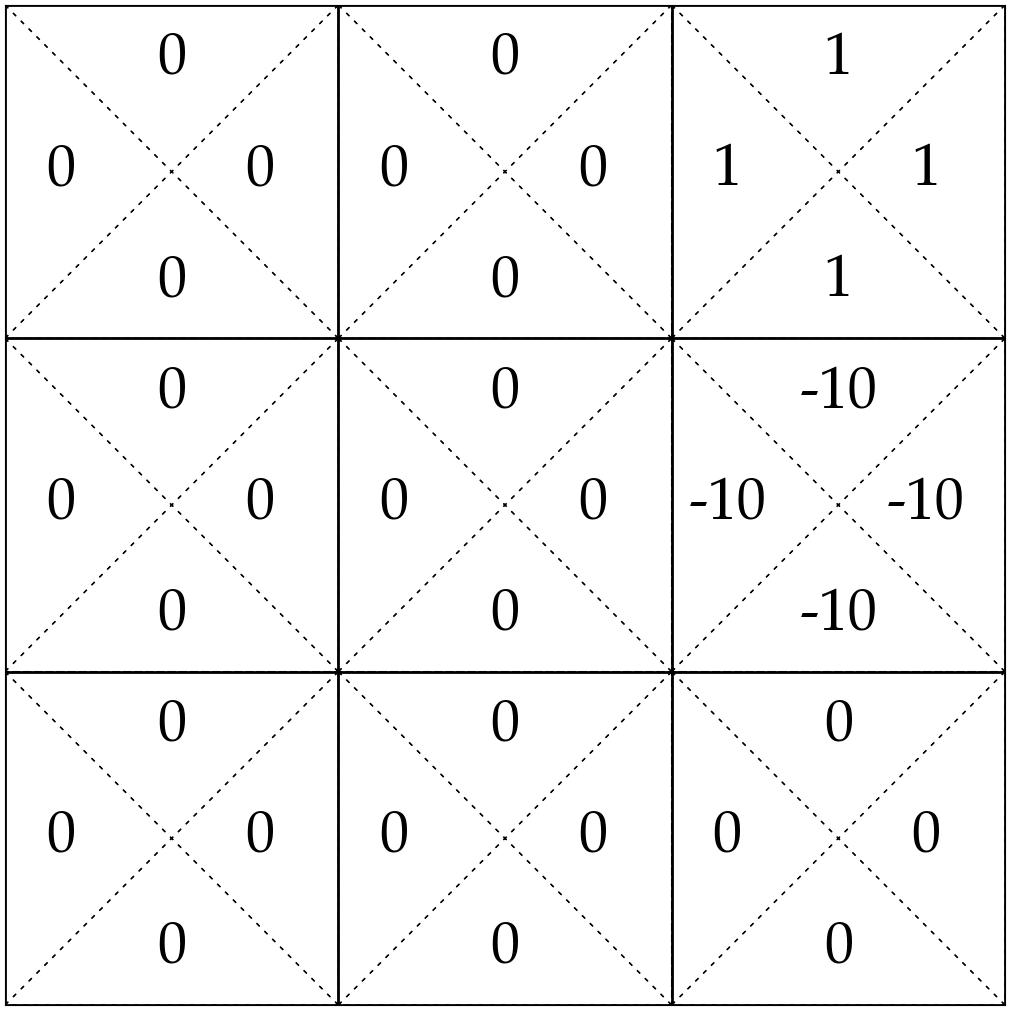
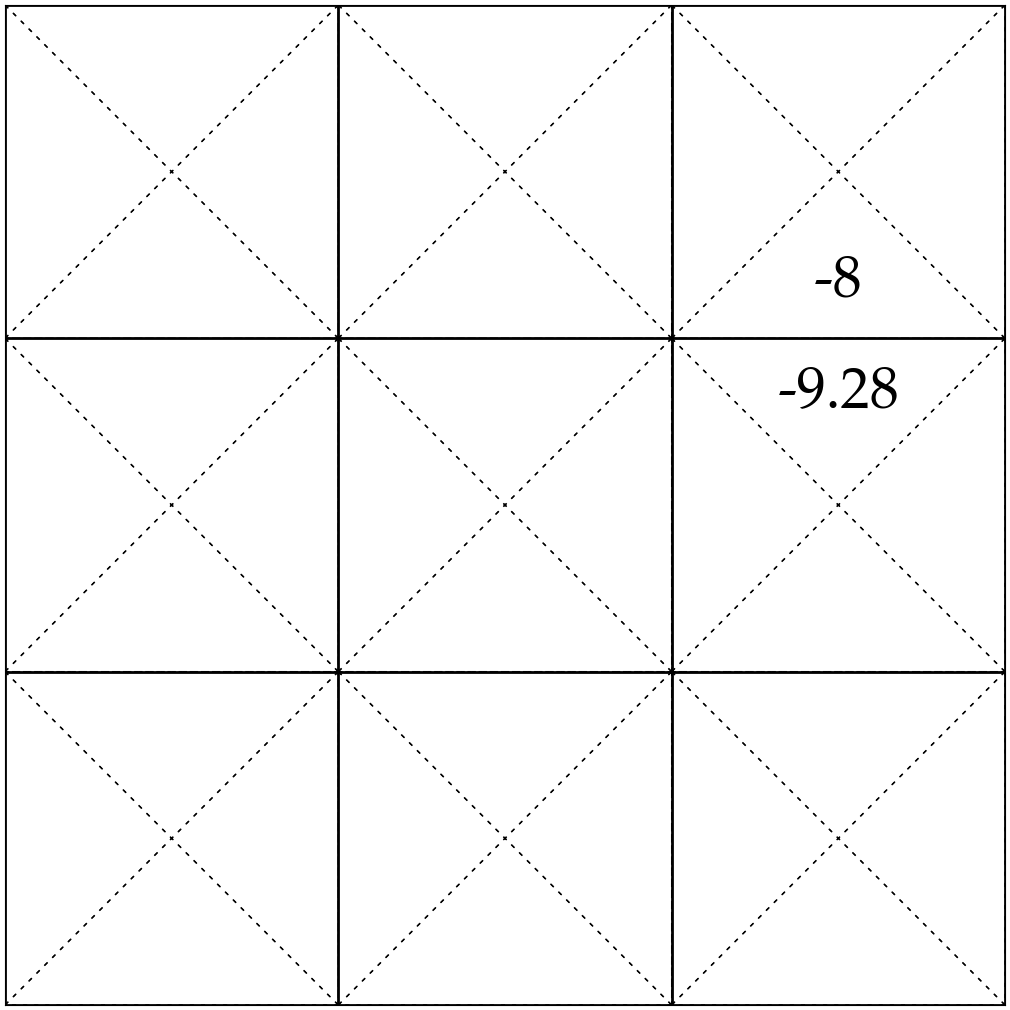
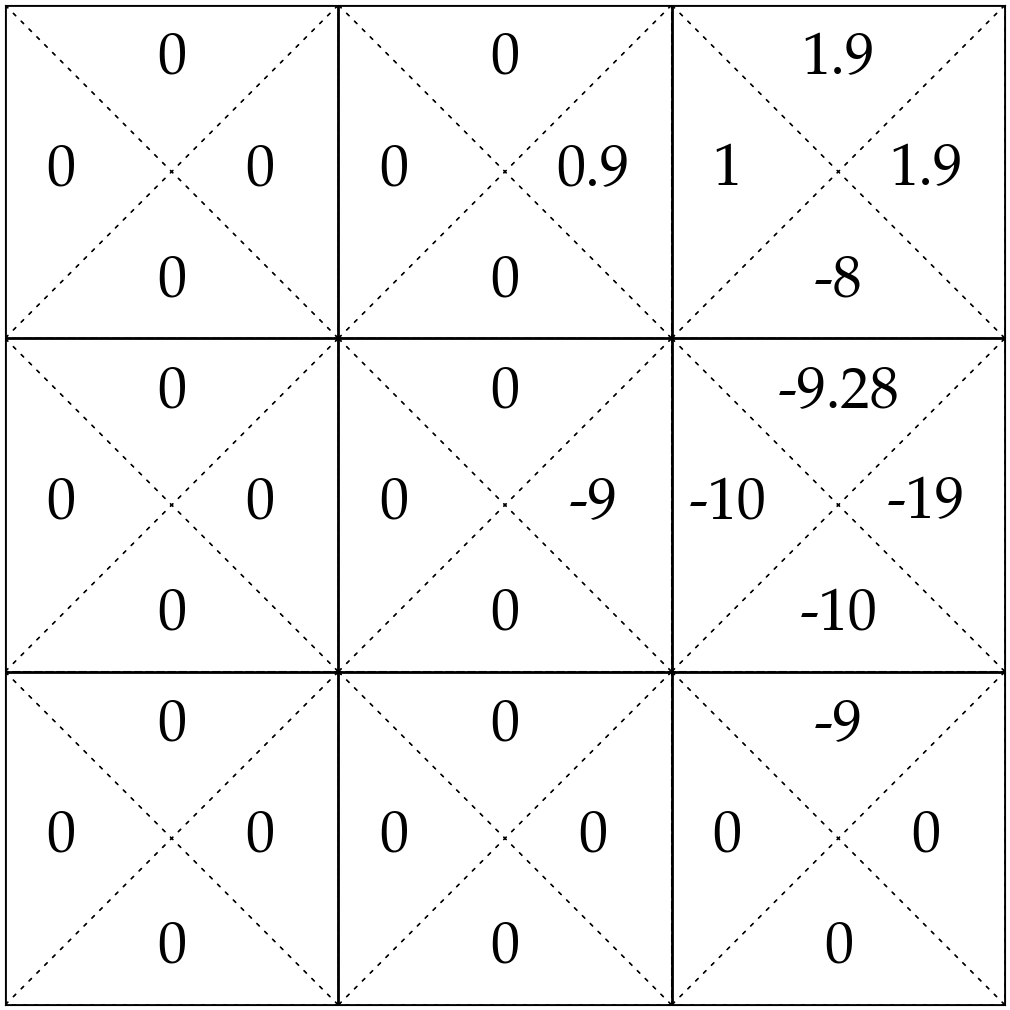
\mathrm{Q}^*_1(s, a)
\mathrm{Q}^*_2(s, a)
\(\mathrm{Q}_2^*(6, \uparrow)=\mathrm{R}(6,\uparrow) + \gamma[.2 \max _{a^{\prime}} \mathrm{Q}_{1}^*\left(2, a^{\prime}\right)+ .8\max _{a^{\prime}} \mathrm{Q}_{1}^*\left(3, a^{\prime}\right)] \)
\(= -10 + .9 [.2 \times 0+ .8 \times 1] \Rightarrow -9.28\)
receive \(\mathrm{R}(6,\uparrow)\)
then act optimally from \(s'\):
20%: \(s' = 2\), get \(\max_{a'} \mathrm{Q}^*_1(2, a')\)
80%: \(s' = 3\), get \(\max_{a'} \mathrm{Q}^*_1(3, a')\)
The same process repeats for every other state and action.
?
\(\mathrm{V}^*\) is the max of \(\mathrm{Q}^*\)
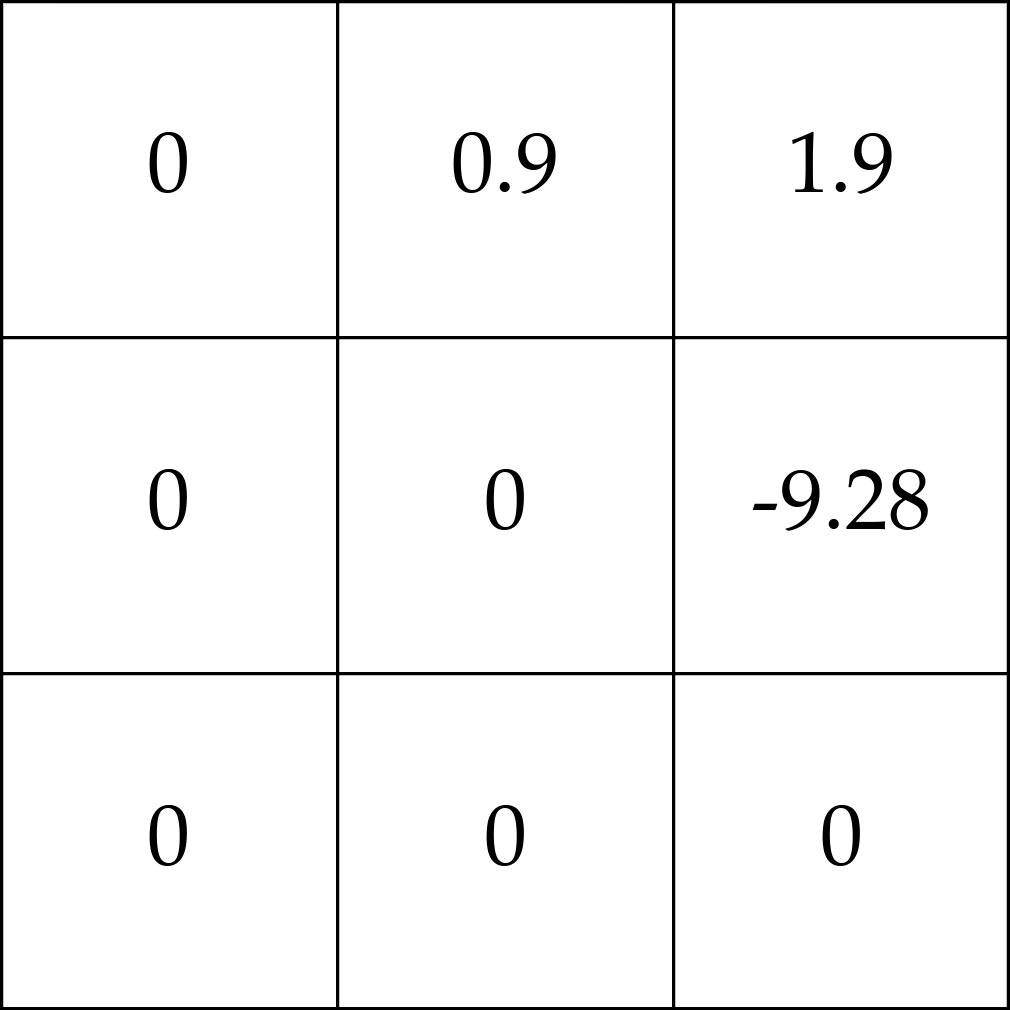
\(\mathrm{Q}^*_2(s, a)\)
\(\mathrm{V}^*_2(s)\)
\(\max_a\)
- \(\mathrm{V}^*_h(s) = \max_a \mathrm{Q}^*_h(s, a)\) holds for all states, for all horizons.
- Where does this max come from? Recall the definitions:
- \(\mathrm{V}^*_h\): act optimally for all \(h\) steps
- \(\mathrm{Q}^*_h\): an arbitrary first action \(a\), then act optimally for \(h-1\) steps
- So \(\mathrm{V}^*\) and \(\mathrm{Q}^*\) are different bookkeeping, and \(\mathrm{Q}^*\) is the more detailed one.
building \(\mathrm{Q}^*_3\): the entry \((6, \uparrow)\)
states and
one special transition:
rewards
- no policy given,
we choose \(a\) - \(\gamma = 0.9\)
80\%
20\%
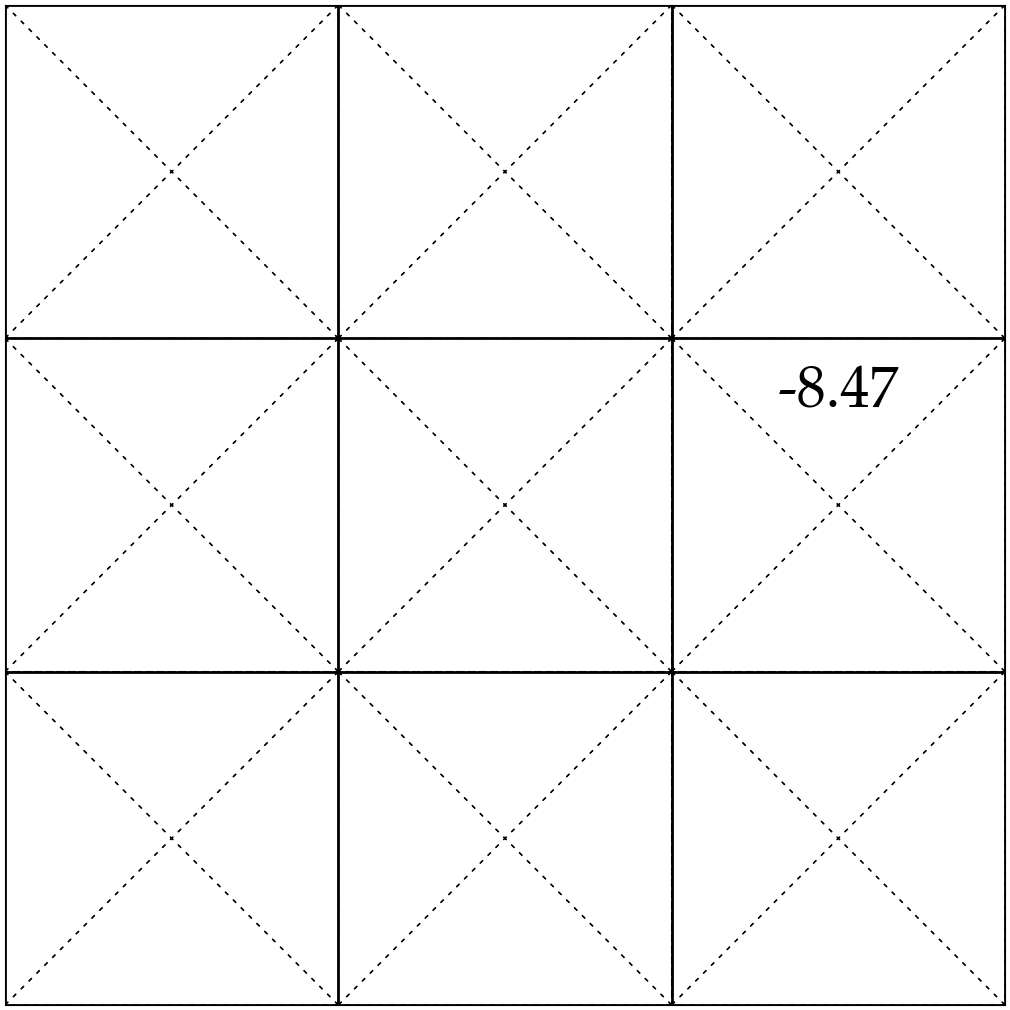
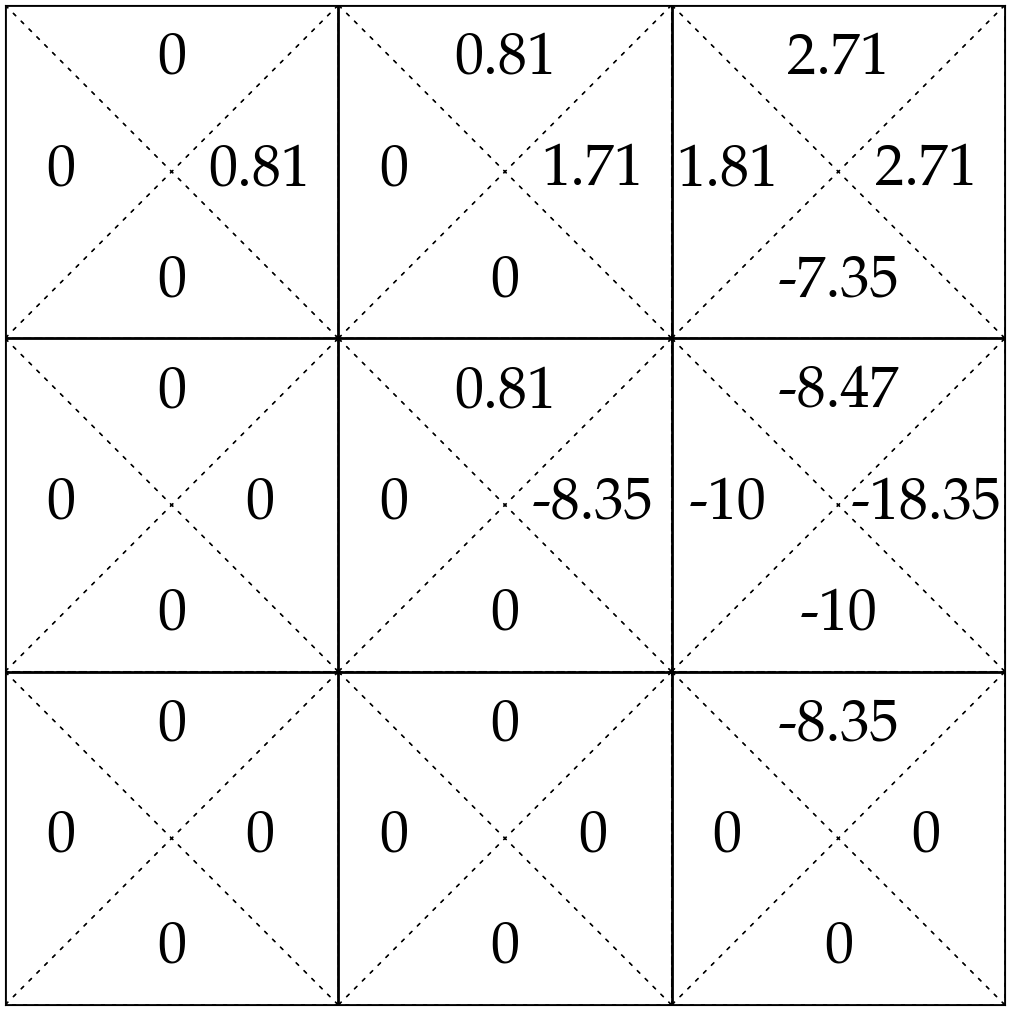
\mathrm{Q}^*_2(s, a)
\mathrm{Q}^*_3(s, a)
\(\mathrm{Q}_3^*(6, \uparrow)=\mathrm{R}(6,\uparrow) + \gamma[.2 \max _{a^{\prime}} \mathrm{Q}_{2}^*\left(2, a^{\prime}\right)+ .8\max _{a^{\prime}} \mathrm{Q}_{2}^*\left(3, a^{\prime}\right)] \)
receive \(\mathrm{R}(6,\uparrow)\)
then act optimally from \(s'\):
20%: \(s' = 2\), get \(\max_{a'} \mathrm{Q}^*_2(2, a')\)
80%: \(s' = 3\), get \(\max_{a'} \mathrm{Q}^*_2(3, a')\)
\(= -10 + .9 [.2 \times 0.9 + .8 \times 1.9] \Rightarrow -8.47\)
The same process repeats for every other state and action.
?
- for \(s \in \mathcal{S}, a \in \mathcal{A}\) :
- \(\mathrm{Q}_{\text {old }}(s, a)=0\)
- while True:
- for \(s \in \mathcal{S}, a \in \mathcal{A}\) :
- \(\mathrm{Q}_{\text {new }}(s, a) \leftarrow \mathrm{R}(s, a)+\gamma \sum_{s^{\prime}} \mathrm{T}\left(s, a, s^{\prime}\right) \max _{a^{\prime}} \mathrm{Q}_{\text {old }}\left(s^{\prime}, a^{\prime}\right)\)
- if \(\max _{s, a}\left|\mathrm{Q}_{\text {old }}(s, a)-\mathrm{Q}_{\text {new }}(s, a)\right|<\epsilon:\)
- return \(\mathrm{Q}_{\text {new }}\)
- \(\mathrm{Q}_{\text {old }} \leftarrow \mathrm{Q}_{\text {new }}\)
Value Iteration
if we run this block \(h\) times and then break, it returns exactly \(\mathrm{Q}^*_h\)
\{
\(\mathrm{Q}^*_{\infty}(s, a)\)
Value iteration: build \(\mathrm{Q}^*\) one horizon at a time (eq. 5️⃣)
\{
so \(\mathrm{Q}_{\text{old}} = \mathrm{Q}^*_0\)
if \(\mathrm{Q}_{\text{old}} = \mathrm{Q}^*_{h-1}\), then \(\mathrm{Q}_{\text{new}} = \mathrm{Q}^*_h\)
\mathrm{Q}_1^*(s, a)
\mathrm{Q}_2^*(s, a)
\pi_h^*(s)=\arg \max _a \mathrm{Q}^*_h(s, a)
So, how do we act? Read it off \(\mathrm{Q}^*\): 6️⃣
\mathrm{Q}_3^*(s, a)
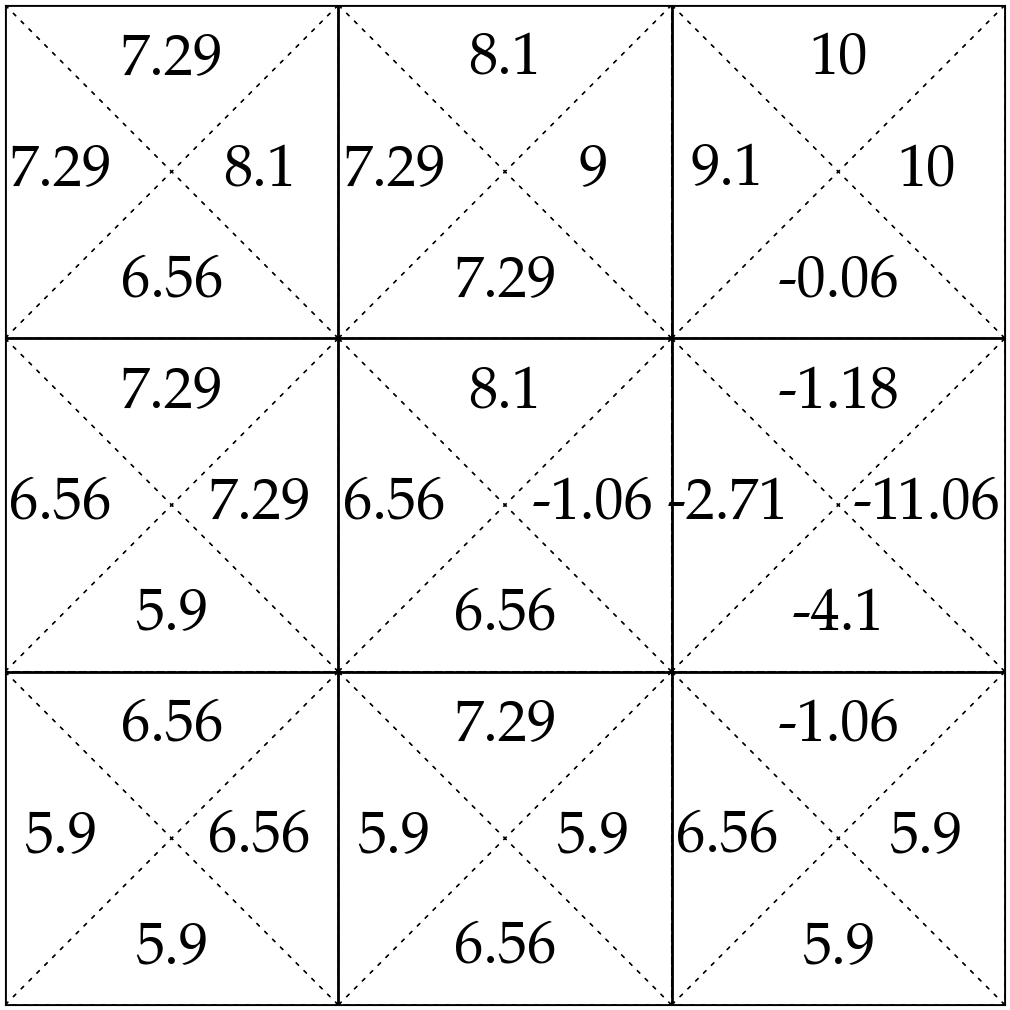
\mathrm{Q}_{\infty}^*(s, a)
\dots
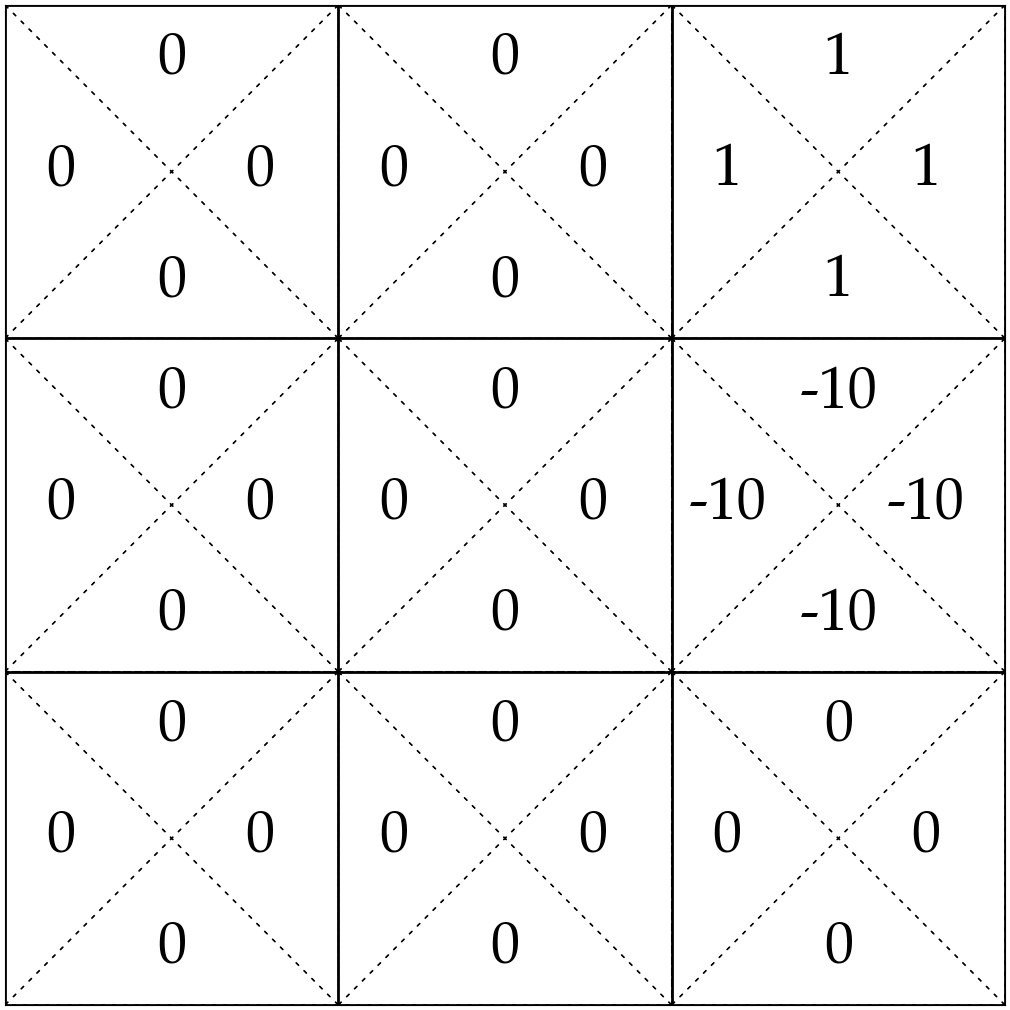
e.g. the best actions to take in state 5
- \(\mathrm{V}^*\) is unique, but \(\pi^*\) need not be: in state 5, several actions tie at \(h = 1, 2\)
- For finite \(h\), optimal policy \(\pi^*_h\) depends on how many time steps are left
- When \(h \rightarrow \infty\), time no longer matters, i.e., there exists a stationary \(\pi^*\)
Summary
- An MDP is defined by the five-tuple \((\mathcal{S}, \mathcal{A}, \mathrm{T}, \mathrm{R}, \gamma)\).
- Three value functions:
first action
remaining \(h-1\) steps
how we compute it
\(\mathrm{V}^{\pi}_h(s)\)
\(\pi(s)\), the policy's pick
keep following \(\pi\)
definition 1️⃣, recursion 2️⃣
as \(h \rightarrow \infty\), equation 3️⃣
\(\mathrm{V}^{*}_h(s)\)
the optimal first action
act optimally
\(\max_a \mathrm{Q}^*_h(s, a)\)
from the principle of optimality 4️⃣
\(\mathrm{Q}^{*}_h(s, a)\)
any action \(a\) we name
act optimally
value iteration 5️⃣
- Then act greedily: \(\pi^*_h(s) = \arg\max_a \mathrm{Q}^*_h(s, a)\) 6️⃣
- Next week, reinforcement learning: the same MDP, but \(\mathrm{T}\) and \(\mathrm{R}\) are unknown.
MDPs are also called stochastic optimal control, stochastic shortest path, or sequential decision making under uncertainty.
6.390 IntroML (Fall26) - Lecture 10 Markov Decision Processes
By Shen Shen