CS 4/5789: Introduction to Reinforcement Learning

Lecture 5: Proximal Policy Optimization

Prof. Sarah Dean

MW 1:25-2:40pm
155 Olin Hall

Reminders

  • Homework
    • PSet 2 released today
    • Project 1 due Friday
  • In-class Exam on 9/23


How should we update the policy parameters to improve the expected reward?

Agenda

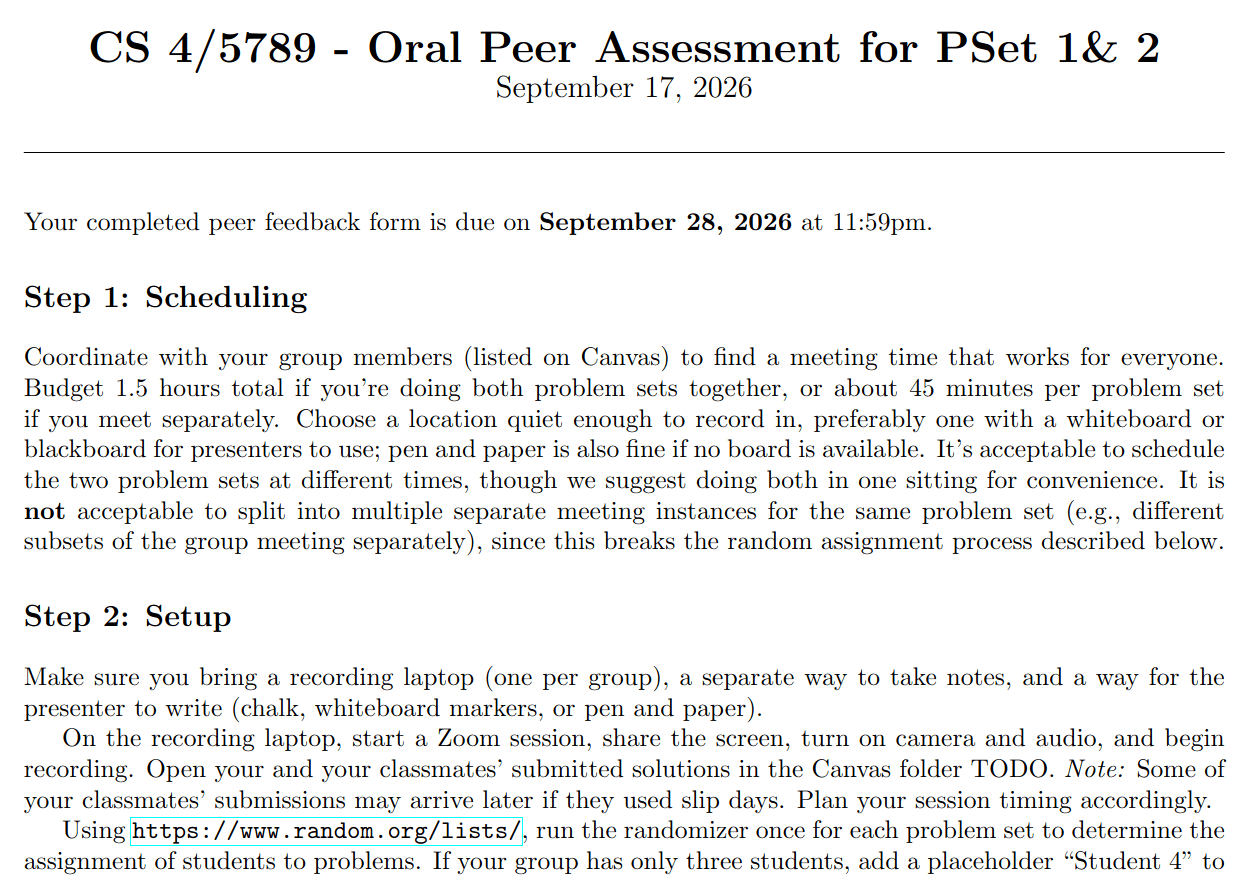
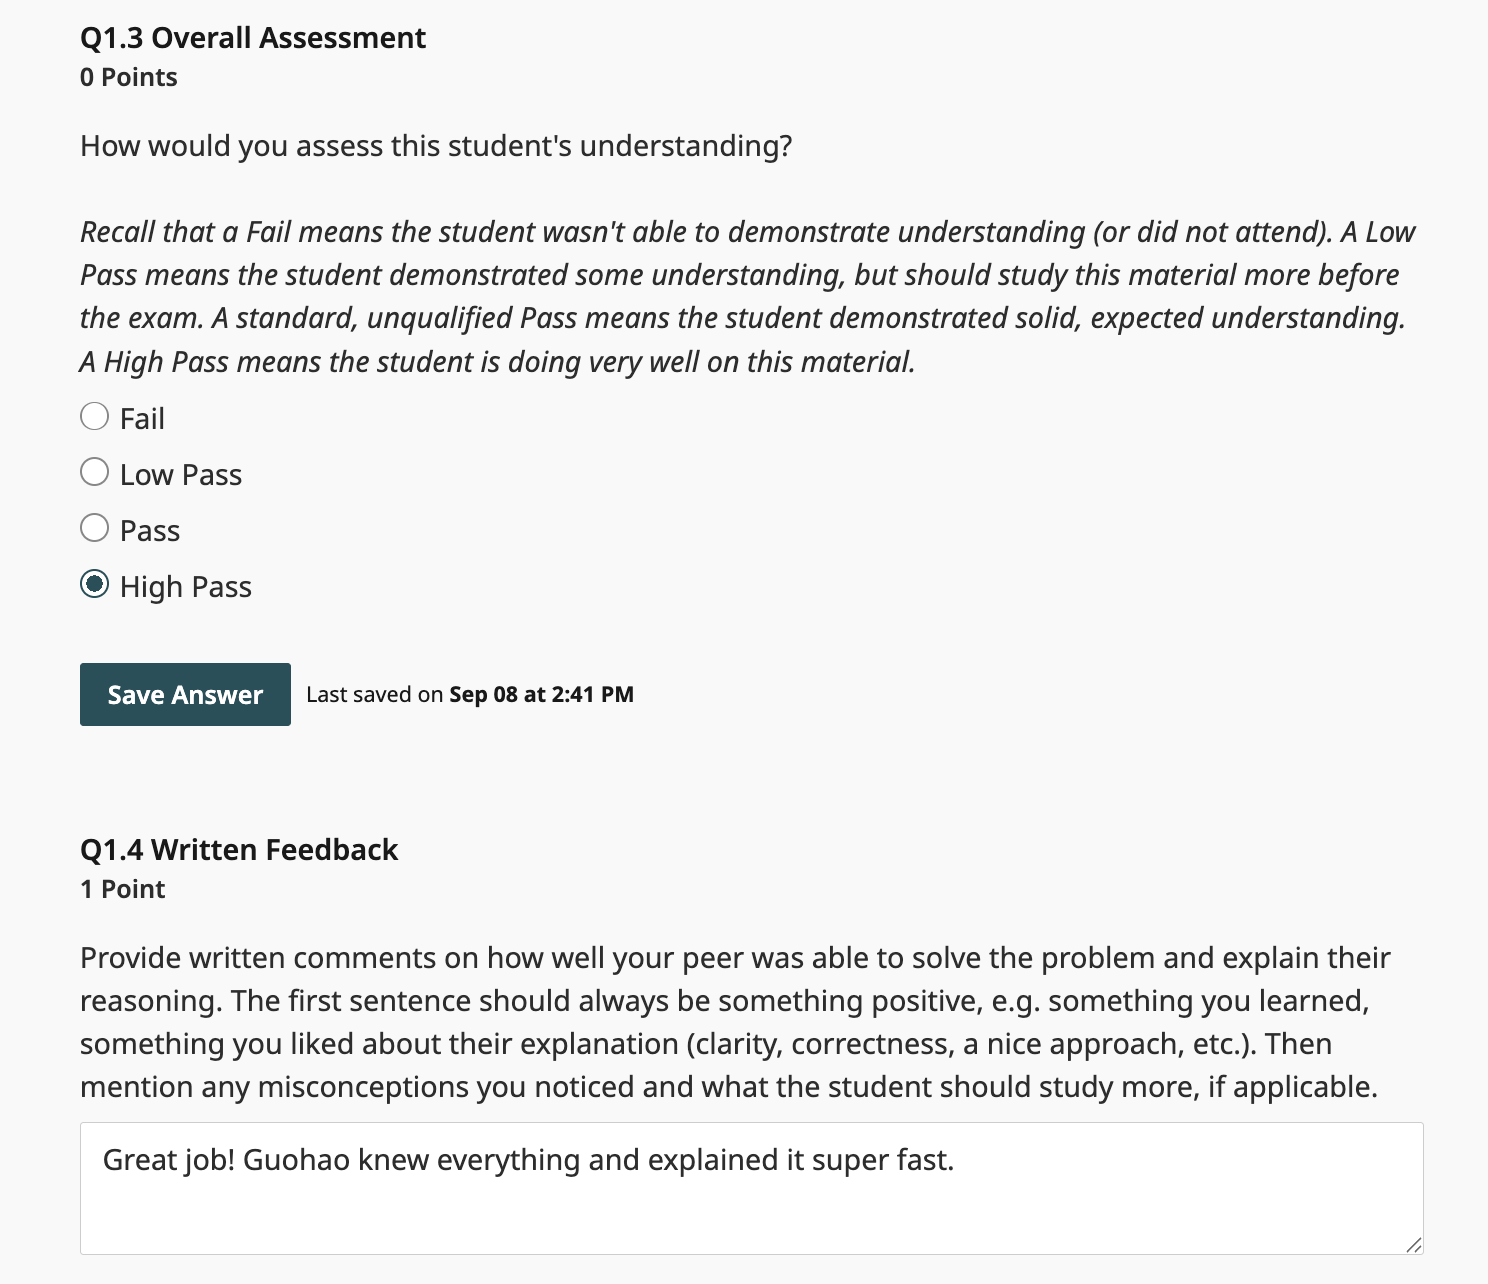
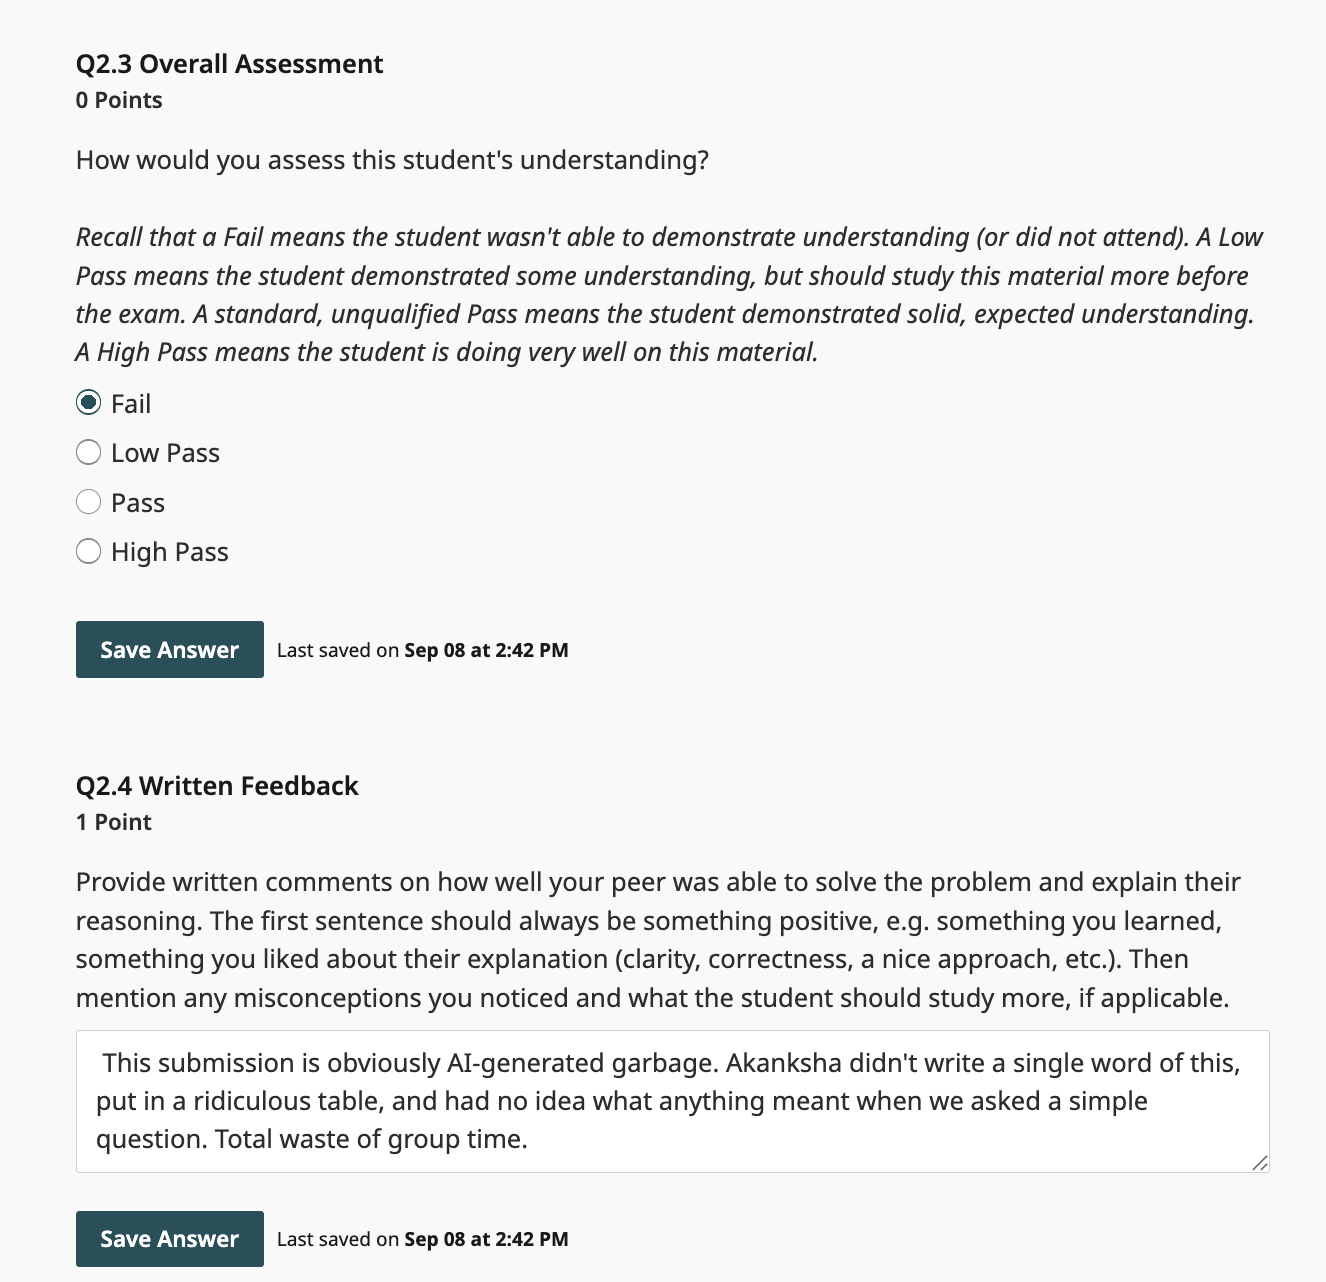
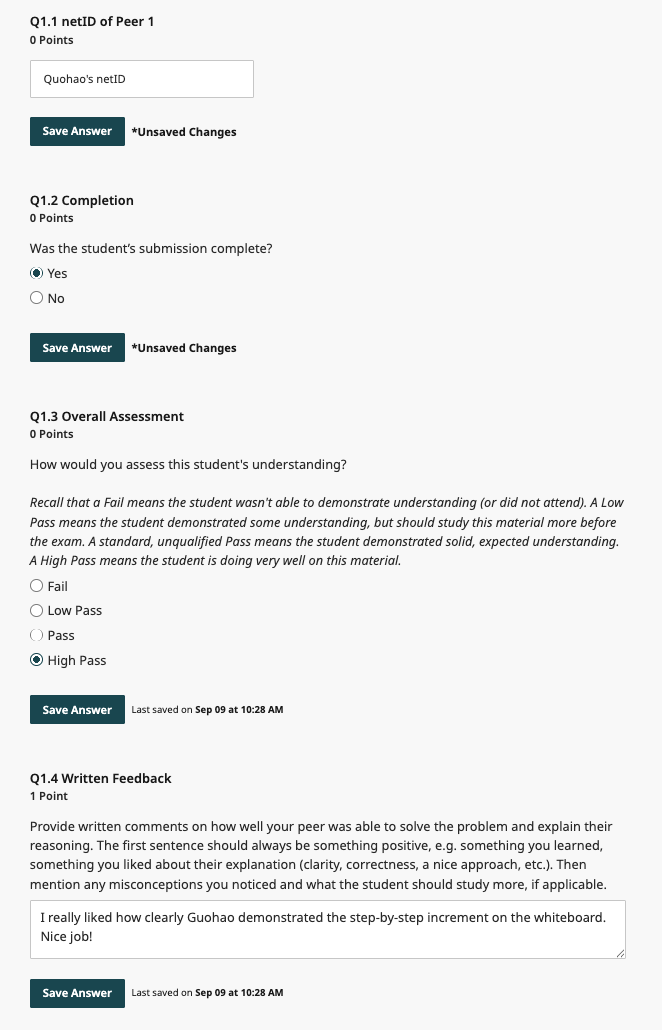
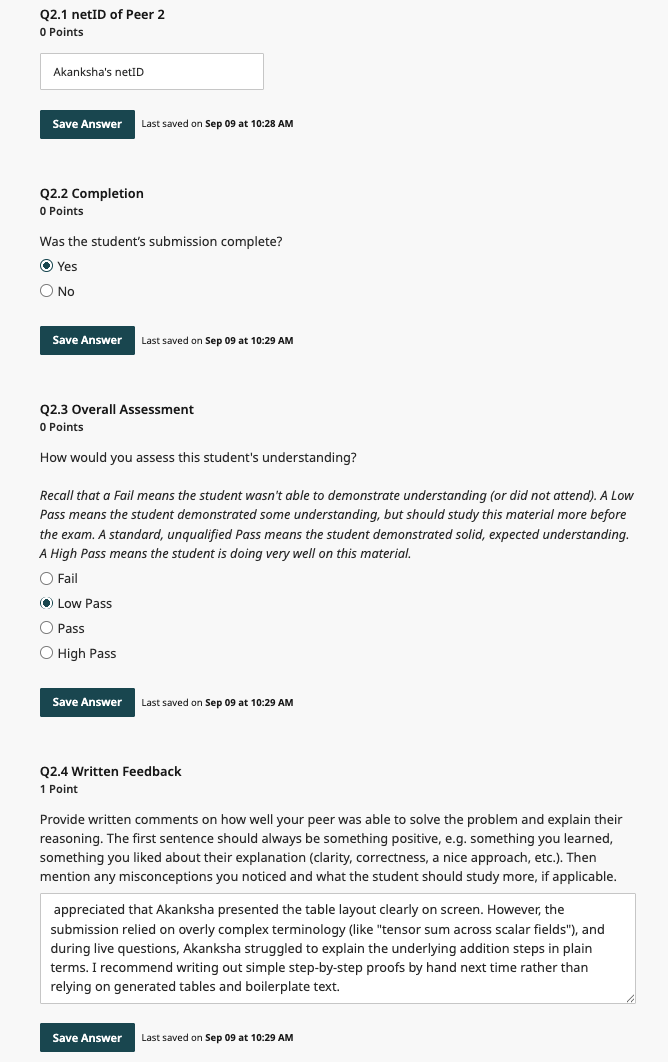
  1. Peer Feedback Demo
  2. Trust Region Recap
  3. Proximal Policy Optimization
  4. Policy Optimization Summary

Peer Feedback Demo

PollEV

Survey

Agenda

  1. Peer Feedback Demo
  2. Trust Region Recap
  3. Proximal Policy Optimization
  4. Policy Optimization Summary

example: J, F


How should we update the policy parameters to improve the expected reward?

What is \(\nabla_\theta d_{KL}(\theta',\theta)\)? Recall $$d_{KL}(\theta',\theta) = \mathbb{E}_{x,a \sim \rho_{\theta'}}\!\left[  \log\frac{\pi_{\theta'}(a|x)}{\pi_{\theta}(a|x)} \right].$$

Think/Pair/Share

REINFORCE (90s)

  • Given: baseline function \(b\)
  1. For data collection epochs \(j=1,...,N_{coll}\):
    1. For collection steps \(i=1,...,n\):
      1. observe \(x_{i}\), sample \(a_{i}\sim \pi_{\theta_{j}}(x_{i})\), get \(r_{i}\)
    2. Update $$\theta_{j+1} = \theta_j + \alpha \frac{1}{n} \sum_{i=1}^n \nabla \log \pi_{\theta_j}(a_i|x_i) (r_i-b(x_i) ) $$

Natural Policy Gradient (00s)

  • Given: baseline function \(b\)
  1. For data collection epochs \(j=1,...,N_{coll}\):
    1. For collection steps \(i=1,...,n_j\):
      1. observe \(x_{i}\), sample \(a_{i}\sim \pi_{\theta_{j}}(x_{i})\), get \(r_{i}\)
    2. Compute then invert $$\hat F_{\theta}=\frac{1}{n} \sum_{i=1}^n \nabla \log \pi_\theta(a_i|x_i) \nabla \log \pi_\theta(a_i|x_i) ^\top $$
    3. Update $$\theta_{j+1} = \theta_j + \alpha \frac{1}{n} \hat F_{\theta_j}^{-1} \sum_{i=1}^n \nabla \log \pi_{\theta_j}(a_i|x_i) (r_i-b(x_i) ) $$
  • Given: baseline function \(b\)
  1. For data collection epochs \(j=1,...,N_{coll}\):
    1. For collection steps \(i=1,...,n_j\):
      1. observe \(x_{i}\), sample \(a_{i}\sim \pi_{\theta_{j,1}}(x_{i})\), get \(r_{i}\)
    2. For update steps \(k=1,...,N_{up}\): $$\theta_{j,k+1}=\theta_{j,k} +\alpha \frac{1}{n} \sum_{i=1}^n  \nabla \log \pi_\theta(a_i|x_i)\left( \frac{\pi_{\theta_{j,k}}(a_i|x_i)}{\pi_{\theta_{j,1}}(a_i|x_i)} (r_i-b(x_i)) + \lambda \right)$$
    3. Set \(\theta_{j+1,1} = \theta_{j,k}\)

Proximal Policy Optimization (10s)

  • Given: baseline function \(b\)
  1. For data collection epochs \(j=1,...,N_{coll}\):
    1. For collection steps \(i=1,...,n_j\):
      1. observe \(x_{i}\), sample \(a_{i}\sim \pi_{\theta_{j}}(x_{i})\), get \(r_{i}\)
    2. For update steps \(k=1,...,N_{up}\):
      1. Form estimates
      2. Update parameter \(\theta_{j,k+1}=\theta_{j,k} +\alpha\)update
    3. Set \(\theta_{j+1,1} = \theta_{j,k}\)

Policy Opt. Meta Algorithm

Policy Opt. Meta Algorithm

  1. For data collection epochs \(j=1,...,N_{coll}\):
    1. For collection steps \(i=1,...,n_j\):
      1. observe \(x_{i}\), sample \(a_{i}\sim \pi_{\theta_{j,1}}(x_{i})\), get \(r_{i}\)
    2. For update steps \(k=1,...,N_{up}\):
      1. Form estimates 
      2. Update parameter \(\theta_{j,k+1}=\theta_{j,k} +\alpha\)update
    3. Set \(\theta_{j+1,1} = \theta_{j,k}\)
  • Policy Gradient: update is \(\alpha \widehat{\nabla J}_{\theta;\theta'}\) with  $$\widehat{\nabla J}_{\theta;\theta'} =\frac{1}{n} \sum_{i=1}^n \frac{\pi_\theta(a_i|x_i)}{\pi_{\theta'}(a_i|x_i)} \nabla \log \pi_\theta(a_i|x_i) (r_i-b(x_i))$$
  • NPG: update is \(\alpha \hat F_{\theta;\theta'}^{-1} \widehat{\nabla J}_{\theta;\theta'}\) with $$\hat F_{\theta;\theta'}^{-1}=\frac{1}{n} \sum_{i=1}^n \frac{\pi_\theta(a_i|x_i)}{\pi_{\theta'}(a_i|x_i)} \nabla \log \pi_\theta(a_i|x_i) \nabla \log \pi_\theta(a_i|x_i) ^\top $$

  • PPO: update is \(\alpha (\widehat{\nabla J}_{\theta;\theta'}+\frac{1}{n}\sum_{i=1}^n\lambda \nabla \log \pi_\theta(a_i|x_i) ) \) $$=\frac{1}{n} \sum_{i=1}^n \nabla \log \pi_\theta(a_i|x_i) (\frac{\pi_\theta(a_i|x_i)}{\pi_{\theta'}(a_i|x_i)} (r_i-b(x_i)) + \lambda)$$

Summary

On-policy whenever \(N_{up}=1\) and importance weight \(=1\)

Fa26 CS 4/5789: Lecture 5

By Sarah Dean

Private

Fa26 CS 4/5789: Lecture 5