Lecture 2: Reading Matters
Effective AI use in applied machine-learning projects
Outline
A. what supports confidence in an AI answer?
B. checking claims beyond the literature
C. why still read?
D. reading with AI
A. what supports confidence in an AI answer?
B. checking claims beyond the literature
C. why still read?
D. reading with AI
models are getting better:
Way lower factual error rates across selected challenging prompt sets, graded by an LLM with web access.
the question shifts to what supports these answers
(aside: what supports human answers?)
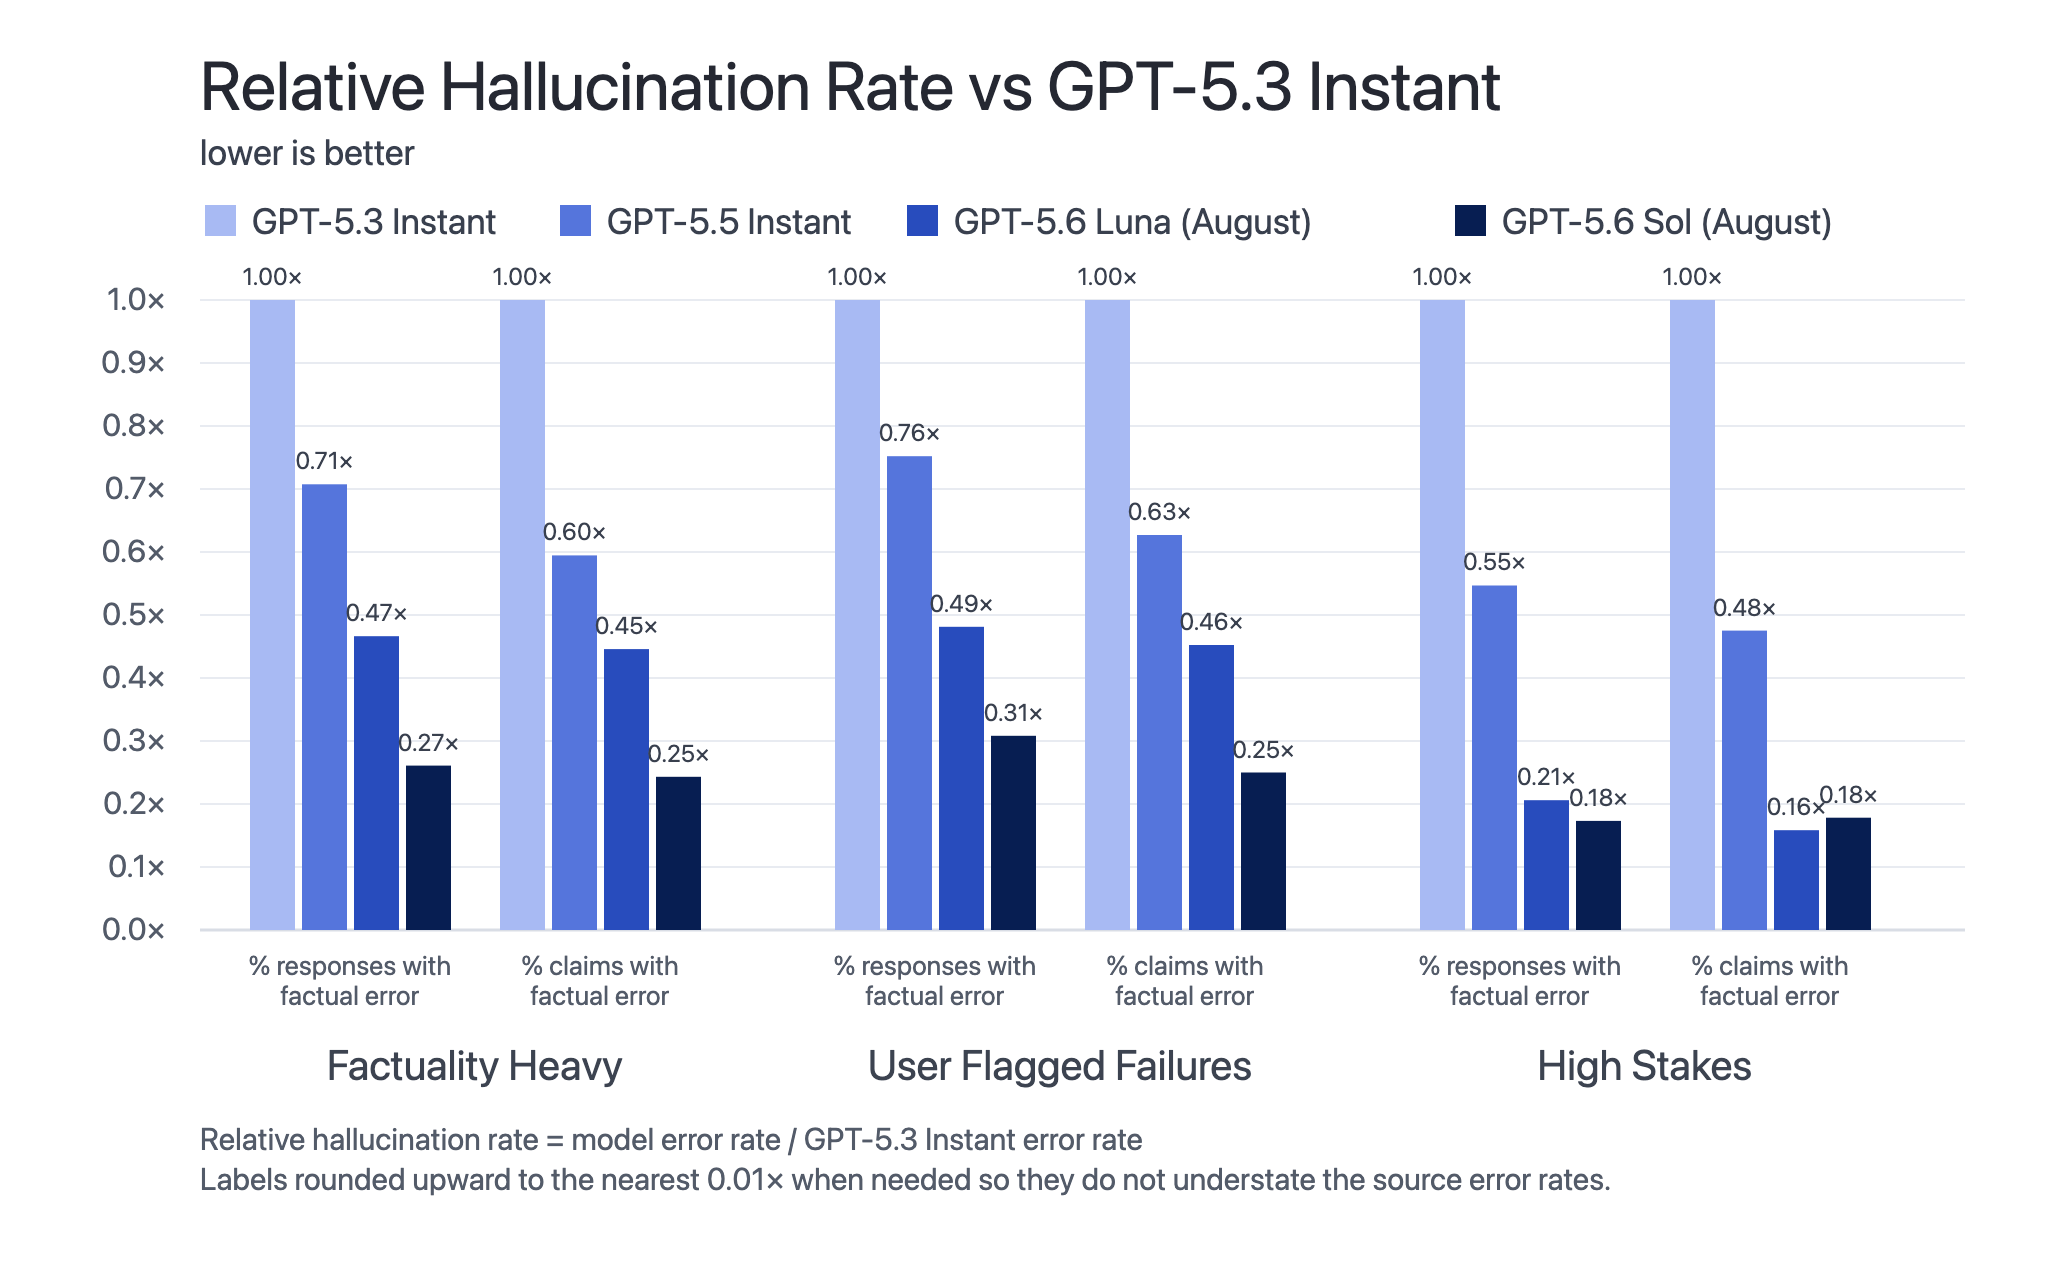
Provider-run, on selected prompts, relative rates, and judged by an LLM.
But aligns with my impression.
Back to Lab 1: how convinced are we, and what supports that?
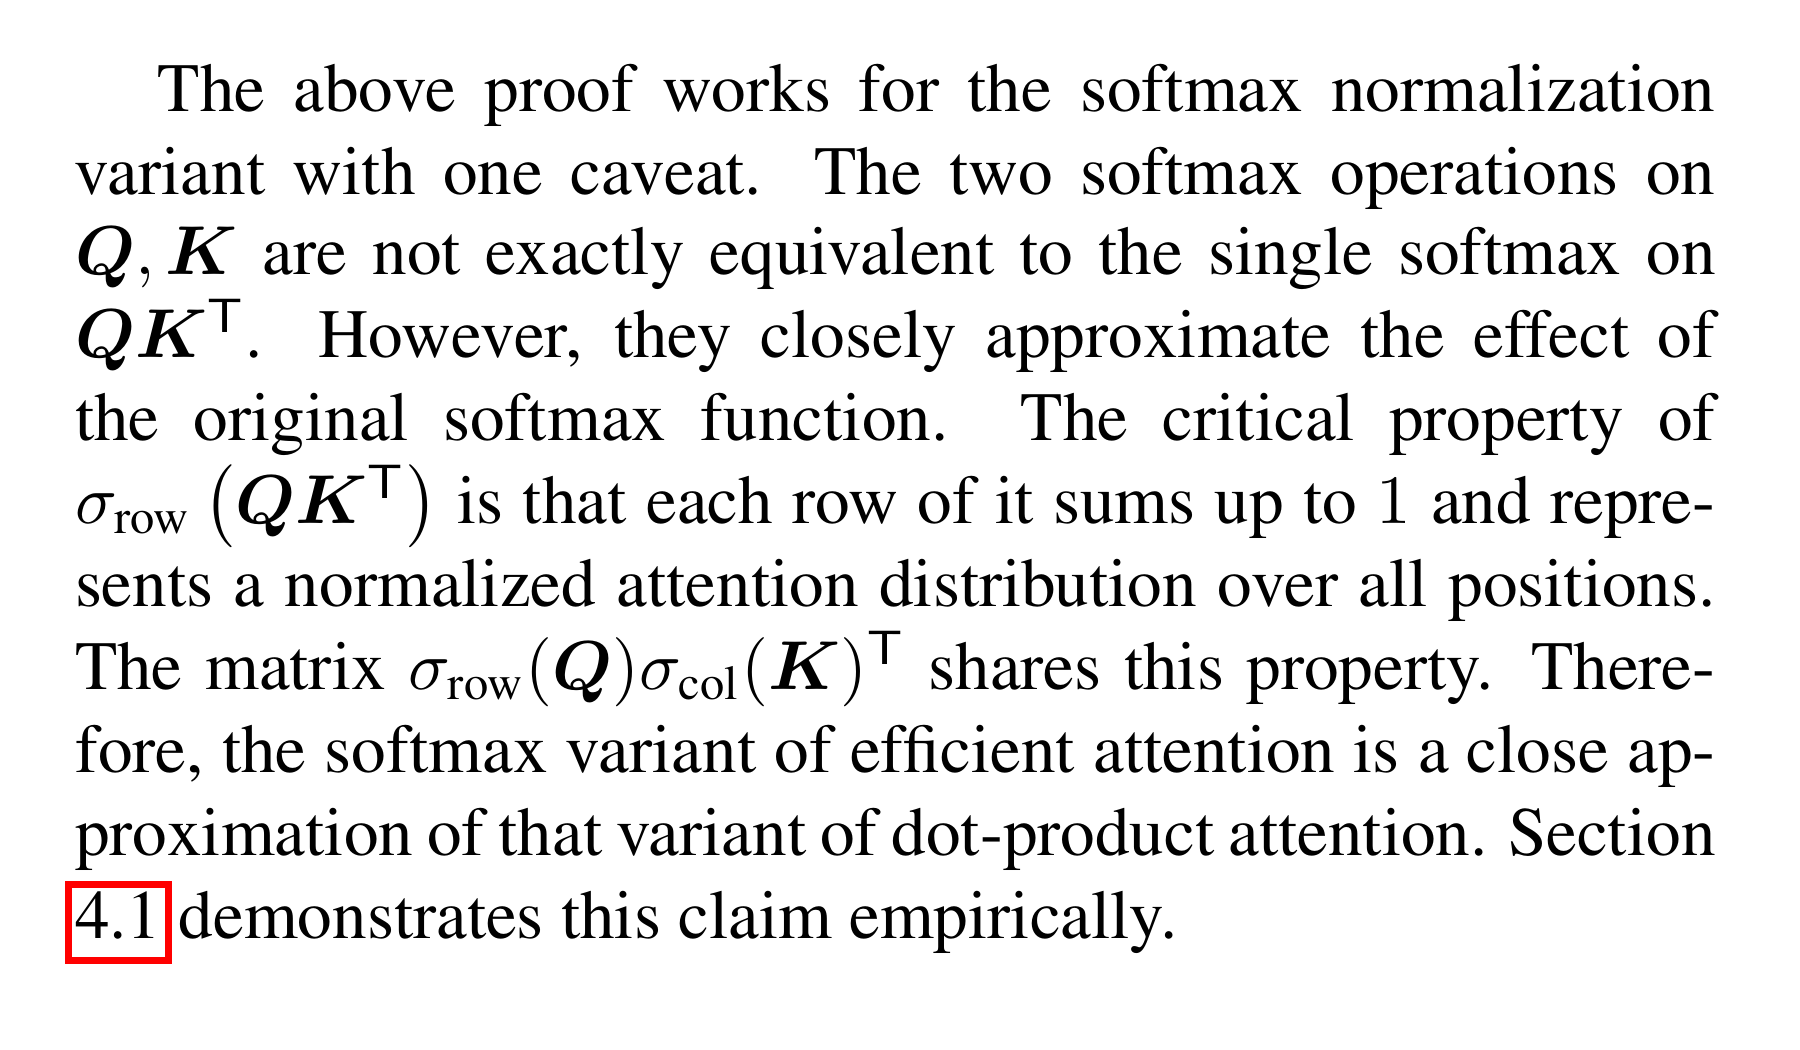
Is the model's own rating evidence?
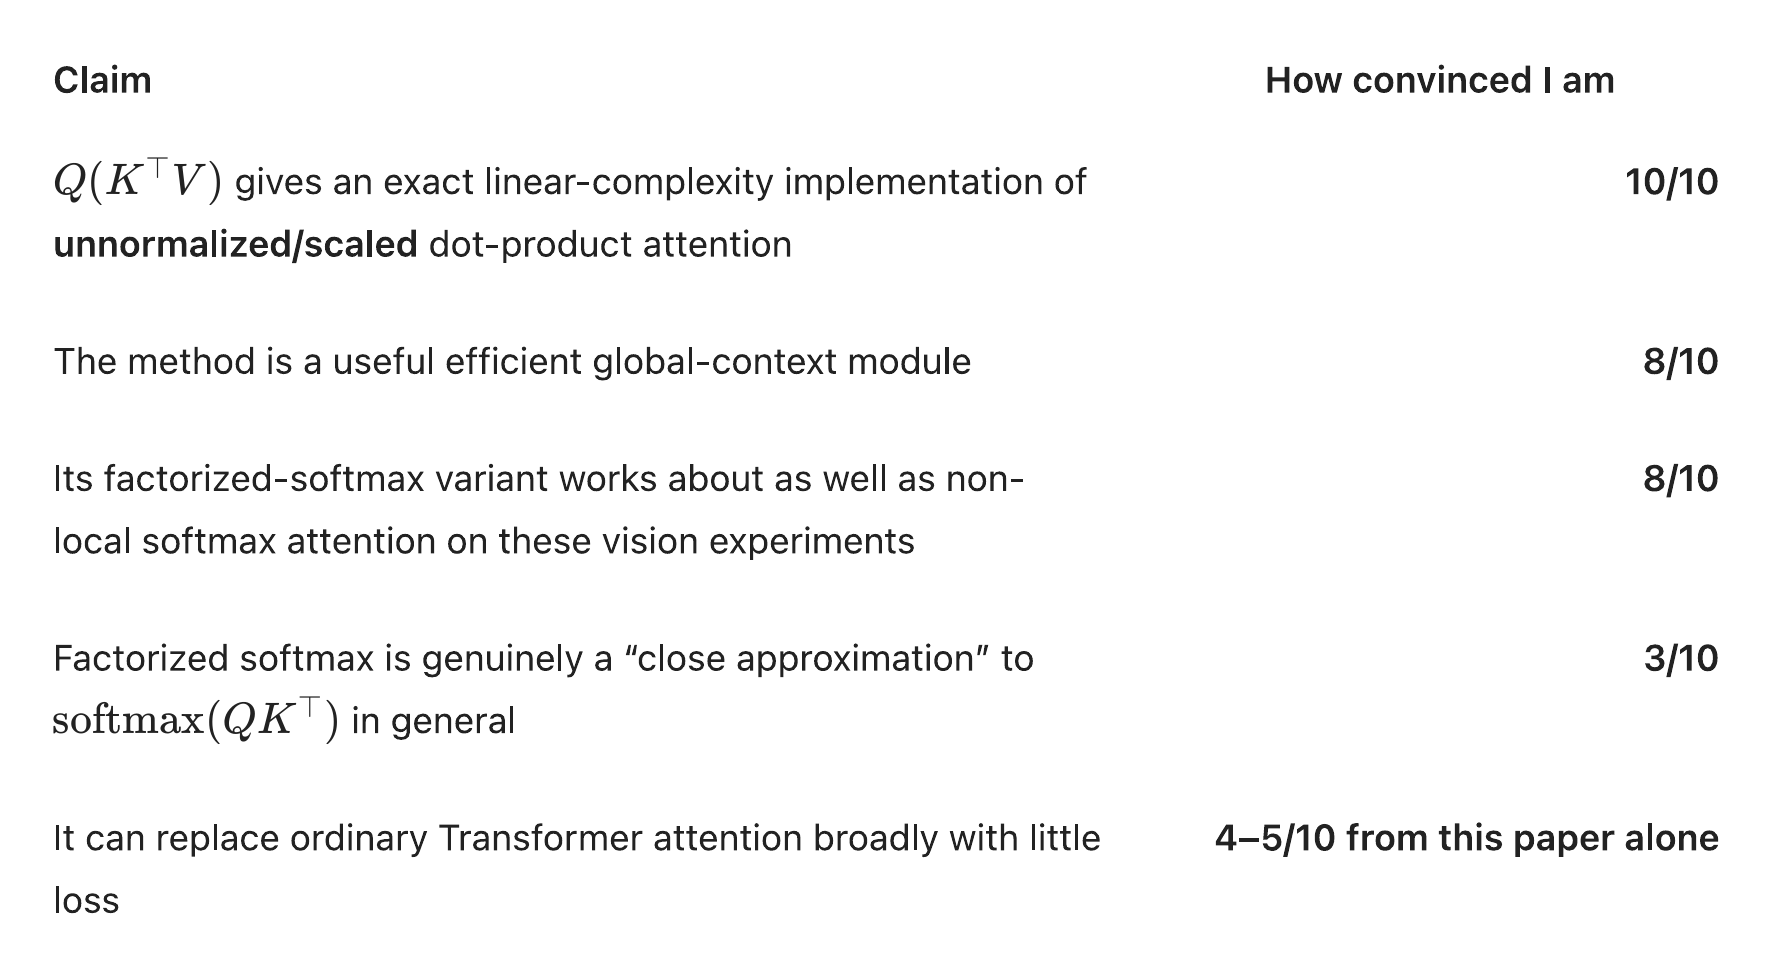
we can measure whether the rating tracks accuracy, model by model and task by task.
Confidence needs calibration for `this` task
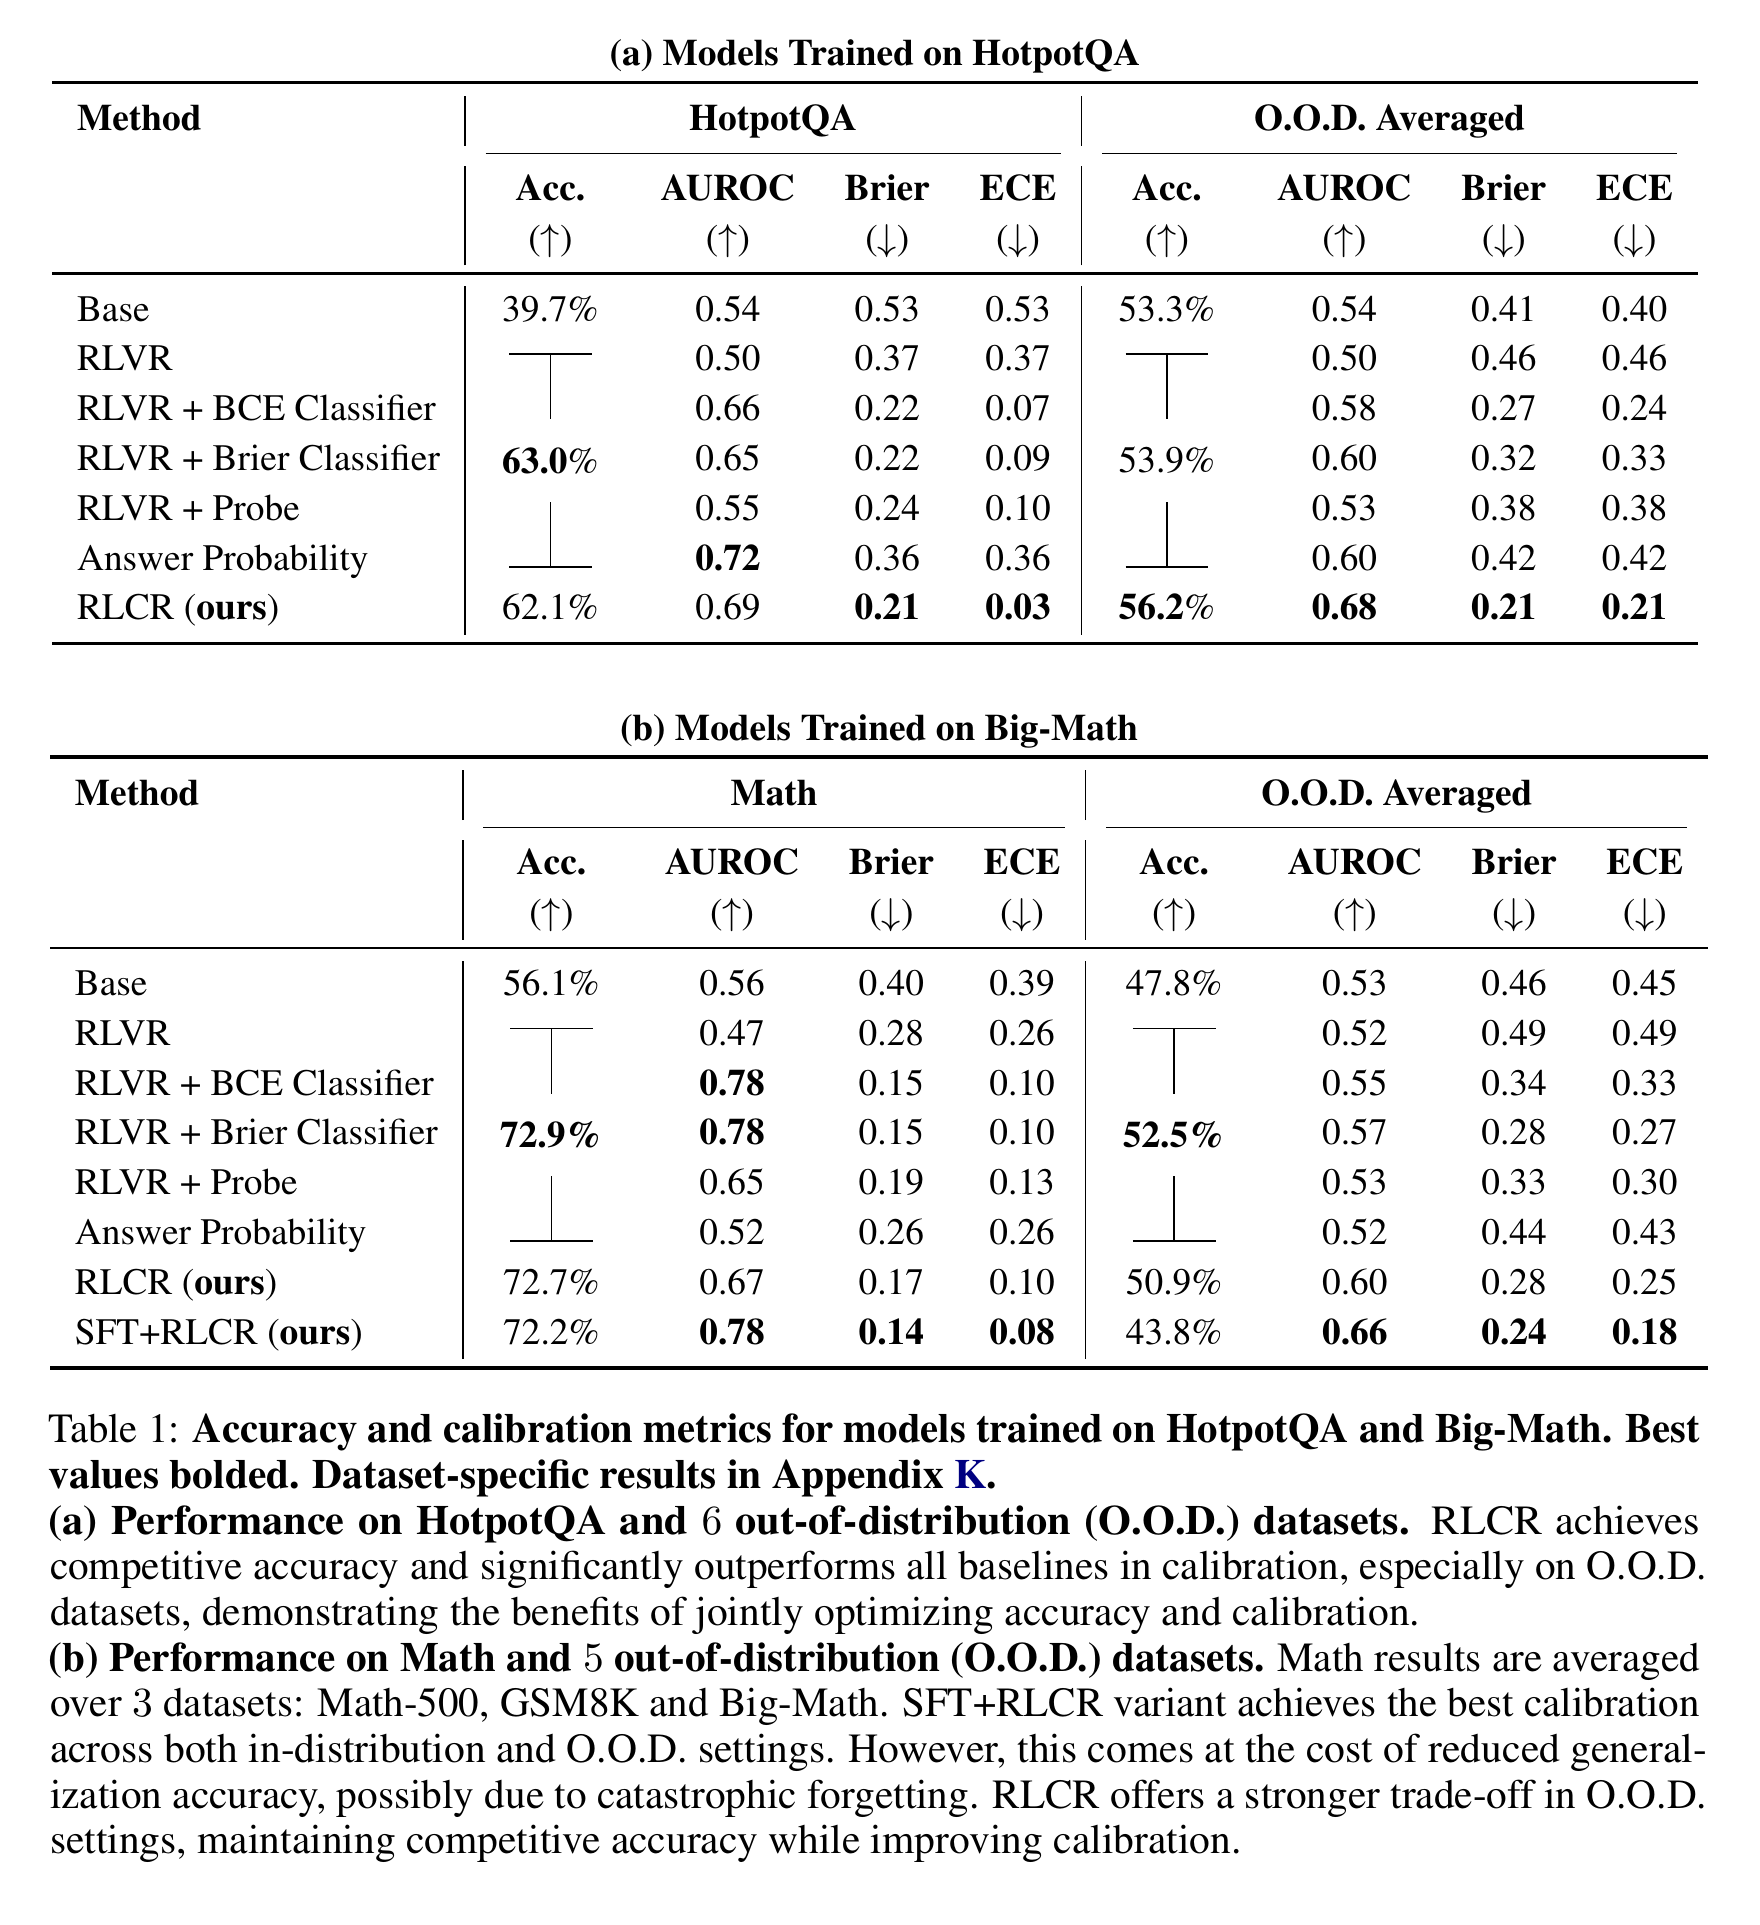
Training can improve calibration on its target task, but the gain is uneven outside it and reverses on one dataset.
How well a rating tracks correctness depends on the model, task, and prompt.
Consistency across samples is a second kind of evidence
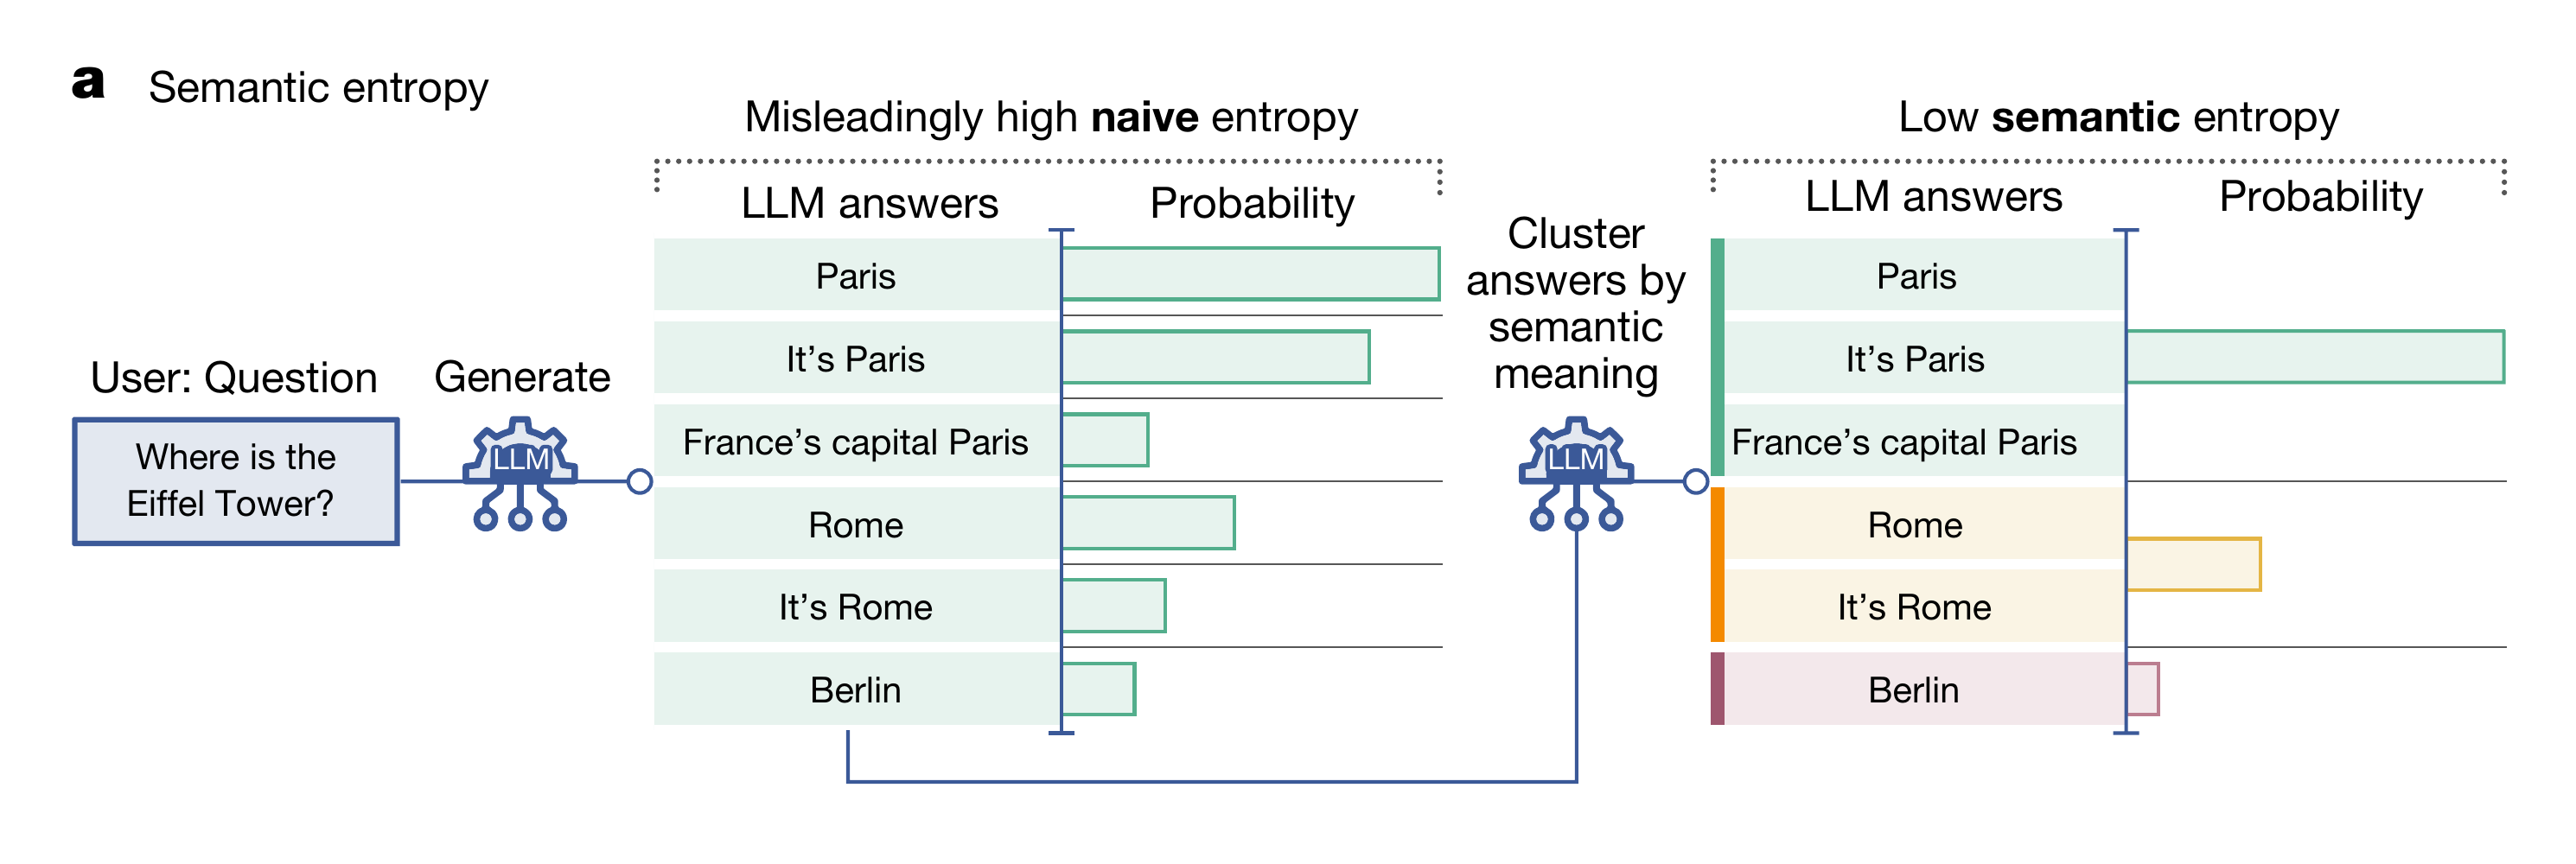
Sample several answers, cluster them by meaning, measure how much the clusters differ. Low entropy raises confidence against errors that vary from sample to sample.
A consistent repetitive wrong answer looks the same as a right one. (the paper acknowledged it.)
Agreement between providers, to the extent they are independent
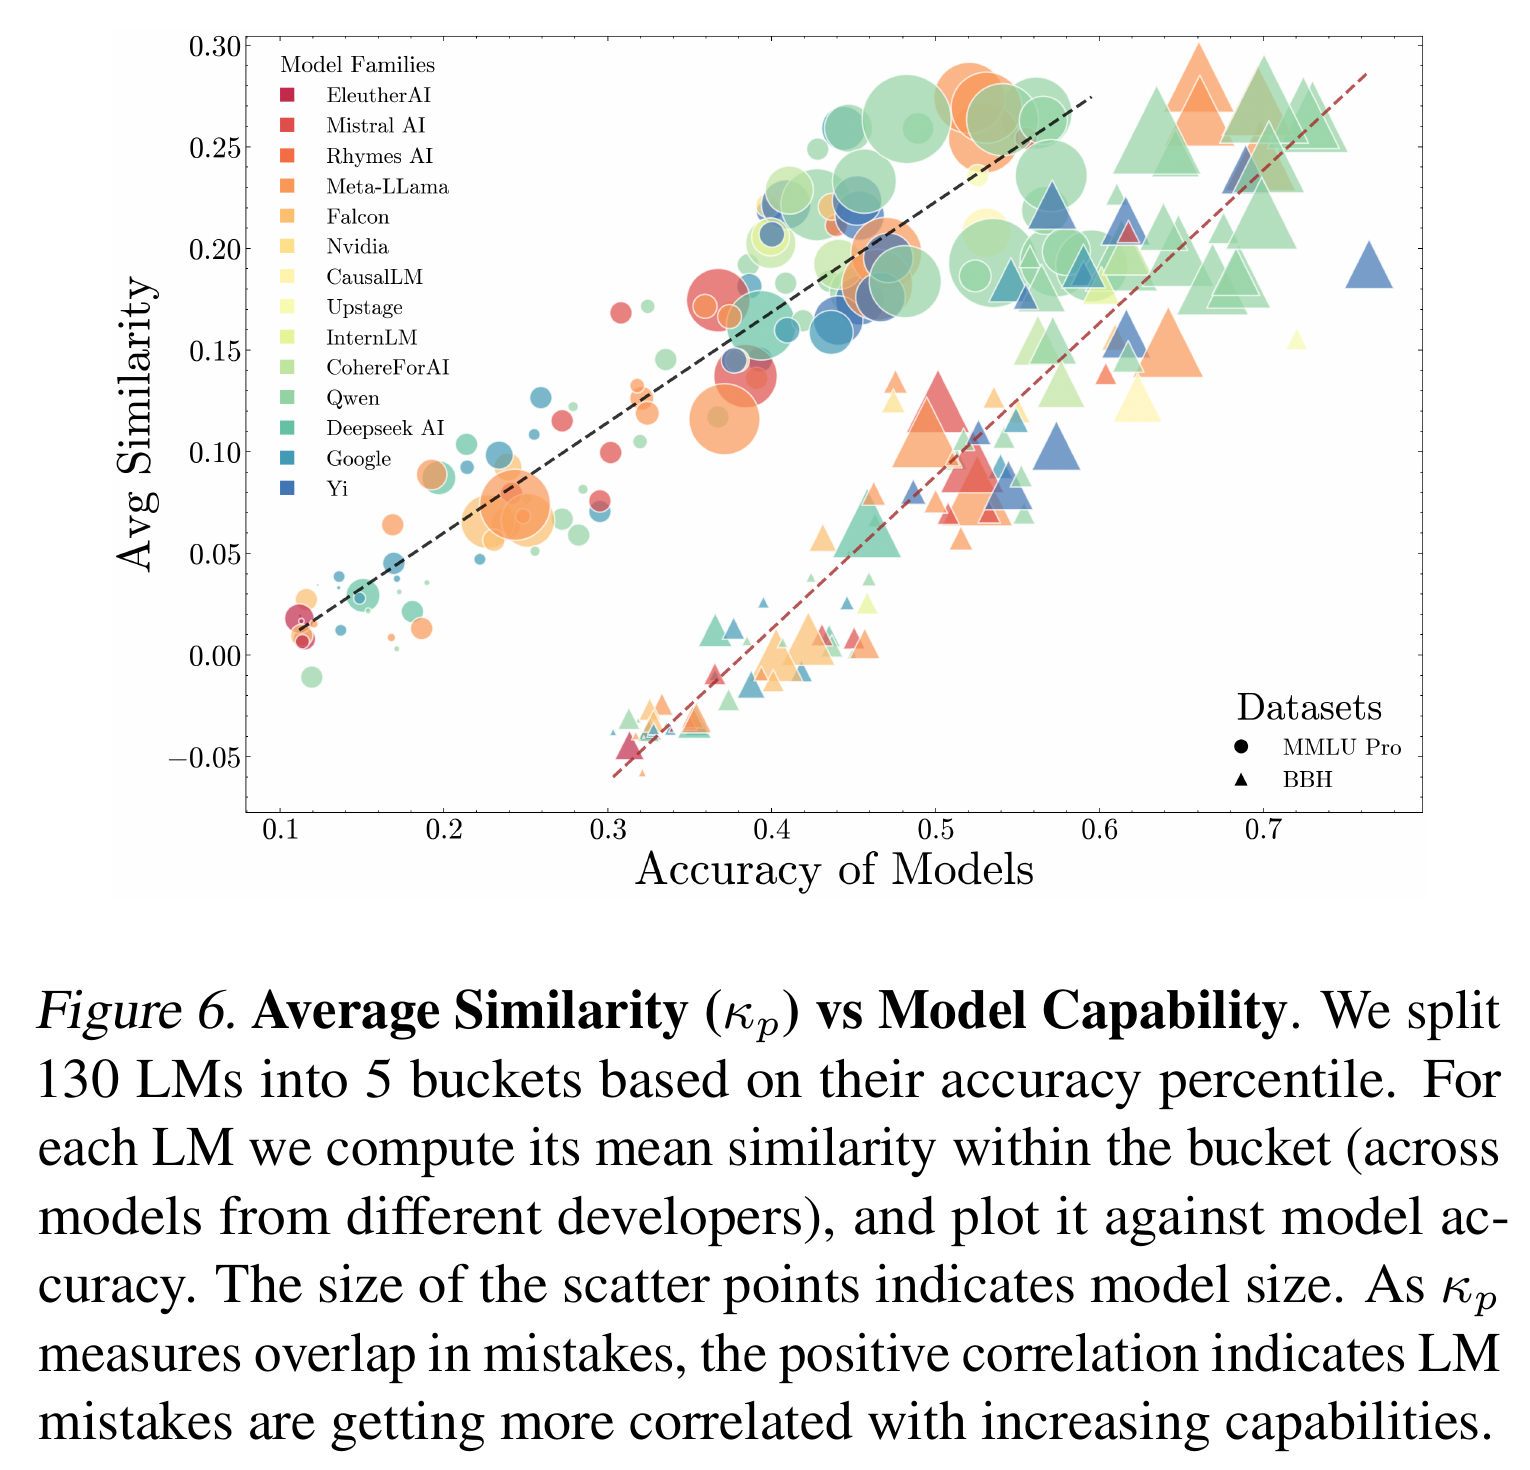
Across 130 open-weight models, the more capable ones shared mistakes more often than chance would predict, and the overlap grew with capability.
A written argument is evidence we can check directly
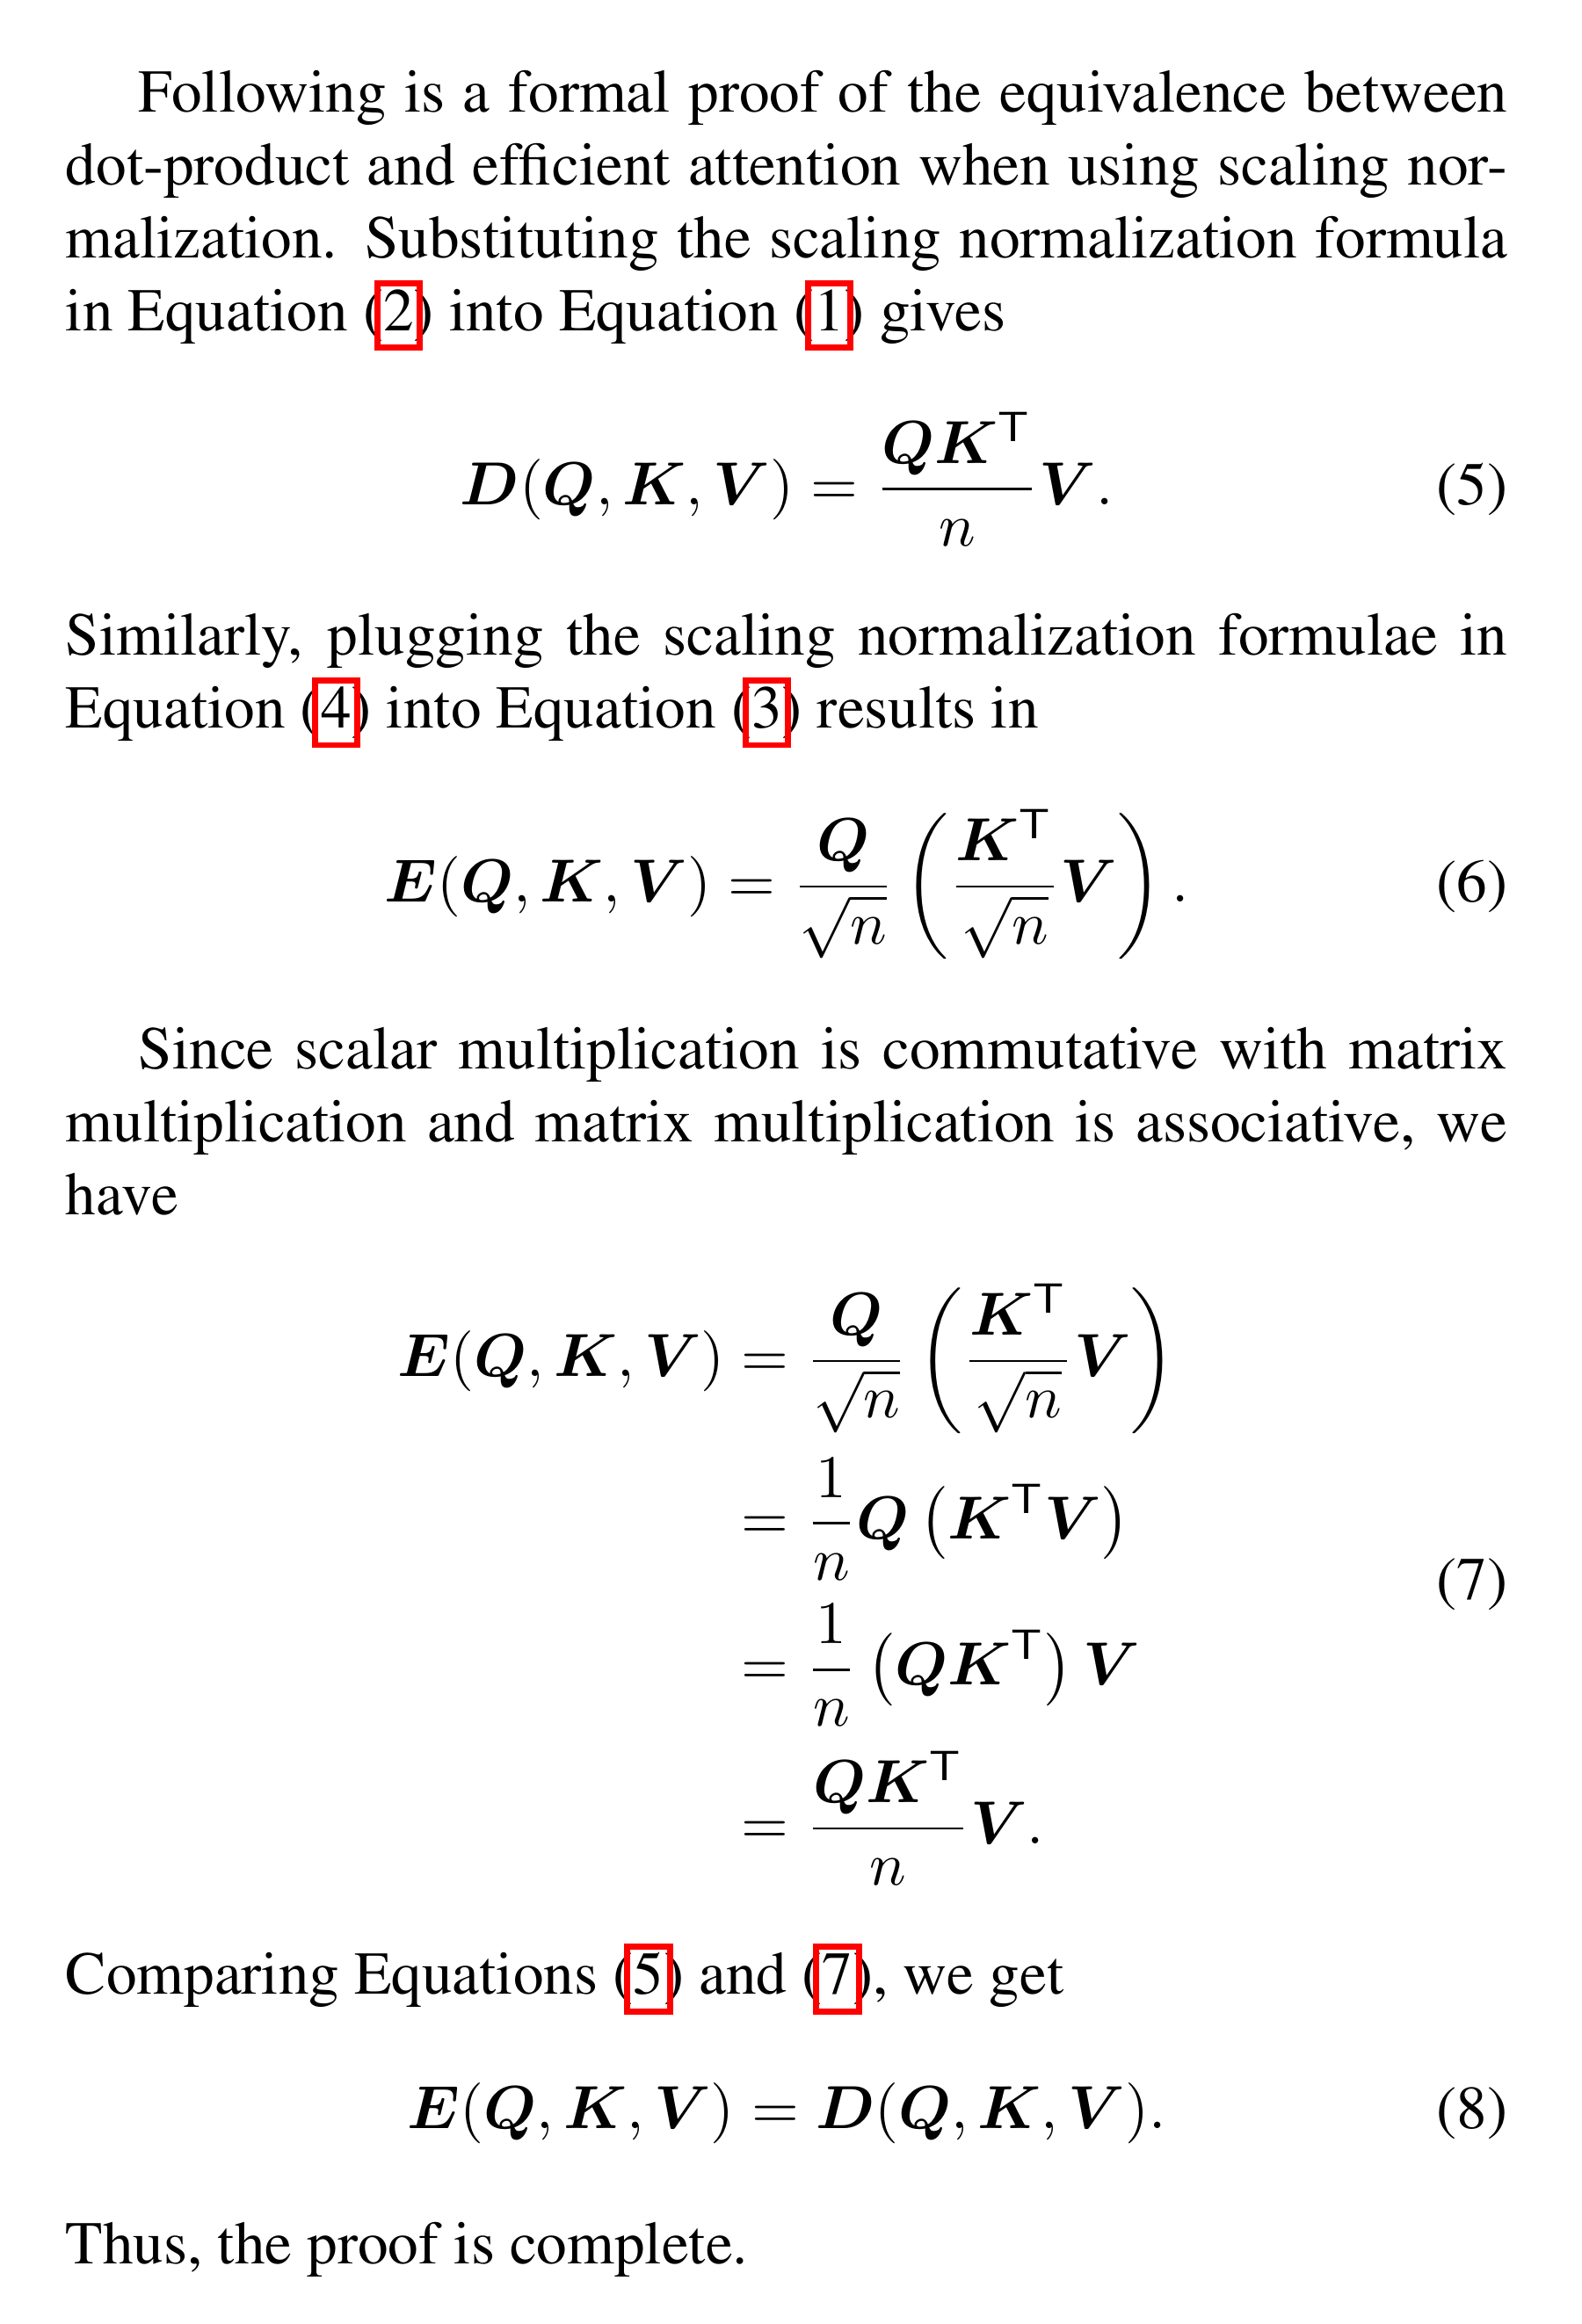
Both readings distinguish the exact scaling case from the softmax approximation claim, and our reassociation check confirms the first.
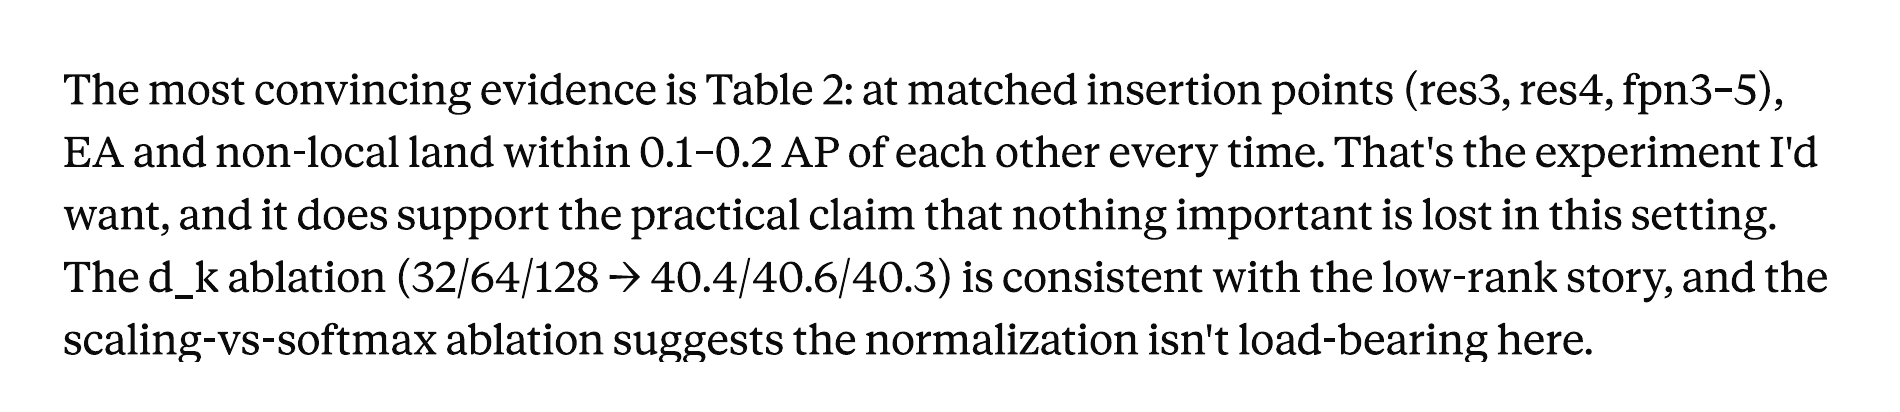
Then check a premise
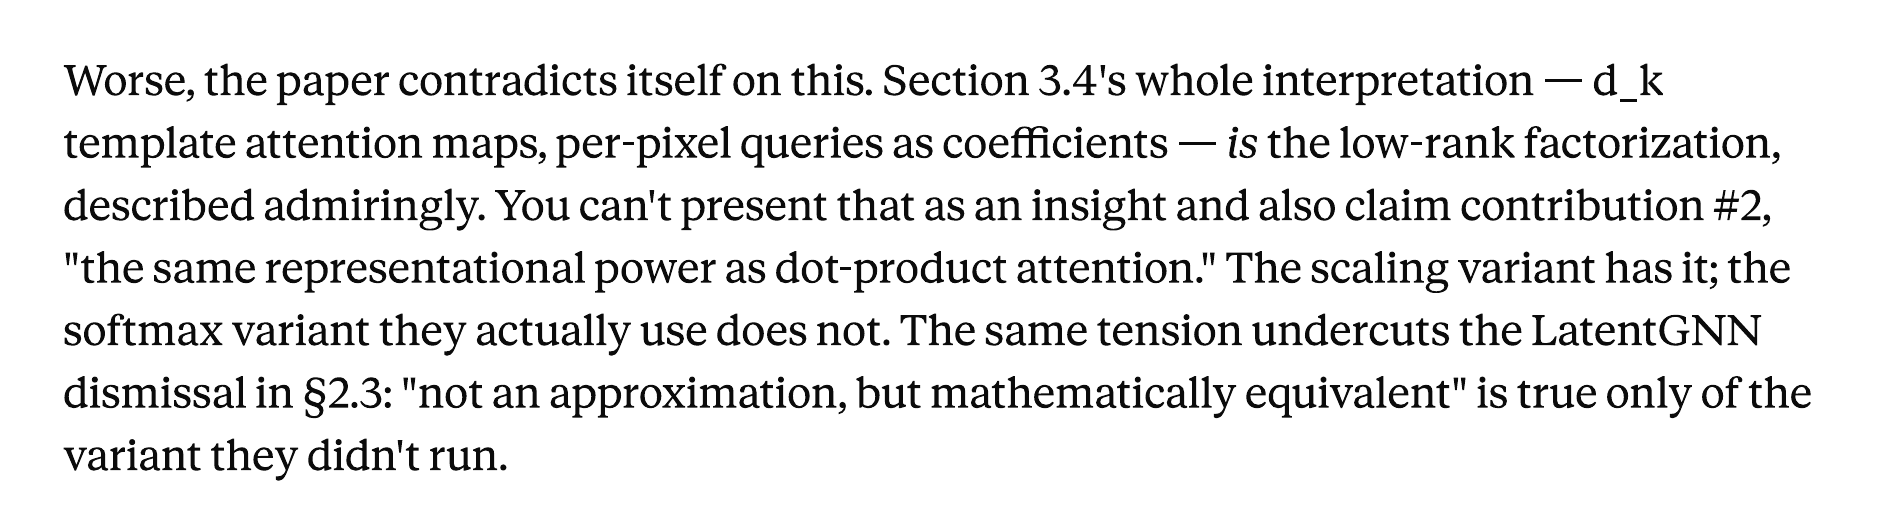
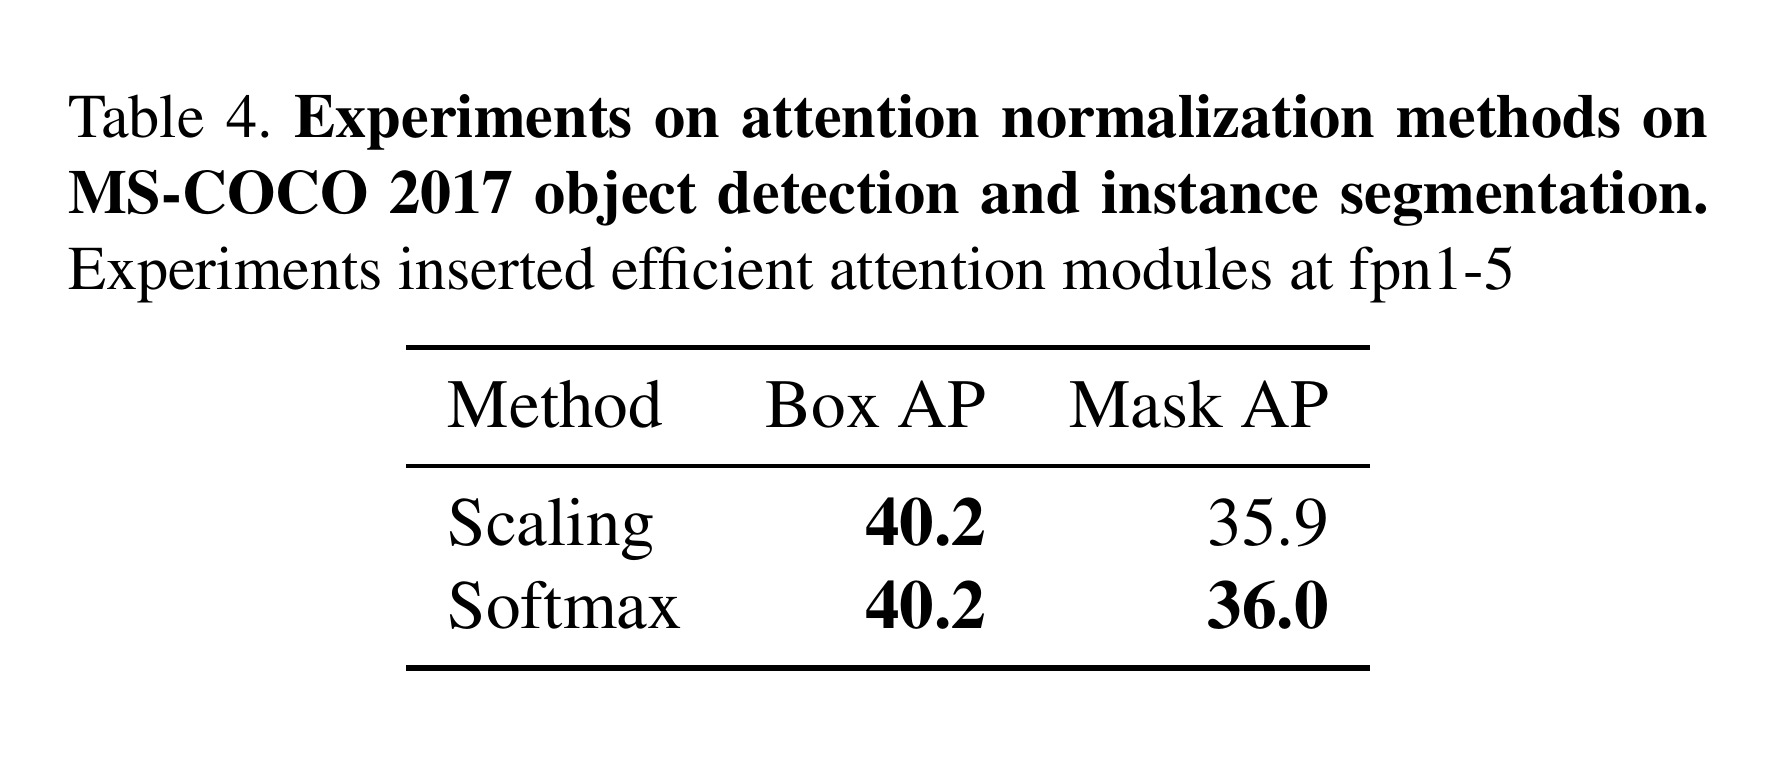
Table 4 reports both normalizations. One premise was wrong. The reading's conclusion about the softmax approximation does not rest on it, and its own page 1 already cited this ablation.
Validity and faithfulness are two questions
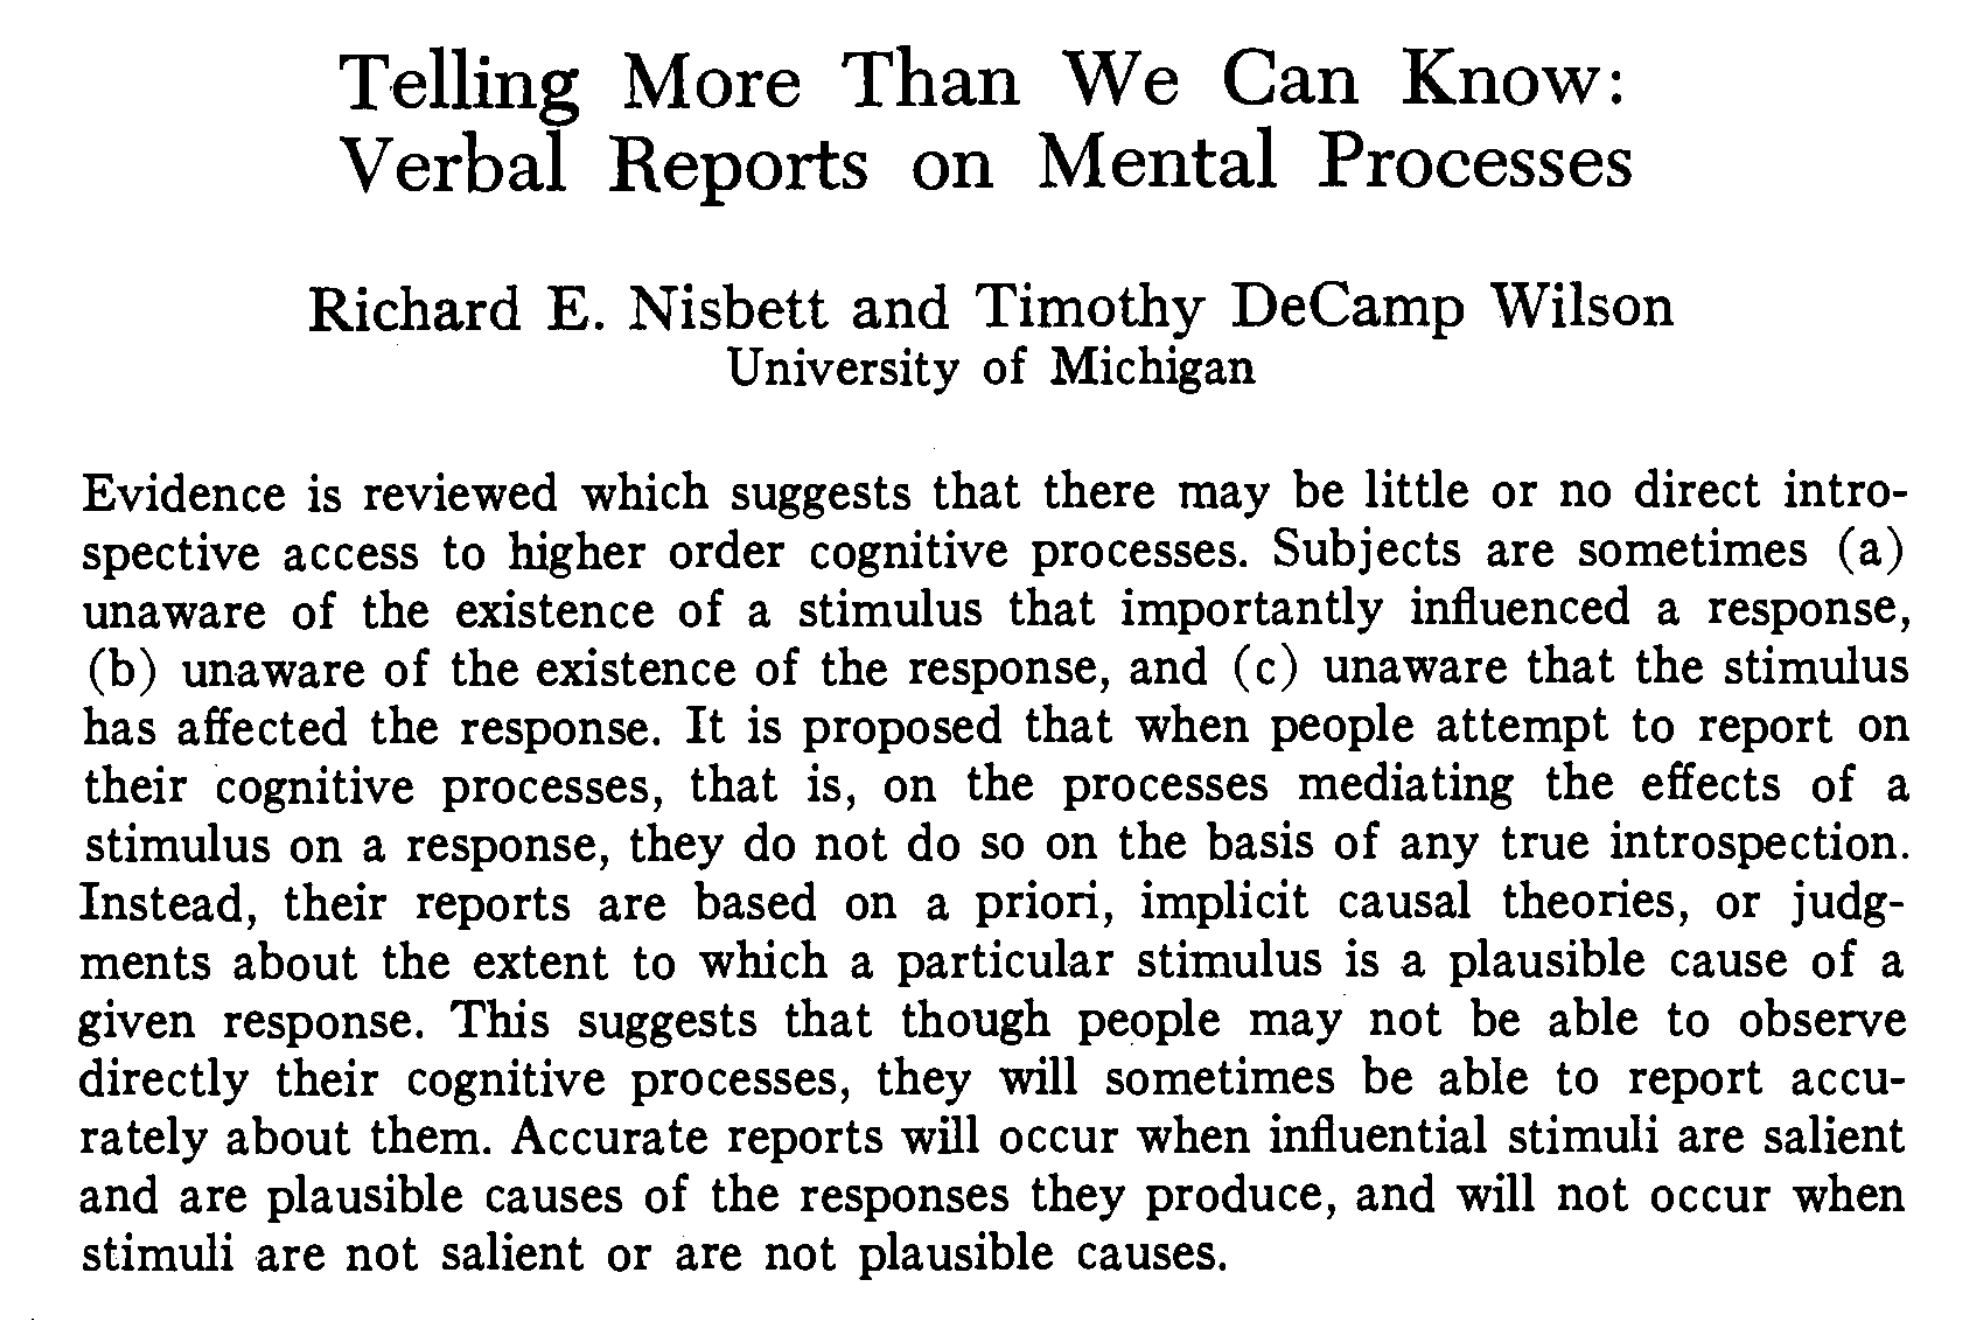
The question predates LLMs.
Reporting our reasoning is one thing; inferring if our reported reasoning is what led us to a conclusion is another.
Validity and faithfulness are two questions
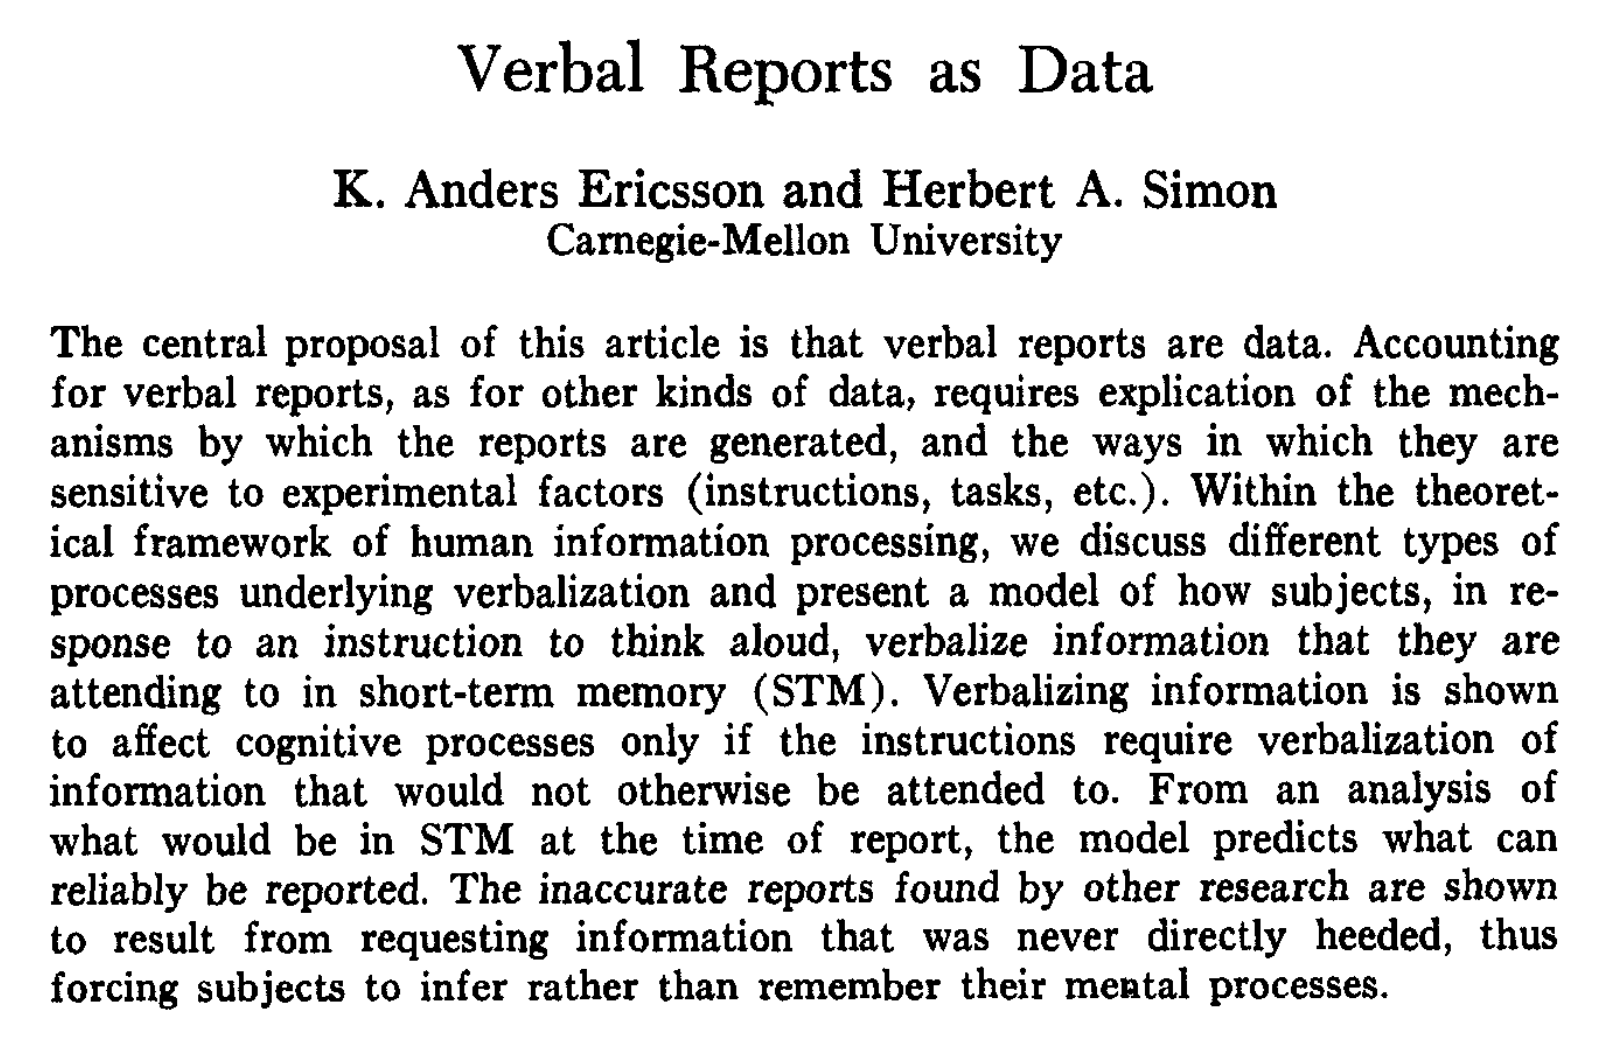
The question predates LLMs.
Reporting our reasoning is one thing; inferring if our reported reasoning is what led us to a conclusion is another.
Plausible arguments for contradictory answers
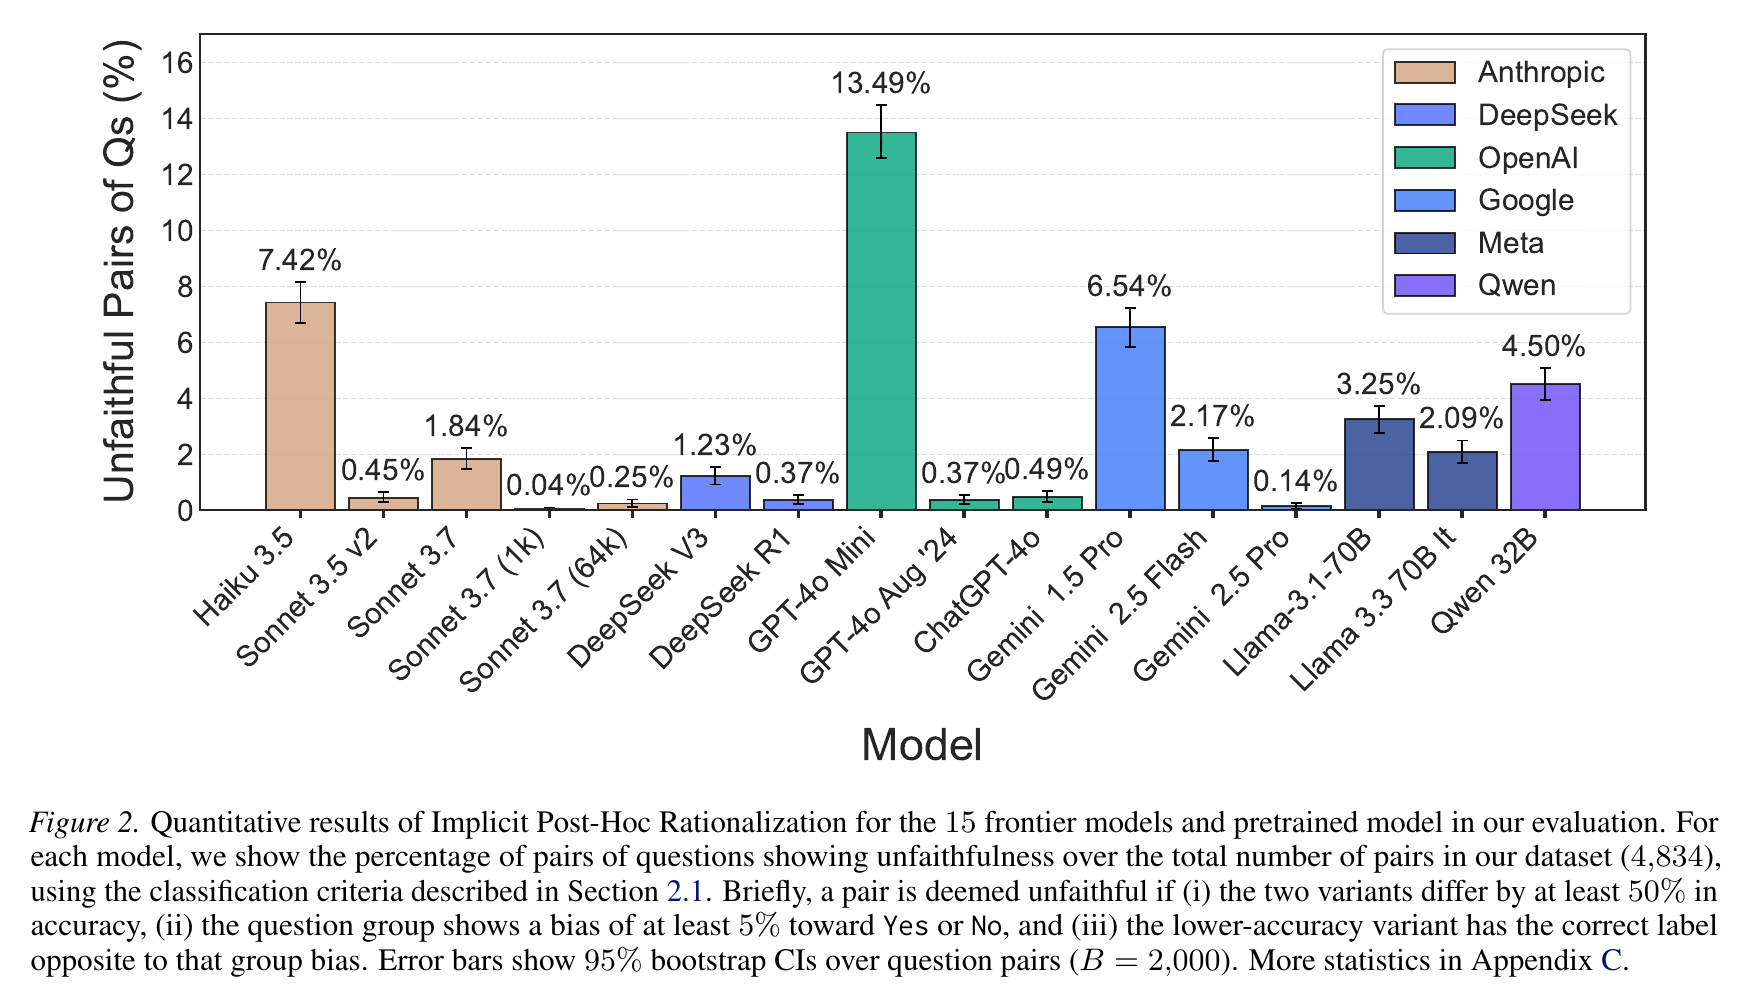
Asked whether X is bigger than Y and then whether Y is bigger than X, models sometimes argued both ways, fluently each time; one production model did so in 13% of question pairs.
The study reads this as unfaithfulness and leaves the cause unsettled.
Before delegating: difficulty and checkability are separate
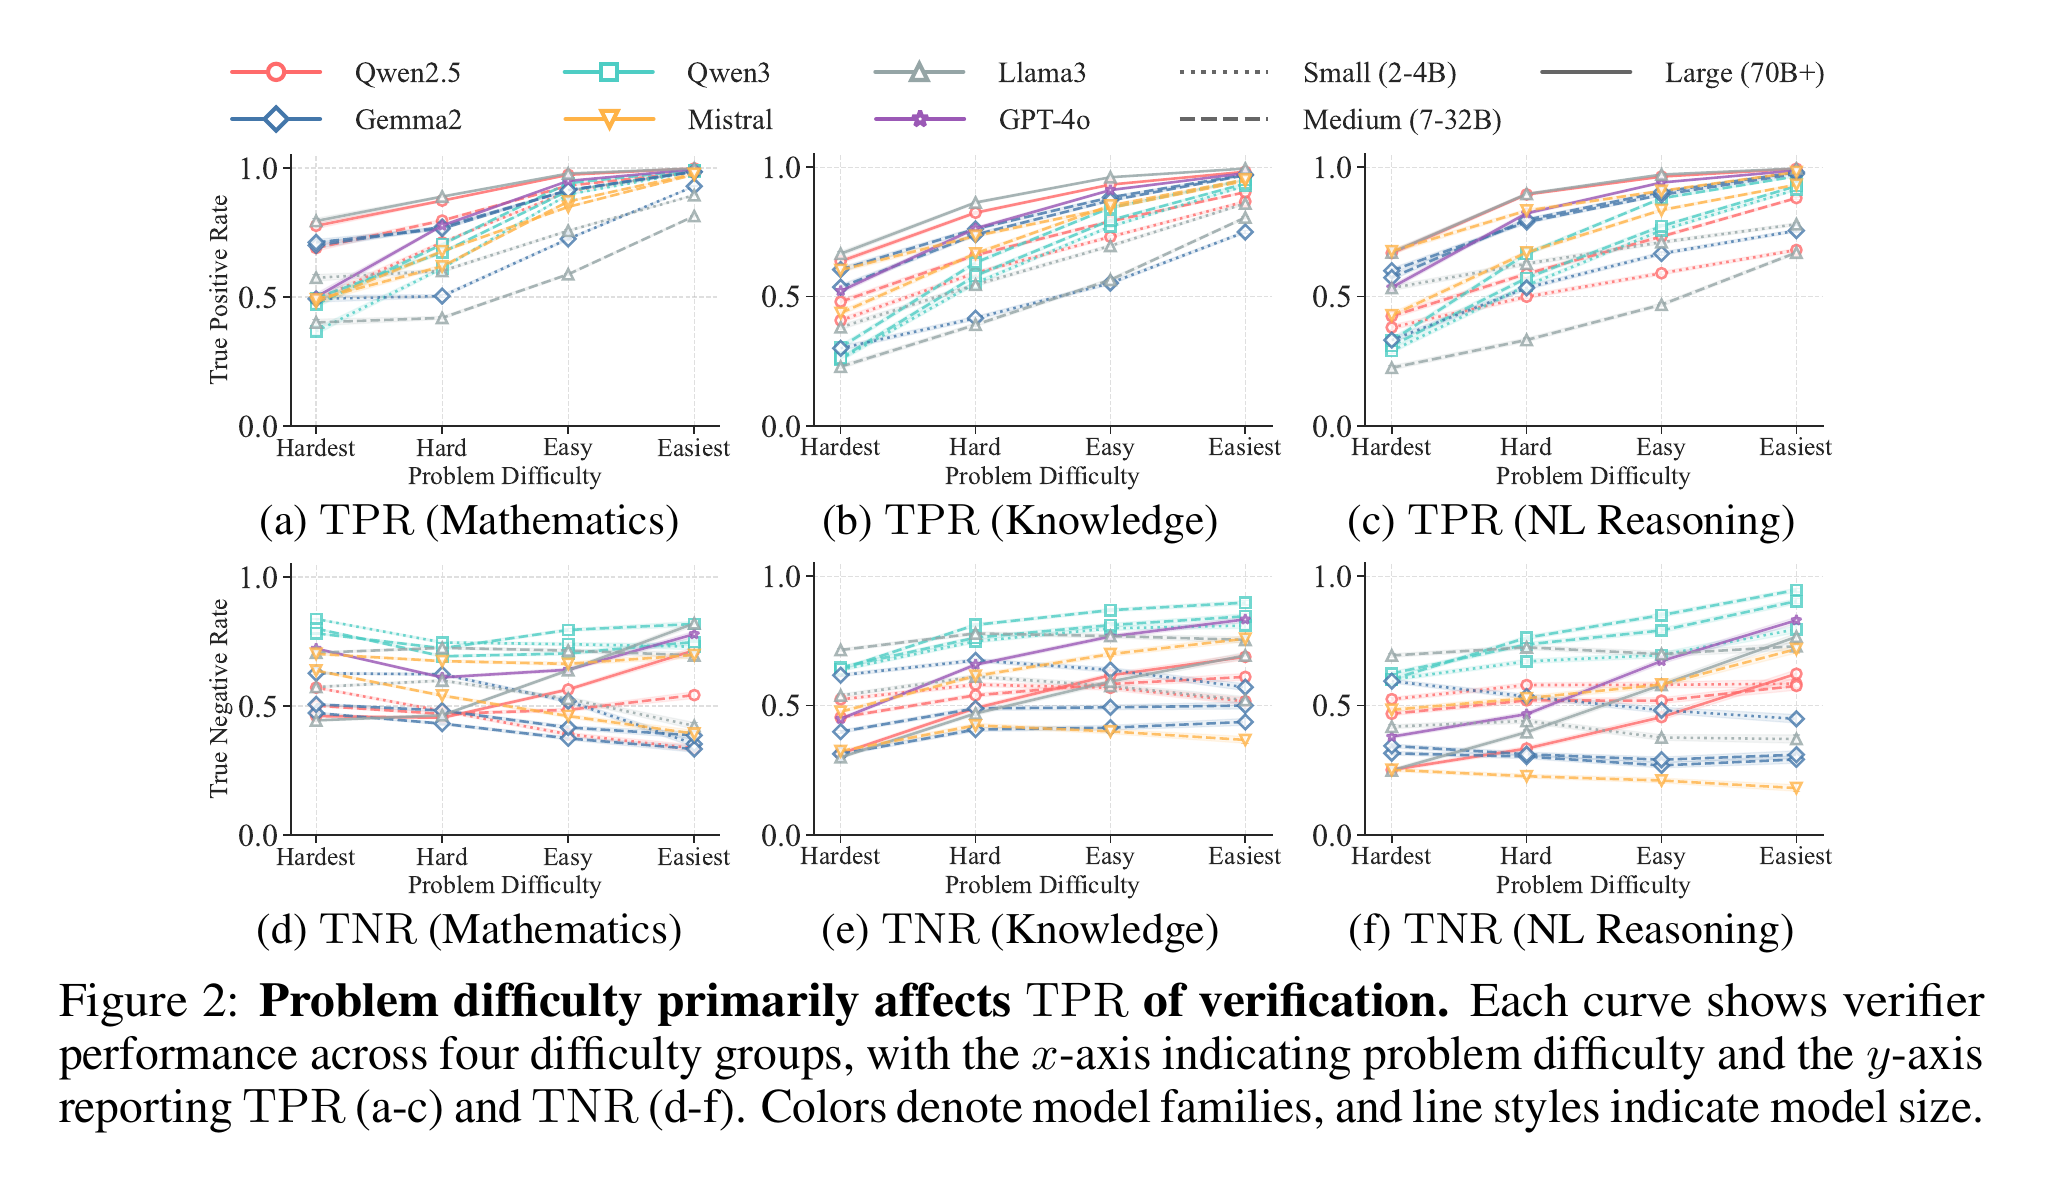
LLM verifiers across 12 benchmarks. Easier questions made correct answers easier to accept, and wrong answers no easier to reject. Wrong answers from stronger generators were harder to reject. Nor is difficulty visible in the request.
The split holds for machine checkers too.
A company ran an LLM router for four months and withdrew it, since what made a task hard isn't in the context the router received; the difficulty only showed up later, in the tool calls.
Outline
A. what supports confidence in an AI answer?
B. checking claims beyond the literature
C. why still read?
D. reading with AI
The research systems again: who does the checking?
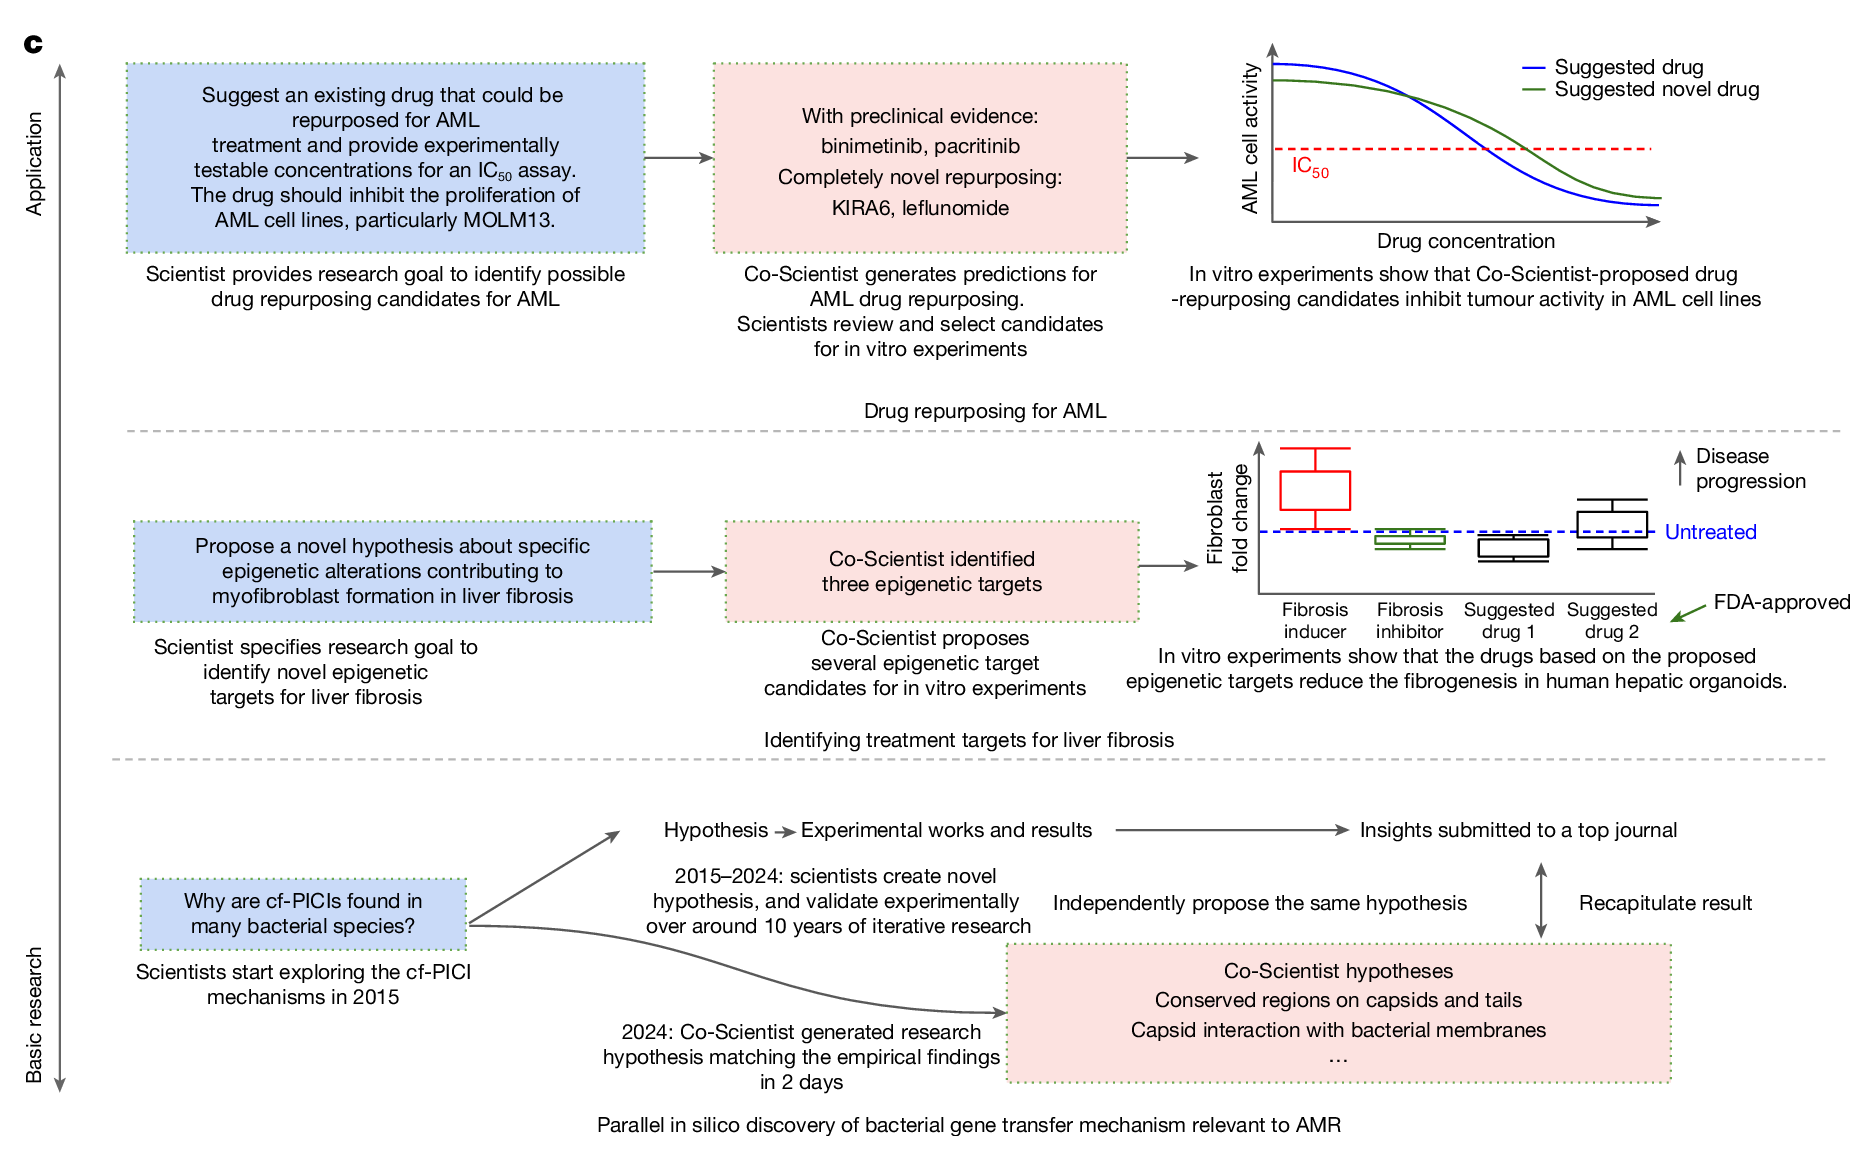
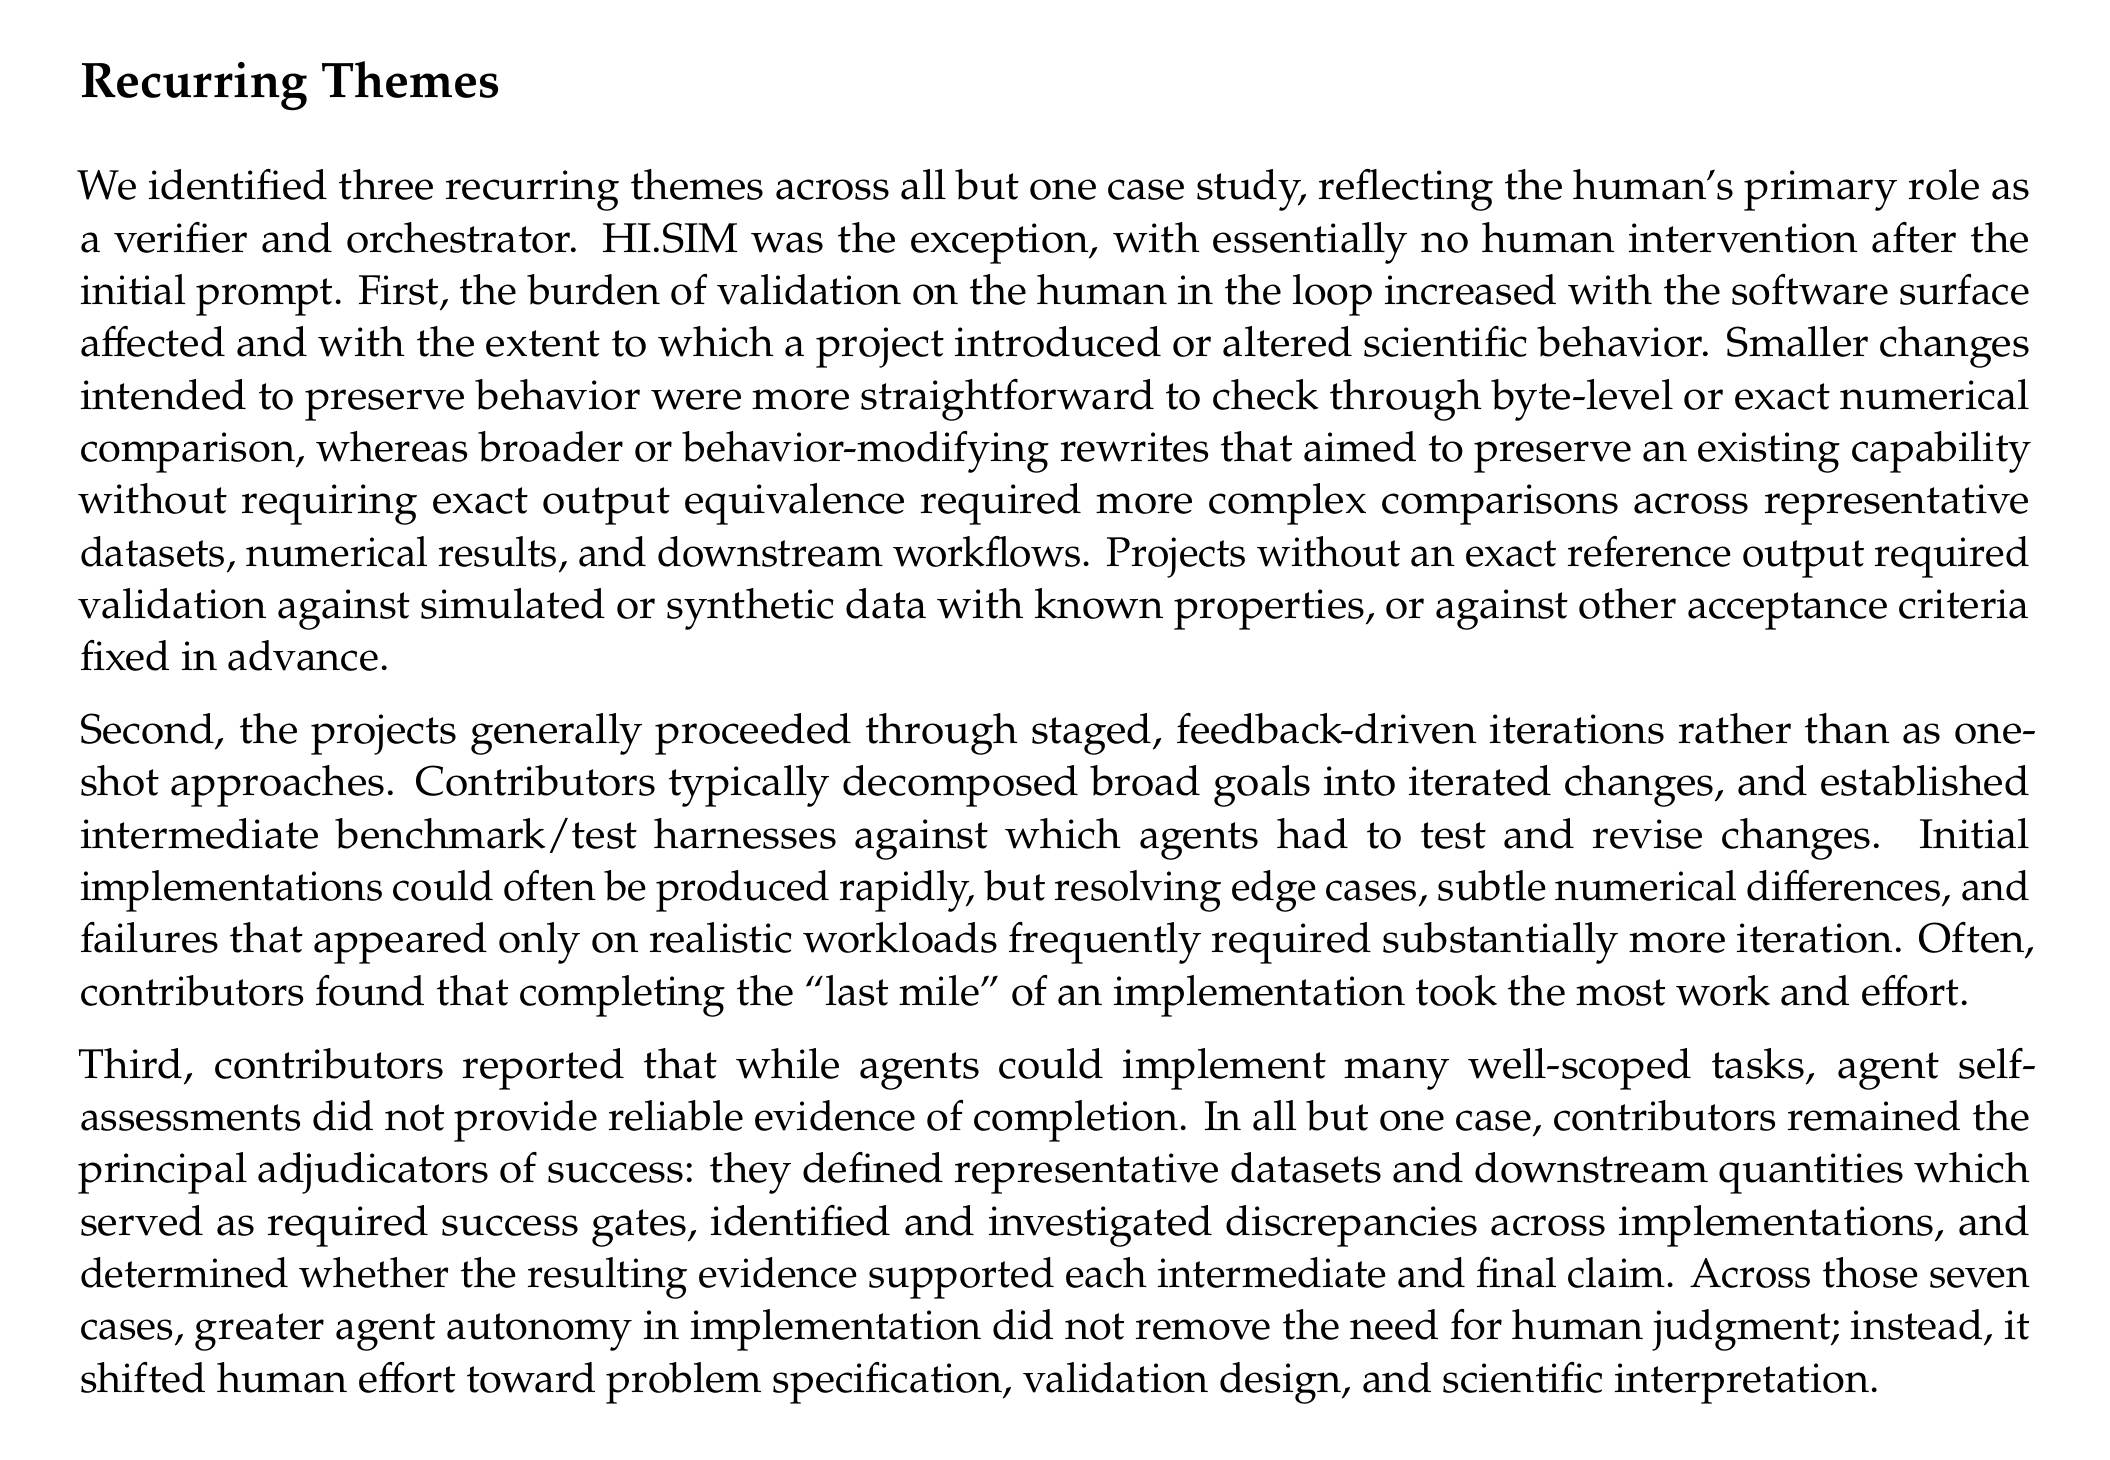
In both, the checks that count as evidence are done by people.
A result can be new and still have a concrete check
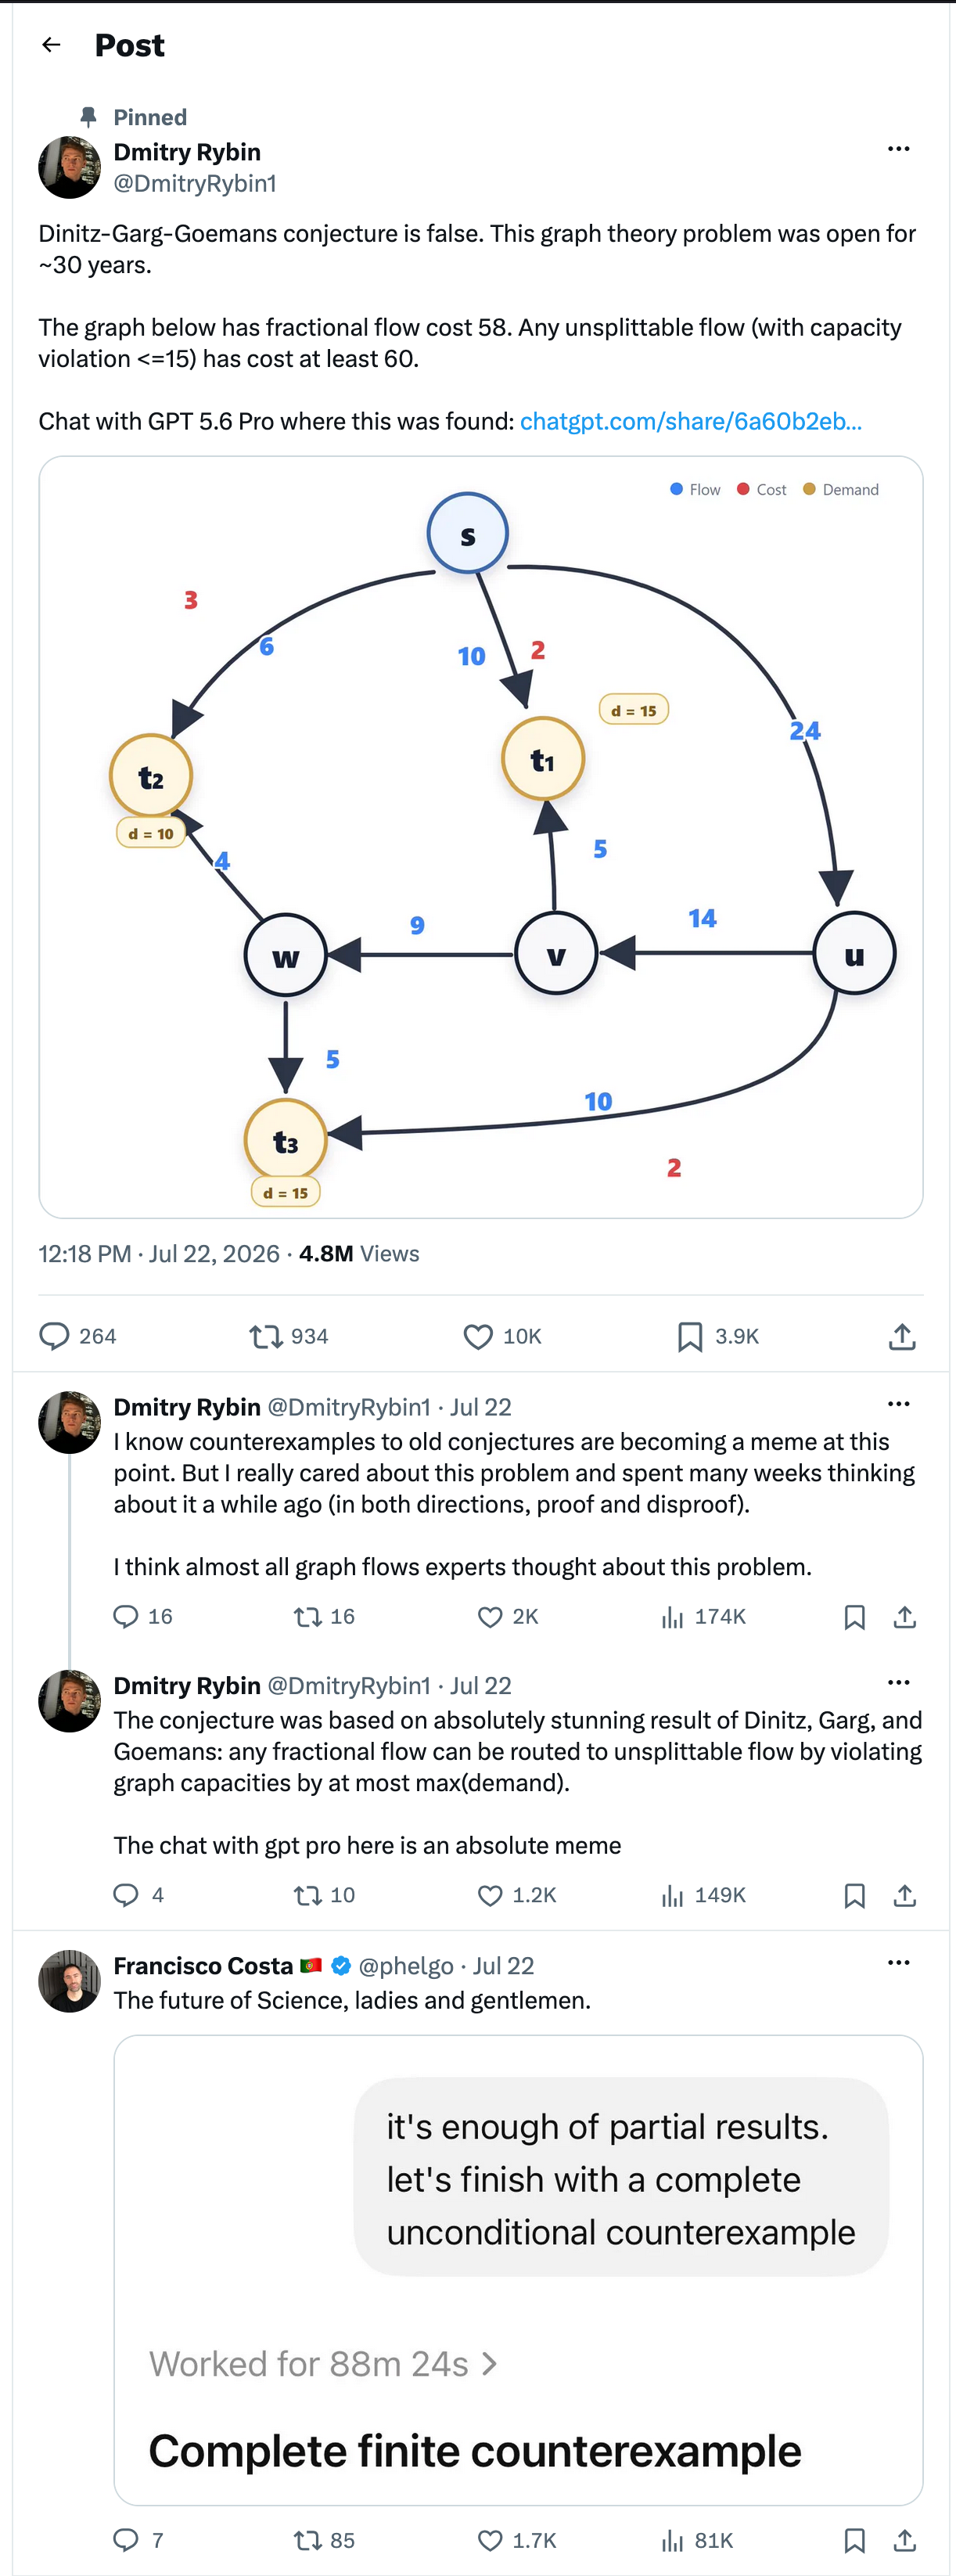
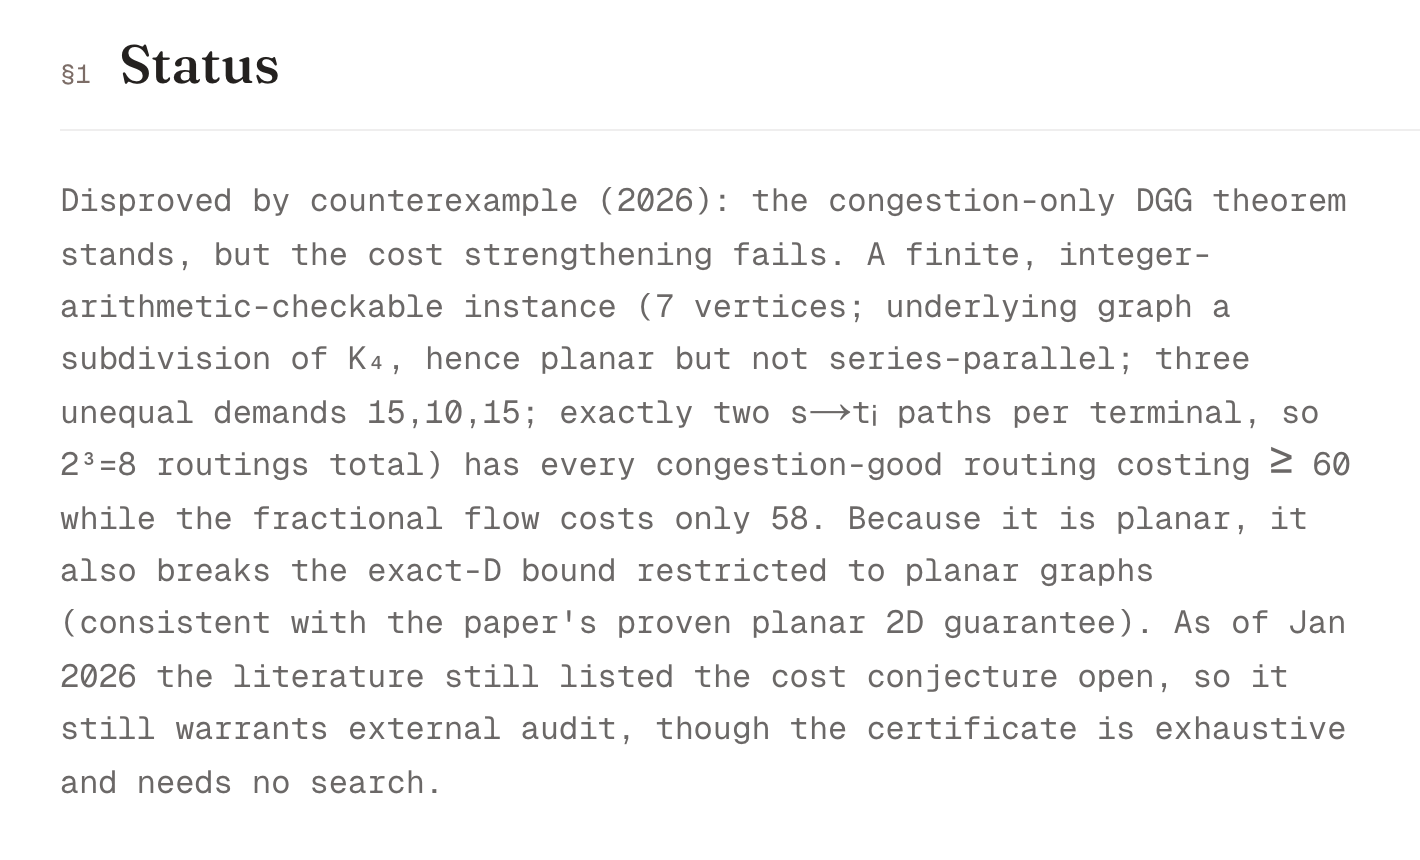
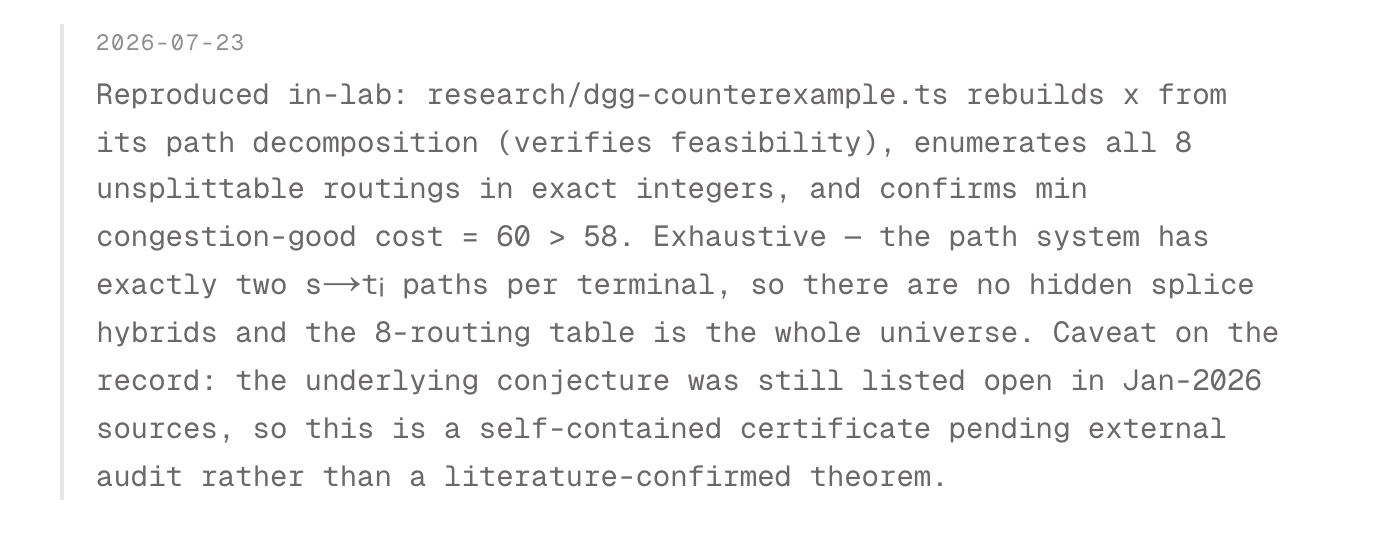
Is this a counterexample, and how would we know? Eight routings is a finite set to enumerate.
Looking up a credible source is one way to verify; running a check ourselves is another.
A counterexample is not a success rate
One valid counterexample refutes a universal claim.
To judge how often a method works, we need observations across relevant cases.
The flow example leaves open how many prompts produced plausible but invalid candidates.
AI-assisted mathematics in 2026
May
Unit distance
Human checks
Later Lean proof
July
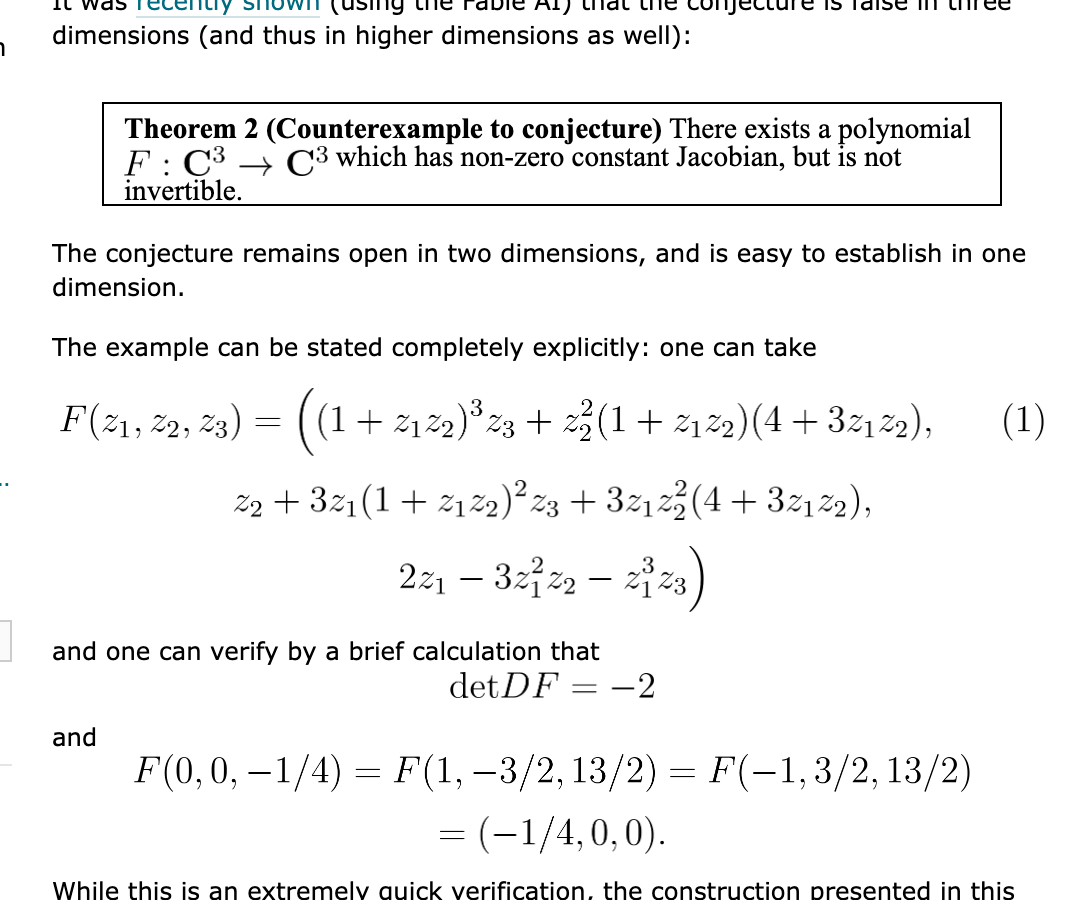
Jacobian
Counterexample
Lean + Isabelle
August
HRT
Analytic proof
One certified bound
September
k-server
Proposed proof
AI contribution disclosed
A counterexample settles in a day; understanding takes longer
Jul 19, evening
one post on X: a degree-7 map, three points share an image, credit to "fable"; no method, no paper
Jul 20
Lean and Isabelle verifications, both within a day; a blog post titled "Human mathematicians are being outcounterexampled"
Jul 21 to 23
digestion posts explain the mechanism; a geometric account follows
Jul 31
a preprint with an infinite family and five new maps
Sep 15
a mathematician on the problem since 1985 shows the example is findable by elementary means
Correctness and novelty are separate checks
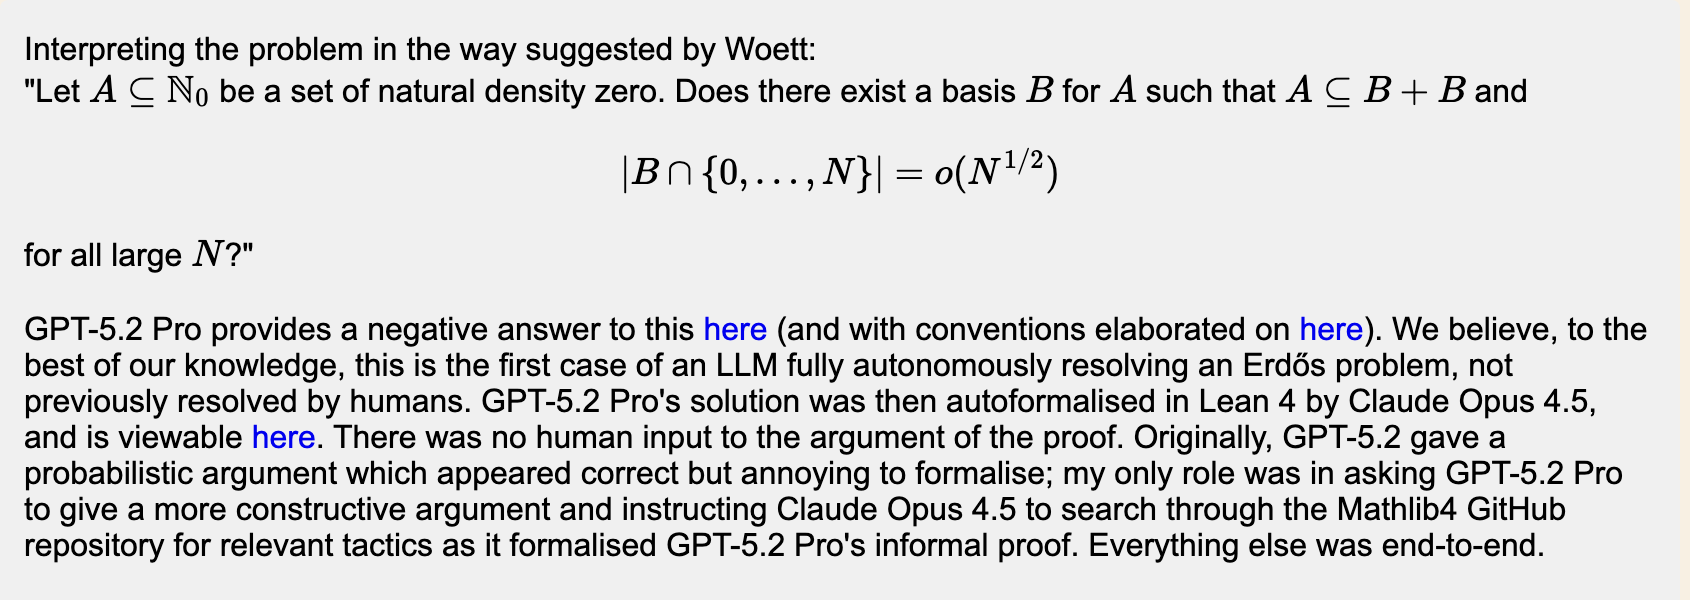
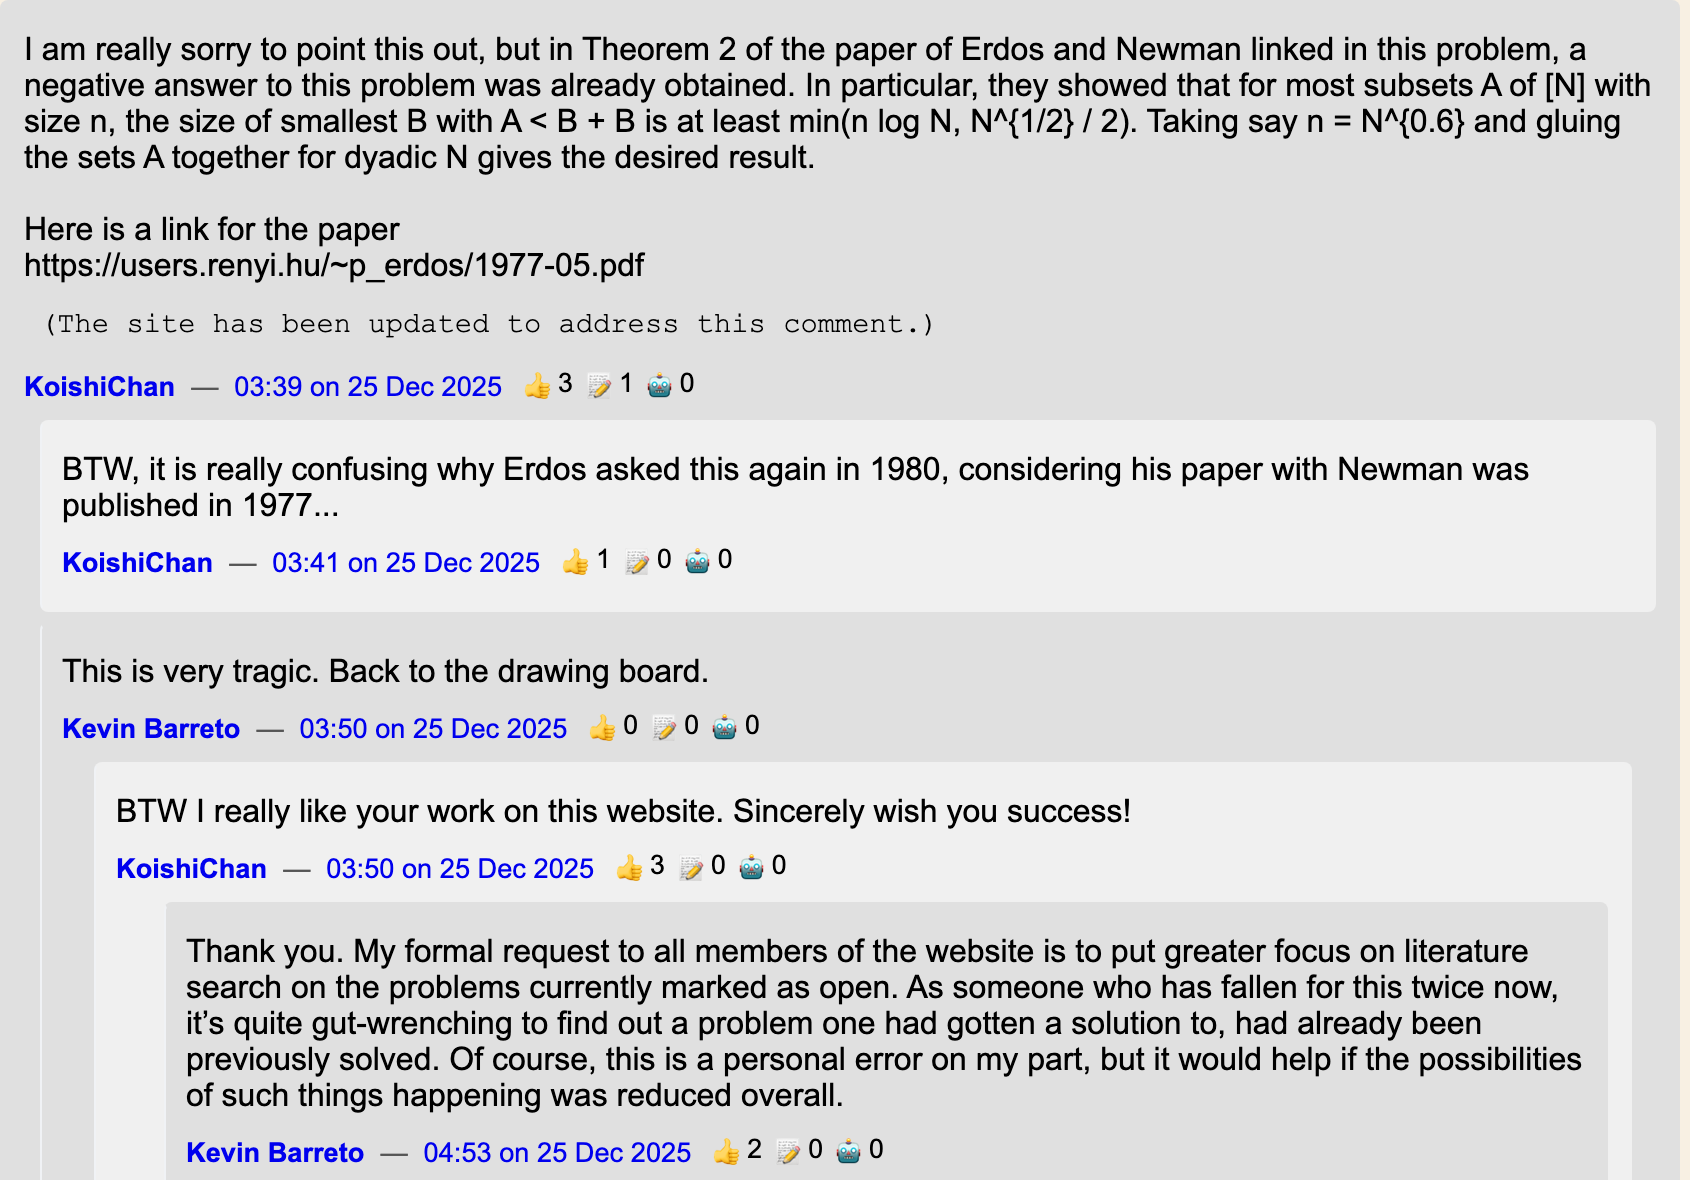
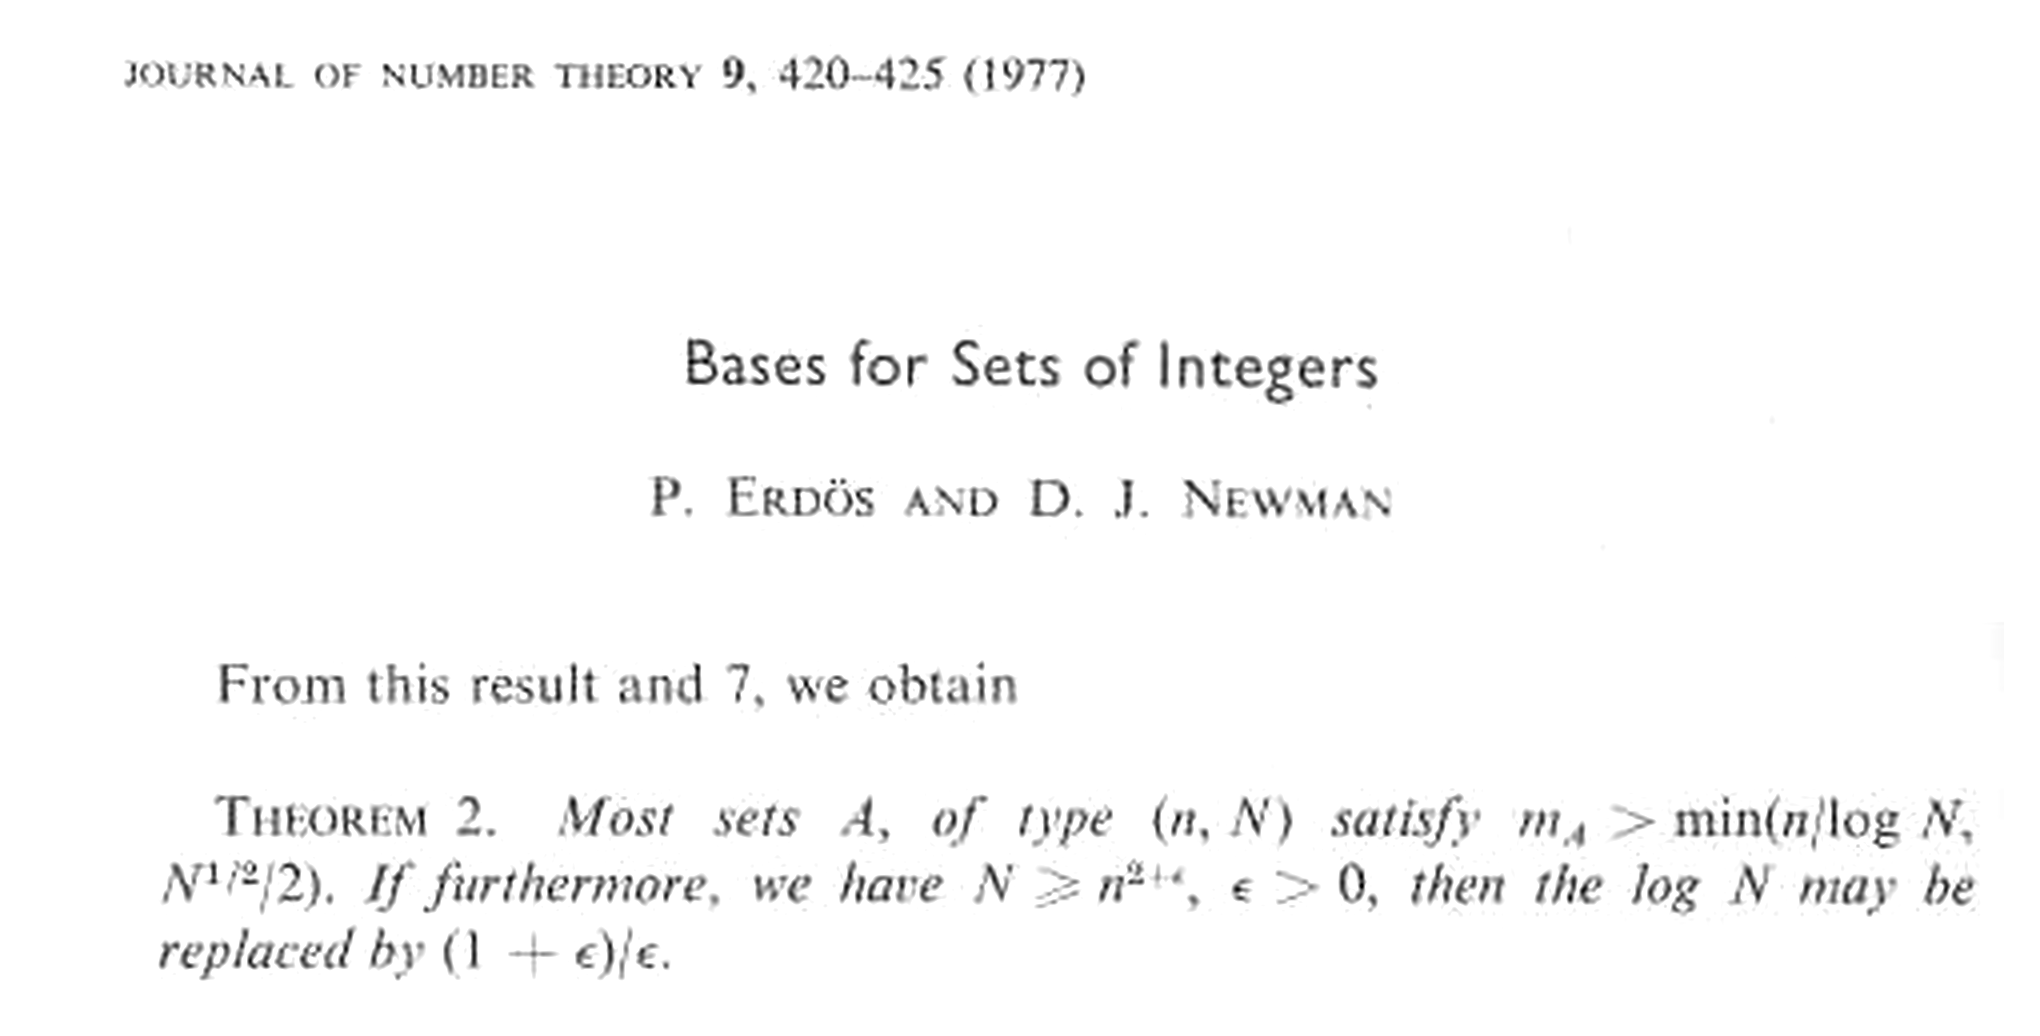
The proof is correct. The novelty claim lost within hours, when a commenter pointed to a 1977 theorem. Knowing the earlier work changes what we can claim as a contribution.
Similarity finds relevant text. It does not by itself check what a paper adds, and a collection that lacks the earlier work cannot return it. Six models refilling 132,000 citation slots wrote fewer contrasting citations than the human authors and rewrote "prior work fails at X" as supportive far more often than the reverse, with or without web search (EMNLP 2026).
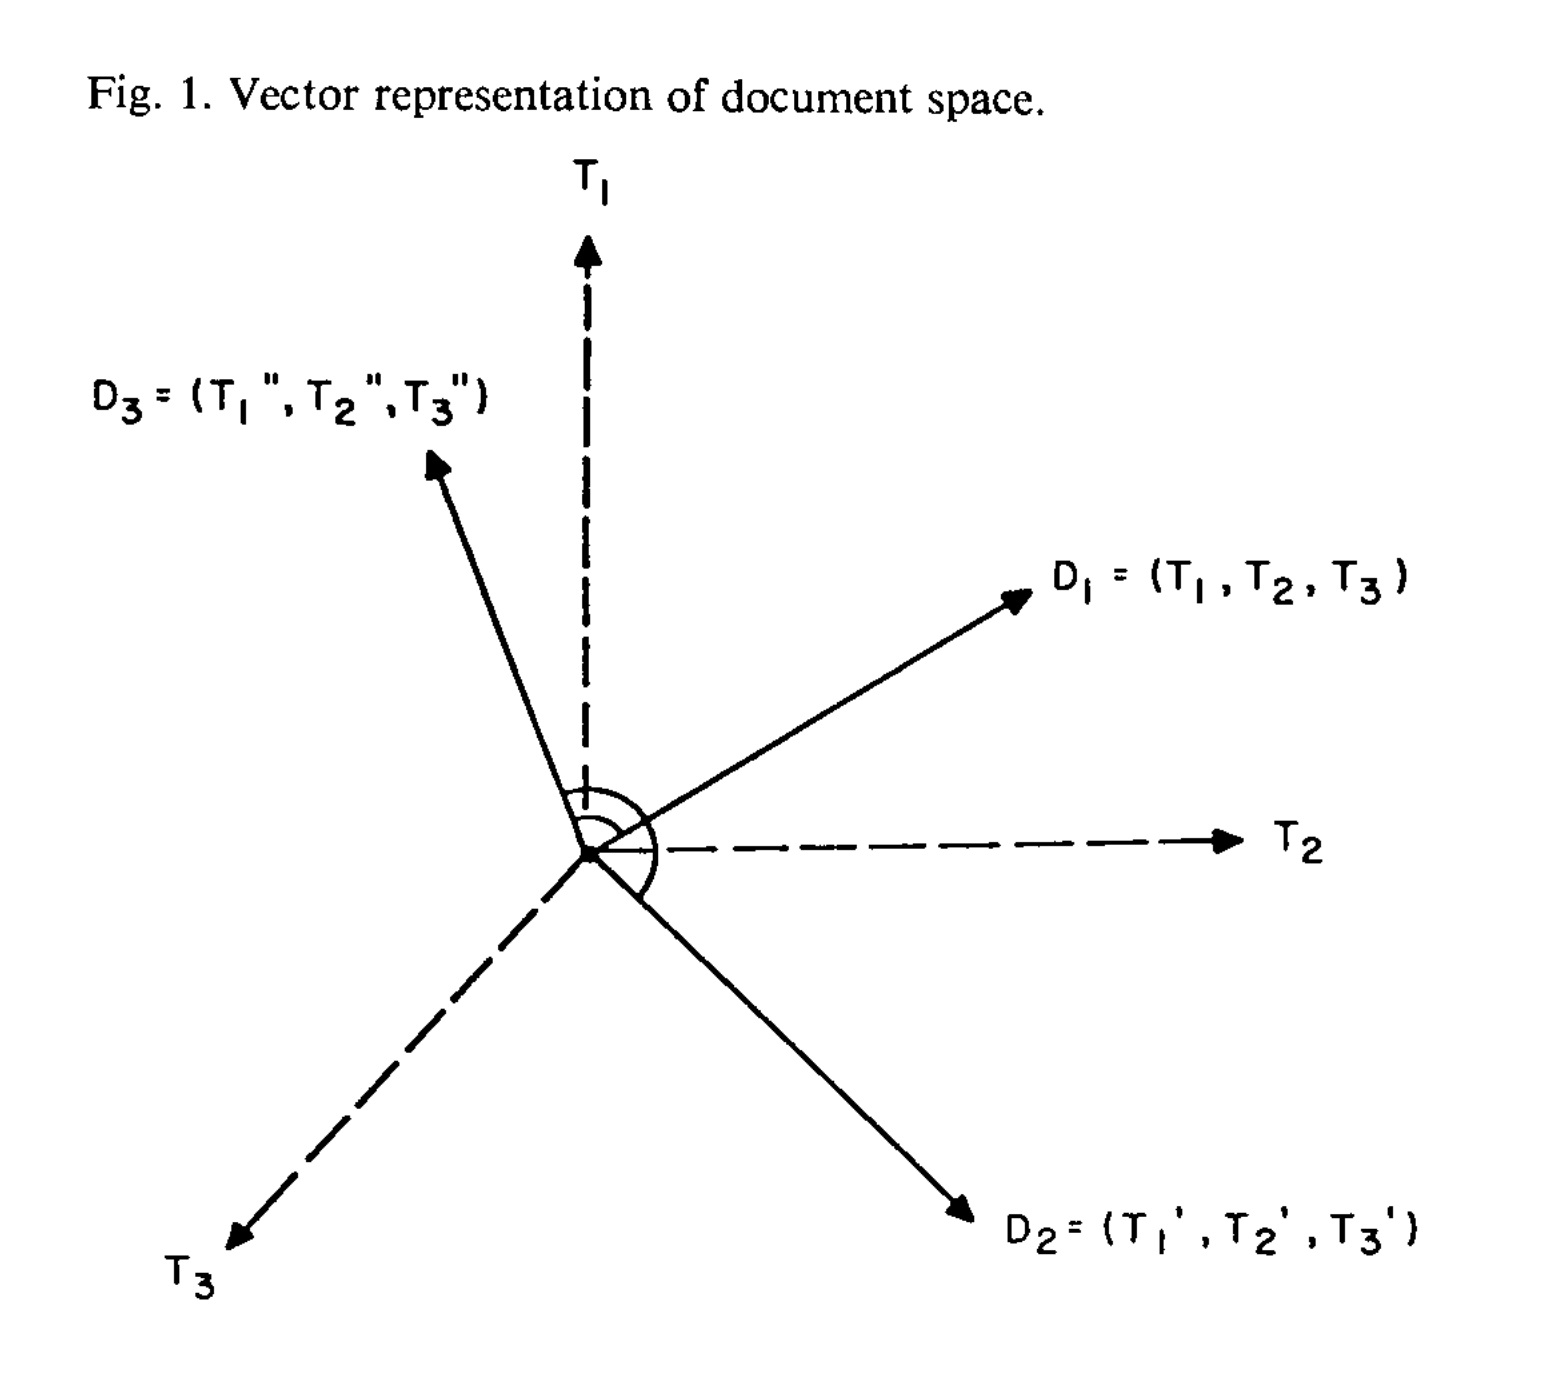
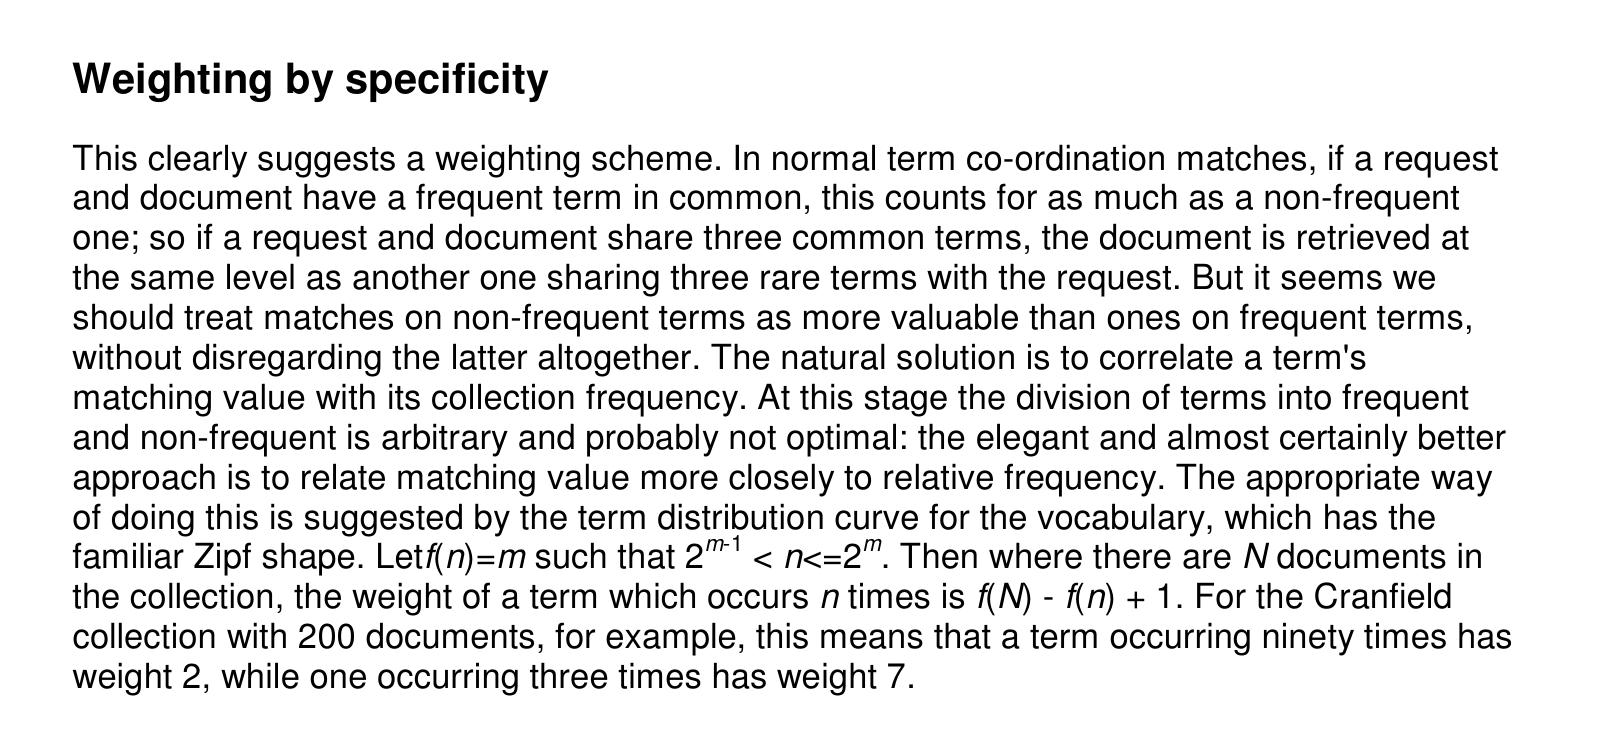
Finding related text and checking novelty are different tasks
Outline
A. what supports confidence in an AI answer?
B. checking claims beyond the literature
C. why still read?
D. reading with AI
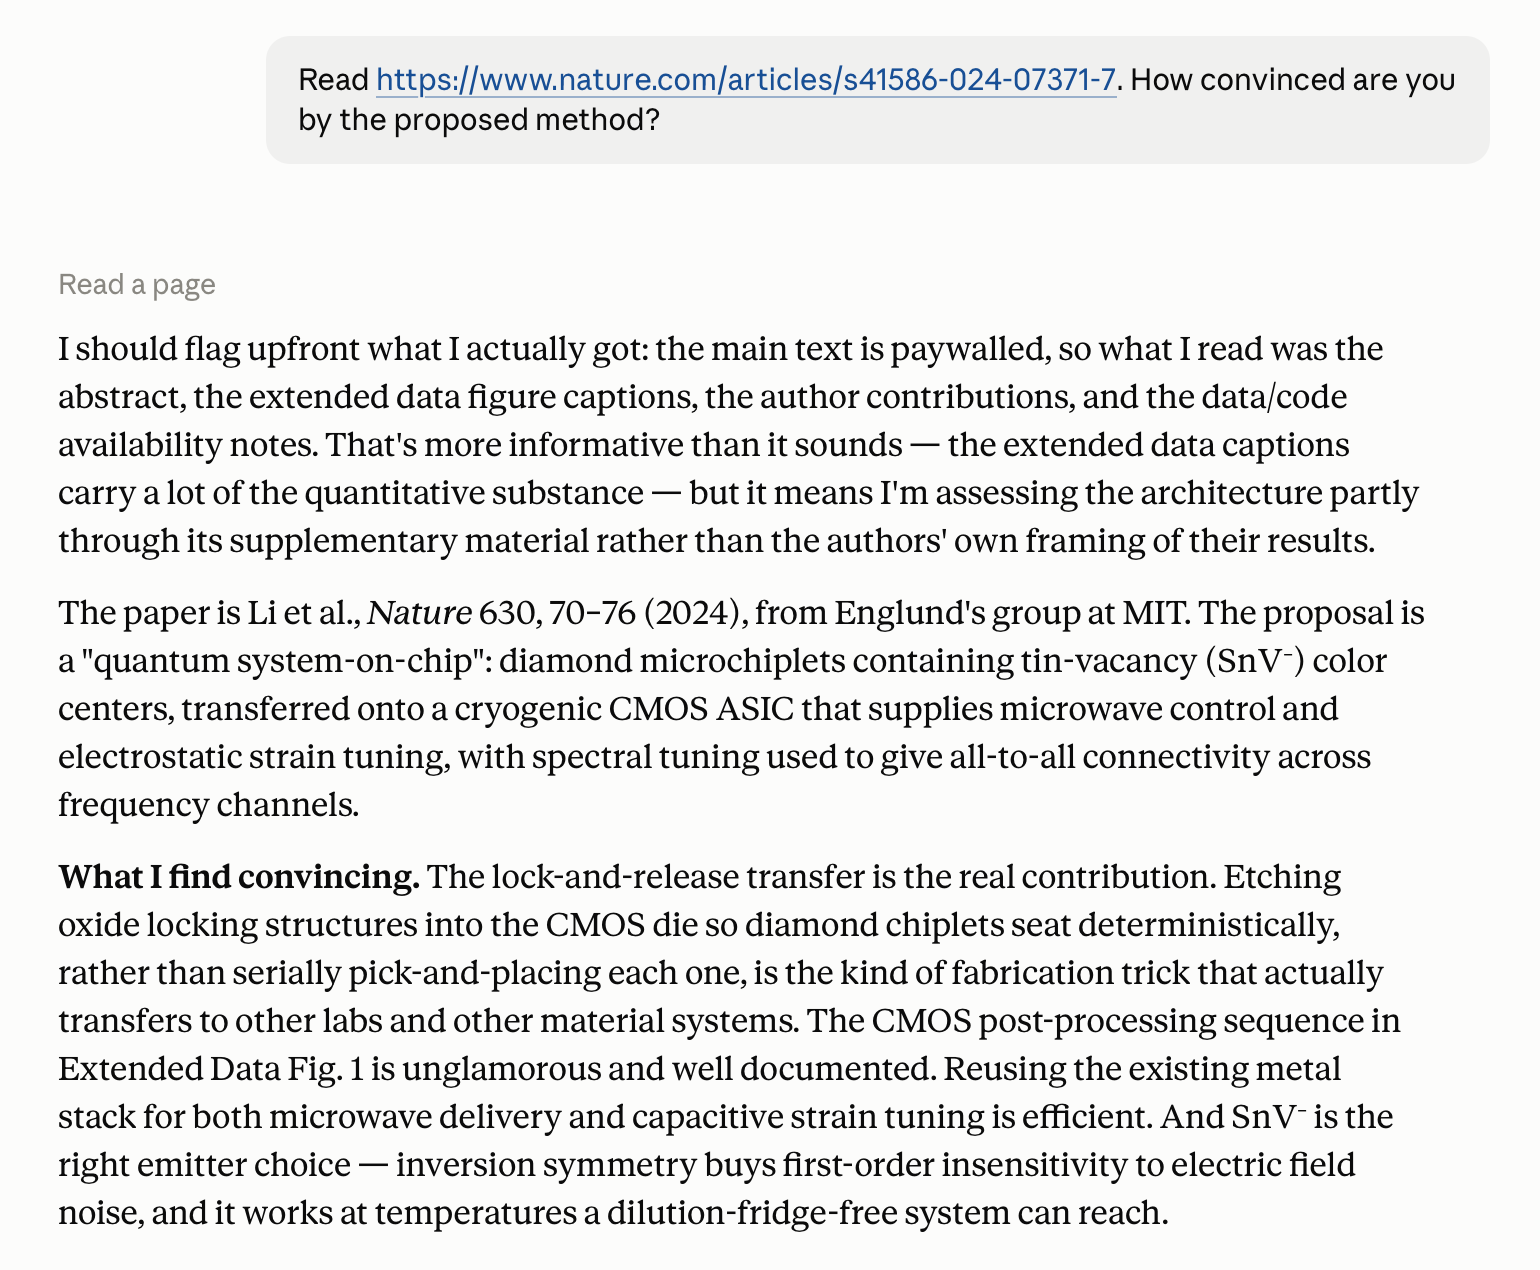
What background would make this explanation understandable?
What would then be needed to assess its claims?
Reading helps us build contextualized map of a field
We can follow the efficient attention paper's AI read, but may not be able to follow this quantum-chip paper.
Four-question recipe for engineering papers
MOTIVATION why should we solve this problem
SOLUTION how did we solve (method); how do we know it's any good (eval)
OLD IDEA how did people before us attempt to solve this problem
DELTA what have we done differently
Typical exceptions:
- a phenomenon paper (no solution yet);
- a many-ancestor paper (placement is a graph, the recipe can hold one edge);
- a survey paper (a whole concept graph, which we ultimately want to build for ourselves for other fields, the recipe for every edge);
The four questions have a lineage
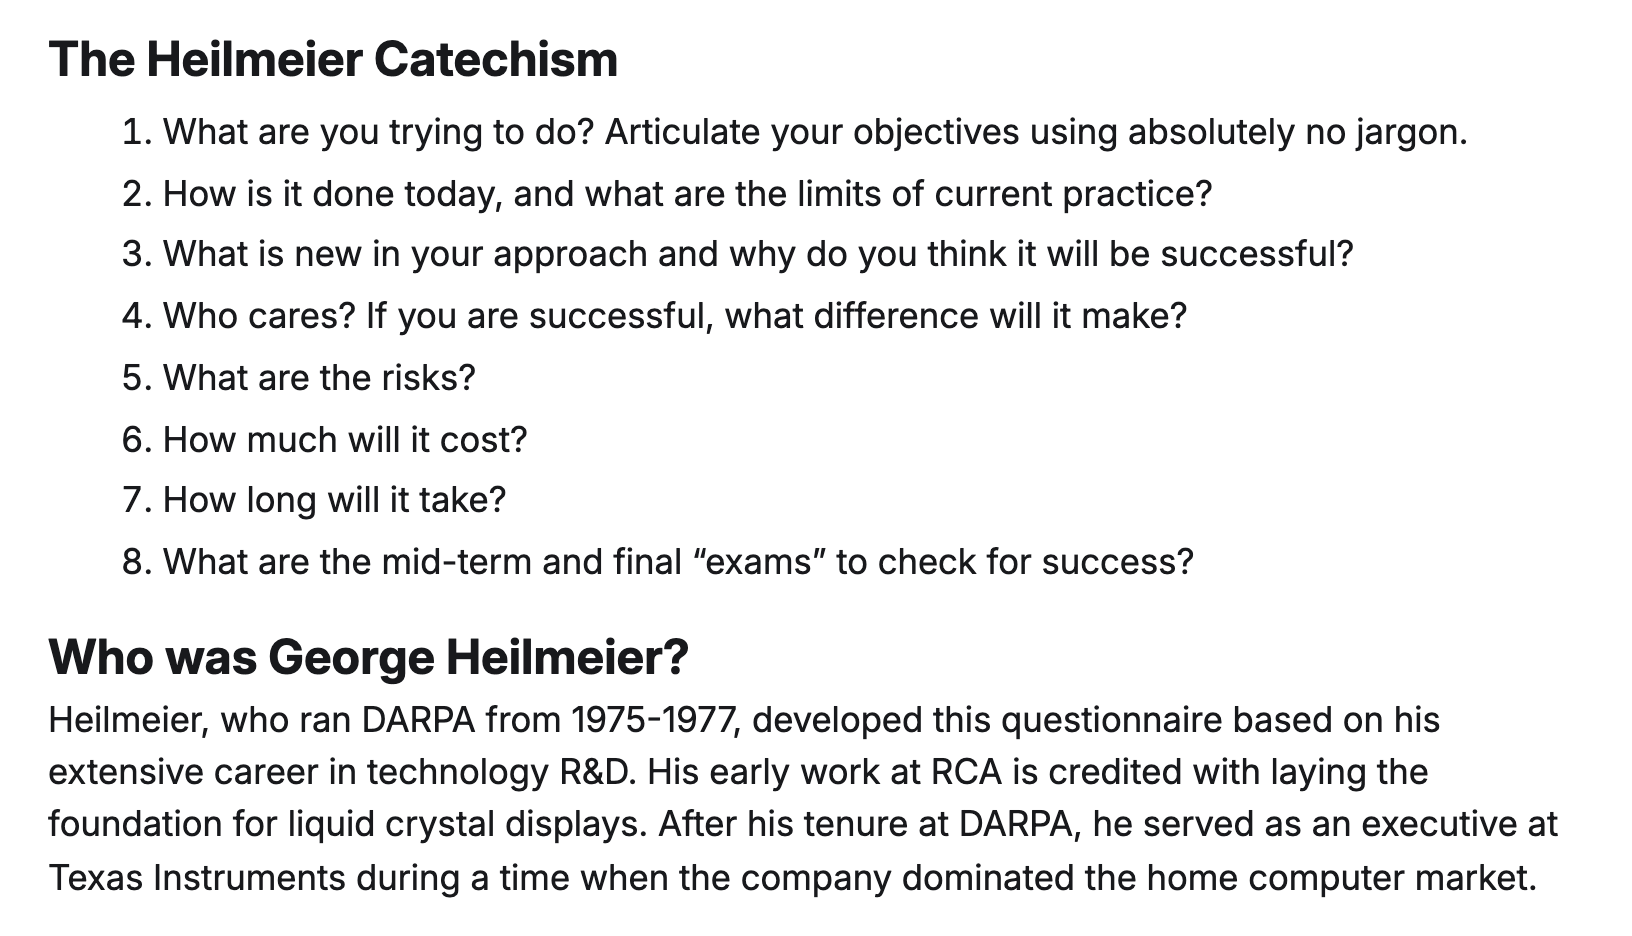
A proposal-writing tool, repurposed for claim auditing.
(this repurposing is our delta.)
Reading earlier work also helps us choose a question
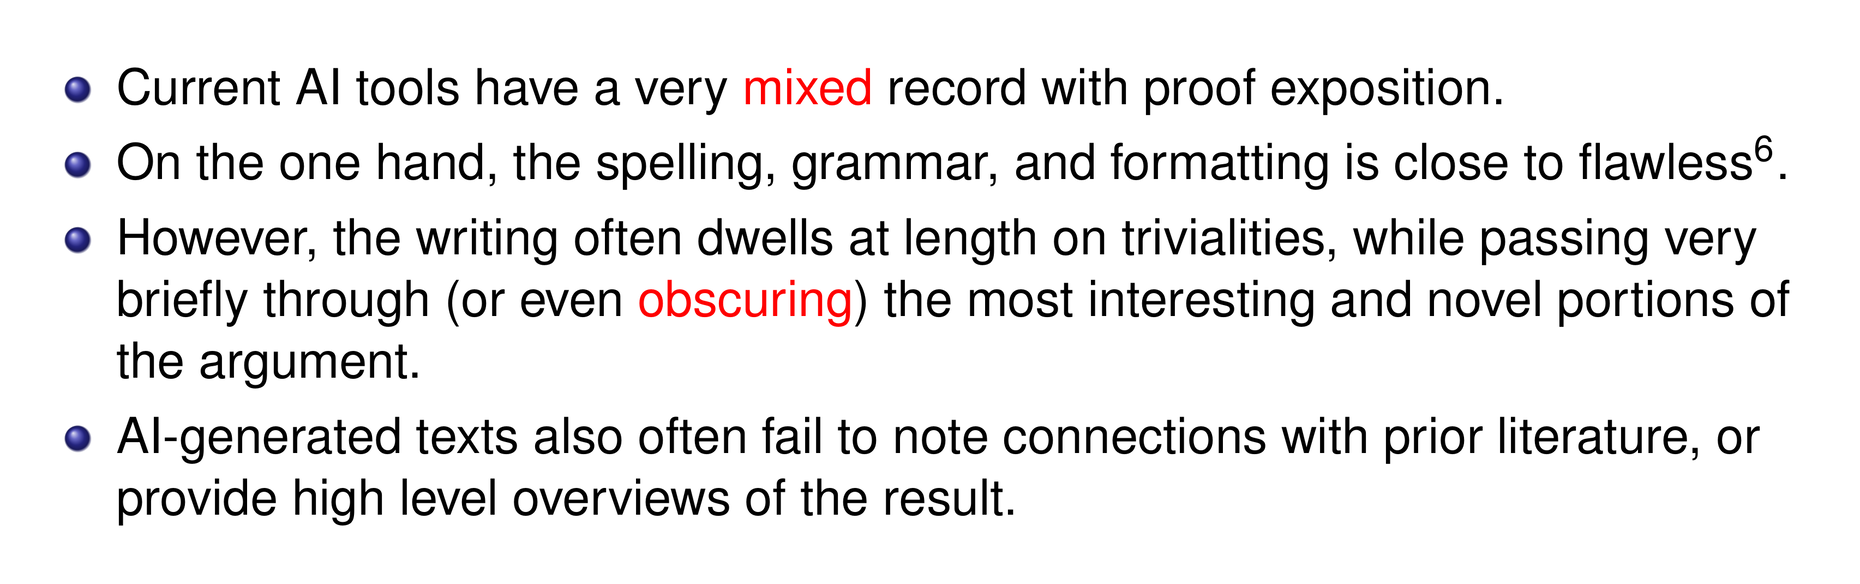
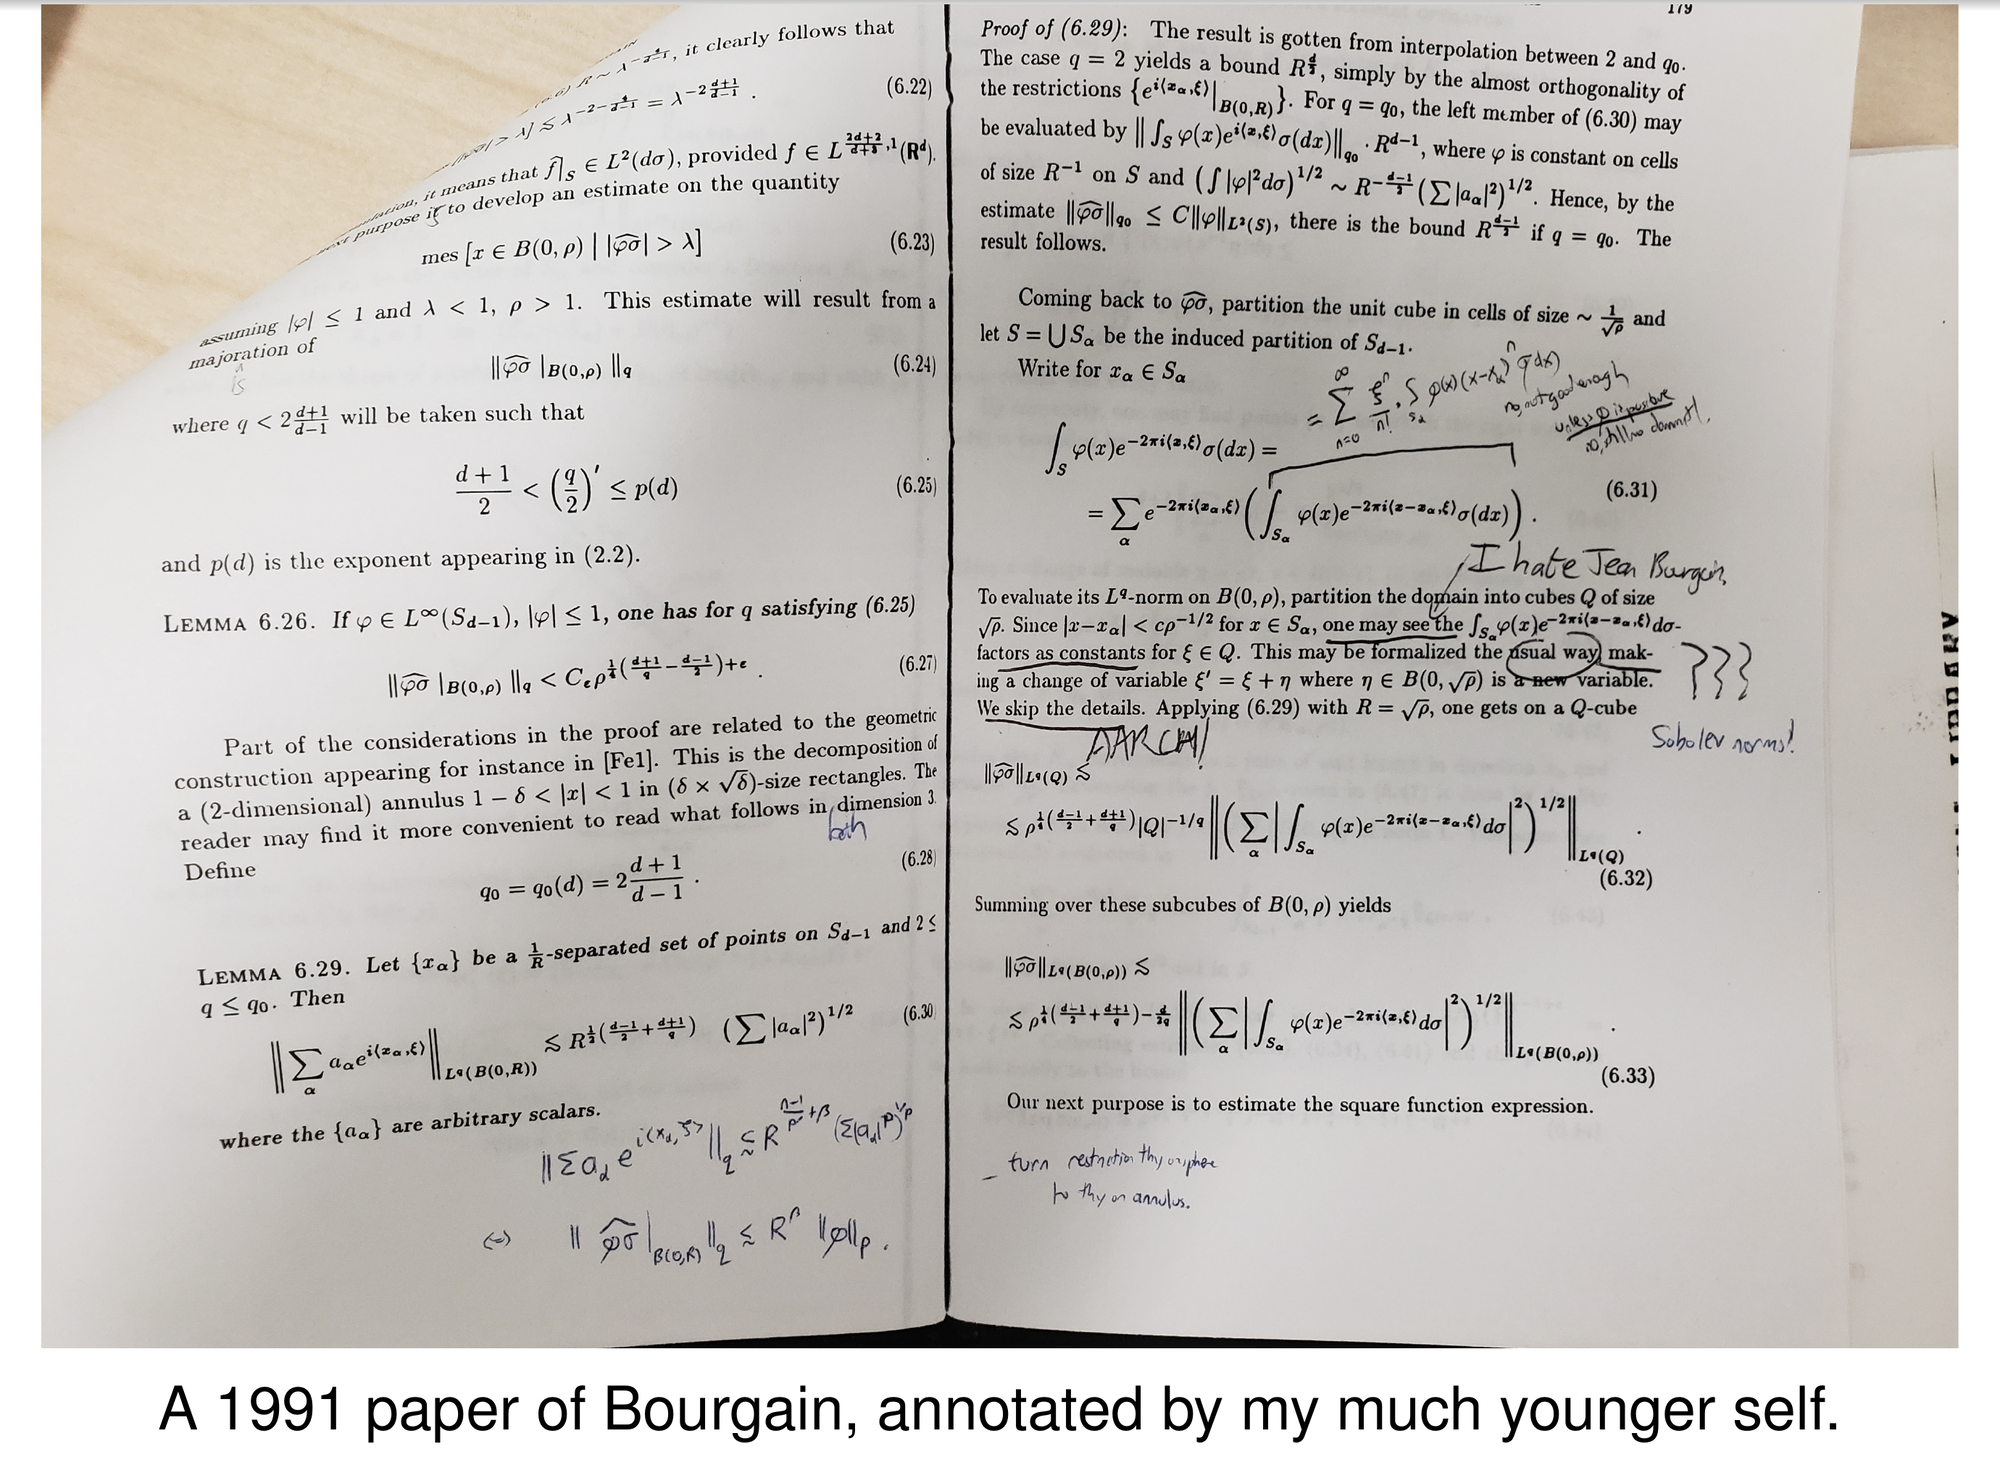
Which step carries the contribution, and how does it depend on earlier results?
What we generate, we remember
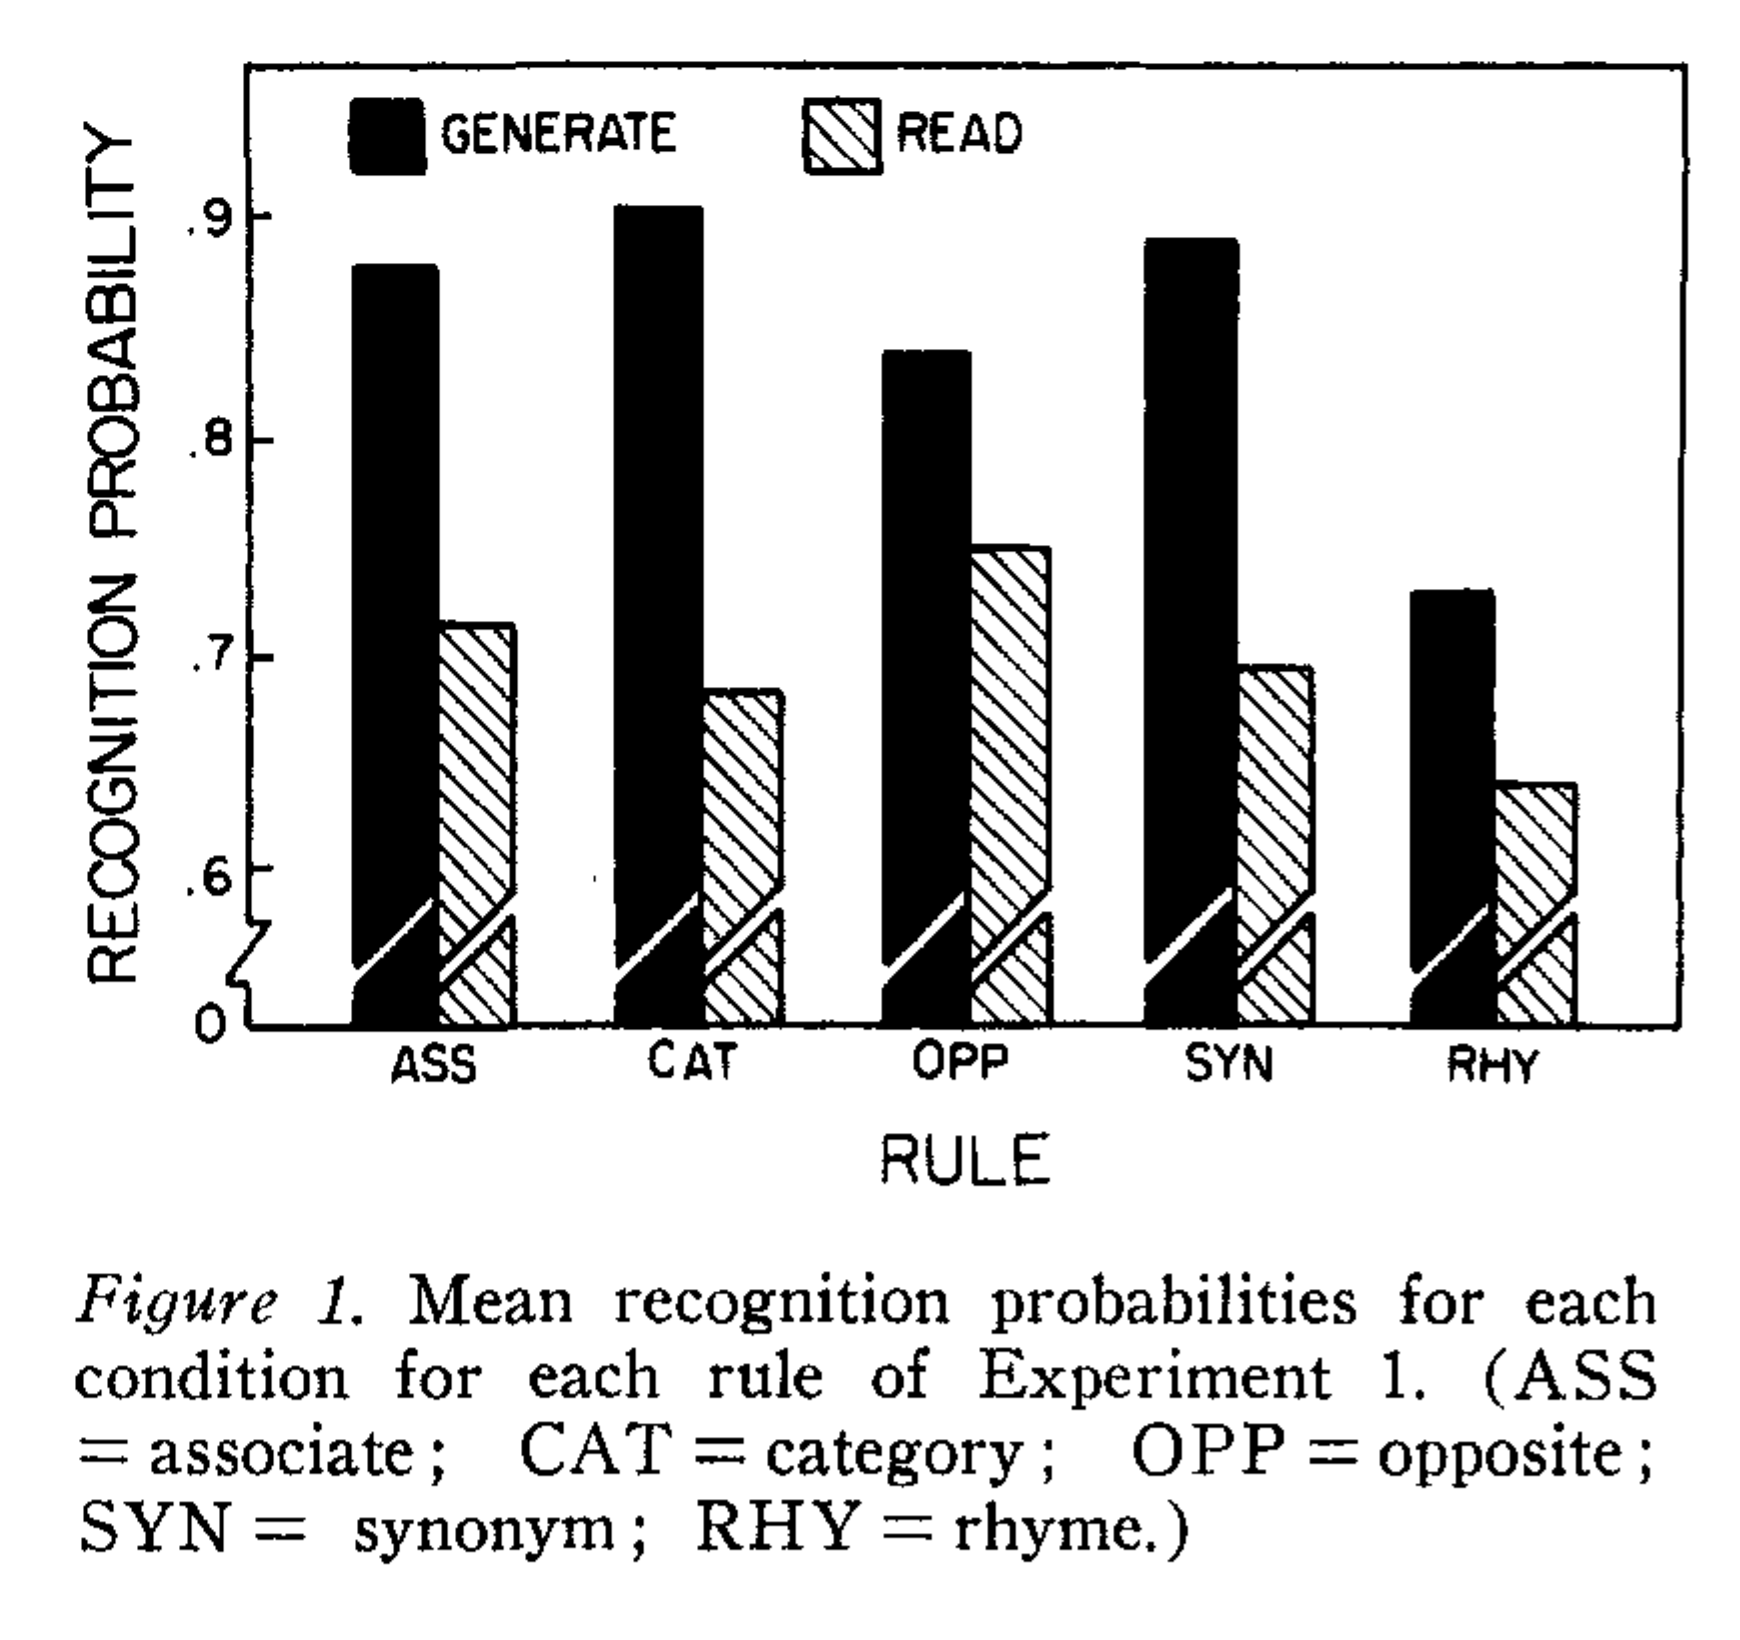
Words we generate are remembered better than words we read (1978). Single-word recognition, not paper reading; it supplies a hypothesis for writing our own explanation before asking the model.
Distinguish the ease of producing a note from what we can explain later.
Why we borrow "lab checkoff' idea from 6.390 and sister courses
Outline
A. what supports confidence in an AI answer?
B. checking claims beyond the literature
C. why still read?
D. reading with AI
What seems to work well:
1. Skim, for an initial impression and explanation without AI.
2. Ask AI to challenge our answer, or help with the step we cannot follow.
Check AI response against the paper, the field, the code, etc.
3. Explain the result to a partner (or your good old rubber duck) with AI closed.
we will practice this in lab2
Student Reading Examples (of individual papers)
1. asks for details and explanations; fact check each round and redirect AI when it drifts.
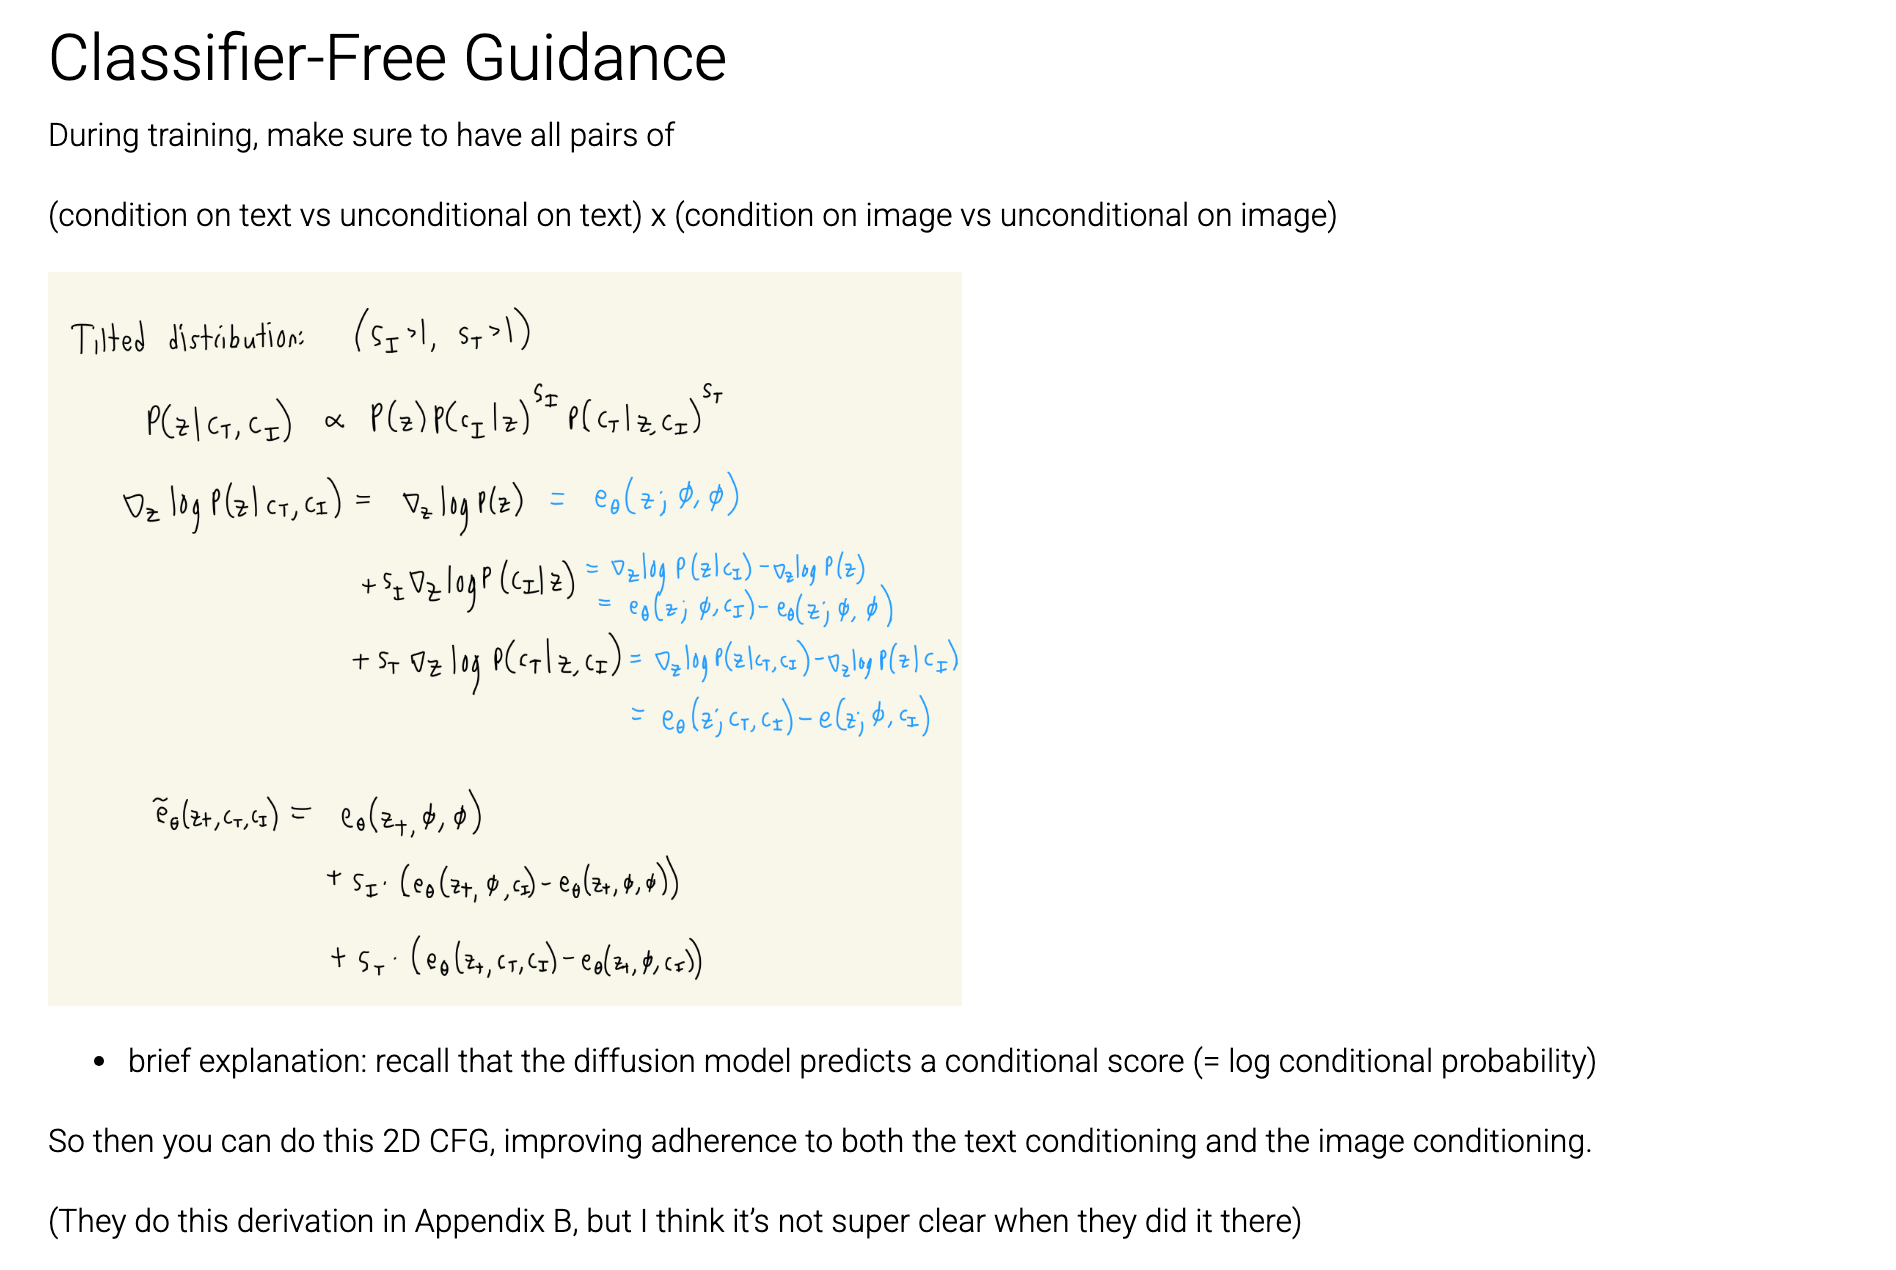
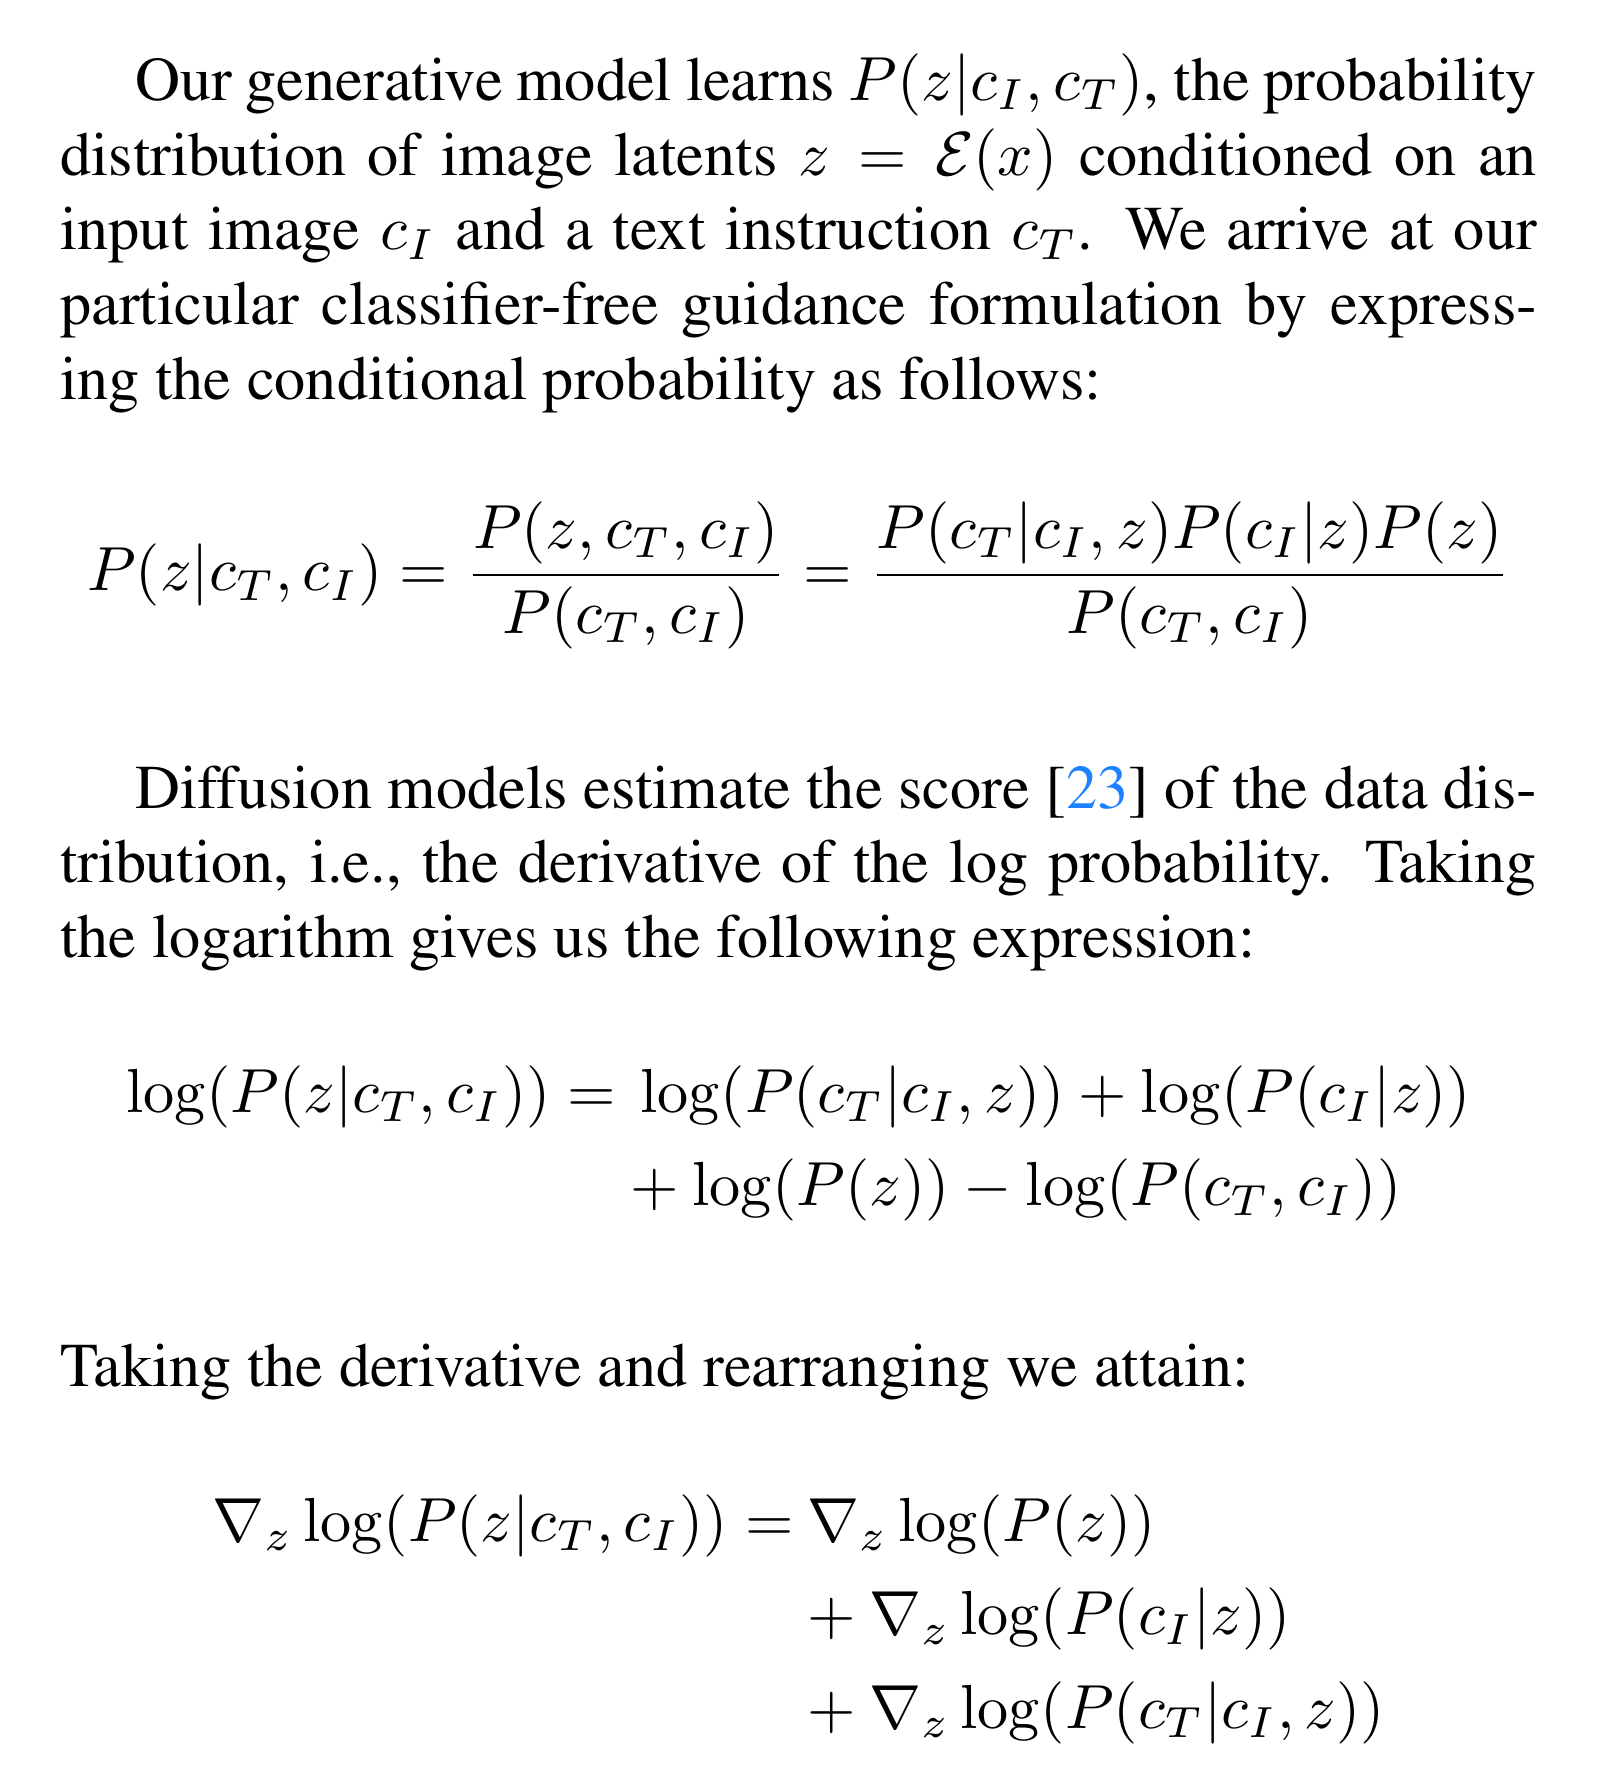
2. Write your summary of the paper and let AI read your summary and critique
3. Ask AI to quiz you on the paper you read
As we read more papers, keep connections
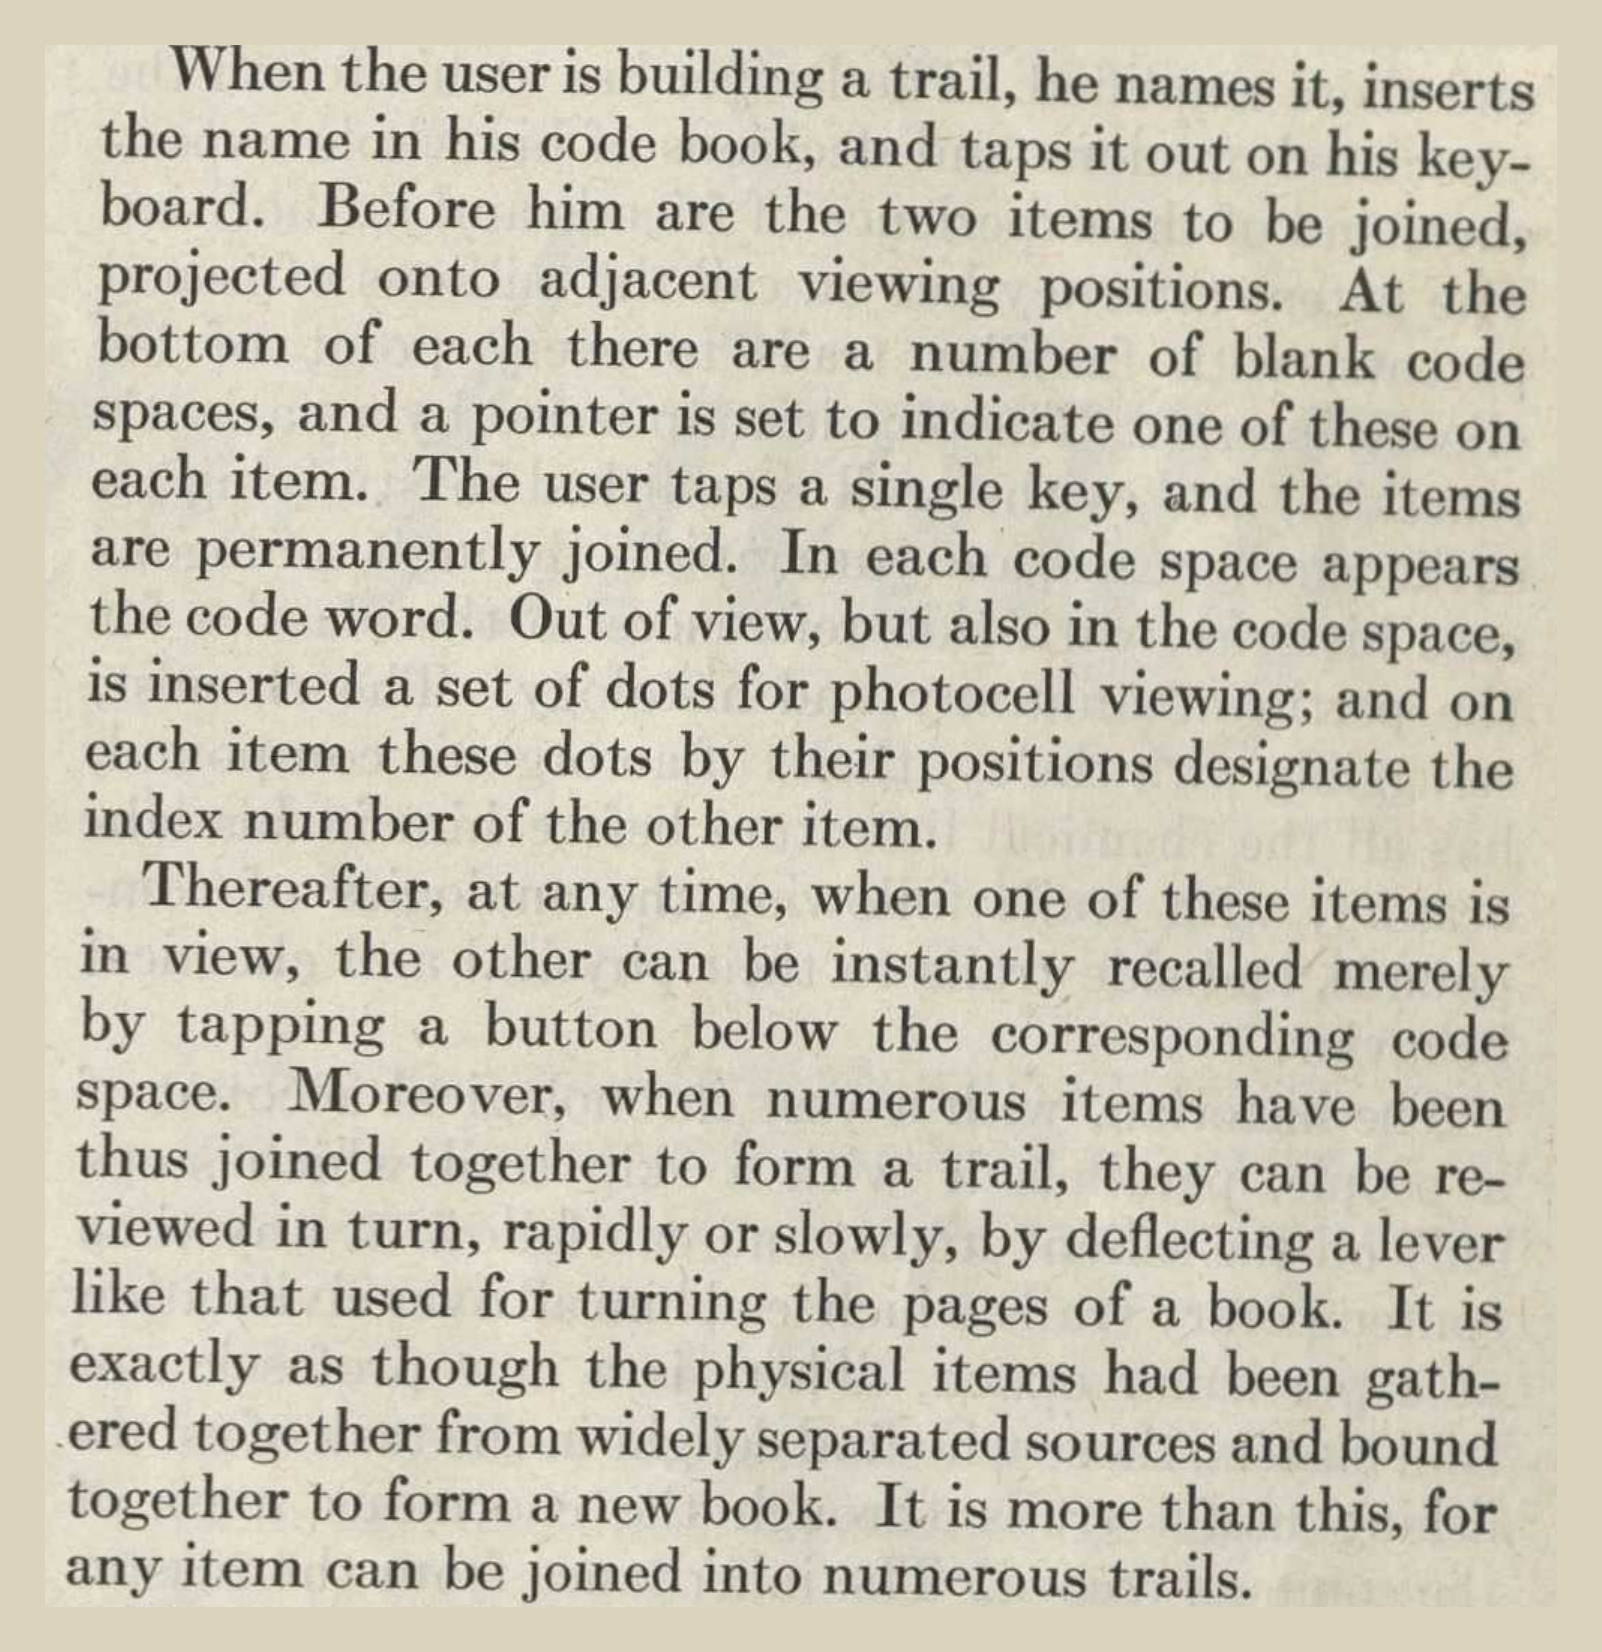
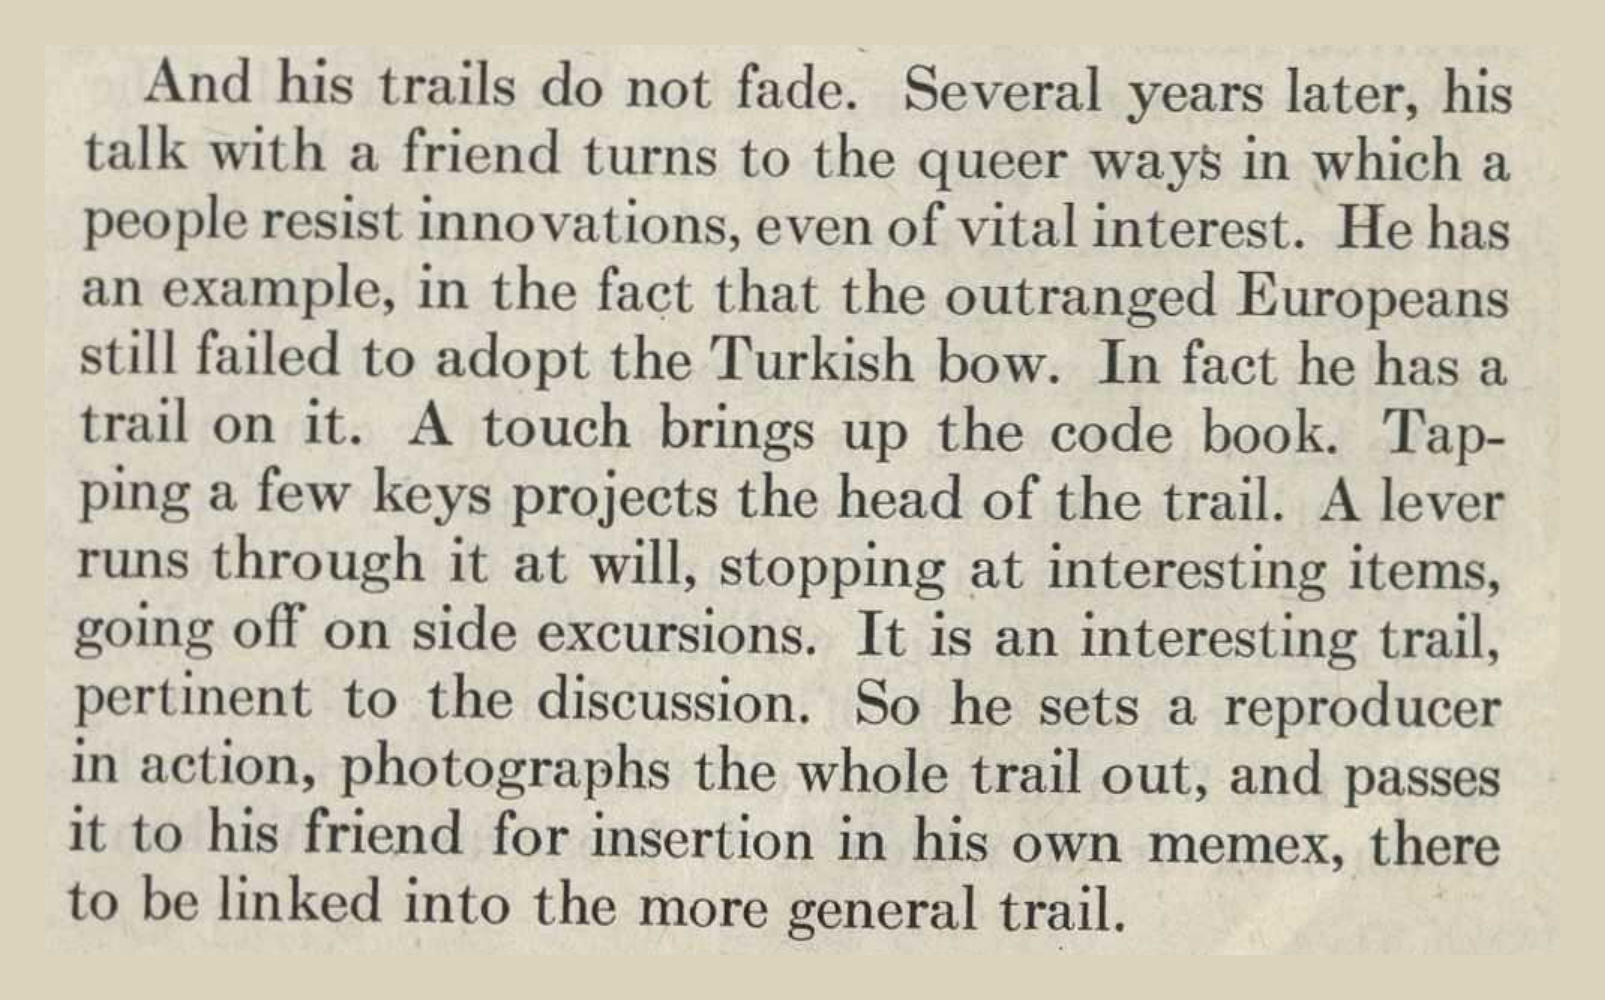
people dreamed of a research machine that stores links between documents so a reader could (re)follow a useful path as they read.
The connection graph is still the reader’s own artifact. Our lineage map is one.
Trails, by hand: 90,000 slips over four decades
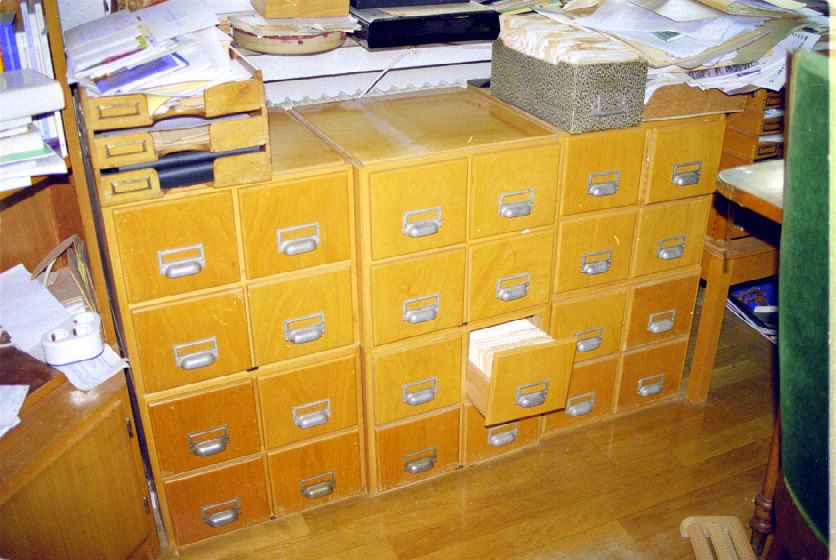
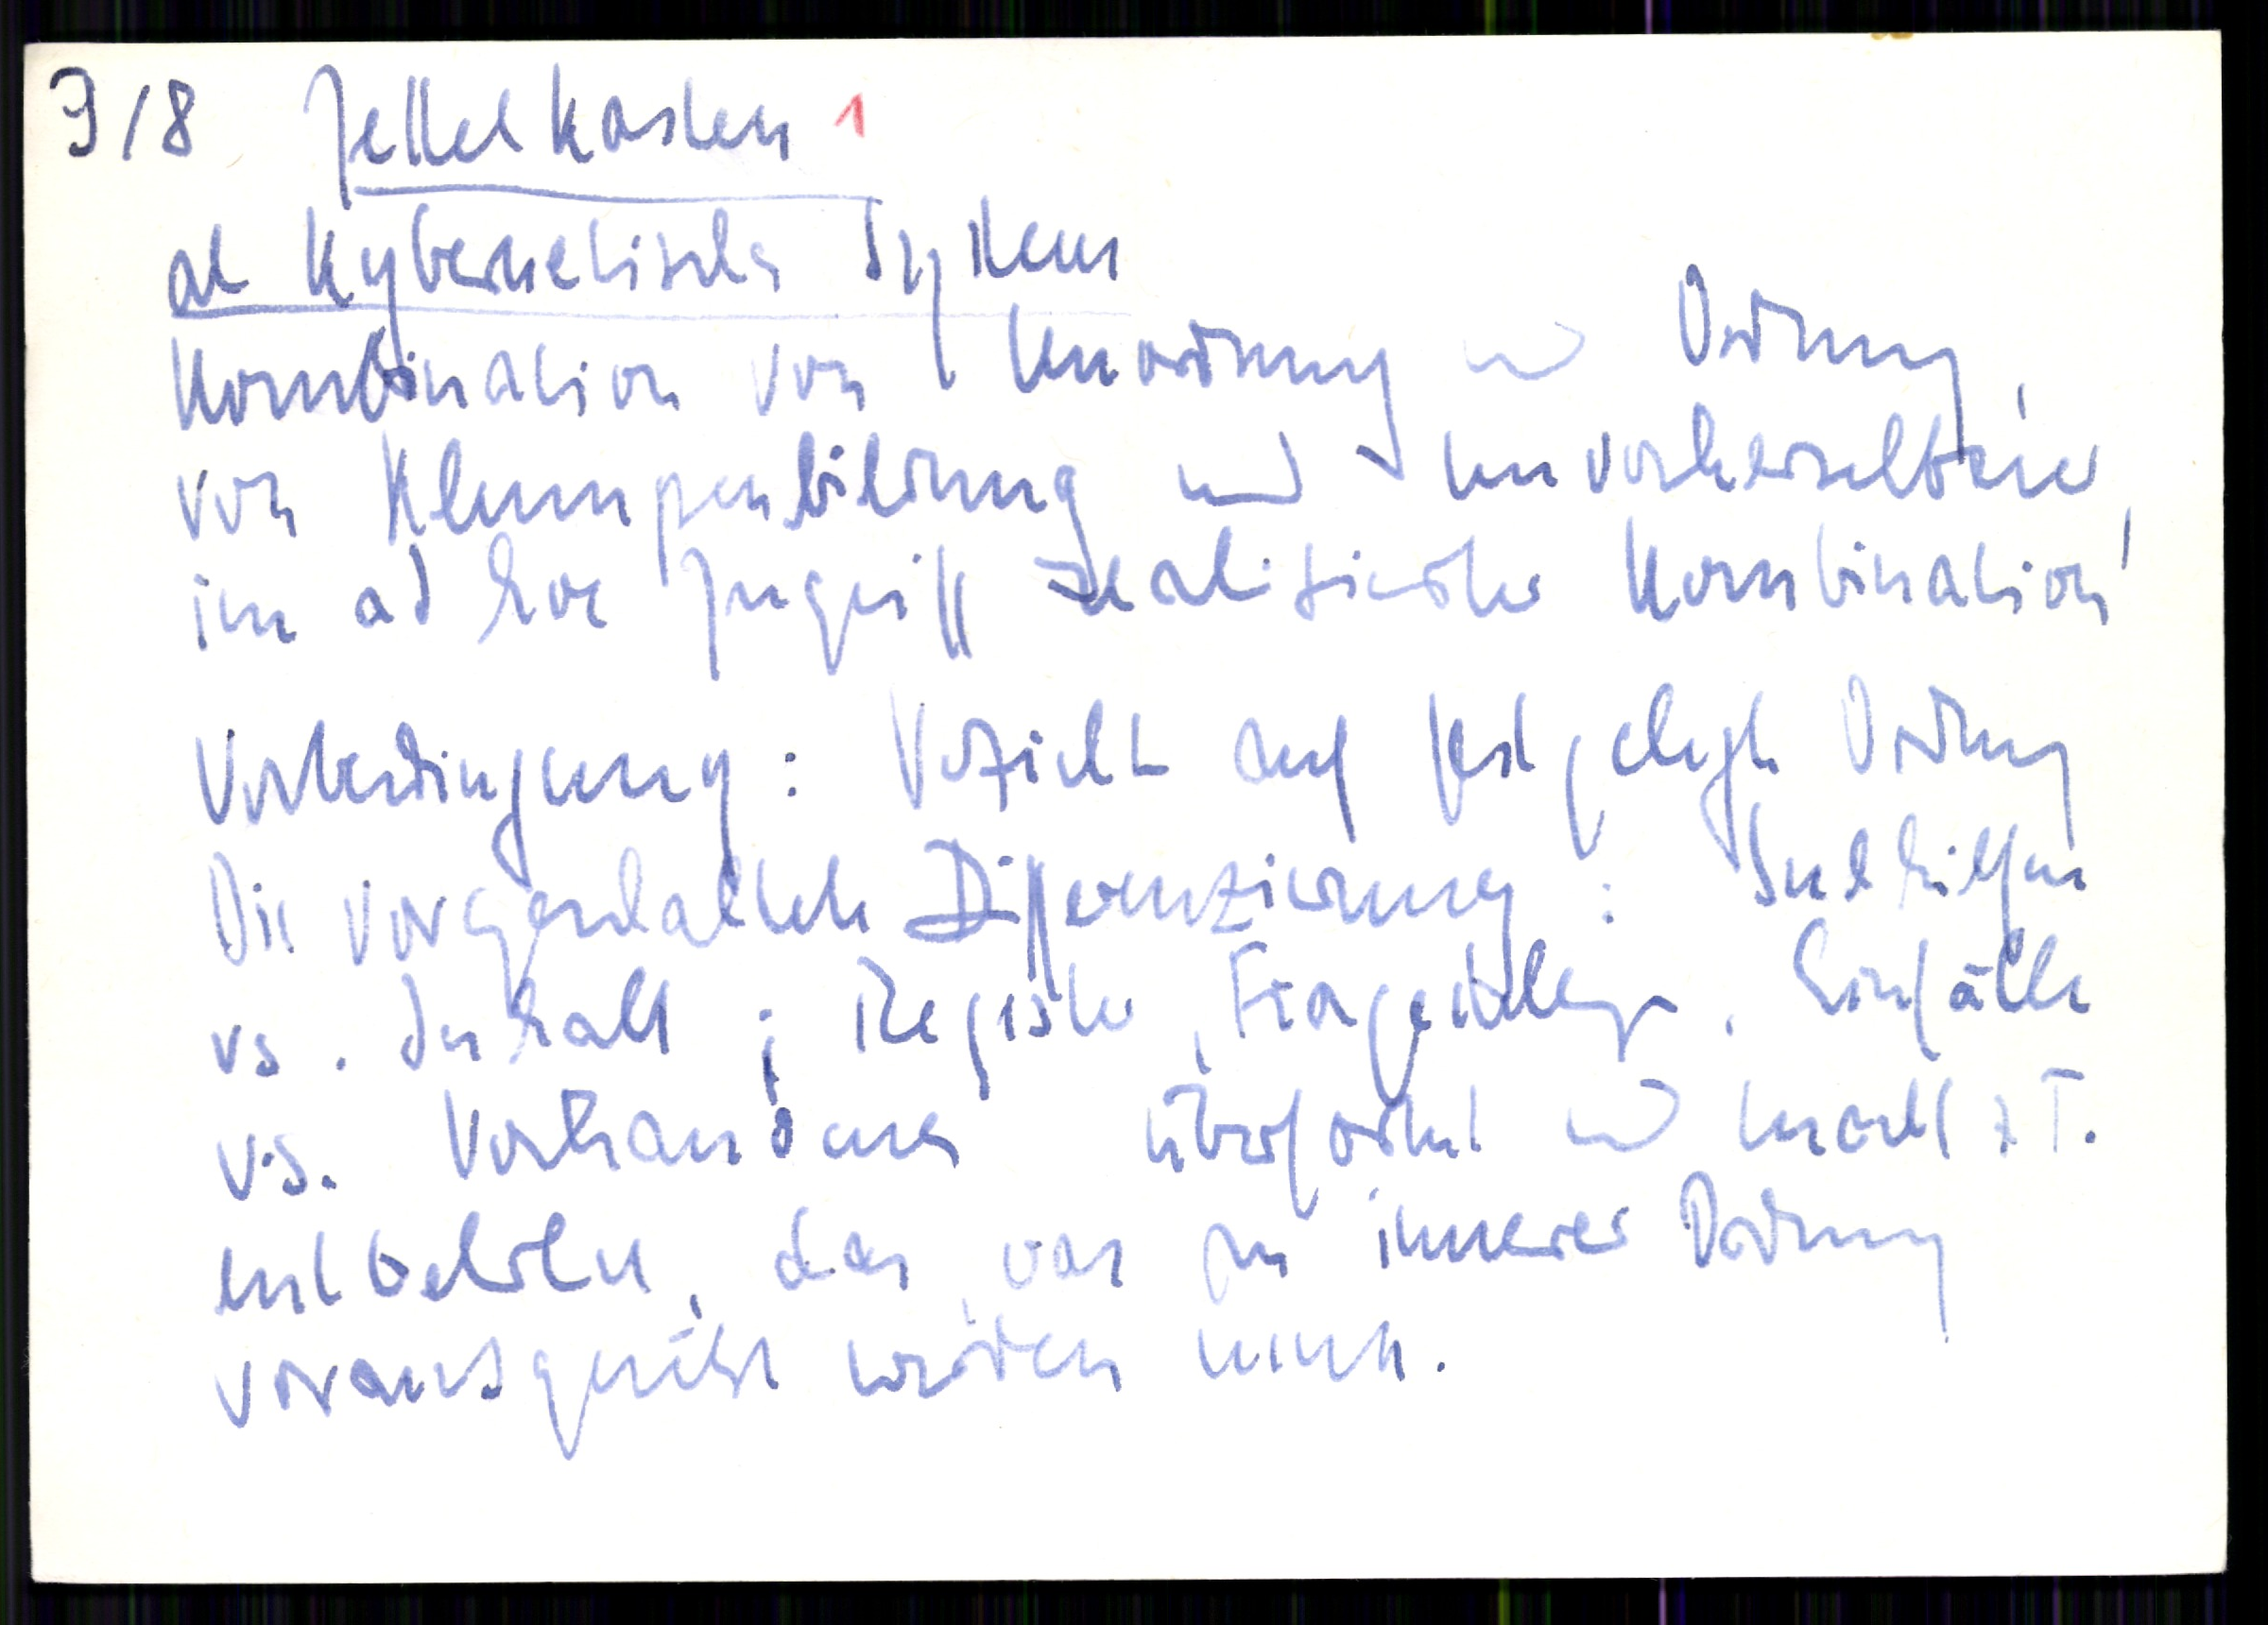
1952 to early 1997; roughly 45,000 cross-references between them.
What would making, linking, and following these require from the reader?
A wiki maintained by an LLM
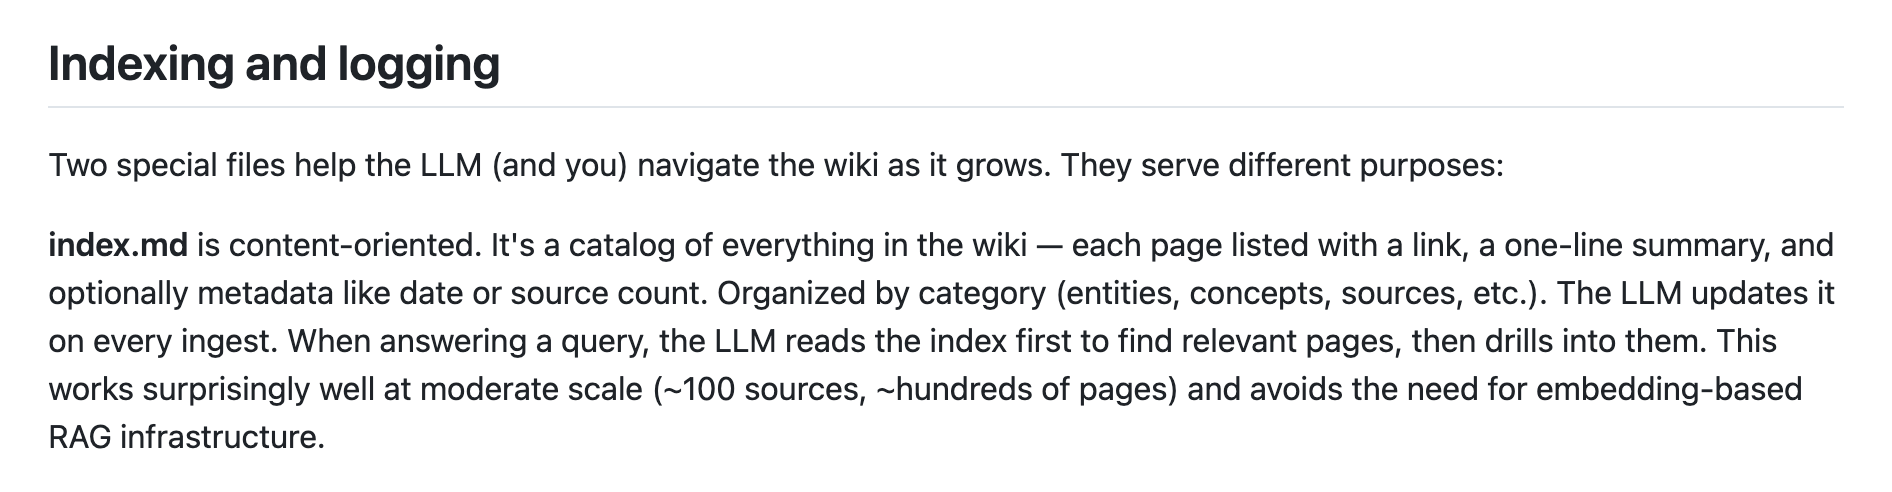
Incorporate sources into pages, flag contradictions, file answers back. Connections compile into pages that later questions can reuse. A workflow proposal; nothing about accuracy or learning is measured. When a tool uses saved notes as memory, check what it actually receives: in an audit of donated ChatGPT histories, 96% of memory entries were written by the system rather than asked for (WWW 2026).
A wiki maintained by an LLM
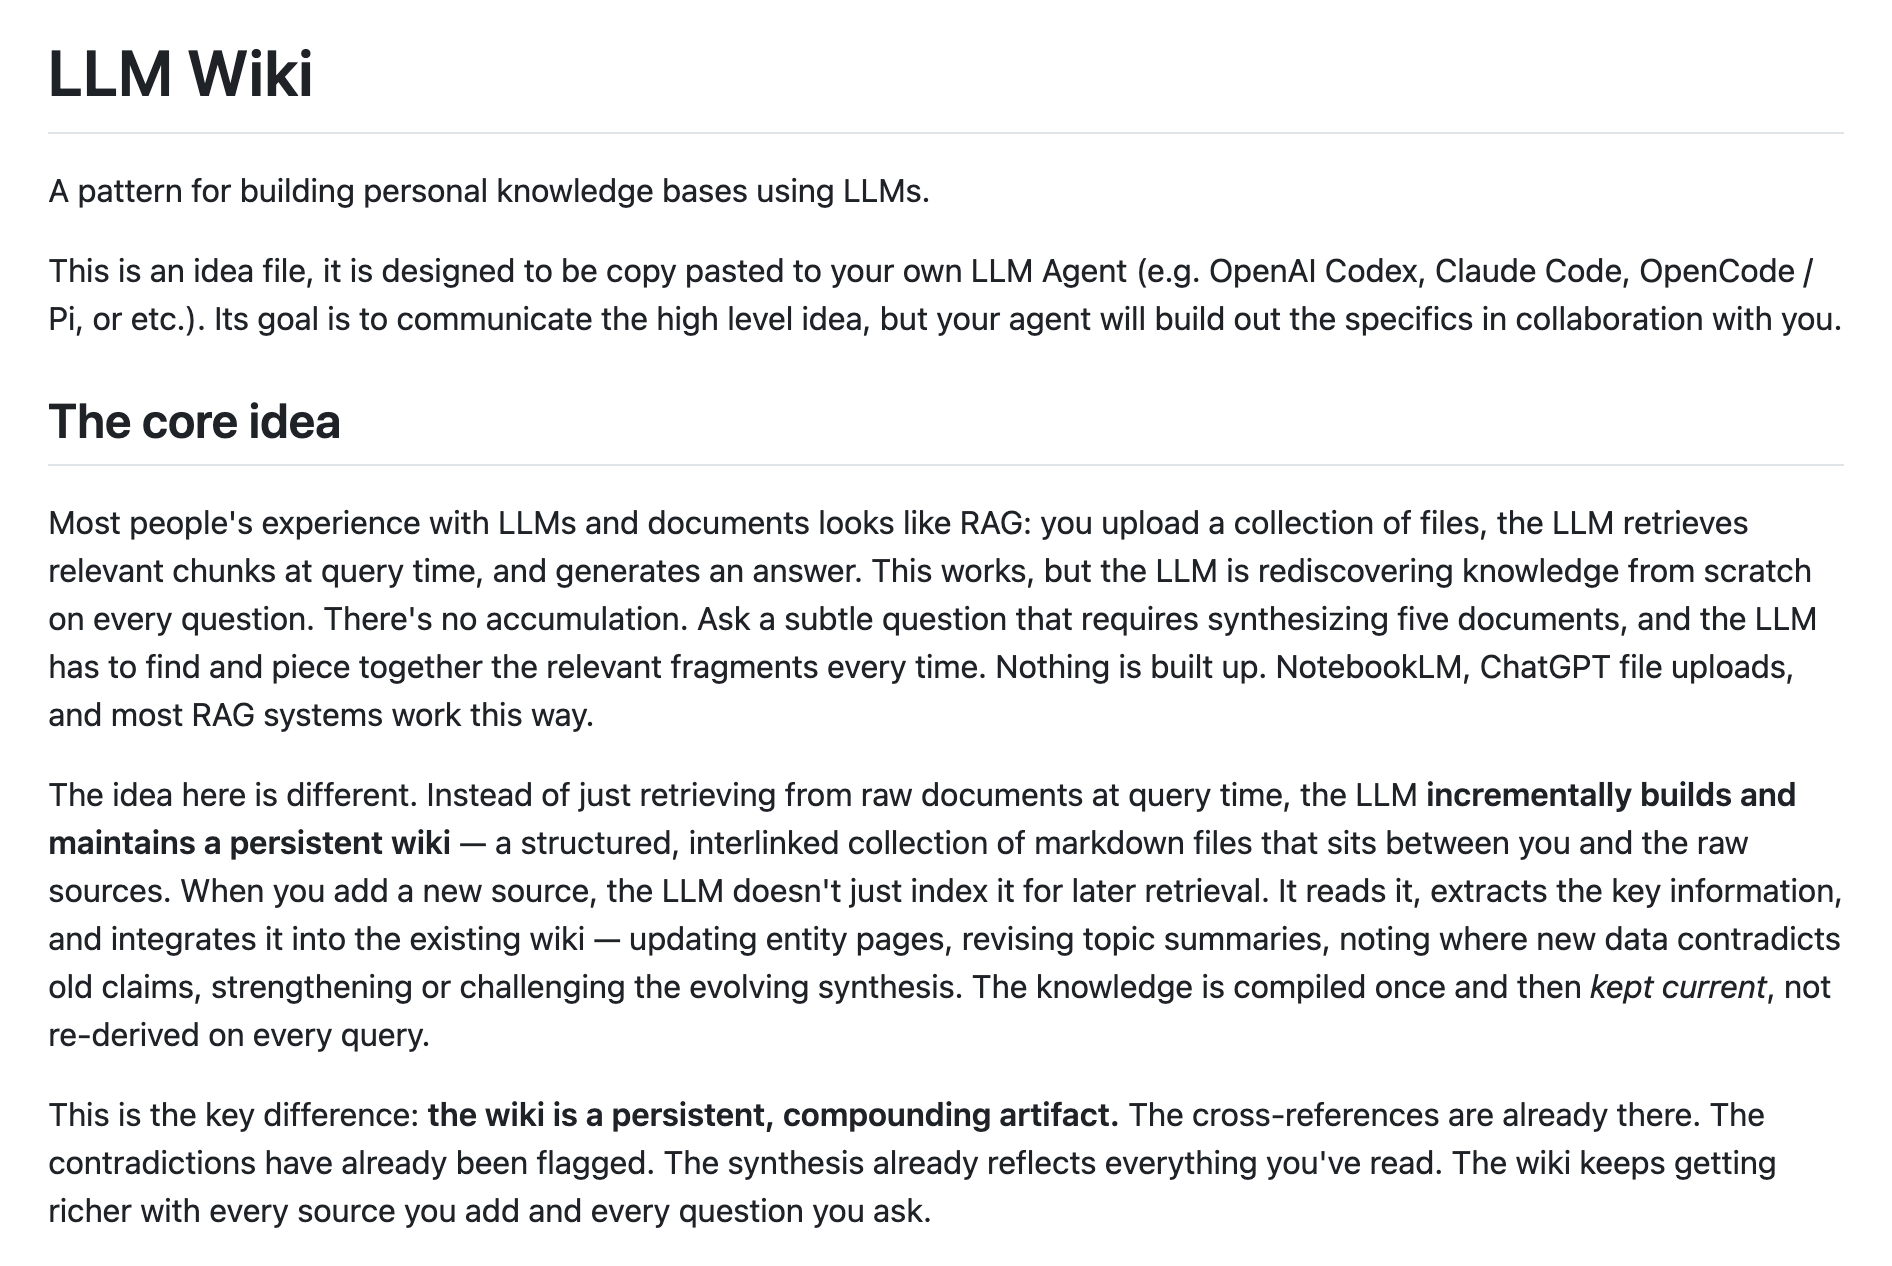
The gist says the LLM owns the wiki layer and the human curates sources. It also cites the memex, "the part he couldn't solve was who does the maintenance."
6.S950 - Agency with AI (Fall 26) - Lecture 2: Reading Matters
By Shen Shen
6.S950 - Agency with AI (Fall 26) - Lecture 2: Reading Matters
Agency with AI, Lecture 2: Reading Matters