Lecture 8: Representation Learning
Intro to Machine Learning

\dots
layer
layer
\dots
x_1
x_2
x_d
features
\Sigma
f(\cdot)
\Sigma
f(\cdot)
\Sigma
f(\cdot)
\Sigma
f(\cdot)
\Sigma
f(\cdot)
\Sigma
f(\cdot)
learnable weights
hidden
output
Recall:
\mathcal{L}(g, y)
g
y
label
\dots
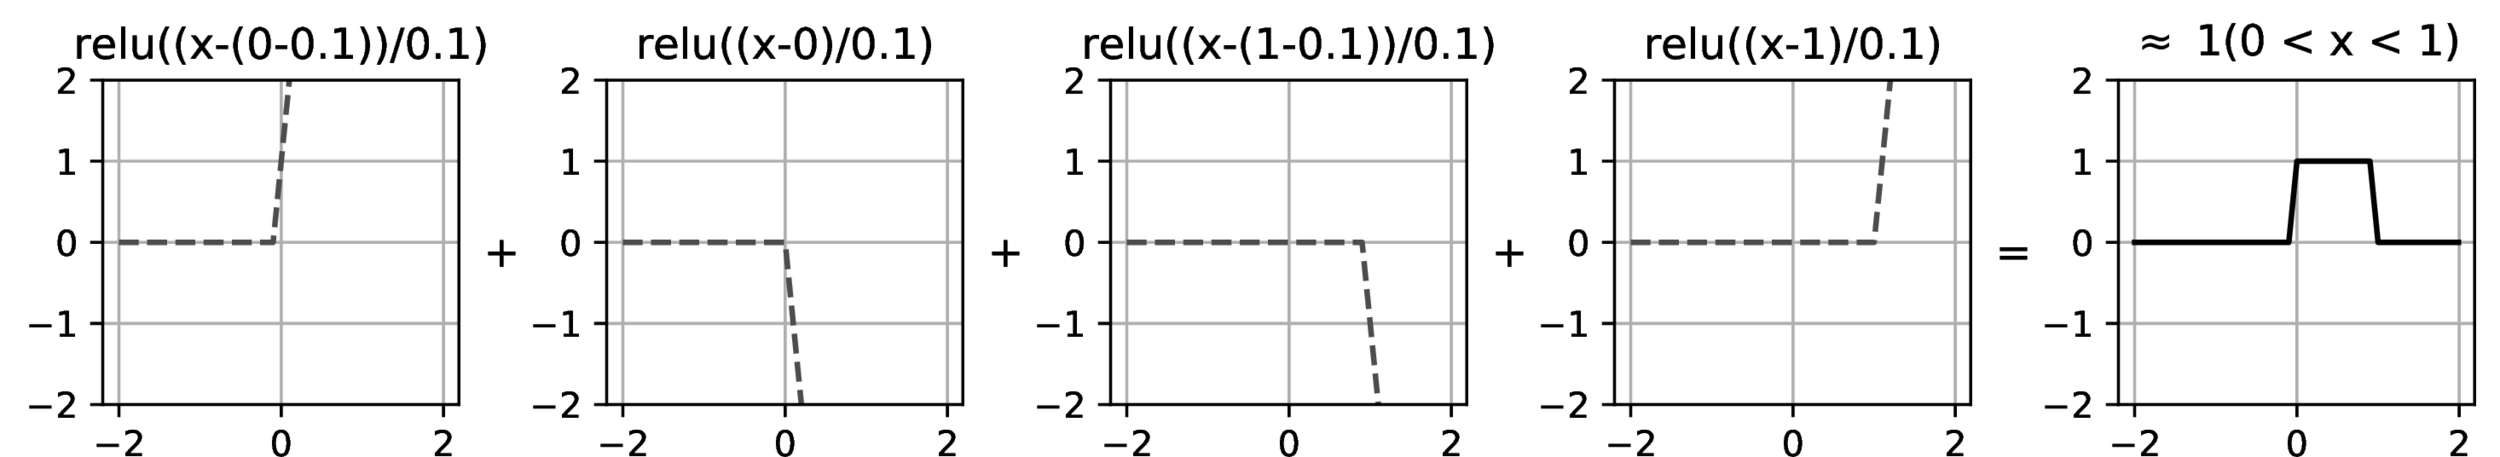
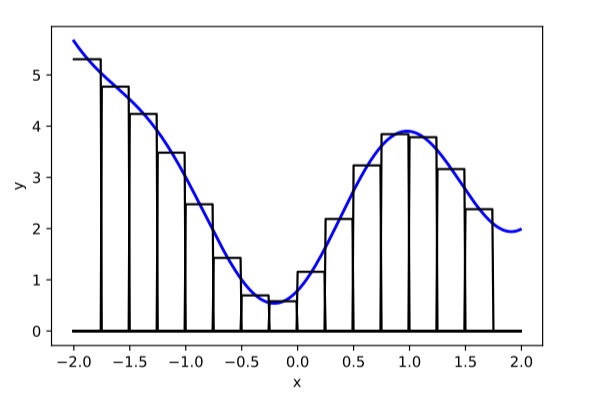
asymptotically, can approximate any smooth function arbitrarily well!
\dots
\dots
\dots
x
Recall:
Outline
- Neural networks are representation learners
- Auto-encoders and self-supervised learning
- Word embeddings
- Multi-modality
- Neural networks are representation learners
- Auto-encoders and self-supervised learning
- Word embeddings
- Multi-modality
[some images in parts 1–2; credit: visionbook.mit.edu]
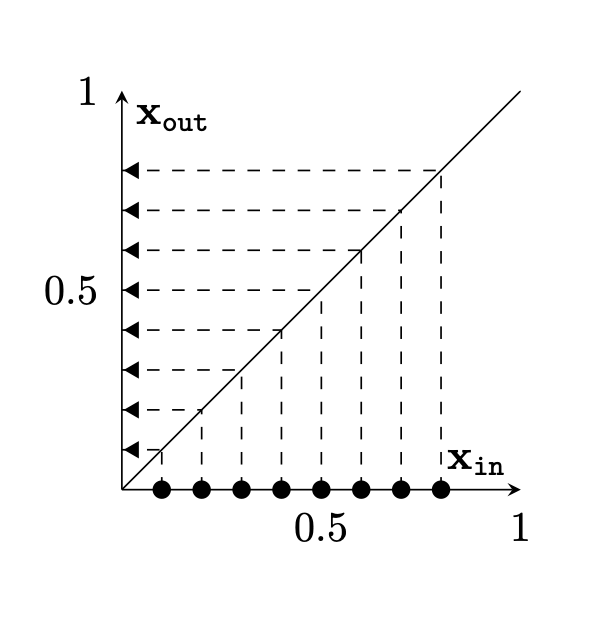
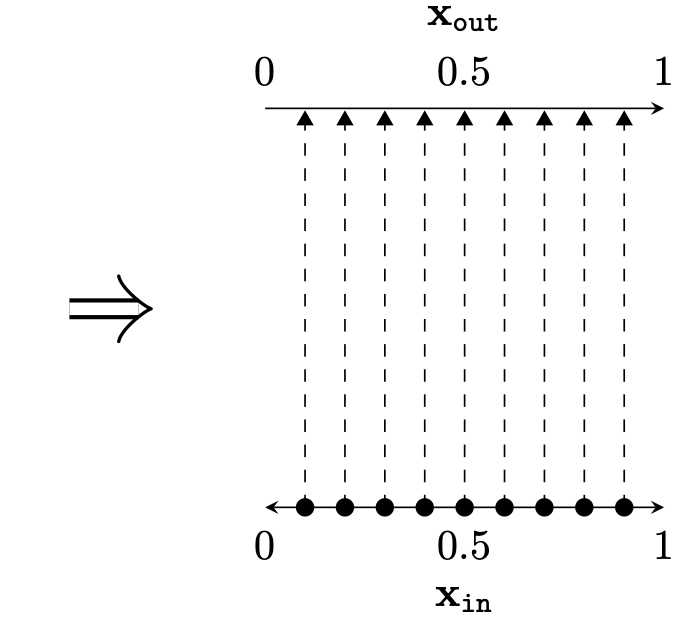
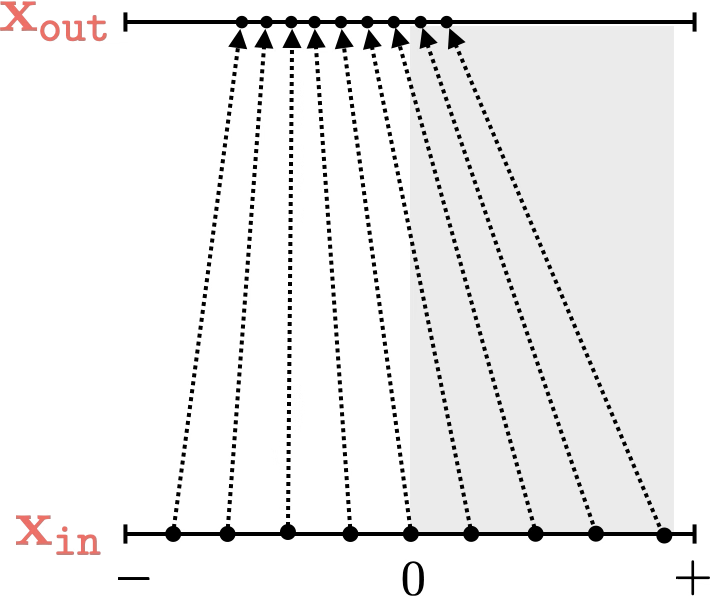
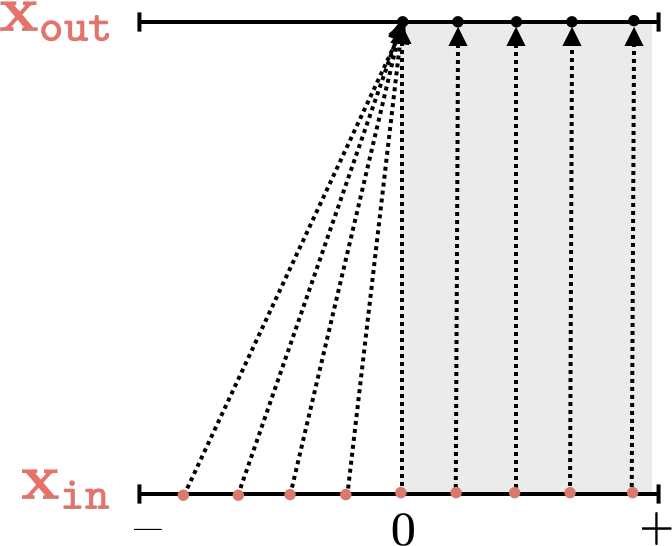
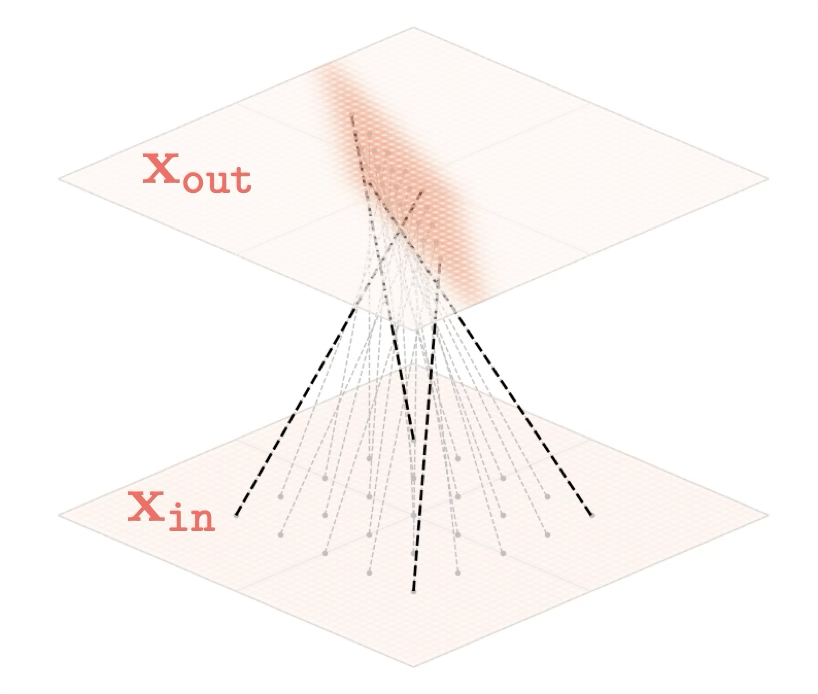
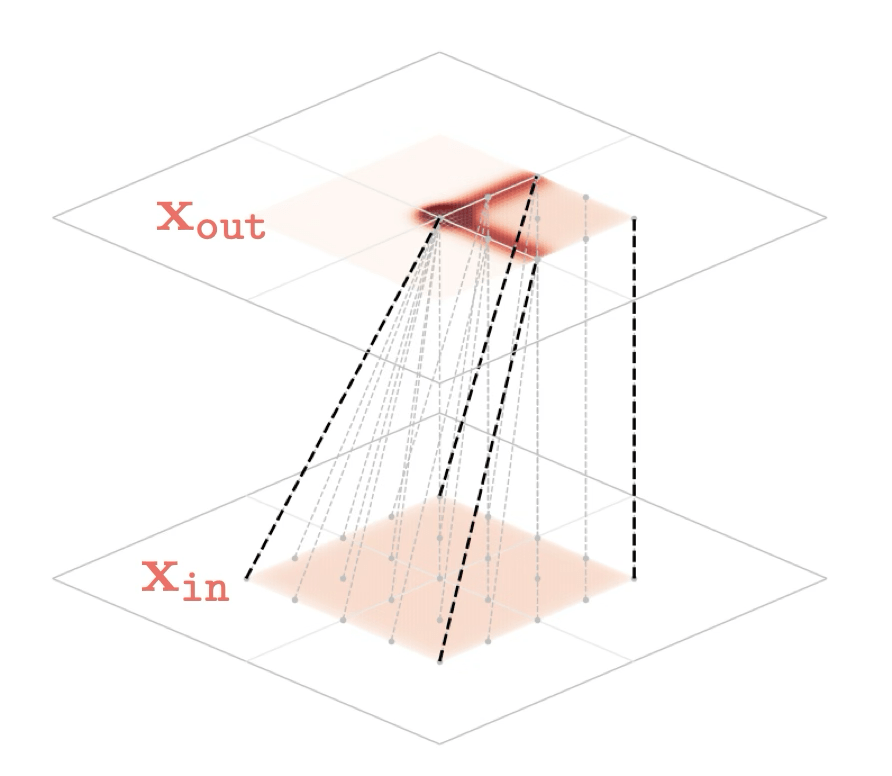
Two different ways to visualize a function
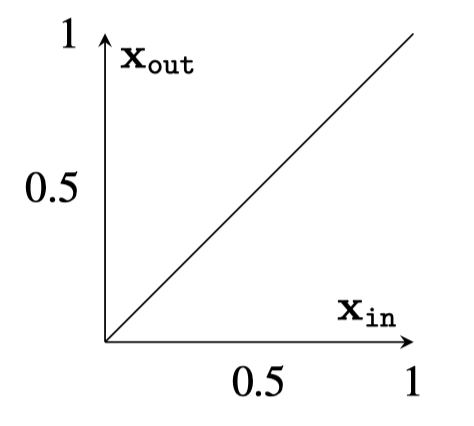
e.g. the identity function
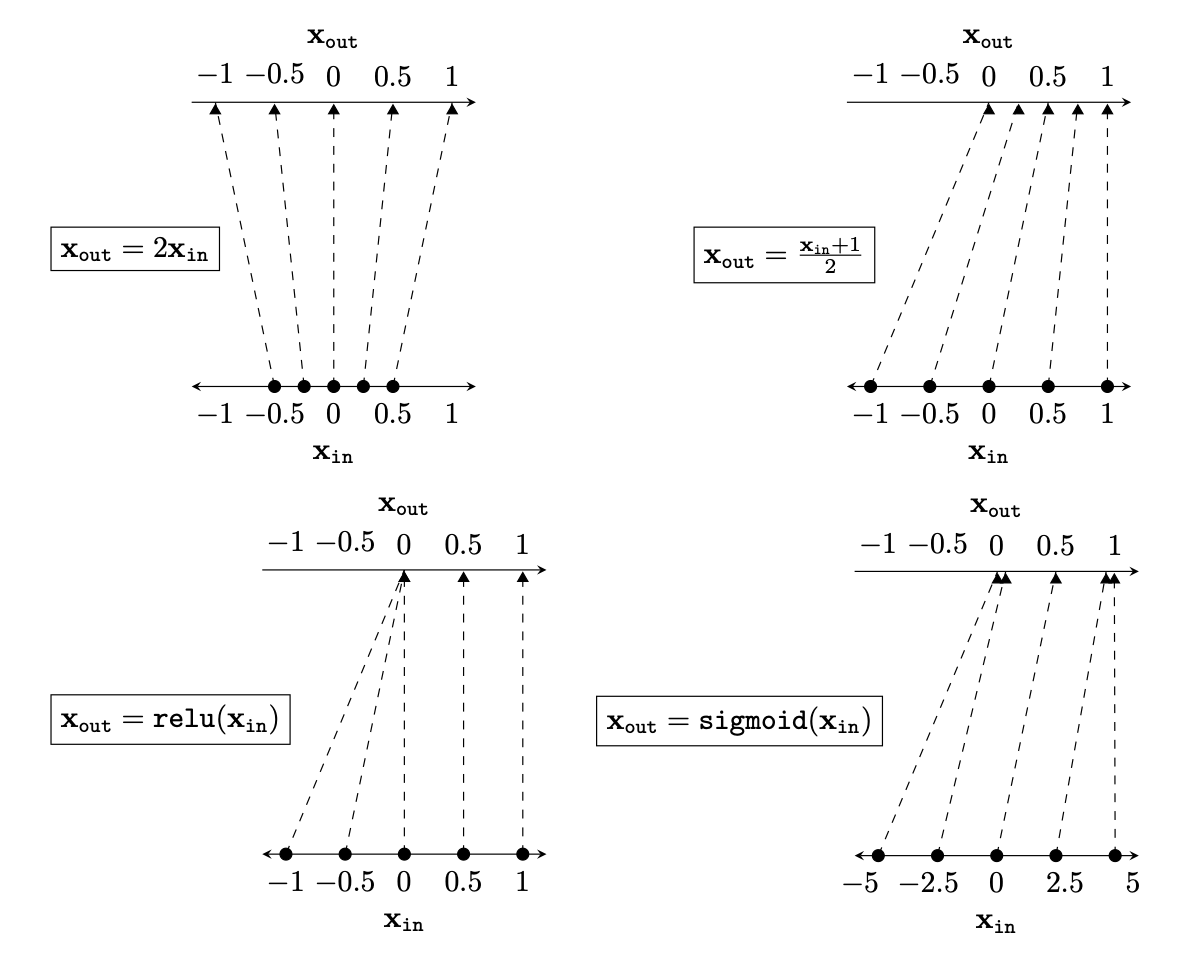
Representation transformations for a variety of neural net operations
and a stack of neural net operations
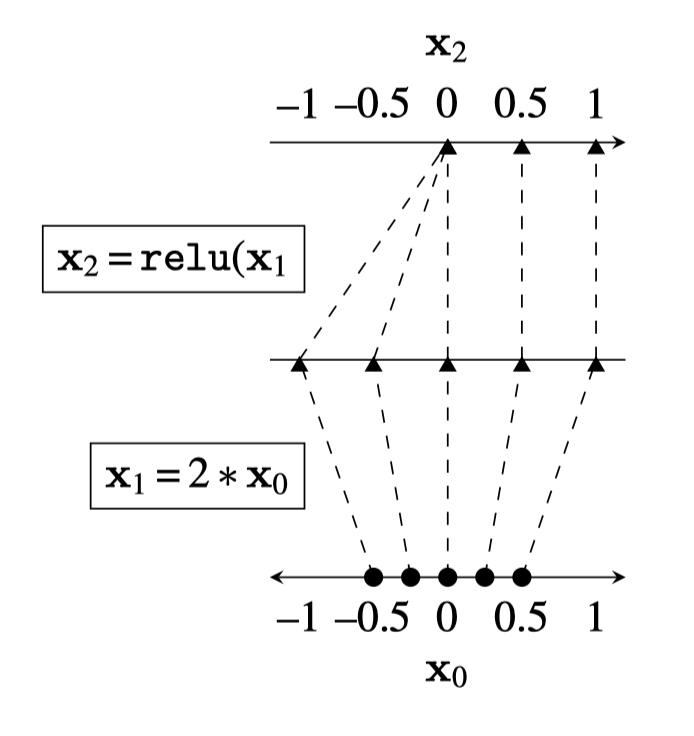
)
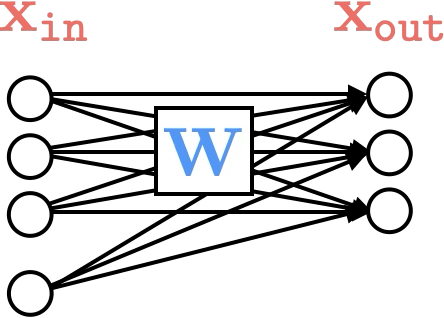
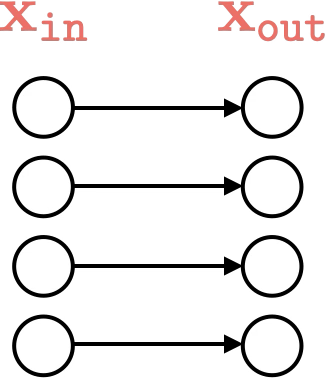
wiring graph
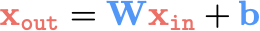
equation
mapping 1D
mapping 2D
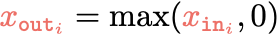
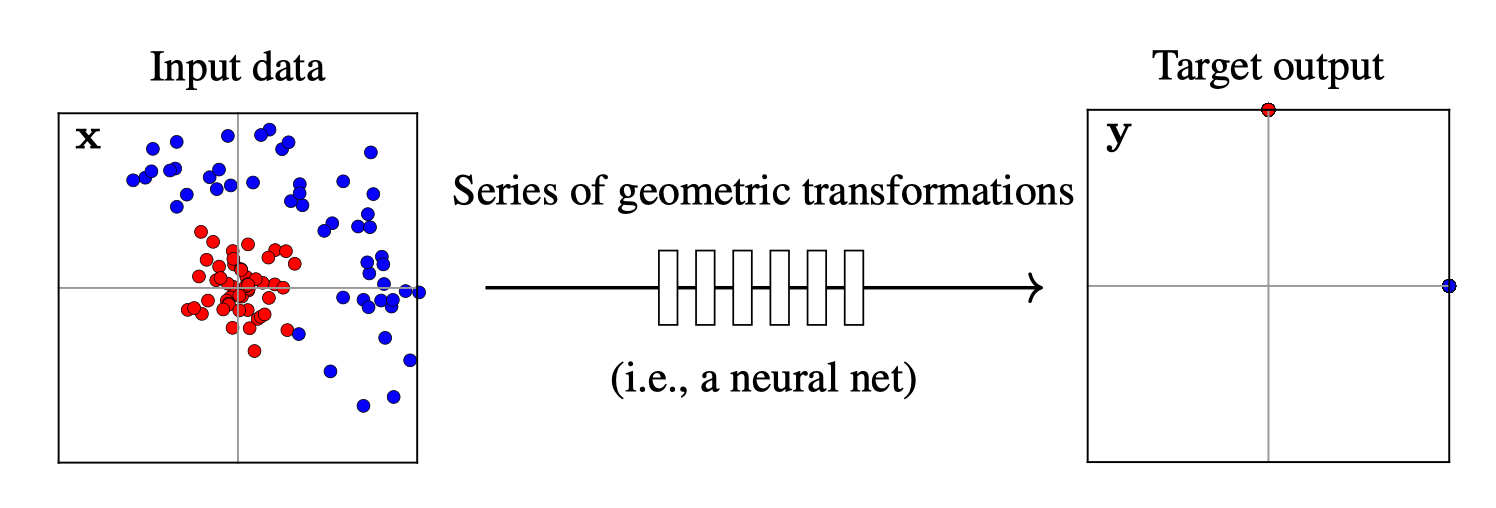
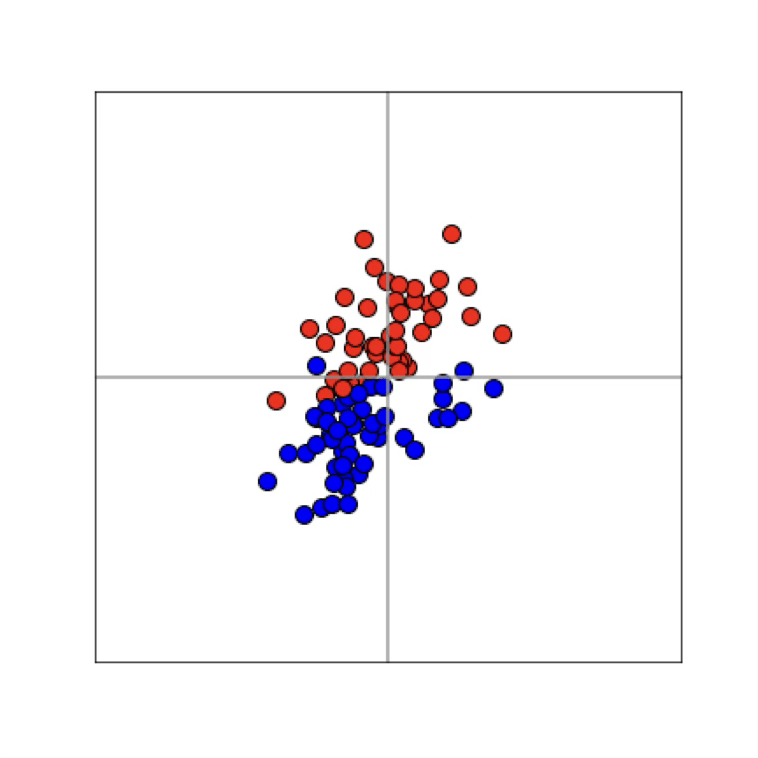
What does training a neural net classifier look like?
Training data
x
z_1
a_1
z_2
g
{z}_1=\text { linear }(x) \in \mathbb{R^2}
{a}_1=\text { ReLU}(z_1)
g=\text {softmax}(z_2)
{z}_2=\text { linear }(a_1) \in \mathbb{R^2}
x\in \mathbb{R^2}
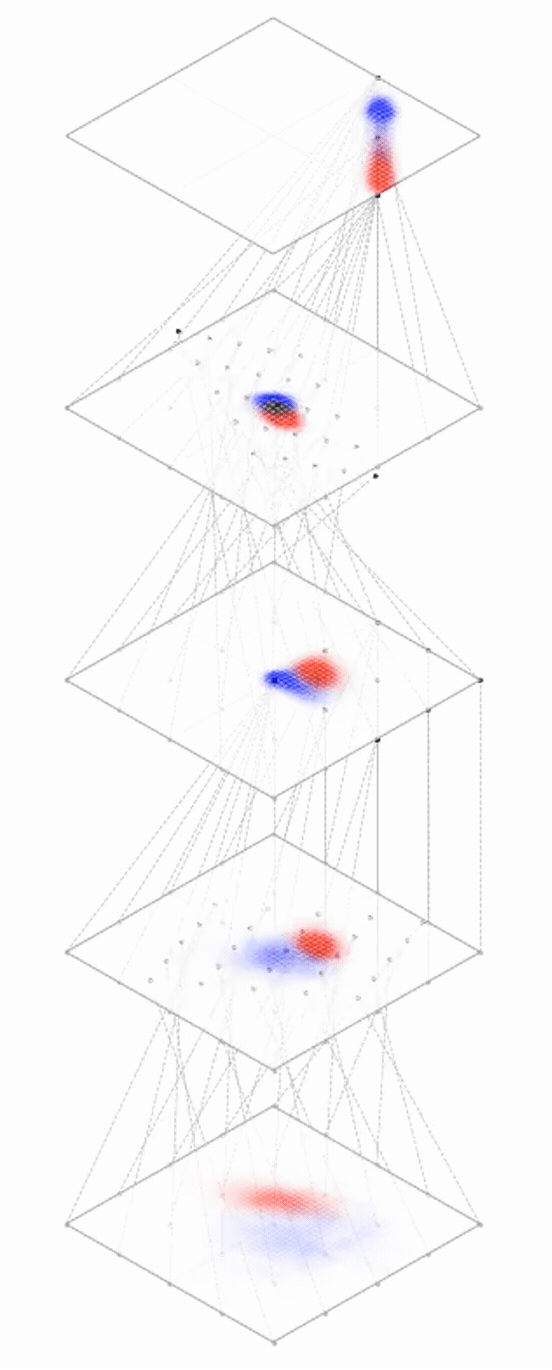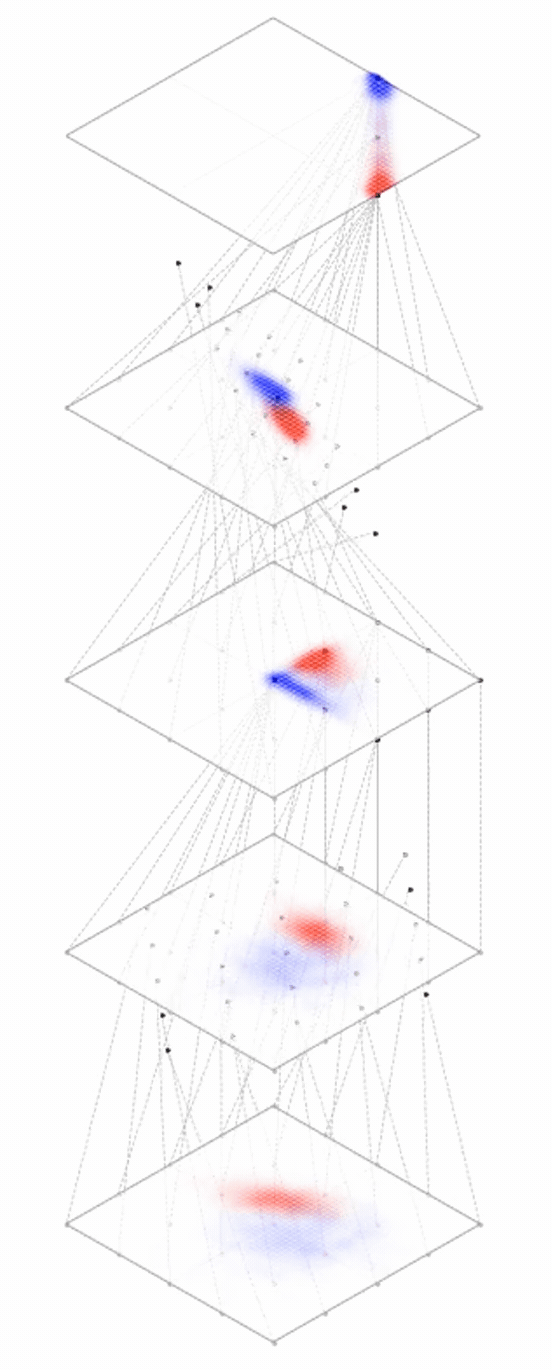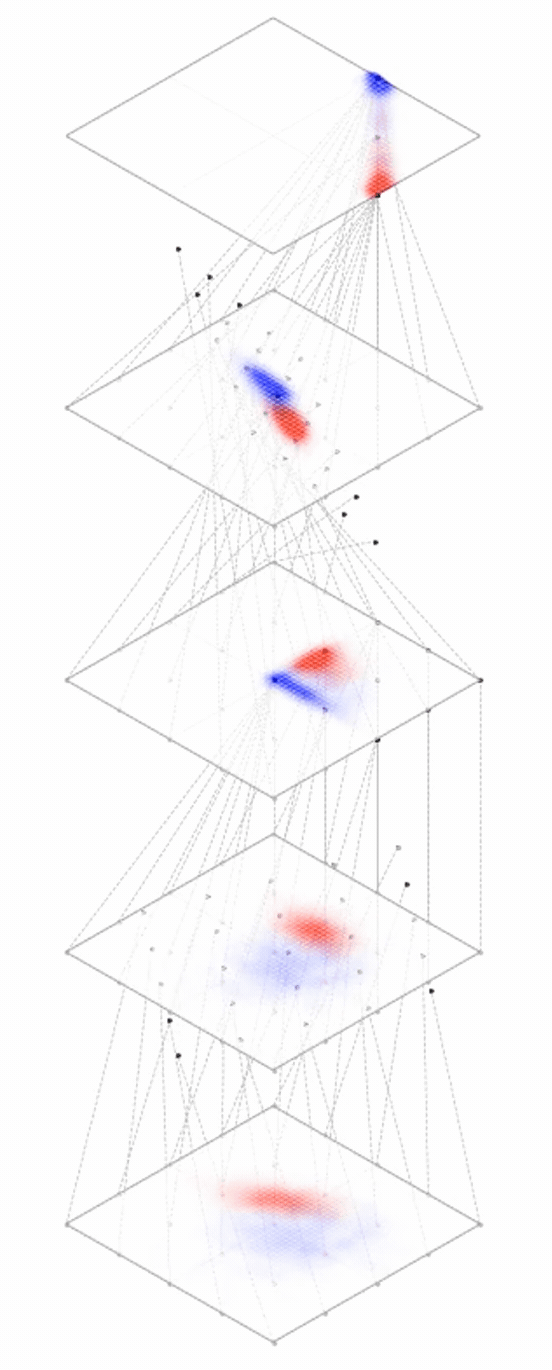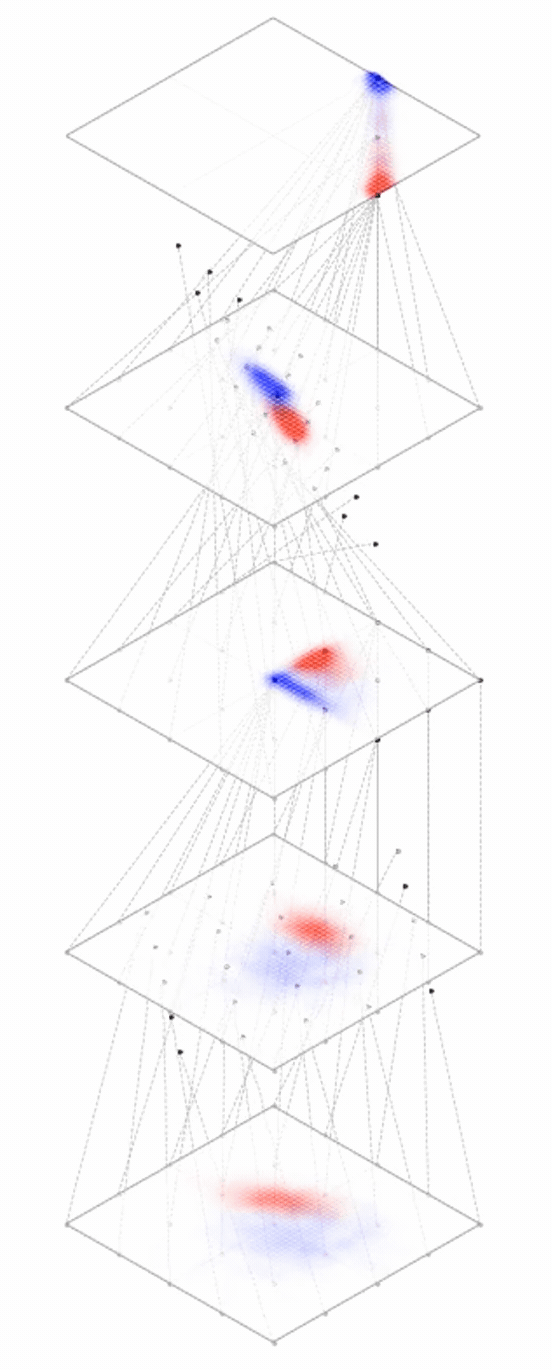
maps from complex data space to desired target space
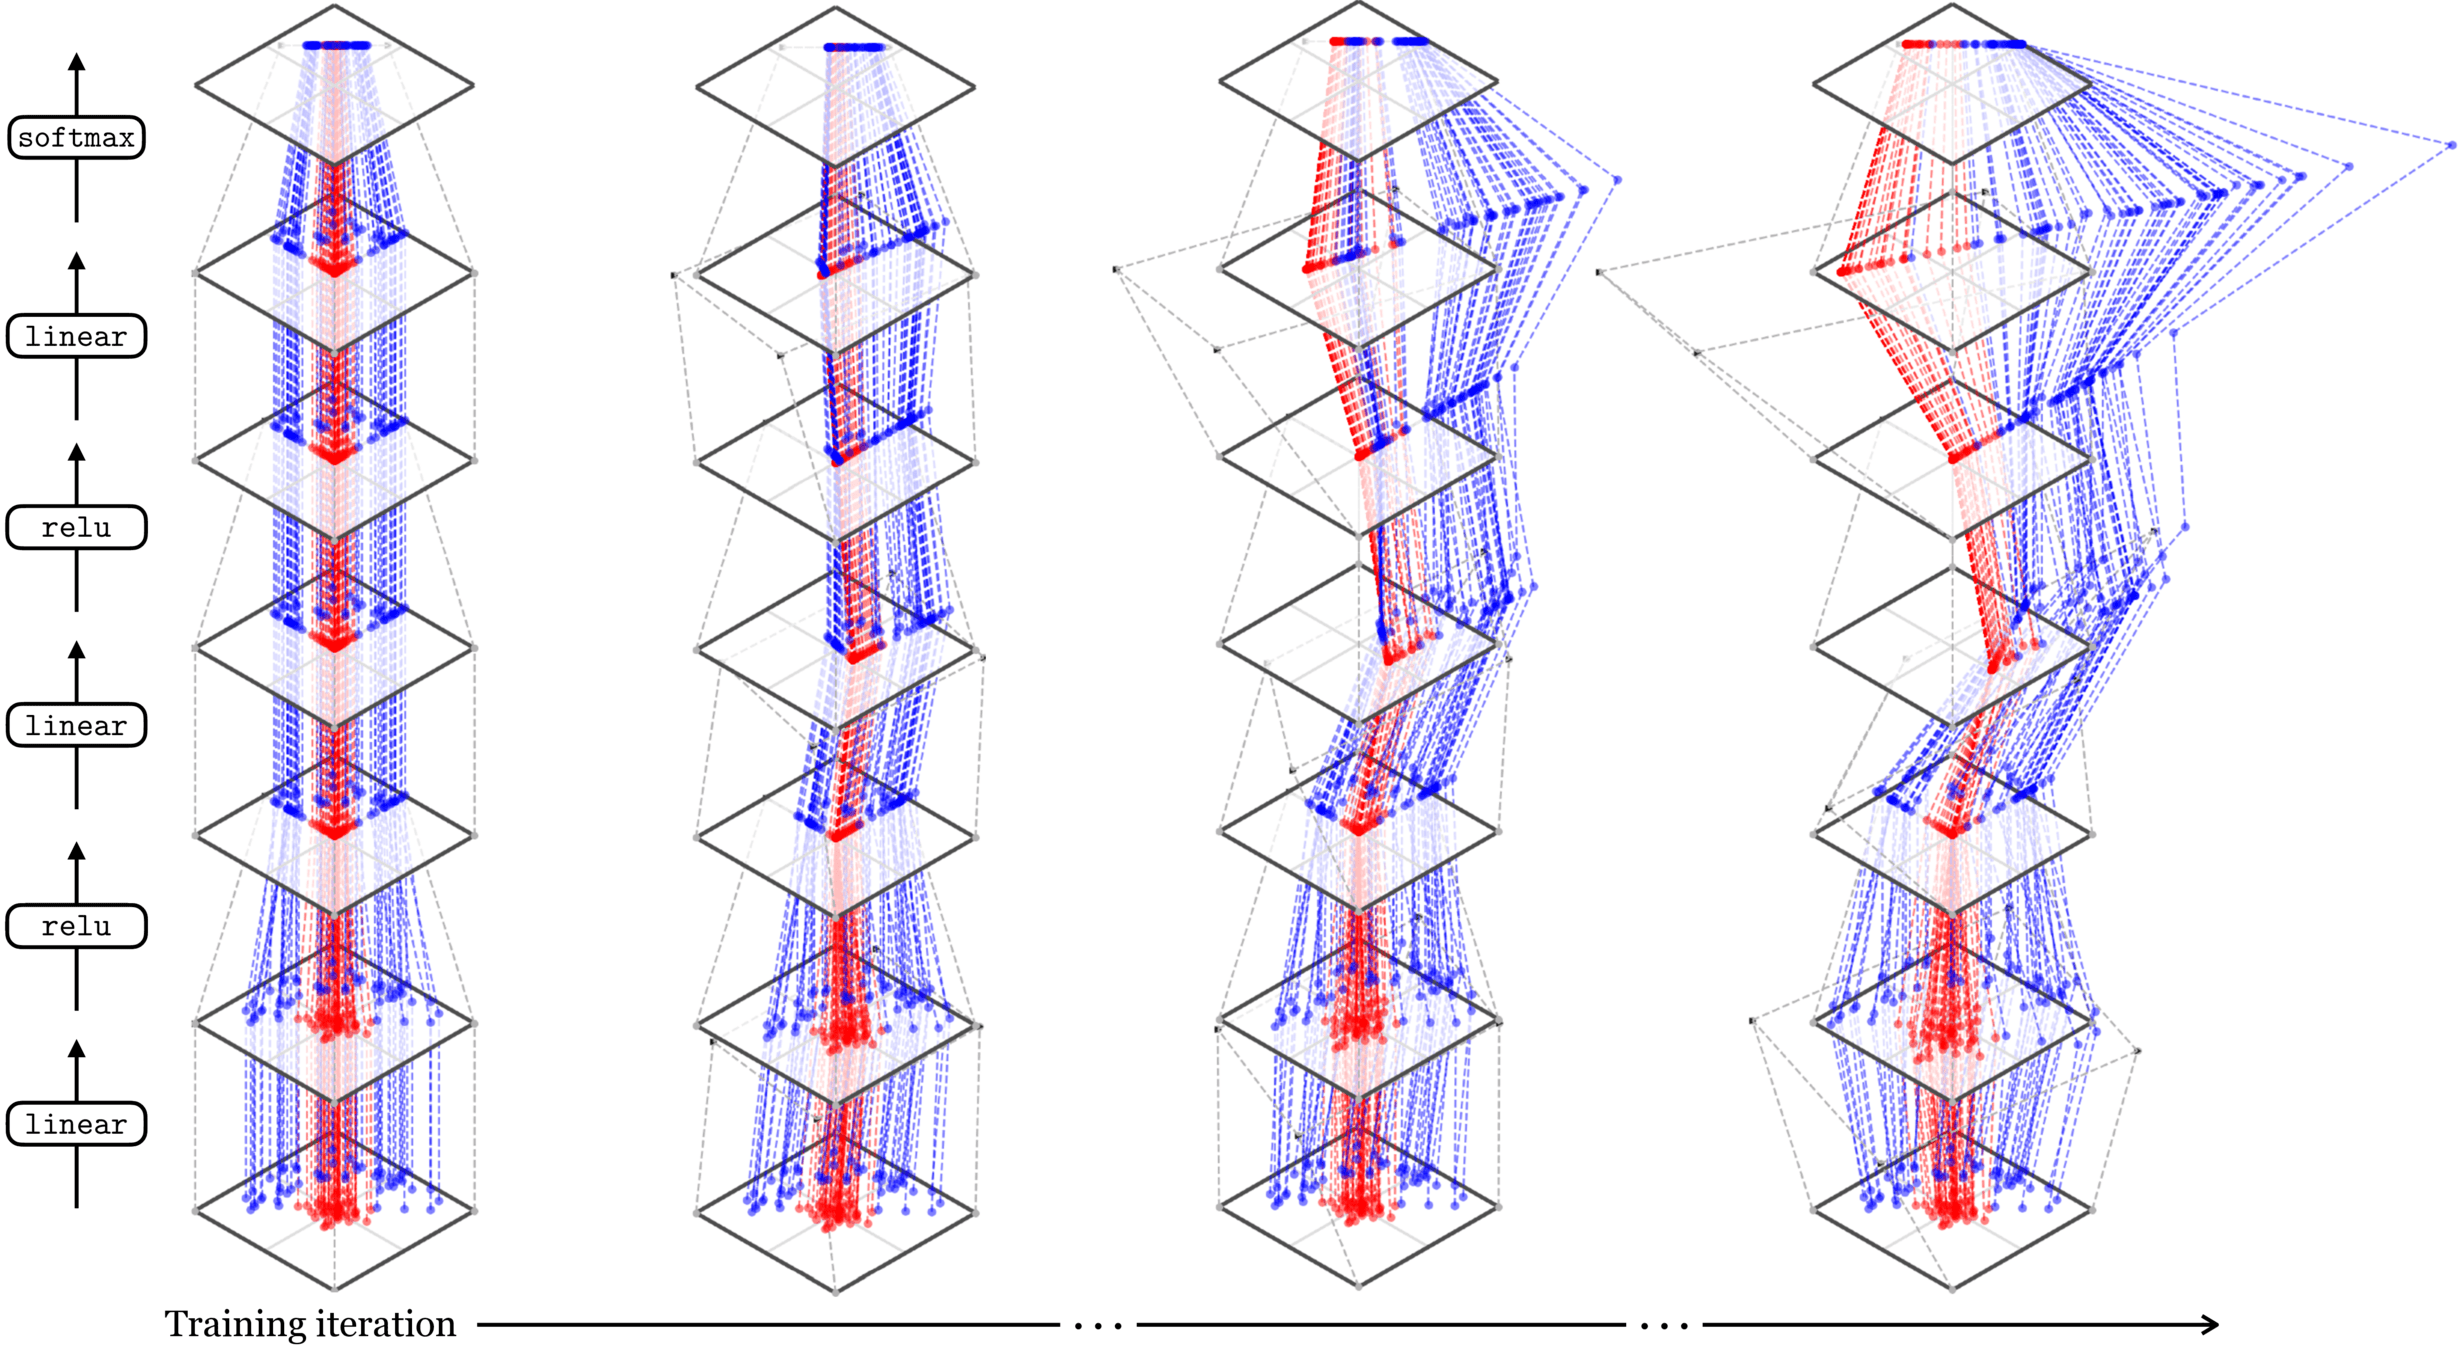
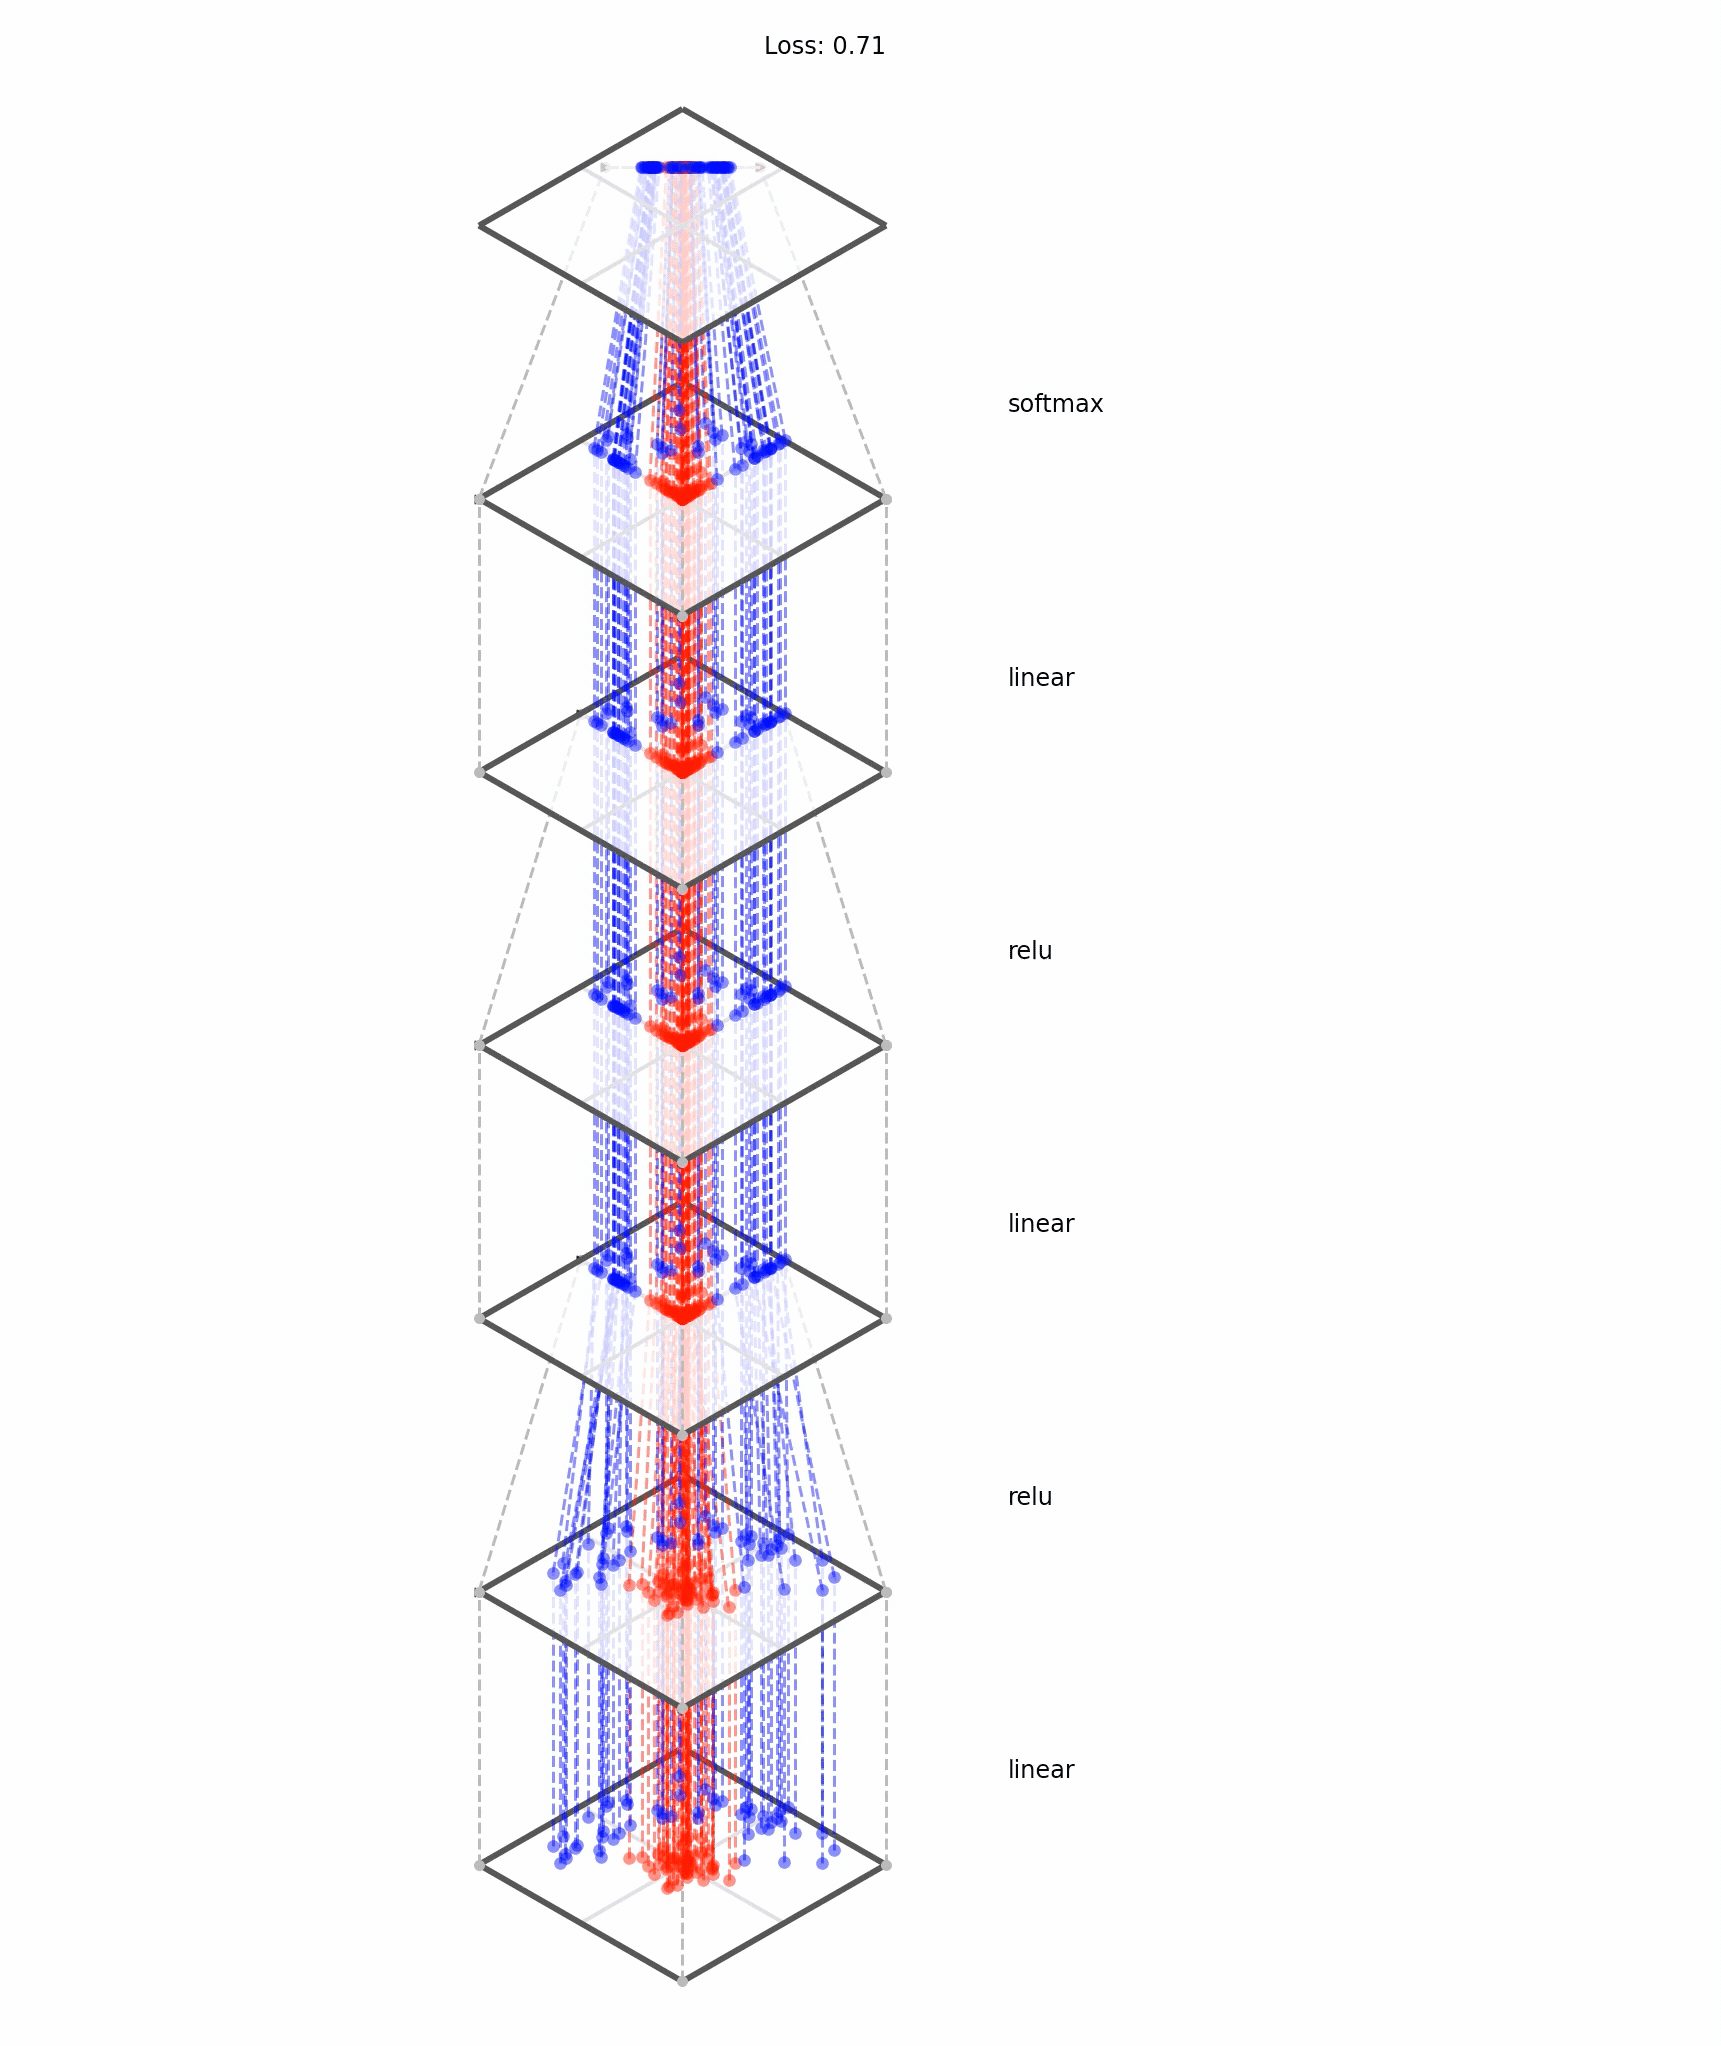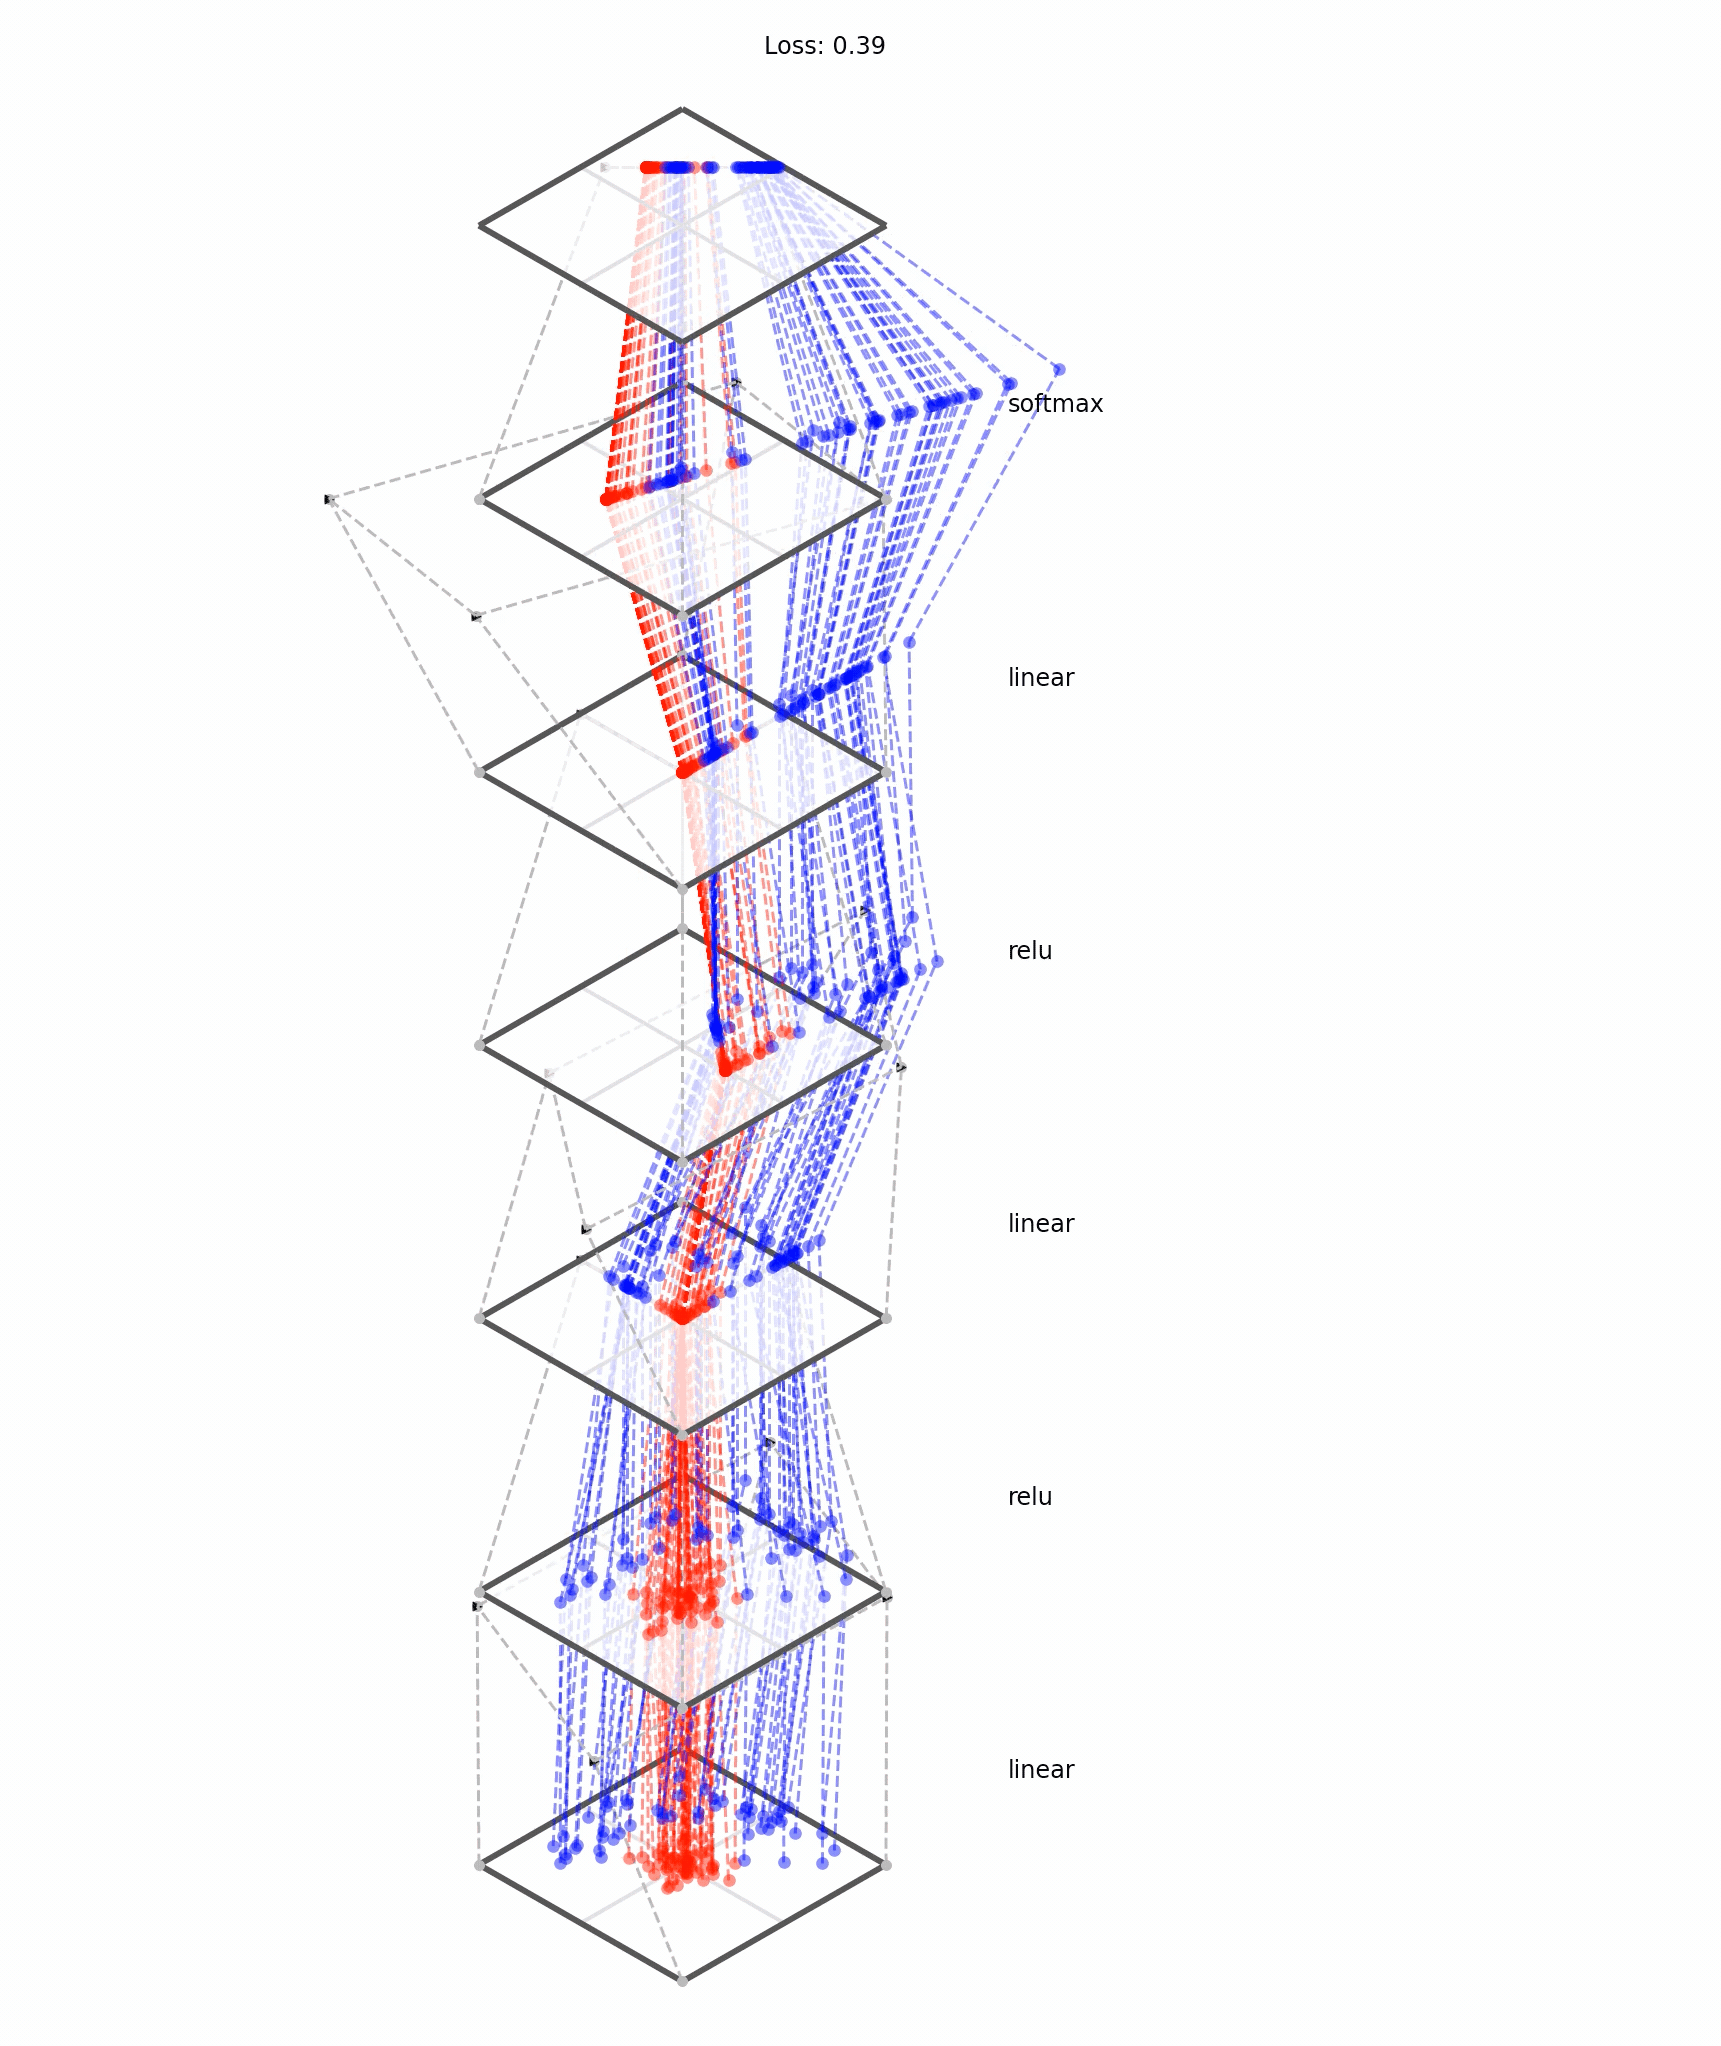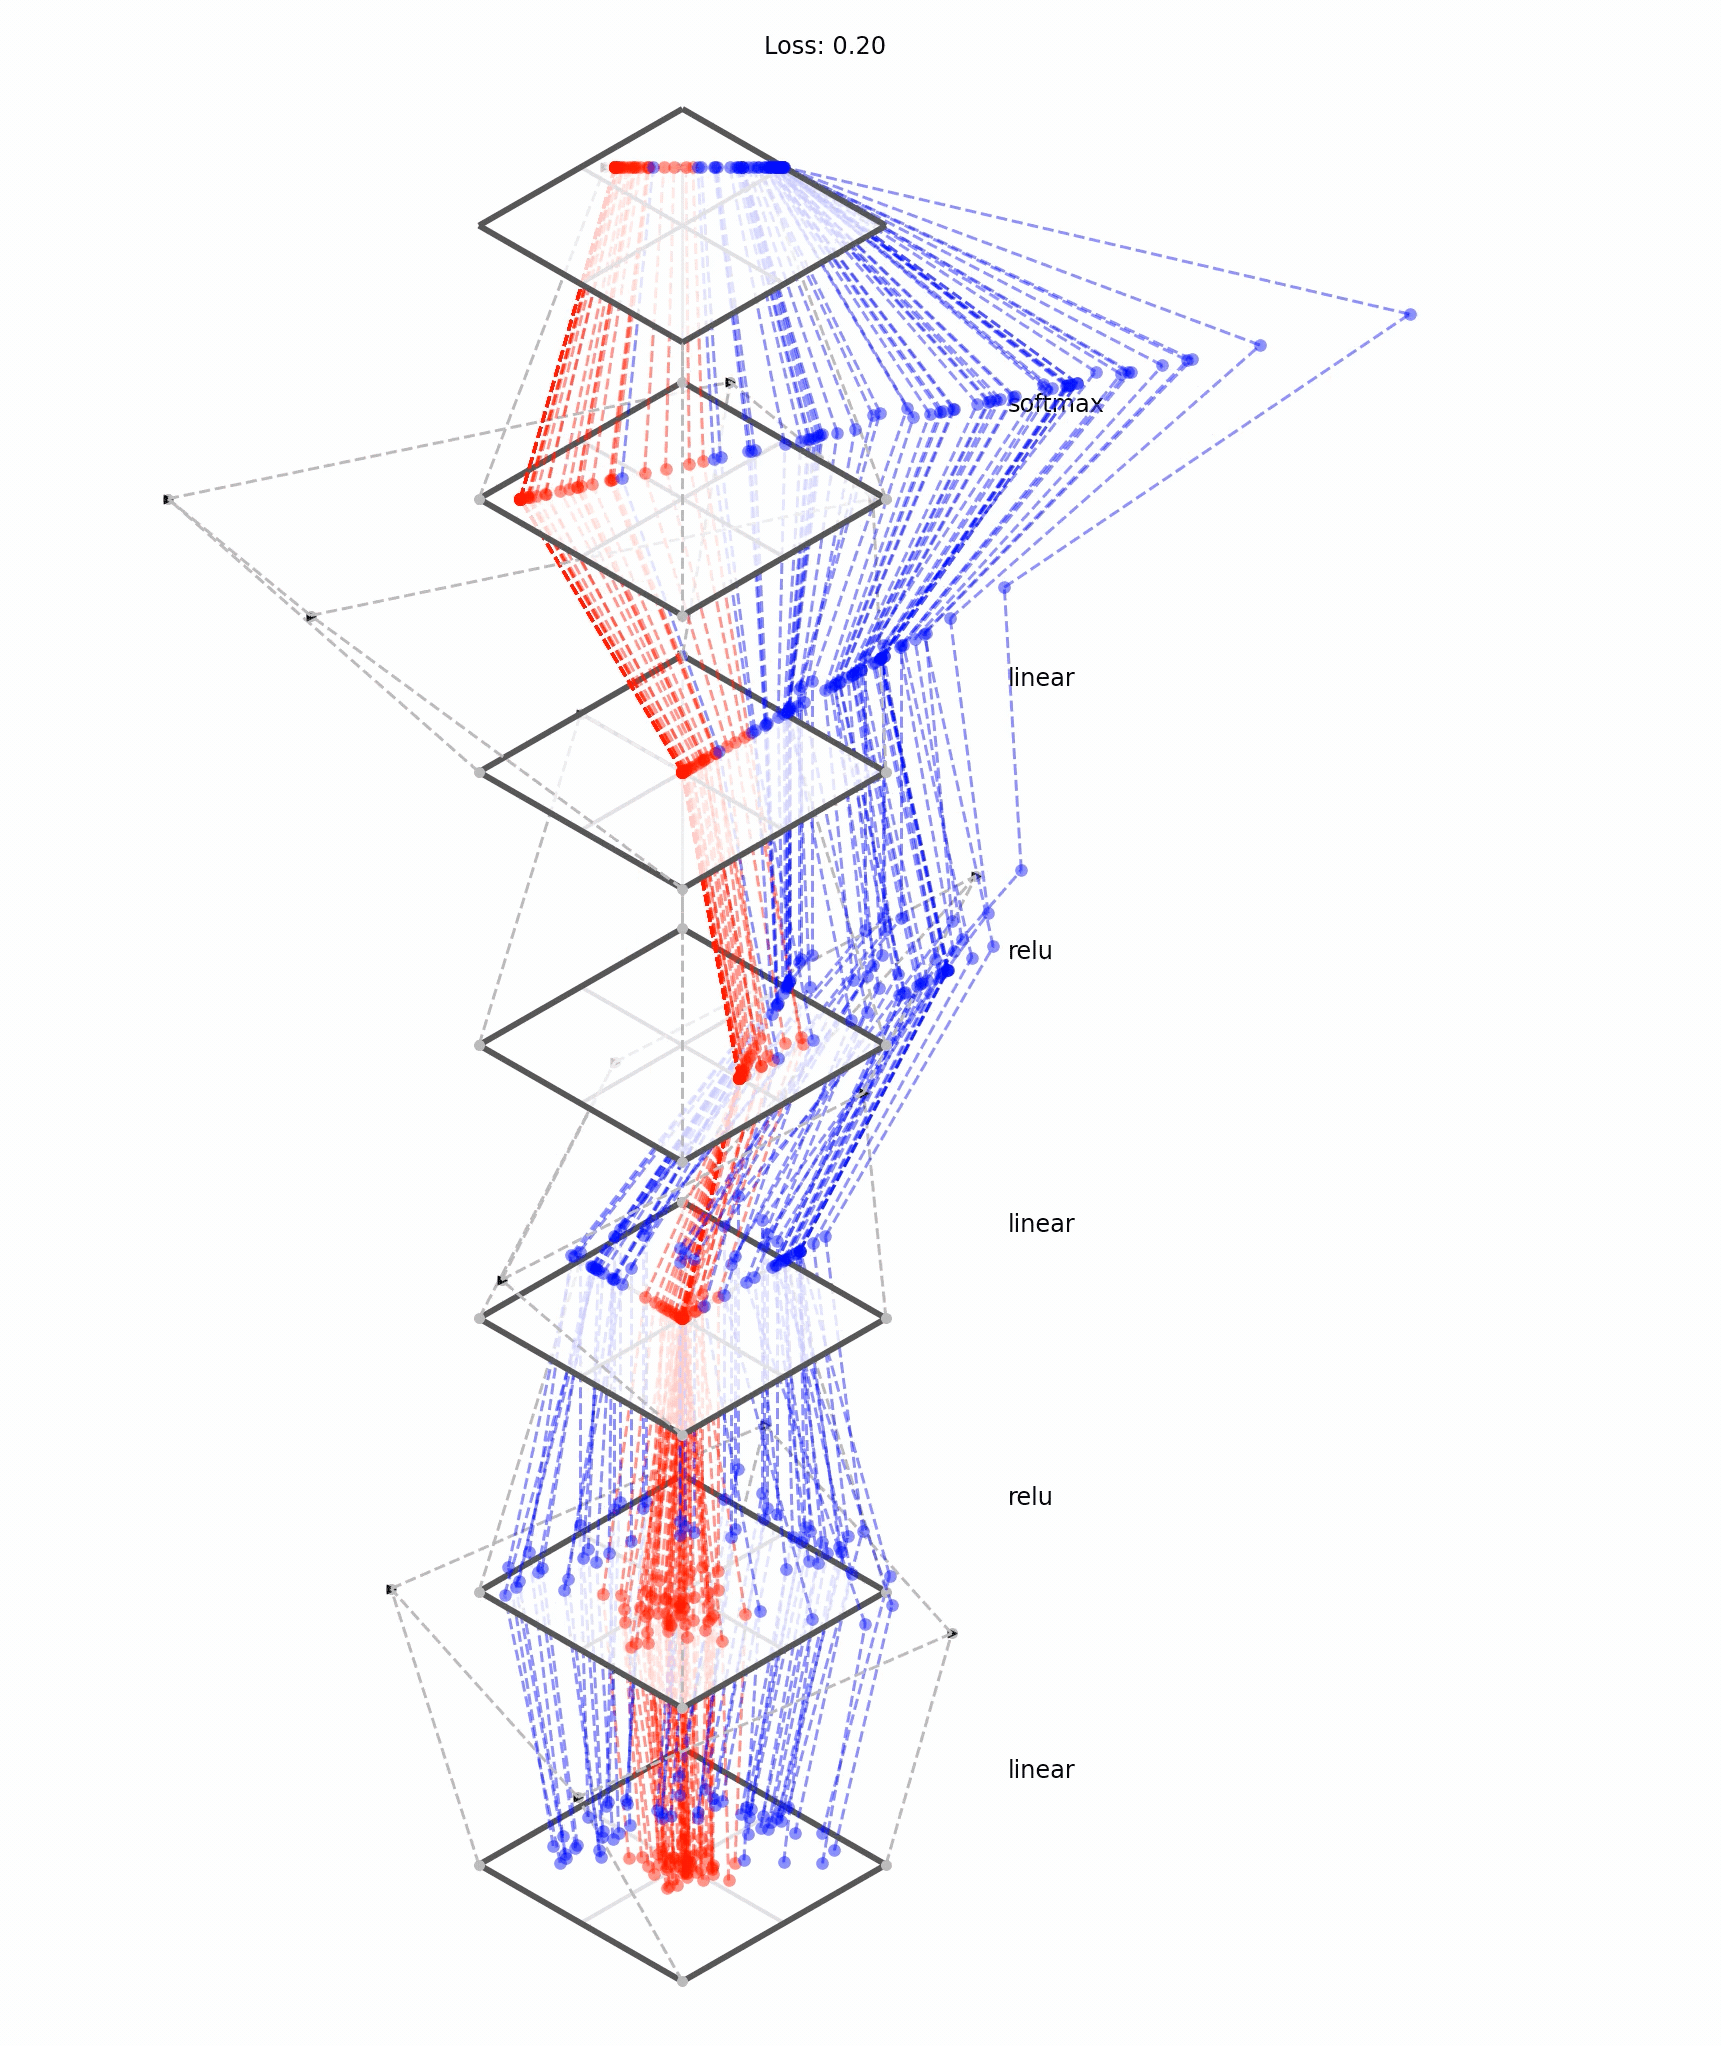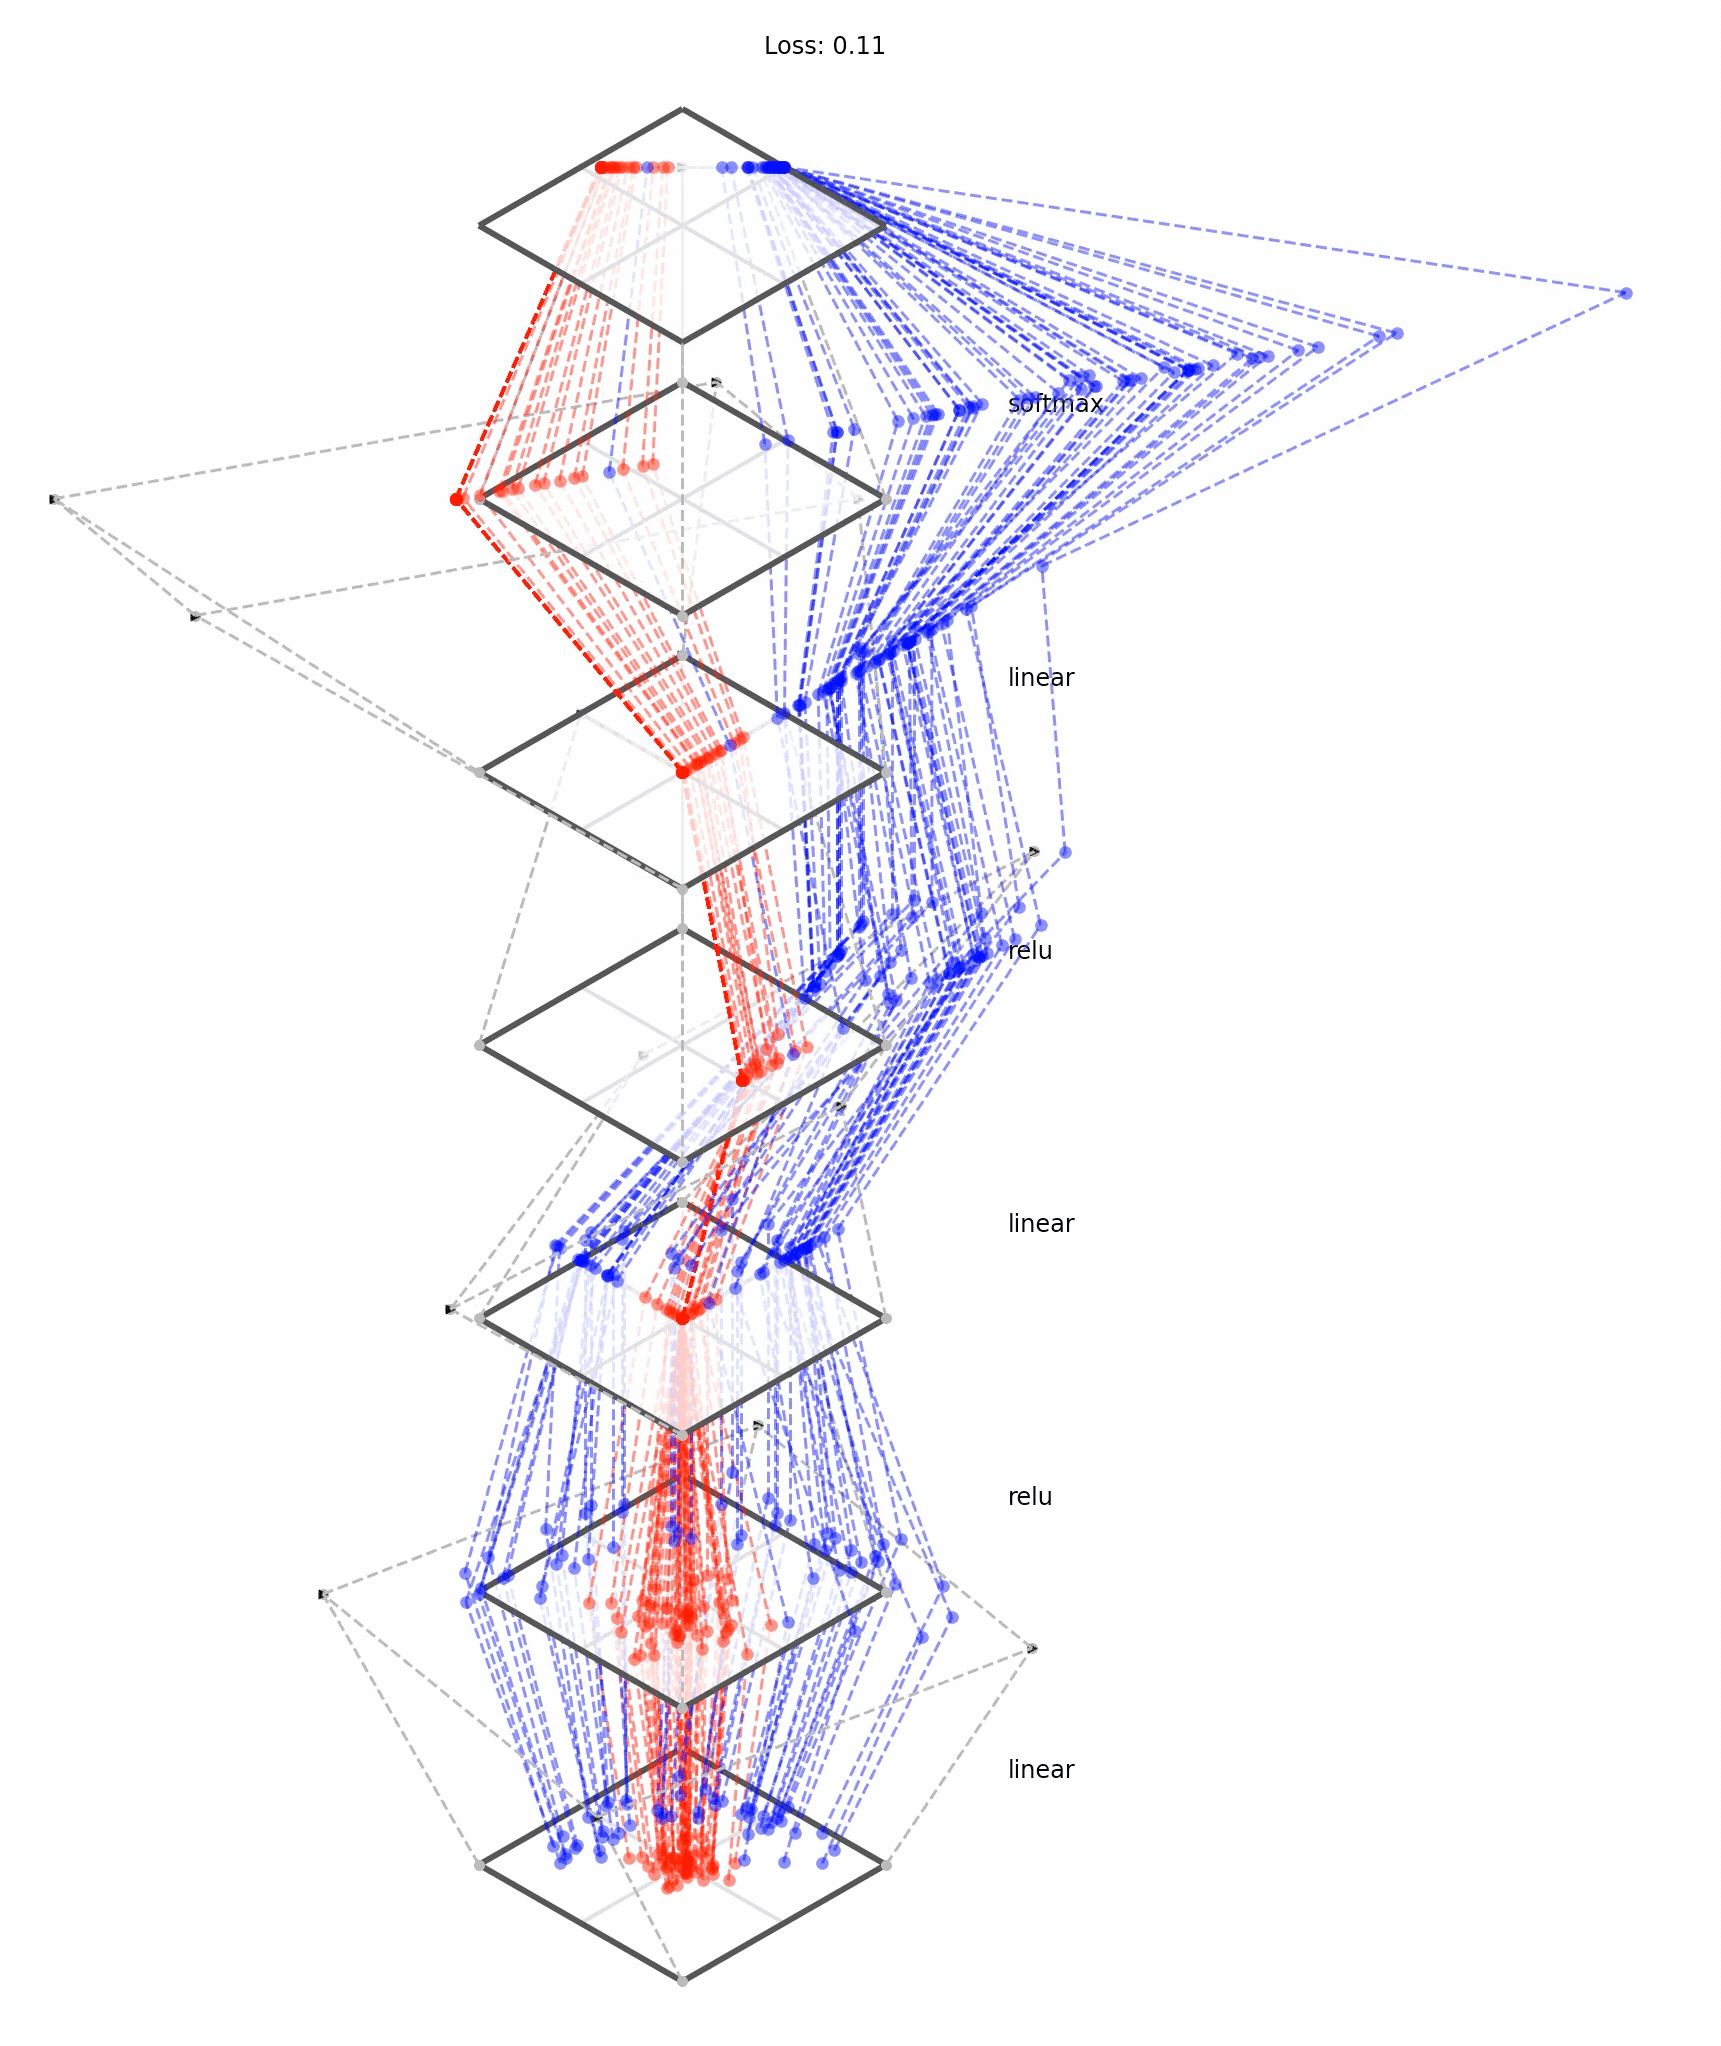
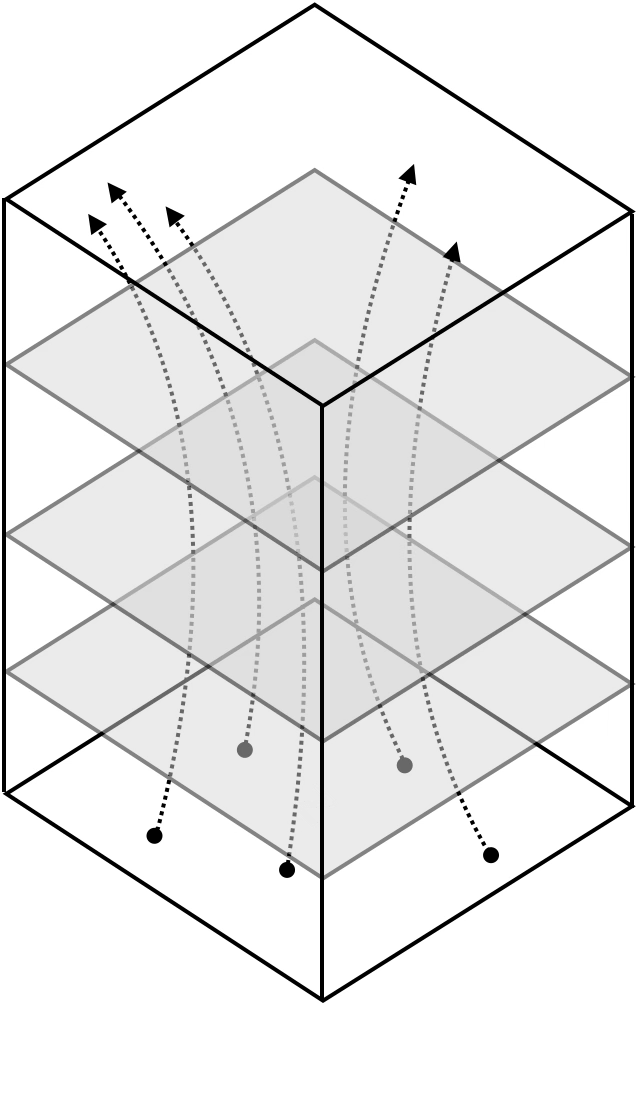
Deep neural nets transform datapoints, layer by layer
Each layer is a different representation, aka embedding, of the data
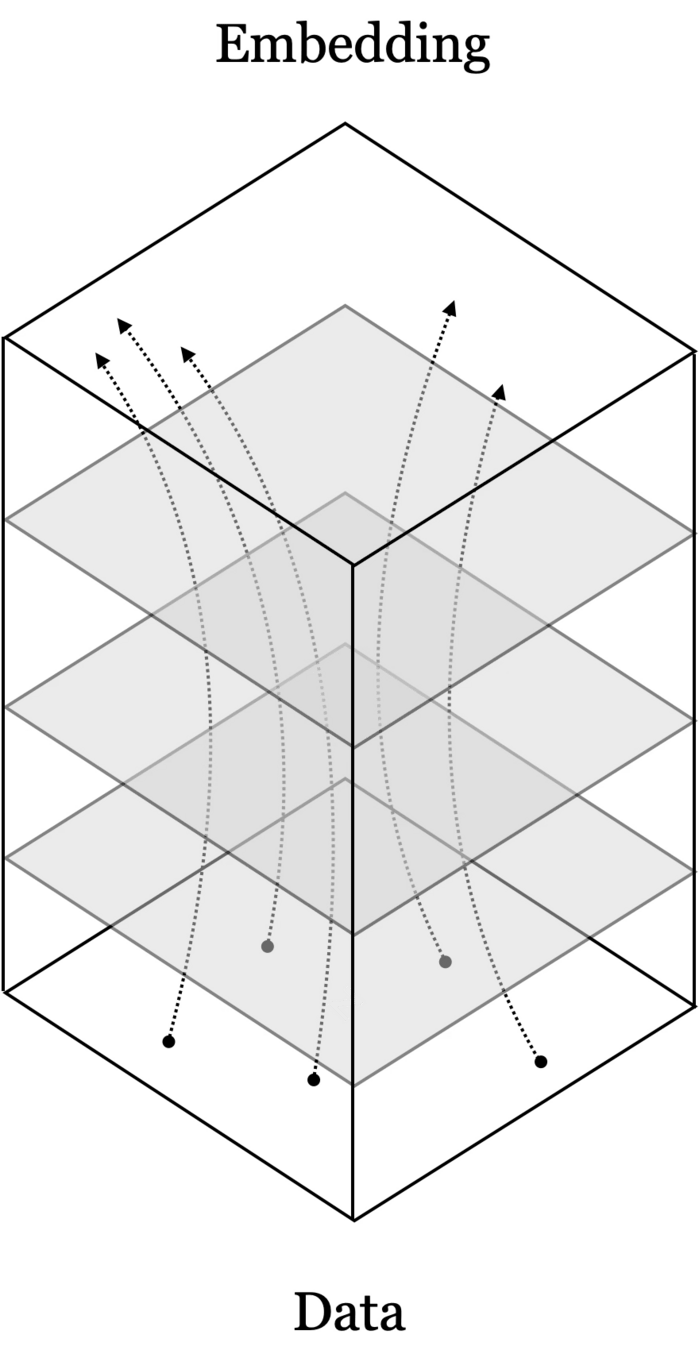
From data to latent embeddings: representation learning
(From latent embeddings to data: generative modeling)
Representation learning
Generative modeling
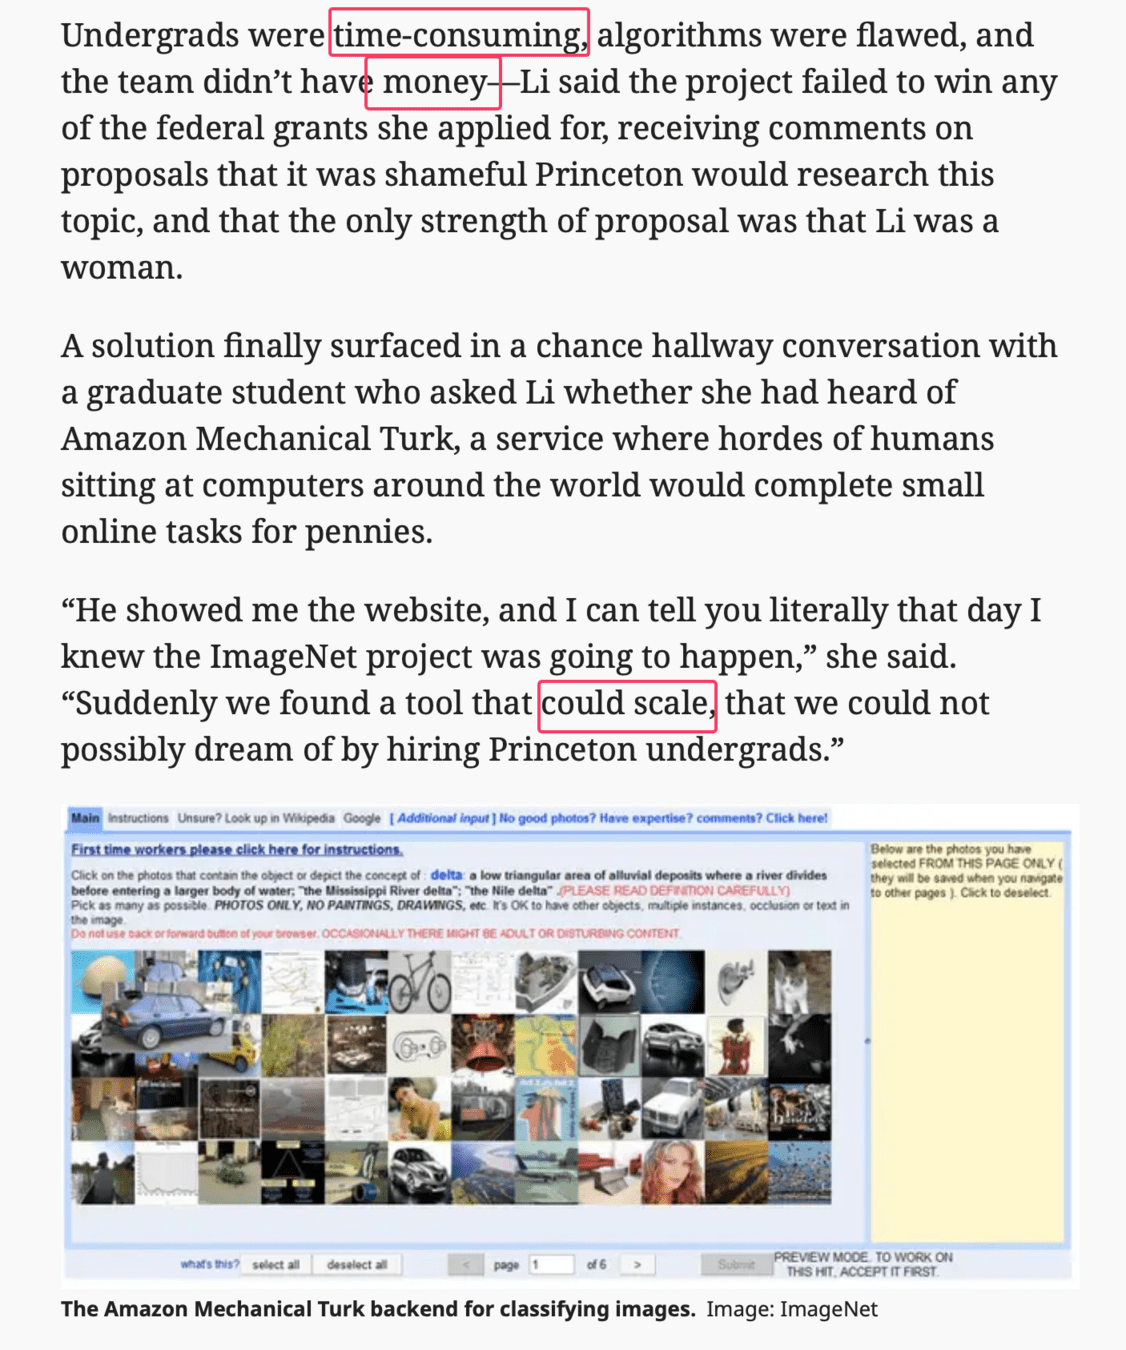
ImageNet also taught us that labeling 14 million images by hand is brutal.
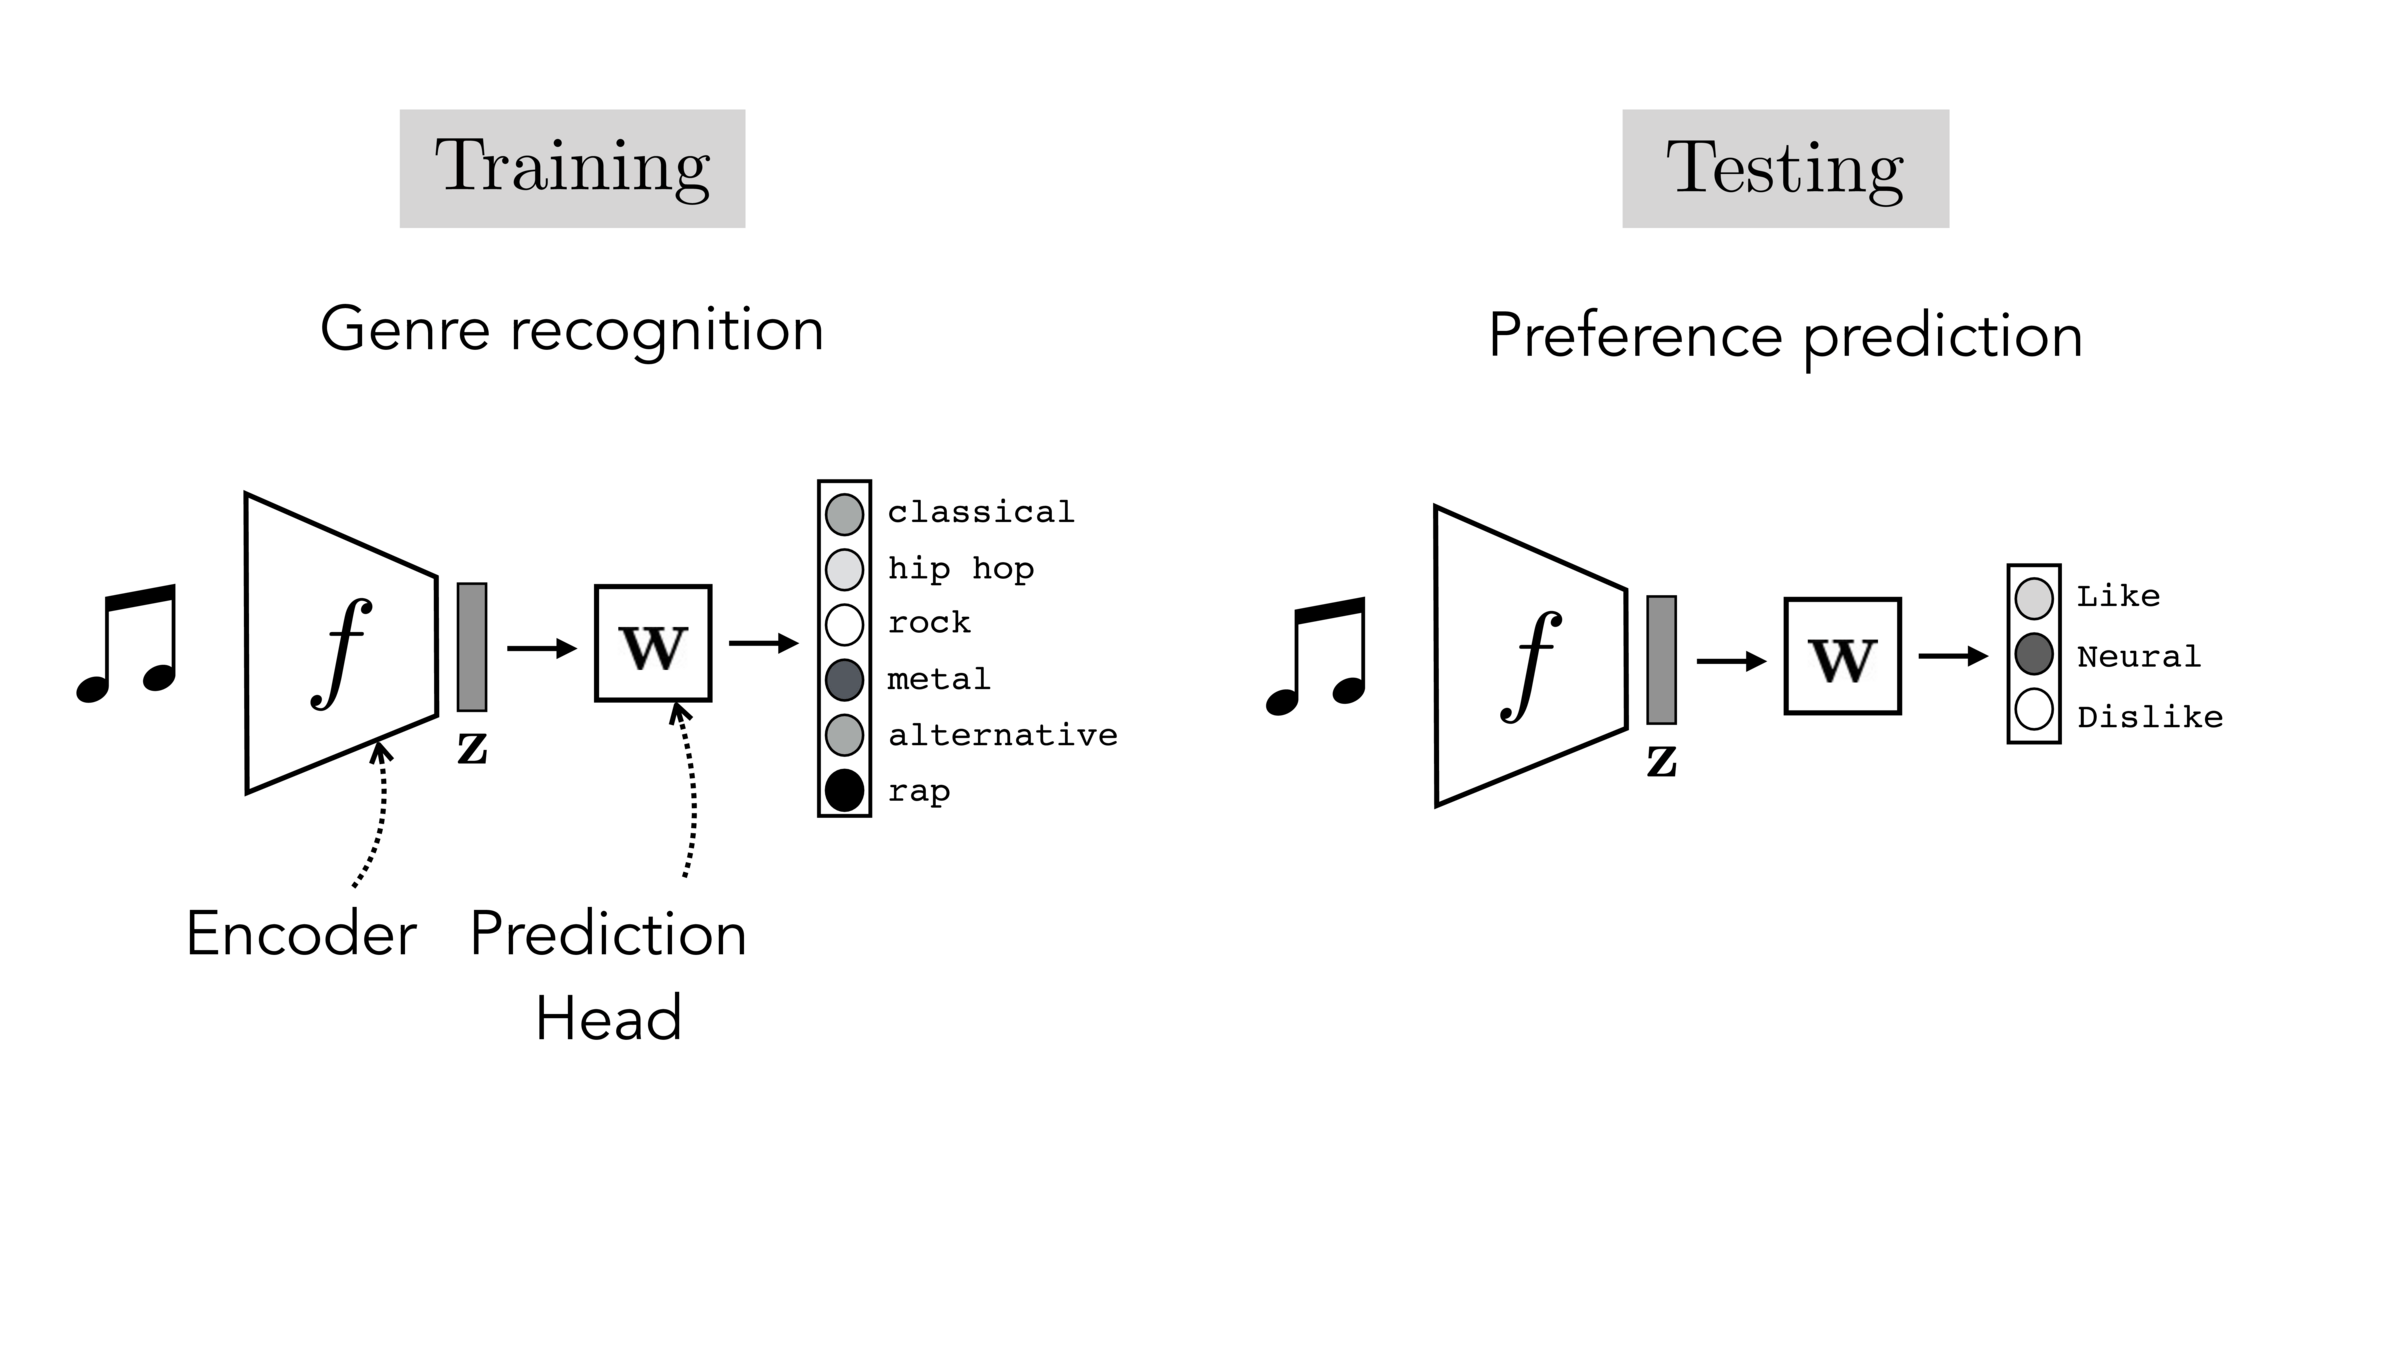
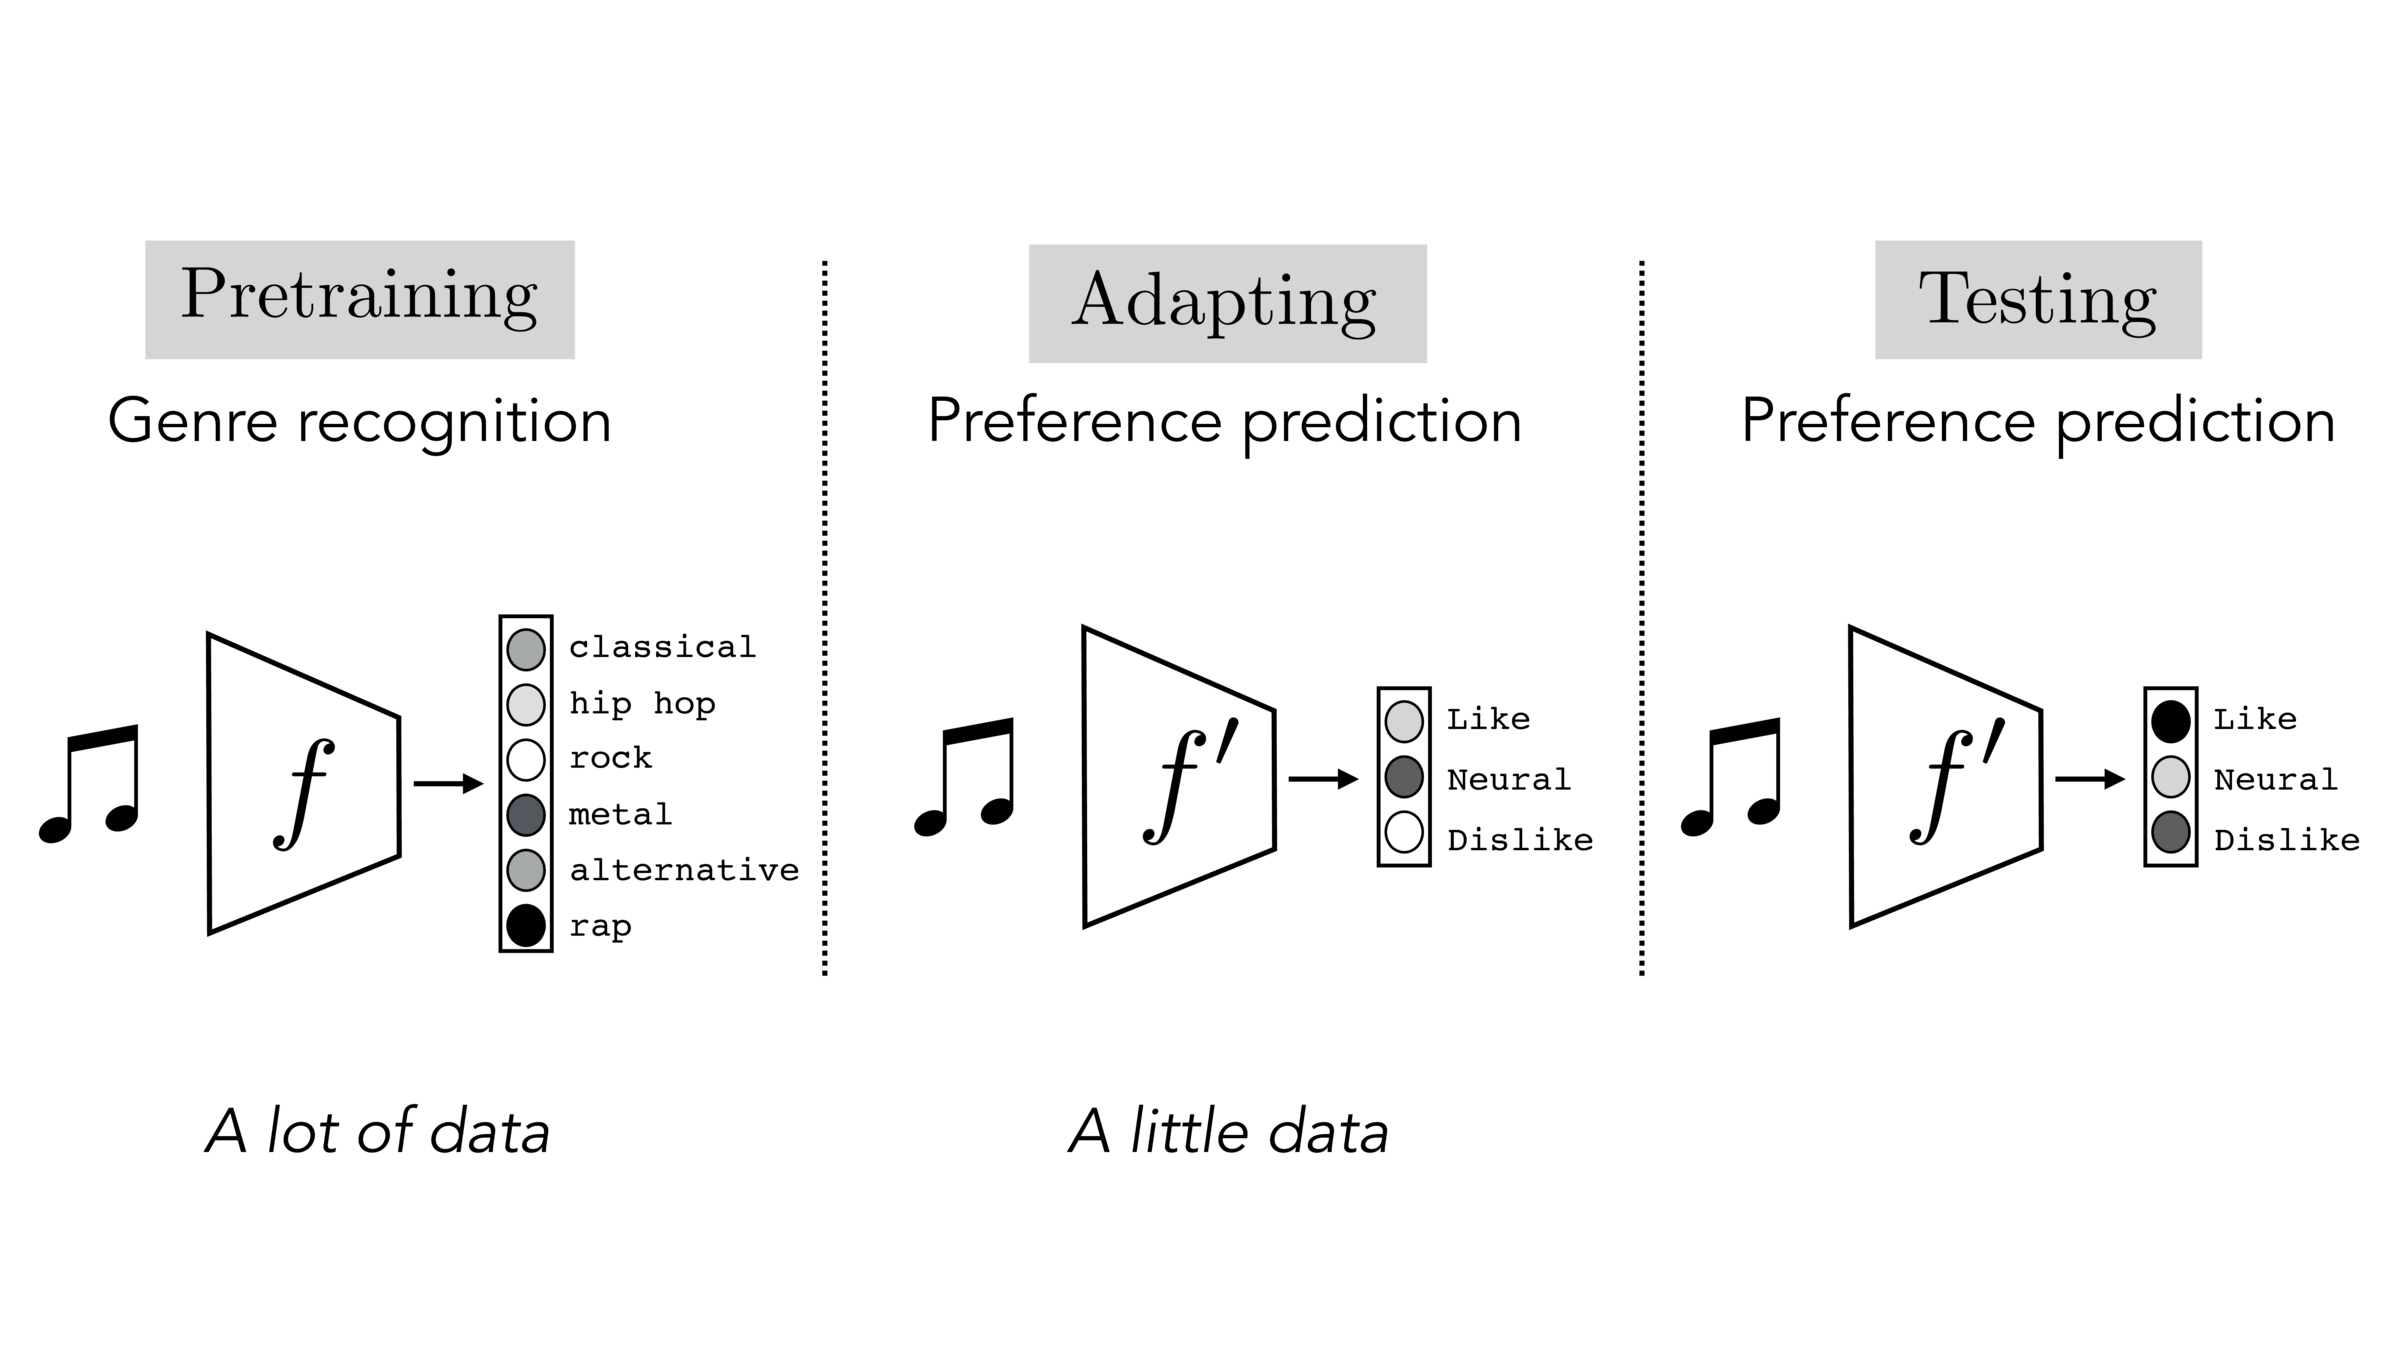
Often, what we will be “tested” on is not what we were trained on.
"common"-sense representation
task-specific prediction
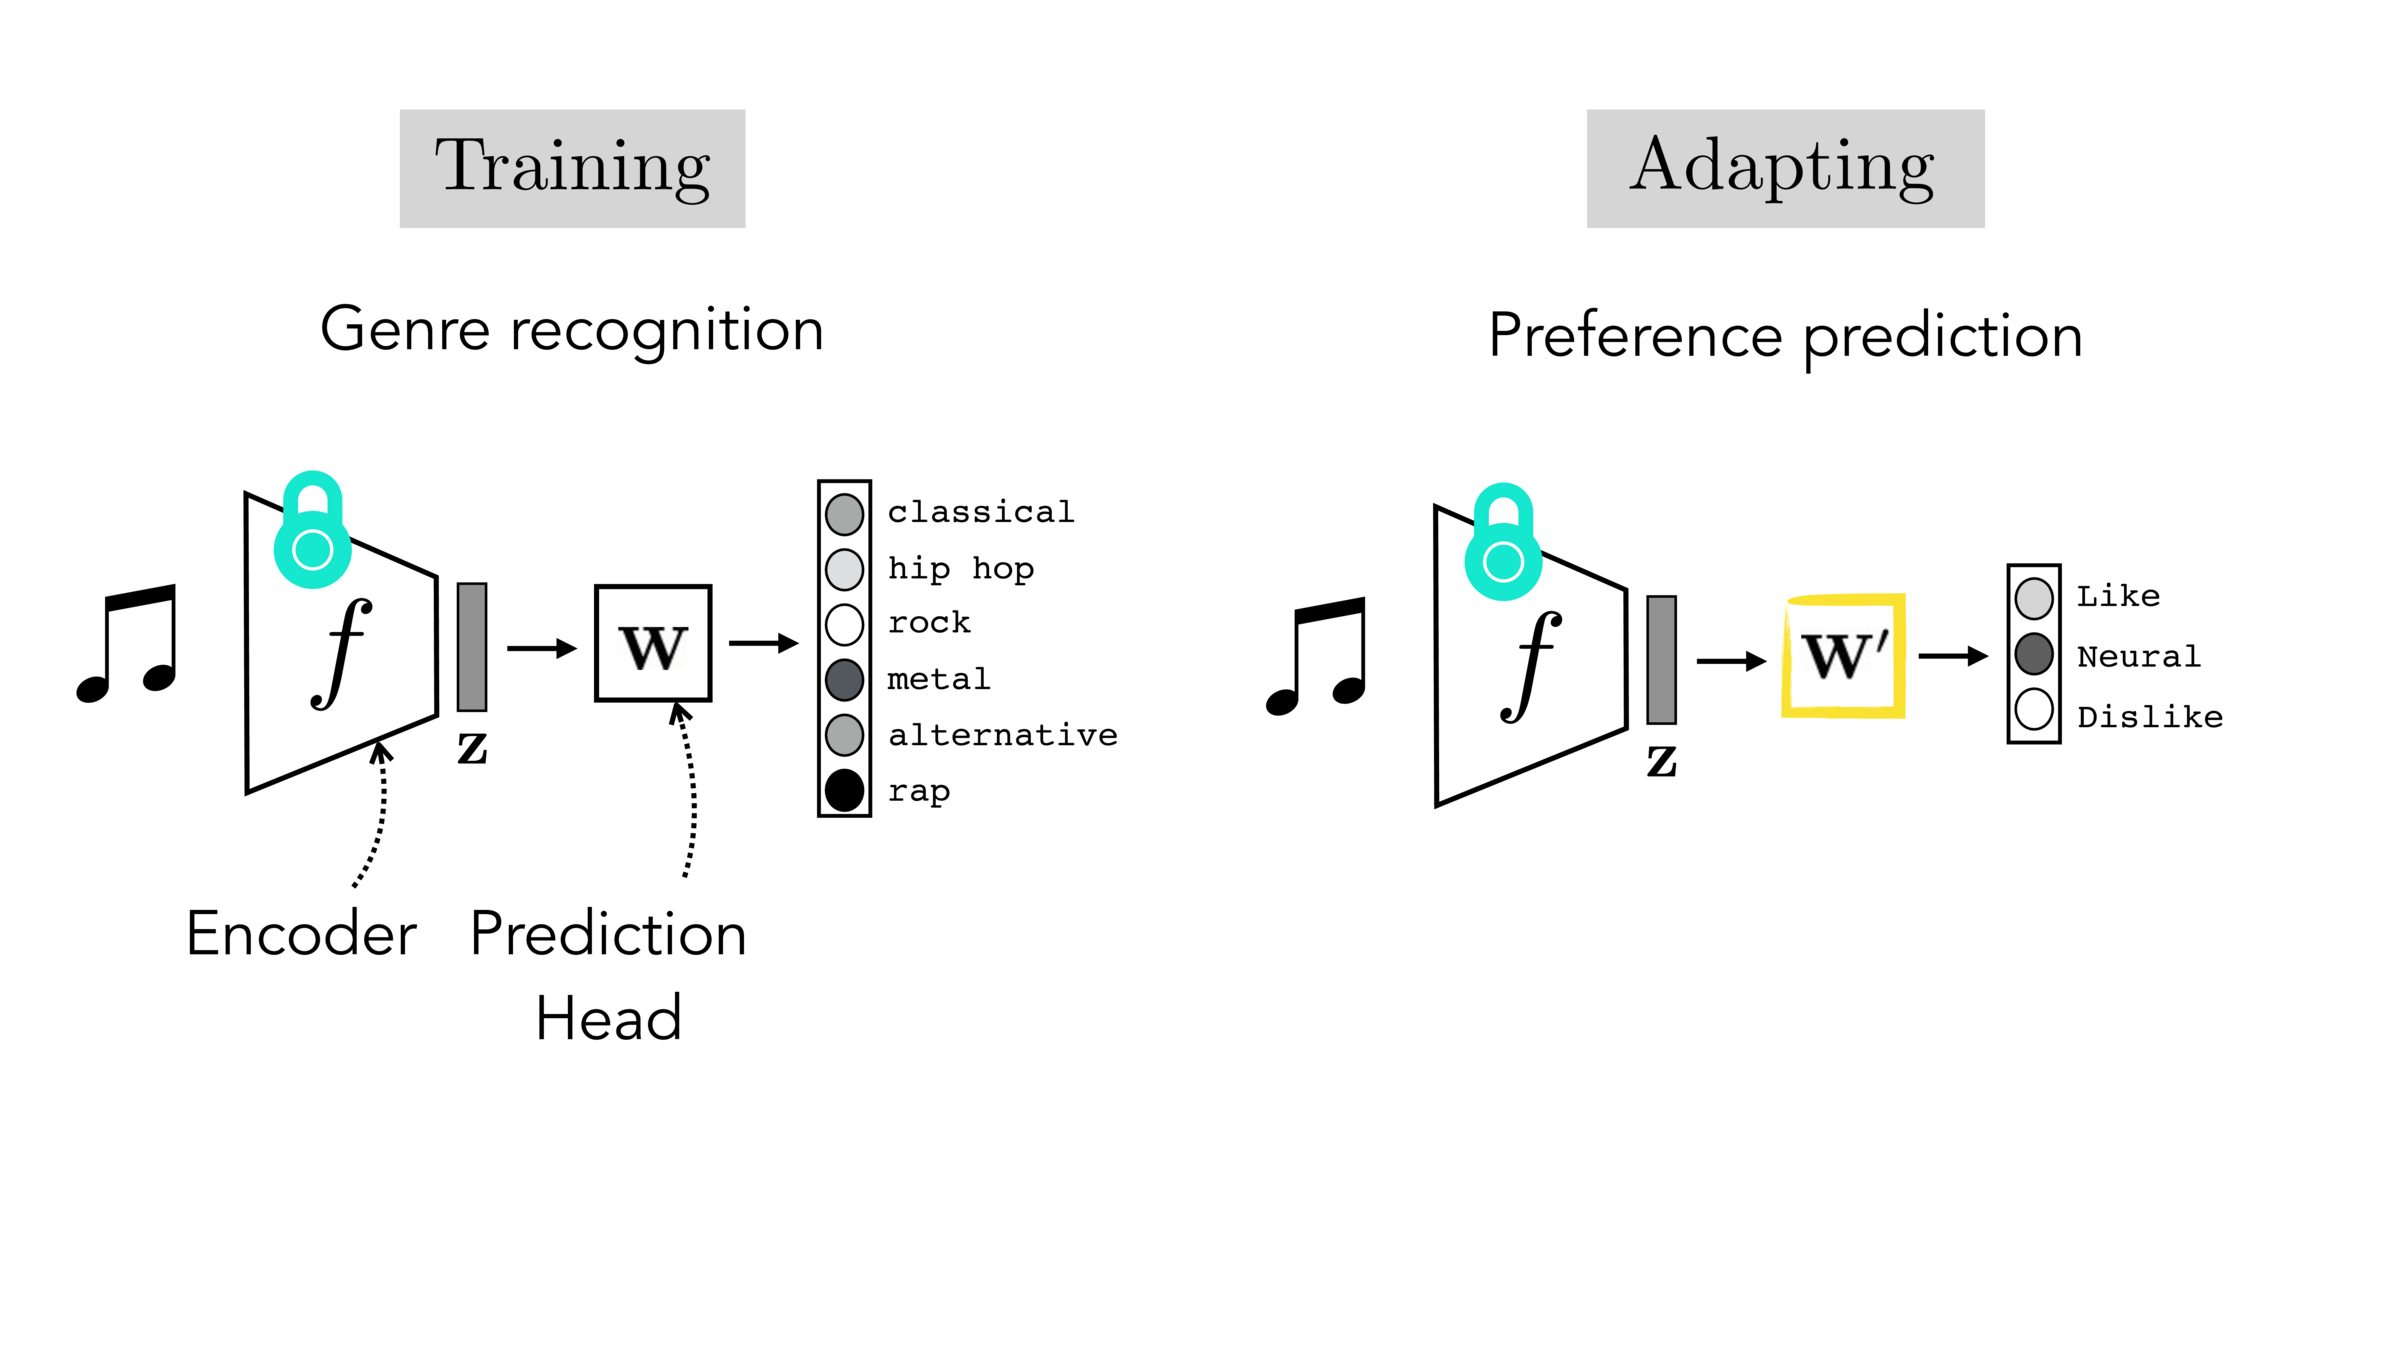
Final-layer adaptation: freeze \(f\), train a new final layer on new target data
"common"-sense representation
task-specific prediction
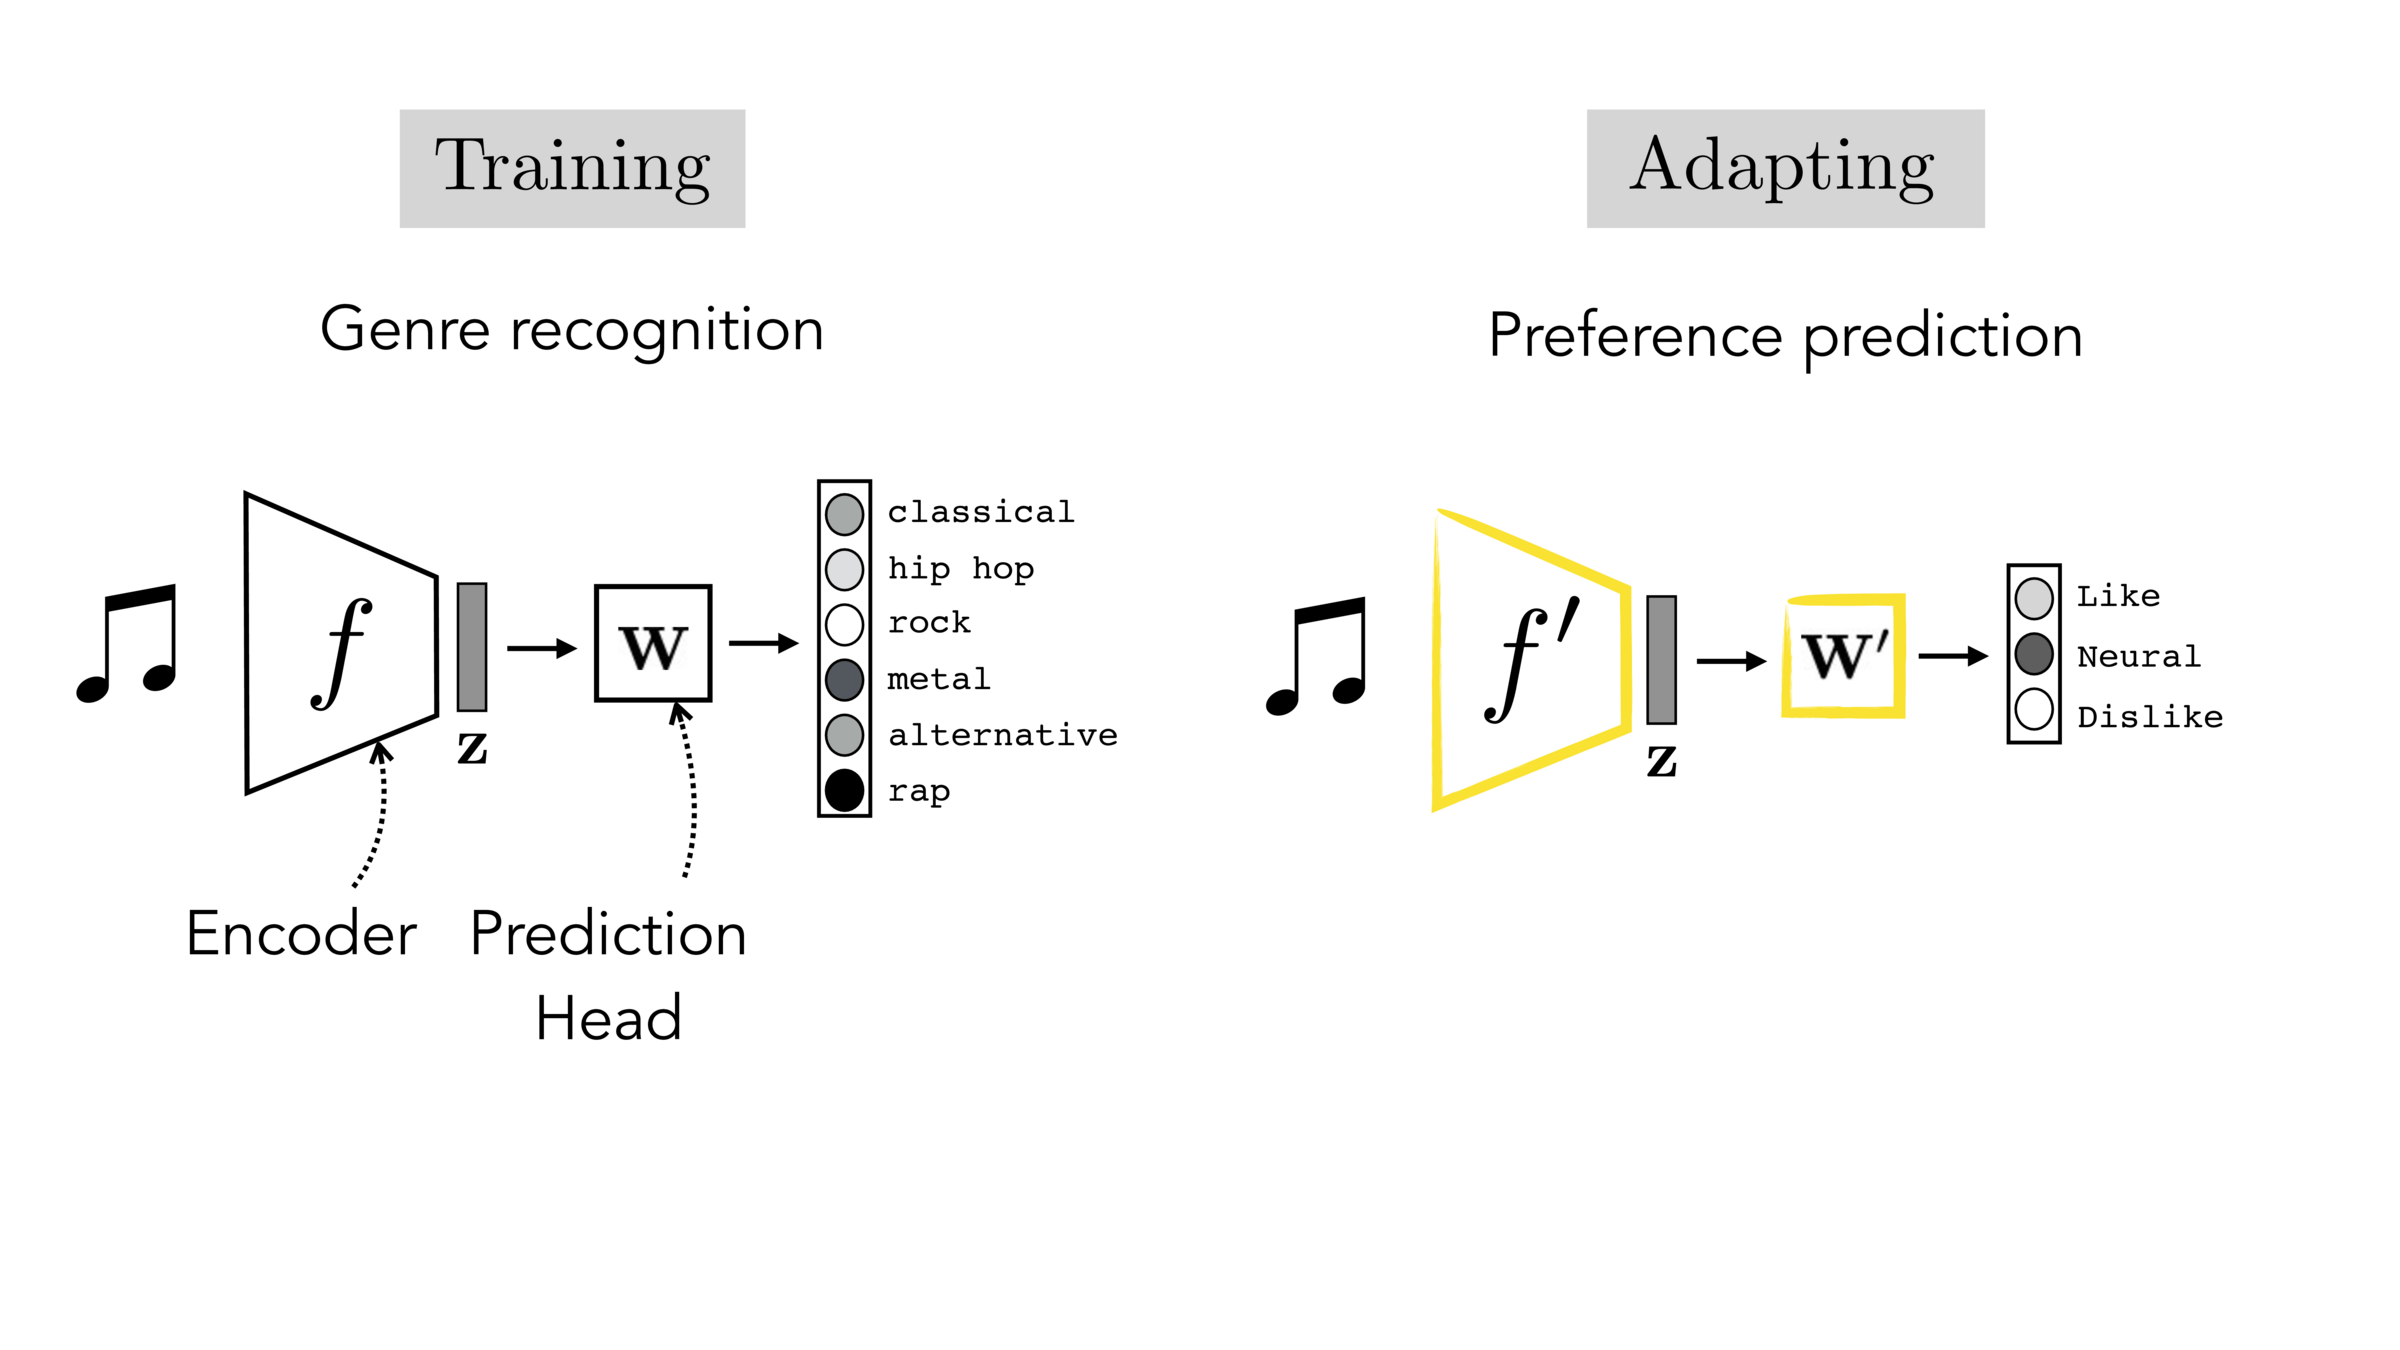
Fine-tuning: initialize \(f’\) as \(f\), then continue training for \(f'\) as well, on new target data
"common"-sense representation
task-specific prediction
Label prediction (supervised learning)
Label
$$x$$
$$y$$
Features
Labels \(y\) are expensive…
Unlabeled features \(x\) are abundant
Can we learn useful representations without external labels?
Outline
- Neural networks are representation learners
- Auto-encoders and self-supervised learning
- Word embeddings
- Multi-modality
🧠
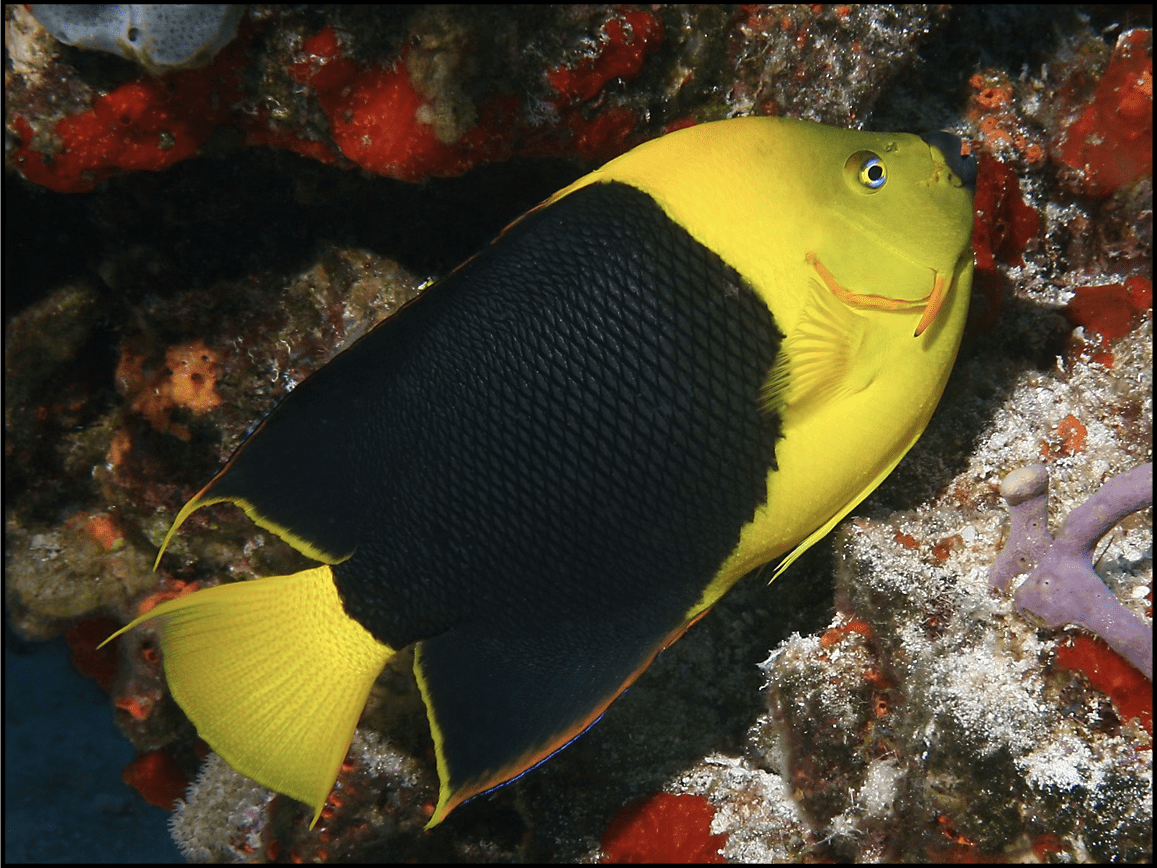
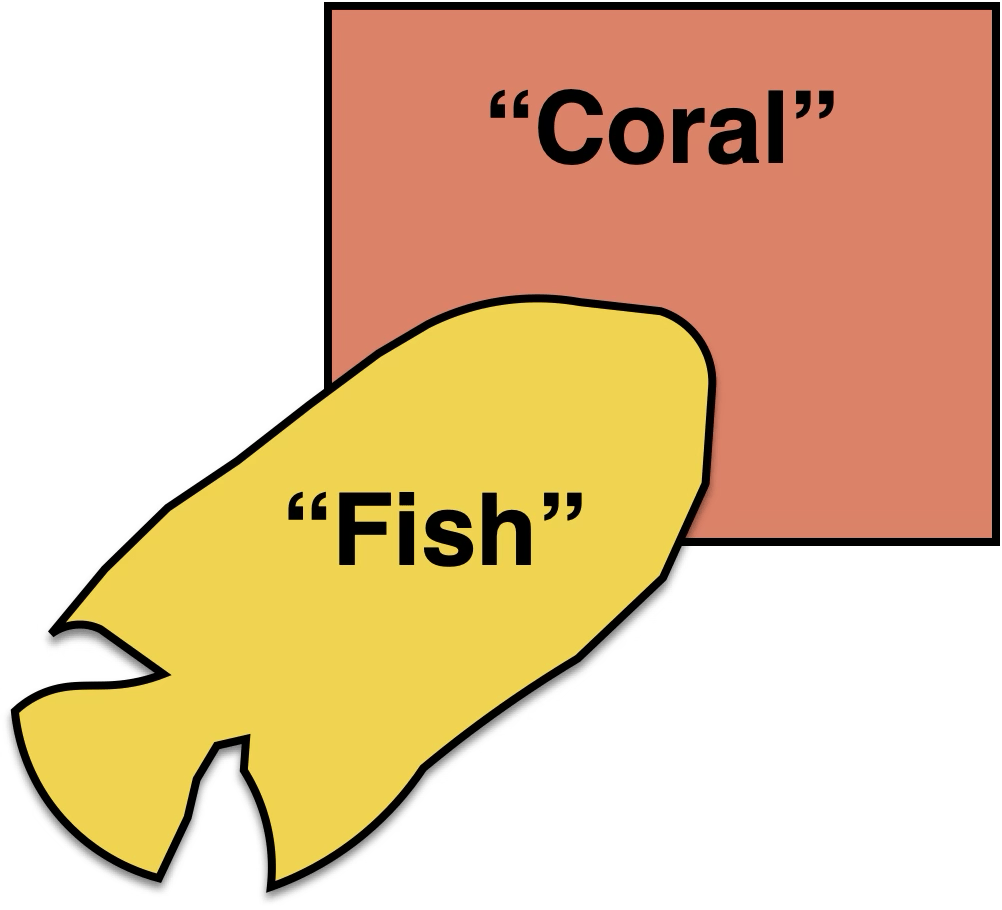
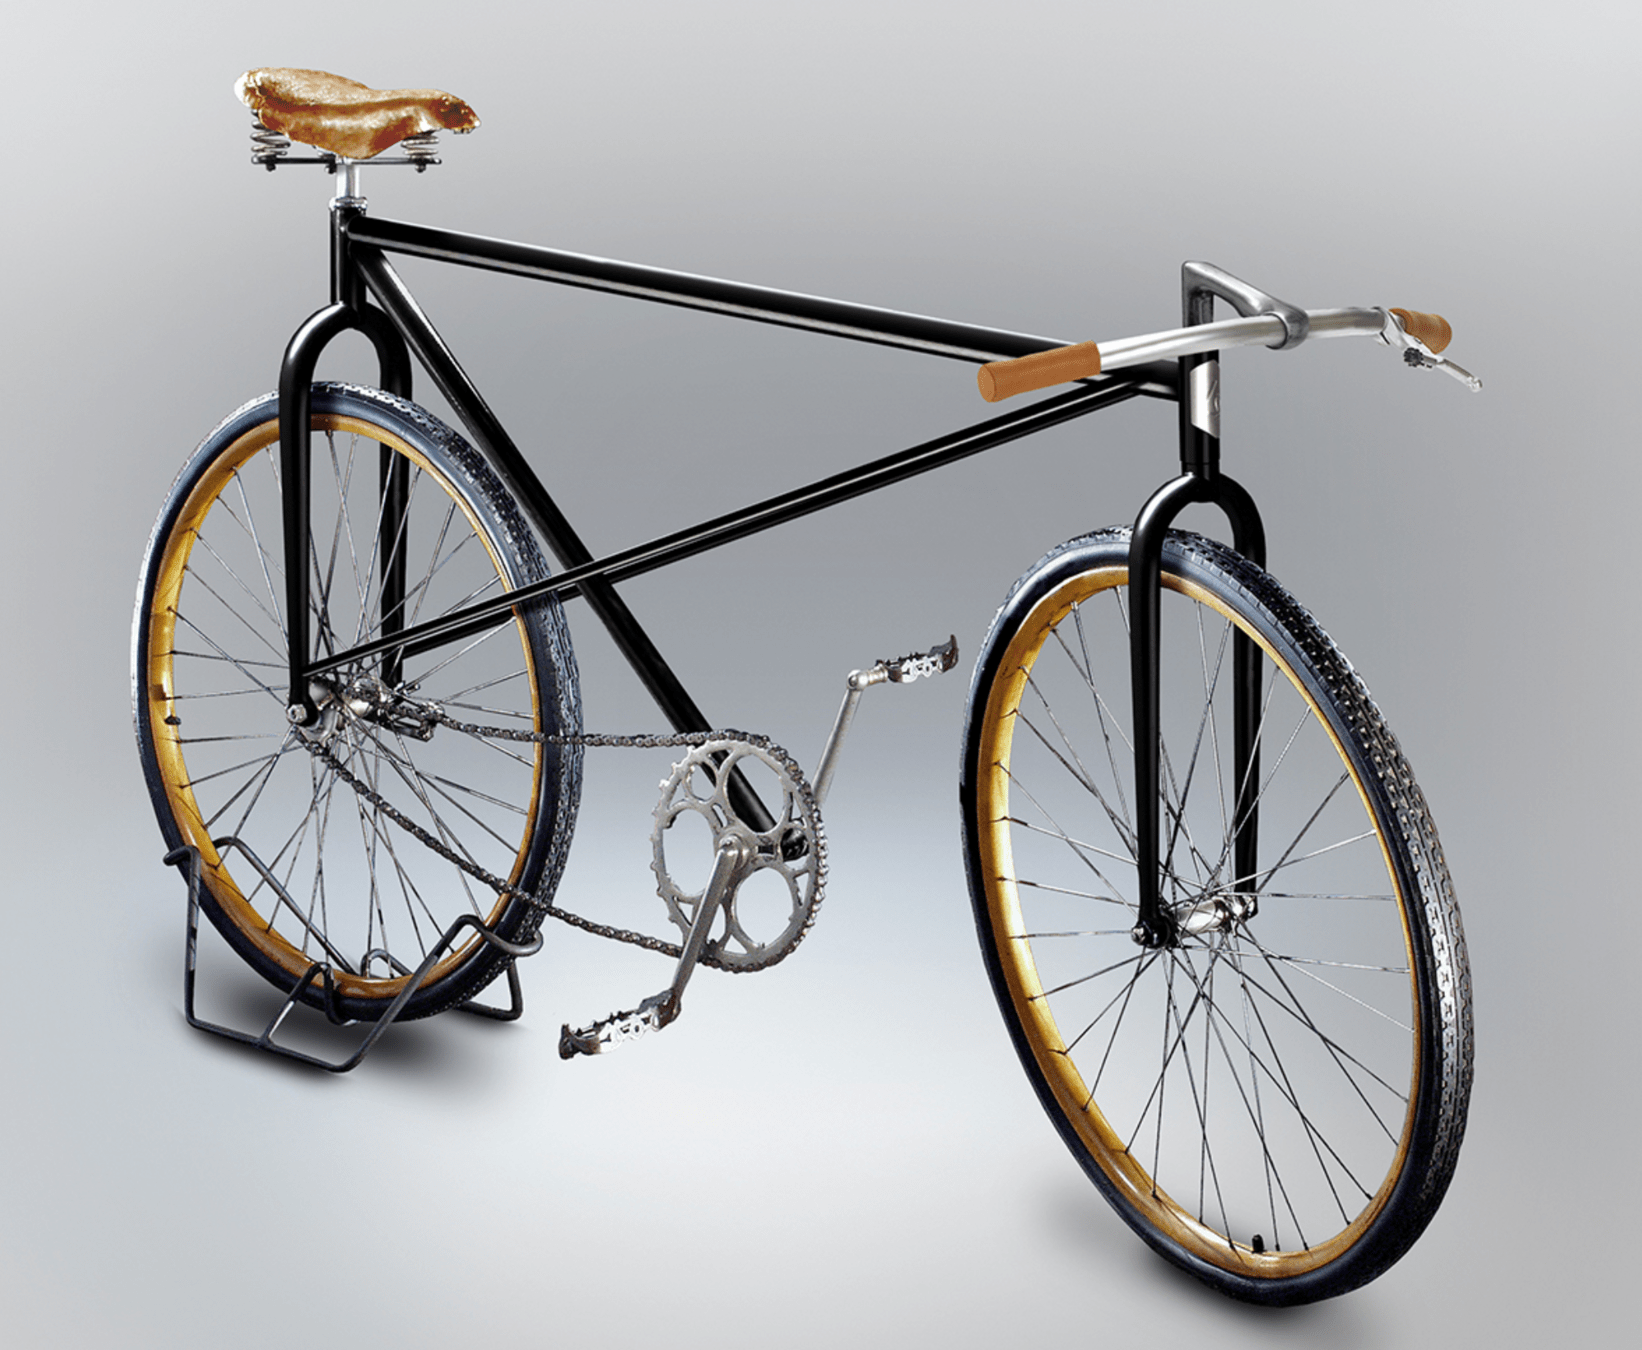
humans also learn representations
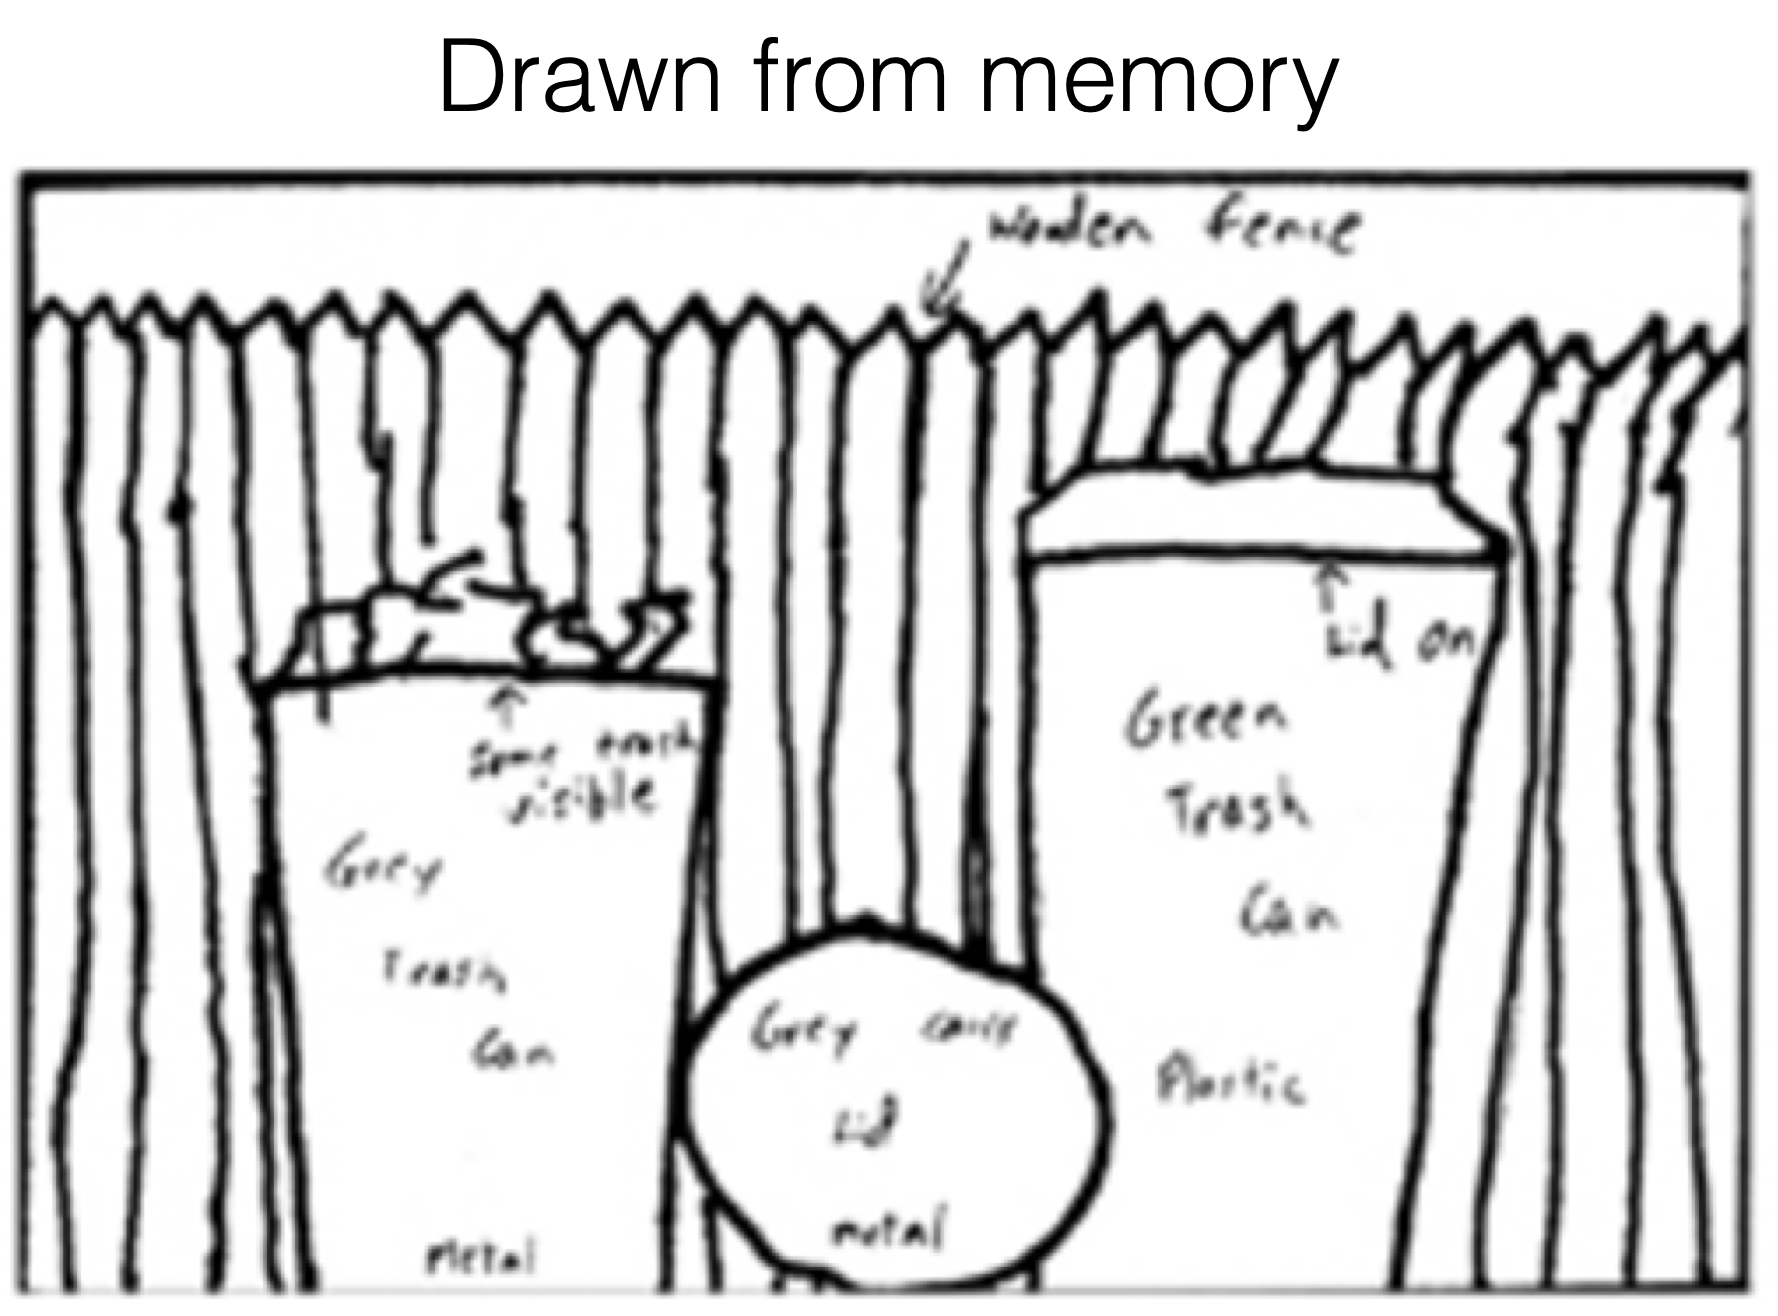
[Bartlett, 1932]
[Intraub & Richardson, 1989]
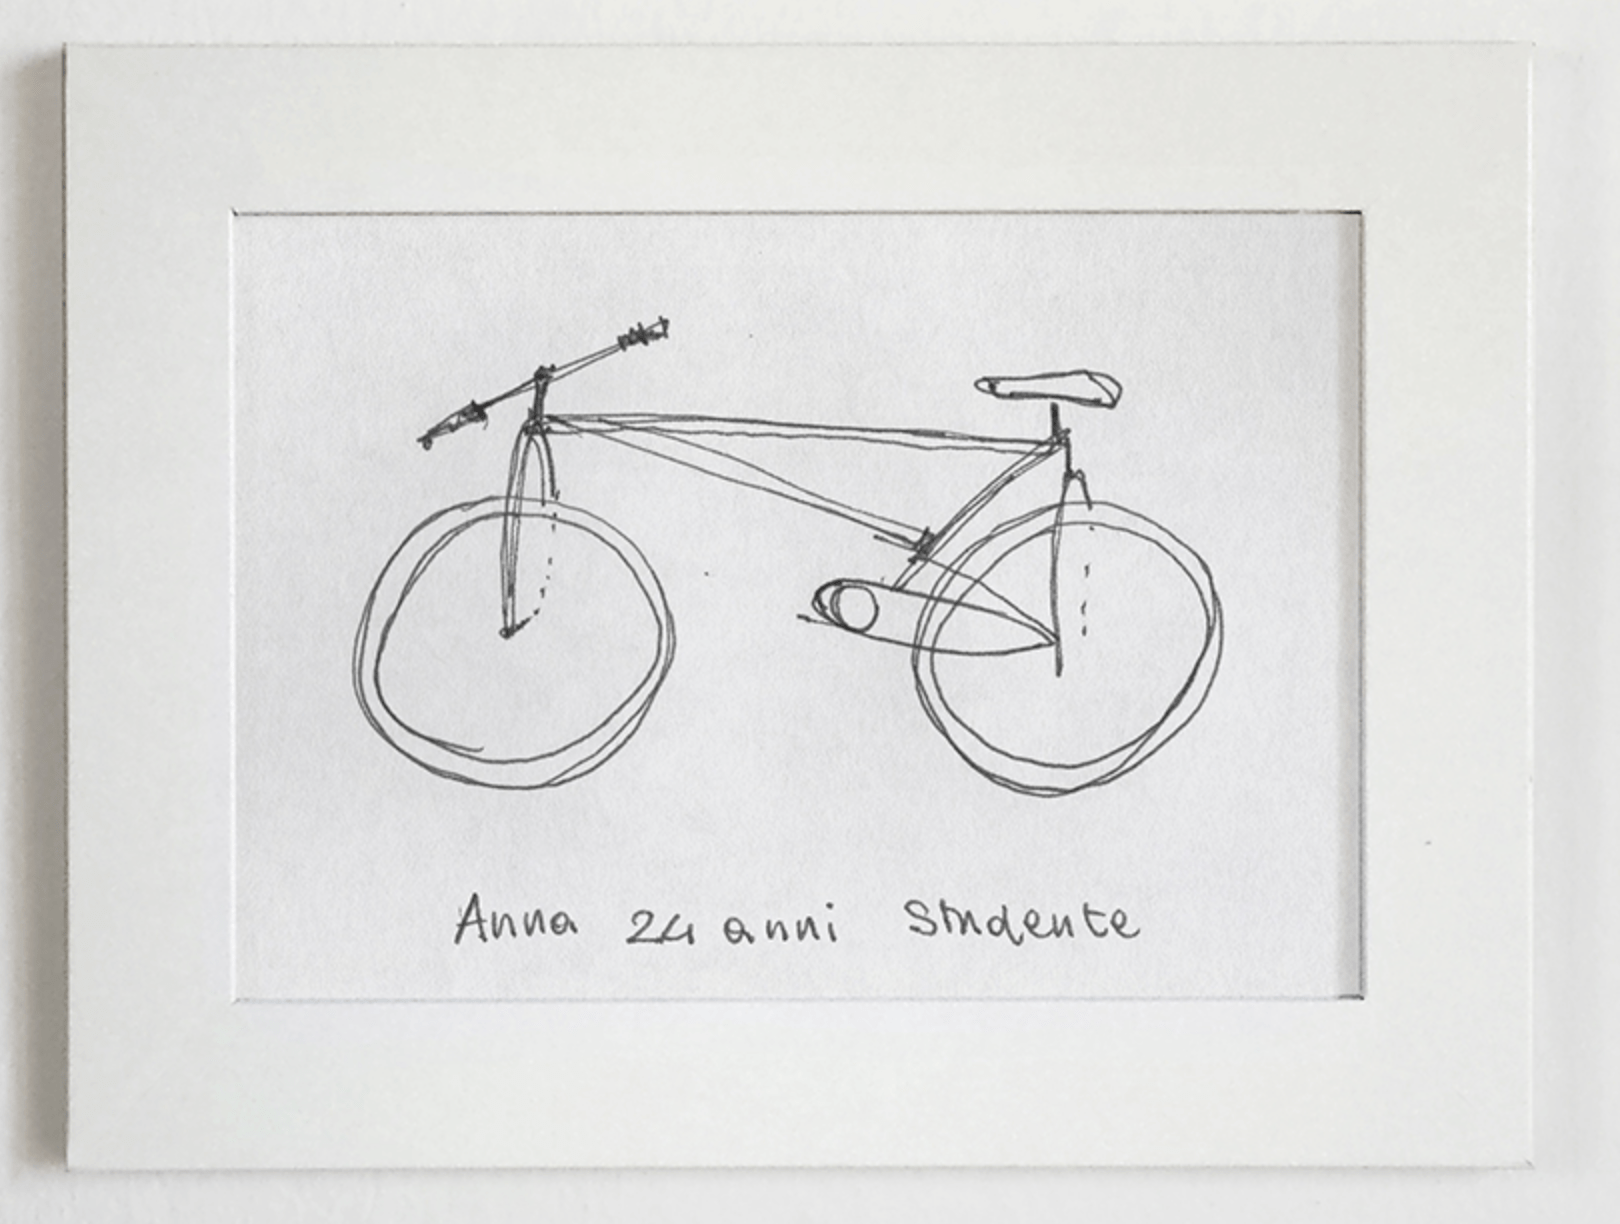
[https://www.behance.net/gallery/35437979/Velocipedia]
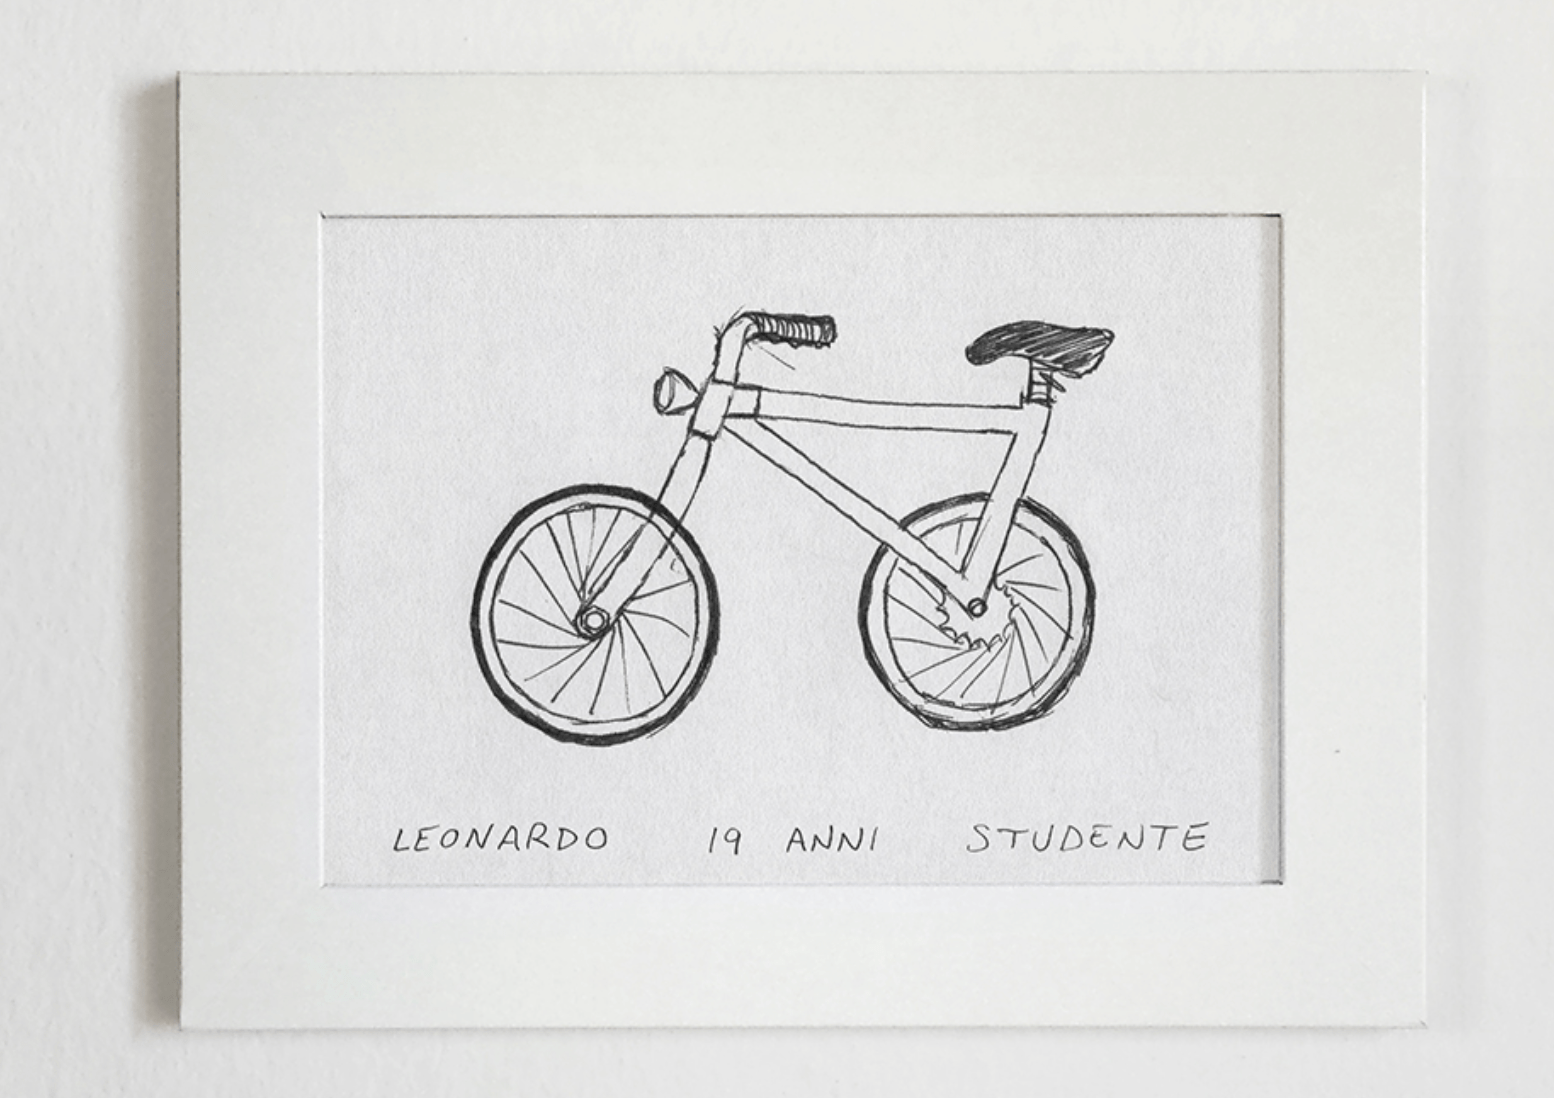
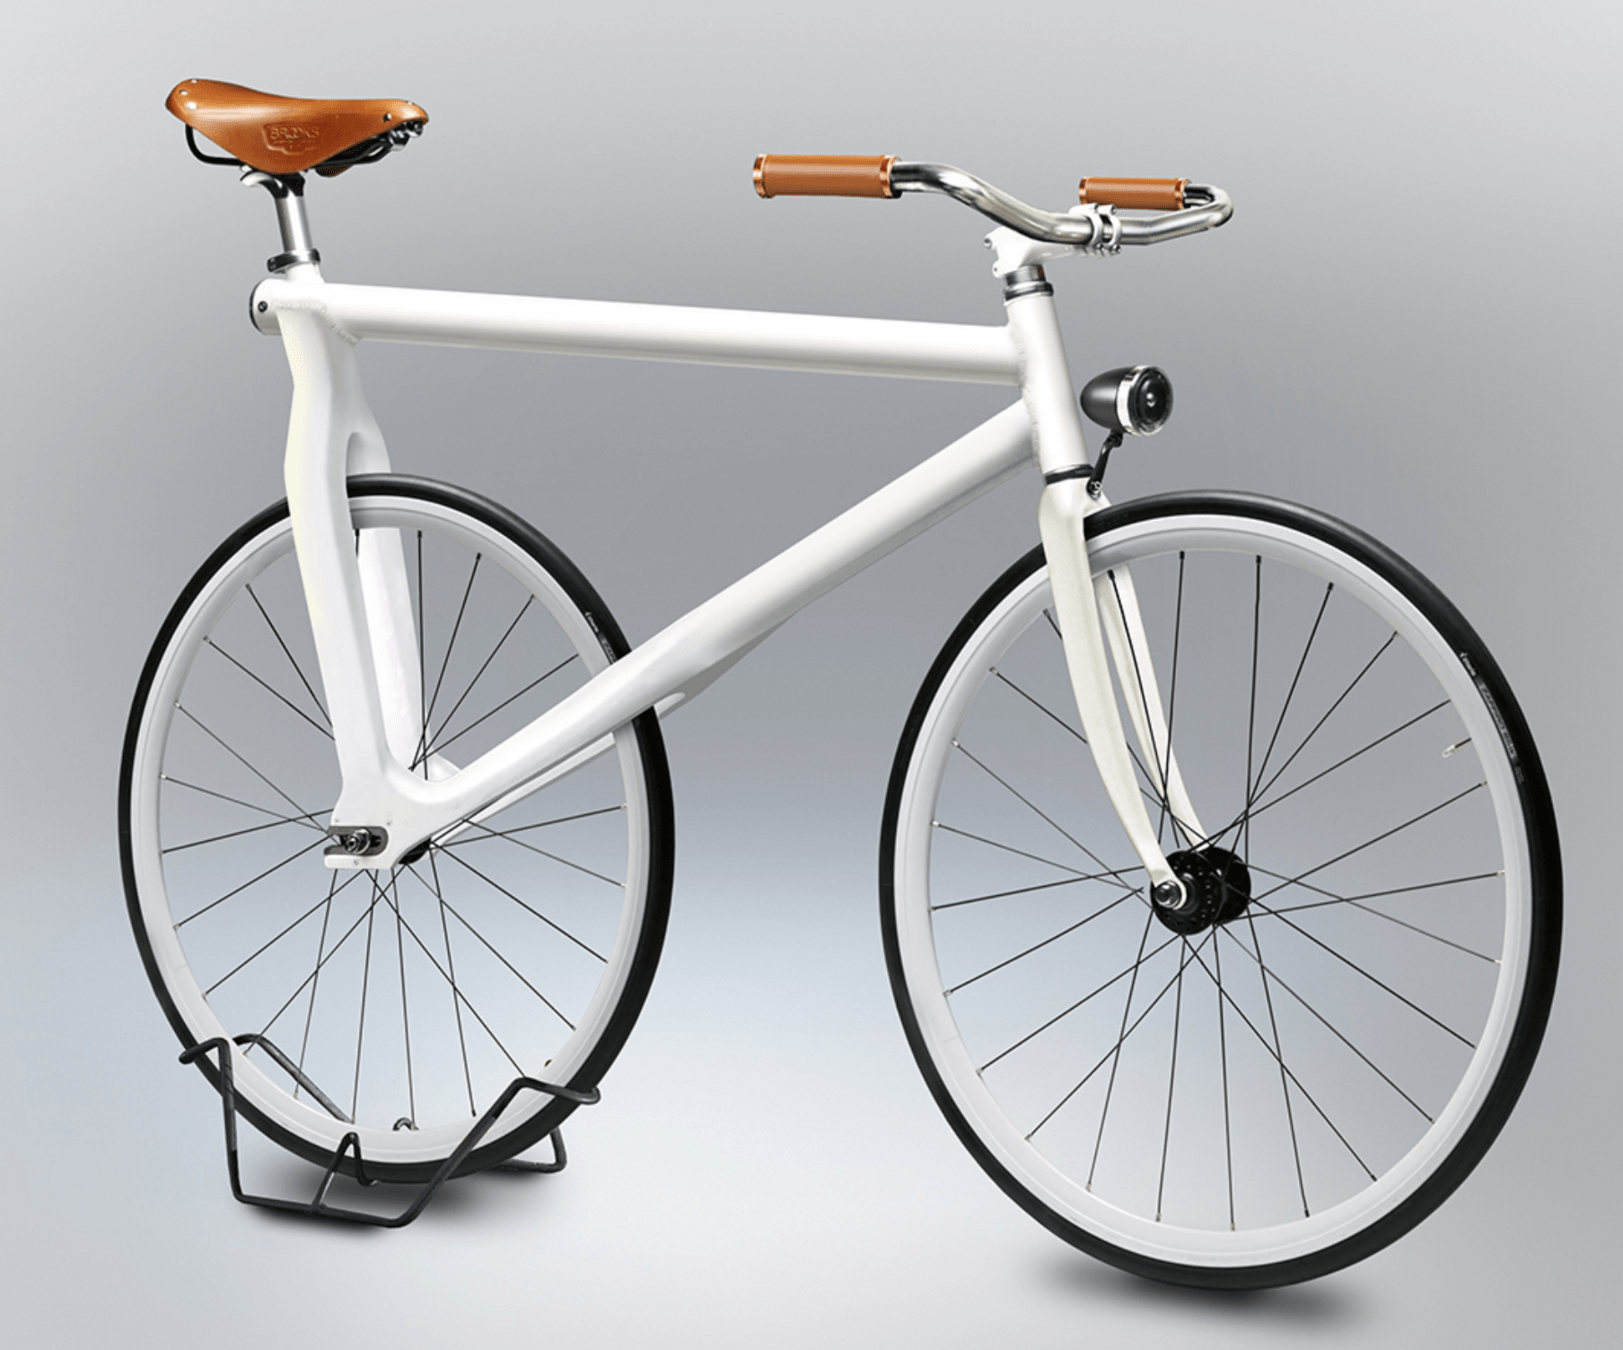
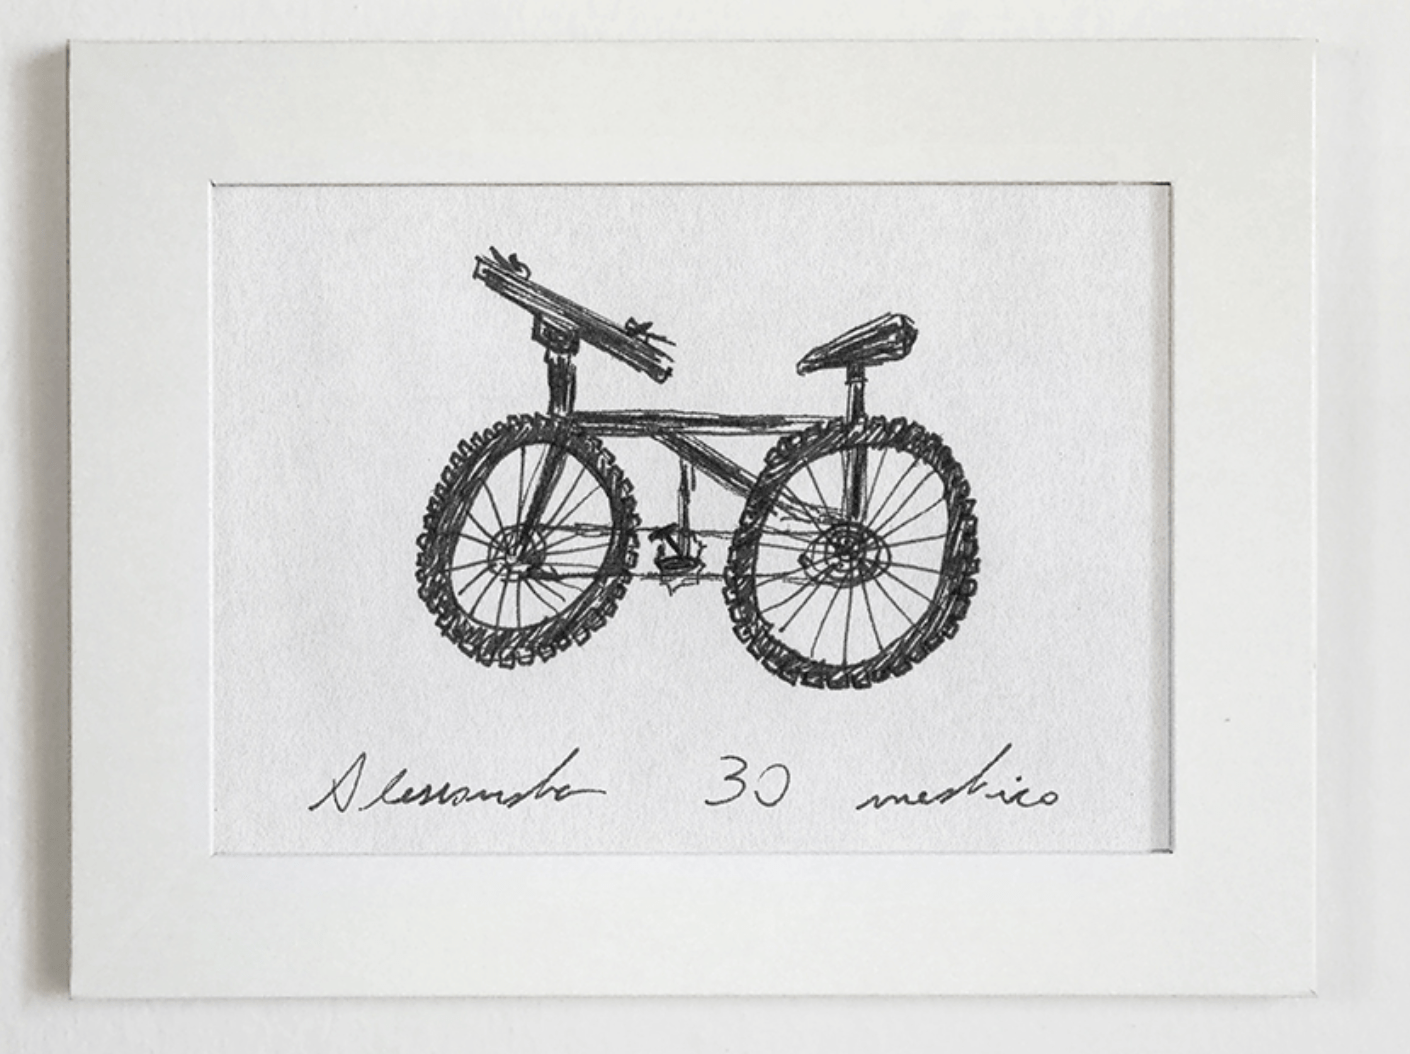
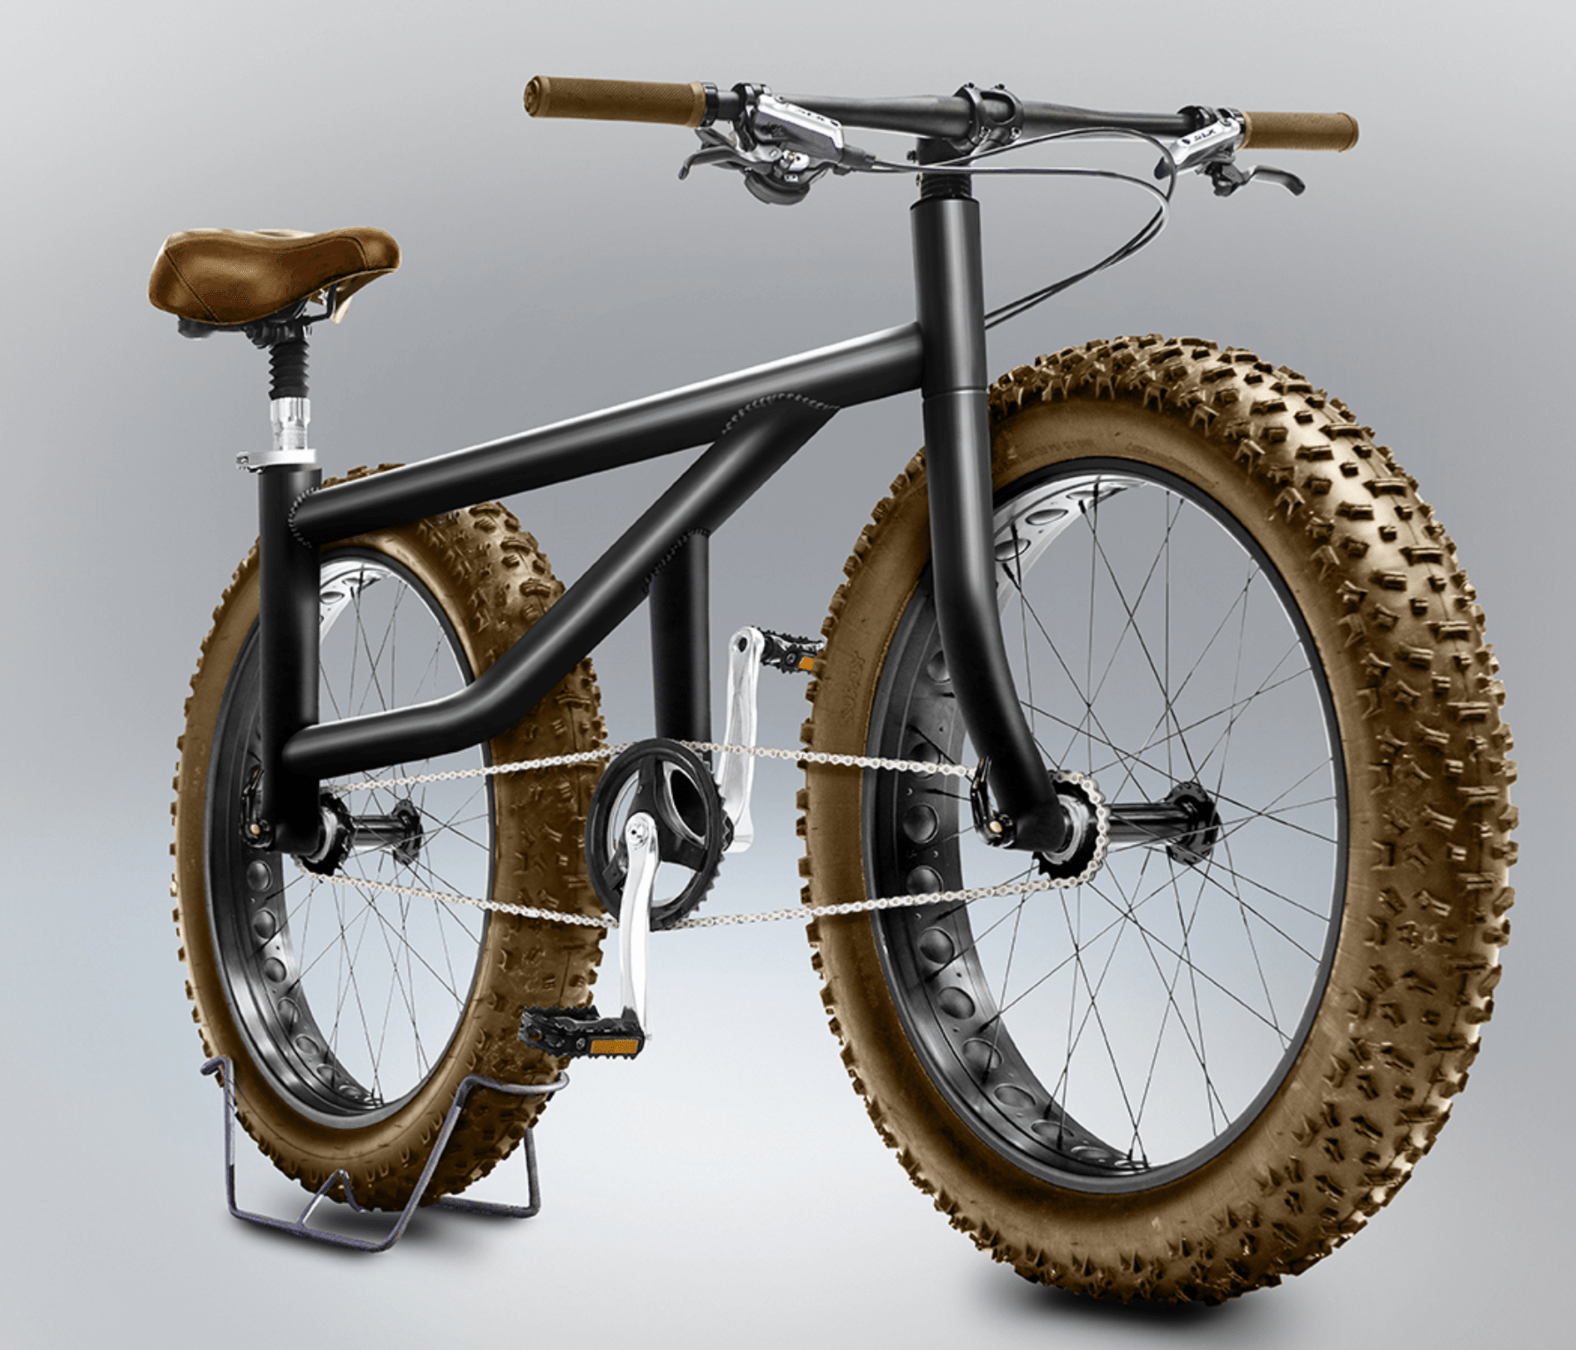
- Compact (minimal)
- Explanatory (roughly sufficient)
- Disentangled (independent factors)
- Interpretable (understandable by humans)
- Make subsequent problem solving easy
[See “Representation Learning”, Bengio 2013, for more commentary]
Auto-encoders explicitly aim for
\left\{
\begin{array}{l}
\\
\\
\end{array}
\right.
\left\{
\begin{array}{l}
\\
\\
\\
\end{array}
\right.
these may just emerge as well
Good representations are:
Feature reconstruction
Features
Reconstructed Features
$$x$$
$$\hat{x}$$
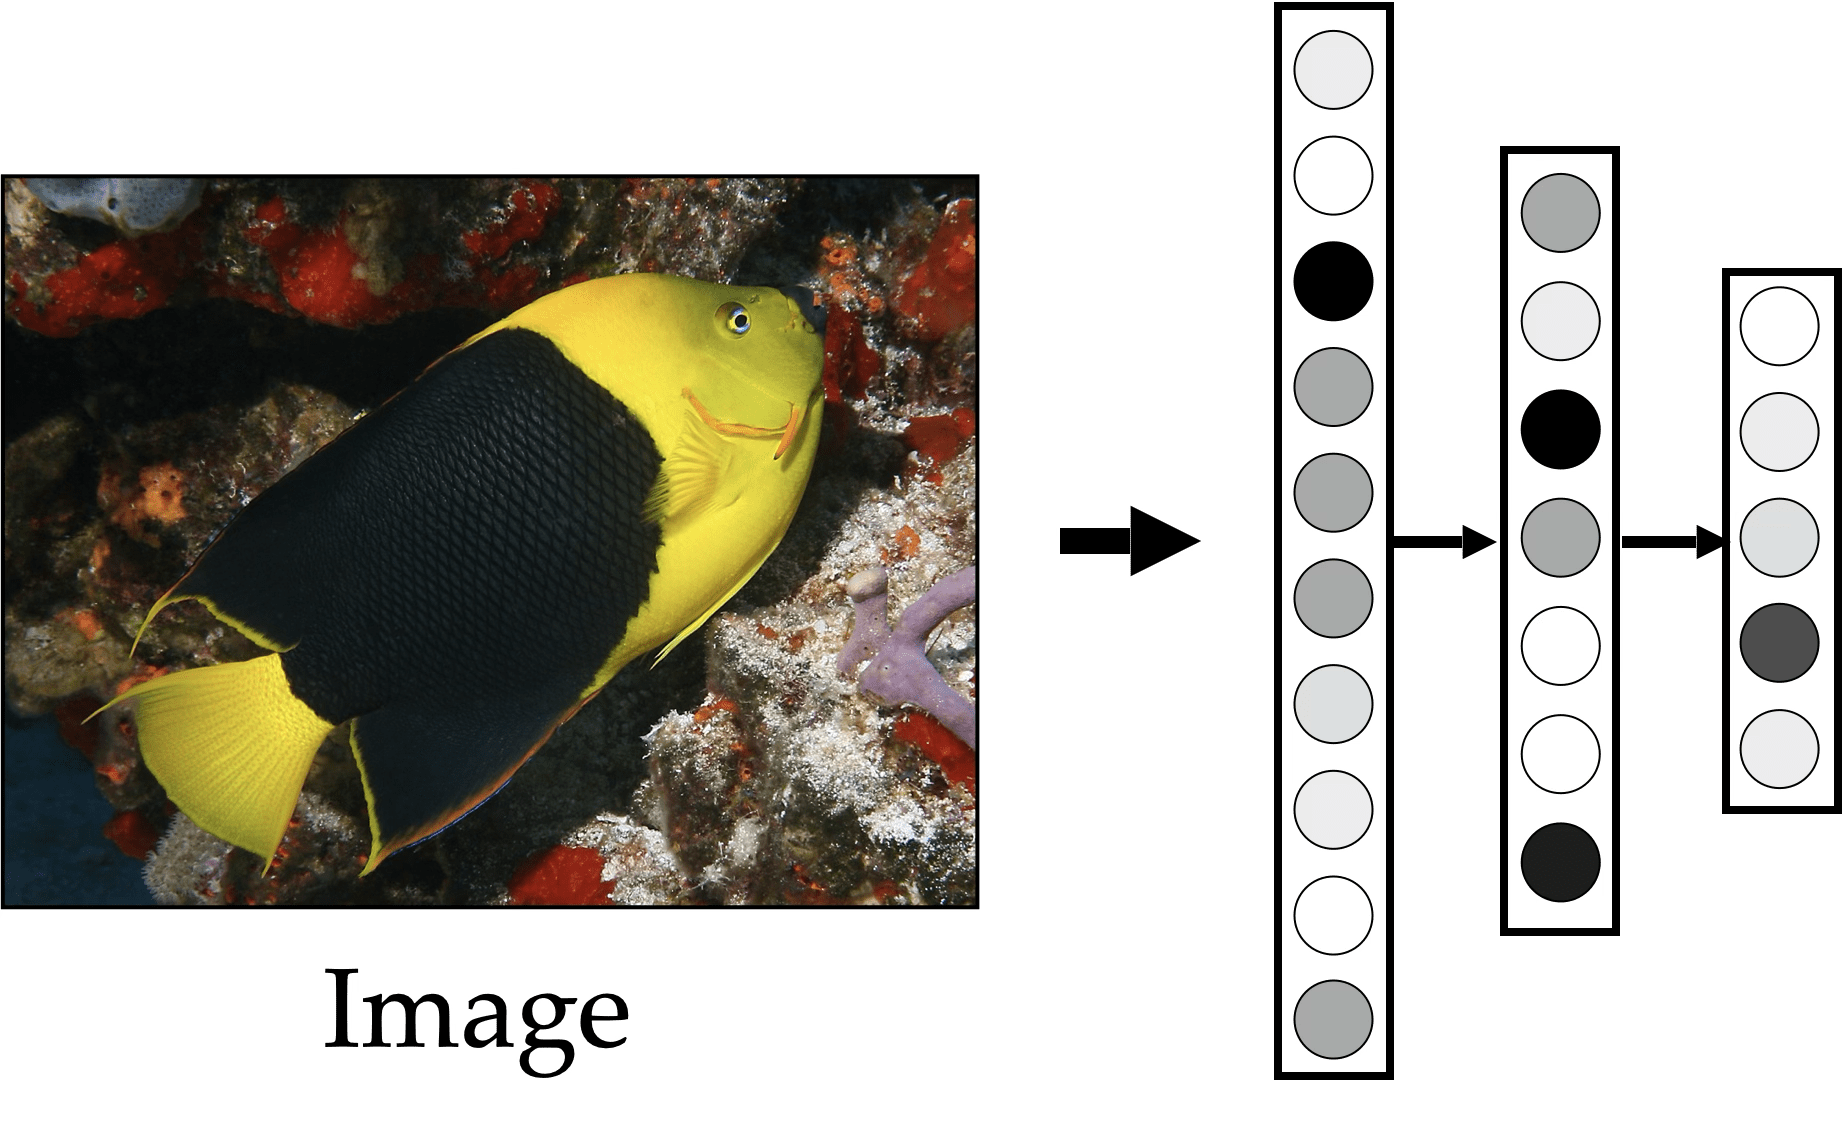
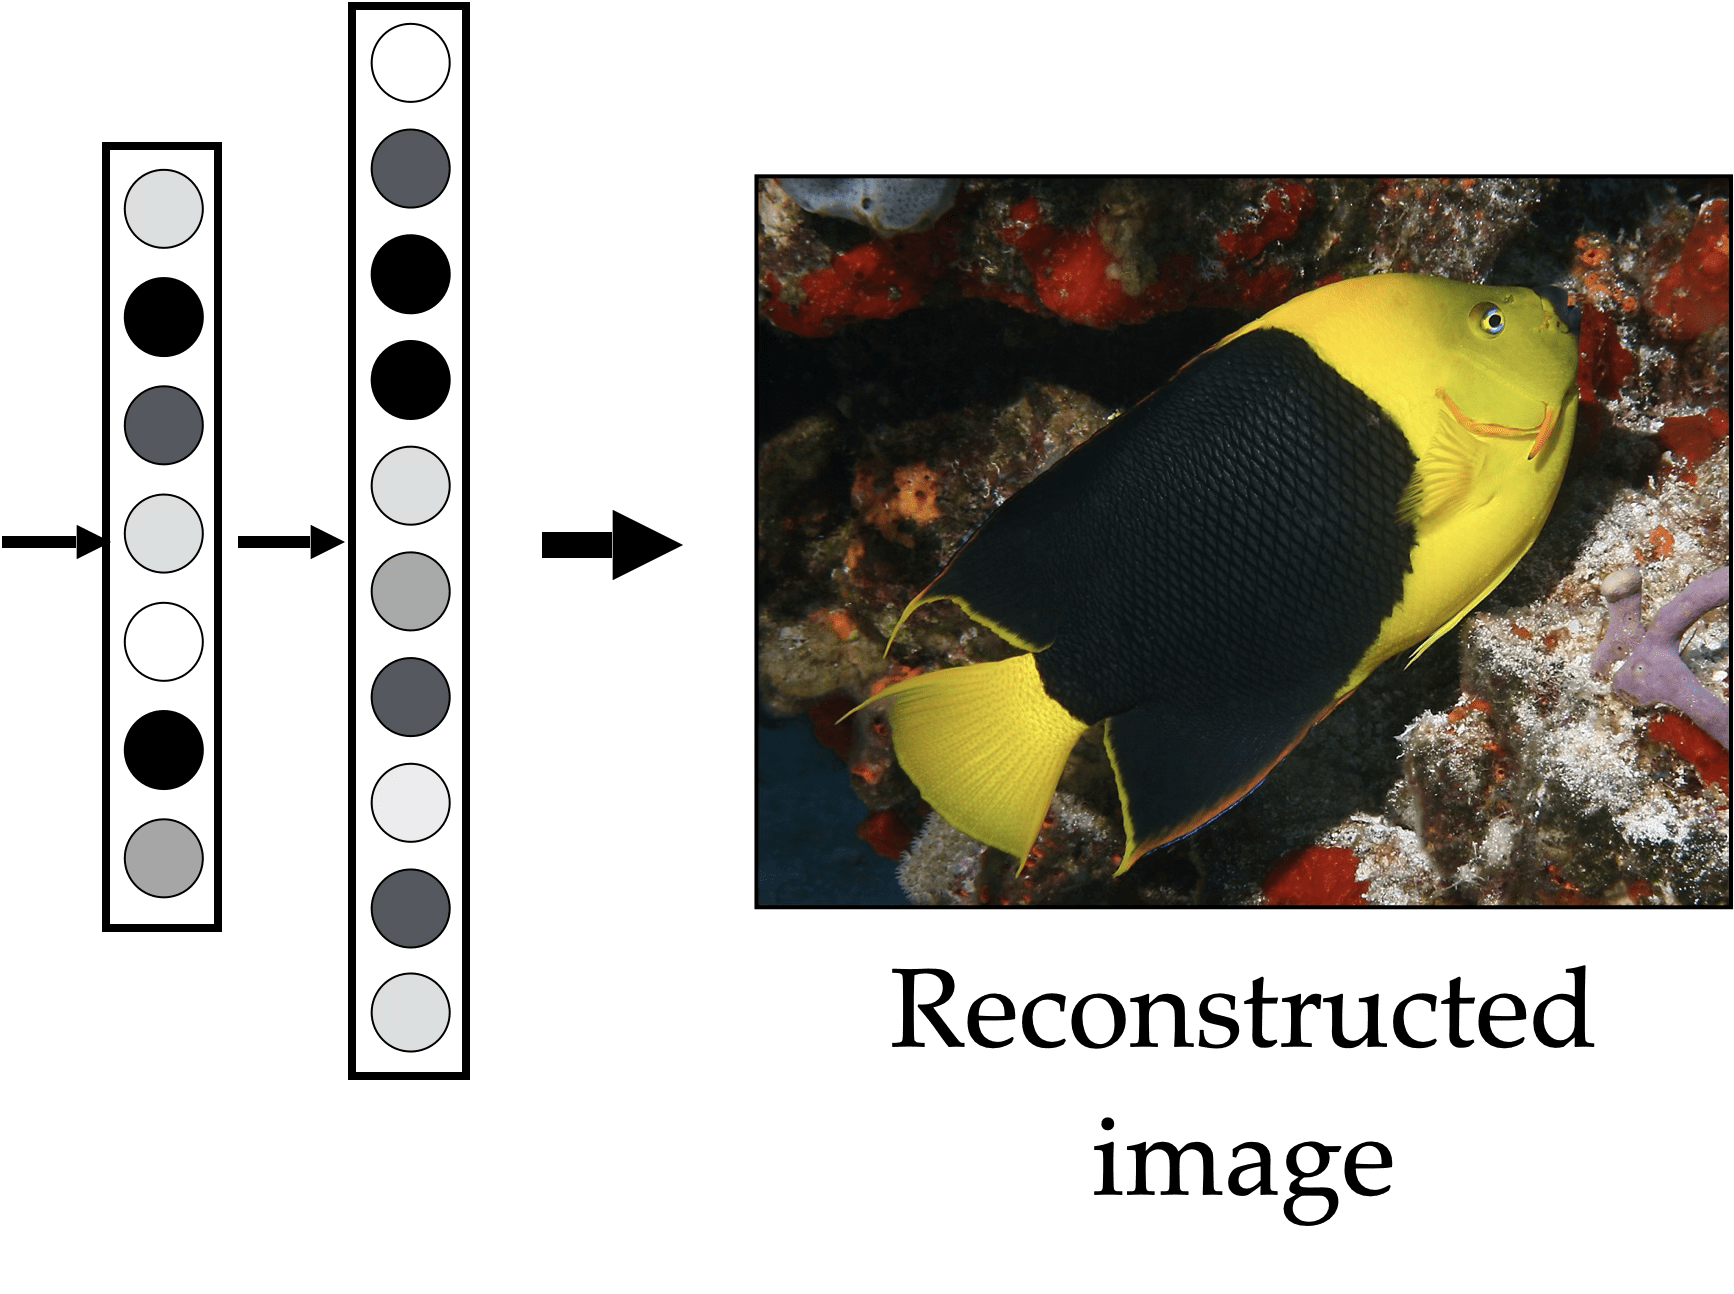
Auto-encoder
"What I cannot create, I do not understand." Feynman
compact representation/embedding
Auto-encoder
\underbrace{\hspace{1cm}}
\underbrace{\hspace{1cm}}
encoder
decoder
bottleneck
Auto-encoder
x
\tilde{x}=\text{NN}(x;W)
\min_{W} ||x - \tilde{x}||^2
Data space:
(high dimensional, irregular)
Encoder
Decoder
Representation space
(low dimensional, regular)
[Typically, encoders can serve as a translator to get "good representations", whereas decoders can serve as "generative models"]
[Vincent et al, Extracting and composing robust features with denoising autoencoders, ICML 08]
It can be easy to "cheat" with auto-encoders
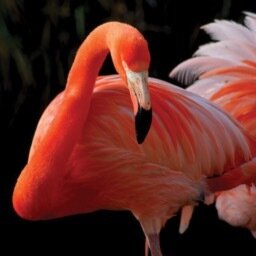
[Steck 20, Zhang et al 17]
decoder
encoder
the reconstruction error is fine
but not very useful
$$\hat{x}$$
$${x}$$
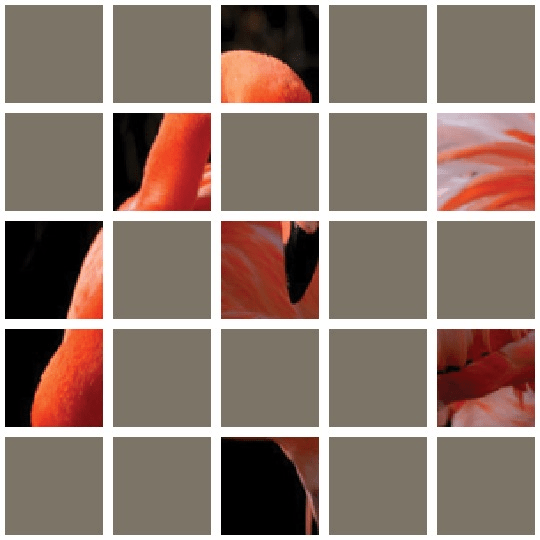
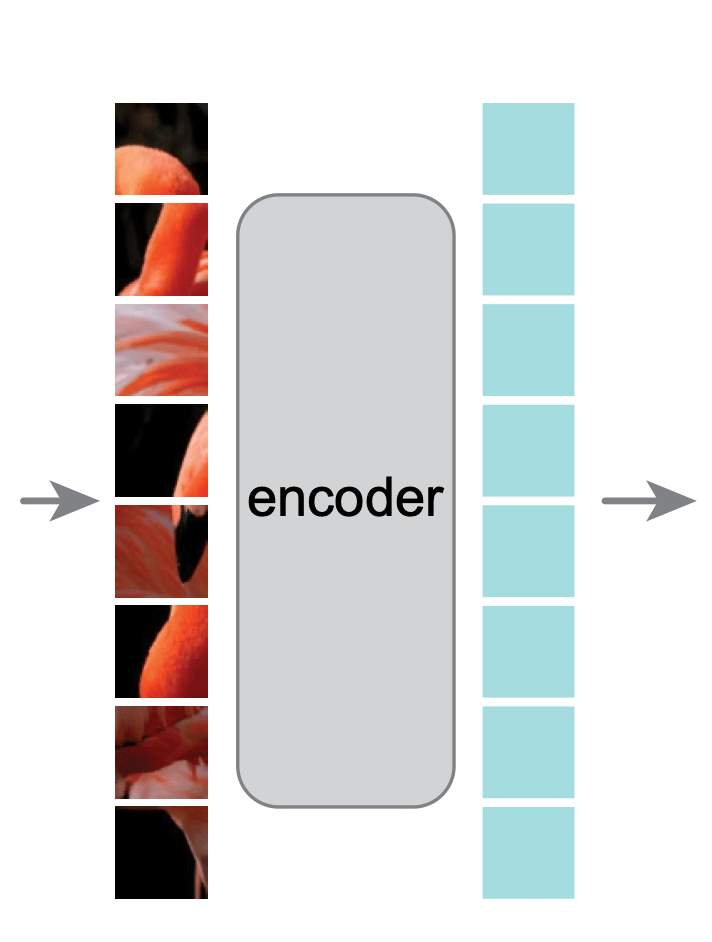
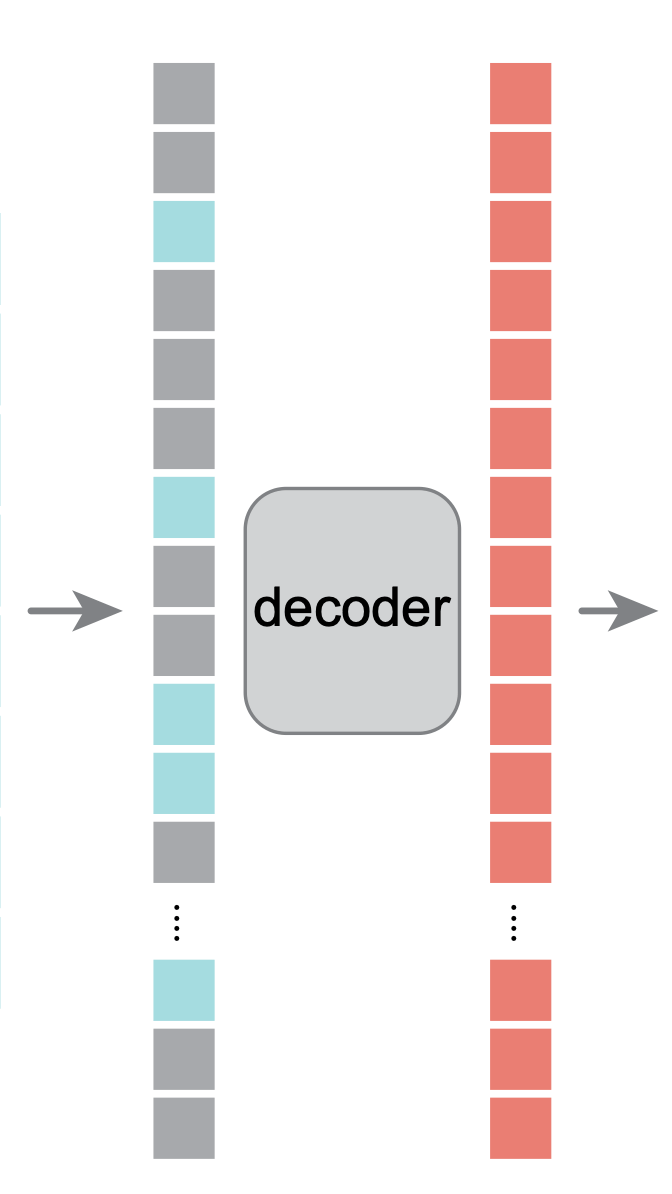
Partial feature reconstruction
Partial
Features
Other Partial Features
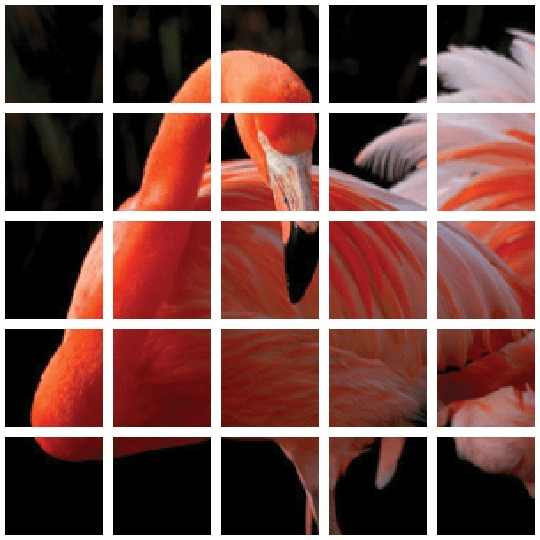
Hard reconstruction forces understanding.
Masked Auto-Encoder (Vision)
[He et al., MAE, 2021]
[Zhang, Isola, Efros, ECCV 2016]
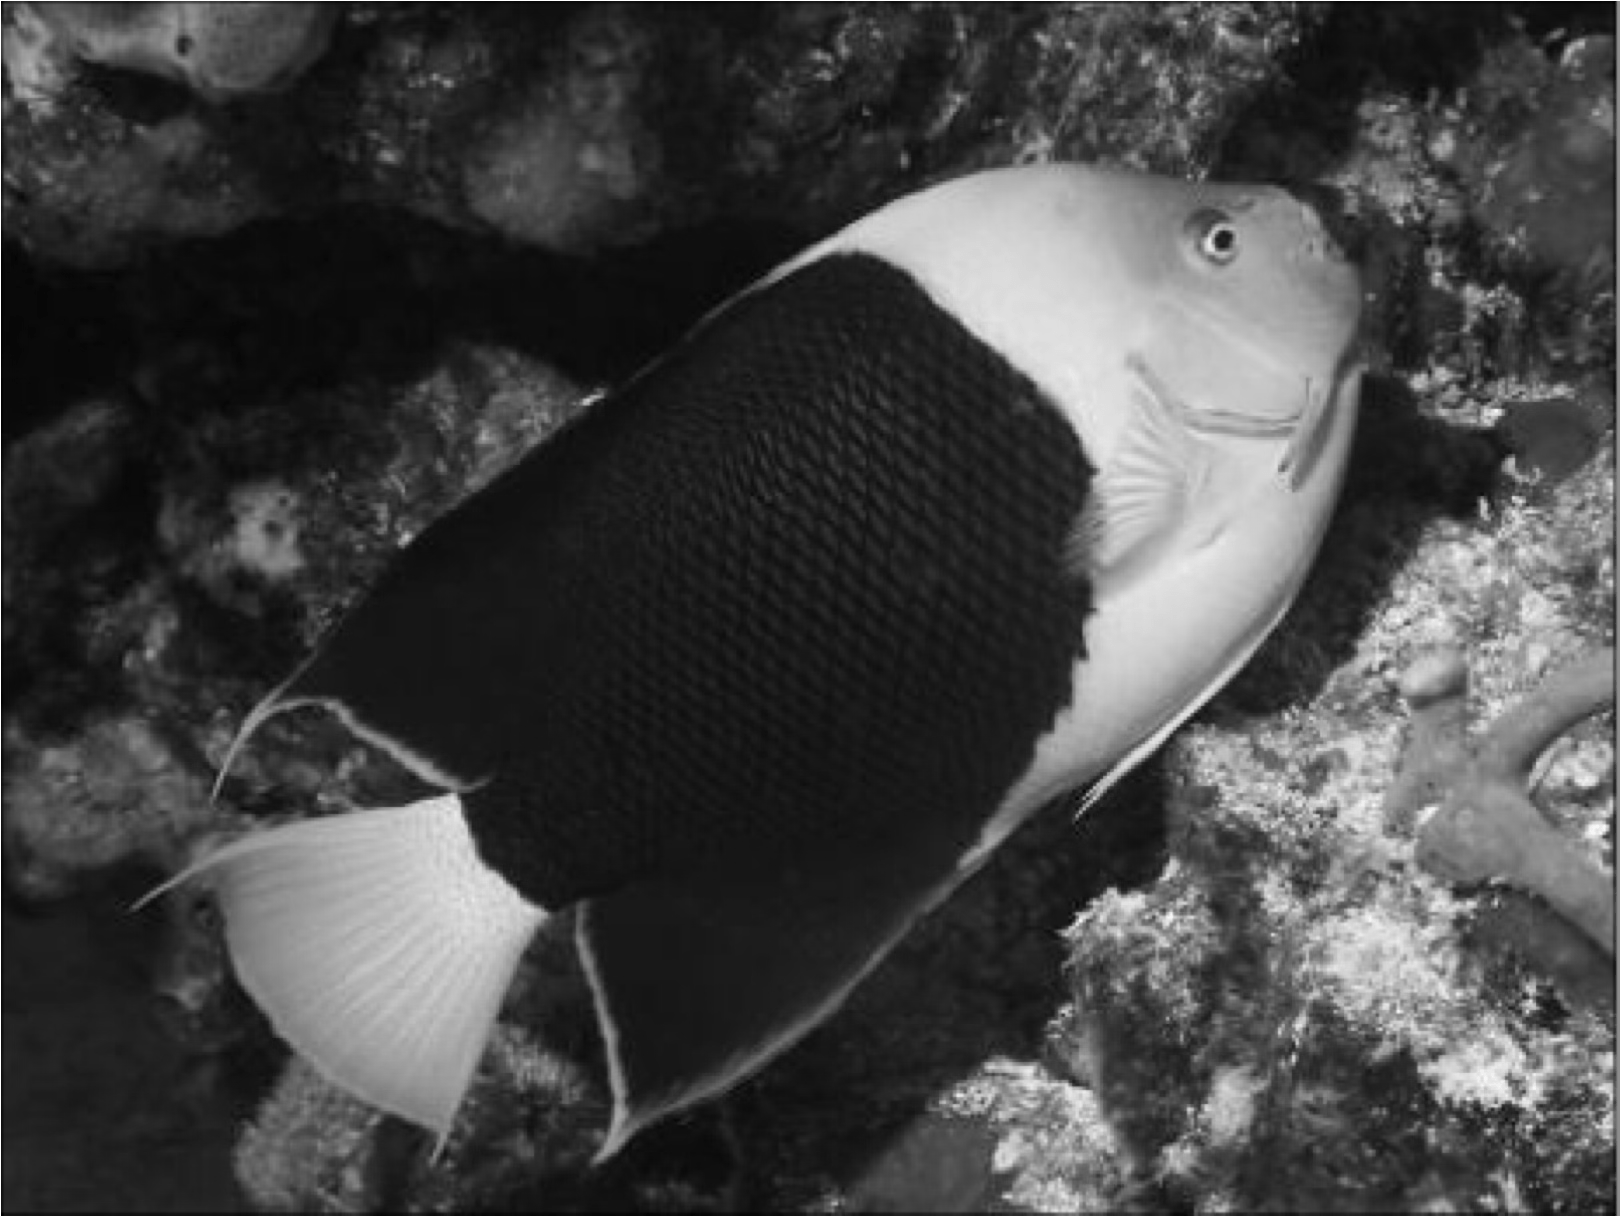
e.g. masking the color
Masking channels
predict color from gray-scale
[Zhang, Isola, Efros, ECCV 2016]
Masking channels
Reconstruction works across domains
Medical imaging
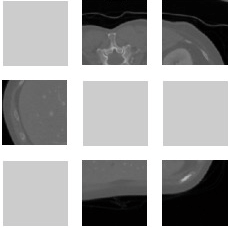
scan patches
3D geometry
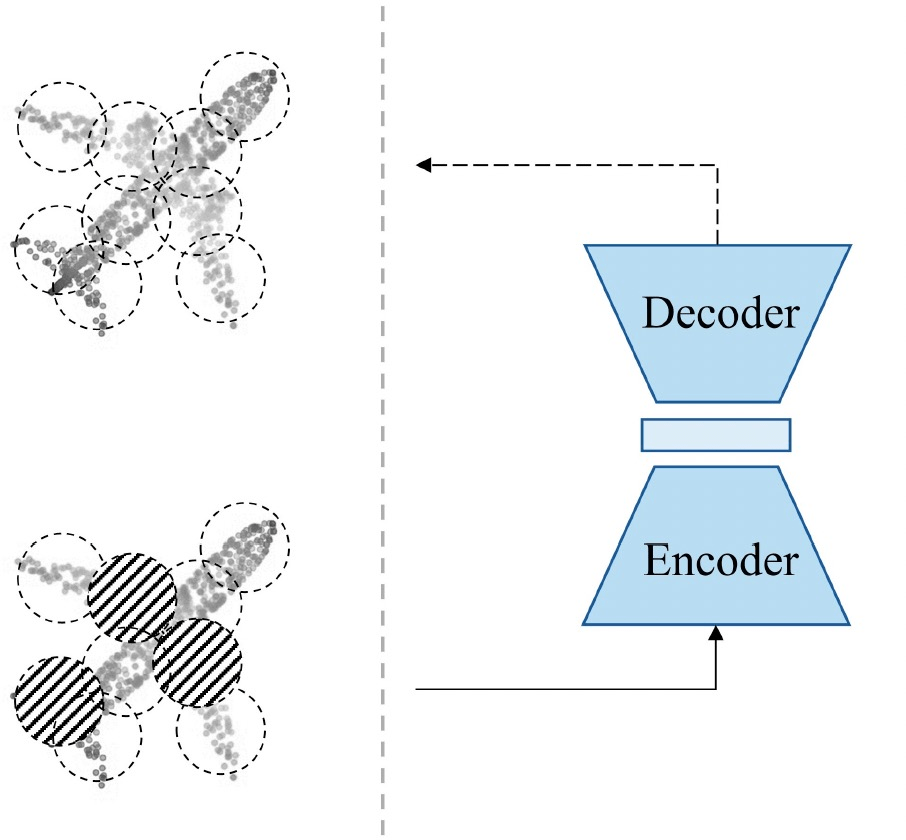
points or
surfaces
Audio
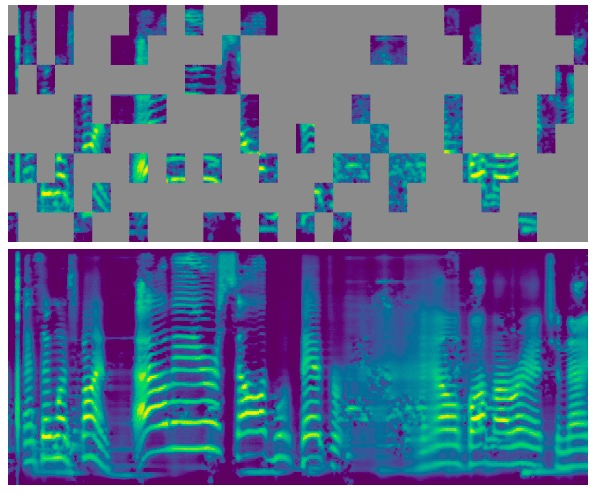
spectrogram
patches
Graphs
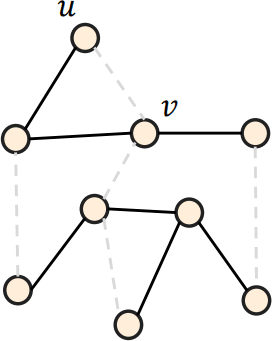
links or
node features
Robotics
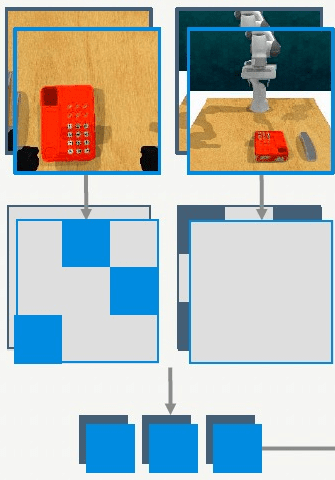
camera
frames
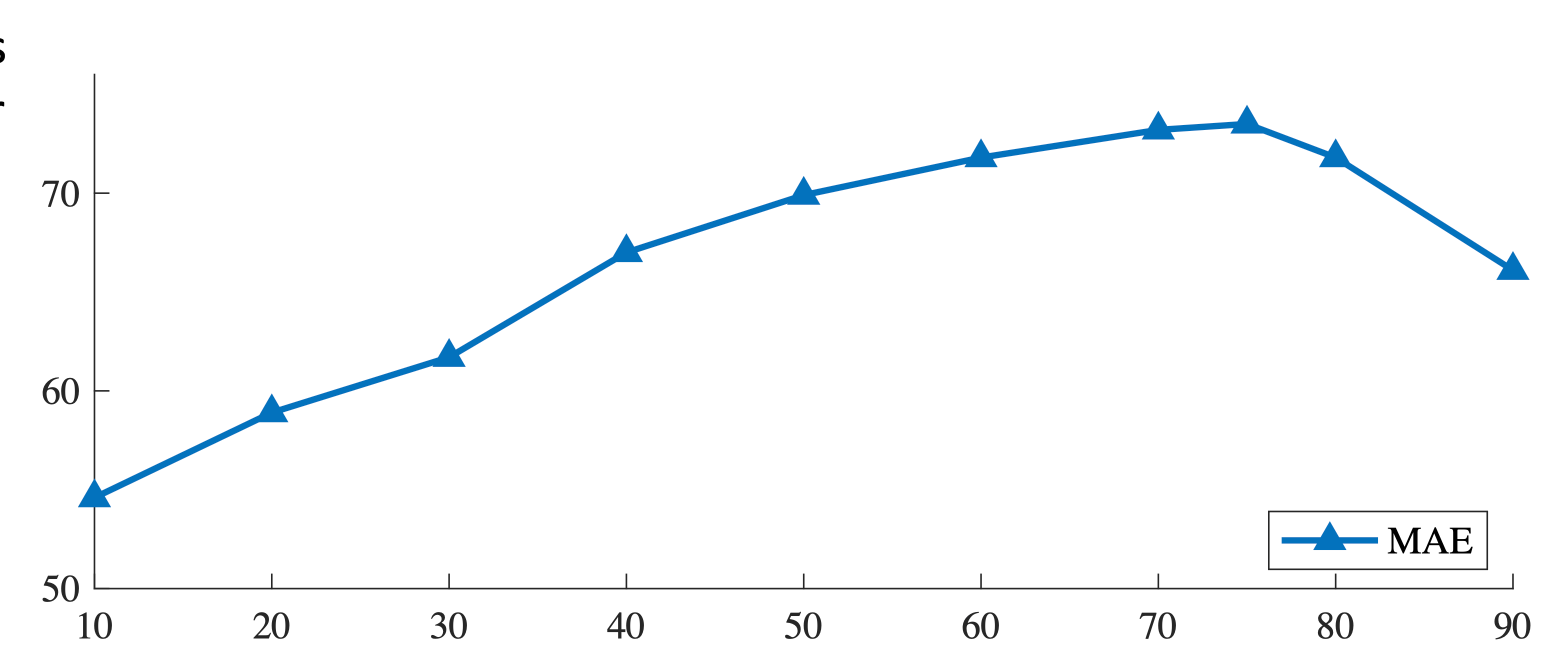
masking ratio
transfer accuracy
masking ~75% is
optimal for images
How much should we hide?
95% masked
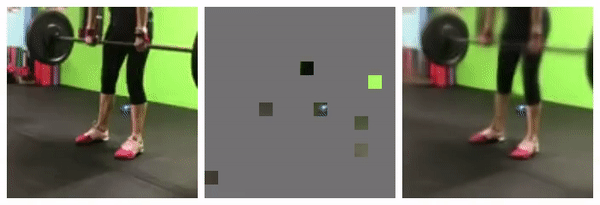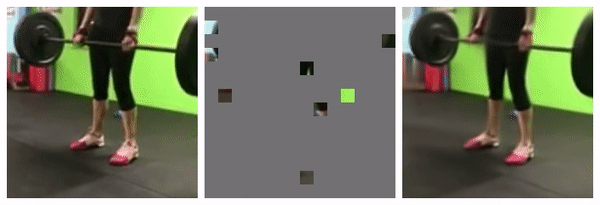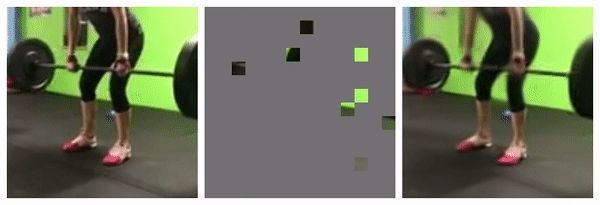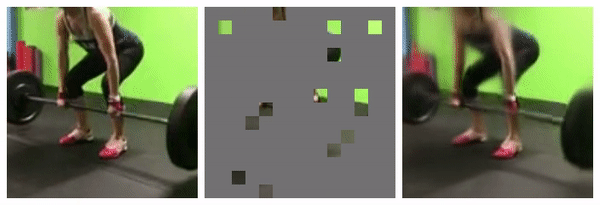
Similar empirical studies show ~15% as optimal for languages, and ~95% for videos
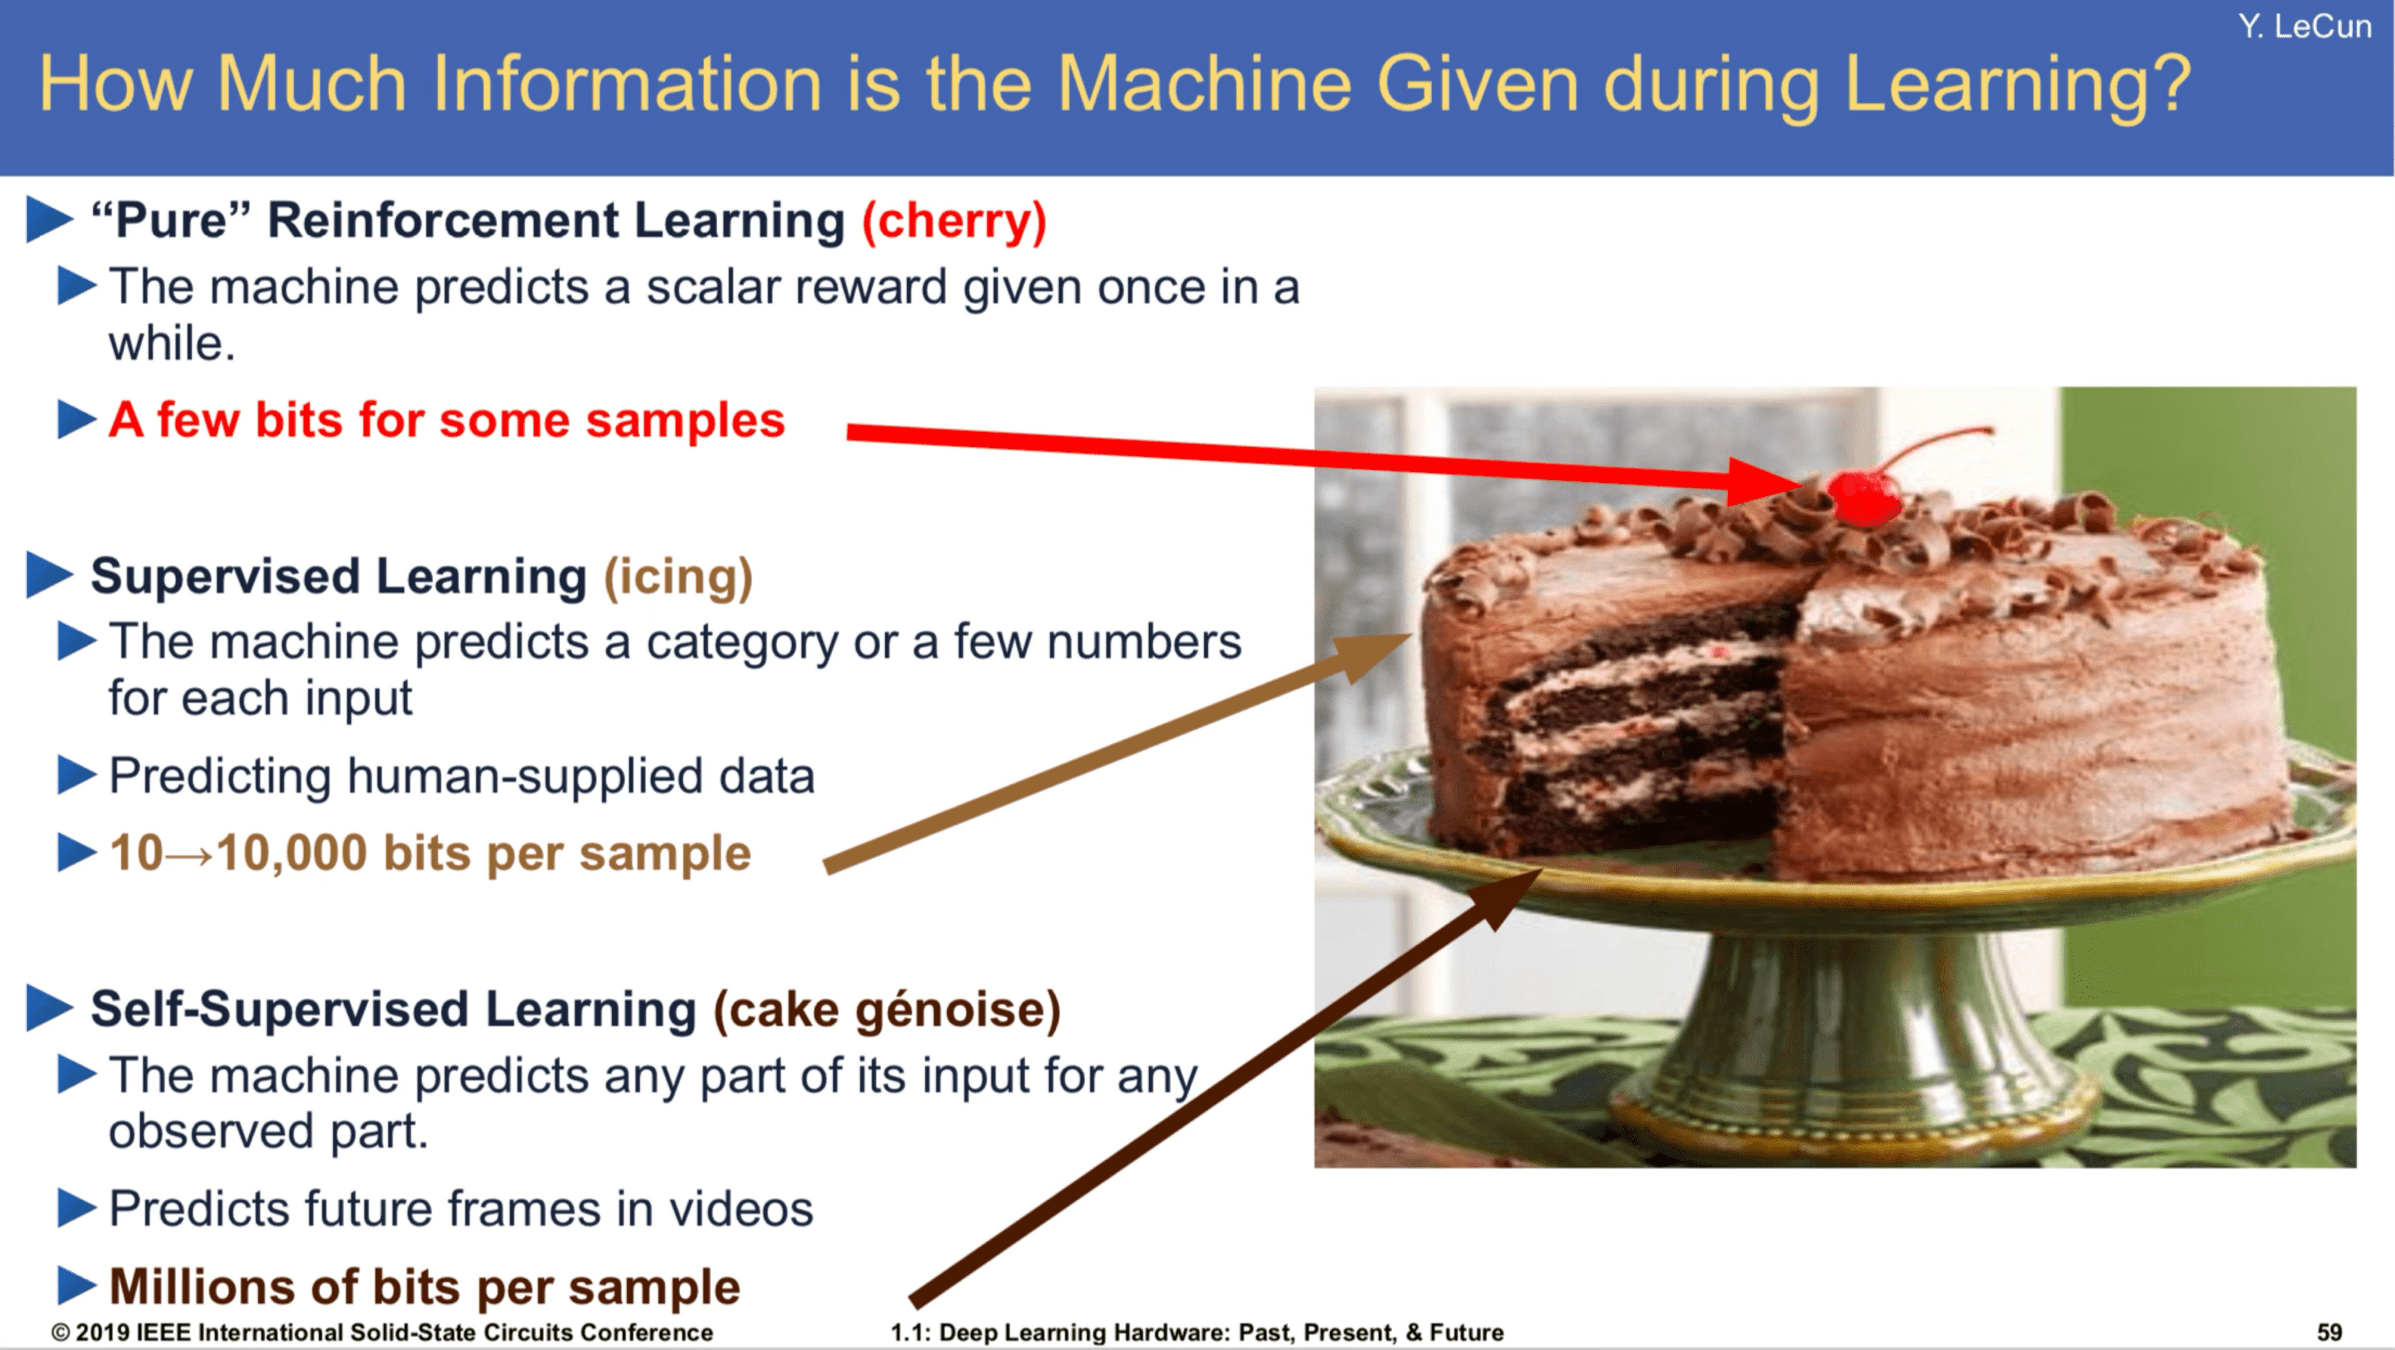
[Slide Credit: Yann LeCun]
Outline
- Neural networks are representation learners
- Auto-encoders and self-supervised learning
- Word embeddings
- Multi-modality
Large Language Models (LLMs) are trained in this self-supervised way:
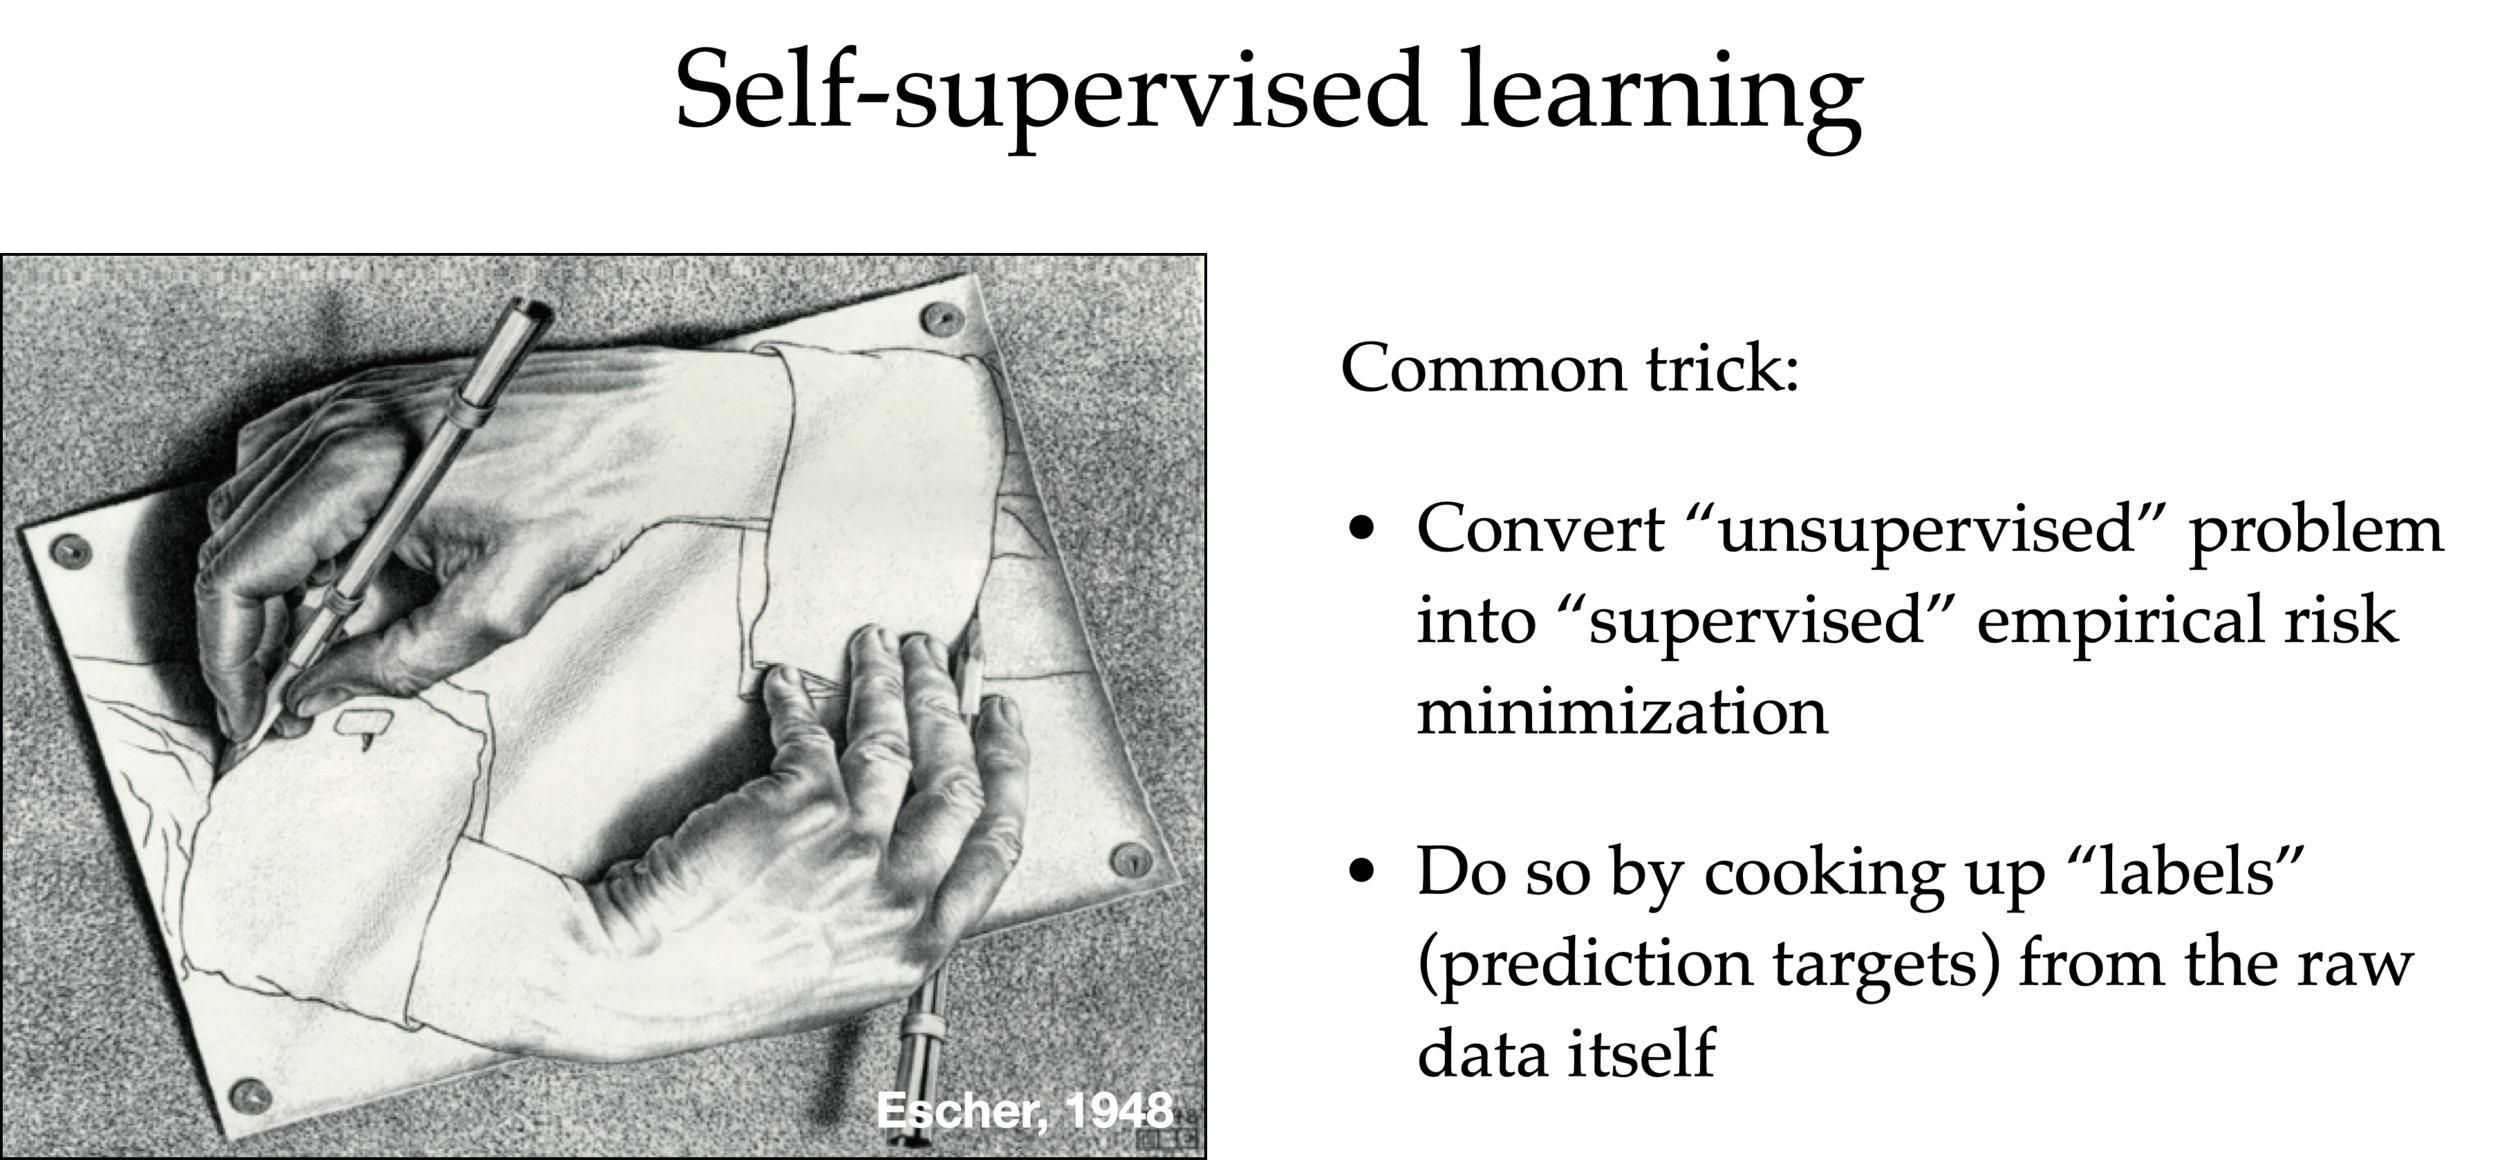
- Scrape the internet for plain texts.
- Cook up “labels” from these texts.
- Use the unhidden part to predict the hidden label.
"To date, the cleverest thinker of all time was Isaac."
feature
label
To date, the
cleverest
\dots
To date, the cleverest
thinker
To date, the cleverest thinker
was
\dots
\dots
\dots
To date, the cleverest thinker of all time was
Isaac
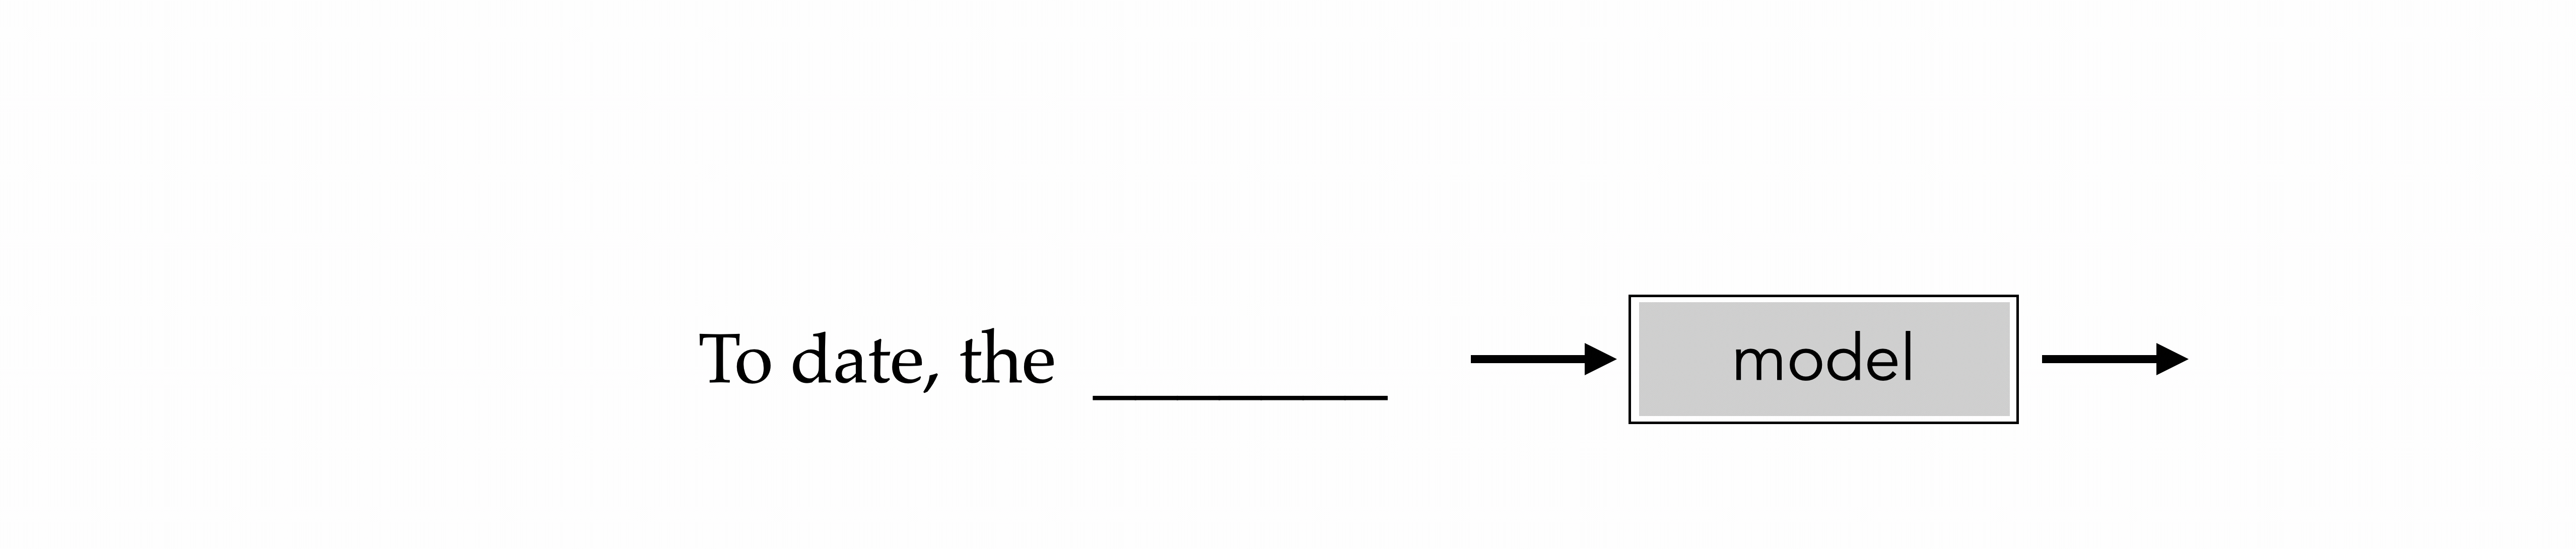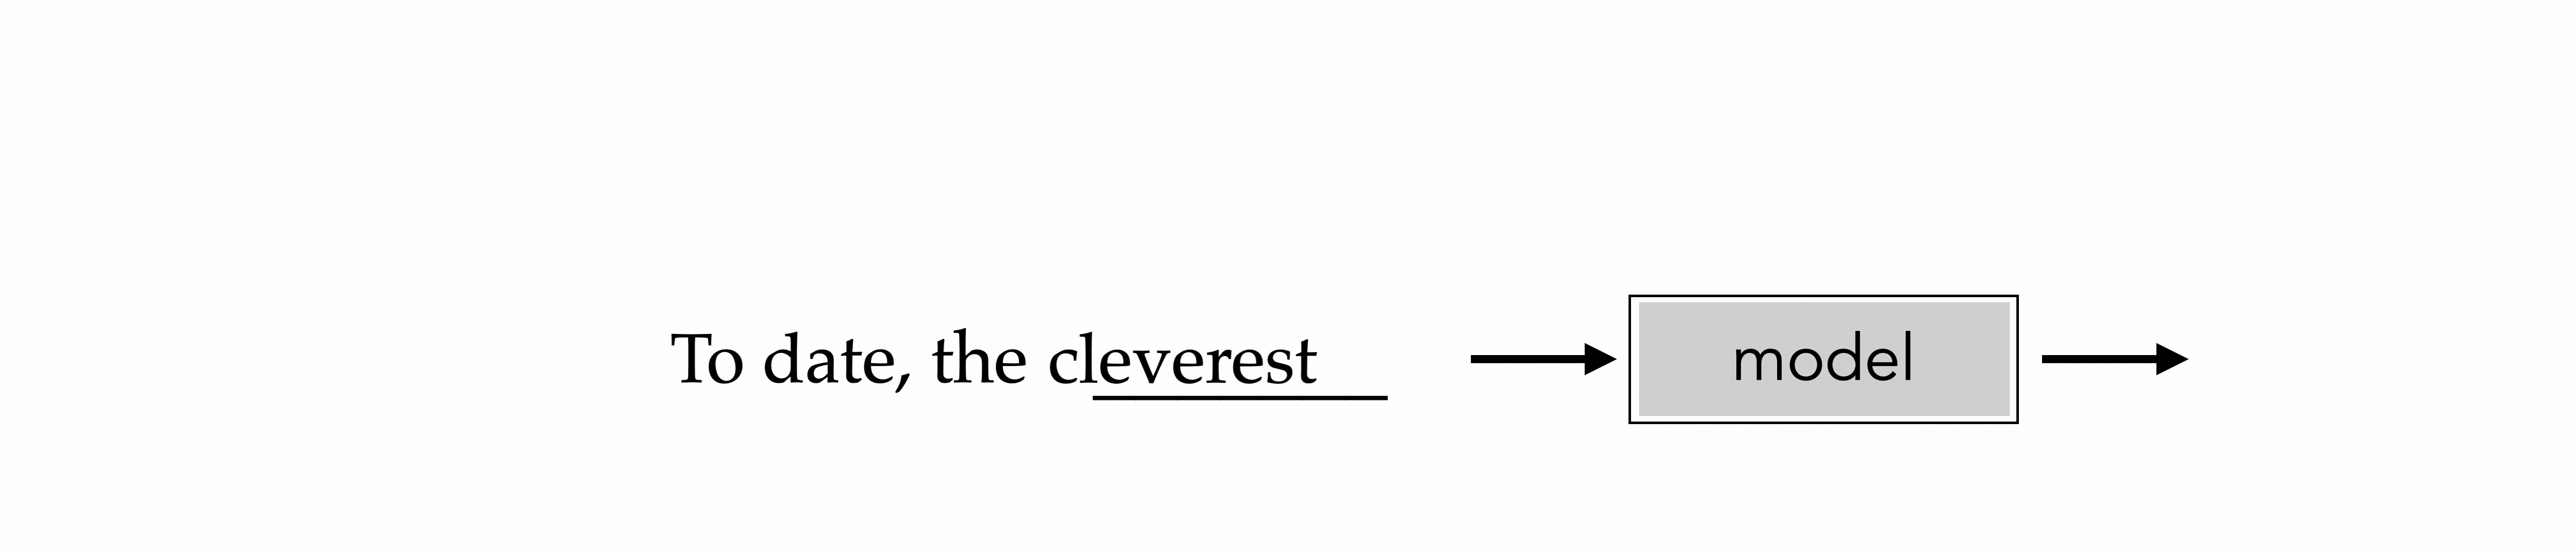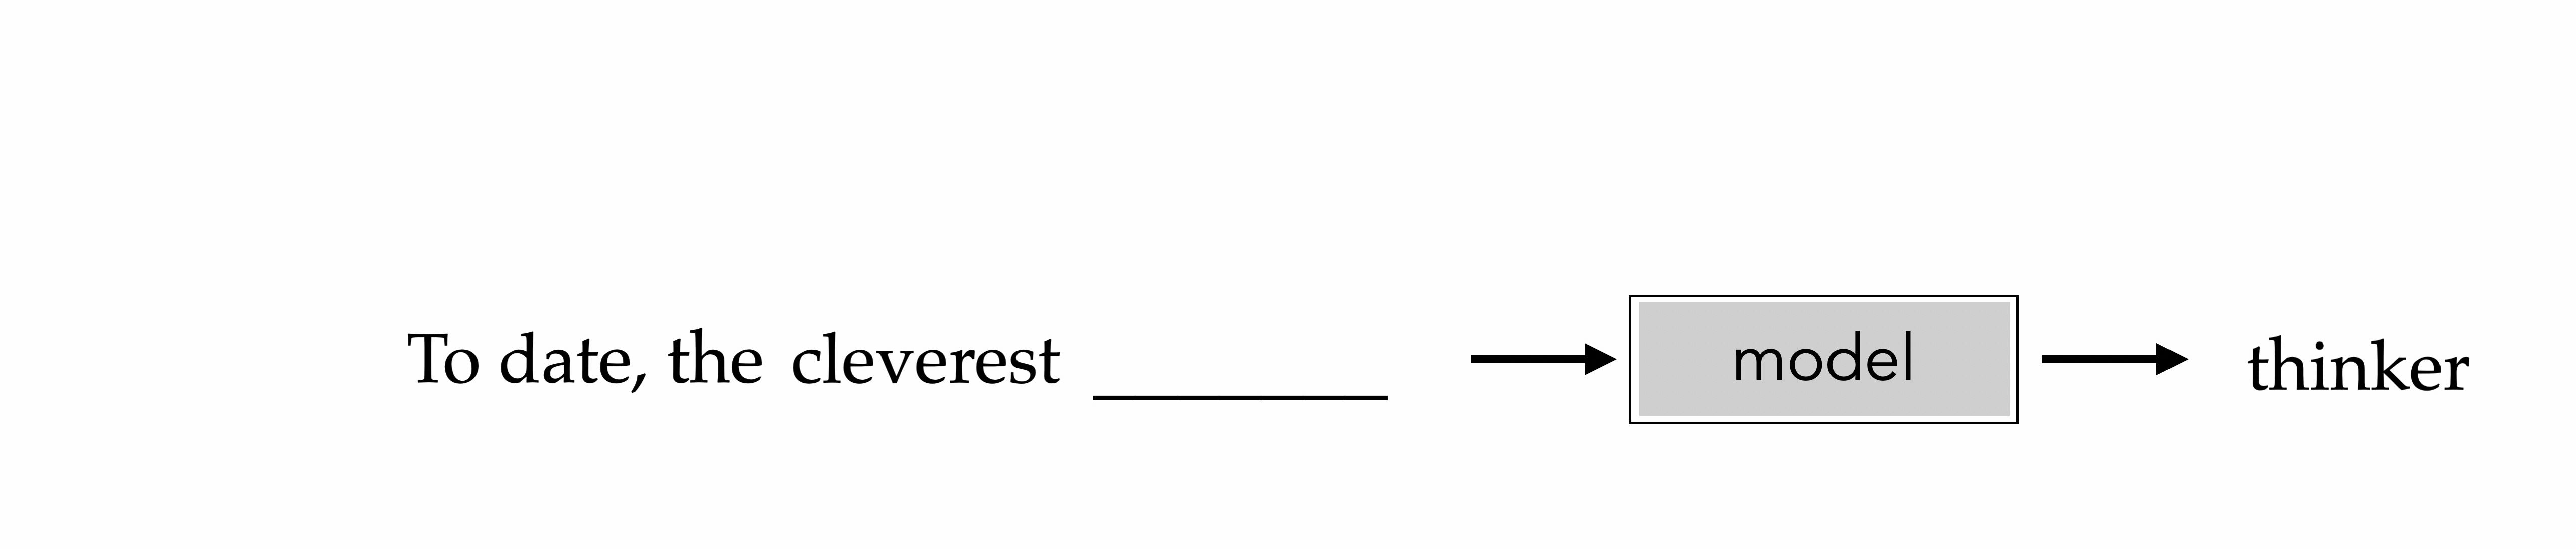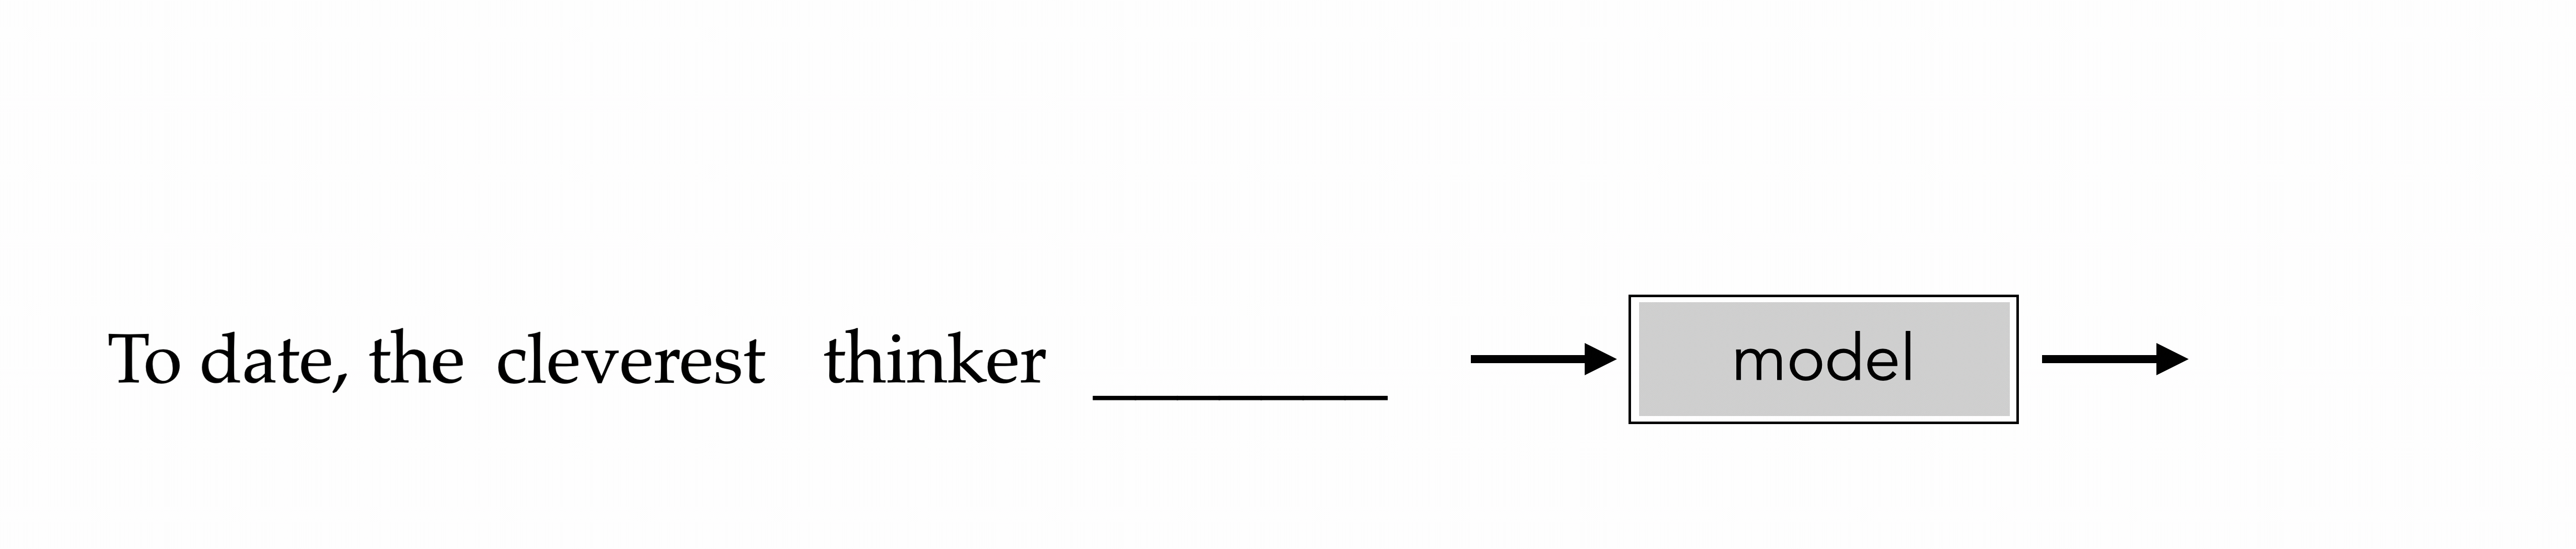
[video edited from 3b1b]
Word embedding
dot-product similarity
[video edited from 3b1b]
dot-product similarity
For now, let's look at how good embeddings enable "soft" dictionary look-up:
dict_en2fr = {
  "apple" : "pomme",
  "banana": "banane",
  "lemon" : "citron"}
A good word embedding space is equipped with sensible dot-product similarity
Key
Value
apple
pomme
\(:\)
banane
banana
\(:\)
citron
lemon
\(:\)
dict_en2fr = {
  "apple" : "pomme",
  "banana": "banane",
  "lemon" : "citron"}

query = "lemon"
output = dict_en2fr[query]
apple
pomme
banane
citron
banana
lemon
Key
Value
lemon
\(:\)
\(:\)
\(:\)
Query
Output
citron
dict_en2fr = {
  "apple" : "pomme",
  "banana": "banane",
  "lemon" : "citron"}

query = "orange"
output = dict_en2fr[query]
Python would complain. 🤯
orange
apple
pomme
banane
citron
banana
lemon
Key
Value
\(:\)
\(:\)
\(:\)
Query
Output
???
What if we run
What if we run
But we can probably see the rationale behind this:
Query
Key
Value
Output
orange
apple
\(:\)
pomme
banana
\(:\)
banane
lemon
\(:\)
citron
dict_en2fr = {
  "apple" : "pomme",
  "banana": "banane",
  "lemon" : "citron"}

query = "orange"
output = dict_en2fr[query]
0.1
pomme
0.1
banane
0.8
citron
+
+
0.1
pomme
0.1
banane
0.8
citron
+
+
via these merging percentages [0.1 0.1 0.8] made sense.
We put (query, key, value) in "good" embeddings in our human brains
such that "merging" the values
Query
Key
Value
Output
orange
apple
\(:\)
pomme
0.1
pomme
0.1
banane
0.8
citron
banana
\(:\)
banane
lemon
\(:\)
citron
+
+
orange
orange
0.1
pomme
0.1
banane
0.8
citron
+
+
apple
banana
lemon
orange
0.8
0.1
0.1
pomme
banane
citron
+
+
Very roughly, the attention mechanism in transformers automates this process. We'll see the details next week.
Outline
- Neural networks are representation learners
- Auto-encoders and self-supervised learning
- Word embeddings
- Multi-modality

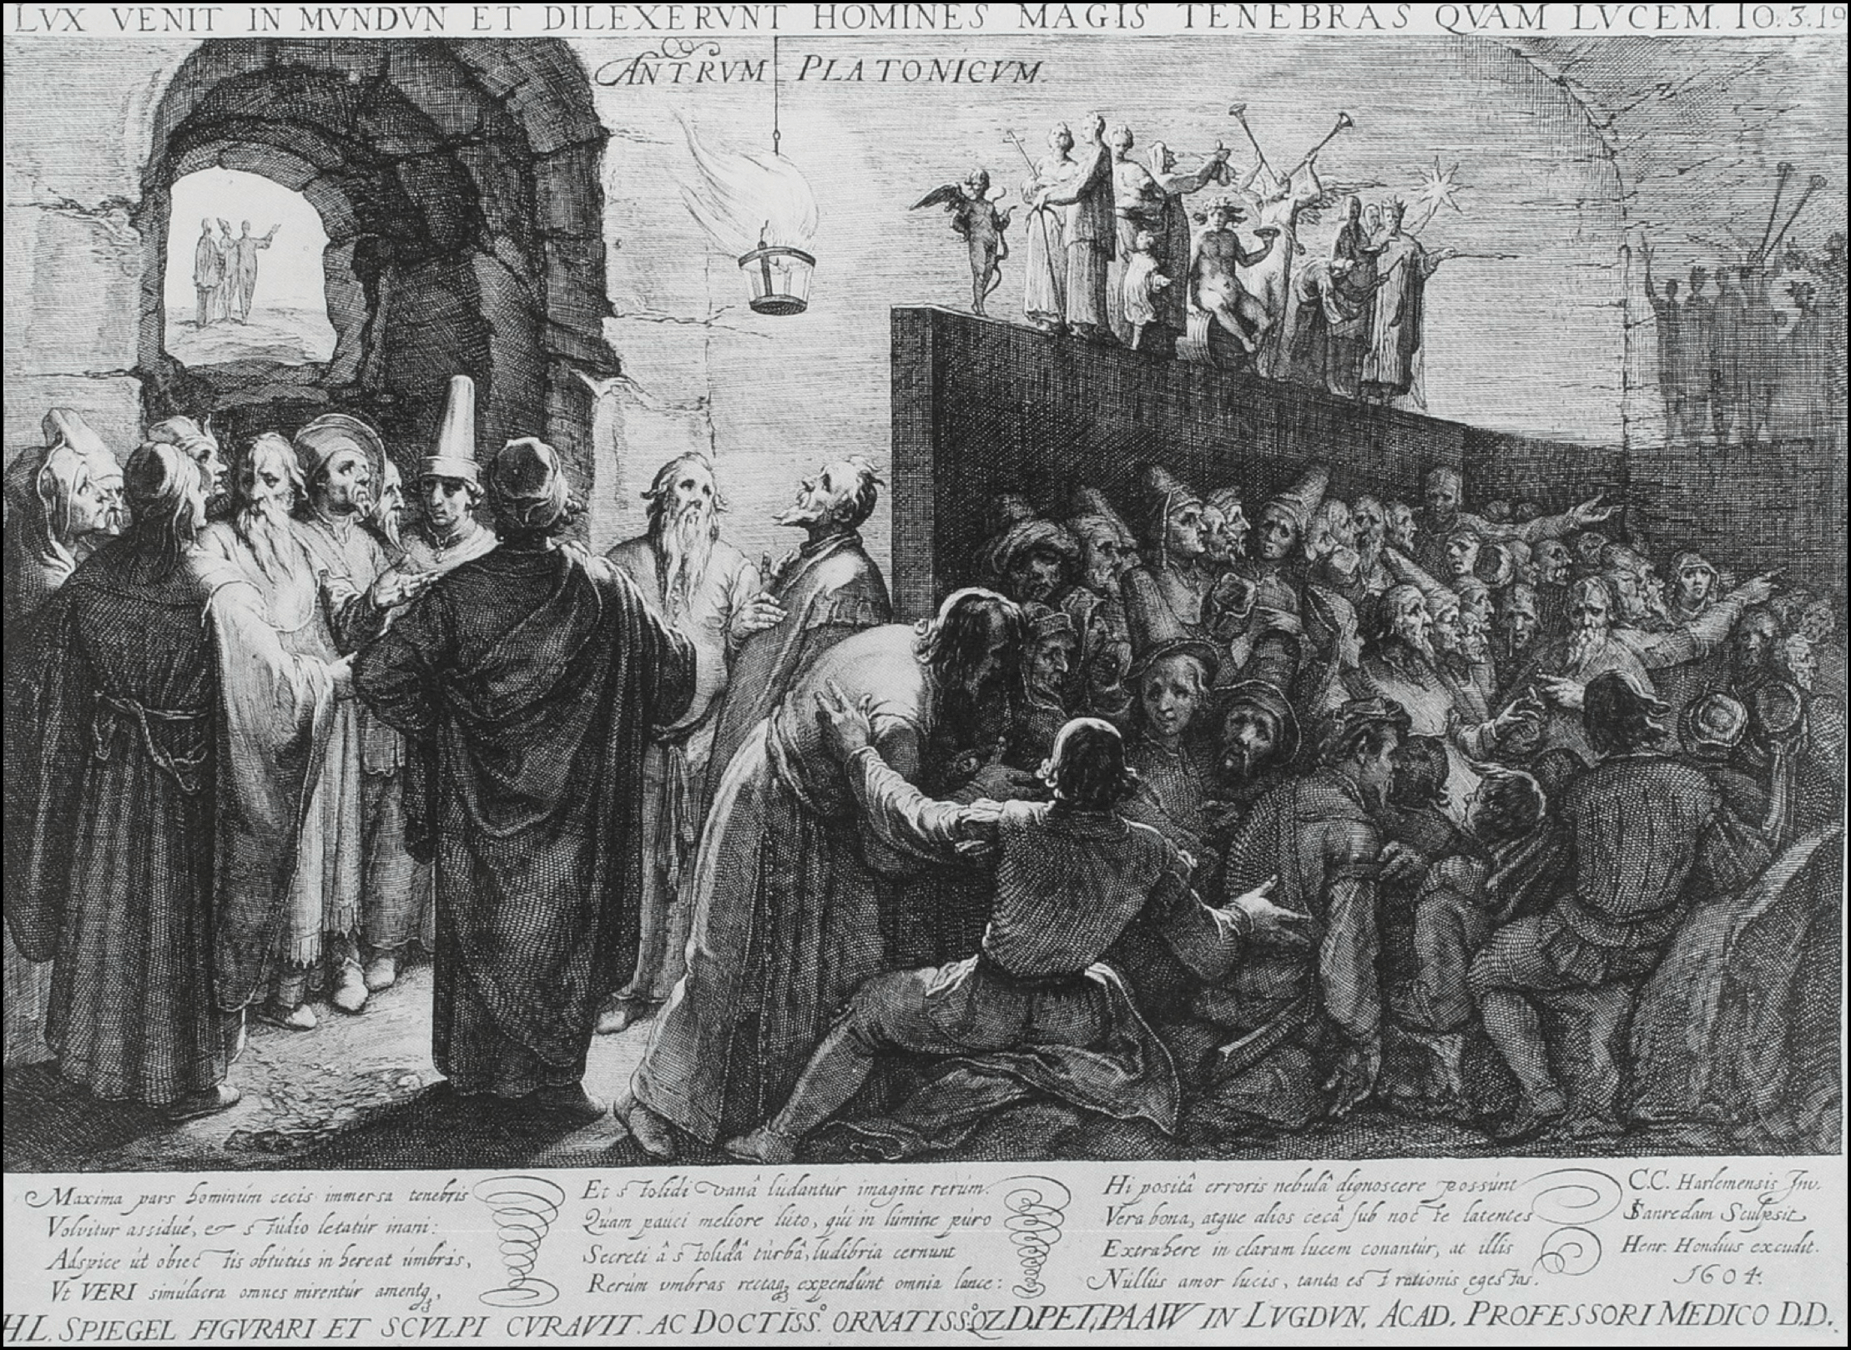
[ images credit: visionbook.mit.edu · top right: Plato's cave, Saenredam, 1604]
Plato's cave
Contrastive learning: SimCLR
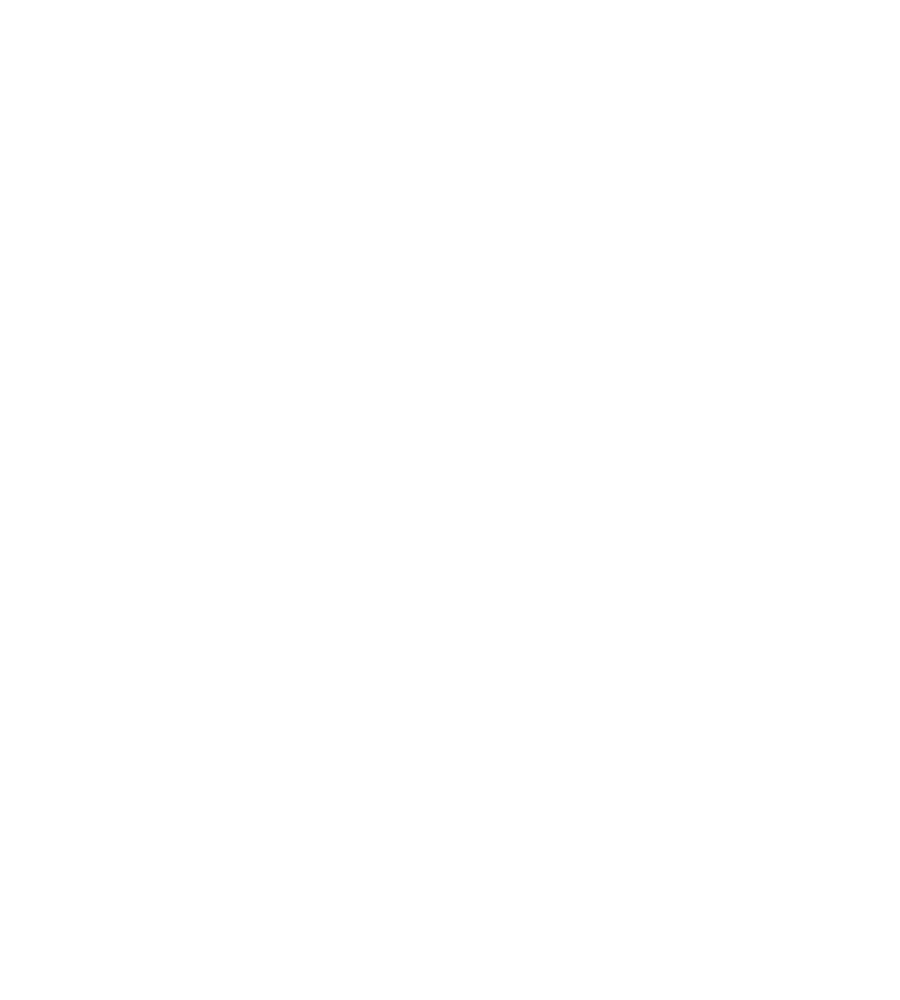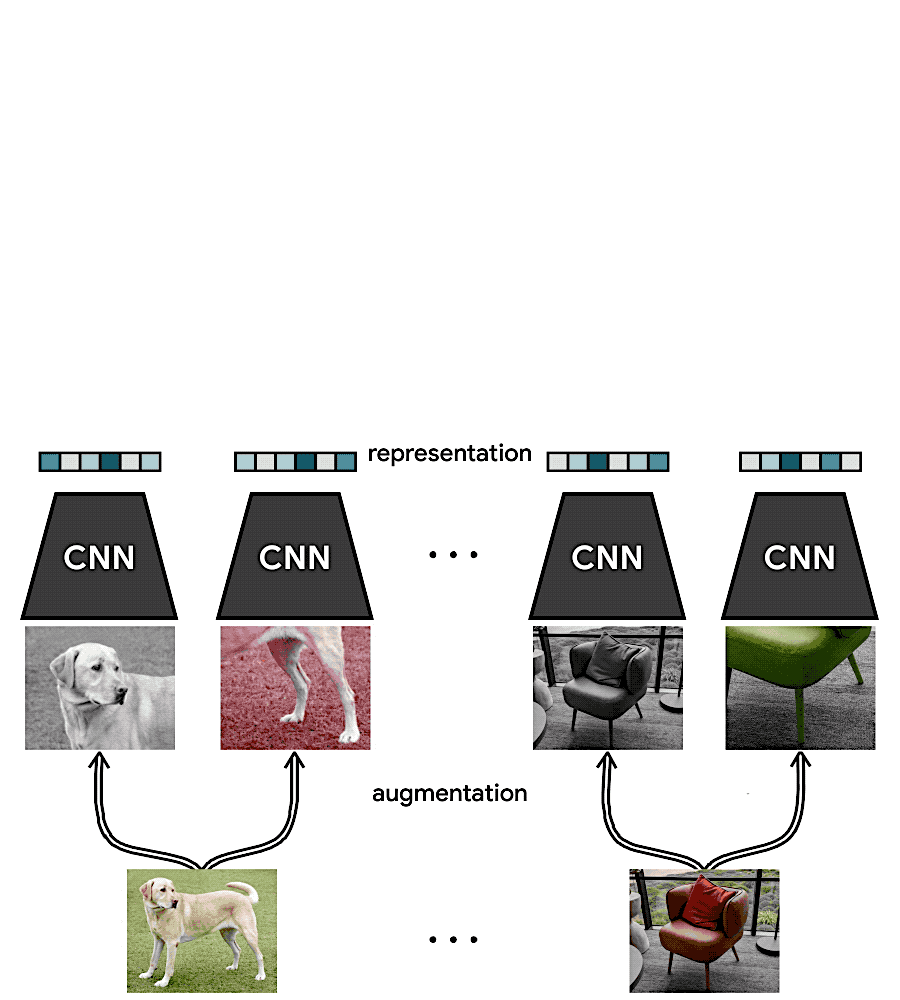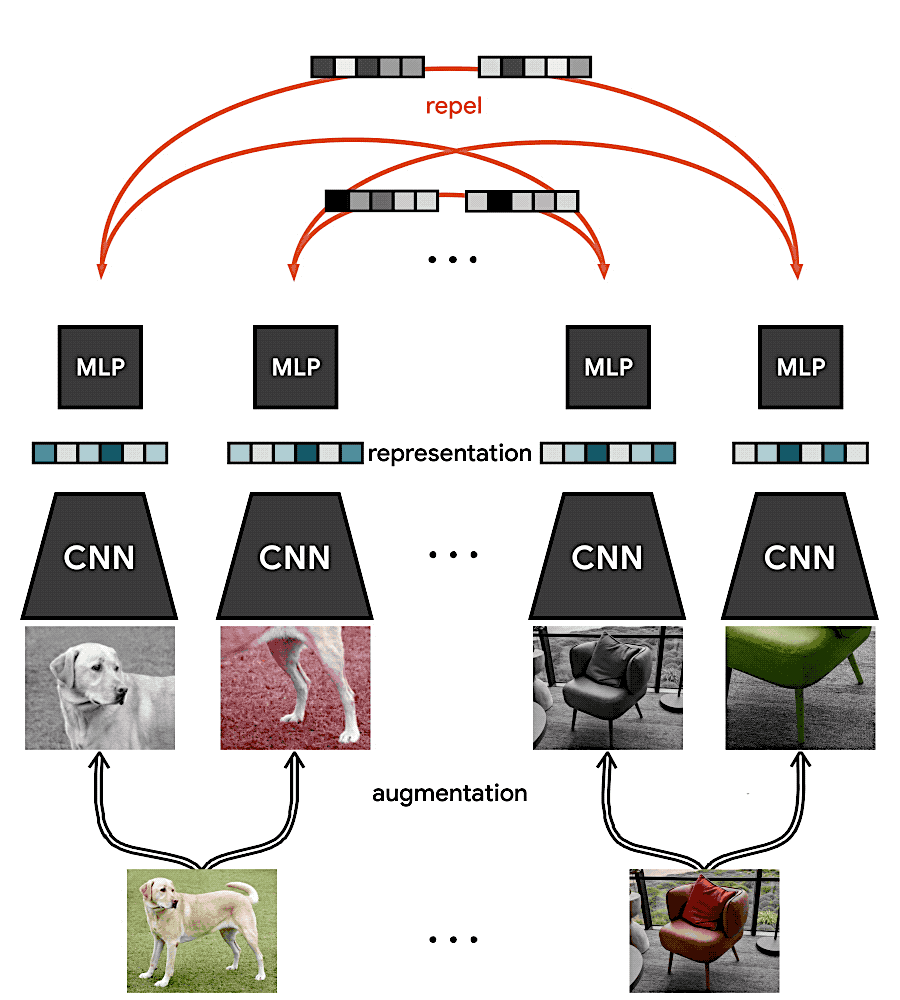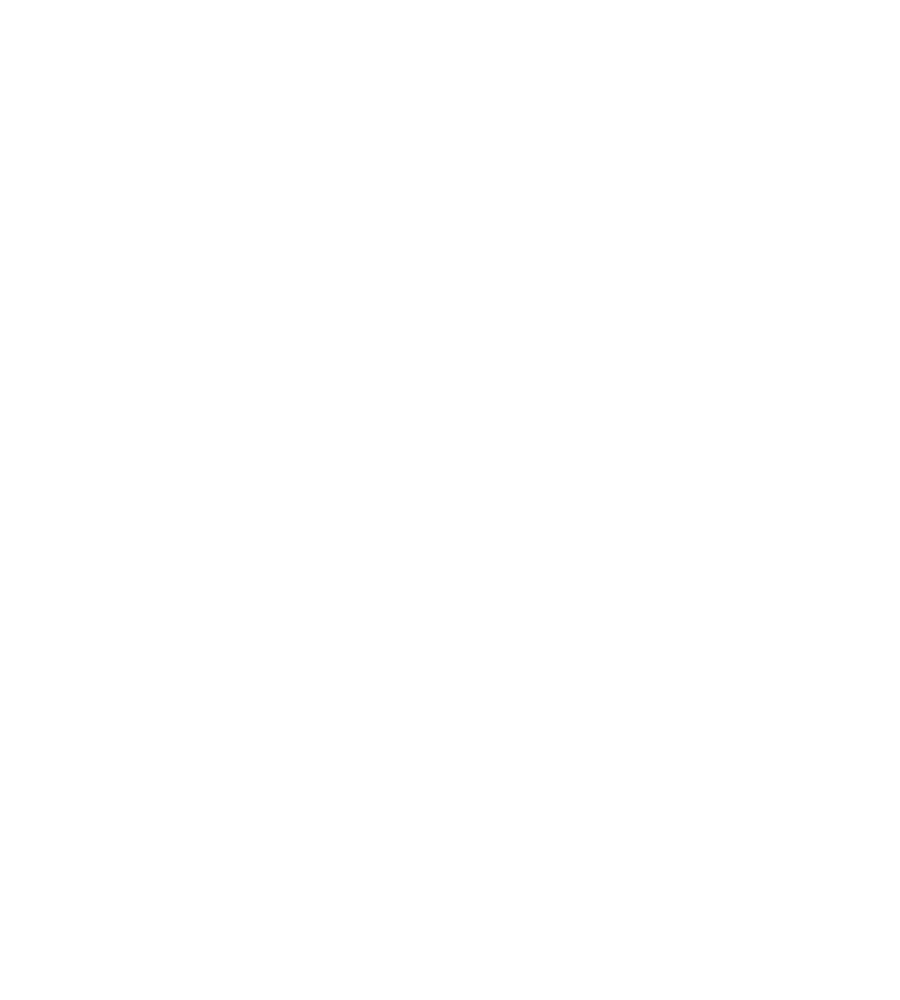
We take two random crops of the same image, with colors changed, and pull their representations together.
Crops from different images are pushed apart.
What we change, such as color, is what the representation learns to ignore.
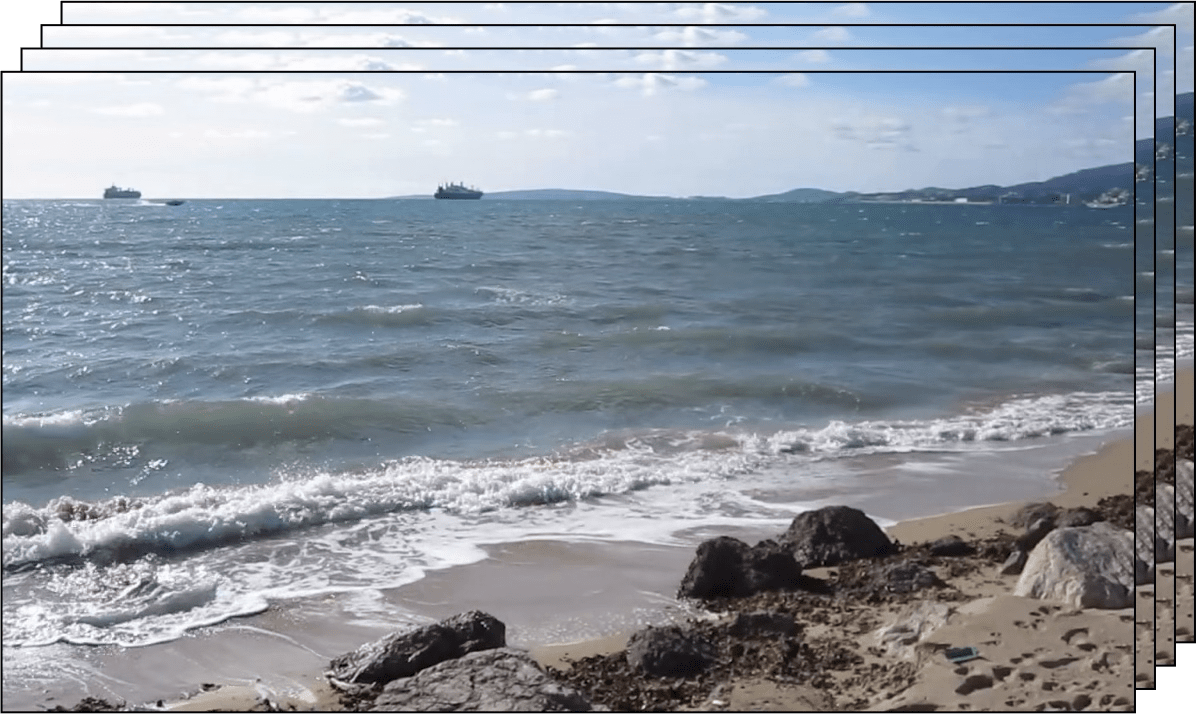
[Owens et al., Ambient Sound Provides Supervision for Visual Learning, ECCV 2016]
Predicting sound from video
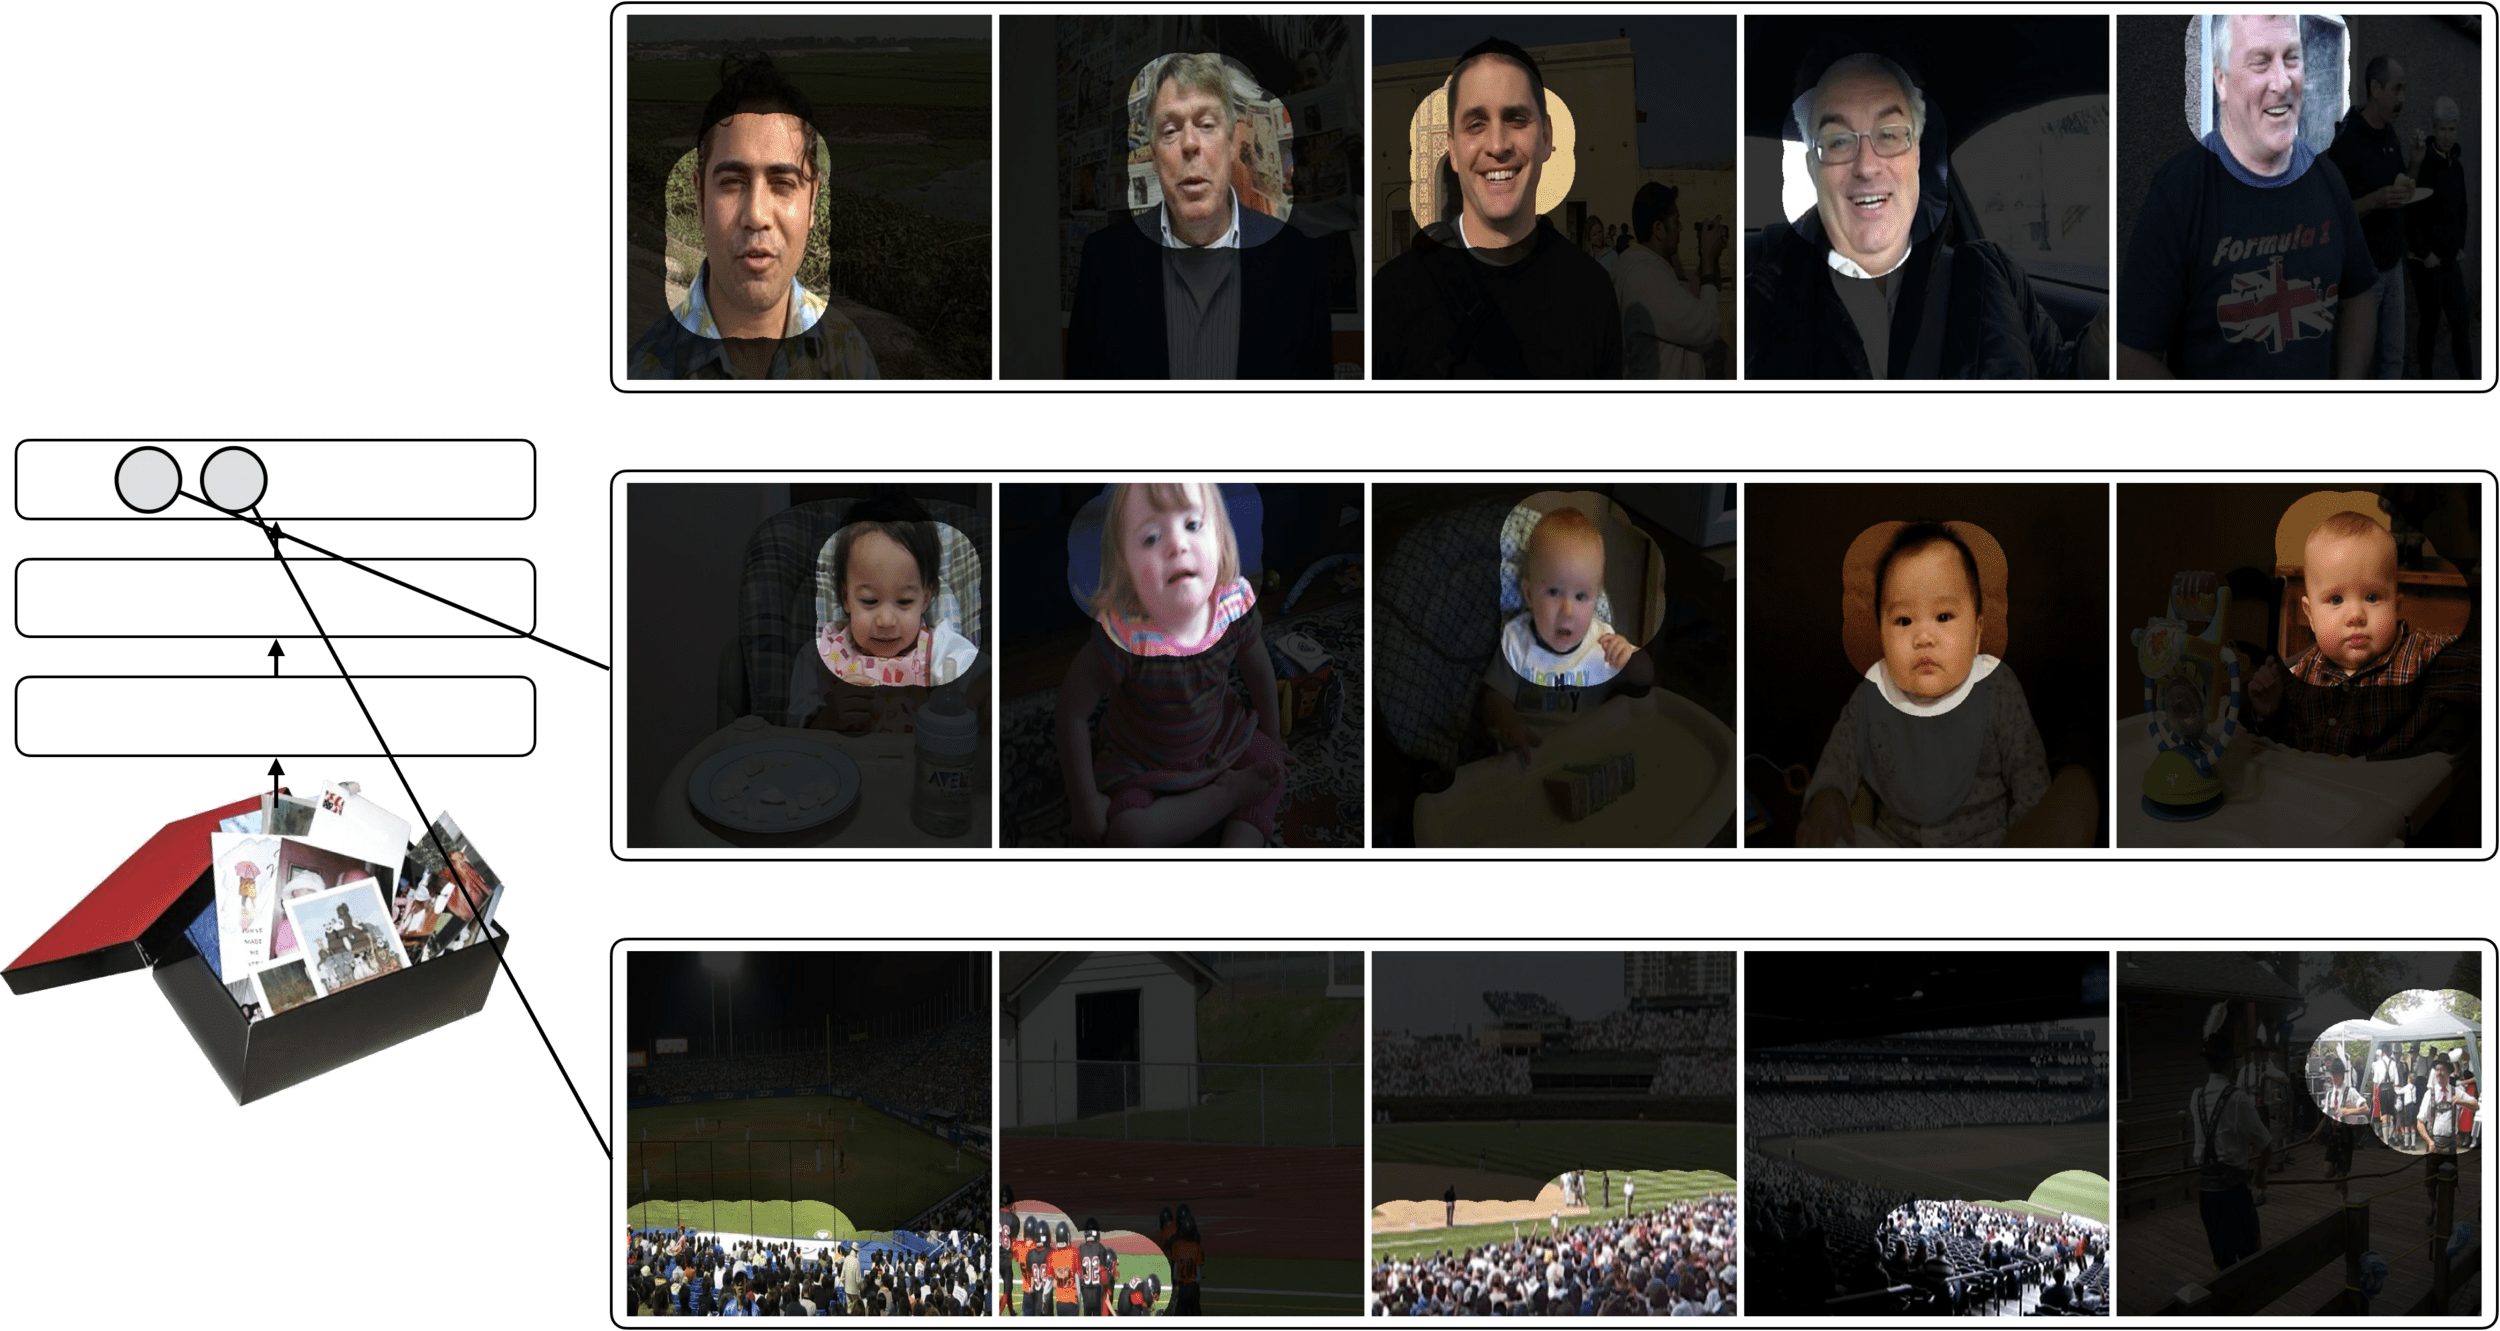
Units that learned to fire on faces, babies, and crowds: things that make sound.
CLIP: images and captions in one space
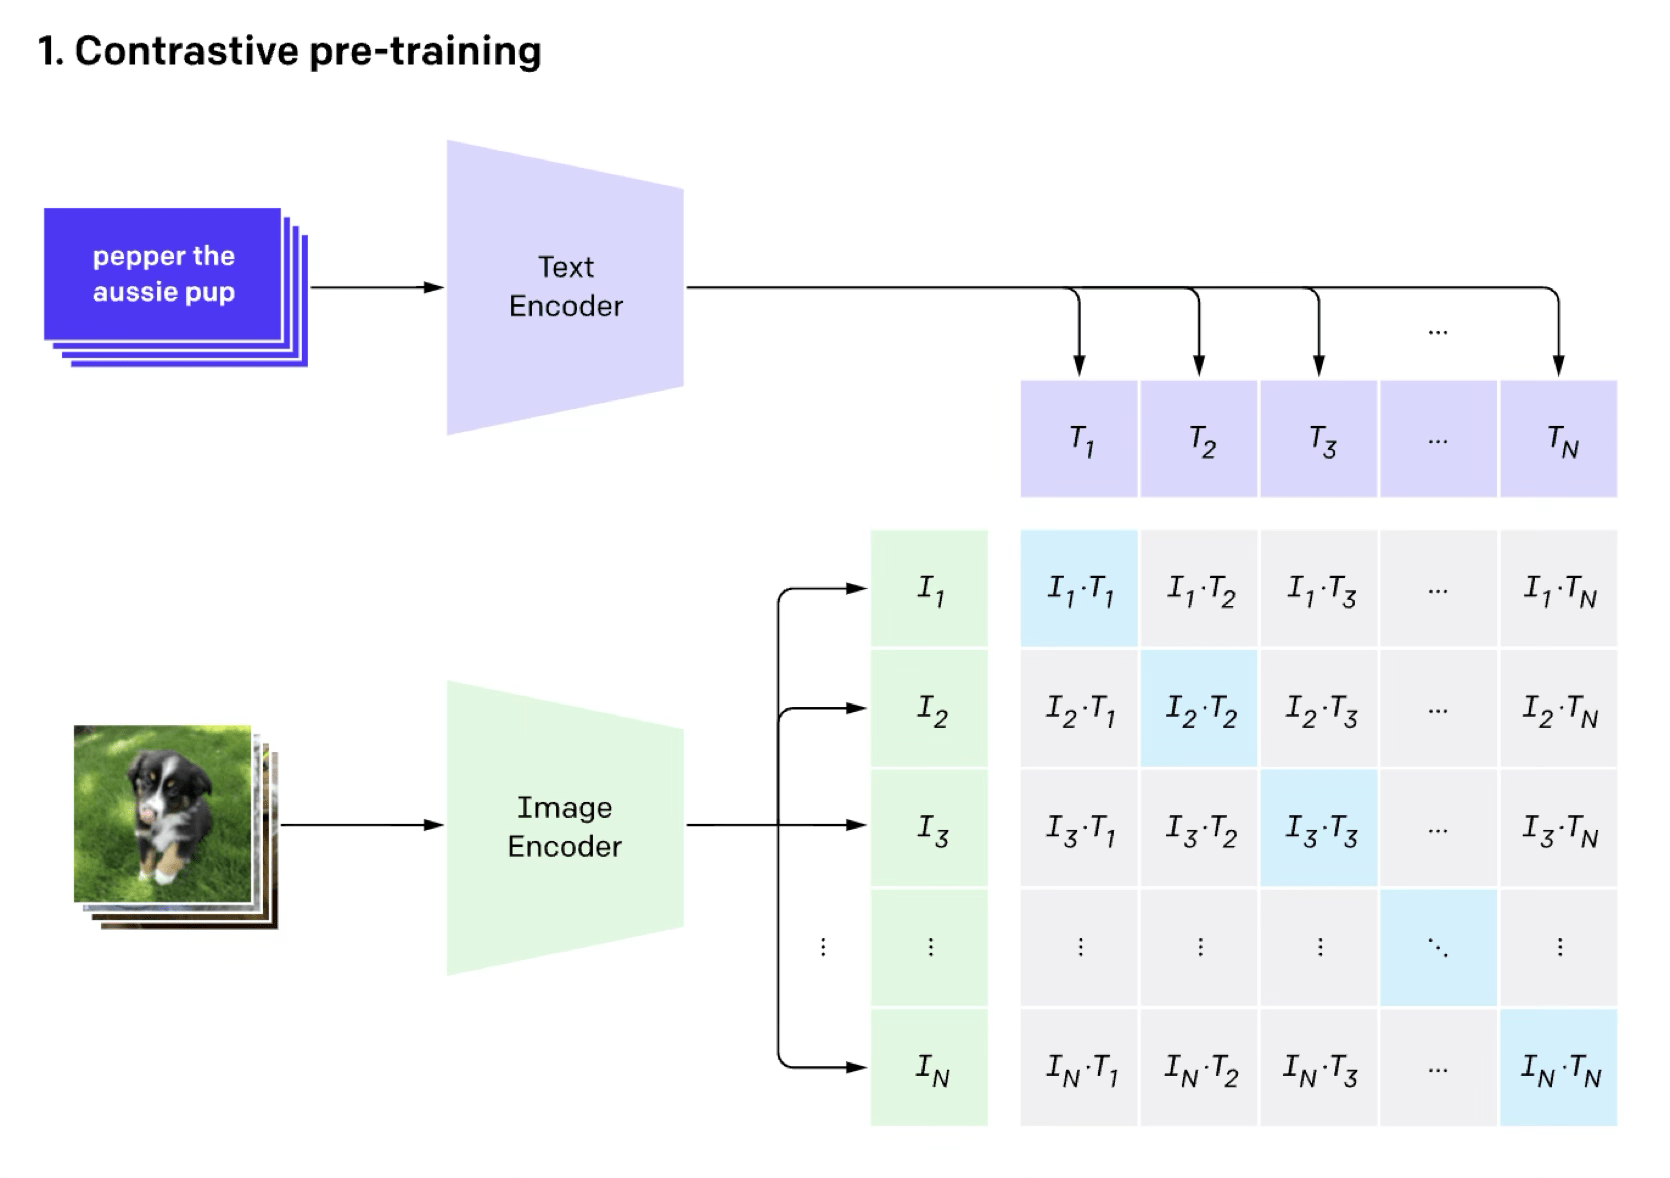
Two encoders map images and captions into one space.
Training raises the score of each image with its own caption.
To classify a new image, we compare it with prompts like “a photo of a dog”. We will try this in the lab.
e.g. DALL·E 2: text-to-image generation
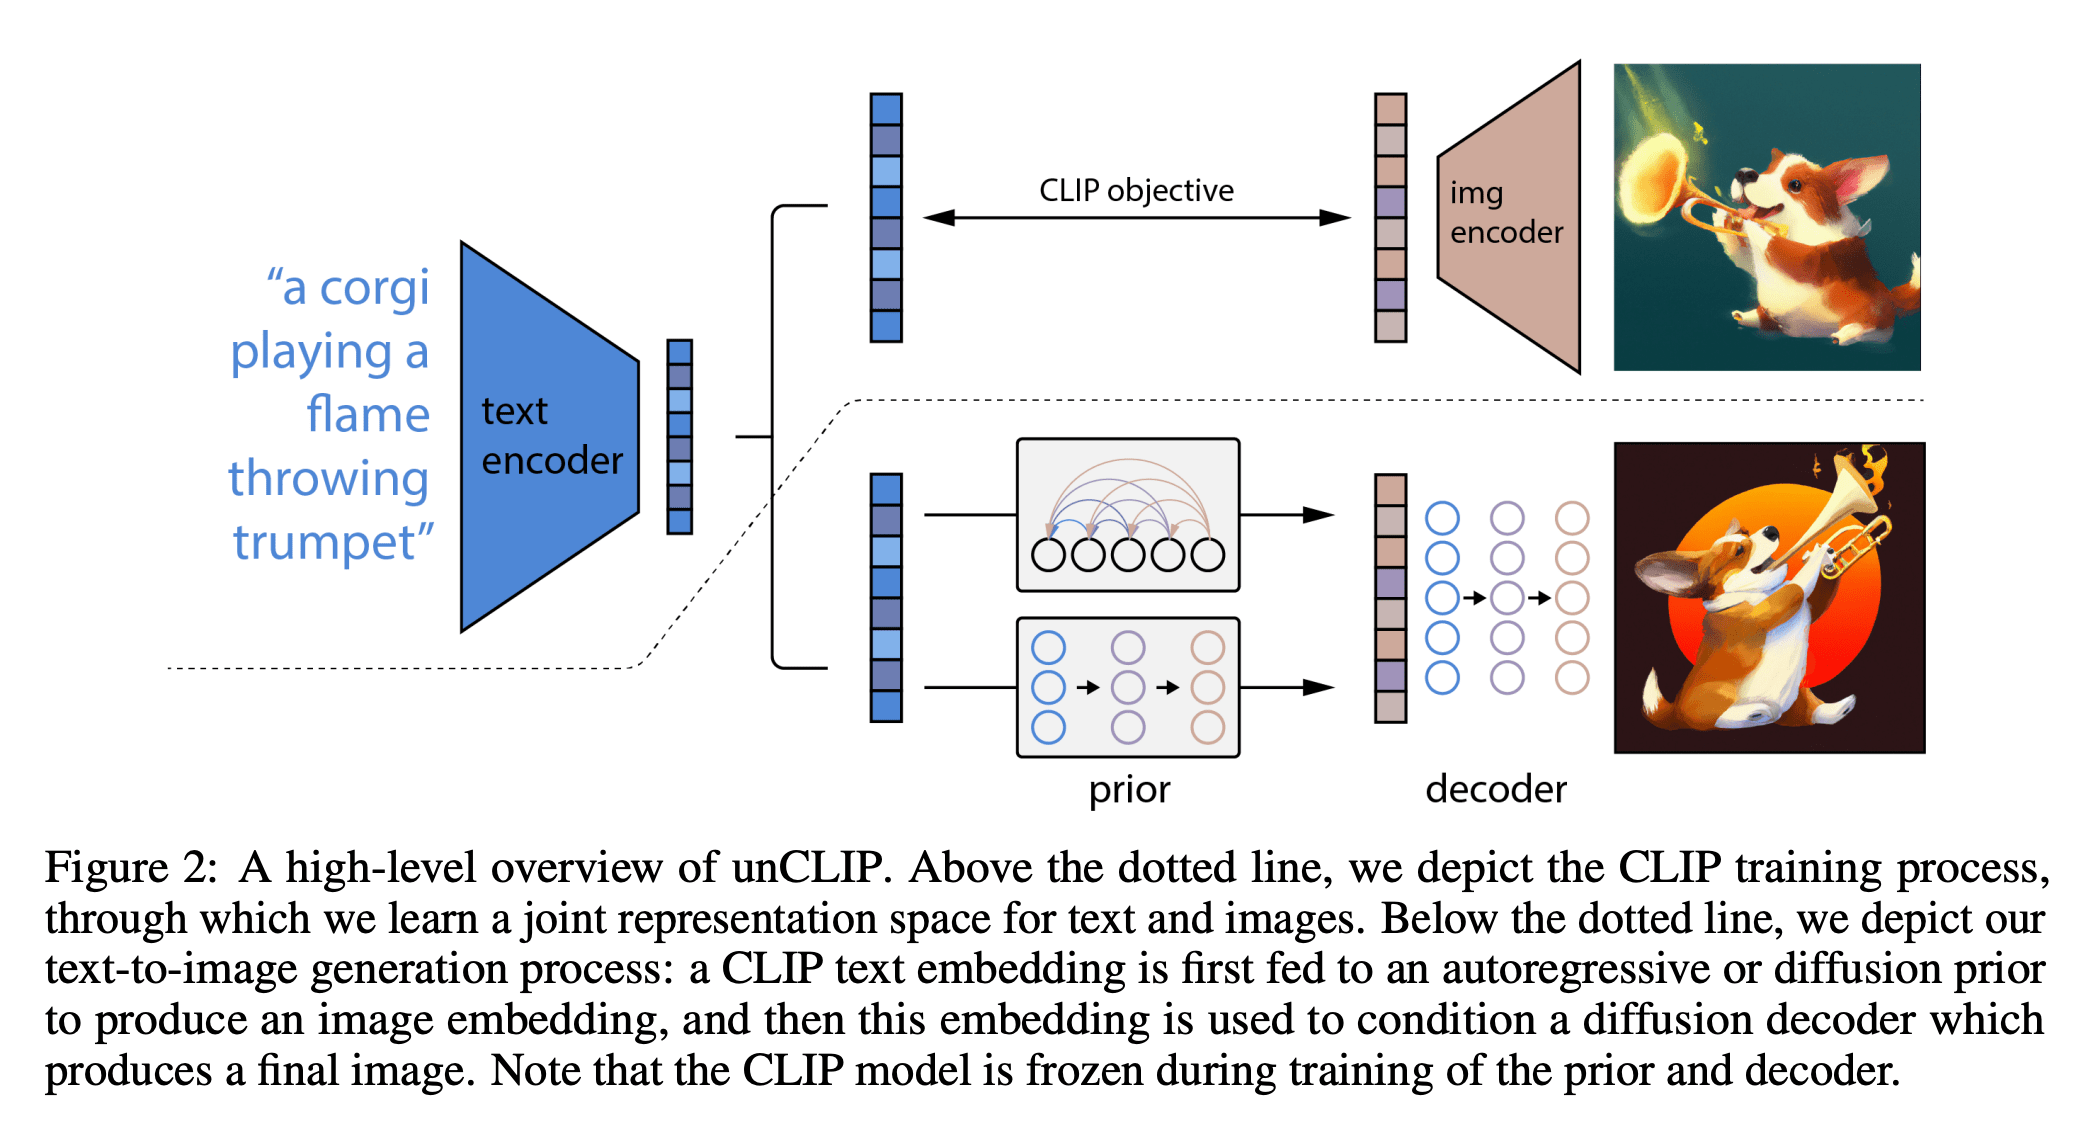
Different modalities, converging representations, without explicit alignment
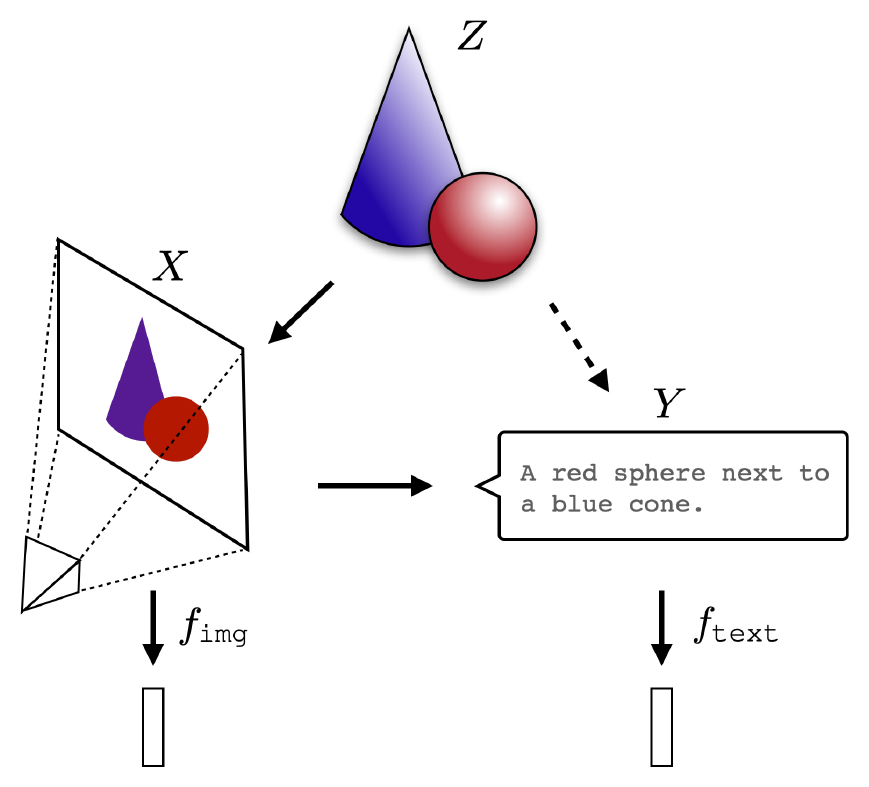
Images \(X\) and text \(Y\) are two projections of the same world \(Z\).
Vision and language models agree on which things are similar, and stronger models agree more.
Models may be converging toward a shared representation of reality.
Algorithmic monoculture
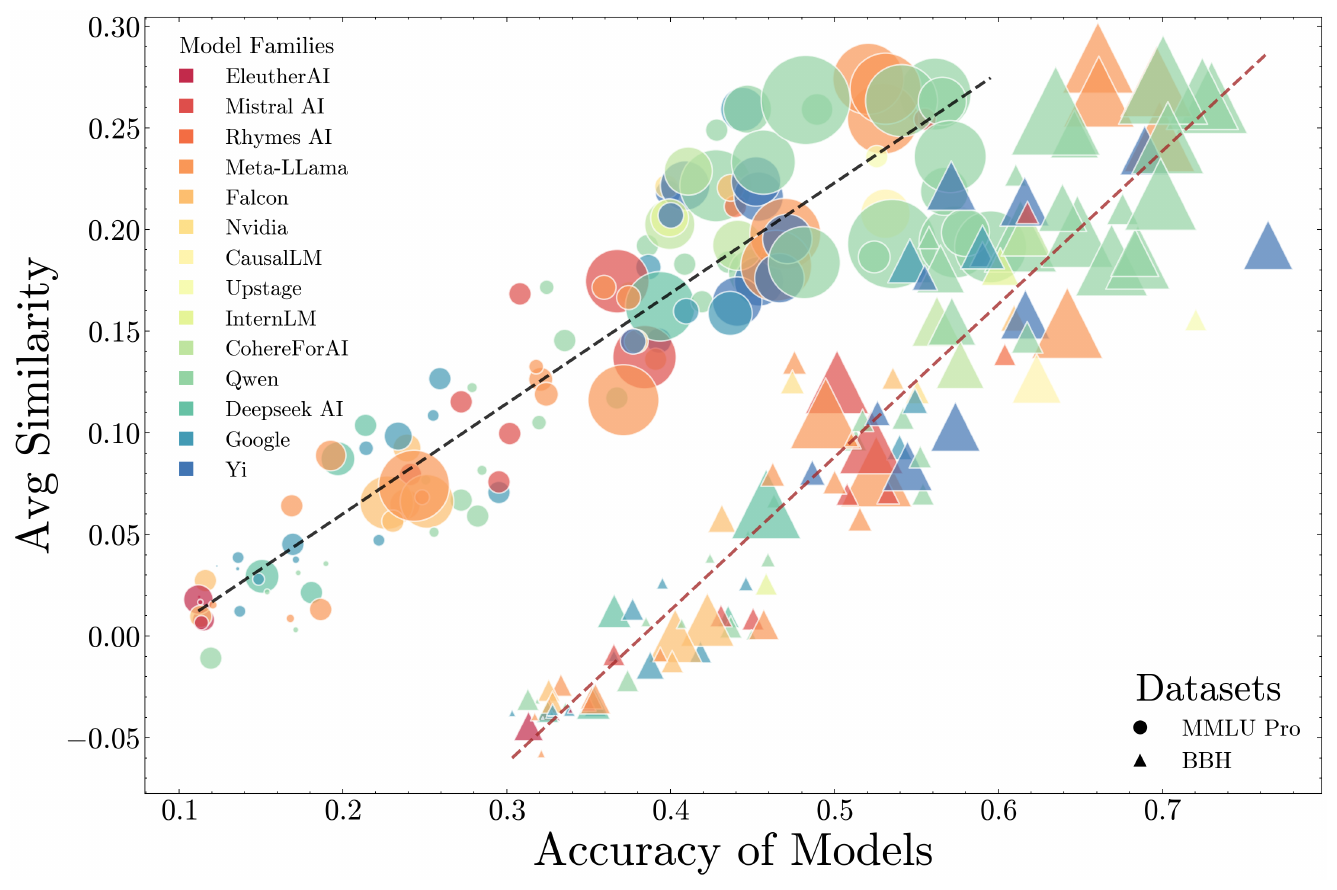
The more accurate a language model, the more its mistakes match those of other models, even across companies.
When many decisions rest on similar models, the same users can be failed everywhere.
Summary
-
We looked at the mechanics of NNs. Today we see they learn representations, just like our brains do.
-
This is useful because representations transfer — they act as prior knowledge that enables quick learning on new tasks.
-
Representations can also be learned without labels, e.g. as we do in unsupervised or self-supervised learning. This is great since labels are expensive and limiting.
-
Without labels, there are many ways to learn representations:
- representations as compressed codes, an auto-encoder with a bottleneck
- representations that are predictive of their context
- representations that are shared across sensory modalities
6.390 IntroML (Fall26) - Lecture 8 Representation Learning
By Shen Shen